The Engine Behind Modern Computer Vision


Convolutional Neural Networks might sound like heavy academic jargon, but if you’ve unlocked your iPhone with FaceID today or relied on a lane-assist feature in your car, you have already benefited from them. In the world of machine learning, this specific architecture has become the gold standard for processing visual data. It isn’t just about teaching computers to ‘see’, it’s about teaching them to interpret context, recognize anomalies, and make decisions faster than a human operator could.

For business leaders and tech strategists, understanding the mechanics behind these networks is no longer optional. It is the key to unlocking automation in quality control, security, and customer analytics.

How Convolutional Neural Networks Actually ‘See’

To understand why these networks are so effective, you have to look at how they differ from traditional neural networks. Standard networks treat input data as a flat list of numbers. That works fine for spreadsheets, but it fails miserably with images where the relationship between neighboring pixels matters.

Convolutional Neural Networks respect the spatial structure of an image. They analyze data through a hierarchy, similar to how the human visual cortex operates.

Here is the simplified breakdown of the architecture:

  • Convolutional Layers (The Feature Detectors): Think of this as a flashlight scanning a dark room. The network moves a ‘filter’ across the image to identify basic shapes, lines, curves, and edges. In later layers, these simple shapes are combined to recognize complex objects like eyes, wheels, or leaves.
  • Pooling Layers (The Summarizers): Analyzing every single pixel is computationally expensive and unnecessary. Pooling layers downsample the image, retaining the most critical information while discarding the noise. This keeps the model lean and fast.
  • Fully Connected Layers (The Decision Makers): Once the features are extracted and summarized, the final layers act as the judge. They look at the evidence (the features) and classify the image (e.g., ‘This is a defective product’ vs. ‘This is a pristine product’).

Real-World Business Applications

The theory is fascinating, but the ROI lies in the application. We are seeing these networks move out of R&D labs and into critical business operations.

1. Automated Quality Control

In manufacturing, human visual inspection is prone to fatigue. A CNN never gets tired. By training a model on images of perfect products versus defective ones, manufacturers can automate the detection of microscopic cracks, paint flaws, or assembly errors on the production line in real-time.

2. Retail and Visual Search

E-commerce giants are using these networks to power visual search engines. A customer can snap a photo of a pair of shoes they see on the street, and the algorithm identifies the make and model, serving up a purchase link instantly. It bridges the gap between offline inspiration and online conversion.

3. Healthcare Diagnostics

Radiology is being revolutionized by AI. Models are currently being used to analyze X-rays and MRIs, flagging potential tumors or fractures with accuracy rates that rival and sometimes surpass human specialists. This doesn’t replace doctors; it gives them a powerful second opinion.

Architecting Convolutional Neural Networks for Scale

If you are planning to implement this technology, you don’t need to start from zero. One of the biggest mistakes companies make is trying to build a proprietary architecture from scratch.

The Power of Transfer Learning

Instead of training a network on millions of images to learn what a ‘line’ or ‘curve’ looks like, smart teams use Transfer Learning. You take a pre-trained model (like ResNet or VGG) that has already learned the basics from a massive public dataset (like ImageNet). You then ‘fine-tune’ it on your specific business data. This saves massive amounts of computing power and allows you to get high accuracy with a much smaller dataset.

Dealing with Computational Cost

These models are heavy. They require significant GPU power to train. Cloud-based solutions are usually the most cost-effective route for training, but for deployment (inference), many companies are moving toward ‘Edge AI’ running lighter versions of these models directly on cameras or mobile devices to reduce server costs and latency.

Best Practices for Implementation

Success with Convolutional Neural Networks isn’t just about the code; it’s about the data strategy.

  • Clean Your Data: A model is only as good as its training set. If your labeled images are inconsistent, your results will be erratic. Invest time in data cleaning before you write a single line of code.
  • Define Success Metrics: Are you optimizing for speed or accuracy? In a self-driving car, accuracy is paramount. In a fun social media filter, speed matters more. Know your trade-offs.
  • Watch for Bias: If you train a facial recognition system only on one demographic, it will fail in the real world. Ensure your datasets are diverse and representative of your actual user base.

The Future is Visual

We are moving toward a future where ‘visual’ is a primary data input for business intelligence. From analyzing foot traffic in retail stores to monitoring crop health via satellite imagery, the ability to process pixel data automatically is a massive competitive advantage.

By integrating Convolutional Neural Networks into your tech stack, you aren’t just adopting a trend. You are building a visual cortex for your business. Start small, leverage pre-trained models, and focus on solving specific, high-value problems.

How to Choose the Right Open-Source LLM for Production


Open-source LLMs and multimodal models are released at a steady pace. Many report strong results across benchmarks for reasoning, coding, and document understanding.

Benchmark performance provides useful signals, but it does not determine production viability. Latency ceilings, GPU availability, licensing terms, data privacy requirements, and inference cost under sustained load define whether a model fits your environment.

In this piece, we’ll outline a structured approach to selecting the right open-source model based on workload type, infrastructure constraints, and measurable deployment requirements.

TL;DR

  • Start with constraints, not benchmarks. GPU limits, latency targets, licensing, and cost narrow the field before capability comparisons begin.
  • Match the model to the workload primitive. Reasoning agents, coding pipelines, RAG systems, and multimodal extraction each require different architectural strengths.
  • Long context does not replace retrieval. Extended token windows require structured chunking to avoid drift.
  • MoE models reduce the number of active parameters per token, lowering inference cost relative to dense architectures of similar scale.
  • Instruction-tuned models prioritize formatting reliability over depth of exploratory reasoning.
  • Benchmark scores are directional signals, not deployment guarantees. Validate performance using your own data and traffic profile.
  • Durable model selection depends on repeatable evaluation under real workload conditions.

Effective model selection begins with defining constraints before reviewing benchmark charts or release notes.

Before You Look at a Single Model

Most teams begin model selection by scanning release announcements or benchmark leaderboards. In practice, the decision space narrows significantly once operational boundaries are defined.

Three questions eliminate most unsuitable options before you evaluate a single benchmark.

What exactly is the task?

Model selection should begin with a precise definition of the workload primitive, since models optimized for extended reasoning behave differently from those tuned for structured extraction or deterministic formatting.

Say, for instance, a customer support agent for a multilingual SaaS platform. It must call internal APIs, summarize account history, and respond under strict latency targets. The challenge is not abstract reasoning; it is structured retrieval, controlled summarization, and reliable function execution within defined time constraints.

Most production workloads fall into a small number of recurring patterns.

Workload Type

Primary Technical Requirement

Multi-step reasoning and agents

Stability across long execution traces

High-precision instruction execution

Consistent formatting and schema adherence

Agentic coding

Multi-file context handling and tool reliability

Long-context summarization and RAG

Relevance retention and drift control

Visual and document understanding

Cross-modal alignment and layout robustness


Where does it need to run?

Infrastructure imposes hard limits. A single-GPU deployment constrains model size and concurrency. Multi-GPU or multi-node environments support larger architectures but introduce orchestration complexity. Real-time systems prioritize predictable latency, while batch workflows can trade response time for deeper reasoning.

The deployment environment often determines feasibility before quality comparisons begin.

What are your non-negotiables?

Licensing defines enterprise eligibility. Permissive licenses such as Apache 2.0 and MIT allow broad flexibility, while custom commercial terms may impose restrictions on redistribution or usage.

Data privacy requirements can mandate on-premises execution. Inference cost under sustained load frequently becomes the decisive factor as traffic scales. Mixture-of-Experts architectures reduce active parameters per token, which can lower operational cost, but they introduce different inference characteristics that must be validated.

Clear answers to these questions convert model selection from an open-ended search into a bounded engineering decision.

Open-Source AI Models Comparison

The models below are organized by workload type. Differences in context length, activation strategy, and reasoning depth often determine whether a system holds up under real production constraints.

Reasoning and Agentic Workflows

Reasoning-heavy systems expose architectural tradeoffs quickly. Long execution traces, tool invocation loops, and verification stages demand stability across intermediate steps.

Context window size, sparse activation strategies, and internal reasoning depth directly influence how reliably a system completes multi-step workflows. The models in this category take different approaches to those constraints.

Kimi K2.5

Kimi K2.5, developed by Moonshot AI and built on the Kimi-K2-Base architecture, is a native multimodal model that supports vision, video, and text inputs via an integrated MoonViT vision encoder. It is designed for sustained multi-step reasoning and coordinated agent execution, supporting a 256K token context window and using sparse activation to manage compute across extended reasoning chains.

Why Should You Use Kimi K2.5

  • Long-chain reasoning depth: The 256K token window reduces breakdown in extended planning and agent workflows, preserving context across the full length of a task.
  • Agent swarm capability: Supports coordinated multi-agent execution through an Agent Swarm architecture, enabling parallelized task completion across complex composite workflows.
  • Sparse activation efficiency: Activates a subset of parameters per token, balancing reasoning capacity with compute cost at scale.
Deployment Considerations
  • Long-context management. Retrieval strategies are recommended near maximum sequence length to maintain coherence and reduce KV cache pressure.
  • Modified MIT license: Large-scale commercial products exceeding 100M monthly active users or USD 20M monthly revenue require visible attribution.

Check Kimi K2.5 on Clarifai

GLM-5

GLM-5, developed by Zhipu AI, is positioned as a reasoning-focused generalist with strong coding capability. It balances structured problem-solving with instructional stability across multi-step workflows.

Why Should You Use GLM-5
  • Reasoning–coding balance: Combines logical planning with code generation in a single model, reducing the need to route between specialized systems.
  • Instruction stability: Maintains consistent formatting under structured prompts across extended agentic sessions.
  • Broad evaluation strength: Performs competitively across reasoning and coding benchmarks, including AIME 2026 and SWE-Bench Verified.
Deployment Considerations
  • Scaling by variant: Larger configurations require multi-GPU deployment for sustained throughput; plan infrastructure around the specific variant size.
  • Latency tuning: Extended reasoning depth should be validated against real-time constraints before production cutover.

MiniMax M2.5

MiniMax M2.5, developed by MiniMax, emphasizes multi-step orchestration and long agent traces. It supports a 200K token context window and uses a sparse MoE architecture with 10B active parameters per token from a 230B total pool.

Why Should You Use MiniMax M2.5
  • Agent trace stability: Achieves 80.2% on SWE-Bench Verified, signaling reliability across extended coding and orchestration workflows.
  • MoE efficiency: Activates only 10B parameters per token, lowering compute relative to dense models at equivalent capability levels.
  • Extended context support: The 200K window accommodates long execution chains when paired with structured retrieval.
Deployment Considerations
  • Distributed infrastructure: Sustained throughput typically requires multi-GPU deployment; 4x H100 96GB is the recommended minimum configuration.
  • Modified MIT license: Commercial products must comply with attribution requirements before deployment.

GLM-4.7

GLM-4.7, developed by Zhipu AI, focuses on agentic coding and terminal-oriented workflows. It introduces turn-level reasoning controls that allow operators to adjust thinking depth per request.

Why Should You Use GLM-4.7
  • Turn-level reasoning control. Enables latency management in interactive coding environments by switching between Interleaved, Preserved, and Turn-level Thinking modes per request.
  • Agentic coding strength: Achieves 73.8% on SWE-Bench Verified, reflecting strong software engineering performance across real-world task resolution.
  • Multi-turn stability: Designed to reduce drift in extended developer-facing sessions, maintaining instruction adherence across long exchanges.
Deployment Considerations
  • Reasoning–latency tradeoff. Higher reasoning modes increase response time; validate under production load before committing to a default mode.
  • MIT license: Allows unrestricted commercial use with no attribution clauses.

Check GLM-4.7 on Clarifai

Kimi K2-Instruct

Kimi K2-Instruct, developed by Moonshot AI, is the instruction-tuned variant of the Kimi K2 architecture, optimized for structured output and tool-calling reliability in production workflows.

Why Should You Use Kimi K2-Instruct
  • Structured output reliability: Maintains consistent schema adherence across complex prompts, making it well-suited for API-facing systems where output structure directly affects downstream processing.
  • Native tool-calling support: Designed for workflows requiring API invocation and structured responses, with strong performance on BFCL-v3 function-calling evaluations.
  • Inherited reasoning capacity: Retains multi-step reasoning strength from the Kimi K2 base without extended thinking overhead, balancing depth with response speed.
Deployment Considerations
  • Instruction-tuning tradeoff: Prioritizes response speed over the depth of exploratory reasoning; workflows that require an extended chain of thought should evaluate Kimi K2-Thinking instead.
  • Modified MIT license: Large-scale commercial products exceeding 100M monthly active users or USD 20M monthly revenue require visible attribution.

Check Kimi K2-Instruct on Clarifai

GPT-OSS-120B

GPT-OSS-120B, released by Open AI, is a sparse MoE model with 117B total parameters and 5.1B active parameters per token. MXFP4 quantization of MoE weights allows it to fit and run on a single 80GB GPU, simplifying infrastructure planning while preserving strong reasoning capability.

Why Should You Use GPT-OSS-120B
  • High output precision: Produces consistent structured responses, with configurable reasoning effort (Low, Medium, High), adjustable via system prompt to match task complexity.
  • Single-GPU deployment: Runs on a single H100 or AMD MI300X 80GB GPU, eliminating the need for multi-GPU orchestration in most production environments.
  • Deterministic behavior. Well-suited for workflows where consistent, exactness-first responses outweigh exploratory chain-of-thought.
Deployment Considerations
  • Hopper or Ada architecture required: MXFP4 quantization is not supported on older GPU generations, such as A100 or L40S; plan infrastructure accordingly.
  • Apache 2.0 license: Permissive commercial use with no copyleft or attribution requirements beyond the usage policy.

Check GPT-OSS-120B on Clarifai

Qwen3-235B

Qwen3-235B-A22B, developed by Alibaba’s Qwen team, uses a Mixture-of-Experts architecture with 22B active parameters per token from a 235B total pool. It targets frontier-level reasoning performance while maintaining inference efficiency through selective activation.

Why Should You Use Qwen3-235B
  • MoE compute efficiency: Activates only 22B parameters per token despite a 235B parameter pool, reducing per-token compute relative to dense models at comparable capability levels.
  • Frontier reasoning capability: Competitive across intelligence and reasoning benchmarks, with support for both thinking and non-thinking modes switchable at inference time.
  • Scalable cost profile: Offers strong capability-to-cost balance at high traffic volumes, particularly when serving diverse workloads that mix simple and complex queries.
Deployment Considerations
  • Distributed deployment: Frontier-scale inference requires multi-GPU orchestration; 8x H100 is a typical minimum for full-context throughput.
  • MoE routing evaluation: Load balancing behavior should be validated under production traffic to avoid expert collapse at high concurrency.
  • Apache 2.0 license: Fully permissive for commercial use with no attribution clauses.

General-Purpose Chat and Instruction Following

Instruction-heavy systems prioritize response stability over deep exploratory reasoning. These workloads emphasize formatting consistency, multilingual fluency, and predictable behavior under varied prompts.

Unlike agent-focused models, chat-oriented architectures are optimized for broad conversational coverage and instruction reliability rather than sustained tool orchestration.

Qwen3-30B-A3B

Qwen3-30B-A3B, developed by Alibaba’s Qwen team, is a Mixture-of-Experts model with approximately 3B active parameters per token. It balances multilingual instruction performance with hybrid reasoning controls, allowing operators to toggle between deeper thinking and faster response modes.

Why Should You Use Qwen3-30B-A3B
  • Efficient MoE architecture: Activates only 3B parameters per token, reducing compute relative to dense 30B-class models while maintaining broad instruction capability.
  • Multilingual instruction strength: Performs reliably across diverse languages and structured prompts, making it well-suited for international-facing products.
  • Hybrid reasoning control: Supports thinking and non-thinking modes via /think and /no_think prompt toggles, enabling latency optimization on a per-request basis.
Deployment Considerations
  • MoE routing evaluation: Performance under sustained load should be validated to ensure consistent token distribution; expert collapse under high concurrency should be tested in advance.
  • Latency tuning: Hybrid reasoning modes should be aligned with real-time service requirements before production cutover.
  • Apache 2.0 license: Fully permissive for commercial use with no attribution requirements.

Check Qwen3-30B-A3B on Clarifai

Mistral Small 3.2 (24B)

Mistral Small 3.2, developed by Mistral AI, is a compact 24B model tuned for instruction clarity and conversational stability. It improves on its predecessor by increasing formatting reliability, reducing repetition, improving function-calling accuracy, and adding native vision support for image and text inputs.

Why Should You Use Mistral Small 3.2
  • Instruction quality improvements: Demonstrates gains on WildBench and Arena Hard over its predecessor, with measurable reductions in instruction drift and infinite generation on challenging prompts.
  • Compact deployment profile: At 24B parameters, it fits on a single RTX 4090 when quantized, simplifying local and edge infrastructure planning.
  • Consistent conversational stability: Maintains consistent formatting across varied prompts, with strong adherence to system prompts across multi-turn sessions.
Deployment Considerations
  • Context limitations: Not designed for extended multi-step reasoning workloads; systems requiring deep chain-of-thought should evaluate larger reasoning-focused models.
  • Hardware note: Running in bf16 requires approximately 55GB of GPU RAM; two GPUs are recommended for full-context throughput at batch scale.
  • Apache 2.0 license: Fully permissive for commercial use with no attribution clauses.

Coding and Software Engineering

Software engineering workloads differ from general chat and reasoning tasks. They require deterministic edits, multi-file context handling, and stability across debugging sequences and tool invocation loops.

In these environments, formatting precision and repository-level reasoning often matter more than conversational fluency.

Qwen3-Coder

Qwen3-Coder, developed by Alibaba’s Qwen team, is purpose-built for agentic coding pipelines and repository-level workflows. It is optimized for structured code generation, refactoring, and multi-step debugging across complex codebases.

Why Should You Use Qwen3-Coder
  • Strong software engineering performance. Achieves state-of-the-art results among open-source models on SWE-Bench Verified without test-time scaling, reflecting reliable multi-file reasoning capability across real-world tasks.
  • Repository-level awareness. Trained on repo-scale data, including Pull Requests, enabling structured edits and iterative debugging across interconnected files rather than isolated snippets.
  • Agent pipeline compatibility. Designed for integration with coding agents that rely on tool invocation and terminal workflows, with long-horizon RL training across 20,000 parallel environments.

Deployment Considerations

  • Context scaling: Native context is 256K tokens, extendable to 1M with YaRN extrapolation; large repository inputs require careful context management to avoid truncation at scale.
  • Hardware scaling by size: The flagship 480B-A35B variant requires multi-GPU deployment; the 30B-A3B variant is available for single-GPU environments.
  • Apache 2.0 license: Fully permissive for commercial use with no attribution requirements.

Check Qwen3-Coder on Clarifai

DeepSeek V3.2

DeepSeek V3.2, developed by DeepSeek AI, is a 685B sparse MoE model built on DeepSeek Sparse Attention (DSA), an efficient attention mechanism that substantially reduces computational complexity for long-context scenarios. It is designed for advanced reasoning tasks, agentic applications, and complex problem solving across mathematics, programming, and enterprise workloads.

Why Should You Use DeepSeek V3.2
  • Advanced reasoning and coding strength. Performs strongly across mathematical and competitive programming benchmarks, with gold-medal results at the 2025 IMO and IOI demonstrating frontier-level formal reasoning.
  • Agentic task integration. Supports tool calling and multi-turn agentic workflows through a large-scale synthesis pipeline, making it suited for complex interactive environments beyond pure reasoning tasks.
  • Deterministic output profile. Configurable thinking mode enables precision-first responses for tasks where exact reasoning steps matter, while standard mode supports general-purpose instruction following.
Deployment Considerations
  • Reasoning–latency tradeoff. Thinking mode increases response time; validate against latency requirements before committing to a default inference configuration.
  • Scale requirements. At 685B parameters, sustained throughput requires H100 or H200 multi-GPU infrastructure; FP8 quantization is supported for memory efficiency.
  • MIT license. Allows unrestricted commercial deployment without attribution clauses.

Long-Context and Retrieval-Augmented Generation

Long-context workloads stress positional stability and relevance management rather than raw reasoning depth. As sequence length increases, small architectural differences can determine whether a system maintains coherence across extended inputs.

In RAG systems, retrieval design often matters as much as model size. Context window length, multimodal grounding capability, and inference cost per token directly affect scalability.

Mistral Large 3

Mistral Large 3, released by Mistral AI, supports a 256K token context window and handles multimodal inputs natively through an integrated vision encoder. Text and image inputs can be processed in a single pass, making it suitable for document-heavy RAG pipelines that include charts, invoices, and scanned PDFs.

Why Should You Use Mistral Large 3
  • Extended 256K context window: Supports large document ingestion without aggressive truncation, with stable cross-domain behavior maintained across the full sequence length.
  • Native multimodal handling: Processes text and images jointly through an integrated vision encoder, reducing the need for separate OCR or vision pipelines in document-heavy retrieval systems.
  • Apache 2.0 license: Permissive licensing enables unrestricted commercial deployment and redistribution without attribution clauses.
Deployment Considerations
  • Context drift at scale: Retrieval and chunking strategies remain essential to maintain relevance near the upper context bound; the model does not eliminate the need for careful retrieval design.
  • Vision capability ceiling: Multimodal handling is generalist rather than specialist; pipelines requiring precise visual reasoning should benchmark against dedicated vision models before committing.
  • Token-cost profile: With 675B total parameters across a granular MoE architecture, full-context inference runs on a single node of B200s or H200s in FP8, or H100s and A100s in NVFP4; multi-node deployment is required for full BF16 precision

Matching Use Cases to Models

Most model selection decisions follow recurring patterns of work. The table below maps common production scenarios to the models best aligned with those requirements.

If you’re building…

Start with…

Why

Multi-step reasoning agents

Kimi K2.5

256K context and agent-swarm support reduce breakdown in long execution traces.

Balanced reasoning + coding workflows

GLM-5

Combines logical planning and code generation in a single model

Agentic coding pipelines

Qwen3-Coder, GLM-4.7

Strong SWE-Bench performance and repository-level reasoning stability.

Precision-first structured output systems

GPT-OSS-120B, Kimi K2-Instruct

Deterministic formatting and stable schema adherence.

Multilingual chat assistants

Qwen3-30B-A3B

Efficient MoE architecture with hybrid reasoning control.

Long-document RAG systems

Mistral Large 3

256K context with native multimodal input support.

Visual document extraction

Qwen2.5-VL

Strong cross-modal grounding across document benchmarks

Edge multimodal applications

MiniCPM-o 4.5

Compact 9B footprint suited for constrained environments.


These mappings reflect architectural alignment rather than leaderboard rank.

How to Make the Decision

After narrowing your shortlist by workload type, model selection becomes a structured evaluation grounded in operational reality. The goal is alignment between architectural intent and system constraints.

Focus on the following dimensions:

Infrastructure Alignment

Validate GPU memory, node configuration, and expected request volume before running qualitative comparisons. Large, dense models may require multi-GPU deployment, while Mixture-of-Experts architectures reduce the number of active parameters per token but introduce routing and orchestration complexity.

Performance on Representative Data

Public benchmarks such as SWE-Bench Verified and reasoning leaderboards provide directional signals. They do not substitute for testing on your own inputs.

Evaluate models using real prompts, repositories, document sets, or agent traces that reflect production workloads. Subtle failure modes often emerge only under domain-specific data.

Latency and Cost Under Projected Load

Measure response time and per-request inference cost at expected traffic levels. Evaluate performance under sustained load and peak concurrency rather than isolated queries.

Long context windows, routing behavior, and total token volume directly shape long-term cost and responsiveness.

Licensing, Compliance, and Model Stability

Review license terms before integration. Apache 2.0 and MIT licenses allow broad commercial use, while modified or custom licenses may impose attribution or distribution requirements.

Beyond license terms, assess release cadence and version stability. For API-wrapped models where version control is handled by the provider, unexpected deprecations or silent updates can introduce operational risk. Durable systems depend not only on performance, but on predictable maintenance.

Durable model selection depends on repeatable evaluation, explicit infrastructure limits, and measurable performance under real workloads.

Wrapping Up

Selecting the right open-source model for production is not about leaderboard positions. It is about whether a model performs within your latency, memory, scaling, and cost constraints under real workload conditions.

Infrastructure plays a role in that evaluation. Clarifai’s Compute Orchestration allows teams to test and run models across cloud, on-prem, or hybrid environments with autoscaling, GPU fractioning, and centralized resource controls. This makes it possible to measure performance under the same conditions the model will see in production.

For teams running open-source LLMs, the Clarifai Reasoning Engine focuses on inference efficiency. Optimized execution and performance tuning help improve throughput and reduce cost at scale, which directly impacts how a model behaves under sustained load.

When testing and production share the same infrastructure, the model you validate under real workloads is the model you promote to production.


Vertical Vs Horizontal Growth: Which Strategy Scales Better?


Vertical vs Horizontal growth isn’t just a question of direction; it’s the fundamental decision that shapes your company’s future architecture.

In the boardroom, these terms don’t refer to lines on a graph. They refer to two distinct ways of seizing power in a market. Do you dig deeper to control your entire supply chain, or do you spread wider to capture more market share?

Most professionals understand the basic definitions. But knowing the definitions won’t save you from a bad strategic pivot. You need to understand the capital requirements, the risk profiles, and the operational drag associated with each.

Here is how a strategist looks at the choice between going deep or going wide.

The Core Distinction

Before analyzing the ROI, let’s strip away the jargon.

  • Vertical Growth is about control. It’s moving up or down your specific supply chain. It means buying your supplier to lower costs or buying your distributor to own the customer relationship.
  • Horizontal Growth is about reach. It’s expanding into new markets or launching adjacent products. It means a shoe company starting a clothing line, or a software firm acquiring a competitor to double its user base.

One maximizes margin; the other maximizes revenue.

Vertical Integration: The Power Play

Vertical integration is the strategy of the perfectionist. When a company decides to ‘go vertical,’ they are usually trying to eliminate dependencies. They are tired of suppliers hiking prices or distributors diluting their brand message.

By taking ownership of different stages of production, you secure your logistics and protect your trade secrets.

Why Go Vertical?

  1. Margin Protection: Middlemen eat profit. By bringing manufacturing or logistics in-house, you recapture that value.
  2. Supply Chain Security: If you own the factory, you rarely have to worry about your supplier prioritizing a competitor’s order over yours.
  3. Quality Dominance: You control the product from raw material to the checkout counter.

The Real-World Application

Look at Tesla. They didn’t just build cars; they built the battery factories (Gigafactories) and the charging network. This is aggressive vertical integration. By refusing to rely on third-party charging networks, they solved the biggest objection to EV ownership: range anxiety. And they did it themselves.

Strategist’s Note on Vertical Risks

Don’t dive into this lightly. Vertical integration is capital-intensive. It requires you to be good at everything. If you are a great retailer but a terrible manufacturer, buying a factory might sink you. Focus on core competencies first.

Horizontal Expansion: The Market Grab

Horizontal expansion is the strategy of the empire builder. This approach is less about squeezing efficiency out of a single product and more about dominating a category.

This usually happens via merger, acquisition, or internal R&D focused on new product lines. The goal is to sell more things to your existing customers or the same thing to new customers.

Why Go Horizontal?

  1. Risk Mitigation: If one product line fails, others can float the company. You aren’t putting all your eggs in one basket.
  2. Economies of Scope: You already have a marketing team and a distribution network. Sliding a new product into that existing infrastructure is cheaper than building it from scratch.
  3. Synergy: Cross-selling becomes a massive revenue driver.

The Real-World Application

Apple is a master of this. They started with computers. Then came the iPod, iPhone, iPad, and the Apple Watch. These are horizontal moves. They’re different products, but they work together within the same ecosystem. Because the brand trust was already established, customers were willing to try the new categories.

Strategist’s Note on Horizontal Risks

The danger here is brand dilution. If a luxury watchmaker suddenly starts selling cheap plastic wall clocks, they expand horizontally but destroy their brand equity. Expansion must make sense to the consumer.

Vertical vs Horizontal: Making the Strategic Choice

Choosing between these two isn’t about which is ‘better.’ It is about your current lifecycle stage and cash flow.

When to choose Vertical:

  • Your suppliers are unreliable or too expensive.
  • You have high transaction costs.
  • Your market is mature, and the only way to grow profit is to improve margins.
  • You need strict secrecy regarding your proprietary technology.

When to choose Horizontal:

  • You have a strong brand that can carry over to new categories.
  • Your current market is saturated, and you need new revenue streams.
  • You want to acquire a competitor to reduce market friction.
  • You have an efficient distribution channel that is currently underutilized.

The Bottom Line

Successful companies rarely stick to just one lane forever. They toggle between these strategies based on market conditions.

The best approach? Audit your bottlenecks.

If your growth is stalled because you can’t get materials fast enough, look at Vertical vs Horizontal solutions and choose the vertical path. If your growth is stalled because you’ve tapped out your current customer base, it’s time to move horizontally.

Don’t follow the trend. Follow the friction in your business, and solve for that.

How to Deploy MCP Servers as an API Endpoint


TL;DR

MCP servers connect LLMs to external tools and data sources through a standardized protocol. Public MCP servers provide capabilities such as web search, GitHub access, database queries, and browser automation through structured tool definitions.

These servers typically run as long-lived stdio processes that respond to tool invocation requests. To use them reliably in applications or share them across teams, they need to be deployed as stable, accessible endpoints.

Clarifai allows MCP servers to be deployed as managed endpoints. The platform runs the configured MCP process, handles lifecycle management, discovers available tools, and exposes them through its API.

This tutorial walks you through how to deploy any public MCP server. We’d be using the DuckDuckGo browser server as a reference implementation. The same approach applies to other stdio-based MCP servers, including GitHub, Slack, and filesystem integrations.

DuckDuckGo Browser MCP Server

The DuckDuckGo browser MCP server is an open-source MCP implementation that exposes web search capabilities as callable tools. It allows language models to perform search queries and retrieve structured results through the MCP protocol.

The server runs as a stdio-based process and provides tools such as ddg_search for executing web searches. When invoked, the tool returns structured search results that LLMs can use to answer questions or complete tasks that require current web information.

We use this server as the reference implementation because it does not require additional secrets or external configuration. The only requirement is defining the MCP command in config.yaml, which makes it straightforward for us to deploy and test on Clarifai.

If you’d like to build a custom MCP server from scratch with your own tools and logic, this guide walks through that process using FastMCP.

Now that we have defined the reference server, let’s start.

Set Up the Environment

Install the Clarifai Python SDK:

Set your Clarifai Personal Access Token as an environment variable. Retrieve your PAT from the security settings in your Clarifai account.

Clone the runners-examples repository and navigate to the browser MCP server directory:

The directory contains the deployment files:

  • config.yaml: Deployment configuration and MCP server specification
  • 1/model.py: Model class implementation
  • requirements.txt: Python dependencies

Configure the Deployment

Before uploading, update config.yaml with your Clarifai model identifiers and compute settings. This file defines the model metadata, MCP server startup command, and resource requirements. Clarifai uses it to start the MCP server, allocate compute, and expose the server’s tools through the model endpoint.

The mcp_server section defines how the MCP server process is started. command specifies the executable, and args lists the arguments passed to that executable. In this example, uvx duckduckgo-mcp-server starts the DuckDuckGo MCP server as a stdio-based process.

The model implementation in 1/model.py inherits from StdioMCPModelClass:

StdioMCPModelClass starts the process defined in config.yaml, discovers the available tools through the MCP protocol, and exposes those tools through the deployed model endpoint. No additional implementation is required beyond inheriting from StdioMCPModelClass.

The DuckDuckGo MCP server runs on CPU and requires minimal resources.

Upload & Deploy MCP Server

Upload the MCP server using the Clarifai CLI:

The –skip_dockerfile flag is required when uploading MCP servers. This command packages the model directory and uploads it to your Clarifai account.

After uploading your MCP server, deploy it on compute so it can run and serve tool requests.

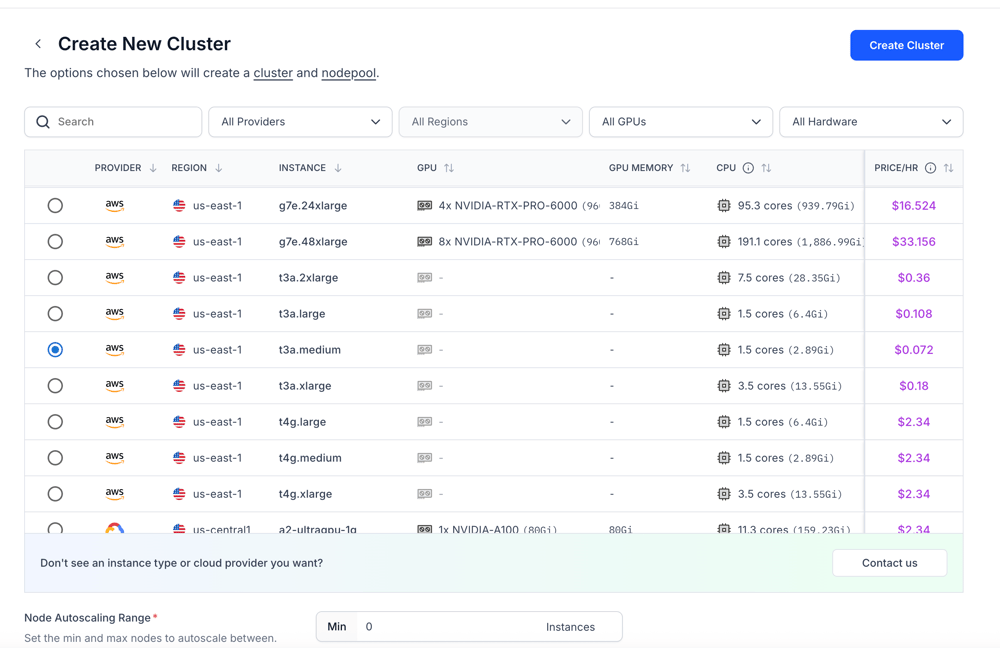
Go to the Compute section and create a new cluster. You will see a list of available instances across different providers and regions, along with their hardware specifications.

Each instance shows:

  • Provider
  • Region
  • Instance type
  • GPU and GPU memory
  • CPU and system memory
  • Hourly price

Screenshot 2026-02-24 at 10.47.09 PM

Select an instance based on the resource requirements you defined in your config.yaml file. For example, if you specified certain CPU and memory limits, choose an instance that satisfies or exceeds those values. Most MCP servers run as lightweight stdio processes, so GPU is typically not required unless your server explicitly depends on it.

After selecting the instance, configure the node pool. You can set autoscaling parameters such as minimum and maximum replicas based on your expected workload.

Finally, create the cluster and node pool, then deploy your MCP server to the selected compute. Clarifai will start the server using the command defined in your config.yaml and expose its tools through the deployed model endpoint.

You can follow the guide to learn how to create your dedicated compute environment and deploy your MCP server to the platform.

Using the Deployed MCP Server

Once deployed, we can interact with the MCP server using the FastMCP client. The client connects to the Clarifai endpoint and discovers the available tools.

Replace the URL with your deployed MCP server endpoint.

This client establishes an HTTP connection to the deployed MCP endpoint and retrieves the tool definitions exposed by the DuckDuckGo server. The list_tools() call confirms that the server is running and that its tools are available for invocation.

Integrate with LLMs

The tools exposed by your deployed MCP server can be used with any LLM that supports function calling. Configure your MCP client and OpenAI-compatible client to connect to your Clarifai MCP endpoint so the model can discover and invoke the available tools.


Your MCP server is now deployed as an API endpoint on Clarifai, and its tools can be accessed and invoked from any compatible LLM through the MCP client.

Frequently Asked Questions (FAQs)

  • Can I deploy any MCP server using this method?

    Yes. As long as the MCP server runs as a stdio-based process, it can be defined in the mcp_server section of config.yaml. Update the command and arguments, upload the model, and the server will be exposed through its own endpoint.

  • Do MCP servers require Docker to deploy?

    No. When uploading MCP servers using the Clarifai CLI, the –skip_dockerfile flag allows the deployment without requiring a custom Dockerfile.

  • Can I use deployed MCP servers with any LLM?

    Yes. Any LLM that supports function calling or tool calling can use the tools exposed by a deployed MCP server. The tools must be formatted according to the model’s function calling schema.

  • Do MCP servers require API keys?

    It depends on the server implementation. Some public MCP servers, such as the DuckDuckGo example used in this guide, do not require additional secrets. Others may require API credentials defined in environment variables or configuration.

Closing Thoughts

We converted a stdio based MCP server into a publicly accessible API endpoint on Clarifai. Its tools can now be discovered and invoked by any LLM that supports function calling.

This approach lets you move MCP servers from local development into stable, shareable infrastructure without changing their core implementation. If a server runs over stdio, it can be packaged, deployed, and exposed through Clarifai.

You can now deploy your own MCP servers, connect them to your models, and extend your LLM applications with custom tools or external integrations. For more examples, explore the runners-examples repository.


LLM Model Architecture Explained: Transformers to MoE


Introduction

Large language models (LLMs) have evolved from simple statistical language predictors into intricate systems capable of reasoning, synthesizing information and even interacting with external tools. Yet most people still see them as auto‑complete engines rather than the modular, evolving architectures they’ve become. Understanding how these models are built is vital for anyone deploying AI: it clarifies why certain models perform better on long documents or multi‑modal tasks and how you can adapt them with minimal compute using tools like Clarifai.

Quick Summary

Question: What is LLM architecture and why should we care?
Answer: Modern LLM architectures are layered systems built on transformers, sparse experts and retrieval systems. Understanding their mechanics—how attention works, why mixture‑of‑experts (MoE) layers route tokens efficiently, how retrieval‑augmented generation (RAG) grounds responses—helps developers choose or customize the right model. Clarifai’s platform simplifies many of these complexities by offering pre‑built components (e.g., MoE‑based reasoning models, vector databases and local inference runners) for efficient deployment.

Quick Digest

  • Transformers replaced recurrent networks to model long sequences via self‑attention.
  • Efficiency innovations such as Mixture‑of‑Experts, FlashAttention and Grouped‑Query Attention push context windows to hundreds of thousands of tokens.
  • Retrieval‑augmented systems like RAG and GraphRAG ground LLM responses in up‑to‑date knowledge.
  • Parameter‑efficient tuning methods (LoRA, QLoRA, DCFT) let you customize models with minimal hardware.
  • Reasoning paradigms have progressed from Chain‑of‑Thought to Graph‑of‑Thought and multi‑agent systems, pushing LLMs towards deeper reasoning.
  • Clarifai’s platform integrates these innovations with fairness dashboards, vector stores, LoRA modules and local runners to simplify deployment.

1. Evolution of LLM Architecture: From RNNs to Transformers

How Did We Get Here?

Early language models relied on n‑grams and recurrent neural networks (RNNs) to predict the next word, but they struggled with long dependencies. In 2017, the transformer architecture introduced self‑attention, enabling models to capture relationships across entire sequences while permitting parallel computation. This breakthrough triggered a cascade of innovations.

Quick Summary

Question: Why did transformers replace RNNs?
Answer: RNNs process tokens sequentially, which hampers long‑range dependencies and parallelism. Transformers use self‑attention to weigh how every token relates to every other, capturing context efficiently and enabling parallel training.

Expert Insights

  • Transformers unlocked scaling: By decoupling sequence modeling from recursion, transformers can scale to billions of parameters, providing the foundation for GPT‑style LLMs.
  • Clarifai perspective: Clarifai’s AI Trends report notes that the transformer has become the default backbone across domains, powering models from text to video. Their platform offers an intuitive interface for developers to explore transformer architectures and fine‑tune them for specific tasks.

Discussion

Transformers incorporate multi‑head attention and feed‑forward networks. Each layer allows the model to attend to different positions in the sequence, encode positional relationships and then transform outputs via feed‑forward networks. Later sections dive into these components, but the key takeaway is that self‑attention replaced sequential RNN processing, enabling LLMs to learn long‑range dependencies in parallel. The ability to process tokens simultaneously is what makes large models such as GPT‑3 possible.

As you’ll see, the transformer is still at the heart of most architectures, but efficiency layers like mixture‑of‑experts and sparse attention have been grafted on top to mitigate its quadratic complexity.

2. Fundamentals of Transformer Architecture

How Does Transformer Attention Work?

The self‑attention mechanism is the core of modern LLMs. Each token is projected into query, key and value vectors; the model computes similarity between queries and keys to decide how much each token should attend to others. This mechanism runs in parallel across multiple “heads,” letting models capture diverse patterns.

Quick Summary

Question: What components form a transformer?
Answer: A transformer consists of stacked layers of multi‑head self‑attention, feed‑forward networks (FFN), and positional encodings. Multi‑head attention computes relationships between all tokens, FFN applies token‑wise transformations, and positional encoding ensures sequence order is captured.

Expert Insights

  • Efficiency matters: FlashAttention is a low‑level algorithm that fuses softmax operations to reduce memory usage and boost performance, enabling 64K‑token contexts. Grouped‑Query Attention (GQA) further reduces key/value cache by sharing key and value vectors among query heads.
  • Positional encoding innovations: Rotary Positional Encoding (RoPE) rotates embeddings in complex space to encode order, scaling to longer sequences. Techniques like YARN stretch RoPE to 128K tokens without retraining.
  • Clarifai integration: Clarifai’s inference engine leverages FlashAttention and GQA under the hood, allowing developers to serve models with long contexts while controlling compute costs.

How Positional Encoding Evolves

Transformers do not have a built‑in notion of sequence order, so they add positional encodings. Traditional sinusoids embed token positions; RoPE rotates embeddings in complex space and supports extended contexts. YARN modifies RoPE to stretch models trained with a 4k context to handle 128k tokens. Clarifai users benefit from these innovations by choosing models with extended contexts for tasks like analyzing long legal documents.

Feed‑Forward Networks

Between attention layers, feed‑forward networks apply non‑linear transformations to each token. They expand the hidden dimension, apply activation functions (often GELU or variants), and compress back to the original dimension. While conceptually simple, FFNs contribute significantly to compute costs; this is why later innovations like Mixture‑of‑Experts replace FFNs with smaller expert networks to reduce active parameters while maintaining capacity.

3. Mixture‑of‑Experts (MoE) and Sparse Architectures

What Is a Mixture‑of‑Experts Layer?

A Mixture‑of‑Experts replaces a single feed‑forward network with multiple smaller networks (“experts”) and a router that dispatches tokens to the most appropriate experts. Only a subset of experts is activated per token, achieving conditional computation and reducing runtime.

Quick Summary

Question: Why do we need MoE layers?
Answer: MoE layers drastically increase the total number of parameters (for knowledge storage) while activating only a fraction for each token. This yields models that are both capacity‑rich and compute‑efficient. For example, Mixtral 8×7B has 47B total parameters but uses only ~13B per token.

Expert Insights

  • Performance boost: Mixtral’s sparse MoE architecture outperforms larger dense models like GPT‑3.5, thanks to targeted experts.
  • Clarifai use cases: Clarifai’s industrial customers employ MoE‑based models for manufacturing intelligence and policy drafting; they route domain‑specific queries through specialized experts while minimizing compute.
  • MoE mechanics: Routers analyze incoming tokens and assign them to experts; tokens with similar semantic patterns are processed by the same expert, improving specialization.
  • Other models: Open‑source systems like DeepSeek and Mistral also use MoE layers to balance context length and cost.

Creative Example

Imagine a manufacturing firm analyzing sensor logs. A dense model might process every log line with the same network, but a MoE model dispatches temperature logs to one expert, vibration readings to another, and chemical data to a third—improving accuracy and reducing compute. Clarifai’s platform allows such domain‑specific expert training through LoRA modules (see Section 6).

Why MoE Matters for EEAT

Mixture‑of‑Experts models often achieve higher factual accuracy thanks to specialized experts, which enhances EEAT. However, routing introduces complexity; mis‑routing tokens can degrade performance. Clarifai mitigates this by providing curated MoE models and monitoring tools to audit expert usage, ensuring fairness and reliability.

4. Sparse Attention and Long‑Context Innovations

Why Do We Need Sparse Attention?

Standard self‑attention scales quadratically with sequence length; for a sequence of length L, computing attention is O(L²). For 100k tokens, this is prohibitive. Sparse attention variants reduce complexity by limiting which tokens attend to which.

Quick Summary

Question: How do models handle millions of tokens efficiently?
Answer: Techniques like Grouped‑Query Attention (GQA) share key/value vectors among query heads, reducing the memory footprint. DeepSeek’s Sparse Attention (DSA) uses a lightning indexer to select top‑k relevant tokens, converting O(L²) complexity to O(L·k). Hierarchical attention (CCA) compresses global context and preserves local detail.

Expert Insights

  • Hierarchical designs: Core Context Aware (CCA) attention splits inputs into global and local branches and fuses them via learnable gates, achieving near‑linear complexity and 3–6× speedups.
  • Compression strategies: ParallelComp splits sequences into chunks, performs local attention, evicts redundant tokens and applies global attention across compressed tokens. Dynamic Chunking adapts chunk size based on semantic similarity to prune irrelevant tokens.
  • State‑space alternatives: Mamba uses selective state‑space models with adaptive recurrences, reducing self‑attention’s quadratic cost to linear time. Mamba 7B matches or exceeds comparable transformer models while maintaining constant memory usage for million‑token sequences.
  • Memory innovations: Artificial Hippocampus Networks combine a sliding window cache with recurrent compression, saving 74% memory and 40.5% FLOPs.
  • Clarifai advantage: Clarifai’s compute orchestration supports models with extended context windows and includes vector stores for retrieval, ensuring that long‑context queries remain efficient.

RAG vs Long Context

Articles often debate whether long‑context models will replace retrieval systems. A recent study notes that OpenAI’s GPT‑4 Turbo supports 128K tokens; Google’s Gemini Flash supports 1M tokens; and DeepSeek matches this with 128K. However, large contexts do not guarantee that models can find relevant information. They still face attention challenges and compute costs. Clarifai recommends combining long contexts with retrieval, using RAG to retrieve only relevant snippets instead of stuffing entire documents.

5. Retrieval‑Augmented Generation (RAG) and GraphRAG

How Does RAG Ground LLMs?

Retrieval‑Augmented Generation (RAG) improves factual accuracy by retrieving relevant context from external sources before generating an answer. The pipeline ingests data, preprocesses it (tokenization, chunking), stores embeddings in a vector database and retrieves top‑k matches at query time.

Quick Summary

Question: Why is retrieval necessary if context windows are large?
Answer: Even with 100K tokens, models may not find the right information because self‑attention’s cost and limited search capability can hinder effective retrieval. RAG retrieves targeted snippets and grounds outputs in verifiable knowledge.

Expert Insights

  • Process steps: Data ingestion, preprocessing (chunking, metadata enrichment), vectorization, indexing and retrieval form the backbone of RAG.
  • Clarifai features: Clarifai’s platform integrates vector databases and model inference into a single workflow. Their fairness dashboard can monitor retrieval results for bias, while the local runner can run RAG pipelines on‑premises.
  • GraphRAG evolution: GraphRAG uses knowledge graphs to retrieve connected context, not just isolated snippets. It traces relationships through nodes to support multi‑hop reasoning.
  • When to choose GraphRAG: Use GraphRAG when relationships matter (e.g., supply chain analysis), and simple similarity search is insufficient.
  • Limitations: Graph construction requires domain knowledge and may introduce complexity, but its relational context can drastically improve reasoning for tasks like root‑cause analysis.

Creative Example

Suppose you’re building an AI assistant for compliance officers. The assistant uses RAG to pull relevant sections of regulations from multiple jurisdictions. GraphRAG enhances this by connecting laws and amendments via relationships (e.g., “regulation A supersedes regulation B”), ensuring the model understands how rules interact. Clarifai’s vector and knowledge graph APIs make it straightforward to build such pipelines.

6. Parameter‑Efficient Fine‑Tuning (PEFT), LoRA and QLoRA

How Can We Tune Gigantic Models Efficiently?

Fine‑tuning a 70B‑parameter model can be prohibitively expensive. Parameter‑Efficient Fine‑Tuning (PEFT) methods, such as LoRA (Low‑Rank Adaptation), insert small trainable matrices into attention layers and freeze most of the base model.

Quick Summary

Question: What are LoRA and QLoRA?
Answer: LoRA fine‑tunes LLMs by learning low‑rank updates added to existing weights, training only a few million parameters. QLoRA combines LoRA with 4‑bit quantization, enabling fine‑tuning on consumer‑grade GPUs while retaining accuracy.

Expert Insights

  • LoRA advantages: LoRA reduces trainable parameters by orders of magnitude and can be merged into the base model at inference with no overhead.
  • QLoRA benefits: QLoRA stores model weights in 4‑bit precision and trains LoRA adapters, allowing a 65B model to be fine‑tuned on a single GPU.
  • New PEFT methods: Deconvolution in Subspace (DCFT) provides an 8× parameter reduction over LoRA by using deconvolution layers and dynamically controlling kernel size.
  • Clarifai integration: Clarifai offers a LoRA manager to upload, train and deploy LoRA modules. Users can fine‑tune domain‑specific LLMs without full retraining, combine LoRA with quantization for edge deployment and manage adapters through the platform.

Creative Example

Imagine customizing a legal language model to draft privacy policies for multiple countries. Instead of full fine‑tuning, you create LoRA modules for each jurisdiction. The model keeps its core knowledge but adapts to local legal nuances. With QLoRA, you can even run these adapters on a laptop. Clarifai’s API automates adapter deployment and versioning.

7. Reasoning and Prompting Techniques: Chain‑, Tree‑ and Graph‑of‑Thought

How Do We Get LLMs to Think Step by Step?

Large language models excel at predicting next tokens, but complex tasks require structured reasoning. Prompting techniques such as Chain‑of‑Thought (CoT) instruct models to generate intermediate reasoning steps before delivering an answer.

Quick Summary

Question: What are Chain‑, Tree‑ and Graph‑of‑Thought?
Answer: These are prompting paradigms that scaffold LLM reasoning. CoT generates linear reasoning steps; Tree‑of‑Thought (ToT) creates multiple candidate paths and prunes the best; Graph‑of‑Thought (GoT) generalizes ToT into a directed acyclic graph, enabling dynamic branching and merging.

Expert Insights

  • CoT benefits and limits: CoT dramatically improves performance on math and logical tasks but is fragile—errors in early steps can derail the entire chain.
  • ToT innovations: ToT treats reasoning as a search problem; multiple candidate thoughts are proposed, evaluated and pruned, boosting success rates on puzzles like Game‑of‑24 from ~4% to ~74%.
  • GoT power: GoT represents reasoning steps as nodes in a DAG, enabling dynamic branching, aggregation and refinement. It supports multi‑modal reasoning and domain‑specific applications like sequential recommendation.
  • Reasoning stack: The field is evolving from CoT to ToT and GoT, with frameworks like MindMap orchestrating LLM calls and external tools.
  • Massively Decomposed Agentic Processes: The MAKER framework decomposes tasks into micro‑agents and uses multi‑agent voting to achieve error‑free reasoning over millions of steps.
  • Clarifai models: Clarifai’s reasoning models incorporate extended context, mixture‑of‑experts layers and CoT-style prompting, delivering improved performance on reasoning benchmarks.

Creative Example

A question like “How many marbles will Julie have left if she gives half to Bob, buys seven, then loses three?” can be answered by CoT: 1) Julie gives half, 2) buys seven, 3) subtracts three. A ToT approach might propose multiple sequences—perhaps she gives away more than half—and evaluate which path leads to a plausible answer, while GoT might combine reasoning with external tool calls (e.g., a calculator or knowledge graph). Clarifai’s platform allows developers to implement these prompting patterns and integrate external tools via actions, making multi‑step reasoning robust and auditable.

8. Agentic AI and Multi‑Agent Architectures

What Is Agentic AI?

Agentic AI describes systems that plan, decide and act autonomously, often coordinating multiple models or tools. These agents rely on planning modules, memory architectures, tool‑use interfaces and learning engines.

Quick Summary

Question: How does agentic AI work?
Answer: Agentic AI combines reasoning models with memory (vector or semantic), interfaces to invoke external tools (APIs, databases), and reinforcement learning or self‑reflection to improve over time. These agents can break down tasks, retrieve information, call functions and compose answers.

Expert Insights

  • Components: Planning modules decompose tasks; memory modules store context; tool‑use interfaces execute API calls; reinforcement or self‑reflective learning adapts strategies.
  • Benefits and challenges: Agentic systems offer operational efficiency and adaptability but raise safety and alignment challenges.
  • ReMemR1 agents: ReMemR1 introduces revisitable memory and multi‑level reward shaping, allowing agents to revisit earlier evidence and achieve superior long‑context QA performance.
  • Massive decomposition: The MAKER framework decomposes long tasks into micro‑agents and uses voting schemes to maintain accuracy over millions of steps.
  • Clarifai tools: Clarifai’s local runner supports agentic workflows by running models and LoRA adapters locally, while their fairness dashboard helps monitor agent behavior and enforce governance.

Creative Example

Consider a travel‑planning agent that books flights, finds hotels, checks visa requirements and monitors weather. It must plan subtasks, recall past decisions, call booking APIs and adapt if plans change. Clarifai’s platform integrates vector search, tool invocation and RL‑based fine‑tuning so that developers can build such agents with built‑in safety checks and fairness auditing.

9. Multi‑Modal LLMs and Vision‑Language Models

How Do LLMs Understand Images and Audio?

Multi‑modal models process different types of input—text, images, audio—and combine them in a unified framework. They typically use a vision encoder (e.g., ViT) to convert images into “visual tokens,” then align these tokens with language embeddings via a projector and feed them to a transformer.

Quick Summary

Question: What makes multi‑modal models special?
Answer: Multi‑modal LLMs, such as GPT‑4V or Gemini, can reason across modalities by processing visual and textual information simultaneously. They enable tasks like visual question answering, captioning and cross‑modal retrieval.

Expert Insights

  • Architecture: Vision tokens from encoders are combined with text tokens and fed into a unified transformer.
  • Context windows: Some multi‑modal models support extremely long contexts (1M tokens for Gemini 2.0), enabling them to analyze whole documents or codebases.
  • Clarifai support: Clarifai provides image and video models that can be paired with LLMs to build custom multi‑modal solutions for tasks like product categorization or defect detection.
  • Future direction: Research is moving toward audio and 3‑D models, and Mamba‑based architectures may further reduce costs for multi‑modal tasks.

Creative Example

Imagine an AI assistant for an e‑commerce site that analyzes product photos, reads their descriptions and generates marketing copy. It uses a vision encoder to extract features from images, merges them with textual descriptions and produces engaging text. Clarifai’s multi‑modal APIs streamline such workflows, while LoRA modules can tune the model to the brand’s tone.

10. Safety, Fairness and Governance in LLM Architecture

Why Should We Care About Safety?

Powerful language models can propagate biases, hallucinate facts or violate regulations. As AI adoption accelerates, safety and fairness become non‑negotiable requirements.

Quick Summary

Question: How do we ensure LLM safety and fairness?
Answer: By auditing models for bias, grounding outputs via retrieval, using human feedback to align behavior and complying with regulations (e.g., EU AI Act). Tools like Clarifai’s fairness dashboard and governance APIs assist in monitoring and controlling models.

Expert Insights

  • Fairness dashboards: Clarifai’s platform provides fairness and governance tools that audit outputs for bias and facilitate compliance.
  • RLHF and DPO: Reinforcement learning from human feedback teaches models to align with human preferences, while Direct Preference Optimization simplifies the process.
  • RAG for safety: Retrieval‑augmented generation grounds answers in verifiable sources, reducing hallucinations. Graph‑augmented retrieval further improves context linkage.
  • Risk mitigation: Clarifai recommends domain‑specific models and RAG pipelines to reduce hallucinations and ensure outputs adhere to regulatory standards.

Creative Example

A healthcare chatbot must not hallucinate diagnoses. By using RAG to retrieve validated medical guidelines and checking outputs with a fairness dashboard, Clarifai helps ensure that the bot provides safe and unbiased advice while complying with privacy regulations.

11. Hardware and Energy Efficiency: Edge Deployment and Local Runners

How Do We Run LLMs Locally?

Deploying LLMs on edge devices improves privacy and latency but requires reducing compute and memory demands.

Quick Summary

Question: How can we deploy models on edge hardware?
Answer: Techniques like 4‑bit quantization and low‑rank fine‑tuning shrink model size, while innovations such as GQA reduce KV cache usage. Clarifai’s local runner lets you serve models (including LoRA‑adapted versions) on on‑premises hardware.

Expert Insights

  • Quantization: Methods like GPTQ and AWQ reduce weight precision from 16‑bit to 4‑bit, shrinking model size and enabling deployment on consumer hardware.
  • LoRA adapters for edge: LoRA modules can be merged into quantized models without overhead, meaning you can fine‑tune once and deploy anywhere.
  • Compute orchestration: Clarifai’s orchestration helps schedule workloads across CPUs and GPUs, optimizing throughput and energy consumption.
  • State‑space models: Mamba’s linear complexity may further reduce hardware costs, making million‑token inference feasible on smaller clusters.

Creative Example

A retailer wants to analyze customer interactions on in‑store devices to personalize offers without sending data to the cloud. They use a quantized and LoRA‑adapted model running on the Clarifai local runner. The device processes audio/text, runs RAG on a local vector store and produces recommendations in real time, preserving privacy and saving bandwidth.

12. Emerging Research and Future Directions

What New Directions Are Researchers Exploring?

The pace of innovation in LLM architecture is accelerating. Researchers are pushing models toward longer contexts, deeper reasoning and energy efficiency.

Quick Summary

Question: What’s next for LLMs?
Answer: Emerging trends include ultra‑long context modeling, state‑space models like Mamba, massively decomposed agentic processes, revisitable memory agents, advanced retrieval and new parameter‑efficient methods.

Expert Insights

  • Ultra‑long context modeling: Techniques such as hierarchical attention (CCA), chunk‑based compression (ParallelComp) and dynamic selection push context windows into the millions while controlling compute.
  • Selective state‑space models: Mamba generalizes state‑space models with input‑dependent transitions, achieving linear‑time complexity. Variants like Mamba‑3 and hybrid architectures (e.g., Mamba‑UNet) are appearing across domains.
  • Massively decomposed processes: The MAKER framework achieves zero errors in tasks requiring over one million reasoning steps by decomposing tasks into micro‑agents and using ensemble voting.
  • Revisitable memory agents: ReMemR1 introduces memory callbacks and multi‑level reward shaping, mitigating irreversible memory updates and improving long‑context QA.
  • New PEFT methods: Deconvolution in Subspace (DCFT) reduces parameters by 8× relative to LoRA, hinting at even more efficient tuning.
  • Evaluation benchmarks: Benchmarks like NoLiMa test long‑context reasoning where there is no literal keyword match, spurring innovations in retrieval and reasoning.
  • Clarifai R&D: Clarifai is researching Graph‑augmented retrieval and agentic controllers integrated with their platform. They plan to support Mamba‑based models and implement fairness‑aware LoRA modules.

Creative Example

Consider a legal research assistant tasked with synthesizing case law across multiple jurisdictions. Future systems might combine GraphRAG to retrieve case relationships, a Mamba‑based long‑context model to read entire judgments, and a multi‑agent framework to decompose tasks (e.g., summarization, citation analysis). Clarifai’s platform will provide the tools to deploy this agent on secure infrastructure, monitor fairness, and maintain compliance with evolving regulations.

Frequently Asked Questions (FAQs)

  1. Is the transformer architecture obsolete?
    No. Transform ers remain the backbone of modern LLMs, but they’re being enhanced with sparsity, expert routing and state‑space innovations.
  2. Are retrieval systems still needed when models support million‑token contexts?
    Yes. Large contexts don’t guarantee models will locate relevant facts. Retrieval (RAG or GraphRAG) narrows the search space and grounds responses.
  3. How can I customize a model without retraining it fully?
    Use parameter‑efficient tuning like LoRA or QLoRA. Clarifai’s LoRA manager helps you upload, train and deploy small adapters.
  4. What’s the difference between Chain‑, Tree‑ and Graph‑of‑Thought?
    Chain‑of‑Thought is linear reasoning; Tree‑of‑Thought explores multiple candidate paths; Graph‑of‑Thought allows dynamic branching and merging, enabling complex reasoning.
  5. How do I ensure my model is fair and compliant?
    Use fairness audits, retrieval grounding and alignment techniques (RLHF, DPO). Clarifai’s fairness dashboard and governance APIs facilitate monitoring and compliance.
  6. What hardware do I need to run LLMs on the edge?
    Quantized models (e.g., 4‑bit) and LoRA adapters can run on consumer GPUs. Clarifai’s local runner provides an optimized environment for local deployment, while Mamba‑based models may further reduce hardware requirements.

Conclusion

Large language model architecture is advancing rapidly, blending transformer fundamentals with mixture‑of‑experts, sparse attention, retrieval and agentic AI. Efficiency and safety are driving innovation: new methods reduce computation while grounding outputs in verifiable knowledge, and agentic systems promise autonomous reasoning with built‑in governance. Clarifai sits at the nexus of these trends—its platform offers a unified hub for hosting modern architectures, customizing models via LoRA, orchestrating compute workloads, enabling retrieval and ensuring fairness. By understanding how these components interconnect, you can confidently choose, tune and deploy LLMs for your business


Budgets, Throttling & Model Tiering


Introduction

Generative AI is no longer just a playground experiment—it’s the backbone of customer support agents, content generation tools, and industrial analytics. By early 2026, enterprise AI budgets more than doubled compared with two years prior. The shift from one‑time training costs to continuous inference means that every user query triggers compute cycles and token consumption. In other words, artificial intelligence now carries a real monthly invoice. Without deliberate cost controls, teams run the risk of runaway bills, misaligned spending, or even “denial‑of‑wallet” attacks, where adversaries exploit expensive models while staying under basic rate limits.

This article offers a comprehensive framework for controlling AI feature costs. You’ll learn why budgets matter, how to design them, when to throttle usage, how to tier models for cost‑performance trade‑offs, and how to manage AI spend through FinOps governance. Each section provides context, operational detail, reasoning logic, and pitfalls to avoid. Throughout, we integrate Clarifai’s platform capabilities—such as Costs & Budget dashboards, compute orchestration, and dynamic batching—so you can implement these strategies within your existing AI workflows.

Quick digest: 1) Identify cost drivers and track unit economics; 2) Design budgets with multi‑level caps and alerts; 3) Enforce limits and throttling to prevent runaway consumption; 4) Use tiered models and routers for optimal cost‑performance; 5) Implement strong FinOps governance and monitoring; 6) Learn from failures and prepare for future cost trends.


Understanding AI Cost Drivers and Why Budget Controls Matter

The New Economics of AI

After years of cheap cloud computing, AI has shifted the cost equation. Large language model (LLM) budgets for enterprises have exploded—often averaging $10 million per year for larger organisations. The cost of inference now outstrips training, because every interaction with an LLM burns GPU cycles and energy. Hidden costs lurk everywhere: idle GPUs, expensive memory footprints, network egress fees, compliance work, and human oversight. Tokens themselves aren’t cheap: output tokens can be four times as expensive as input tokens, and API call volume, model choice, fine‑tuning, and retrieval operations all add up. The result? An 88 % gap between planned and actual cloud spending for many companies.

AI cost drivers aren’t static. GPU supply constraints—limited high‑bandwidth memory and manufacturing capacity—will persist until at least 2026, pushing prices higher. Meanwhile, generative AI budgets are growing around 36 % year‑over‑year. As inference workloads become the dominant cost factor, ignoring budgets is no longer an option.

Mapping and Tracking Costs

Effective cost control starts with unit economics. Clarify the cost components of your AI stack:

  • Compute: GPU hours and memory; underutilised GPUs can waste capacity.
  • Tokens: Input/output tokens used in calls to LLM APIs; track cost per inference, cost per transaction, and ROI.
  • Storage and Data Transfer: Fees for storing datasets, model checkpoints, and moving data across regions.
  • Human Factors: The effort of engineers, prompt engineers, and product owners to maintain models.

Clarifai’s Costs & Budget dashboard helps monitor these metrics in real time. It visualises spending across billable operations, models and token types, giving you a single pane of glass to track compute, storage, and token usage. Adopt rigorous tagging so every expense is attributed to a team, feature, or project.

When and Why to Budget

If you see rising token usage or GPU spend without a corresponding increase in value, implement a budget immediately. A decision tree might look like this:

  • No visibility into costs? → Start tagging and tracking unit economics via dashboards.
  • Unexpected spikes in token consumption? → Analyse prompt design and reduce output length or adopt caching.
  • Compute cost growth outpaces user growth? → Right‑size models or consider quantisation and pruning.
  • Plans to scale features significantly? → Design a budget cap and forecasting model before launching.

Trade‑offs are inevitable. Premium LLMs charge $15–$75 per million tokens, while economy models cost $0.25–$4. Higher accuracy might justify the cost for mission‑critical tasks but not for simple queries.

Pitfalls and Misconceptions

It’s a myth that AI becomes cheap once trained—ongoing inference costs dominate. Uniform rate limits don’t protect budgets; attackers can issue a few high‑cost requests and drain resources. Auto‑scaling may seem like a solution but can backfire, leaving expensive GPUs idle while waiting for tasks.

Expert Insights

  • FinOps Foundation: Recommend setting strict usage limits, quotas and throttling.
  • CloudZero: Encourage creating dedicated cost centres and aligning budgets with revenue.
  • Clarifai Engineers: Emphasise unified compute orchestration and built‑in cost controls for budgets, alerts and scaling.

Quick Summary

Question: Why are AI budgets critical in 2026?
Summary: AI costs are dominated by inference and hidden expenses. Budgets help map unit economics, plan for GPU shortages and avoid the “denial‑of‑wallet” scenario. Monitoring tools like Clarifai’s Costs & Budget dashboard provide real‑time visibility and allow teams to assign costs accurately.


Designing AI Budgets and Forecasting Frameworks

The Role of Budgets in AI Strategy

An AI budget is more than a cap; it’s a statement of intent. Budgets allocate compute, tokens and talent to features with the highest expected ROI, while capping experimentation to protect margins. Many organisations move new projects into AI sandboxes, where dedicated environments have smaller quotas and auto‑shutdown policies to prevent runaway costs. Budgets can be hierarchical: global caps cascade down to team, feature or user levels, as implemented in tools like the Bifrost AI Gateway. Pricing models vary—subscription, usage‑based, or custom. Each requires guardrails such as rate limits, budget caps and procurement thresholds.

Building a Budget Step‑by‑Step

  1. Profile Workloads: Estimate token volume and compute hours based on expected traffic. Clarifai’s historical usage graphs can be used to extrapolate future demand.
  2. Map Costs to Value: Align AI spend with business outcomes (e.g., revenue uplift, customer satisfaction).
  3. Forecast Scenarios: Model different growth scenarios (steady, peak, worst‑case). Factor in the rising cost of GPUs and the possibility of price hikes.
  4. Define Budgets and Limits: Set global, team and feature budgets. For example, allocate a monthly budget of $2K for a pilot and define soft/hard limits. Use Clarifai’s budgeting suite to set these thresholds and automate alerts.
  5. Establish Alerts: Configure thresholds at 70 %, 100 % and 120 % of the budget. Alerts should go to product owners, finance and engineering.
  6. Enforce Budgets: Decide enforcement actions when budgets are reached: throttle requests, block access, or route to cheaper models.
  7. Review and Adjust: At the end of each cycle, compare forecasted vs. actual spend and adjust budgets accordingly.

Clarifai’s platform supports these steps with forecasting dashboards, project‑level budgets and automated alerts. The FinOps & Budgeting suite even models future spend using historical data and machine learning.

Choosing the Right Budgeting Approach

  • Variable demand? Choose a usage‑based budget with dynamic caps and alerts.
  • Predictable training jobs? Use reserved instances and commitment discounts to secure lower per‑hour rates.
  • Burst workloads? Pair a small reserved footprint with on‑demand capacity and spot instances.
  • Heavy experimentation? Create a separate sandbox budget that auto‑shuts down after each experiment.

The trade‑off between soft and hard budgets is crucial. Soft budgets trigger alerts but allow limited overage—useful for customer‑facing systems. Hard budgets enforce strict caps; they protect finances but may degrade experience if triggered mid‑session.

Common Budgeting Mistakes

Under‑estimating token consumption is common; output tokens can be four times more expensive than input tokens. Uniform budgets fail to recognise varying request costs. Static budgets set in January rarely reflect pricing changes or unplanned adoption later in the year. Finally, budgets without an enforcement plan are meaningless—alerts alone won’t stop runaway costs.

The 4‑S Budget System

To simplify budgeting, adopt the 4‑S Budget System:

  • Scope: Define and prioritise features and workloads to fund.
  • Segment: Break budgets down into global, team and user levels.
  • Signal: Configure multi‑level alerts (pre‑warning, limit reached, overage).
  • Shut Down/Shift: Enforce budgets by either pausing non‑critical workloads or shifting to more economical models when limits hit.

The 4‑S system ensures budgets are comprehensive, enforceable and flexible.

Expert Insights

  • BetterCloud: Recommends profiling workloads and mapping costs to value before selecting pricing models.
  • FinOps Foundation: Advocates combining budgets with anomaly detection.
  • Clarifai: Offers forecasting and budgeting tools that integrate with billing metrics.

Quick Summary

Question: How do I design AI budgets that align with value and prevent overspending?
Summary: Start with workload profiling and cost‑to‑value mapping. Forecast multiple scenarios, define budgets with soft and hard limits, set alerts at key thresholds, and enforce via throttling or routing. Adopt the 4‑S Budget System to scope, segment, signal and shut down or shift workloads. Use Clarifai’s budgeting tools for forecasting and automation.


Implementing Usage Limits, Quotas and Throttling

Why Limits and Throttles Are Essential

AI workloads are unpredictable; a single chat session can trigger dozens of LLM calls, causing costs to skyrocket. Traditional rate limits (e.g., requests per second) protect performance but do not protect budgets—high‑cost operations can slip through. FinOps Foundation guidance emphasises the need for usage limits, quotas and throttling mechanisms to keep consumption aligned with budgets.

Implementing Limits and Throttles

  1. Define Quotas: Assign quotas per API key, user, team or feature for API calls, tokens and GPU hours. For instance, a customer support bot might have a daily token quota, while a research team’s training job gets a GPU‑hour quota.
  2. Choose a Rate‑Limiting Algorithm: Uniform rate limits allocate a constant number of requests per second. For cost control, adopt token‑bucket algorithms that measure budget units (e.g., 1 unit = $0.001) and charge each request based on estimated and actual cost. Excessive requests are either delayed (soft throttle) or rejected (hard throttle).
  3. Throttling for Peak Hours: During peak business hours, reduce the number of inference requests to prioritise cost efficiency over latency. Non‑critical workloads can be paused or queued.
  4. Cost‑Aware Limits: Apply dynamic rate limiting based on model tier or usage pattern—premium models might have stricter quotas than economy models. This ensures that high‑cost calls are limited more aggressively.
  5. Alerts and Monitoring: Combine limits with anomaly detection. Set alerts when token consumption or GPU hours spike unexpectedly.
  6. Enforcement: When limits are hit, enforcement options include: downgrading to a cheaper model tier, queueing requests, or blocking access. Clarifai’s compute orchestration supports these actions by dynamically scaling inference pipelines and routing to cost‑efficient models.

Deciding How to Limit

If your application is customer‑facing and latency‑sensitive, choose soft throttles and send proactive messages when the system is busy. For internal experiments, enforce hard limits—cost overages provide little benefit. When budgets approach caps, automatically downgrade to a cheaper model tier or serve cached responses. Use cost‑aware rate limiting: allocate more budget units to low‑cost operations and fewer to expensive operations. Consider whether to implement global vs. per‑user throttles: global throttles protect infrastructure, while per‑user throttles ensure fairness.

Mistakes to Avoid

Uniform requests‑per‑second limits are insufficient; they can be bypassed with fewer, high‑cost requests. Heavy throttling may degrade user experience, leading to abandoned sessions. Autoscaling is not a panacea—LLMs often have memory footprints that don’t scale down quickly. Finally, limits without monitoring can cause silent failures; always pair rate limits with alerting and logging.

The TIER‑L System

To structure usage control, implement the TIER‑L system:

  • Threshold Definitions: Set quotas and budget units for requests, tokens and GPU hours.
  • Identify High‑Cost Requests: Classify calls by cost and complexity.
  • Enforce Cost‑Aware Rate Limiting: Use token‑bucket algorithms that deduct budget units proportionally to cost.
  • Route to Cheaper Models: When budgets near limits, downgrade to a lower tier or serve cached results.
  • Log Anomalies: Record all throttled or rejected requests for post‑mortem analysis and continuous improvement.

Expert Insights

  • FinOps Foundation: Insists on combining usage limits, throttling and anomaly detection.
  • Tetrate’s Analysis: Rate limiting must be dynamic and cost‑aware, not just throughput‑based.
  • Denial‑of‑Wallet Research: Highlights token‑bucket algorithms to prevent budget exploitation.
  • Clarifai Platform: Supports rate limiting on pipelines and enforces quotas at model and project levels.

Quick Summary

Question: How should I limit AI usage to avoid runaway costs?
Summary: Set quotas for calls, tokens and GPU hours. Use cost‑aware rate limiting via token‑bucket algorithms, throttle non‑critical workloads, and downgrade to cheaper tiers when budgets near thresholds. Combine limits with anomaly detection and logging. Implement the TIER‑L system to set thresholds, identify costly requests, enforce dynamic limits, route to cheaper models, and log anomalies.


Model Tiering and Routing for Cost–Performance Optimization

The Rationale for Tiering

All models are not created equal. Premium LLMs deliver high accuracy and context length but can cost $15–$75 per million tokens, while mid‑tier models cost $3–$15 and economy models $0.25–$4. Meanwhile, model selection and fine‑tuning account for 10–25 % of AI budgets. To manage costs, teams increasingly adopt tiering—routing simple queries to cheaper models and reserving premium models for complex tasks. Many enterprises now deploy model routers that automatically switch between tiers and have achieved 30–70 % cost reductions.

Building a Tiered Architecture

  1. Classify Queries: Use heuristics, user metadata, or classifier models to determine query complexity and required accuracy.
  2. Map to Tiers: Align classes with model tiers. For example:
    • Economy tier: Simple lookups, FAQ answers.
    • Mid‑tier: Customer support, basic summarisation.
    • Premium tier: Regulatory or high‑stakes content requiring nuance and reliability.
  3. Implement a Router: Deploy a model router that receives requests, evaluates classification and budget state, and forwards to the appropriate model. Track cost per request and maintain budgets at global, user and application levels; throttle or downgrade when budgets approach limits.
  4. Integrate Caching: Use semantic caching to store responses to recurring queries, eliminating redundant calls.
  5. Leverage Pre‑Trained Models: Fine‑tuning only high‑value intents and using pre‑trained models for the rest can reduce training costs by up to 90 %.
  6. Use Clarifai’s Orchestration: Clarifai’s compute orchestration offers dynamic batching, caching, and GPU‑level scheduling; this allows multi‑model pipelines where requests are automatically routed and load is balanced across GPUs.

Deciding When to Tier

If query classification indicates low complexity, route to an economy model; if budgets near caps, downgrade to cheaper tiers across the board. When dealing with high‑stakes information, choose premium models regardless of cost but cache the result for future re‑use. Use open‑source or fine‑tuned models when accuracy requirements are moderate and data privacy is a concern. Evaluate whether to host models yourself or use API‑based services; self‑hosting may reduce long‑term cost but increases operational overhead.

Missteps in Tiering

Using premium models for routine tasks wastes money. Fine‑tuning every use case drains budgets—only fine‑tune high‑value intents. Cheap models may produce inferior output; always implement a fallback mechanism to upgrade to a higher tier when the quality is insufficient. Relying solely on a router can create single points of failure; plan for redundancy and monitor for anomalous routing patterns.

S.M.A.R.T. Tiering Matrix

The S.M.A.R.T. Tiering Matrix helps decide which model to use:

  • Simplicity of Query: Evaluate input length and complexity.
  • Model Cost: Consider per‑token or per‑minute pricing.
  • Accuracy Requirement: Assess tolerance for hallucinations and content risk.
  • Route Decision: Map to the appropriate tier.
  • Thresholds: Define budget and latency thresholds for switching tiers.

Apply the matrix to each request so you can dynamically optimise cost vs. quality. For example, a low‑complexity query with moderate accuracy requirement might go to a mid‑tier model until the monthly budget hits 80 %, then downgrade to an economy model.

Expert Insights

  • MindStudio Model Router: Reports that cost‑aware routing yields 30–70 % savings.
  • Holori Guide: Premium models cost much more than economy models; only use them when the task demands it.
  • Research on Fine‑Tuning: Pre‑trained models reduce training cost by up to 90 %.
  • Clarifai Platform: Offers dynamic batching and caching in compute orchestration.

Quick Summary

Question: How can I balance cost and performance across different models?
Summary: Classify queries and map them to model tiers (economy, mid, premium). Use a router to dynamically select the right model and enforce budgets at multiple levels. Integrate caching and pre‑trained models to reduce costs. Follow the S.M.A.R.T. Tiering Matrix to evaluate simplicity, cost, accuracy, route and thresholds for each request.


Operational FinOps Practices and Governance for AI Cost Control

Why FinOps Matters for AI

AI cost management is a cross‑functional responsibility. Finance, engineering, product management and leadership must collaborate. FinOps principles—managing commitments, optimising data transfer, and continuous monitoring—apply to AI. Clarifai’s compute orchestration offers a unified environment with built‑in cost dashboards, scaling policies and governance tools.

Putting FinOps Into Action

  • Rightsize Models and Hardware: Deploy the smallest model or GPU that meets performance requirements to reduce idle capacity. Use dynamic pooling and scheduling so multiple jobs share GPU resources.
  • Commitment Management: Secure reserved instances or purchase commitments when workloads are predictable. Analyse whether savings plans or committed use discounts offer better cost coverage.
  • Negotiating Discounts: Consolidate usage with fewer vendors to negotiate better pricing. Evaluate pay‑as‑you‑go vs. reserved vs. subscription to maximise flexibility and savings.
  • Model Lifecycle Management: Implement CI/CD pipelines with continuous training. Automate retraining triggered by data drift or performance degradation. Archive unused models to free up storage and compute.
  • Data Transfer Optimisation: Locate data and compute resources in the same region and leverage CDNs.
  • Cost Governance: Adopt FOCUS 1.2 or similar standards to unify billing and allocate costs to consuming teams. Implement chargeback or showback models so teams are accountable for their usage. Clarifai’s platform supports project‑level budgets, forecasting and compliance tracking.

FinOps Decision‑Making

Decide whether to invest in reserved capacity vs. on‑demand by analysing workload predictability and price stability. If your workload is steady and long‑term, reserved instances reduce cost. If it is bursty and unpredictable, combining a small reserved base with on‑demand and spot instances offers flexibility. Evaluate the trade‑off between discount level and vendor lock‑in—large commitments can limit agility when switching providers.

FinOps is not only about saving money; it’s about aligning spend with business value. Each feature should be evaluated on cost‑per‑unit and expected revenue or user satisfaction. Leadership should insist that every new AI proposal includes a margin impact estimate.

What FinOps Doesn’t Solve

FinOps practices can’t replace good engineering. If your prompts are inefficient or models are over‑parameterised, no amount of cost allocation will offset waste. Over‑optimising for discounts may trap you in long‑term contracts, hindering innovation. Ignoring data transfer costs and compliance requirements can create unforeseen liabilities.

The B.U.I.L.D. Governance Model

To ensure comprehensive governance, adopt the B.U.I.L.D. model:

  • Budgets Aligned with Value: Assign budgets based on expected business impact.
  • Unit Economics Tracked: Monitor cost per inference, transaction and user.
  • Incentives for Teams: Implement chargeback or showback so teams have skin in the game.
  • Lifecycle Management: Automate deployment, retraining and retirement of models.
  • Data Locality: Minimise data transfer and respect compliance requirements.

B.U.I.L.D. creates a culture of accountability and continuous optimisation.

Expert Insights

  • CloudZero: Advises creating dedicated AI cost centres and aligning budgets with revenue.
  • FinOps Foundation: Suggests combining commitment management, data transfer optimisation and proactive cost monitoring.
  • Clarifai: Provides unified orchestration, cost dashboards and budget policies.

Quick Summary

Question: How do I govern AI costs across teams?
Summary: FinOps involves rightsizing models, managing commitments, negotiating discounts, implementing CI/CD for models, and optimising data transfer. Governance frameworks like B.U.I.L.D. align budgets with value, track unit economics, incentivise teams, manage model lifecycles, and enforce data locality. Clarifai’s compute orchestration and budgeting suite support these practices.


Monitoring, Anomaly Detection and Cost Accountability

The Importance of Continuous Monitoring

Even the best budgets and limits can be undermined by a runaway process or malicious activity. Anomaly detection catches sudden spikes in GPU usage or token consumption that could indicate misconfigured prompts, bugs or denial‑of‑wallet attacks. Clarifai’s cost dashboards break down costs by operation type and token type, offering granular visibility.

Building an Anomaly‑Aware Monitoring System

  • Alert Configuration: Define thresholds for unusual consumption patterns. For instance, alert when daily token usage exceeds 150 % of the seven‑day average.
  • Automated Detection: Use cloud‑native tools like AWS Cost Anomaly Detection or third‑party platforms integrated into your pipeline. Compare current usage against historical baselines and trigger notifications when anomalies are detected.
  • Audit Trails: Maintain detailed logs of API calls, token usage and routing decisions. In a hierarchical budget system, logs should show which virtual key, team or customer consumed budget.
  • Post‑mortem Reviews: When anomalies occur, perform root‑cause analysis. Identify whether inefficient code, unoptimised prompts or user abuse caused the spike.
  • Stakeholder Reporting: Provide regular reports to finance, engineering and leadership detailing cost trends, ROI, anomalies and actions taken.

What to Do When Anomalies Occur

If an anomaly is small and transient, monitor the situation but avoid immediate throttling. If it is significant and persistent, automatically suspend the offending workflow or restrict user access. Distinguish between legitimate usage surges (e.g., successful product launch) and malicious spikes. Apply additional rate limits or model tier downgrades if anomalies persist.

Challenges in Monitoring

Monitoring systems can generate false positives if thresholds are too sensitive, leading to unnecessary throttling. Conversely, high thresholds may allow runaway costs to go undetected. Anomaly detection without context may misinterpret natural growth as abuse. Furthermore, logging and monitoring add overhead; ensure instrumentation doesn’t impact latency.

The AIM Audit Cycle

To handle anomalies systematically, follow the AIM audit cycle:

  • Anomaly Detection: Use statistical or AI‑driven models to flag unusual patterns.
  • Investigation: Quickly triage the anomaly, identify root causes, and evaluate the impact on budgets and service levels.
  • Mitigation: Apply corrective actions—throttle, block, fix code—or adjust budgets. Document lessons learned and update thresholds accordingly.

Expert Insights

  • FinOps Foundation: Recommends combining usage limits with anomaly detection and alerts.
  • Clarifai: Offers interactive cost charts that help visualise anomalies by operation or token type.
  • CloudZero & nOps: Suggest using FinOps platforms for real‑time anomaly detection and accountability.

Quick Summary

Question: How can I detect and respond to cost anomalies in AI workloads?
Summary: Configure alerts and anomaly detection tools to spot unusual usage patterns. Maintain audit logs and perform root‑cause analyses. Use the AIM audit cycle—Detect, Investigate, Mitigate—to ensure anomalies are quickly addressed. Clarifai’s cost charts and third‑party tools help visualise and act on anomalies.


Case Studies, Failure Scenarios and Future Outlook

Learning from Successes and Failures

Real‑world experiences offer the best lessons. Research shows that 70–85 % of generative AI projects fail due to trust issues and human factors, and budgets often double unexpectedly. Hidden cost drivers—like idle GPUs, misconfigured storage and unmonitored prompts—cause waste. To avoid repeating mistakes, we need to dissect both triumphs and failures.

Stories from the Field

  • Success: An enterprise set up an AI sandbox with a $2K monthly budget cap. They defined soft alerts at 70 % and hard limits at 100 %. When the project hit 70 %, Clarifai’s budgeting suite sent alerts, prompting engineers to optimise prompts and implement caching. They stayed within budget and gained insights for future scaling.
  • Failure (Denial‑of‑Wallet): A developer deployed a chatbot with uniform rate limits but no cost awareness. A malicious user bypassed the limits by issuing a few high‑cost prompts and triggered a spike in spend. Without cost‑aware throttling, the company incurred substantial overages. Afterward, they adopted token‑bucket rate limiting and multi‑level quotas.
  • Success: A media company used a model router to dynamically choose between economy, mid‑tier and premium models. They achieved 30–70 % cost reductions while maintaining quality, using caching for repeated queries and downgrading when budgets approached thresholds.
  • Failure: An analytics firm committed to large GPU reservations to secure discounts. When GPU prices fell later in the year, they were locked into higher prices, and their fixed capacity discouraged experimentation. The lesson: balance discounts against flexibility.

Why Projects Fail or Succeed

  • Success Factors: Early budgeting, multi‑layer limits, model tiering, cross‑functional governance, and continuous monitoring.
  • Failure Factors: Lack of cost forecasting, poor communication between teams, reliance on uniform rate limits, over‑commitment to specific hardware, and ignoring hidden costs such as data transfer or compliance.
  • Decision Framework: Before launching new features, apply the L.E.A.R.N. Loop—Limit budgets, Evaluate outcomes, Adjust models/tier, Review anomalies, Nurture cost‑aware culture. This ensures a cycle of continuous improvement.

Misconceptions Exposed

Myth: “AI is cheap after training.” Reality: inference is a recurring operating expense. Myth: “Rate limiting solves cost control.” Reality: cost‑aware budgets and throttling are needed. Myth: “More data always improves models.” Reality: data transfer and storage costs can quickly outstrip benefits.

Future Outlook and Temporal Signals

  • Hardware Trends: GPUs remain scarce and pricey through 2026, but new energy‑efficient architectures may emerge.
  • Regulation: The EU AI Act and other regulations require cost transparency and data localisation, influencing budget structures.
  • FinOps Evolution: Version 2.0 of FinOps frameworks emphasises cost‑aware rate limiting and model tiering; organisations will increasingly adopt AI‑powered anomaly detection.
  • Market Dynamics: Cloud providers continue to introduce new pricing tiers (e.g., monthly PTU) and discounts.
  • AI Agents: By 2026, agentic architectures handle tasks autonomously. These agents consume tokens unpredictably; cost controls must be integrated at the agent level.

Expert Insights

  • FinOps Foundation: Reinforces that building a cost‑aware culture is critical.
  • Clarifai: Demonstrated cost reductions using dynamic pooling and AI‑powered FinOps.
  • CloudZero & Others: Encourage predictive forecasting and cost‑to‑value analysis.

Quick Summary

Question: What lessons can we learn from AI cost control successes and failures?
Summary: Success comes from early budgeting, multi‑layer limits, model tiering, collaborative governance, and continuous monitoring. Failures stem from hidden costs, uniform rate limits, over‑commitment to hardware, and lack of forecasting. The L.E.A.R.N. Loop—Limit, Evaluate, Adjust, Review, Nurture—helps teams iterate and avoid repeating mistakes. Future trends include new hardware, regulations, and FinOps frameworks emphasizing cost‑aware controls.


Frequently Asked Questions (FAQs)

Q1. Why are AI costs so unpredictable?
AI costs depend on variables like token volume, model complexity, prompt length and user behaviour. Output tokens can be several times more expensive than input tokens. A single user query may spawn multiple model calls, causing costs to climb rapidly.

Q2. How do I choose between reserved instances and on‑demand capacity?
If your workload is predictable and long‑term, reserved or committed use discounts offer savings. For bursty workloads, combine a small reserved baseline with on‑demand and spot instances to maintain flexibility.

Q3. What is a Denial‑of‑Wallet attack?
It’s when an attacker sends a small number of high‑cost requests, bypassing simple rate limits and draining your budget. Cost‑aware rate limiting and budgets prevent this by charging requests based on their cost and enforcing limits.

Q4. Does model tiering compromise quality?
Tiering involves routing simple queries to cheaper models while reserving premium models for high‑stakes tasks. As long as queries are classified correctly and fallback logic is in place, quality remains high and costs decrease.

Q5. How often should budgets be reviewed?
Review budgets at least quarterly, or whenever there are major changes in pricing or workload. Compare forecasted vs. actual spend and adjust thresholds accordingly.

Q6. Can Clarifai help me implement these strategies?
Yes. Clarifai’s platform offers Costs & Budget dashboards for real‑time monitoring, budgeting suites for setting caps and alerts, compute orchestration for dynamic batching and model routing, and support for multi‑tenant hierarchical budgets. These tools integrate seamlessly with the frameworks discussed in this article. 


Multi-GPU vs Single-GPU Scaling economics


Introduction—Why scale economics matter more than ever

The modern AI boom is powered by one thing: compute. Whether you’re fine‑tuning a vision model for edge deployment or running a large language model (LLM) in the cloud, your ability to deliver value hinges on access to GPU cycles and the economics of scaling. In 2026 the landscape feels like an arms race. Analysts expect the market for high‑bandwidth memory (HBM) to triple between 2025 and 2028. Lead times for data‑center GPUs stretch over six months. Meanwhile, costs lurk everywhere—from underutilised cards to network egress fees and compliance overhead.

This article isn’t another shallow listicle. Instead, it cuts through the hype to explain why GPU costs explode as AI products scale, how to decide between single‑ and multi‑GPU setups, and when alternative hardware makes sense. We’ll introduce original frameworks—GPU Economics Stack and Scale‑Right Decision Tree—to help your team make confident, financially sound decisions. Throughout, we integrate Clarifai’s compute orchestration and model‑inference capabilities naturally, showing how a modern AI platform can tame costs without sacrificing performance.

Quick digest

  • What drives costs? Scarcity in HBM and advanced packaging; super‑linear scaling of compute; hidden operational overhead.
  • When do single GPUs suffice? Prototyping, small models and latency‑sensitive workloads with limited context.
  • Why choose multi‑GPU? Large models exceeding single‑GPU memory; faster throughput; better utilisation when orchestrated well.
  • How to optimise? Rightsize models, apply quantisation, adopt FinOps practices, and leverage orchestration platforms like Clarifai’s to pool resources.
  • What’s ahead? DePIN networks, photonic chips and AI‑native FinOps promise new cost curves. Staying agile is key.

GPU Supply & Pricing Dynamics—Why are GPUs expensive?

Context: scarcity, not speculation

A core economic reality of 2026 is that demand outstrips supply. Data‑centre GPUs rely on high‑bandwidth memory stacks and advanced packaging technologies like CoWoS. Consumer DDR5 kits that cost US$90 in 2025 now retail at over US$240, and lead times have stretched beyond twenty weeks. Data‑centre accelerators monopolise roughly 70 % of global memory supply, leaving gamers and researchers waiting in line. It’s not that manufacturers are asleep at the wheel; building new HBM factories or 2.5‑D packaging lines takes years. Suppliers prioritise hyperscalers because a single rack of H100 cards priced at US$25 K–US$40 K each can generate over US$400 K in revenue.

The result is predictable: prices soar. Renting a high‑end GPU on cloud providers costs between US$2 and US$10 per hour. Buying a single H100 card costs US$25 K–US$40 K, and an eight‑GPU server can exceed US$400 K. Even mid‑tier cards like an RTX 4090 cost around US$1,200 to buy and US$0.18 per hour to rent on marketplace platforms. Supply scarcity also creates time costs: companies cannot immediately secure cards even when they can pay, because chip vendors require multi‑year contracts. Late deliveries delay model training and product launches, turning time into an opportunity cost.

Operational reality: capex, opex and break‑even math

AI teams face a fundamental decision: own or rent. Owning hardware (capex) means large upfront capital but gives full control and avoids price spikes. Renting (opex) offers flexibility and scales with usage but can be expensive if you run GPUs continuously. A practical break‑even analysis shows that for a single RTX 4090 build (~US$2,200 plus ~US$770 per year in electricity), renting at US$0.18/hr is cheaper unless you run it more than 4–6 hours daily over two years. For high‑end clusters, a true cost of US$8–US$15/hr per GPU emerges once you include power distribution upgrades (US$10 K–US$50 K), cooling (US$15 K–US$100 K) and operational overhead.

To help navigate this, consider the Capex vs Opex Decision Matrix:

  • Utilisation < 4 h/day: Rent. Cloud or marketplace GPUs minimise idle costs and let you choose hardware per job.
  • Utilisation 4–6 h/day for > 18 months: Buy single cards. You’ll break even in the second year, provided you maintain usage.
  • Multi‑GPU or high‑VRAM jobs: Rent. The capital outlay for on‑prem multi‑GPU rigs is steep and hardware depreciates quickly.
  • Baseline capacity + bursts: Hybrid. Own a small workstation for experiments, rent cloud GPUs for big jobs. This is how many Clarifai customers operate today.

elasticity and rationing

Scarcity isn’t just about price—it’s about elasticity. Even if your budget allows expensive GPUs, the supply chain won’t magically produce more chips on your schedule. The triple‑constraint (HBM shortages, advanced packaging and supplier prioritisation) means the market remains tight until at least late 2026. Because supply cannot meet exponential demand, vendors ration units to hyperscalers, leaving smaller teams to scour spot markets. The rational response is to optimise demand: right‑size models, adopt efficient algorithms, and look beyond GPUs.

What this does NOT solve

Hoping that prices will revert to pre‑2022 levels is wishful thinking. Even as new GPUs like Nvidia H200 or AMD MI400 ship later in 2026, supply constraints and memory shortages persist. And buying hardware doesn’t absolve you of hidden costs; power, cooling and networking can easily double or triple your spend.

Expert insights

  • Clarifai perspective: Hyperscalers lock in supply through multi‑year contracts while smaller teams are forced to rent, creating a two‑tier market.
  • Market projections: The data‑centre GPU market is forecast to grow from US$16.94 B in 2024 to US$192.68 B by 2034.
  • Hidden costs: Jarvislabs analysts warn that purchasing an H100 card is only the beginning; facility upgrades and operations can double costs.

Quick summary

Question – Why are GPUs so expensive today?

Summary – Scarcity in high‑bandwidth memory and advanced packaging, combined with prioritisation for hyperscale buyers, drives up prices and stretches lead times. Owning hardware makes sense only at high utilisation; renting is generally cheaper under 6 hours/day. Hidden costs such as power, cooling and networking must be included.

Mathematical & Memory Scaling – When single GPUs hit a wall

Context: super‑linear scaling and memory limits

Transformer‑based models don’t scale linearly. Inference cost is roughly 2 × n × p FLOPs, and training cost is ~6 × p FLOPs per token. Doubling parameters or context window multiplies FLOPs more than fourfold. Memory consumption follows: a practical guideline is ~16 GB VRAM per billion parameters. That means fine‑tuning a 70‑billion‑parameter model demands over 1.1 TB of GPU memory, clearly beyond a single H100 card. As context windows expand from 32 K to 128 K tokens, the key/value cache triple in size, further squeezing VRAM.

Operational strategies: parallelism choices

Once you hit that memory wall, you must distribute your workload. There are three primary strategies:

  1. Data parallelism: Replicate the model on multiple GPUs and split the batch. This scales nearly linearly but duplicates model memory, so it’s suitable when your model fits in a single GPU’s memory but your dataset is large.
  2. Model parallelism: Partition the model’s layers across GPUs. This allows training models that otherwise wouldn’t fit, at the cost of extra communication to synchronise activations and gradients.
  3. Pipeline parallelism: Stages of the model are executed sequentially across GPUs. This keeps all devices busy by overlapping forward and backward passes.

Hybrid approaches combine these methods to balance memory, communication and throughput. Frameworks like PyTorch Distributed, Megatron‑LM or Clarifai’s training orchestration tools support these paradigms.

when splitting becomes mandatory

If your model’s parameter count × 16 GB > available VRAM, model parallelism or pipeline parallelism is non‑negotiable. For example, a 13 B model needs ~208 GB of VRAM; even an H100 with 80 GB cannot host it, so splitting across two or three cards is required. The PDLP algorithm demonstrates that careful grid partitioning yields substantial speedups with minimal communication overhead. However, just adding more GPUs doesn’t guarantee linear acceleration: communication overhead and synchronisation latencies can degrade efficiency, especially without high‑bandwidth interconnects.

What this does NOT solve

Multi‑GPU setups are not a silver bullet. Idle memory slices, network latency and imbalanced workloads often lead to underutilisation. Without careful partitioning and orchestration, the cost of extra GPUs can outweigh the benefits.

Parallelism Selector

To decide which strategy to use, employ the Parallelism Selector:

  • If model size exceeds single‑GPU memory → choose model parallelism (split layers).
  • If dataset or batch size is large but model fits in memory → choose data parallelism (replicate model).
  • If both model and dataset sizes push limits → adopt pipeline parallelism or a hybrid strategy.

Add an extra decision: Check interconnect. If NVLink or InfiniBand isn’t available, the communication cost may negate benefits; consider mid‑tier GPUs or smaller models instead.

Expert insights

  • Utilisation realities: Training GPT‑4 across 25 000 GPUs achieved only 32–36 % utilisation, underscoring the difficulty of maintaining efficiency at scale.
  • Mid‑tier value: For smaller models, GPUs like A10G or T4 deliver better price–performance than H100s.
  • Research breakthroughs: The PDLP distributed algorithm uses grid partitioning and random shuffling to reduce communication overhead.

Quick summary

Question – When do single GPUs hit a wall, and how do we decide on parallelism?

Summary – Single GPUs run out of memory when model size × VRAM requirement exceeds available capacity. Transformers scale super‑linearly: inference costs 2 × tokens × parameters, while training costs ~6 × parameters per token. Use the Parallelism Selector to choose data, model or pipeline parallelism based on memory and batch size. Beware of underutilisation due to communication overhead.

Single‑GPU vs Multi‑GPU Performance & Efficiency

Context: when one card isn’t enough

In the early stages of product development, a single GPU often suffices. Prototyping, debugging and small model training run with minimal overhead and lower cost. Single‑GPU inference can also meet strict latency budgets for interactive applications because there’s no cross‑device communication. But as models grow and data explodes, single GPUs become bottlenecks.

Multi‑GPU clusters, by contrast, can reduce training time from months to days. For example, training a 175 B parameter model may require splitting layers across dozens of cards. Multi‑GPU setups also improve utilisation—clusters maintain > 80 % utilisation when orchestrated effectively, and they process workloads up to 50× faster than single cards. However, clusters introduce complexity: you need high‑bandwidth interconnects (NVLink, NVSwitch, InfiniBand) and distributed storage and must manage inter‑GPU communication.

Operational considerations: measuring real efficiency

Measuring performance isn’t as simple as counting FLOPs. Evaluate:

  • Throughput per GPU: How many tokens or samples per second does each GPU deliver? If throughput drops as you add GPUs, communication overhead may dominate.
  • Latency: Pipeline parallelism adds latency; small batch sizes may suffer. For interactive services with sub‑300 ms budgets, multi‑GPU inference can struggle. In such cases, smaller models or Clarifai’s local runner can run on-device or on mid‑tier GPUs.
  • Utilisation: Use orchestration tools to monitor occupancy. Clusters that maintain > 80 % utilisation justify their cost; underutilised clusters burn cash.

cost‑performance trade‑offs

High utilisation is the economic lever. Suppose a cluster costs US$8/hr per GPU but reduces training time from six months to two days. If time‑to‑market is critical, the payback is clear. For inference, the picture changes: because inference accounts for 80–90 % of spending, throughput per watt matters more than raw speed. It may be cheaper to serve high volumes on well‑utilised multi‑GPU clusters, but low‑volume workloads benefit from single GPUs or serverless inference.

What this does NOT solve

Don’t assume that doubling GPUs halves your training time. Idle slices and synchronisation overhead can waste capacity. Building large on‑prem clusters without FinOps discipline invites capital misallocation and obsolescence; cards depreciate quickly and generational leaps shorten economic life.

Utilisation Efficiency Curve

Plot GPU count on the x‑axis and utilisation (%) on the y‑axis. The curve rises quickly at first, then plateaus and may even decline as communication costs grow. The optimal point—where incremental GPUs deliver diminishing returns—marks your economically efficient cluster size. Orchestration platforms like Clarifai’s compute orchestration can help you operate near this peak by queueing jobs, dynamically batching requests and shifting workloads between clusters.

Expert insights

  • Idle realities: Single GPUs sit idle 70 % of the time on average; clusters maintain 80 %+ utilisation when properly managed.
  • Time vs money: A single GPU would take decades to train GPT‑3, while distributed clusters cut the timeline to weeks or days.
  • Infrastructure: Distributed systems require compute nodes, high‑bandwidth interconnects, storage and orchestration software.

Quick summary

Question – What are the real performance and efficiency trade‑offs between single‑ and multi‑GPU systems?

Summary – Single GPUs are suitable for prototyping and low‑latency inference. Multi‑GPU clusters accelerate training and improve utilisation but require high‑bandwidth interconnects and careful orchestration. Plotting a utilisation efficiency curve helps identify the economically optimal cluster size.

Cost Economics – Capex vs Opex & Unit Economics

Context: what GPUs really cost

Beyond hardware prices, building AI infrastructure means paying for power, cooling, networking and talent. A single H100 costs US$25 K–US$40 K; eight of them in a server cost US$200 K–US$400 K. Upgrading power distribution can run US$10 K–US$50 K, cooling upgrades US$15 K–US$100 K and operational overhead adds US$2–US$7/hr per GPU. True cluster cost therefore lands around US$8–US$15/hr per GPU. On the renting side, marketplace rates in early 2026 are US$0.18/hr for an RTX 4090 and ~US$0.54/hr for an H100 NVL. Given these figures, buying is only cheaper if you sustain high utilisation.

Operational calculation: cost per token and break‑even points

Unit economics isn’t just about the hardware sticker price; it’s about cost per million tokens. A 7 B parameter model must achieve ~50 % utilisation to beat an API’s cost; a 13 B model needs only 10 % utilisation due to economies of scale. Using Clarifai’s dashboards, teams monitor cost per inference or per thousand tokens and adjust accordingly. The Unit‑Economics Calculator framework works as follows:

  1. Input: GPU rental rate or purchase price, electricity cost, model size, expected utilisation hours.
  2. Compute: Total cost over time, including depreciation (e.g., selling a US$1,200 RTX 4090 for US$600 after two years).
  3. Output: Cost per hour and cost per million tokens. Compare to API costs to determine break‑even.

This granular view reveals counterintuitive results: owning an RTX 4090 makes sense only when average utilisation exceeds 4–6 hours/day. For sporadic workloads, renting wins. For inference at scale, multi‑GPU clusters can deliver low cost per token when utilisation is high.

logic for buy vs rent decisions

The logic flows like this: If your workload runs < 4 hours/day or is bursty → rent. If you need constant compute > 6 hours/day for multiple years and can absorb capex and depreciation → buy. If you need multi‑GPU or high‑VRAM jobs → rent because the capital outlay is prohibitive. If you need a mix → adopt a hybrid model: own a small rig, rent for big spikes. Clarifai’s customers often combine local runners for small jobs with remote orchestration for heavy training.

What this does NOT solve

Buying hardware doesn’t protect you from obsolescence; new GPU generations like H200 or MI400 deliver 4× speedups, shrinking the economic life of older cards. Owning also introduces fixed electricity costs—~US$64 per month per GPU at US$0.16/kWh—regardless of utilisation.

Expert insights

  • Investor expectations: Startups that fail to articulate GPU COGS (cost of goods sold) see valuations 20 % lower. Investors expect margins to improve from 50–60 % to ~82 % by Series A.
  • True cost: A 8×H100 cluster costs US$8–US$15/hr after including operational overhead.
  • Marketplace trends: H100 rental prices dropped from US$8/hr to US$2.85–US$3.50/hr; A100 prices sit at US$0.66–US$0.78/hr.

Quick summary

Question – How do I calculate whether to buy or rent GPUs?

Summary – Factor in the full cost: hardware price, electricity, cooling, networking and depreciation. Owning pays off only above about 4–6 hours of daily utilisation; renting makes sense for bursty or multi‑GPU jobs. Use a unit‑economics calculator to compare cost per million tokens and break‑even points.

Inference vs Training – Where do costs accrue?

Context: inference dominates the bill

It’s easy to obsess over training cost, but in production inference usually dwarfs it. According to the FinOps Foundation, inference accounts for 80–90 % of total AI spend, especially for generative applications serving millions of daily queries. Teams that plan budgets around training cost alone find themselves hemorrhaging money when latency‑sensitive inference workloads run around the clock.

Operational practices: boosting inference efficiency

Clarifai’s experience shows that inference workloads are asynchronous and bursty, making autoscaling tricky. Key techniques to improve efficiency include:

  • Server‑side batching: Combine multiple requests into a single GPU call. Clarifai’s inference API automatically merges requests when possible, increasing throughput.
  • Caching: Store results for repeated prompts or subqueries. This is crucial when similar requests recur.
  • Quantisation and LoRA: Use lower‑precision arithmetic (INT8 or 4‑bit) and low‑rank adaptation to cut memory and compute. Clarifai’s platform integrates these optimisations.
  • Dynamic pooling: Share GPUs across services via queueing and priority scheduling. Dynamic scheduling can raise utilisation from 15–30 % to 60–80 %.
  • FinOps dashboards: Track cost per inference or per thousand tokens, set budgets and trigger alerts. Clarifai’s dashboard helps FinOps teams spot anomalies and adjust budgets on the fly.

linking throughput, latency and cost

The economic logic is straightforward: If your inference traffic is steady and high, invest in batching and caching to reduce GPU invocations. If traffic is sporadic, consider serverless inference or small models on mid‑tier GPUs to avoid paying for idle resources. If latency budgets are tight (e.g., interactive coding assistants), larger models may degrade user experience; choose smaller models or quantised versions. Finally, rightsizing—choosing the smallest model that satisfies quality needs—can reduce inference cost dramatically.

What this does NOT solve

Autoscaling isn’t free. AI workloads have high memory consumption and latency sensitivity; spiky traffic can trigger over‑provisioning and leave GPUs idle. Without careful monitoring, autoscaling can backfire and burn money.

Inference Efficiency Ladder

A simple ladder to climb toward optimal inference economics:

  1. Quantise and prune. If your accuracy drop is acceptable (< 1 %), apply INT8 or 4‑bit quantisation and pruning to shrink models.
  2. LoRA fine‑tuning. Use low‑rank adapters to customise models without full retraining.
  3. Dynamic batching and caching. Merge requests and reuse outputs to boost throughput.
  4. GPU pooling and scheduling. Share GPUs across services to maximise occupancy.

Each rung yields incremental savings; together they can reduce inference costs by 30–40 %.

Expert insights

  • Idle cost: A fintech firm wasted US$15 K–US$40 K per month on idle GPUs due to poorly configured autoscaling. Dynamic pooling cut costs by 30 %.
  • FinOps practices: Cross‑functional governance—engineers, finance and executives—helps monitor unit economics and apply optimisation levers.
  • Inference dominance: Serving millions of queries means inference spending dwarfs training.

Quick summary

Question – Where do AI compute costs really accumulate, and how can inference be optimised?

Summary – Inference typically consumes 80–90 % of AI budgets. Techniques like quantisation, LoRA, batching, caching and dynamic pooling can raise utilisation from 15–30 % to 60–80 %, dramatically reducing costs. Autoscaling alone isn’t enough; FinOps dashboards and rightsizing are essential.

Optimisation Levers – Techniques to tame costs

Context: low‑hanging fruit and advanced tricks

Hardware scarcity means software optimisation matters more than ever. Luckily, innovations in model compression and adaptive scheduling are no longer experimental. Quantisation reduces precision to INT8 or even 4‑bit, pruning removes redundant weights, and Low‑Rank Adaptation (LoRA) allows fine‑tuning large models by learning small adaptation matrices. Combined, these techniques can shrink models by up to 4× and speed up inference by 1.29× to 1.71×.

Operational guidance: applying the levers

  1. Choose the smallest model: Before compressing anything, start with the smallest model that meets your task requirements. Clarifai’s model zoo includes small, medium and large models, and its routing features allow you to call different models per request.
  2. Quantise and prune: Use built‑in quantisation tools to convert weights to INT8/INT4. Prune unnecessary parameters either globally or layer‑wise, then re‑train to recover accuracy. Monitor accuracy impact at each step.
  3. Apply LoRA: Fine‑tune only a subset of parameters, often < 1 % of the model, to adapt to your dataset. This reduces memory and training time while maintaining performance.
  4. Enable dynamic batching and caching: On Clarifai’s inference platform, simply setting a parameter turns on server‑side batching; caching repeated prompts is automatic for many endpoints.
  5. Measure and iterate: After each optimisation, check throughput, latency and accuracy. Cost dashboards should display cost per inference to confirm savings.

trade‑offs and decision logic

Not all optimisations suit every workload. If your application demands exact numerical outputs (e.g., scientific computation), aggressive quantisation may degrade results—skip it. If your model is already small (e.g., 3 B parameters), quantisation might yield limited savings; focus on batching and caching instead. If latency budgets are tight, batching may increase tail latency—compensate by tuning batch sizes.

What this does NOT solve

No amount of optimisation will overcome poorly aligned models. Using the wrong architecture for your task wastes compute even if it’s quantised. Similarly, quantisation and pruning aren’t plug‑and‑play; they can cause accuracy drops if not carefully calibrated.

Cost‑Reduction Checklist

Use this step‑by‑step checklist to ensure you don’t miss any savings:

  1. Model selection: Start with the smallest viable model.
  2. Quantisation: Apply INT8 → check accuracy; apply INT4 if acceptable.
  3. Pruning: Remove unimportant weights and re‑train.
  4. LoRA/PEFT: Fine‑tune with low‑rank adapters.
  5. Batching & caching: Enable server‑side batching; implement KV‑cache compression.
  6. Pooling & scheduling: Pool GPUs across services; set queue priorities.
  7. FinOps dashboard: Monitor cost per inference; adjust policies regularly.

Expert insights

  • Clarifai engineers: Quantisation and LoRA can cut costs by around 40 % without new hardware.
  • Photonic future: Researchers demonstrated photonic chips performing convolution at near‑zero energy consumption; while not mainstream yet, they hint at long‑term cost reductions.
  • N:M sparsity: Combining 4‑bit quantisation with structured sparsity speeds up matrix multiplication by 1.71× and reduces latency by 1.29×.

Quick summary

Question – What optimisation techniques can significantly reduce GPU costs?

Summary – Start with the smallest model, then apply quantisation, pruning, LoRA, batching, caching and scheduling. These levers can cut compute costs by 30–40 %. Use a cost‑reduction checklist to ensure no optimisation is missed. Always measure accuracy and throughput after each step.

Model Selection & Routing – Using smaller models effectively

Context: token count drives cost more than parameters

A hidden truth about LLMs is that context length dominates costs. Doubling from a 32 K to a 128 K context triples the memory required for the key/value cache. Similarly, prompting models to “think step‑by‑step” can generate long chains of thought that chew through tokens. In real‑time workloads, large models struggle to maintain high efficiency because requests are sporadic and cannot be batched. Small models, by contrast, often run on a single GPU or even on device, avoiding the overhead of splitting across multiple cards.

Operational tactics: tiered stack and routing

Adopting a tiered model stack is like using the right tool for the job. Instead of defaulting to the largest model, route each request to the smallest capable model. Clarifai’s model routing allows you to set rules based on task type:

  • Tiny local model: Handles simple classification, extraction and rewriting tasks at the edge.
  • Small cloud model: Manages moderate reasoning with short context.
  • Medium model: Tackles multi‑step reasoning or longer context when small models aren’t enough.
  • Large model: Reserved for complex queries that small models cannot answer. Only a small fraction of requests should reach this tier.

Routing can be powered by a lightweight classifier that predicts which model will succeed. Research shows that such Universal Model Routing can dramatically cut costs while maintaining quality.

why small is powerful

Smaller models deliver faster inference, lower latency and higher utilisation. If latency budget is < 300 ms, a large model might never satisfy user expectations; route to a small model instead. If accuracy difference is marginal (e.g., 2 %), favour the smaller model to save compute. Distillation and Parameter‑Efficient Fine‑Tuning (PEFT) closed much of the quality gap in 2025, so small models can tackle tasks once considered out of reach.

What this does NOT solve

Routing doesn’t eliminate the need for large models. Some tasks, such as open‑ended reasoning or multi‑modal generation, still require frontier‑scale models. Routing also requires maintenance; as new models emerge, you must update the classifier and thresholds.

Use‑the‑Smallest‑Thing‑That‑Works (USTTW)

This framework captures the essence of efficient deployment:

  1. Start tiny: Always try the smallest model first.
  2. Escalate only when needed: Route to a larger model if the small model fails.
  3. Monitor and adjust: Regularly evaluate which tier handles what percentage of traffic and adjust thresholds.
  4. Compress tokens: Encourage users to write succinct prompts and responses. Apply token‑efficient reasoning techniques to reduce output length.

Expert insights

  • Default model problem: Teams that pick one large model early and never revisit it leak substantial costs.
  • Distillation works: Research in 2025 showed that distilling a 405 B model into an 8 B version produced 21 % better accuracy on NLI tasks.
  • On‑device tiers: Models like Phi‑4 mini and GPT‑4o mini run on edge devices, enabling hybrid deployment.

Quick summary

Question – How can routing and small models cut costs without sacrificing quality?

Summary – Token count often drives cost more than parameter count. Adopting a tiered stack and routing requests to the smallest capable model reduces compute and latency. Distillation and PEFT have narrowed the quality gap, making small models viable for many tasks.

Multi‑GPU Training – Parallelism Strategies & Implementation

Context: distributing for capacity and speed

Large‑parameter models and massive datasets demand multi‑GPU training. Data parallelism replicates the model and splits the batch across GPUs; model parallelism splits layers; pipeline parallelism stages operations across devices. Hybrid strategies blend these to handle complex workloads. Without multi‑GPU training, training times become impractically long—one article noted that training GPT‑3 on a single GPU would take decades.

Operational steps: running distributed training

A practical multi‑GPU training workflow looks like this:

  1. Choose parallelism strategy: Use the Parallelism Selector to decide between data, model, pipeline or hybrid parallelism.
  2. Set up environment: Install distributed training libraries (e.g., PyTorch Distributed, DeepSpeed). Ensure high‑bandwidth interconnects (NVLink, InfiniBand) and proper topology mapping. Clarifai’s training orchestration automates some of these steps, abstracting hardware details.
  3. Profile communication overhead: Run small batches to measure all‑reduce latency. Adjust batch sizes and gradient accumulation steps accordingly.
  4. Implement checkpointing: For long jobs, especially on pre‑emptible spot instances, periodically save checkpoints to avoid losing work.
  5. Monitor utilisation: Use Clarifai’s dashboards or other profilers to track utilisation. Balance workloads to prevent stragglers.

weighing the trade‑offs

If your model fits in memory but training time is long, data parallelism gives linear speedups at the expense of memory duplication. If your model doesn’t fit, model or pipeline parallelism becomes mandatory. If both memory and compute are bottlenecks, hybrid strategies deliver the best of both worlds. The choice also depends on interconnect; without NVLink, model parallelism may stall due to slow PCIe transfers.

What this does NOT solve

Parallelism can complicate debugging and increase code complexity. Over‑segmenting models can introduce excessive communication overhead. Multi‑GPU training is also power‑hungry; energy costs add up quickly. When budgets are tight, consider starting with a smaller model or renting bigger single‑GPU cards.

Parallelism Playbook

A comparison table helps decision‑making:

Strategy

Memory usage

Throughput

Latency

Complexity

Use case

Data

High (full model on each GPU)

Near‑linear

Low

Simple

Fits memory; large datasets

Model

Low (split across GPUs)

Moderate

High

Moderate

Model too large for one GPU

Pipeline

Low

High

High

Moderate

Sequential tasks; long models

Hybrid

Moderate

High

Moderate

High

Both memory and compute limits

Expert insights

  • Time savings: Multi‑GPU training can cut months off training schedules and enable models that wouldn’t fit otherwise.
  • Interconnect matter: High‑bandwidth networks (NVLink, NVSwitch) minimise communication overhead.
  • Checkpoints and spot instances: Pre‑emptible GPUs are cheaper but require checkpointing to avoid job loss.

Quick summary

Question – How do I implement multi‑GPU training efficiently?

Summary – Decide on parallelism type based on memory and dataset size. Use distributed training libraries, high‑bandwidth interconnects and checkpointing. Monitor utilisation and avoid over‑partitioning, which can introduce communication bottlenecks.

Deployment Models – Cloud, On‑Premise & Hybrid

Context: choosing where to run

Deployment strategies range from on‑prem clusters (capex heavy) to cloud rentals (opex) to home labs and hybrid setups. A typical home lab with a single RTX 4090 costs around US$2,200 plus US$770/year for electricity; a dual‑GPU build costs ~US$4,000. Cloud platforms rent GPUs by the hour with no upfront cost but charge higher rates for high‑end cards. Hybrid setups mix both: own a workstation for experiments and rent clusters for heavy lifting.

Operational decision tree

Use the Deployment Decision Tree to guide choices:

  • Daily usage < 4 h: Rent. Marketplace GPUs cost US$0.18/hr for RTX 4090 or US$0.54/hr for H100.
  • Daily usage 4–6 h for ≥ 18 months: Buy. The initial investment pays off after two years.
  • Multi‑GPU jobs: Rent or hybrid. Capex for multi‑GPU rigs is high and hardware depreciates quickly.
  • Data sensitive: On‑prem. Compliance requirements or low‑latency needs justify local servers; Clarifai’s local runner makes on‑prem inference easy.
  • Regional diversity & cost arbitrage: Multi‑cloud. Spread workloads across regions and providers to avoid lock‑in and exploit price differences; Clarifai’s orchestration layer abstracts provider differences and schedules jobs across clusters.

balancing flexibility and capital

If you experiment often and need different hardware types, renting provides agility; you can spin up an 80 GB GPU for a day and return to smaller cards tomorrow. If your product requires 24/7 inference and data can’t leave your network, owning hardware or using a local runner reduces opex and mitigates data‑sovereignty concerns. If you value both flexibility and baseline capacity, adopt hybrid: own one card, rent the rest.

What this does NOT solve

Deploying on‑prem doesn’t immunise you from supply shocks; you still need to maintain hardware, handle power and cooling, and upgrade when generational leaps arrive. Renting isn’t always available either; spot instances can sell out during demand spikes, leaving you without capacity.

Expert insights

  • Energy cost: Running a home‑lab GPU 24/7 at US$0.16/kWh costs ~US$64/month, rising to US$120/month in high‑cost regions.
  • Hybrid in practice: Many practitioners own one GPU for experiments but rent clusters for large training; this approach keeps fixed costs low and offers flexibility.
  • Clarifai tooling: The platform’s local runner supports on‑prem inference; its compute orchestration schedules jobs across clouds and on‑prem clusters.

Quick summary

Question – Should you deploy on‑prem, in the cloud or hybrid?

Summary – The choice depends on utilisation, capital and data sensitivity. Rent GPUs for bursty or multi‑GPU workloads, buy single cards when utilisation is high and long‑term, and use hybrid when you need both flexibility and baseline capacity. Clarifai’s orchestration layer abstracts multi‑cloud differences and supports on‑prem inference.

Sustainability & Environmental Considerations

Context: the unseen footprint

AI isn’t just expensive; it’s energy‑hungry. Analysts estimate that AI inference could consume 165–326 TWh of electricity annually by 2028—equivalent to powering about 22 % of U.S. households. Training a single large model can use over 1,000 MWh of energy, and generating 1,000 images emits carbon equivalent to driving four miles. GPUs rely on rare earth elements and heavy metals, and training GPT‑4 could consume up to seven tons of toxic materials.

Operational practices: eco‑efficiency

Environmental and financial efficiencies are intertwined. If you raise utilisation from 20 % to 60 %, you can reduce GPU needs by 93 %—saving money and carbon simultaneously. Adopt these practices:

  • Quantisation and pruning: Smaller models require less power and memory.
  • LoRA and PEFT: Update only a fraction of parameters to reduce training time and energy.
  • Utilisation monitoring: Use orchestration to keep GPUs busy; Clarifai’s scheduler offloads idle capacity automatically.
  • Renewable co‑location: Place data centres near renewable energy sources and implement advanced cooling (liquid immersion or AI‑driven temperature optimisation).
  • Recycling and longevity: Extend GPU lifespan through high utilisation; delaying upgrades reduces rare‑material waste.

cost meets carbon

Your power bill and your carbon bill often scale together. If you ignore utilisation, you waste both money and energy. If you can run a smaller quantised model on a T4 GPU instead of an H100, you save on electricity and prolong hardware life. Efficiency improvements also reduce cooling needs; smaller clusters generate less heat.

What this does NOT solve

Eco‑efficiency strategies don’t remove the material footprint entirely. Rare earth mining and chip fabrication remain resource‑intensive. Without broad industry change—recycling programs, alternative materials and photonic chips—AI’s environmental impact will continue to grow.

Eco‑Efficiency Scorecard

Rate each deployment option across utilisation (%), model size, hardware type and energy consumption. For example, a quantised small model on a mid‑tier GPU with 80 % utilisation scores high on eco‑efficiency; a large model on an underutilised H100 scores poorly. Use the scorecard to balance performance, cost and sustainability.

Expert insights

  • Energy researchers: AI inference could strain national grids; some providers are even exploring nuclear power.
  • Materials scientists: Extending GPU life from one to three years and increasing utilisation from 20 % to 60 % can reduce GPU needs by 93 %.
  • Clarifai’s stance: Quantisation and layer offloading reduce energy per inference and allow deployment on smaller hardware.

Quick summary

Question – How do GPU scaling choices impact sustainability?

Summary – AI workloads consume enormous energy and rely on scarce materials. Raising utilisation and employing model optimisation techniques reduce both cost and carbon. Co‑locating with renewable energy and using advanced cooling further improve eco‑efficiency.

Emerging Hardware & Alternative Compute Paradigms

Context: beyond the GPU

While GPUs dominate today, the future is heterogeneous. Mid‑tier GPUs handle many workloads at a fraction of the cost; domain‑specific accelerators like TPUs, FPGAs and custom ASICs offer efficiency gains; AMD’s MI300X and upcoming MI400 deliver competitive price–performance; photonic or optical chips promise 10–100× energy efficiency. Meanwhile, decentralised physical infrastructure networks (DePIN) pool GPUs across the globe, offering cost savings of 50–80 %.

Operational guidance: evaluating alternatives

  • Match hardware to workload: Matrix multiplications benefit from GPUs; convolutional tasks may run better on FPGAs; search queries can leverage TPUs. Clarifai’s hardware‑abstraction layer helps deploy models across GPUs, TPUs or FPGAs without rewriting code.
  • Assess ecosystem maturity: TPUs and FPGAs have smaller developer ecosystems than GPUs. Ensure your frameworks support the hardware.
  • Consider integration costs: Porting code to a new accelerator may require engineering effort; weigh this against potential savings.
  • Explore DePIN: If your workload is tolerant of variable latency and you can encrypt data, DePIN networks provide massive capacity at lower prices—but evaluate privacy and compliance risks.

When to adopt

If GPU supply is constrained or too expensive, exploring alternative hardware makes sense. If your workload is stable and high volume, porting to a TPU or custom ASIC may offer long‑term savings. If you need elasticity and low commitment, DePIN or multi‑cloud strategies let you arbitrage pricing and capacity. But early adoption can suffer from immature tooling; consider waiting until software stacks mature.

What this does NOT solve

Alternative hardware doesn’t fix fragmentation. Each accelerator has its own compilers, toolchains and limitations. DePIN networks raise latency and data‑privacy concerns; secure scheduling and encryption are essential. Photonic chips are promising but not yet production‑ready.

Hardware Selection Radar

Visualise accelerators on a radar chart with axes for cost, performance, energy efficiency and ecosystem maturity. GPUs score high on maturity and performance but medium on cost and energy. TPUs score high on efficiency and cost but lower on maturity. Photonic chips show high potential on efficiency but low current maturity. Use this radar to identify which accelerator aligns with your priorities.

Expert insights

  • Clarifai roadmap: The platform will integrate photonic and alternative accelerators, abstracting complexity for developers.
  • DePIN projections: Decentralised GPU networks could generate US$3.5 T by 2028; 89 % of organisations already use multi‑cloud strategies.
  • XPUs rising: Enterprise spending on TPUs, FPGAs and ASICs is growing 22.1 % YoY.

Quick summary

Question – When should AI teams consider alternative hardware or DePIN?

Summary – Explore alternative accelerators when GPUs are scarce or costly. Match workloads to hardware, evaluate ecosystem maturity and integration costs, and consider DePIN for price arbitrage. Photonic chips and MI400 promise future efficiency but are still maturing.

Conclusion & Recommendations

Synthesising the journey

The economics of AI compute are shaped by scarcity, super‑linear scaling and hidden costs. GPUs are expensive not only because of high‑bandwidth memory constraints but also due to lead times and vendor prioritisation. Single GPUs are perfect for experimentation and low‑latency inference; multi‑GPU clusters unlock large models and faster training but require careful orchestration. True cost includes power, cooling and depreciation; owning hardware makes sense only above 4–6 hours of daily use. Most spending goes to inference, so optimising quantisation, batching and routing is paramount. Sustainable computing demands high utilisation, model compression and renewable energy.

Recommendations: the Scale‑Right Decision Tree

Our final framework synthesises the article’s insights into a practical tool:

  1. Assess demand: Estimate model size, context length and daily compute hours. Use the GPU Economics Stack to identify demand drivers (tokens, parameters, context).
  2. Check supply and budget: Evaluate current GPU prices, availability and lead times. Decide if you can secure cards or need to rent.
  3. Right‑size models: Apply the Use‑the‑Smallest‑Thing‑That‑Works framework: start with small models, use routing to call larger models only when necessary.
  4. Decide on hardware: Use the Capex vs Opex Decision Matrix and Hardware Selection Radar to choose between on‑prem, cloud or hybrid and evaluate alternative accelerators.
  5. Choose parallelism strategy: Apply the Parallelism Selector and Parallelism Playbook to pick data, model, pipeline or hybrid parallelism.
  6. Optimise execution: Run through the Cost‑Reduction Checklist—quantise, prune, LoRA, batch, cache, pool, monitor—keeping the Inference Efficiency Ladder in mind.
  7. Monitor and iterate: Use FinOps dashboards to track unit economics. Adjust budgets, thresholds and routing as workloads evolve.
  8. Consider sustainability: Evaluate your deployment using the Eco‑Efficiency Scorecard and co‑locate with renewable energy where possible.
  9. Stay future‑proof: Watch the rise of DePIN, TPUs, FPGAs and photonic chips. Be ready to migrate when they deliver compelling cost or energy benefits.

Final thoughts

Compute is the oxygen of AI, but oxygen isn’t free. Winning in the AI arms race means more than buying GPUs; it requires strategic planning, efficient algorithms, disciplined financial governance and a willingness to embrace new paradigms. Clarifai’s platform embodies these principles: its compute orchestration pools GPUs across clouds and on‑prem clusters, its inference API dynamically batches and caches, and its local runner brings models to the edge. By combining these tools with the frameworks in this guide, your organisation can scale right—delivering transformative AI without suffocating under hardware costs.


Deploying MCP Across SaaS, VPC & On-Prem


Introduction

Why this matters now

The Model Context Protocol (MCP) has emerged as a powerful way for AI agents to call context‑aware tools and models through a consistent interface. Rapid adoption of large language models (LLMs) and the need for contextual grounding mean that organizations must deploy LLM infrastructure across different environments without sacrificing performance or compliance. In early 2026, cloud outages, rising SaaS prices and looming AI regulations are forcing companies to rethink their infrastructure strategies. By designing MCP deployments that span public cloud services (SaaS), virtual private clouds (VPCs) and on‑premises servers, organizations can balance agility with control. This article provides a roadmap for decision‑makers and engineers who want to deploy MCP‑powered applications across heterogeneous infrastructure.

What you’ll learn (quick digest)

This guide covers:

  • A primer on MCP and the differences between SaaS, VPC, and on‑prem environments.
  • A decision‑making framework that helps you evaluate where to place workloads based on sensitivity and volatility.
  • Architectural guidance for designing mixed MCP deployments using Clarifai’s compute orchestration, local runners and AI Runners.
  • Hybrid and multi‑cloud strategies, including a step‑by‑step Hybrid MCP Playbook.
  • Security and compliance best practices with a MCP Security Posture Checklist.
  • Operational roll‑out strategies, cost optimisation advice, and lessons learned from failure cases.
  • Forward‑looking trends and a 2026 MCP Trend Radar.

Throughout the article you’ll find expert insights, quick summaries and practical checklists to make the content actionable.

Understanding MCP and Deployment Options

What is the Model Context Protocol?

The Model Context Protocol (MCP) is an emerging standard for invoking and chaining AI models and tools that are aware of their context. Instead of hard‑coding integration logic into an agent, MCP defines a uniform way for an agent to call a tool (a model, API or function) and receive context‑rich responses. Clarifai’s platform, for example, allows developers to upload custom tools as MCP servers and host them anywhere—on a public cloud, inside a virtual private cloud or on a private server. This hardware‑agnostic orchestration means a single MCP server can be reused across multiple environments.

Deployment environments: SaaS, VPC and On‑Prem

SaaS (public cloud). In a typical Software‑as‑a‑Service deployment the provider runs multi‑tenant infrastructure and exposes a web‑based API. Elastic scaling, pay‑per‑use pricing and reduced operational overhead make SaaS attractive. However, multi‑tenant services share resources with other customers, which can lead to performance variability (“noisy neighbours”) and limited customisation.

Virtual private cloud (VPC). A VPC is a logically isolated segment of a public cloud that uses private IP ranges, VPNs or VLANs to emulate a private data centre. VPCs provide stronger isolation and can restrict network access while still leveraging cloud elasticity. They are cheaper than building a private cloud but still depend on the underlying public cloud provider; outages or service limitations propagate into the VPC.

On‑premises. On‑prem deployments run inside an organisation’s own data centre or on hardware it controls. This model offers maximum control over data residency and latency but requires significant capital expenditure and ongoing maintenance. On‑prem environments often lack elasticity, so planning for peak loads is critical.

MCP Deployment Suitability Matrix (Framework)

To decide which environment to use for an MCP component, consider two axes: sensitivity of the workload (how critical or confidential it is) and traffic volatility (how much it spikes). This MCP Deployment Suitability Matrix helps you map workloads:

Workload type

Sensitivity

Volatility

Recommended environment

Mission‑critical & highly regulated (healthcare, finance)

High

Low

On‑prem/VPC for maximum control

Customer‑facing with moderate sensitivity

Medium

High

Hybrid: VPC for sensitive components, SaaS for bursty traffic

Experimental or low‑risk workloads

Low

High

SaaS for agility and cost efficiency

Batch processing or predictable offline workloads

Medium

Low

On‑prem if hardware utilisation is high; VPC if data residency rules apply

Use this matrix as a starting point and adjust based on regulatory requirements, resource availability and budget.

Expert insights

  • The global SaaS market was worth US$408 billion in 2025, forecast to reach US$465 billion in 2026, reflecting strong adoption.
  • Research suggests 52 % of businesses have moved most of their IT environment to the cloud, yet many are adopting hybrid strategies due to rising vendor costs and compliance pressures.
  • Clarifai’s platform has supported over 1.5 million models across 400 k users in 170 countries, demonstrating maturity in multi‑environment deployment.

Quick summary

Question: Why should you understand MCP deployment options?

Summary: MCP allows AI agents to call context‑aware tools across different infrastructures. SaaS offers elasticity and low operational overhead but introduces shared tenancy and potential lock‑in. VPCs strike a balance between public cloud and private isolation. On‑prem provides maximum control at the cost of flexibility and higher capex. Use the MCP Deployment Suitability Matrix to map workloads to the right environment.

Evaluating Deployment Environments — SaaS vs VPC vs On‑Prem

Context and evolution

When cloud computing emerged a decade ago, organisations often had a binary choice: build everything on‑prem or move to public SaaS. Over time, regulatory constraints and the need for customisation drove the rise of private clouds and VPCs. The hybrid cloud market is projected to hit US$145 billion by 2026, highlighting demand for mixed strategies.

While SaaS eliminates upfront capital and simplifies maintenance, it shares compute resources with other tenants, leading to potential performance unpredictability. In contrast, VPCs offer dedicated virtual networks on top of public cloud providers, combining control with elasticity. On‑prem solutions remain crucial in industries where data residency and ultra‑low latency are mandatory.

Detailed comparison

Control and security. On‑prem gives full control over data and hardware, enabling air‑gapped deployments. VPCs provide isolated environments but still rely on the public cloud’s shared infrastructure; misconfigurations or provider breaches can affect your operations. SaaS requires trust in the provider’s multi‑tenant security controls.

Cost structure. Public cloud follows a pay‑per‑use model, avoiding capital expenditure but sometimes leading to unpredictable bills. On‑prem involves high initial investment and ongoing maintenance but can be more cost‑effective for steady workloads. VPCs are typically cheaper than building a private cloud and offer better value for regulated workloads.

Scalability and performance. SaaS excels at scaling for bursty traffic but may suffer from cold‑start latency in serverless inference. On‑prem provides predictable performance but lacks elasticity. VPCs offer elasticity while being limited by the public cloud’s capacity and possible outages.

Environment Comparison Checklist

Use this checklist to evaluate options:

  1. Sensitivity: Does data require sovereign storage or specific certifications? If yes, lean toward on‑prem or VPC.
  2. Traffic pattern: Are workloads spiky or predictable? Spiky workloads benefit from SaaS/VPC elasticity, whereas predictable workloads suit on‑prem for cost amortisation.
  3. Budget & cost predictability: Are you prepared for operational expenses and potential price hikes? SaaS pricing can vary over time.
  4. Performance needs: Do you need sub‑millisecond latency? On‑prem often offers the best latency, while VPC provides a compromise.
  5. Compliance & governance: What regulations must you comply with (e.g., HIPAA, GDPR)? VPCs can help meet compliance with controlled environments; on‑prem ensures maximum sovereignty.

Opinionated insight

In my experience, organisations often misjudge their workloads’ volatility and over‑provision on‑prem hardware, leading to underutilised resources. A smarter approach is to model traffic patterns and consider VPCs for sensitive workloads that also need elasticity. You should also avoid blindly adopting SaaS based on cost; usage‑based pricing can balloon when models perform retrieval‑augmented generation (RAG) with high inference loads.

Quick summary

Question: How do you choose between SaaS, VPC and on‑prem?

Summary: Assess control, cost, scalability, performance and compliance. SaaS offers agility but may be expensive during peak loads. VPCs balance isolation with elasticity and suit regulated or sensitive workloads. On‑prem suits highly sensitive, stable workloads but requires significant capital and maintenance. Use the checklist above to guide decisions.

Designing MCP Architecture for Mixed Environments

Multi‑tenant design and RAG pipelines

Modern AI workflows often combine multiple components: vector databases for retrieval, large language models for generation, and domain‑specific tools. Clarifai’s blog notes that cell‑based rollouts isolate tenants in multi‑tenant SaaS deployments to reduce cross‑tenant interference. A retrieval‑augmented generation (RAG) pipeline embeds documents into a vector space, retrieves relevant chunks and then passes them to a generative model. The RAG market was worth US$1.85 billion in 2024, growing at 49 % per year.

Leveraging Clarifai’s compute orchestration

Clarifai’s compute orchestration routes model traffic across nodepools spanning public cloud, on‑prem or hybrid clusters. A single MCP call can automatically dispatch to the appropriate compute target based on tenant, workload type or policy. This eliminates the need to replicate models across environments. AI Runners let you run models on local machines or on‑prem servers and expose them via Clarifai’s API, providing traffic‑based autoscaling, batching and GPU fractioning.

Implementation notes and dependencies

  • Packaging MCP servers: Containerise your tool or model (e.g., using Docker) and define the MCP API. Clarifai’s platform supports uploading these containers and hosts them with an OpenAI‑compatible API.
  • Network configuration: For VPC or on‑prem deployments, configure a VPN, IP allow‑list or private link to expose the MCP server securely. Clarifai’s local runners create a public URL for models running on your own hardware.
  • Routing logic: Use compute orchestration policies to route sensitive tenants to on‑prem clusters and other tenants to SaaS. Incorporate health checks and fallback strategies; for example, if the on‑prem nodepool is saturated, temporarily offload traffic to a VPC nodepool.
  • Version management: Use champion‑challenger or multi‑armed bandit rollouts to test new model versions and gather performance metrics.

MCP Topology Blueprint (Framework)

The MCP Topology Blueprint is a modular architecture that connects multiple deployment environments:

  1. MCP Servers: Containerised tools or models exposing a consistent MCP interface.
  2. Compute Orchestration Layer: A control plane (e.g., Clarifai) that routes requests to nodepools based on policies and metrics.
  3. Nodepools: Collections of compute instances. You can have a SaaS nodepool (auto‑scaling public cloud), VPC nodepool (isolated in a public cloud), and on‑prem nodepool (Kubernetes or bare metal clusters).
  4. AI Runners & Local Runners: Connect local or on‑prem models to the orchestration plane, enabling API access and scaling features.
  5. Observability: Logging, metrics and tracing across all environments with centralised dashboards.

By adopting this blueprint, teams can scale up and down across environments without rewriting integration logic.

Negative knowledge

Do not assume that a single environment can serve all requests efficiently. Serverless SaaS deployments introduce cold‑start latency, which can degrade user experience for chatbots or voice assistants. VPC connectivity misconfigurations can expose sensitive data or cause downtime. On‑prem clusters may become a bottleneck if compute demand spikes; a fallback strategy is essential.

Quick summary

Question: What are the key components when architecting MCP across mixed environments?

Summary: Design multi‑tenant isolation, leverage compute orchestration to route traffic across SaaS, VPC and on‑prem nodepools, and use AI Runners or local runners to connect your own hardware to Clarifai’s API. Containerise MCP servers, secure network access and implement versioning strategies. Beware of cold‑start latency and misconfigurations.

Building Hybrid & Multi‑Cloud Strategies for MCP

Why hybrid and multi‑cloud?

Hybrid and multi‑cloud strategies allow organisations to harness the strengths of multiple environments. For regulated industries, hybrid cloud means storing sensitive data on‑premises while leveraging public cloud for bursts. Multi‑cloud goes a step further by using multiple public clouds to avoid vendor lock‑in and improve resilience. By 2026, price increases from major cloud vendors and frequent service outages have accelerated adoption of these strategies.

The Hybrid MCP Playbook (Framework)

Use this playbook to deploy MCP services across hybrid or multi‑cloud environments:

  1. Workload classification: Categorise workloads into buckets (e.g., confidential data, latency‑sensitive, bursty). Map them to the appropriate environment using the MCP Deployment Suitability Matrix.
  2. Connectivity design: Establish secure VPNs or private links between on‑prem clusters and VPCs. Use DNS routing or Clarifai’s compute orchestration policies to direct traffic.
  3. Data residency management: Replicate or shard vector embeddings and databases across environments where required. For retrieval‑augmented generation, store sensitive vectors on‑prem and general vectors in the cloud.
  4. Failover & resilience: Configure nodepools with health checks and define fallback targets. Use multi‑armed bandit policies to shift traffic in real time.
  5. Cost and capacity planning: Allocate budgets for each environment. Use Clarifai’s autoscaling, batching and GPU fractioning features to control costs across nodepools.
  6. Continuous observability: Centralise logs and metrics. Use dashboards to monitor latency, cost per request and success rates.

Operational considerations

  • Latency management: Keep inference closer to the user for low‑latency interactions. Use geo‑distributed VPCs and on‑prem clusters to minimise round‑trip times.
  • Compliance: When data residency laws change, adjust your environment map. For instance, the European AI Act may require certain personal data to stay within the EU.
  • Vendor diversity: Balance your workloads across cloud providers to mitigate outages and negotiate better pricing. Clarifai’s hardware‑agnostic orchestration simplifies this.

Negative knowledge

Hybrid complexity should not be underestimated. Without unified observability, debugging cross‑environment latency can become a nightmare. Over‑optimising for multi‑cloud may introduce fragmentation and duplicate effort. Avoid building bespoke connectors for each environment; instead, rely on standardised orchestration and APIs.

Quick summary

Question: How do you build a hybrid or multi‑cloud MCP strategy?

Summary: Classify workloads by sensitivity and volatility, design secure connectivity, manage data residency, configure failover, control costs and maintain observability. Use Clarifai’s compute orchestration to simplify routing across multiple clouds and on‑prem clusters. Beware of complexity and duplication.

Security & Compliance Considerations for MCP Deployment


Security and compliance remain top concerns when deploying AI systems. Cloud environments have suffered high breach rates; one report found that 82 % of breaches in 2025 occurred in cloud environments. Misconfigured SaaS integrations and over‑privileged access are common; in 2025, 33 % of SaaS integrations gained privileged access to core applications. MCP deployments, which orchestrate many services, can amplify these risks if not designed carefully.

The MCP Security Posture Checklist (Framework)

Follow this checklist to secure your MCP deployments:

  1. Identity & Access Management: Use role‑based access control (RBAC) to restrict who can call each MCP server. Integrate with your identity provider (e.g., Okta) and enforce least privilege.
  2. Network segmentation: Isolate nodepools using VPCs or subnets. Use private endpoints and VPNs for on‑prem connectivity. Deny inbound traffic by default.
  3. Data encryption: Encrypt embeddings, prompts and outputs at rest and in transit. Use hardware security modules (HSM) for key management.
  4. Audit & logging: Log all MCP calls, including input context and output. Monitor for abnormal patterns such as unexpected tools being invoked.
  5. Compliance mapping: Align with relevant regulations (GDPR, HIPAA). Maintain data processing agreements and ensure that data residency rules are honoured.
  6. Privacy by design: For retrieval‑augmented generation, store sensitive embeddings locally or in a sovereign cloud. Use anonymisation or pseudonymisation where possible.
  7. Third‑party risk: Assess the security posture of any upstream services (e.g., vector databases, LLM providers). Avoid integrating proprietary models without due diligence.

Expert insights

  • Multi‑tenant SaaS introduces noise; isolate high‑risk tenants in dedicated cells.
  • On‑prem isolation is effective but must be paired with strong physical security and disaster recovery planning.
  • VPC misconfigurations, such as overly permissive security groups, remain a primary attack vector.

Negative knowledge

No amount of encryption can fully mitigate the risk of model inversion or prompt injection. Always assume that a compromised tool can exfiltrate sensitive context. Don’t trust third‑party models blindly; implement content filtering and domain adaptation. Avoid storing secrets within retrieval corpora or prompts.

Quick summary

Question: How do you secure MCP deployments?

Summary: Apply RBAC, network segmentation and encryption; log and audit all interactions; maintain compliance; and implement privacy by design. Evaluate the security posture of third‑party services and avoid storing sensitive data in retrieval corpora. Don’t rely solely on cloud providers; misconfigurations are a common attack vector.

Operational Best Practices & Roll‑out Strategies

Deploying new models or tools can be risky. Many AI SaaS platforms launched generic LLM features in 2025 without adequate use‑case alignment; this led to hallucinations, misaligned outputs and poor user experience. Clarifai’s blog highlights champion‑challenger, multi‑armed bandit and champion‑challenger roll‑out patterns to reduce risk.

Roll‑out strategies and operational depth

  • Pilot & fine‑tune: Start by fine‑tuning models on domain‑specific data. Avoid relying on generic models; inaccurate outputs erode trust.
  • Shadow testing: Deploy new models in parallel with production systems but do not yet serve their outputs. Compare responses and monitor divergences.
  • Canary releases: Serve the new model to a small percentage of users or requests. Monitor key metrics (latency, accuracy, cost) and gradually increase traffic.
  • Multi‑armed bandit: Use algorithms that allocate traffic to models based on performance; this accelerates convergence to the best model while limiting risk.
  • Blue‑green deployment: Maintain two identical environments (blue and green) and switch traffic between them during updates to minimise downtime.
  • Champion‑challenger: Retain a stable “champion” model while testing “challenger” models. Promote challengers only when they exceed the champion’s performance.

Common mistakes

  • Skipping human evaluation: Automated metrics alone cannot capture user satisfaction. Include human‑in‑the‑loop reviews, especially for critical tasks.
  • Rushing to market: In 2025, rushed AI roll‑outs led to a 20 % drop in user adoption.
  • Neglecting monitoring: Without continuous monitoring, model drift goes unnoticed. Incorporate drift detection and anomaly alerts.

MCP Roll‑out Ladder (Framework)

Visualise roll‑outs as a ladder:

  1. Development: Fine‑tune models offline.
  2. Internal preview: Test with internal users; gather qualitative feedback.
  3. Shadow traffic: Compare outputs against the champion model.
  4. Canary launch: Release to a small user subset; monitor metrics.
  5. Bandit allocation: Dynamically adjust traffic based on real‑time performance.
  6. Full promotion: Once a challenger consistently outperforms, promote it to champion.

This ladder reduces risk by gradually exposing users to new models.

Quick summary

Question: What are the best practices for rolling out new MCP models?

Summary: Fine‑tune models with domain data; use shadow testing, canary releases, multi‑armed bandits and champion‑challenger patterns; monitor continuously; and avoid rushing. Following a structured rollout ladder minimises risk and improves user trust.

Cost & Performance Optimisation Across Environments


Costs and performance must be balanced carefully. Public cloud eliminates upfront capital but introduces unpredictable expenses—79 % of IT leaders reported price increases at renewal. On‑prem requires significant capex but ensures predictable performance. VPC costs lie between these extremes and may offer better cost control for regulated workloads.

MCP Cost Efficiency Calculator (Framework)

Consider three cost categories:

  1. Compute & storage: Count GPU/CPU hours, memory, and disk. On‑prem hardware costs amortise over its lifespan; cloud costs scale linearly.
  2. Network: Data transfer fees vary across clouds; egress charges can be significant in hybrid architectures. On‑prem internal traffic has negligible cost.
  3. Operational labour: Cloud reduces labour for maintenance but increases costs for DevOps and FinOps to manage variable spending.

Plug estimated usage into each category to compare total cost of ownership. For example:

Deployment

Capex

Opex

Notes

SaaS

None

Pay per request, variable with usage

Cost effective for unpredictable workloads but subject to price hikes

VPC

Moderate

Pay for dedicated capacity and bandwidth

Balances isolation and elasticity; consider egress costs

On‑prem

High

Maintenance, energy and staffing

Predictable cost for steady workloads

Performance tuning

  • Autoscaling and batching: Use Clarifai’s compute orchestration to batch requests and share GPUs across models, improving throughput.
  • GPU fractioning: Allocate fractional GPU resources to small models, reducing idle time.
  • Model pruning and quantisation: Smaller model sizes reduce inference time and memory footprint; they are ideal for on‑prem deployments with limited resources.
  • Caching: Cache embeddings and intermediate results to avoid redundant computation. However, ensure caches are invalidated when data updates.

Negative knowledge

Avoid over‑optimising for cost at the expense of user experience. Aggressive batching can increase latency. Buying large on‑prem clusters without analysing utilisation will result in idle resources. Watch out for hidden cloud costs, such as data egress or API rate limits.

Quick summary

Question: How do you balance cost and performance in MCP deployments?

Summary: Use a cost calculator to weigh compute, network and labour expenses across SaaS, VPC and on‑prem. Optimise performance via autoscaling, batching and GPU fractioning. Don’t sacrifice user experience for cost; examine hidden fees and plan for resilience.

Failure Scenarios & Common Pitfalls to Avoid

Many AI deployments fail because of unrealistic expectations. In 2025, vendors relied on generic LLMs without fine‑tuning or proper prompt engineering, leading to hallucinations and misaligned outputs. Some companies over‑spent on cloud infrastructure, exhausting budgets without delivering value. Security oversights are rampant; 33 % of SaaS integrations have privileged access they do not need.

Diagnosing failures

Use the following decision tree when your deployment misbehaves:

  • Inaccurate outputs? → Inspect training data and fine‑tuning. Domain adaptation may be missing.
  • Slow response times? → Check compute placement and autoscaling policies. Serverless cold‑start latency could be the culprit.
  • Unexpected costs? → Review usage patterns. Batch requests where possible and monitor GPU utilisation. Consider moving parts of the workload on‑prem or to VPC.
  • Compliance issues? → Audit access controls and data residency. Ensure VPC network rules are not overly permissive.
  • User drop‑off? → Evaluate user experience. Rushed roll‑outs often neglect UX and can result in adoption declines.

MCP Failure Readiness Checklist (Framework)

  1. Dataset quality: Evaluate your training corpus. Remove bias and ensure domain relevance.
  2. Fine‑tuning strategy: Choose a base model that aligns with your use case. Use retrieval‑augmented generation to improve grounding.
  3. Prompt engineering: Provide precise instructions and guardrails to models. Test adversarial prompts.
  4. Cost modelling: Project total cost of ownership and set budget alerts.
  5. Scaling plan: Model expected traffic; design fallback plans.
  6. Compliance review: Verify that data residency, privacy and security requirements are met.
  7. User experience: Conduct usability testing. Include non‑technical users in feedback loops.
  8. Monitoring & logging: Instrument all components; set up anomaly detection.

Negative knowledge

Avoid prematurely scaling to multiple clouds before proving value. Don’t ignore the need for domain adaptation; off‑the‑shelf models rarely satisfy specialised use cases. Keep your compliance and security teams involved from day one.

Quick summary

Question: What causes MCP deployments to fail and how can we avoid it?

Summary: Failures stem from generic models, poor prompt engineering, uncontrolled costs and misconfigured security. Diagnose issues systematically: examine data, compute placement and user experience. Use the MCP Failure Readiness Checklist to proactively address risks.

Future Trends & Emerging Considerations (As of 2026 and Beyond)

Agentic AI and multi‑agent orchestration

The next wave of AI involves agentic systems, where multiple agents collaborate to complete complex tasks. These agents need context, memory and long‑running workflows. Clarifai has introduced support for AI agents and OpenAI‑compatible MCP servers, enabling developers to integrate proprietary business logic and real‑time data. Retrieval‑augmented generation will become even more prevalent, with the market growing at nearly 49 % per year.

Sovereign clouds and regulation

Regulators are stepping up enforcement. Many enterprises expect to adopt private or sovereign clouds to meet evolving privacy laws; predictions suggest 40 % of large enterprises may adopt private clouds for AI workloads by 2028. Data localisation rules in regions like the EU and India require careful placement of vector databases and prompts.

Hardware and software innovation

Advances in AI hardware—custom accelerators, memory‑centric processors and dynamic GPU allocation—will continue to shape deployment strategies. Software innovations such as function chaining and stateful serverless frameworks will allow models to persist context across calls. Clarifai’s roadmap includes deeper integration of hardware‑agnostic scheduling and dynamic GPU allocation.

The 2026 MCP Trend Radar (Framework)

This visual tool (imagine a radar chart) maps emerging trends against adoption timelines:

  • Near‑term (0–12 months): Retrieval‑augmented generation, hybrid cloud adoption, price‑based auto‑scaling, agentic tool execution.
  • Medium term (1–3 years): Sovereign clouds, AI regulation enforcement, cross‑cloud observability standards.
  • Long term (3–5 years): On‑device inference, federated multi‑agent collaboration, self‑optimising compute orchestration.

Negative knowledge

Not every trend is ready for production. Resist the urge to adopt multi‑agent systems without a clear business need; complexity can outweigh benefits. Stay vigilant about hype cycles and invest in fundamentals—data quality, security and user experience.

Quick summary

Question: What trends will influence MCP deployments in the coming years?

Summary: Agentic AI, retrieval‑augmented generation, sovereign clouds, hardware innovations and new regulations will shape the MCP landscape. Use the 2026 MCP Trend Radar to prioritise investments and avoid chasing hype.

Conclusion & Next Steps

Deploying MCP across SaaS, VPC and on‑prem environments is not just a technical exercise—it’s a strategic imperative in 2026. To succeed, you must: (1) understand the strengths and limitations of each environment; (2) design robust architectures using compute orchestration and tools like Clarifai’s AI Runners; (3) adopt hybrid and multi‑cloud strategies using the Hybrid MCP Playbook; (4) embed security and compliance into your design using the MCP Security Posture Checklist; (5) follow disciplined rollout practices like the MCP Roll‑out Ladder; (6) optimise cost and performance with the MCP Cost Efficiency Calculator; (7) anticipate failure scenarios using the MCP Failure Readiness Checklist; and (8) stay ahead of future trends with the 2026 MCP Trend Radar.

Adopting these frameworks ensures your MCP deployments deliver reliable, secure and cost‑effective AI services across diverse environments. Use the checklists and decision tools provided throughout this article to guide your next project—and remember that successful deployment depends on continuous learning, user feedback and ethical practices. Clarifai’s platform can support you on this journey, providing a hardware‑agnostic orchestration layer that integrates with your existing infrastructure and helps you harness the full potential of the Model Context Protocol.

Frequently Asked Questions (FAQs)

Q: Is the Model Context Protocol proprietary?
A: No. MCP is an emerging open standard designed to provide a consistent interface for AI agents to call tools and models. Clarifai supports open‑source MCP servers and allows developers to host them anywhere.

Q: Can I deploy the same MCP server across multiple environments without modification?
A: Yes. Clarifai’s hardware‑agnostic orchestration lets you upload an MCP server once and route calls to different nodepools (SaaS, VPC, on‑prem) based on policies.

Q: How do retrieval‑augmented generation pipelines fit into MCP?
A: RAG pipelines connect a retrieval component (vector database) to an LLM. Using MCP, you can containerise both components and orchestrate them across environments. RAG is particularly important for grounding LLMs and reducing hallucinations.

Q: What happens if a cloud provider has an outage?
A: Multi‑cloud and hybrid strategies mitigate this risk. You can configure failover policies so that traffic is rerouted to healthy nodepools in other clouds or on‑prem clusters. However, this requires careful planning and testing.

Q: Are there hidden costs in multi‑environment deployments?
A: Yes. Data transfer fees, underutilised on‑prem hardware and management overhead can add up. Use the MCP Cost Efficiency Calculator to model costs and monitor spending.

Q: How does Clarifai handle compliance?
A: Clarifai provides features like local runners and compute orchestration to keep data where it belongs and route requests appropriately. However, compliance remains the customer’s responsibility. Use the MCP Security Posture Checklist to implement best practices.


Automate SEO: Revolutionize Your Digital Strategy Without Losing Quality


You can’t manually brute-force your way to the top of Google anymore. The sheer volume of data involved in modern search marketing—keywords, backlinks, technical audits, content clusters—is impossible to manage with just spreadsheets and willpower. If you want to scale, you have to automate SEO processes.

This isn’t about letting robots run your entire marketing department. It’s about offloading the grunt work so you can focus on the high-level strategy that actually moves the needle. Whether you are an agency owner or an in-house marketer, automation is the only way to stay competitive without burning out.

Here is how to integrate automation into your workflow without sacrificing quality.

The Case for Automation: Why Manual SEO is Dead

Let’s be honest: half of SEO is data entry and pattern recognition. Doing this manually is a waste of human talent. When you automate SEO tasks, you aren’t just saving time; you are eliminating human error.

A human might miss a broken canonical tag on page 400 of a site audit. A crawler won’t. A human might forget to check rank fluctuations on a Sunday morning. A script won’t.

By implementing automation, you gain:

  • Speed: Execute audits and reports in minutes, not days.
  • Scale: Manage 10,000 pages as easily as you manage 10.
  • Accuracy: Remove the ‘fat finger’ errors from your reporting data.

Smart Workflows: How to Automate SEO Effectively

You shouldn’t automate everything. Strategy requires a human brain. Relationship building requires empathy. But the operational side? That’s ripe for automation.

1. Technical Audits and Monitoring

This is the lowest-hanging fruit. You should never manually check for 404 errors or broken redirects unless you are debugging a specific issue.

Tools like Screaming Frog or DeepCrawl can be scheduled to run weekly crawls automatically. You can set up alerts to ping your Slack channel the moment a critical tag breaks or site speed dips below a certain threshold. This turns SEO from a reactive ‘clean up’ job into a proactive monitoring system.

2. Intelligent Keyword Research

Gone are the days of manually combing through Google Suggest. Modern automation tools use AI to cluster keywords by intent.

Instead of staring at a list of 5,000 raw keywords, automation tools can group them into topic clusters, analyze the SERP volatility, and tell you exactly which terms have the best difficulty-to-traffic ratio. This allows you to build a content roadmap based on data, not gut feeling.

3. Reporting and Analytics

If you are still manually copy-pasting data from Google Analytics into Excel, stop immediately.

Reporting is perhaps the easiest thing to automate SEO workflows around. Tools like Looker Studio (formerly Data Studio) or AgencyAnalytics can pull live data from Search Console, GA4, and your rank tracker into a single dashboard. Set it to email you (and your stakeholders) a PDF summary every Monday morning. You just saved yourself five hours a month.

The Role of AI Agents in SEO

We are moving beyond simple scripts and into the era of AI agents. Tools like Lindy AI are changing the game by acting as virtual employees rather than just software.

Imagine an AI assistant that doesn’t just report on rankings but actually drafts the optimization brief for pages that dropped. AI agents can manage workflows, trigger content updates, and even handle initial outreach emails for link building.

While AI shouldn’t write your final publishable content without human review, it should be handling the drafting, outlining, and metadata generation. This allows your human writers to act as editors and strategists, polishing good content into great content.

Steps to Build Your Automated Stack

Ready to automate SEO operations? Don’t try to change everything overnight. Start here:

  1. Audit Your Time: Track what you do for a week. Circle every repetitive task (rank checking, reporting, metadata writing).
  2. Pick Your Tools: Select a stack that plays well together. For example, connect SEMrush to Zapier, and Zapier to your project management tool (like Asana or Trello).
  3. Start with Reporting: It’s the safest place to start. Automate your weekly updates.
  4. Move to On-Page: Use tools to auto-generate alt text and meta descriptions, then manually review them in batches.
  5. Monitor and Iterate: Automation breaks. APIs change. Review your automated workflows monthly to ensure they are still accurate.

The Human Element: What NOT to Automate

There is a trap here. It’s tempting to try and put the whole strategy on autopilot. Do not do this.

Keep these tasks human:

  • Final Content Approval: AI lacks nuance and cultural context.
  • High-Level Strategy: Deciding why you are targeting a specific niche.
  • Relationship Building: High-quality backlinks come from real relationships, not spammy automated emails.

Final Thoughts

The goal when you automate SEO is not to replace the SEO expert. It’s to give the expert superpowers. By handing over the repetitive, data-heavy tasks to machines, you free yourself up to be creative, strategic, and impactful.

The future of search belongs to those who can blend technical automation with human creativity. Start building your stack today, and stop drowning in the data.

Categories: Digital Marketing, SEO Strategy, Marketing Automation, AI Tools

Best Private Cloud Hosting Platforms in 2026


Overview of Private Cloud Hosting

Quick Summary

What is private cloud hosting and why is it important? Private cloud hosting provides cloud‑like computing resources within a dedicated, enterprise‑controlled environment. It combines the elasticity and convenience of public cloud with heightened security, compliance and data sovereignty—making it ideal for regulated industries, latency‑sensitive applications and AI workloads.

Private vs Public vs Hybrid

In a public cloud, customers rent compute, storage and networking from providers like Amazon Web Services or Microsoft Azure. Resources are shared across customers, and data resides in provider‑owned facilities. A private cloud, however, runs on infrastructure dedicated to a single organisation. It may be located on‑premises or hosted in a service provider’s data centre. Hybrid clouds blend both models, allowing workloads to move between environments.

Private clouds appeal to industries with stringent compliance requirements—finance, healthcare and government. Regulations often require data residency in specific jurisdictions. Research shows that the rise of sovereign clouds is driven by privacy concerns and regulatory mandates. By hosting data on dedicated infrastructure, organisations maintain control over location, encryption and access policies. Hybrid models further allow them to burst into public cloud for peak loads without sacrificing sovereignty.

Key Use Cases

  1. Regulated Workloads: Financial services, healthcare and government agencies must comply with regulations like GDPR, HIPAA or financial industry rules. Private clouds offer auditability and controlled data residency.
  2. Latency‑Sensitive Applications: Manufacturing control systems, real‑time analytics and AI inference often require milliseconds‑level latency. Running applications close to end users or equipment ensures responsiveness.
  3. AI & Machine Learning: Training models on proprietary data or running inference at the edge demands powerful GPUs and secure data handling. With Clarifai’s platform, organisations can deploy models locally, orchestrate compute across clusters, and ensure data never leaves the premises.
  4. Legacy Modernisation: Many organisations still run monolithic applications on legacy servers. Private clouds enable them to modernise using container platforms like OpenShift while maintaining compatibility.

Emerging Drivers

Analysts predict that private and sovereign clouds will continue to grow as organisations seek control over their data. Multi‑cloud adoption helps companies avoid vendor lock‑in and optimise costs. Meanwhile, the surge in edge computing and micro‑clouds means workloads are moving closer to where data is generated. These trends make private cloud hosting more relevant than ever.

Expert Insights

  • The rise of sovereign cloud is not just a trend; it is becoming a necessity for organisations facing geopolitical uncertainties.
  • Multi‑cloud strategies help avoid proprietary lock‑in and ensure resilience.
  • Edge AI requires local compute capacity and low latency—private clouds provide an ideal foundation.

Public Cloud Extensions – Hybrid & Dedicated Regions

Quick Summary

Which public cloud extensions transform into private cloud solutions? AWS Outposts, Azure Stack/Local, Google Anthos & Distributed Cloud, and Oracle Cloud@Customer deliver public cloud services as fully managed hardware installed in customer facilities. They combine the familiarity of public cloud APIs with on‑premises control—ideal for regulated industries and low‑latency applications.

AWS Outposts

AWS Outposts is a fully managed service that brings AWS infrastructure, services and APIs to customer data centres and co‑location facilities. Outposts racks include compute, storage and networking hardware; AWS installs and manages them remotely. Customers subscribe to three‑year terms with flexible payment options. The same AWS console and SDKs are used to manage services like EC2, EBS, EKS, RDS and EMR. Use cases include low‑latency manufacturing control, healthcare imaging, financial trading and regulated workloads.

Clarifai Integration: Deploy Clarifai models directly on Outposts racks to perform real‑time inference near data sources. Use the Clarifai local runner to orchestrate GPU‑accelerated workloads inside the Outpost, ensuring data does not leave the site. When training requires scale, the same models can run in AWS regions via Clarifai’s cloud service.

Microsoft Azure Stack/Local

Azure Stack Hub (rebranded as Azure Local) extends Azure services into on‑prem environments. Organisations run Azure VMs, containers and services using the same tools, APIs and billing as the public cloud. Benefits include low latency, consistent developer experience, and compliance with data residency. Disadvantages include a limited subset of services and the need for expertise in both on‑prem and cloud environments. Azure Local is ideal for edge analytics, healthcare, retail and scenarios requiring offline capability.

Clarifai Integration: Use Clarifai’s model inference engine to serve AI models on Azure Local clusters. Because Azure Local uses the same Kubernetes operator patterns, Clarifai’s containerised models can be deployed via Helm charts or operators. When connectivity to Azure public cloud is available, models can synchronise for training or updates.

Google Anthos & Distributed Cloud

Google’s Anthos provides a unified platform for building and managing applications across on‑premises, Google Cloud and other public clouds. It includes Google Kubernetes Engine (GKE) on‑prem, Istio service mesh, and Anthos Config Management for policy consistency. Google Distributed Cloud (GDC) extends services to edge sites: GDC Edge offers low‑latency infrastructure for AR/VR, 5G and industrial IoT, while GDC Hosted serves regulated industries with local deployments. Strengths include strong AI and analytics integration (BigQuery, Dataflow, Vertex AI), open‑source leadership and multi‑cloud freedom. Challenges include integration complexity for organisations tied to other ecosystems.

Clarifai Integration: Deploy Clarifai models into Anthos clusters via Kubernetes or serverless functions. Use Clarifai’s compute orchestration to schedule inference tasks across Anthos clusters and GDC Edge; pair with Clarifai’s model versioning for consistent AI behaviour across regions. For data pipelines, integrate Clarifai outputs into BigQuery or Dataflow for analytics.

Oracle Cloud@Customer & OCI Dedicated Region

Oracle’s private cloud solution, Cloud@Customer, brings the OCI (Oracle Cloud Infrastructure) stack—compute, storage, networking, databases and AI services—into customer data centres. OCI offers flexible compute options (VMs, bare metal, GPUs), comprehensive storage, high‑performance networking, autonomous databases and AI/analytics integrations. Uniform global pricing and universal credits simplify cost management. Limitations include a smaller ecosystem, learning curve and potential vendor lock‑in. Cloud@Customer suits industries deeply tied to Oracle enterprise software—finance, healthcare and government.

Clarifai Integration: Host Clarifai’s inference engine on OCI bare‑metal GPU instances within Cloud@Customer to run models on sensitive data. Use Clarifai’s local runners for offline or air‑gapped environments. When needed, connect to Oracle’s AI services for additional analytics or training.

Comparative Considerations

When selecting a public cloud extension, evaluate service breadth, integration, pricing models, ecosystem fit, and operational complexity. AWS Outposts offers the broadest service portfolio but requires a multi‑year commitment. Azure Local suits organisations already invested in Microsoft tooling. Anthos emphasises open source and multi‑cloud freedom but may require more expertise. OCI appeals to Oracle‑centric enterprises with consistent pricing.

Expert Insights

  • AWS Outposts provides low latency and regulatory compliance but may increase dependency on AWS.
  • Azure Local offers a unified developer experience across on‑prem and cloud.
  • Anthos and GDC enable build‑once, deploy‑anywhere models and pair well with AI workloads.
  • Oracle Cloud@Customer delivers high performance and integrates deeply with Oracle databases.

Enterprise Private Cloud Solutions

Quick Summary

Which enterprise solutions offer comprehensive private cloud platforms? HPE GreenLake, VMware Cloud Foundation, Nutanix Cloud Platform, IBM Cloud Private & Satellite, Dell APEX and Cisco Intersight provide turn‑key infrastructures combining compute, storage, networking and management. They emphasise security, automation and flexible consumption.

HPE GreenLake

HPE GreenLake delivers a consumption‑based private cloud where customers pay for resources as they use them. HPE installs pre‑configured hardware—compute, storage, networking—and manages capacity planning. GreenLake Central provides a unified dashboard for monitoring usage, security, cost and compliance, enabling rapid scale‑up. GreenLake supports VMs and containers, integrated with HPE’s Ezmeral for Kubernetes and with partnerships for storage and networking. Recent expansions include HPE Morpheus VM Essentials, which reduces VMware licensing costs by supporting multiple hypervisors; zero‑trust security with micro‑segmentation via Juniper; stretched clusters for failover; and Private Cloud AI bundles with NVIDIA RTX GPUs and FIPS‑hardened AI software.

Clarifai Integration: Run Clarifai inference workloads on GreenLake’s GPU‑enabled nodes using the Clarifai local runner. The consumption model aligns with variable AI workloads: pay only for the GPU hours consumed. Integrate Clarifai’s compute orchestrator with GreenLake Central to monitor model performance and resource utilisation.

VMware Cloud Foundation

VMware Cloud Foundation (VCF) unifies compute (vSphere), storage (vSAN), networking (NSX) and security in a single software‑defined data‑centre stack. It automates lifecycle management via SDDC Manager, enabling seamless upgrades and patching. The platform includes Tanzu Kubernetes Grid for container workloads, offering a consistent platform across private and public VMware clouds. An IDC study reports that VCF delivers 564 % return on investment, 42 % cost savings, 98 % reduction in downtime and 61 % faster application deployment. Built‑in security features include zero‑trust access, micro‑segmentation, encryption and IDS/IPS. VCF also supports private AI add‑ons and integrates with partner solutions for ransomware protection.

Clarifai Integration: Deploy Clarifai’s AI models on VCF clusters with GPU‑backed VMs. Use Clarifai’s compute orchestrator to allocate GPU resources across vSphere clusters, automatically scaling inference tasks. When training models, integrate with Tanzu services for Kubernetes‑native MLOps pipelines.

Nutanix Cloud Platform

Nutanix offers a hyperconverged platform combining compute, storage and virtualisation. Recent releases focus on sovereign cloud deployment with Nutanix Cloud Infrastructure 7.5, enabling orchestrated lifecycle management for multiple dark‑site environments and on‑premises control planes. Security updates include SOC 2 and ISO certifications, FIPS 140‑3 validated images, micro‑segmentation and load balancing. Nutanix Enterprise AI supports government‑ready NVIDIA AI Enterprise software with STIG‑hardened microservices. Resilience enhancements include tiered disaster recovery strategies and support for 10 000 VMs per cluster. Nutanix emphasises data sovereignty, hybrid multicloud integration and simplified management.

Clarifai Integration: Use Clarifai’s local runner to deploy AI inference on Nutanix clusters. The platform’s GPU support and micro‑segmentation align with high‑security AI workloads. Nutanix’s replication features enable cross‑site model redundancy.

IBM Cloud Private & Satellite

IBM Cloud Private (ICP) combines Kubernetes, a private Docker image repository, management console and monitoring frameworks. The community edition is free (limited to one master node); commercial editions bundle over 40 services, including developer versions of IBM software, enabling containerisation of legacy applications. IBM Cloud Satellite extends IBM Cloud services to any environment using a control plane in the public cloud and satellite locations in customers’ data centres. Satellite leverages Istio‑based service mesh and Razee for continuous delivery, enabling open‑source portability. This architecture is ideal for regulated industries requiring data residency and encryption.

Clarifai Integration: Deploy Clarifai models as containers within ICP clusters or on Satellite sites. Use Clarifai’s workflow to integrate with IBM Watson NLP or generate multimodal AI solutions. Because Satellite uses OpenShift, Clarifai’s Kubernetes operators can manage model lifecycle across on‑prem and cloud environments.

Dell APEX & Cisco Intersight

Dell’s APEX Private Cloud provides a consumption‑based infrastructure-as-a-service built on VMware vSphere Enterprise Plus and vSAN. It targets remote and branch offices and offers centralised management through the APEX console. Custom solutions allow mixing Dell’s storage, server and HCI offerings under a flexible procurement model called Flex on Demand. Cisco Intersight delivers cloud‑managed infrastructure for Cisco UCS servers and hyperconverged systems, providing a single management plane, Kubernetes services and workload optimisation.

Clarifai Integration: For Dell APEX, deploy Clarifai models on VxRail hardware, taking advantage of GPU options. Use Intersight’s Kubernetes Service to host Clarifai containers and integrate with Clarifai’s APIs for inference orchestration.

Comparative Analysis & Considerations

Enterprise solutions differ in billing models, ecosystem fit and AI readiness. HPE GreenLake emphasises consumption and zero‑trust; VMware provides a familiar VMware stack and strong ROI; Nutanix excels in sovereign deployments and resilience; IBM packages open‑source Kubernetes with enterprise tools; Dell and Cisco target edge and remote sites. Consider factors like hypervisor compatibility, GPU support, management complexity and licensing changes.

Expert Insights

  • Consumption‑based models shift CapEx to OpEx and reduce overprovisioning.
  • VMware’s unified stack yields significant cost savings and faster deployment.
  • Nutanix’s focus on sovereign cloud and AI readiness addresses regulatory and AI needs simultaneously.
  • IBM Satellite offers open‑source portability with secure control planes.

Open‑Source Private Cloud Frameworks

Quick Summary

What open‑source frameworks power private clouds? Apache CloudStack, OpenStack, OpenNebula, Eucalyptus, Red Hat OpenShift and managed services like Platform9 provide flexible foundations for building private clouds. They offer vendor independence, customization and a community‑driven ecosystem.

Apache CloudStack

Apache CloudStack is an open‑source IaaS platform that supports multiple hypervisors and provides integrated usage metering. It offers features like dashboard‑based orchestration, network provisioning and resource allocation. CloudStack appeals to organisations seeking an easy‑to‑deploy private cloud with minimal licensing costs. With built‑in support for VMware, KVM and Xen, it enables multi‑hypervisor environments.

OpenStack

OpenStack is a popular open‑source cloud operating system providing compute, storage and networking services. Benefits include cost control, vendor independence, complete infrastructure control, unlimited scalability and self‑service APIs. Its modular architecture (Nova, Cinder, Neutron, etc.) allows custom deployments. However, deploying OpenStack can be complex and requires skilled operators.

OpenNebula

OpenNebula offers an open‑source cloud platform that emphasises vendor neutrality, unified management, high availability and flexibility. It supports KVM and VMware hypervisors, Kubernetes orchestration, and integrates with NetApp and Pure Storage. OpenNebula’s AI‑ready features include NVIDIA GPU support for large language models and multi‑site federation for global operations.

Eucalyptus

Eucalyptus is a Linux‑based IaaS that provides AWS‑compatible services like EC2 and S3. It supports various network modes (Static, System, Managed), access control, elastic block storage, auto‑scaling and integration with DevOps tools like Chef and Puppet. Eucalyptus enables organisations to build private clouds that seamlessly integrate with Amazon ecosystems.

Red Hat OpenShift

Although not fully open-source (enterprise support is required), OpenShift is built on Kubernetes and provides enterprise security, CI/CD pipelines, developer‑focused tools, multi‑cloud portability and operator‑based automation. Version 4.20 emphasises security hardening, introducing post‑quantum cryptography, zero‑trust workload identity and advanced cluster security. It also enhances AI acceleration with features like LeaderWorkerSet API for distributed AI workloads and virtualization flexibility.

Platform9 & Managed Open‑Source

Platform9 offers a managed service for OpenStack and Kubernetes. Features include high availability, live migration, software‑defined networking, predictive resource rebalancing and built‑in observability. The platform supports both VMs and container workloads and can be deployed at scale across data centres or edge sites. Its vJailbreak migration tool simplifies migration from VMware or other virtualisation platforms.

Clarifai Integration

With open‑source frameworks, organisations can use Clarifai’s local runner and compute orchestration API to deploy AI models on KVM or Kubernetes clusters. The vendor‑independent nature of these frameworks ensures control and customization, allowing Clarifai models to run near data sources without proprietary lock‑in.

Expert Insights

  • Open‑source frameworks provide flexibility and avoid vendor lock‑in.
  • OpenShift 4.20’s security and AI features make it a strong choice for AI‑centric private clouds.
  • Managed services like Platform9 simplify operations while retaining open‑source benefits.

Emerging & Niche Players

Quick Summary

Which emerging platforms address specific niches? Platforms like Platform9, Civo, Nutanix NC2, IBM Cloud Satellite, Google Distributed Cloud Edge, HPE Morpheus, and AWS Local Zones cater to specialised requirements such as edge computing, developer simplicity and sovereign deployments.

Platform9

Platform9 provides a managed open‑source private cloud with features like familiar VM management, live migration, software‑defined networking and dynamic resource rebalancing. It offers both hosted and self‑hosted management planes, enabling enterprises to maintain control over security. Predictive resource rebalancing uses machine learning to optimise workloads, and built‑in observability surfaces metrics without external tools. Platform9’s hybrid capability supports edge deployments and remote sites.

Clarifai Integration: Use Platform9’s Kubernetes service to deploy Clarifai’s containerised models. The predictive resource feature can work in tandem with Clarifai’s compute orchestration to allocate GPU resources efficiently.

Civo Private Cloud

Civo is a developer‑first Kubernetes platform that provides a simple, cost‑effective private cloud. Its focus on rapid cluster provisioning and low overhead appeals to startups and development teams seeking to experiment with microservices. Civo’s managed environment offers predictable pricing, but its smaller ecosystem may limit integration options compared to major vendors.

Clarifai Integration: Deploy Clarifai models as containers on Civo clusters. Use Clarifai’s API to orchestrate inference workloads and manage models through CLI tools.

Nutanix NC2 and Sovereign Clusters

Nutanix NC2 on public clouds extends Nutanix’s hyperconverged infrastructure to AWS and Azure. The new sovereign cluster options support region‑based control planes, aligning with regulatory requirements. The platform’s security certifications and resilience enhancements cater to government and regulated industries.

IBM Cloud Satellite & Google Distributed Cloud Edge

IBM Cloud Satellite delivers a public cloud control plane and observability while running workloads locally. It uses an Istio‑based service mesh (Satellite Mesh) and integrates with IBM’s watsonx AI services. Google Distributed Cloud Edge offers a fully managed hardware and software stack for ultra‑low latency use cases such as AR/VR and 5G, built on Anthos. Both solutions enable consistent management across heterogenous sites.

Clarifai Integration: Deploy Clarifai models on Satellite or GDC Edge devices to perform inference near sensors or end‑users. Use Clarifai’s orchestrator to manage deployments across multiple edge locations.

HPE Morpheus & AWS Local Zones

HPE Morpheus VM Essentials reduces VMware licensing costs and provides multi‑hypervisor support. It introduces zero‑trust security with micro‑segmentation and stretched cluster technology for near‑zero downtime. AWS Local Zones bring select AWS services to metro areas for low‑latency access; they differ from Outposts by being provider‑owned but physically closer to users.

Comparative Insights

These emerging platforms fill gaps not addressed by mainstream solutions: Platform9 emphasises simplicity and predictive optimisation; Civo targets developers; Nutanix NC2 focuses on sovereign cloud; Satellite and GDC Edge cater to ultra‑low latency; Morpheus and Local Zones offer alternatives for cost and performance. Each can integrate with Clarifai to deliver AI inference at the edge or across multi‑cloud.

Expert Insights

  • Predictive optimisation reduces infrastructure waste.
  • Sovereign clusters satisfy regulatory and geopolitical requirements.
  • Edge platforms like GDC Edge enable latency‑sensitive AI applications.

Key Trends Shaping Private Clouds in 2026

Quick Summary

What trends are reshaping private cloud strategy?

Important trends include the surge of sovereign clouds, growing multi‑cloud adoption, end‑to‑end security & observability, edge computing and micro‑clouds, AI‑driven infrastructure, rising ARM servers, zero‑trust and confidential computing, sustainability mandates, and power/cooling constraints.

Sovereign Cloud & Regulatory Pressures

Governments increasingly require data to stay within national borders, driving demand for private and sovereign clouds. Providers respond by offering dedicated regions and sovereign clusters; companies must evaluate cross‑border compliance. Clarifai’s ability to run models entirely on‑premises helps maintain compliance with data residency laws.

Multi‑Cloud Strategies & Vendor Lock‑In

Organisations adopt multiple clouds to avoid reliance on a single vendor and optimise costs. Private clouds must interoperate with public clouds and other private environments. Tools like Anthos, Platform9 and Clarifai’s compute orchestration facilitate cross‑cloud workload management.

End‑to‑End Security & Observability

Hybrid environments create blind spots. Emerging solutions emphasise cloud identity and entitlement management and observability across clouds. Platforms like OpenShift 4.20 and HPE Morpheus incorporate zero‑trust features. Clarifai ensures models are secured with access controls and can integrate with zero‑trust architectures.

Micro‑Edge & Autonomous Clouds

Edge computing requires compact, self‑managing micro clouds. Autonomous edge clouds self‑configure and self‑heal, using AI to manage resources. Clarifai’s local runners allow AI inference on micro‑edge devices, connecting to central orchestration only when necessary.

AI‑Driven Infrastructure & GPU Diversity

The explosive demand for AI leads to AI‑first infrastructure with diverse GPU options and AI accelerators. Providers integrate GPU support (OpenNebula, GreenLake Private Cloud AI, Nutanix Enterprise AI) to meet LLM requirements. Clarifai’s platform abstracts hardware differences, enabling developers to deploy models without worrying about GPU vendor diversity.

ARM Servers & Energy Efficiency

ARM‑based servers enter mainstream due to lower power consumption and high core density. Private cloud platforms need to support heterogeneous architectures, including x86 and ARM. Clarifai’s inference engine runs on both architectures, providing flexibility.

Zero‑Trust & Confidential Computing

Security strategies shift to zero‑trust, eliminating implicit trust and verifying each request. Confidential computing encrypts data in use, protecting data even from administrators. OpenShift 4.20 introduces post‑quantum cryptography and workload identity. Confidential VMs and enclaves appear in many platforms. Clarifai uses secure enclaves to protect sensitive AI models.

Sustainability & Power/Cooling Constraints

Regulations will require organisations to disclose the environmental impact of their IT infrastructure. Data centres face power and cooling constraints; thus, efficient design, renewable energy and optimisation become priorities. Some providers offer carbon accounting dashboards. Clarifai optimises model inference to reduce compute usage and energy consumption.

Expert Insights

  • Sovereign cloud adoption will accelerate due to geopolitical tensions.
  • Multi‑cloud complexity will drive demand for management platforms like Anthos and Platform9.
  • Security innovations such as post‑quantum cryptography and confidential computing will become standard.
  • Sustainability reporting will impact purchasing decisions.

How to Evaluate & Choose the Right Private Cloud

Quick Summary

How should organisations evaluate private cloud platforms? Assess workload requirements, existing infrastructure, regulatory obligations, AI needs, cost models and vendor ecosystem. Create a shortlist by mapping must‑have capabilities to platform features and test with pilot deployments.

Step‑by‑Step Evaluation Guide

  1. Define Workload Profiles: Identify the types of workloads—transactional databases, AI/ML training or inference, analytics, web services—and their latency and throughput needs. Clarify compliance requirements (e.g., HIPAA, GDPR, FIPS) and data residency constraints.
  2. Check Architecture Compatibility: Determine whether your environment is virtualised on VMware, Hyper‑V or KVM. Choose a platform that supports existing hypervisors and container orchestration. For example, HPE Morpheus supports multiple hypervisors, whereas VMware Cloud Foundation is optimised for vSphere.
  3. Evaluate AI & GPU Support: If you run AI workloads, ensure the platform offers GPU acceleration (GreenLake AI bundles, OpenNebula GPU support, Nutanix Enterprise AI) and can integrate with Clarifai’s inference engine.
  4. Assess Security & Compliance: Look for zero‑trust architectures, micro‑segmentation, encryption, compliance certifications and support for confidential computing.
  5. Analyse Cost Models: Compare CapEx vs OpEx. HPE GreenLake’s consumption model reduces upfront investment; VMware Cloud Foundation shows ROI metrics; Oracle offers universal credits. Estimate total cost of ownership, including licensing, support and energy consumption.
  6. Consider Vendor Ecosystem & Lock‑In: Evaluate integration with existing software stacks (Microsoft, VMware, Oracle, Red Hat) and open‑source flexibility. Public cloud extensions may increase vendor lock‑in; open‑source platforms offer more independence.
  7. Test Developer Experience: Pilot projects using developer tools, CI/CD pipelines and management consoles. Observe the learning curve and productivity improvements. Solutions like Red Hat OpenShift emphasise developer productivity.
  8. Plan for Lifecycle & Observability: Ensure the platform offers automated updates, monitoring and resource optimisation. Platform9’s built‑in observability and VMware’s SDDC Manager simplify operations.
  9. Integrate AI Platform: Finally, integrate Clarifai. Use the compute orchestration API to allocate resources, deploy models via local runners or Kubernetes operators, and connect to Clarifai’s cloud for training or advanced analytics.

Comparison Table

Below is a comparison of selected platforms across key features. Note that high‑level summaries cannot capture every nuance; conduct detailed evaluations for procurement decisions.

Platform

Billing Model

AI/GPU Support

Multi‑Cloud Integration

Security Features

Unique Strengths

HPE GreenLake

Consumption‑based pay‑per‑use

Private Cloud AI with NVIDIA GPUs

Integrates with public clouds and edge

Zero‑trust micro‑segmentation, stretched clusters

Flexible hypervisor support, strong hardware portfolio

VMware Cloud Foundation

Traditional licensing with ROI benefits

GPU support via vSphere & Tanzu

Hybrid via VMware Cloud on AWS/Azure

Zero‑trust, micro‑segmentation, encryption

Unified compute, storage & networking; high ROI

Nutanix Cloud Platform

Subscription

NVIDIA AI Enterprise with STIG compliance

Multicloud with NC2 & sovereign clusters

Micro‑segmentation, ISO & FIPS certifications

Sovereign cloud focus, resilience features

IBM Cloud Private/Satellite

Subscription

GPU via OpenShift & watsonx

Satellite extends IBM Cloud anywhere

Istio‑based service mesh, encryption

Open‑source portability, strong enterprise software integration

Oracle Cloud@Customer

Universal credits, pay‑as‑you‑go

GPU instances, AI services

OCI Dedicated Region & Cloud@Customer

Isolated network virtualization, compliance

Integration with Oracle databases, consistent pricing

AWS Outposts

Multi‑year subscription

GPU options via EC2

Unified AWS ecosystem

AWS security & compliance features

Broadest service portfolio, low latency

Azure Local/Stack

Pay‑as‑you‑go

GPU support via Azure services

Hybrid via Azure Arc & public cloud

Azure’s security tools

Consistent developer experience across cloud & on‑prem

Google Anthos & GDC

Subscription

GPU via GKE & GDC Edge

Multi‑cloud across Google & other clouds

Anthos Config Management & Istio mesh

Open‑source leadership, strong AI & analytics

Dell APEX

Consumption model

GPU options via Dell hardware

Limited; more edge/branch oriented

VMware security features

Flex on Demand procurement; edge focus

OpenStack

Free (open source); paid support

GPU via integration

Federation & multi‑cloud; vendor neutral

Depends on deployment

High flexibility, community ecosystem

OpenShift

Subscription

AI acceleration & virtualization

Multi‑cloud portability

Post‑quantum cryptography, zero‑trust

Developer‑centric, CI/CD integration

Expert Insights

  • Use reserved instances and tag resources to optimise costs.
  • Design for fault and availability domains to enhance resilience.
  • Evaluate cross‑region replication for disaster recovery and latency.
  • Consider open‑source platforms for maximum control but account for operational complexity.

Best Practices for Deploying AI & ML Workloads on Private Clouds

Quick Summary

How can organisations effectively run AI and machine learning workloads on private clouds? By selecting GPU‑enabled hardware, leveraging Kubernetes and serverless frameworks, adopting MLOps practices, and integrating with Clarifai’s AI platform for model management and inference.

Hardware & GPU Considerations

AI workloads benefit from GPUs and accelerators. When building a private cloud, choose nodes with NVIDIA GPUs or other accelerators. HPE GreenLake’s Private Cloud AI bundles include NVIDIA RTX GPUs; OpenNebula offers integrated GPU support; Nutanix provides government‑ready NVIDIA AI Enterprise software.

Containerization & Orchestration

Modern AI workloads are containerised. Use Kubernetes with operators to deploy and scale models. OpenShift offers built‑in CI/CD and operator frameworks. Clarifai provides Kubernetes operators and Helm charts for deploying inference services. For batch processing, schedule jobs with Kubernetes CronJobs or serverless functions.

MLOps & Model Lifecycle

Establish pipelines for model training, validation, deployment and monitoring. Integrate tools like Kubeflow, Jenkins or GitLab CI. Clarifai’s platform includes model versioning, A/B testing and drift detection, enabling continuous learning across private clouds. Use Anthos Config Management or OpenShift GitOps to enforce consistent policies.

Edge AI & Local Inference

Deploy models near data sources to minimise latency. Use Outposts, Azure Local, GDC Edge, IBM Satellite or HPE Morpheus to run inference. Clarifai’s local runner executes models offline, synchronising results when connectivity is available. This is essential for autonomous vehicles, industrial robots and field sensors.

Security & Compliance

Protect AI models and data with encryption, access controls and isolated environments. Use zero‑trust architecture and confidential computing where possible. Implement robust logging and monitoring, integrating with platforms like VMware Aria or Platform9’s observability. Clarifai supports secure APIs and can run within encrypted enclaves.

Performance Optimization

Benchmark model performance on target hardware. Use GPU utilisation metrics and dynamic resource rebalancing (e.g., Platform9’s predictive rebalancing). Clarifai’s compute orchestrator allocates resources based on workload demands and can spin up additional nodes if necessary.

Expert Insights

  • Start small with a pilot project to validate AI workloads on the selected platform.
  • Use hybrid training: train models in public cloud for scale and deploy inference on private clouds for low latency and privacy.
  • Monitor GPU utilisation and scale horizontally to avoid bottlenecks.
  • Automate model lifecycle with MLOps pipelines integrated into the chosen cloud platform.

FAQs About Private Cloud Hosting

Quick Summary

What are the most common questions about private cloud hosting? Readers often ask about the differences between private and public clouds, cost considerations, security benefits, integration with AI platforms like Clarifai, and strategies for migration and scaling.

Frequently Asked Questions

  1. What distinguishes private cloud from public cloud? Private clouds run on dedicated infrastructure, offering greater control, security and compliance. Public clouds share resources among customers and provide broad service portfolios. Hybrid clouds combine both.
  2. Is private cloud more expensive than public cloud? Not necessarily. Consumption‑based models like HPE GreenLake and Oracle’s universal credits offer cost efficiency. However, organisations must manage hardware lifecycles and operations.
  3. How does private cloud improve security? Private clouds allow physical and logical isolation, micro‑segmentation, and zero‑trust architectures. Data residency and compliance are easier to enforce.
  4. Can I run AI workloads on a private cloud? Yes. Many platforms offer GPU support. Clarifai’s local runner and compute orchestration enable model deployment across private and edge environments.
  5. What are the risks of vendor lock‑in? Using proprietary stacks (AWS Outposts, Azure Local, Oracle Cloud@Customer) may tie you to one vendor. Open‑source frameworks and multi‑cloud platforms like Anthos mitigate this.
  6. How do I migrate from a public cloud to a private cloud? Use migration tools (e.g., VMware vMotion, Platform9’s vJailbreak) and plan for data transfer, networking, and security. Piloting workloads helps assess performance.
  7. Do private clouds support serverless and DevOps? Yes. Many platforms support containers, functions and CI/CD pipelines. OpenShift, Anthos and Platform9 provide serverless runtimes.
  8. How does Clarifai fit into private cloud strategies? Clarifai offers a comprehensive AI platform that can run on any infrastructure via local runners, Kubernetes operators and compute orchestration. This allows organisations to deploy models where data resides, maintain privacy, and scale inference across multi‑cloud environments.

Conclusion

Private cloud hosting is evolving rapidly to meet the demands of regulation, AI and edge computing. Organisations now have a rich landscape of options—from consumption‑based enterprise stacks and managed public cloud extensions to open‑source frameworks and niche providers. Key trends such as sovereign cloud, multi‑cloud strategies, zero‑trust security and sustainability shape the ecosystem. When selecting a platform, consider workload requirements, AI readiness, cost models and vendor ecosystems. Integrating a flexible AI platform like Clarifai ensures you can deploy and manage models across any environment, unlocking value from data while maintaining control, compliance and performance