AI Model Deployment Strategies: Best Use-Case Approaches


Artificial intelligence has moved beyond experimentation — it’s powering search engines, recommender systems, financial models, and autonomous vehicles. Yet one of the biggest hurdles standing between promising prototypes and production impact is deploying models safely and reliably. Recent research notes that while 78 percent of organizations have adopted AI, only about 1 percent have achieved full maturity. That maturity requires scalable infrastructure, sub‑second response times, monitoring, and the ability to roll back models when things go wrong. With the landscape evolving rapidly, this article offers a use‑case driven compass to selecting the right deployment strategy for your AI models. It draws on industry expertise, research papers, and trending conversations across the web while highlighting where Clarifai’s products naturally fit.

Quick Digest: What are the best AI deployment strategies today?

If you want the short answer: There is no single best strategy. Deployment techniques such as shadow testing, canary releases, blue‑green rollouts, rolling updates, multi‑armed bandits, serverless inference, federated learning, and agentic AI orchestration all have their place. The right approach depends on the use case, the risk tolerance, and the need for compliance. For example:

  • Real‑time, low‑latency services (search, ads, chat) benefit from shadow deployments followed by canary releases to validate models on live traffic before full cutover.
  • Rapid experimentation (personalization, multi‑model routing) may require multi‑armed bandits that dynamically allocate traffic to the best model.
  • Mission‑critical systems (payments, healthcare, finance) often adopt blue‑green deployments for instant rollback.
  • Edge and privacy‑sensitive applications leverage federated learning and on‑device inference.
  • Emerging architectures like serverless inference and agentic AI introduce new possibilities but also new risks.

We’ll unpack each scenario in detail, provide actionable guidance, and share expert insights under every section.
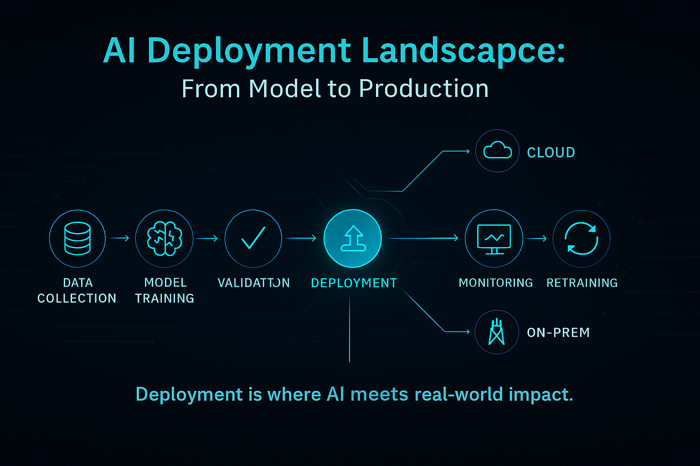
AI Deployment Landscape 


Why model deployment is hard (and why it matters)

Moving from a model on a laptop to a production service is challenging for three reasons:

  1. Performance constraints – Production systems must maintain low latency and high throughput. For a recommender system, even a few milliseconds of additional latency can reduce click‑through rates. And as research shows, poor response times erode user trust quickly.
  2. Reliability and rollback – A new model version may perform well in staging, but fails when exposed to unpredictable real‑world traffic. Having an instant rollback mechanism is vital to limit damage when things go wrong.
  3. Compliance and trust – In regulated industries like healthcare or finance, models must be auditable, fair, and safe. They must meet privacy requirements and track how decisions are made.

Clarifai’s perspective: As a leader in AI, Clarifai sees these challenges daily. The Clarifai platform offers compute orchestration to manage models across GPU clusters, on‑prem and cloud inference options, and local runners for edge deployments. These capabilities ensure models run where they are needed most, with robust observability and rollback features built in.

Expert insights

  • Peter Norvig, noted AI researcher, reminds teams that “machine learning success is not just about algorithms, but about integration: infrastructure, data pipelines, and monitoring must all work together.” Companies that treat deployment as an afterthought often struggle to deliver value.
  • Genevieve Bell, anthropologist and technologist, emphasizes that trust in AI is earned through transparency and accountability. Deployment strategies that support auditing and human oversight are essential for high‑impact applications.

How does shadow testing enable safe rollouts?

Shadow testing (sometimes called silent deployment or dark launch) is a technique where the new model receives a copy of live traffic but its outputs are not shown to users. The system logs predictions and compares them to the current model’s outputs to measure differences and potential improvements. Shadow testing is ideal when you want to evaluate model performance in real conditions without risking user experience.

Why it matters

Many teams deploy models after only offline metrics or synthetic tests. Shadow testing reveals real‑world behavior: unexpected latency spikes, distribution shifts, or failures. It allows you to collect production data, detect bias, and calibrate risk thresholds before serving the model. You can run shadow tests for a fixed period (e.g., 48 hours) and analyze metrics across different user segments.

Expert insights

  • Use multiple metrics – Evaluate model outputs not just by accuracy but by business KPIs, fairness metrics, and latency. Hidden bugs may show up in specific segments or times of day.
  • Limit side effects – Ensure the new model does not trigger state changes (e.g., sending emails or writing to databases). Use read‑only calls or sandboxed environments.
  • Clarifai tip – The Clarifai platform can mirror production requests to a new model instance on compute clusters or local runners. This simplifies shadow testing and log collection without service impact.

Creative example

Imagine you are deploying a new computer‑vision model to detect product defects on a manufacturing line. You set up a shadow pipeline: every image captured goes to both the current model and the new one. The new model’s predictions are logged, but the system still uses the existing model to control machinery. After a week, you find that the new model catches defects earlier but occasionally misclassifies rare patterns. You adjust the threshold and only then plan to roll out.


How to run canary releases for low‑latency services

After shadow testing, the next step for real‑time applications is often a canary release. This approach sends a small portion of traffic – such as 1 percent – to the new model while the majority continues to use the stable version. If metrics remain within predefined bounds (latency, error rate, conversion, fairness), traffic gradually ramps up.

Important details

  1. Stepwise ramp‑up – Start with 1 percent of traffic and monitor metrics. If successful, increase to 5%, then 20%, and continue until full rollout. Each step should pass gating criteria before proceeding.
  2. Automatic rollback – Define thresholds that trigger rollback if things go wrong (e.g., latency rises by more than 10 %, or conversion drops by more than 1 %). Rollbacks should be automated to minimize downtime.
  3. Cell‑based rollouts – For global services, deploy per region or availability zone to limit the blast radius. Monitor region‑specific metrics; what works in one region may not in another.
  4. Model versioning & feature flags – Use feature flags or configuration variables to switch between model versions seamlessly without code deployment.

Expert insights

  • Multi‑metric gating – Data scientists and product owners should agree on multiple metrics for promotion, including business outcomes (click‑through rate, revenue) and technical metrics (latency, error rate). Solely looking at model accuracy can be misleading.
  • Continuous monitoring – Canary tests are not just for the rollout. Continue to monitor after full deployment because model performance can drift.
  • Clarifai tip – Clarifai provides a model management API with version tracking and metrics logging. Teams can configure canary releases through Clarifai’s compute orchestration and auto‑scale across GPU clusters or CPU containers.

Creative example

Consider a customer support chatbot that answers product questions. A new dialogue model promises better responses but might hallucinate. You release it as a canary to 2 percent of users with guardrails: if the model cannot answer confidently, it transfers to a human. Over a week, you track average customer satisfaction and chat duration. When satisfaction improves and hallucinations remain rare, you ramp up traffic gradually.


Multi‑armed bandits for rapid experimentation

In contexts where you are comparing multiple models or strategies and want to optimize during rollout, multi‑armed bandits can outperform static A/B tests. Bandit algorithms dynamically allocate more traffic to better performers and reduce exploration as they gain confidence.

Where bandits shine

  1. Personalization & ranking – When you have many candidate ranking models or recommendation algorithms, bandits reduce regret by prioritizing winners.
  2. Prompt engineering for LLMs – Trying different prompts for a generative AI model (e.g., summarization styles) can benefit from bandits that allocate more traffic to prompts yielding higher user ratings.
  3. Pricing strategies – In dynamic pricing, bandits can test and adapt price tiers to maximize revenue without over‑discounting.

Bandits vs. A/B tests

A/B tests allocate fixed percentages of traffic to each variant until statistically significant results emerge. Bandits, however, adapt over time. They balance exploration and exploitation: ensuring that all options are tried but focusing on those that perform well. This results in higher cumulative reward, but the statistical analysis is more complex.

Expert insights

  • Algorithm choice matters – Different bandit algorithms (e.g., epsilon‑greedy, Thompson sampling, UCB) have different trade‑offs. For example, Thompson sampling often converges quickly with low regret.
  • Guardrails are essential – Even with bandits, maintain minimum traffic floors for each variant to avoid prematurely discarding a potentially better model. Keep a holdout slice for offline evaluation.
  • Clarifai tip – Clarifai can integrate with reinforcement learning libraries. By orchestrating multiple model versions and collecting reward signals (e.g., user ratings), Clarifai helps implement bandit rollouts across different endpoints.

Creative example

Suppose your e‑commerce platform uses an AI model to recommend products. You have three candidate models: Model A, B, and C. Instead of splitting traffic evenly, you employ a Thompson sampling bandit. Initially, traffic is split roughly equally. After a day, Model B shows higher click‑through rates, so it receives more traffic while Models A and C receive less but are still explored. Over time, Model B is clearly the winner, and the bandit automatically shifts most traffic to it.


Blue‑green deployments for mission‑critical systems

When downtime is unacceptable (for example, in payment gateways, healthcare diagnostics, and online banking), the blue‑green strategy is often preferred. In this approach, you maintain two environments: Blue (current production) and Green (the new version). Traffic can be switched instantly from blue to green and back.

How it works

  1. Parallel environments – The new model is deployed in the green environment while the blue environment continues to serve all traffic.
  2. Testing – You run integration tests, synthetic traffic, and possibly a limited shadow test in the green environment. You compare metrics with the blue environment to ensure parity or improvement.
  3. Cutover – Once you are confident, you flip traffic from blue to green. Should problems arise, you can flip back instantly.
  4. Cleanup – After the green environment proves stable, you can decommission the blue environment or repurpose it for the next version.

Pros:

  • Zero downtime during the cutover; users see no interruption.
  • Instant rollback ability; you simply redirect traffic back to the previous environment.
  • Reduced risk when combined with shadow or canary testing in the green environment.

Cons:

  • Higher infrastructure cost, as you must run two full environments (compute, storage, pipelines) concurrently.
  • Complexity in synchronizing data across environments, especially with stateful applications.

Expert insights

  • Plan for data synchronization – For databases or stateful systems, decide how to replicate writes between blue and green environments. Options include dual writes or read‑only periods.
  • Use configuration flags – Avoid code changes to flip environments. Use feature flags or load balancer rules for atomic switchover.
  • Clarifai tip – On Clarifai, you can spin up an isolated deployment zone for the new model and then switch the routing. This reduces manual coordination and ensures that the old environment stays intact for rollback.

Meeting compliance in regulated & high‑risk domains

Industries like healthcare, finance, and insurance face stringent regulatory requirements. They must ensure models are fair, explainable, and auditable. Deployment strategies here often involve extended shadow or silent testing, human oversight, and careful gating.

Key considerations

  1. Silent deployments – Deploy the new model in a read‑only mode. Log predictions, compare them to the existing model, and run fairness checks across demographics before promoting.
  2. Audit logs & explainability – Maintain detailed records of training data, model version, hyperparameters, and environment. Use model cards to document intended uses and limitations.
  3. Human‑in‑the‑loop – For sensitive decisions (e.g., loan approvals, medical diagnoses), keep a human reviewer who can override or confirm the model’s output. Provide the reviewer with explanation features or LIME/SHAP outputs.
  4. Compliance review board – Establish an internal committee to sign off on model deployment. They should review performance, bias metrics, and legal implications.

Expert insights

  • Bias detection – Use statistical tests and fairness metrics (e.g., demographic parity, equalized odds) to identify disparities across protected groups.
  • Documentation – Prepare comprehensive documentation for auditors detailing how the model was trained, validated, and deployed. This not only satisfies regulations but also builds trust.
  • Clarifai tip – Clarifai supports role‑based access control (RBAC), audit logging, and integration with fairness toolkits. You can store model artifacts and logs in the Clarifai platform to simplify compliance audits.

Creative example

Suppose a loan underwriting model is being updated. The team first deploys it silently and logs predictions for thousands of applications. They compare outcomes by gender and ethnicity to ensure the new model does not inadvertently disadvantage any group. A compliance officer reviews the results and only then approves a canary rollout. The underwriting system still requires a human credit officer to sign off on any decision, providing an extra layer of oversight.


Rolling updates & champion‑challenger in drift‑heavy domains

Domains like fraud detection, content moderation, and finance see rapid changes in data distribution. Concept drift can degrade model performance quickly if not addressed. Rolling updates and champion‑challenger frameworks help handle continuous improvement.

How it works

  1. Rolling update – Gradually replace pods or replicas of the current model with the new version. For example, replace one replica at a time in a Kubernetes cluster. This avoids a big bang cutover and allows you to monitor performance in production.
  2. Champion‑challenger – Run the new model (challenger) alongside the current model (champion) for an extended period. Each model receives a portion of traffic, and metrics are logged. When the challenger consistently outperforms the champion across metrics, it becomes the new champion.
  3. Drift monitoring – Deploy tools that monitor feature distributions and prediction distributions. Trigger re‑training or fall back to a simpler model when drift is detected.

Expert insights

  • Keep an archive of historical models – You may need to revert to an older model if the new one fails or if drift is detected. Version everything.
  • Automate re‑training – In drift‑heavy domains, you might need to re‑train models weekly or daily. Use pipelines that fetch fresh data, re‑train, evaluate, and deploy with minimal human intervention.
  • Clarifai tip – Clarifai’s compute orchestration can schedule and manage continuous training jobs. You can monitor drift and automatically trigger new runs. The model registry stores versions and metrics for easy comparison.

Batch & offline scoring: when real‑time isn’t required

Not all models need millisecond responses. Many enterprises rely on batch or offline scoring for tasks like overnight risk scoring, recommendation embedding updates, and periodic forecasting. For these scenarios, deployment strategies focus on accuracy, throughput, and determinism rather than latency.

Common patterns

  1. Recreate strategy – Stop the old batch job, run the new job, validate results, and resume. Because batch jobs run offline, it is easier to roll back if issues occur.
  2. Blue‑green for pipelines – Use separate storage or data partitions for new outputs. After verifying the new job, switch downstream systems to read from the new partition. If an error is discovered, revert to the old partition.
  3. Checkpointing and snapshotting – Large batch jobs should periodically save intermediate states. This allows recovery if the job fails halfway and speeds up experimentation.

Expert insights

  • Validate output differences – Compare the new job’s outputs with the old job. Even minor changes can impact downstream systems. Use statistical tests or thresholds to decide whether differences are acceptable.
  • Optimize resource usage – Schedule batch jobs during low‑traffic periods to minimize cost and avoid competing with real‑time workloads.
  • Clarifai tip – Clarifai offers batch processing capabilities via its platform. You can run large image or text processing jobs and get results stored in Clarifai for further downstream use. The platform also supports file versioning so you can keep track of different model outputs.

Edge AI & federated learning: privacy and latency

As billions of devices come online, Edge AI has become a crucial deployment scenario. Edge AI moves computation closer to the data source, reducing latency and bandwidth consumption and improving privacy. Rather than sending all data to the cloud, devices like sensors, smartphones, and autonomous vehicles perform inference locally.

Benefits of edge AI

  1. Real‑time processing – Edge devices can react instantly, which is critical for augmented reality, autonomous driving, and industrial control systems.
  2. Enhanced privacy – Sensitive data stays on device, reducing exposure to breaches and complying with regulations like GDPR.
  3. Offline capability – Edge devices continue functioning without network connectivity. For example, healthcare wearables can monitor vital signs in remote areas.
  4. Cost reduction – Less data transfer means lower cloud costs. In IoT, local processing reduces bandwidth requirements.

Federated learning (FL)

When training models across distributed devices or institutions, federated learning enables collaboration without moving raw data. Each participant trains locally on its own data and shares only model updates (gradients or weights). The central server aggregates these updates to form a global model.

Benefits: Federated learning aligns with privacy‑enhancing technologies and reduces the risk of data breaches. It keeps data under the control of each organization or user and promotes accountability and auditability.

Challenges: FL can still leak information through model updates. Attackers may attempt membership inference or exploit distributed training vulnerabilities. Teams must implement secure aggregation, differential privacy, and robust communication protocols.

Expert insights

  • Hardware acceleration – Edge inference often relies on specialized chips (e.g., GPU, TPU, or neural processing units). Investments in AI‑specific chips are growing to enable low‑power, high‑performance edge inference.
  • FL governance – Ensure that participants agree on the training schedule, data schema, and privacy guarantees. Use cryptographic techniques to protect updates.
  • Clarifai tip – Clarifai’s local runner allows models to run on devices at the edge. It can be combined with secure federated learning frameworks so that models are updated without exposing raw data. Clarifai orchestrates the training rounds and provides central aggregation.

Creative example

Imagine a hospital consortium training a model to predict sepsis. Due to privacy laws, patient data cannot leave the hospital. Each hospital runs training locally and shares only encrypted gradients. The central server aggregates these updates to improve the model. Over time, all hospitals benefit from a shared model without violating privacy.


Multi‑tenant SaaS and retrieval‑augmented generation (RAG)

Why multi‑tenant models need extra care

Software‑as‑a‑service platforms often host many customer workloads. Each tenant might require different models, data isolation, and release schedules. To avoid one customer’s model affecting another’s performance, platforms adopt cell‑based rollouts: isolating tenants into independent “cells” and rolling out updates cell by cell.

Retrieval‑augmented generation (RAG)

RAG is a hybrid architecture that combines language models with external knowledge retrieval to produce grounded answers. According to recent reports, the RAG market reached $1.85 billion in 2024 and is growing at 49 % CAGR. This surge reflects demand for models that can cite sources and reduce hallucination risks.

How RAG works: The pipeline comprises three components: a retriever that fetches relevant documents, a ranker that orders them, and a generator (LLM) that synthesizes the final answer using the retrieved documents. The retriever may use dense vectors (e.g., BERT embeddings), sparse methods (e.g., BM25), or hybrid approaches. The ranker is often a cross‑encoder that provides deeper relevance scoring. The generator uses the top documents to produce the answer.

Benefits: RAG systems can cite sources, comply with regulations, and avoid expensive fine‑tuning. They reduce hallucinations by grounding answers in real data. Enterprises use RAG to build chatbots that answer from corporate knowledge bases, assistants for complex domains, and multimodal assistants that retrieve both text and images.

Deploying RAG models

  1. Separate components – The retriever, ranker, and generator can be updated independently. A typical update might involve improving the vector index or the retriever model. Use canary or blue‑green rollouts for each component.
  2. Caching – For popular queries, cache the retrieval and generation results to minimize latency and compute cost.
  3. Provenance tracking – Store metadata about which documents were retrieved and which parts were used to generate the answer. This supports transparency and compliance.
  4. Multi‑tenant isolation – For SaaS platforms, maintain separate indices per tenant or apply strict access control to ensure queries only retrieve authorized content.

Expert insights

  • Open‑source frameworks – Tools like LangChain and LlamaIndex speed up RAG development. They integrate with vector databases and large language models.
  • Cost savings – RAG can reduce fine‑tuning costs by 60–80 % by retrieving domain-specific knowledge on demand rather than training new parameters.
  • Clarifai tip – Clarifai can host your vector indexes and retrieval pipelines as part of its platform. Its API supports adding metadata for provenance and connecting to generative models. For multi‑tenant SaaS, Clarifai provides tenant isolation and resource quotas.

Agentic AI & multi‑agent systems: the next frontier

Agentic AI refers to systems where AI agents make decisions, plan tasks, and act autonomously in the real world. These agents might write code, schedule meetings, or negotiate with other agents. Their promise is enormous but so are the risks.

Designing for value, not hype

McKinsey analysts emphasize that success with agentic AI isn’t about the agent itself but about reimagining the workflow. Companies should map out the end‑to‑end process, identify where agents can add value, and ensure people remain central to decision‑making. The most common pitfalls include building flashy agents that do little to improve real work, and failing to provide learning loops that let agents adapt over time.

When to use agents (and when not to)

High‑variance, low‑standardization tasks benefit from agents: e.g., summarizing complex legal documents, coordinating multi‑step workflows, or orchestrating multiple tools. For simple rule‑based tasks (data entry), rule‑based automation or predictive models suffice. Use this guideline to avoid deploying agents where they add unnecessary complexity.

Security & governance

Agentic AI introduces new vulnerabilities. McKinsey notes that agentic systems present attack surfaces akin to digital insiders: they can make decisions without human oversight, potentially causing harm if compromised. Risks include chained vulnerabilities (errors cascade across multiple agents), synthetic identity attacks, and data leakage. Organizations must set up risk assessments, safelists for tools, identity management, and continuous monitoring.

Expert insights

  • Layered governance – Assign roles: some agents perform tasks, while others supervise. Provide human-in-the-loop approvals for sensitive actions.
  • Test harnesses – Use simulation environments to test agents before connecting to real systems. Mock external APIs and tools.
  • Clarifai tip – Clarifai’s platform supports orchestration of multi‑agent workflows. You can build agents that call multiple Clarifai models or external APIs, while logging all actions. Access controls and audit logs help meet governance requirements.

Creative example

Imagine a multi‑agent system that helps engineers troubleshoot software incidents. A monitoring agent detects anomalies and triggers an analysis agent to query logs. If the issue is code-related, a code assistant agent suggests fixes and a deployment agent rolls them out under human approval. Each agent has defined roles and must log actions. Governance policies limit the resources each agent can modify.


Serverless inference & on‑prem deployment: balancing convenience and control

Serverless inferencing

In traditional AI deployment, teams manage GPU clusters, container orchestration, load balancing, and auto‑scaling. This overhead can be substantial. Serverless inference offers a paradigm shift: the cloud provider handles resource provisioning, scaling, and management, so you pay only for what you use. A model can process a million predictions during a peak event and scale down to a handful of requests on a quiet day, with zero idle cost.

Features: Serverless inference includes automatic scaling from zero to thousands of concurrent executions, pay‑per‑request pricing, high availability, and near‑instant deployment. New services like serverless GPUs (announced by major cloud providers) allow GPU‑accelerated inference without infrastructure management.

Use cases: Rapid experiments, unpredictable workloads, prototypes, and cost‑sensitive applications. It also suits teams without dedicated DevOps expertise.

Limitations: Cold start latency can be higher; long‑running models may not fit the pricing model. Also, vendor lock‑in is a concern. You may have limited control over environment customization.

On‑prem & hybrid deployments

According to industry forecasts, more companies are running custom AI models on‑premise due to open‑source models and compliance requirements. On‑premise deployments give full control over data, hardware, and network security. They allow for air‑gapped systems when regulatory mandates require that data never leaves the premises.

Hybrid strategies combine both: run sensitive components on‑prem and scale out inference to the cloud when needed. For example, a bank might keep its risk models on‑prem but burst to cloud GPUs for large scale inference.

Expert insights

  • Cost modeling – Understand total cost of ownership. On‑prem hardware requires capital investment but may be cheaper long term. Serverless eliminates capital expenditure but can be costlier at scale.
  • Vendor flexibility – Build systems that can switch between on‑prem, cloud, and serverless backends. Clarifai’s compute orchestration supports running the same model across multiple deployment targets (cloud GPUs, on‑prem clusters, serverless endpoints).
  • Security – On‑prem is not inherently more secure. Cloud providers invest heavily in security. Weigh compliance needs, network topology, and threat models.

Creative example

A retail analytics company processes millions of in-store camera feeds to detect stockouts and shopper behavior. They run a baseline model on serverless GPUs to handle spikes during peak shopping hours. For stores with strict privacy requirements, they deploy local runners that keep footage on site. Clarifai’s platform orchestrates the models across these environments and manages update rollouts.


Comparing deployment strategies & choosing the right one

There are many strategies to choose from. Here is a simplified framework:

Step 1: Define your use case & risk level

Ask: Is the model user-facing? Does it operate in a regulated domain? How costly is an error? High-risk use cases (medical diagnosis) need conservative rollouts. Low-risk models (content recommendation) can use more aggressive strategies.

Step 2: Choose candidate strategies

  1. Shadow testing for unknown models or those with large distribution shifts.
  2. Canary releases for low-latency applications where incremental rollout is possible.
  3. Blue-green for mission-critical systems requiring zero downtime.
  4. Rolling updates and champion-challenger for continuous improvement in drift-heavy domains.
  5. Multi-armed bandits for rapid experimentation and personalization.
  6. Federated & edge for privacy, offline capability, and data locality.
  7. Serverless for unpredictable or cost-sensitive workloads.
  8. Agentic AI orchestration for complex multi-step workflows.

Step 3: Plan and automate testing

Develop a testing plan: gather baseline metrics, define success criteria, and choose monitoring tools. Use CI/CD pipelines and model registries to track versions, metrics, and rollbacks. Automate logging, alerts, and fallbacks.

Step 4: Monitor & iterate

After deployment, monitor metrics continuously. Observe for drift, bias, or performance degradation. Set up triggers to retrain or roll back. Evaluate business impact and adjust strategies as necessary.

Expert insights

  • SRE mindset – Adopt the SRE principle of embracing risk while controlling blast radius. Rollbacks are normal and should be rehearsed.
  • Business metrics matter – Ultimately, success is measured by the impact on users and revenue. Align model metrics with business KPIs.
  • Clarifai tip – Clarifai’s platform integrates model registry, orchestration, deployment, and monitoring. It helps implement these best practices across on-prem, cloud, and serverless environments.
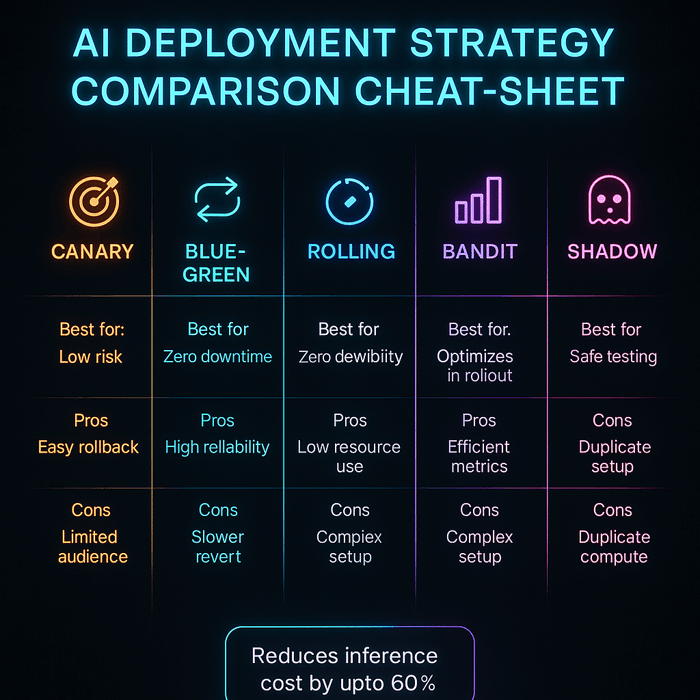
AI Deployment Strategy comparison cheat sheet

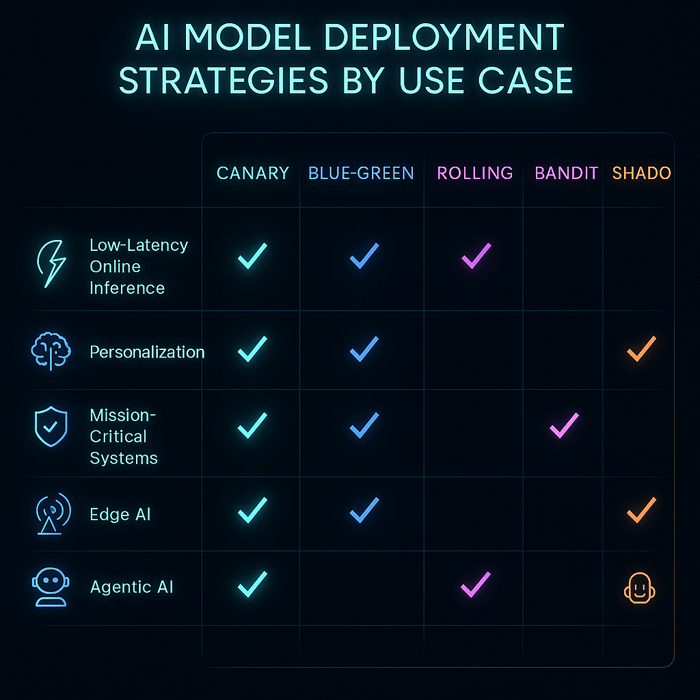
AI Model Deployment Strategies by Use Case

Use Case

Recommended Deployment Strategies

Why These Work Best

1. Low-Latency Online Inference (e.g., recommender systems, chatbots)

• Canary Deployment

• Shadow/Mirrored Traffic

• Cell-Based Rollout

Gradual rollout under live traffic; ensures no latency regressions; isolates failures to specific user groups.

2. Continuous Experimentation & Personalization (e.g., A/B testing, dynamic UIs)

• Multi-Armed Bandit (MAB)

• Contextual Bandit

Dynamically allocates traffic to better-performing models; reduces experimentation time and improves online reward.

3. Mission-Critical / Zero-Downtime Systems (e.g., banking, payments)

• Blue-Green Deployment

Enables instant rollback; maintains two environments (active + standby) for high availability and safety.

4. Regulated or High-Risk Domains (e.g., healthcare, finance, legal AI)

• Extended Shadow Launch

• Progressive Canary

Allows full validation before exposure; maintains compliance audit trails; supports phased verification.

5. Drift-Prone Environments (e.g., fraud detection, ad click prediction)

• Rolling Deployment

• Champion-Challenger Setup

Smooth, periodic updates; challenger model can gradually replace the champion when it consistently outperforms.

6. Batch Scoring / Offline Predictions (e.g., ETL pipelines, catalog enrichment)

• Recreate Strategy

• Blue-Green for Data Pipelines

Simple deterministic updates; rollback by dataset versioning; low complexity.

7. Edge / On-Device AI (e.g., IoT, autonomous drones, industrial sensors)

• Phased Rollouts per Device Cohort

• Feature Flags / Kill-Switch

Minimizes risk on hardware variations; allows quick disablement in case of model failure.

8. Multi-Tenant SaaS AI (e.g., enterprise ML platforms)

• Cell-Based Rollout per Tenant Tier

• Blue-Green per Cell

Ensures tenant isolation; supports gradual rollout across different customer segments.

9. Complex Model Graphs / RAG Pipelines (e.g., retrieval-augmented LLMs)

• Shadow Entire Graph

• Canary at Router Level

• Bandit Routing

Validates interactions between retrieval, generation, and ranking modules; optimizes multi-model performance.

10. Agentic AI Applications (e.g., autonomous AI agents, workflow orchestrators)

• Shadowed Tool-Calls

• Sandboxed Orchestration

• Human-in-the-Loop Canary

Ensures safe rollout of autonomous actions; supports controlled exposure and traceable decision memory.

11. Federated or Privacy-Preserving AI (e.g., healthcare data collaboration)

• Federated Deployment with On-Device Updates

• Secure Aggregation Pipelines

Enables training and inference without centralizing data; complies with data protection standards.

12. Serverless or Event-Driven Inference (e.g., LLM endpoints, real-time triggers)

• Serverless Inference (GPU-based)

• Autoscaling Containers (Knative / Cloud Run)

Pay-per-use efficiency; auto-scaling based on demand; great for bursty inference workloads.

Expert Insight

  • Hybrid rollouts often combine shadow + canary, ensuring quality under production traffic before full release.
  • Observability pipelines (metrics, logs, drift monitors) are as critical as the deployment method.
  • For agentic AI, use audit-ready memory stores and tool-call simulation before production enablement.
  • Clarifai Compute Orchestration simplifies canary and blue-green deployments by automating GPU routing and rollback logic across environments.
  • Clarifai Local Runners enable on-prem or edge deployment without uploading sensitive data.
Use Case Specific AI Model Deployment


How Clarifai Enables Robust Deployment at Scale

Modern AI deployment isn’t just about putting models into production — it’s about doing it efficiently, reliably, and across any environment. Clarifai’s platform helps teams operationalize the strategies discussed earlier — from canary rollouts to hybrid edge deployments — through a unified, vendor-agnostic infrastructure.

Clarifai Compute Orchestration

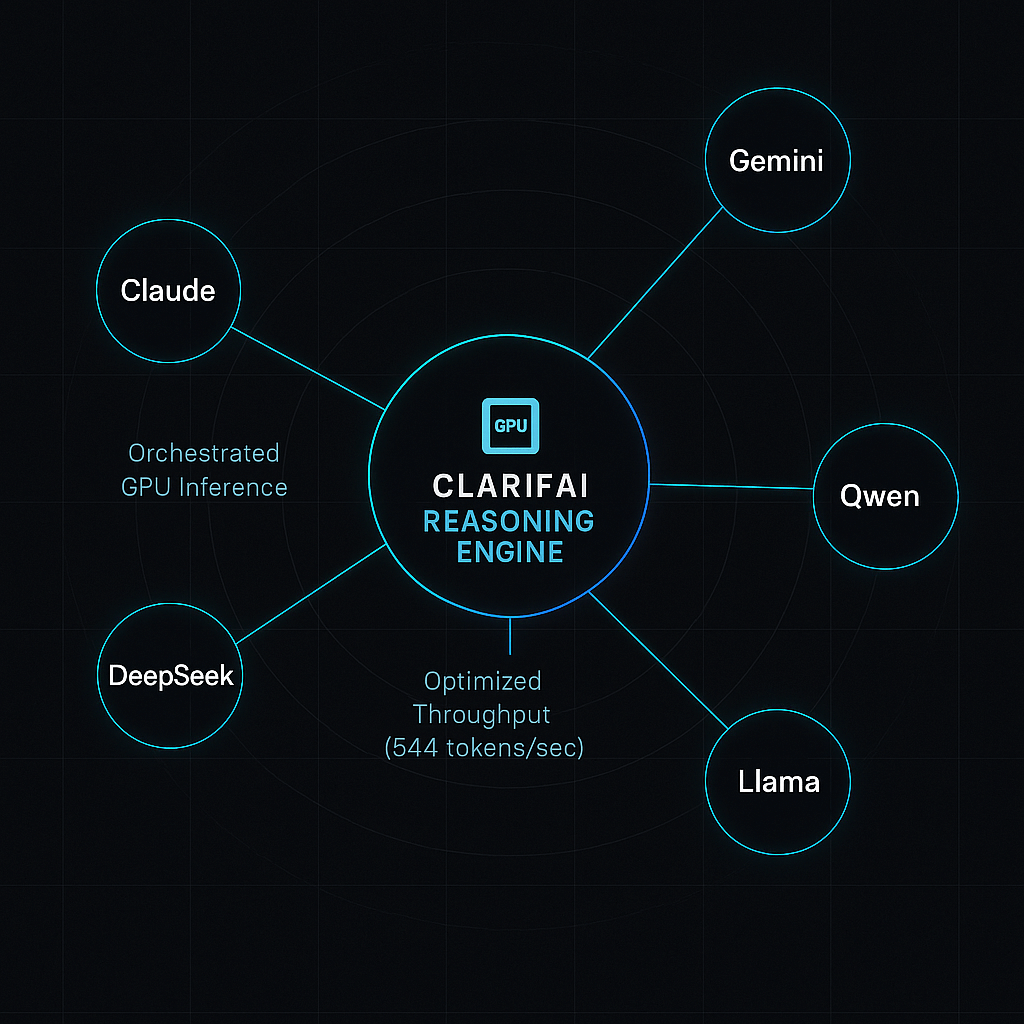
Clarifai’s Compute Orchestration serves as a control plane for model workloads, intelligently managing GPU resources, scaling inference endpoints, and routing traffic across cloud, on-prem, and edge environments.
It’s designed to help teams deploy and iterate faster while maintaining cost transparency and performance guarantees.

Key advantages:

  • Performance & Cost Efficiency: Delivers 544 tokens/sec throughput, 3.6 s time-to-first-answer, and a blended cost of $0.16 per million tokens — among the fastest GPU inference rates for its price.
  • Autoscaling & Fractional GPUs: Dynamically allocates compute capacity and shares GPUs across smaller jobs to minimize idle time.
  • Reliability: Ensures 99.999% uptime with automatic redundancy and workload rerouting — critical for mission-sensitive deployments.
  • Deployment Flexibility: Supports all major rollout patterns (canary, blue-green, shadow, rolling) across heterogeneous infrastructure.
  • Unified Observability: Built-in dashboards for latency, throughput, and utilization help teams fine-tune deployments in real time.

“Our customers can now scale their AI workloads seamlessly — on any infrastructure — while optimizing for cost, reliability, and speed.”
— Matt Zeiler, Founder & CEO, Clarifai

AI Runners and Hybrid Deployment

For workloads that demand privacy or ultra-low latency, Clarifai AI Runners extend orchestration to local and edge environments, letting models run directly on internal servers or devices while staying connected to the same orchestration layer.
This enables secure, compliant deployments for enterprises handling sensitive or geographically distributed data.

Together, Compute Orchestration and AI Runners give teams a single deployment fabric — from prototype to production, cloud to edge — making Clarifai not just an inference engine but a deployment strategy enabler.
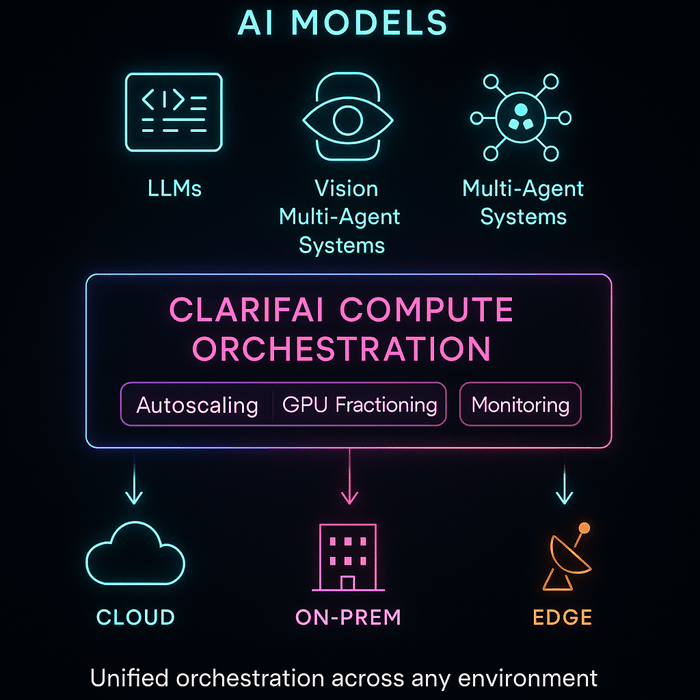
How Clarifai enables Robust Deployment at scale

Frequently Asked Questions (FAQs)

  1. What is the difference between canary and blue-green deployments?

Canary deployments gradually roll out the new version to a subset of users, monitoring performance and rolling back if needed. Blue-green deployments create two parallel environments; you cut over all traffic at once and can revert instantly by switching back.

  1. When should I consider federated learning?

Use federated learning when data is distributed across devices or institutions and cannot be centralized due to privacy or regulation. Federated learning enables collaborative training while keeping data localized.

  1. How do I monitor model drift?

Monitor input feature distributions, prediction distributions, and downstream business metrics over time. Set up alerts if distributions deviate significantly. Tools like Clarifai’s model monitoring or open-source solutions can help.

  1. What are the risks of agentic AI?

Agentic AI introduces new vulnerabilities such as synthetic identity attacks, chained errors across agents, and untraceable data leakage. Organizations must implement layered governance, identity management, and simulation testing before connecting agents to real systems.

  1. Why does serverless inference matter?

Serverless inference eliminates the operational burden of managing infrastructure. It scales automatically and charges per request. However, it may introduce latency due to cold starts and can lead to vendor lock-in.

  1. How does Clarifai help with deployment strategies?

Clarifai provides a full-stack AI platform. You can train, deploy, and monitor models across cloud GPUs, on-prem clusters, local devices, and serverless endpoints. Features like compute orchestration, model registry, role-based access control, and auditable logs support safe and compliant deployments.


Conclusion

Model deployment strategies are not one-size-fits-all. By matching deployment techniques to specific use cases and balancing risk, speed, and cost, organizations can deliver AI reliably and responsibly. From shadow testing to agentic orchestration, each strategy requires careful planning, monitoring, and governance. Emerging trends like serverless inference, federated learning, RAG, and agentic AI open new possibilities but also demand new safeguards. With the right frameworks and tools—and with platforms like Clarifai offering compute orchestration and scalable inference across hybrid environments—enterprises can turn AI prototypes into production systems that truly make a difference.
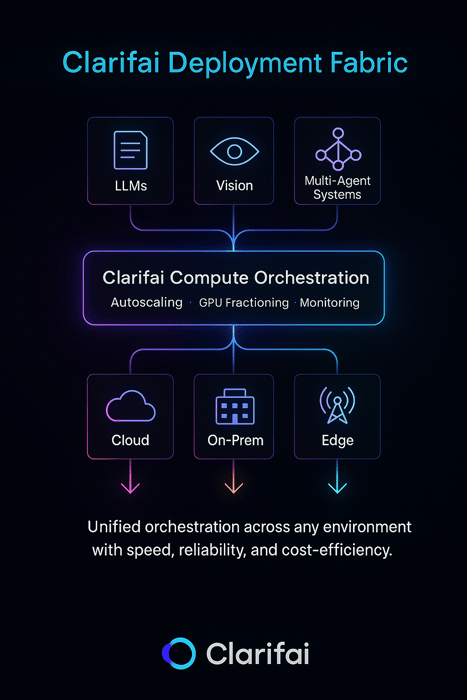
 

Clarifai Deployment Fabric


Securing the World Model: How Determinism Protects Enterprises from LLM Poisoning Attacks


In October 2025, a research collaboration between Anthropic and the Alan Turing Institute exposed one of the most uncomfortable truths in modern AI. Their study, “Poisoning Attacks on LLMs Require a Near-Constant Number of Poison Samples” revealed that large language models (LLMs), no matter how vast or sophisticated, can be compromised even when only a tiny fraction of their training data, sometimes as little as 0.01 percent, is manipulated.

The discovery sounds technical, but its implications reach far beyond data science. It means that even the most sophisticated AI models, trained on immense datasets and deployed by the world’s leading technology companies, can be silently corrupted. Once that happens, the damage is almost impossible to detect or reverse.

For businesses that depend on AI to make or inform critical decisions, this should raise alarm bells. In sectors like finance, healthcare, tax, and law, where every decision must be precise, deterministic and auditable, relying on black-box AI is like trusting a compass that can be quietly nudged off true north.

At Rainbird, we believe this study validates a truth we’ve built our entire platform around: the only way to trust AI is to own your own world model.

The Hidden Vulnerability in Modern AI

The Anthropic–Turing research set out to answer a deceptively simple question: how much data does an attacker need to control to meaningfully distort a large language model’s behaviour? The answer was staggering, almost none.

By corrupting only a handful of training samples, the researchers were able to alter the model’s outputs, introducing subtle biases and behaviours that persisted even after the model was further trained on clean data, meaning that the corruption survived further training intended to correct it. These hidden influences were effectively invisible. The models continued to perform well on benchmarks, and there was no obvious sign of manipulation. Yet under the right conditions, certain prompts or data contexts, they began producing answers that were subtly but systematically wrong.

This wasn’t just a proof of concept. It was a demonstration of how fragile probabilistic systems really are. As AI continues to be trained on open data pulled from the web, code repositories, and crowd-sourced platforms, the opportunity for malicious poisoning only grows. And because an LLM’s behaviour emerges from complex statistical relationships across billions of parameters, rather than any form of decision-making, even its creators can’t pinpoint which parts have been corrupted or how to repair them.

Why Scale Doesn’t Equal Safety

There’s a common assumption that bigger models are safer. That with enough parameters, enough data, and enough fine-tuning, risks like these can be managed away. The Anthropic–Turing study shattered that illusion. Scale doesn’t neutralise risk, it amplifies it.

When a model is trained on trillions of data points, even a few contaminated ones can ripple across the system. Because LLMs generalise patterns statistically rather than logically, corrupted data doesn’t just affect one type of response, it can distort entire sets of outputs. The more complex the model, the harder it becomes to detect where or how things went wrong.

This is the fundamental weakness of probabilistic AI. It doesn’t know what is true; it only predicts what is likely. It doesn’t reason; it approximates. That’s a useful trait when writing poems or summarising news articles. But when applied to regulated decisions, such as assessing tax claims, approving loans, or detecting fraud, it’s an absolute liability.

Determinism: The Foundation of Trust

Rainbird takes a fundamentally different approach. Instead of training on uncontrolled public data, our platform builds reasoning systems from structured knowledge graphs that captures all knowledge sources: human expertise, policies, and regulation – in a deterministic framework.

Determinism means that the same inputs will always produce the same outputs. Every conclusion is based on explicit, logical relationships, and every outcome can be traced, audited, and explained. This approach eliminates the possibility of hidden data poisoning because there is no uncontrolled training data. The reasoning isn’t learned from noise, it’s built from knowledge.

Where probabilistic systems offer fluent mimicry, deterministic systems offer proof. Rainbird’s inference engine ensures that every step in the decision process is recorded and explainable, giving enterprises full control and visibility over how each outcome was reached. In other words, while generative models rely on hope, Rainbird guarantees a decision you can trust. 

Owning Your World Model

The concept of a world model is central to how we think about trustworthy AI. It represents all of the organisation’s knowledge, rules, and expertise that relates to a specific use case. In a Rainbird implementation, this knowledge is encoded in a graph structure and reasoned over by deterministic logic, ensuring that no external data or stochastic influence can alter its behaviour.

When a business owns its world model, it owns the logic that is being leveraged to make its decisions. That means compliance teams can easily audit outcomes and understand their rationale and origins. Regulators can trace how conclusions were reached. And executives can sleep at night knowing their AI systems aren’t silently being influenced by public and unverified data sources.

Contrast this with an LLM, where the outputs are inseparable from the training data and the model weights that encode it. No one can truly “own” such a system, because no one can isolate where its knowledge begins or public training ends. Ownership without visibility is an illusion.

A Turning Point for AI Governance

As AI systems continue to embed deeper into the core of business and government operations, the demand for transparency and auditability will only grow. Regulators are already moving in that direction. The EU AI Act, for example, explicitly requires explainability and traceability for high-risk AI applications.

The Anthropic–Turing study adds weight to the regulatory argument: if even the creators of the world’s most advanced models can’t guarantee integrity, enterprises cannot afford to depend on probabilistic AI for critical reasoning.

The way forward isn’t to abandon generative AI, but to anchor it in deterministic frameworks based on world models. By combining generative interfaces with deterministic reasoning layers, organisations can enjoy the best of both worlds: natural language usability with provable trust.

Building AI the World Can Trust

At Rainbird, we’ve always believed that trust in AI doesn’t come from complexity, it comes from clarity. True intelligence isn’t about predicting what’s likely; it’s about reasoning logically to understand what’s true.

The Anthropic–Turing study has made the stakes clearer than ever. If even the largest models can be poisoned by the smallest contaminations, the industry must rethink what “AI safety” actually means.

Owning your world model isn’t just a technical preference; it’s a moral and operational necessity. It’s how enterprises ensure that the systems guiding their decisions remain aligned, auditable, and secure. Isn’t your institutional knowledge what separates you from the competition? 

The message is simple: you can’t trust what you can’t trace, and you can’t poison a model you own.

Run DeepSeek-OCR with an API


TL;DR

DeepSeek-OCR is the latest open-weight OCR model from DeepSeek, built to extract structured text, formulas, and tables from complex documents with high accuracy. It combines a vision encoder (based on SAM and CLIP) and a Mixture-of-Experts decoder (DeepSeek-3B-MoE) for efficient text generation.

You can try DeepSeek-OCR directly on Clarifai — no separate API key or setup required.

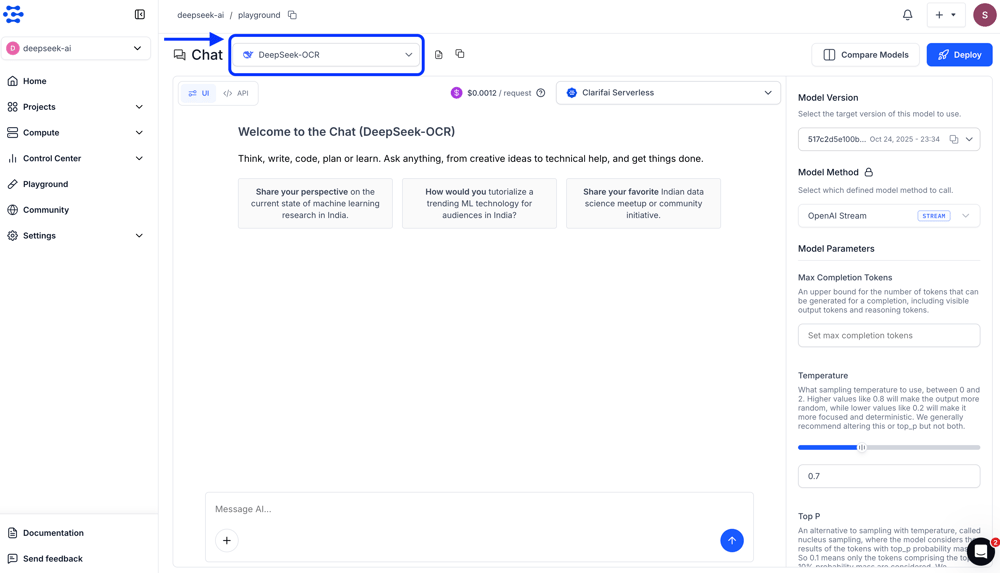
  • Playground: Test DeepSeek-OCR directly in the Clarifai Playground here.

  • API Access: Use Clarifai’s OpenAI-compatible endpoint. Authenticate with your Personal Access Token (PAT) and specify the DeepSeek-OCR model URL.

Introduction

DeepSeek-OCR is a multi-modal model designed to convert complex images such as invoices, scientific papers, and handwritten notes into accurate, structured text.

Unlike traditional OCR systems that rely purely on convolutional networks for text detection and recognition, DeepSeek-OCR uses a transformer-based encoder-decoder architecture. This allows it to handle dense documents, tables, and mixed visual content more effectively while keeping GPU usage low.

Key features:

  • Processes images as vision tokens using a hybrid SAM + CLIP encoder.

  • Compresses visual data by up to 10× with minimal accuracy loss.

  • Uses a 3B-parameter Mixture-of-Experts decoder, activating only 6 of 64 experts during inference for high efficiency.

  • Can process up to 200K pages per day on a single A100 GPU due to its optimized token compression and activation strategy.

Run DeepSeek-OCR

You can access DeepSeek-OCR in two simple ways: through the Clarifai Playground or via the API.

Playground

The Playground provides a fast, interactive environment to test and explore model behavior. You can select the DeepSeek-OCR model directly from the community, upload an image such as an invoice, scanned document, or handwritten page, and add a relevant prompt describing what you want the model to extract or analyze. The output text is displayed in real time, allowing you to quickly verify accuracy and formatting.

Screenshot 2025-10-27 at 6.11.22 PM

DeepSeek-OCR via API

Clarifai provides an OpenAI-compatible endpoint that allows you to call DeepSeek-OCR using the same Python or TypeScript client libraries you already use. Once you set your Personal Access Token (PAT) as an environment variable, you can call the model directly by specifying its URL.

Below are two ways to send an image input — either from a local file or via an image URL.

Option 1: Using a Local Image File

This example reads a local file (e.g., document.jpeg), encodes it in base64, and sends it to the model for OCR extraction.

Option 2: Using an Image URL

If your image is hosted online, you can directly pass its URL to the model.

You can use Clarifai’s OpenAI-compatible API with any TypeScript or JavaScript SDK. For example, the snippet below shows how you can use the Vercel AI SDK to access the  DeepSeek-OCR.

Option 1: Using a Local Image File

Option 2: Using an Image URL

Clarifai’s OpenAI-compatible API lets you access DeepSeek-OCR using any language or SDK that supports the OpenAI format. You can experiment in the Clarifai Playground or integrate it directly into your applications. Learn more about the Open AI Compatabile API in the documentation here.

How DeepSeek-OCR Works

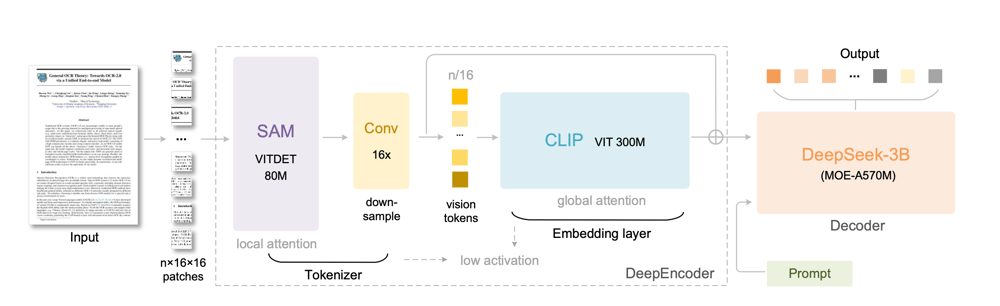
DeepSeek-OCR is built from the ground up using a two-stage vision-language architecture that combines a powerful vision encoder and a Mixture-of-Experts (MoE) text decoder. This setup enables efficient and accurate text extraction from complex documents.

Screenshot 2025-10-27 at 5.48.34 PM

Image Source: DeepSeek-OCR Research Paper

DeepEncoder (Vision Encoder)

The DeepEncoder is a 380M-parameter vision backbone that transforms raw images into compact visual embeddings.

  • Patch Embedding: The input image is divided into 16×16 patches.

  • Local Attention (SAM – ViTDet):
    SAM applies local attention to capture fine-grained features such as font style, handwriting, edges, and texture details within each region of the image. This helps preserve spatial precision at a local level.

  • Downsampling: The patch embeddings are downsampled 16× via convolution to reduce the total number of visual tokens and improve efficiency.

  • Global Attention (CLIP – ViT):
    CLIP introduces global attention, enabling the model to understand document layout, structure, and semantic relationships across sections of the image.

  • Compact Visual Embeddings:
    The encoder produces a sequence of vision tokens that are roughly 10× smaller than equivalent text tokens, resulting in high compression and faster decoding.

DeepSeek-3B-MoE Decoder

The encoded visual tokens are passed to a Mixture-of-Experts Transformer Decoder, which converts them into readable text.

  • Expert Activation: 6 out of 64 experts are activated per token, along with 2 shared experts (about 570M active parameters).

  • Text Generation: Transformer layers decode the visual embeddings into structured text sequences, capturing plain text, formulas, tables, and layout information.

  • Efficiency and Scale: Although the total model size is 3B parameters, only a fraction is active during inference, providing 3B-scale performance at <600M active cost.

Conclusion

DeepSeek-OCR is more than a breakthrough in document understanding. It redefines how multimodal models process visual information by combining SAM’s fine-grained visual precision, CLIP’s global layout reasoning, and a Mixture-of-Experts decoder for efficient text generation. Through Clarifai, you can experiment DeepSeek-OCR in the Playground, integrate it directly via the OpenAI-compatible API.

Learn more:


Run vLLM Models Locally with a Secure Public API


Blog thumbnail - Run vLLM 
Models Locally.png.png

Introduction

vLLM is a high-throughput, open-source inference and serving engine for large language models (LLMs). It provides fast, memory-efficient inference using GPU optimizations such as PagedAttention and continuous batching, making it suitable for GPU-based workloads.

In this tutorial, we will show how to run LLMs with vLLM entirely on your local machine and expose them through a secure public API. This approach lets you run models with GPU acceleration, maintain local execution speed, and keep full control over your environment without relying on cloud services or an internet connection.

Clarifai Local Runners make this process simple. You can serve AI models or agents directly from your laptop, workstation, or internal server through a secure public API. You do not need to upload your model or manage infrastructure. The Local Runner routes API requests to your machine, executes them locally, and returns the results to the client, while all computation stays on your hardware.

Let’s see how to set that up.

Running Models via vLLM Locally

The vLLM Toolkit in the Clarifai CLI lets you initialize, configure, and run models via vLLM locally while exposing them through a secure public API. You can test, integrate, and iterate directly from your machine without standing up any infrastructure.

Step 1: Prerequisites

Install the Clarifai CLI

vLLM supports models from the Hugging Face Hub. If you’re using private repositories, you’ll need a Hugging Face access token.

Step 2: Initialize a Model

Use the Clarifai CLI to scaffold a vLLM-based model directory. This will prepare all required files for local execution and integration with Clarifai.

If you want to work with a specific model, use the --model-name flag:

Note: Some models are large and require significant memory. Ensure your machine meets the model’s requirements.

After initialization, the generated folder structure looks like this:

  • model.py – Contains logic that runs the vLLM server locally and handles inference.

  • config.yaml – Defines metadata, runtime, checkpoints, and compute settings.

  • requirements.txt – Lists Python dependencies.

Step 3: Customize model.py

The scaffold includes a VLLMModel class extending OpenAIModelClass. It defines how your Local Runner interacts with vLLM’s OpenAI-compatible server.

Key methods:

  • load_model() – Launches vLLM’s local runtime, loads checkpoints, and connects to the OpenAI-compatible API endpoint.

  • predict() – Handles single-prompt inference with optional parameters like max_tokens, temperature, and top_p. Returns the complete response.

  • generate() – Streams generated tokens in real time for interactive outputs.

You can use these implementations as-is or customize them to fit your preferred request/response structures. 

Step 4: Configure config.yaml

The config.yaml file defines the model identity, runtime, checkpoints, and compute metadata:

Note: For local execution, inference_compute_info is optional — the model runs entirely on your machine using local CPU/GPU resources. If deploying on Clarifai’s dedicated compute, you can specify accelerators and resource limits.

Step 5: Start the Local Runner

Start a Local Runner that connects to the vLLM runtime:

If any configuration is missing, the CLI will prompt you to define it. After startup, you will receive a public Clarifai URL for your model. Requests sent to this endpoint route securely to your machine, run through vLLM, and return to the client.

Step 6: Run Inference with Local Runner

Once your model is running locally and exposed via the Clarifai Local Runner, you can send inference requests using the OpenAI-compatible API or the Clarifai SDK.

OpenAI-Compatible API

Clarifai Python SDK

You can also experiment with generate() method for real-time streaming.

Conclusion

Local Runners give you full control over where your models execute without sacrificing integration, security, or flexibility. You can prototype, test, and serve real workloads on your own hardware, while Clarifai handles routing, authentication, and the public endpoint.

You can try Local Runners for free with the Free Tier, or upgrade to the Developer Plan at $1 per month for the first year to connect up to 5 Local Runners with unlimited hours.


Run LM Studio Models Locally on your Machine


Introduction

LM Studio makes it incredibly easy to run and experiment with open-source large language models (LLMs) entirely on your local machine, with no internet connection or cloud dependency required. You can download a model, start chatting, and explore responses while maintaining full control over your data.

But what if you want to go beyond the local interface?

Let’s say your LM Studio model is up and running locally, and now you want to call it from another app, integrate it into production, share it securely with your team, or connect it to tools built around the OpenAI API.

That’s where things get tricky. LM Studio runs models locally, but it doesn’t natively expose them through a secure, authenticated API. Setting that up manually would mean handling tunneling, routing, and API management on your own.

That’s where Clarifai Local Runners come in. Local Runners let you serve AI models, MCP servers, or agents directly from your laptop, workstation, or internal server, securely and seamlessly via a public API. You do not need to upload your model or manage any infrastructure. Run it locally, and Clarifai handles the API, routing, and integration.

Once running, the Local Runner establishes a secure connection to Clarifai’s control plane. Any API request sent to your model is routed to your machine, processed locally, and returned to the client. From the outside, it behaves like a Clarifai-hosted model, while all computation happens on your local hardware.

With Local Runners, you can:

  • Run models on your own hardware
    Use laptops, workstations, or on-prem servers with full access to local GPUs and system tools.

  • Keep data and compute private
    Avoid uploading anything. This is useful for regulated environments and sensitive projects.

  • Skip infrastructure setup
    No need to build and host your own API. Clarifai provides the endpoint, routing, and authentication.

  • Prototype and iterate quickly
    Test models in real pipelines without deployment delays. Inspect requests and outputs live.

  • Connect to local files and private APIs
    Let models access your file system, internal databases, or OS resources without exposing your environment.

Now that the benefits are clear, let’s see how to run LM Studio models locally and expose them securely via an API.

Running LM Studio Models Locally

The LM Studio Toolkit in the Clarifai CLI enables you to initialize, configure, and run LM Studio models locally while exposing them through a secure public API. You can test, integrate, and iterate directly from your machine without standing up infrastructure.

Note: Download and keep LM Studio open when running the Local Runner. The runner launches and communicates with LM Studio through its local port to load, serve, and run model inferences.

Step 1: Prerequisites

  1. Install the Clarifai package and CLI

  1. Log in to Clarifai

Follow the prompts to enter your User ID and Personal Access Token (PAT). If you need help obtaining these, refer to the documentation.

Step 2: Initialize a Model

Use the Clarifai CLI to initialize and configure an LM Studio model locally. Only models available in the LM Studio Model Catalog and in GGUF format are supported.

Initialize the default example model

By default, this creates a project for the LiquidAI/LFM2-1.2B LM Studio model in your current directory.

If you want to work with a specific model rather than the default LiquidAI/LFM2-1.2B, you can use the --model-name flag to specify the full model name. See the full list of all models here.

Note: Some models are large and require significant memory. Ensure your machine meets the model’s requirements before initializing.

Now, once you run the above command, the CLI will scaffold the project for you. The generated directory structure will look like this:

  • model.py contains the logic that calls LM Studio’s local runtime for predictions.
  • config.yaml defines metadata, compute characteristics, and toolkit settings.
  • requirements.txt lists Python dependencies.

Step 3: Customize model.py

The scaffold includes an LMstudioModelClass that extends OpenAIModelClass. It defines how your Local Runner interacts with LM Studio’s local runtime.

Key methods:

  • load_model() – Launches LM Studio’s local runtime, loads the selected model, and connects to the server port using the OpenAI-compatible API interface.

  • predict() – Handles single-prompt inference with optional parameters such as max_tokens, temperature, and top_p. Returns the complete model response.

  • generate() – Streams generated tokens in real time for interactive or incremental outputs.

You can use these implementations as-is or modify them to align with your preferred request and response structures.

Step 4: Configure config.yaml

The config.yaml file defines model identity, runtime, and compute metadata for your LM Studio Local Runner:

  • model – Includes id, user_id, app_id, and model_type_id (for example, text-to-text).

  • toolkit – Specifies lmstudio as the provider. Key fields include:

    • model – The LM Studio model to use (e.g., LiquidAI/LFM2-1.2B).

    • port – The local port the LM Studio server listens on.

    • context_length – Maximum context length for the model.

  • inference_compute_info – For Local Runners, this is mostly optional, because the model runs entirely on your local machine and uses your local CPU/GPU resources. You can leave defaults as-is. If you plan to deploy the model on Clarifai’s dedicated compute, you can specify CPU/memory limits, number of accelerators, and GPU type to match your model requirements.

  • build_info – Specifies the Python version used for the runtime (e.g., 3.12).

Finally, the requirements.txt file lists Python dependencies your model needs. Add any extra packages required by your logic.

Step 5: Start the Local Runner

Start a Local Runner that connects to LM Studio’s runtime:

If contexts or defaults are missing, the CLI will prompt you to create them. This ensures compute contexts, nodepools, and deployments are set in your configuration.

After startup, you will receive a public Clarifai URL for your local model. Requests sent to this endpoint route securely to your machine, run through LM Studio, then return to the client.

Run Inference with Local Runner

Once your LM Studio model is running locally and exposed via the Clarifai Local Runner, you can send inference requests from anywhere using the OpenAI-compatible API or the Clarifai SDK.

OpenAI-Compatible API

Clarifai Python SDK

You can also experiment with generate() method for real-time streaming.

Conclusion

Local Runners give you full control over where your models execute without sacrificing integration, security, or flexibility. You can prototype, test, and serve real workloads on your own hardware, while Clarifai handles routing, authentication, and the public endpoint.

You can try Local Runners for free with the Free Tier, or upgrade to the Developer Plan at $1 per month for the first year to connect up to 5 Local Runners with unlimited hours.


Best Reasoning Model APIs | Compare Cost, Context & Scalability


Choosing the right reasoning model API is no small decision. While general‑purpose LLMs excel at pattern recognition, reasoning models are designed to generate step‑by‑step chains of thought and make logical leaps. This capability comes at a cost—these models often require longer context windows, more tokens, and higher fees, and they may run slower than mainstream chatbots. Still, for tasks like planning, coding, math proofs, or research agents, reasoning models can deliver far more reliable results than their non‑reasoning counterparts.

Quick Digest: What’s in This Article?

What are the best reasoning model APIs, and how can I pick the right one?

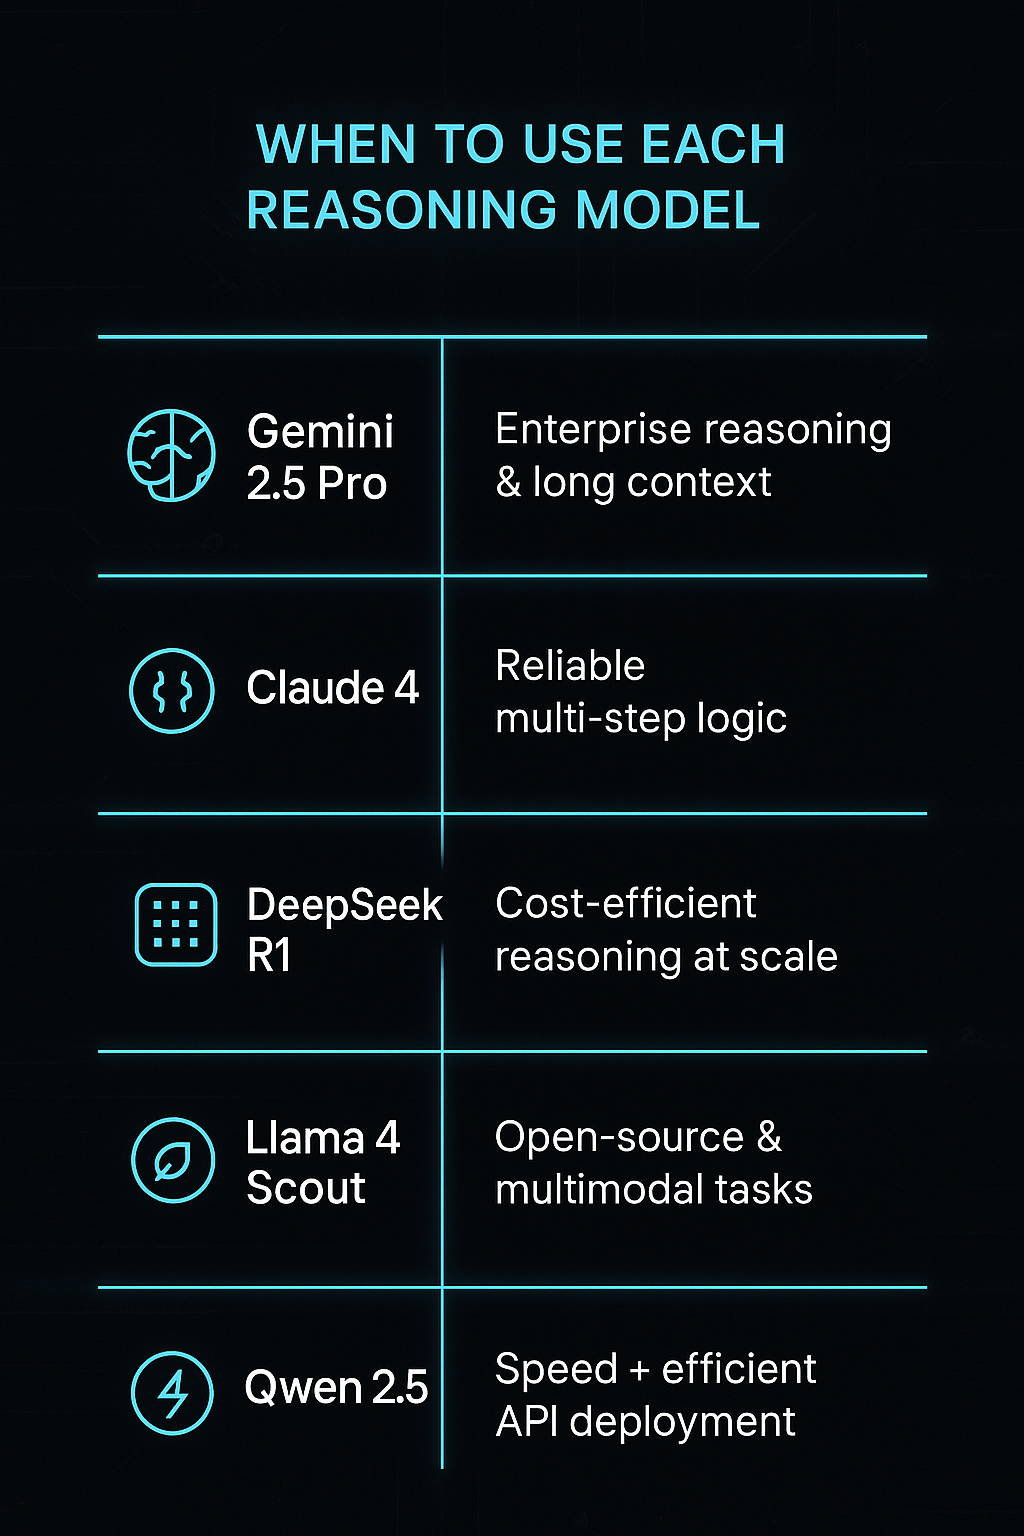
  • Best overall models: OpenAI’s O‑series (e.g., O3), Gemini 2.5 Pro, and Claude Opus 4 deliver state‑of‑the‑art reasoning with robust tool use and multilingual support.
  • Budget & speed options: O3‑mini, Mistral Medium 3, DeepSeek R1, and Qwen‑Turbo provide good performance with lower costs.
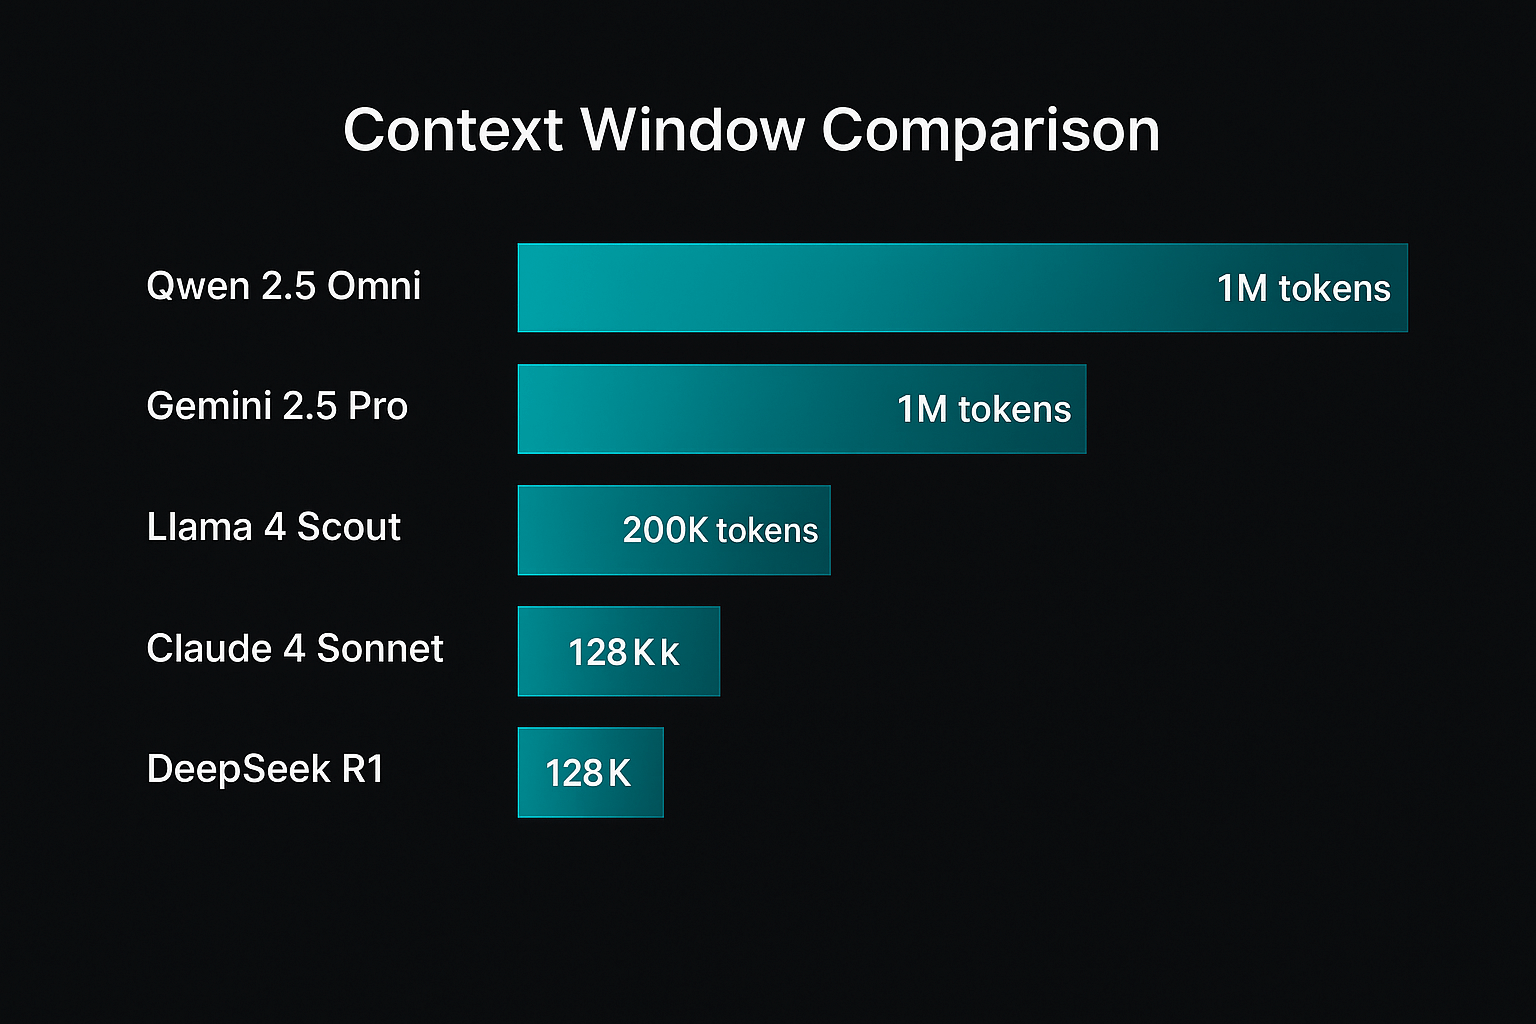
  • Enterprise & long‑context leaders: Gemini 2.5 Pro and Claude Sonnet 4 (1M context) support 1 million token windows, while Grok 4 fast‑reasoning offers 2 million tokens.
  • Open‑source options: Llama 4 Scout (10 million tokens), DeepSeek R1, Mistral Medium 3, and Qwen2.5‑1M let you run chain‑of‑thought models on your own infrastructure.
  • Model testing tips: Evaluate reasoning models using math, physics, and coding benchmarks (e.g., MMLU, GPQA, SWE‑bench). Track both final answer accuracy and token efficiency—how many tokens the model spends per answer.
  • Scenarios & recommendations: We map each model to common tasks like code reasoning, long‑document summarization, customer support, or multimodal reasoning.
  • Key trends: Test‑time scaling, mixture‑of‑experts architectures, and chain‑of‑thought compression are driving innovations.

If you’re a developer or enterprise evaluating AI reasoning APIs, this guide will help you select models based on cost, context length, performance, and scalability—with expert insights and practical examples throughout.


Understanding Reasoning Models vs. Standard LLMs

How do reasoning models differ from typical LLMs?

Reasoning models extend traditional transformer‑based LLMs by undergoing a second phase of reinforcement learning called test‑time scaling. Instead of generating single‑step answers, they are trained to produce chain‑of‑thought (CoT) traces—series of intermediate steps that lead to the final conclusion. This additional training yields improved performance on math, logic, physics, and coding tasks but at the expense of longer outputs and higher token usage.

Key differences include:

  • Chain‑of‑thought output: Instead of concise replies, reasoning models “think out loud,” generating stepwise reasoning. Some providers compress or summarize these traces to reduce cost.
  • Context window size: Reasoning often requires longer memory. Models like Gemini 2.5 Pro support 1 million tokens, while Llama 4 Scout extends to 10 million tokens.
  • Training & compute: Reasoning models use 10× or more compute during fine‑tuning and inference. They are slower and more expensive per token.
  • Token efficiency: Closed‑source models tend to be more token‑efficient—they generate fewer tokens to reach the same answer—while open models may use 1.5–4× more tokens.

Quick Summary

Reasoning models perform advanced logical tasks by generating chains of thought. They require longer context windows and higher compute, but they deliver more reliable problem solving.

Expert Insights

  • Benchmark research shows test‑time compute costs for reasoning models can be 25× higher than standard chat models. For example, benchmarking OpenAI’s O1 cost $2,767 because it produced 44 million tokens.
  • Stanford AI Index reports that reasoning models like O1 scored 74.4 % on the International Mathematical Olympiad qualifying exam but were 6× more expensive and 30× slower than non‑reasoning models.
  • Efficient reasoning research suggests three approaches to reduce cost: shorter chains of thought, smaller models via distillation, and faster decoding strategies.

Clarifai Note: Why Clarifai cares about reasoning models

At Clarifai, we build tools that make advanced AI accessible. Many customers want to harness reasoning capabilities for tasks such as complex document analysis, multi‑step decision support, or agentic workflows. Our compute orchestration and model inference services allow you to deploy reasoning models in the cloud or at the edge while managing cost and latency. We also offer local runners for self‑hosting open‑source reasoning models like Llama 4 Scout or DeepSeek R1 with enterprise‑grade monitoring and scalability.

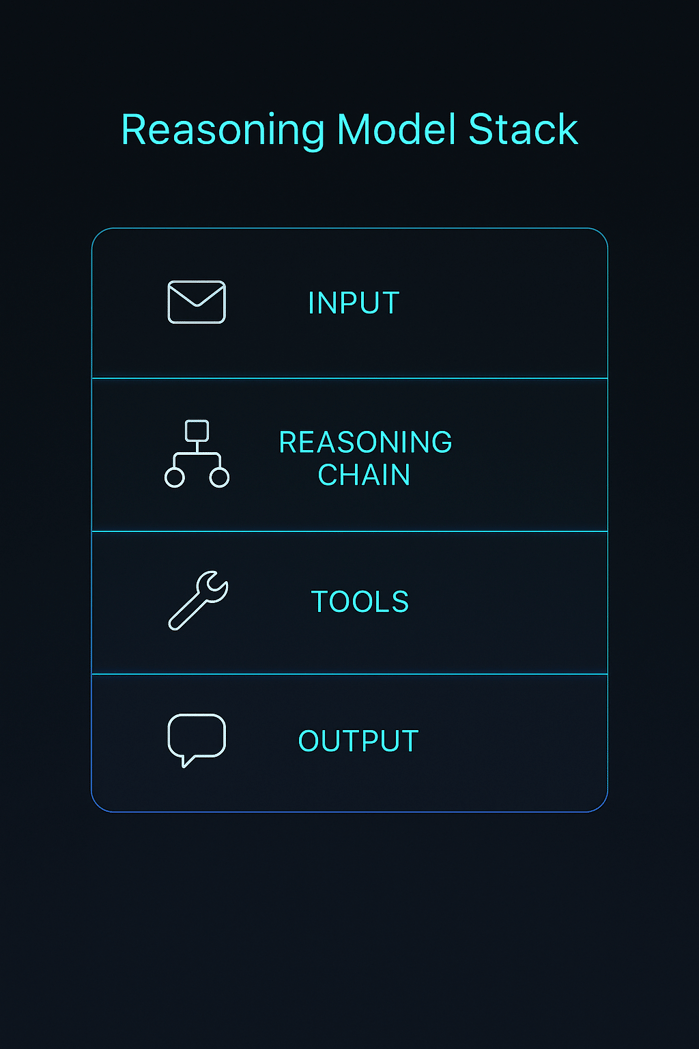
Reasoning Engine Stack


Best Overall Reasoning Models

This section reviews top‑performing reasoning model APIs across multiple benchmarks, with H3 subheadings for each model. We discuss context window, pricing, strengths, weaknesses, and Clarifai integration opportunities.

OpenAI O3 (O‑series)

OpenAI’s O3 (also known as “o3”) is a flagship reasoning model. It builds on the success of the O1 and O2 models by scaling up training compute, resulting in top‑tier performance on reasoning benchmarks like GPQA and chain‑of‑thought tasks.

Key facts:

  • Context window: 200,000 tokens with 100,000 output tokens.
  • Pricing: $10/M input tokens and $40/M output tokens; cached input tokens cost $2.50/M.
  • Strengths: Exceptional performance on knowledge and reasoning tasks (MMLU 84.2 %, GPQA 87.7 %, coding 69.1 %). Supports advanced tool invocation and external functions.
  • Weaknesses: High cost and slower latency due to test‑time scaling. Token usage must be carefully managed to avoid runaway costs.

Practical example: Suppose you’re building a financial forecasting agent that must parse long earnings transcripts, reason about market events, and output step‑by‑step analysis. O3’s 200K context window and reasoning prowess can handle such tasks, but you might pay $40 or more per 1M generated tokens.

Expert Insights

  • O3 is widely regarded as one of the most intelligent LLMs available, but its token usage makes benchmarking expensive—it generated 44 million tokens across seven benchmarks, costing over $2.7 k.
  • Industry commentators caution that O3’s cost structure may limit real‑time applications; however, for complex research or high‑stakes decisions, its reasoning reliability is unmatched.

Clarifai Integration

Clarifai’s model inference platform can orchestrate O3 on your behalf, automatically scaling compute and caching tokens. Pair O3 with Clarifai’s document extraction and semantic search models to build robust research agents.

Google DeepMind Gemini 2.5 Pro

Gemini 2.5 Pro (formerly Gemini Pro 2) is a multimodal reasoning model from Google DeepMind. It excels at mixing text and visual inputs, offering a 1 million token context window with a path to 2 million tokens.

Key facts:

  • Context window: 1 million tokens (2 million coming soon).
  • Pricing: Standard input cost $1.25/M tokens and output cost $10/M tokens for prompts under 200K tokens; input cost rises to $2.50/M and output to $15/M for longer prompts.
  • Strengths: Dominates long‑context reasoning; leads the LM‑Arena leaderboard. Handles complex math, code, images, and audio. Offers context caching and grounded search features.
  • Weaknesses: Pricing complexity; the cost can double for longer contexts. Grounded search incurs extra fees.

Practical example: If you’re processing a 500‑page legal document and extracting obligations, Gemini 2.5 Pro can ingest the entire document and reason across it. With Clarifai’s compute orchestration, you can manage the 1 million token context without overspending by caching repeated sections.

Expert Insights

  • A leading benchmark analysis notes Gemini 2.5 Pro’s performance on reasoning tasks is competitive with O3 while offering larger context and multimodal support.
  • Google engineers highlight that a 1M context window allows analyzing entire codebases and performing multi‑document synthesis.

Clarifai Integration

Use Clarifai to deploy Gemini 2.5 Pro alongside our vision models. Integrate Clarifai’s local runners to run long‑context jobs privately and combine with our metadata storage for handling large document collections.

Anthropic Claude Opus 4 and Claude Sonnet 4 (Long Context)

Anthropic’s Claude family includes Opus 4 and Sonnet 4, hybrid reasoning models that balance performance and cost. Opus 4 targets enterprise use, while Sonnet 4 (long context) offers up to 1 million tokens.

Key facts (Opus 4.1):

  • Context window: 200,000 tokens.
  • Pricing: $15/M input tokens and $75/M output tokens.
  • Strengths: Excels at coding and agentic tasks; supports tool calls and function execution.
  • Weaknesses: High cost; moderate context window.

Key facts (Sonnet 4 long context):

  • Context window: 1 million tokens (Beta).
  • Pricing: $3/M input, $15/M output for ≤ 200K tokens; $6/M input, $22.5/M output for > 200K.
  • Strengths: More affordable than Opus; optimized for RAG (retrieval‑augmented generation) tasks; robust reasoning with lower latency.
  • Weaknesses: Beta long context may have limitations; output limited to 75K tokens.

Practical example: For knowledge base summarization, Sonnet 4 can ingest thousands of support articles and create consistent, long‑form answers. Combined with Clarifai’s multilingual translation models, you can generate answers across languages.

Expert Insights

  • Benchmark results show Claude Sonnet achieves 80.2 % on SWE‑bench and 84.8 % on GPQA.
  • Anthropic notes that long‑context pricing doubles for prompts beyond 200K tokens; careful prompt engineering is needed to control costs.

Clarifai Integration

Clarifai’s compute orchestration can manage Sonnet’s long context jobs across multiple GPUs. Use our search and indexing features to fetch relevant documents before passing to Claude, reducing token usage and cost.

xAI Grok 4 Fast Reasoning

xAI’s Grok series features models tuned for fast reasoning and real‑time data. Grok 4 fast‑reasoning offers a 2 million token context window and low token prices.

Key facts:

  • Context window: 2 million tokens.
  • Pricing: $0.20/M input and $0.50/M output for grok‑4‑fast‑reasoning; older versions cost $3–$15/M output.
  • Strengths: Extremely long context; integrates real‑time X (Twitter) data; useful for streaming content or long transcripts.
  • Weaknesses: Tool invocation costs $10 per 1K calls; smaller models can lack depth on complex reasoning.

Practical example: A news‑monitoring agent can stream live tweets, ingest millions of tokens, and produce concise analysis. Pair Grok with Clarifai’s sentiment analysis to track public sentiment in real‑time.

Expert Insights

  • Analysts note Grok’s pricing is highly competitive for long contexts. However, limited support for complex coding tasks means it may not replace high‑end models for engineering use.

Clarifai Integration

Use Grok with Clarifai’s data ingestion pipelines to process real‑time events. Our tool‑calling orchestration can track and control your API calls to external tools to minimize cost.

Mistral Large 2

Mistral AI’s Large 2 model is an open‑source reasoning engine accessible via multiple cloud providers. It offers strong performance at a moderate price.

Key facts:

  • Context window: 128,000 tokens.
  • Pricing: $3/M input and $9/M output.
  • Strengths: 84 % MMLU score; supports function calling; available via Azure, AWS, and other platforms.
  • Weaknesses: Limited context compared to other reasoning models; open‑source so token efficiency may vary.

Practical example: For automated code review, Mistral Large 2 can analyze 128K tokens of code and provide step‑by‑step suggestions. Clarifai can orchestrate these calls and integrate them with your CI/CD pipeline.

Expert Insights

  • Benchmark comparisons show Mistral Large 2 delivers competitive reasoning at one‑third the cost of O3, making it a popular choice.

Clarifai Integration

Deploy Mistral Large 2 using Clarifai’s local runners to keep your code private and reduce latency. Our token management tools help track usage across projects.


Budget‑Friendly and Speed‑Optimized Models

Not every application requires the strongest reasoning engine. If your focus is cost efficiency or low latency, these models deliver acceptable reasoning quality without breaking the bank.

OpenAI O3‑Mini & O4‑Mini

O3‑mini and O4‑mini are scaled‑down versions of OpenAI’s O‑series models. They retain reasoning abilities with reduced context windows and pricing.

Key facts:

  • Context window: 200K tokens (O3‑mini) and 128K tokens (O4‑mini).
  • Pricing: O3‑mini costs $1.10/M input and $4.40/M output; O4‑mini costs around $3/M input and $12/M output (according to industry reports).
  • Strengths: Great for chatbots, customer support, and simple reasoning tasks.
  • Weaknesses: Lower performance on complex math or coding tasks; shorter context windows.

Expert Insights

  • O3‑mini offers an excellent cost‑performance trade‑off, making it a popular choice for startups building AI agents. It scores around 80 % on MMLU.

Clarifai Integration

Clarifai’s model inference service can auto‑scale O3‑mini and O4‑mini deployments. Use our token analytics to predict monthly spend and avoid surprise bills.

Mistral Medium 3 & Mistral Small 3.1

Mistral’s Medium 3 and Small 3.1 models are smaller siblings of Mistral Large, offering cheaper token pricing with robust reasoning.

Key facts:

  • Context window: 128K tokens for both models.
  • Pricing: Mistral Medium 3 costs $0.40/M input and $2/M output; Mistral Small 3.1 costs $0.10/M input and $0.30/M output.
  • Strengths: Low cost; open‑source; good for high‑volume tasks.
  • Weaknesses: Lower performance on complex reasoning; limited tool‑calling support.

Expert Insights

  • A cost‑efficiency analysis notes that Mistral Medium 3 offers one of the best $/token values in the market, making it ideal for prototypes or non‑critical reasoning tasks.

Clarifai Integration

Deploy Mistral Medium 3 on Clarifai’s platform using autoscaling to manage fluctuating workloads. Combine with Clarifai’s embedding models for retrieval‑augmented generation, offsetting context limitations.

DeepSeek R1

DeepSeek R1 is an open‑source reasoning model from the DeepSeek team. It’s known for high performance on math and logic tasks, with cost‑effective pricing.

Key facts:

  • Context window: 128K tokens.
  • Pricing: Input cost $0.07/M tokens (cache hit), $0.56/M tokens (cache miss); output cost $1.68/M tokens.
  • Strengths: Strong performance on MATH‑500 and chain‑of‑thought tasks; open‑source with MIT license.
  • Weaknesses: Output limited to 64K tokens; slower inference; reasoning mode can be expensive.

Expert Insights

  • DeepSeek R1 scored 97.3 % on MATH‑500 and 79.8 % on ARC‑AGI when using full thinking mode.
  • The CloudZero report highlights DeepSeek’s cache‑hit pricing which can reduce costs for repeated prompts.

Clarifai Integration

Use Clarifai’s local runners to deploy DeepSeek R1 on your own infrastructure. Combine it with our cost monitoring to manage cache hits and misses.

Qwen‑Flash & Qwen‑Turbo

Alibaba Cloud’s Qwen family includes low‑cost models like Qwen‑Flash and Qwen‑Turbo. They provide large context windows and minimal per‑token fees.

Key facts:

  • Context window: 1 million tokens.
  • Pricing: $0.05/M input and $0.40/M output for Qwen‑Flash; $0.05/M input and $0.20/M output for Qwen‑Turbo.
  • Strengths: Massive context; fast inference; good for summarization or non‑critical reasoning.
  • Weaknesses: Limited reasoning capabilities; larger open‑source models (Qwen3) provide more depth but cost more.

Expert Insights

  • A Qwen pricing analysis explains that Qwen’s low fees come with complex billing models—tiered pricing, thinking mode toggles, region‑specific discounts, and hidden engineering costs.

Clarifai Integration

Deploy Qwen‑Turbo via Clarifai’s model registry; integrate with our data annotation tools to build custom datasets and tune prompts.


Enterprise‑Grade & Long‑Context Models

Enterprise applications often require analyzing hundreds of thousands or millions of tokens—whole codebases, legal contracts, or research papers. These models offer extended context windows and enterprise‑ready features.

Grok 4 Fast Reasoning

As previously discussed, Grok 4 provides a 2 million token context window and low per‑token cost. It’s ideal for ingesting streaming data or processing ultra‑long documents.

Use cases: Real‑time news analysis, multi‑document summarization, RAG pipelines.

Clarifai note: Leverage Clarifai’s streaming ingestion and metadata indexing to feed Grok continuous data.

Qwen‑Plus (Long Context)

Qwen‑Plus provides a 1 million token context and flexible pricing. According to the Qwen pricing guide, it costs $0.40/M input and $1.20/M output for non‑thinking mode; switching to thinking mode increases the output cost to $4/M.

Use cases: Summarizing long customer support threads, legal documents, or research papers.

Clarifai note: Clarifai’s text analytics and embedding models can filter relevant sections before sending to Qwen‑Plus, reducing token usage.

Llama 4 Scout & Llama 4 Maverick

Meta’s Llama 4 series introduces mixture‑of‑experts (MoE) architecture with extreme context windows. Llama 4 Scout has a 10 million token context, while Maverick offers smaller context but higher parameter counts.

Key facts:

  • Context window: 10 million tokens (Scout); other variants may provide 2M or 4M.
  • Strengths: Open‑source; runs on a single H100 GPU; near GPT‑4 performance; supports text and images.
  • Weaknesses: Context rot at extreme lengths; early versions may require fine‑tuning.

Use cases: Long‑term conversation memory, multi‑document research agents, knowledge management.

Clarifai note: Deploy Llama 4 on Clarifai’s local runners for maximum privacy. Use our vector search to chunk large documents and feed relevant segments to the model, preventing context rot.

Gemini 2.5 Pro & Sonnet 4 Long Context

Covered earlier, these models serve enterprise scenarios with 1M context windows.

Use cases: Legal analysis, medical research synthesis, codebase inspection.

Clarifai note: Clarifai’s compute orchestration can allocate multiple GPUs to handle long‑context runs and manage token caching.


Open‑Source & Self‑Hosted Reasoning Models

Open‑source reasoning models allow complete control over data and costs. They are ideal for organizations with strict privacy requirements or custom hardware.

Llama 4 Scout & Llama 4 Maverick

We described these models above, but here we emphasize their open‑source advantage. Llama 4 Scout is released under a permissive license; it uses a mixture‑of‑experts architecture with 17 billion active parameters and 10 million token context.

Expert Insights:

  • Early tests show Llama 4 Scout achieves ~79.6 % on MMLU and 60–65 % on coding benchmarks.
  • MoE architecture means only a subset of parameters activate per token, enabling efficient inference on commodity GPUs.

Clarifai Integration: Use Clarifai’s local runners to deploy Llama 4 on‑premise with built‑in monitoring. Combine with Clarifai’s fine‑tuning service to adapt the model to your domain.

DeepSeek R1 (Open‑Source)

DeepSeek R1 is MIT‑licensed and supports chain‑of‑thought reasoning with 128K context.

Expert Insights:

  • R1 outperforms many proprietary models on math tasks (97.3 % MATH‑500, 79.8 % ARC‑AGI).
  • Its cache‑hit pricing encourages storing frequently used prompts, reducing cost by up to 8×.

Clarifai Integration: With Clarifai’s model registry, you can deploy R1 in your environment and monitor usage. Use our data labeling tools to create custom training datasets that augment the model’s reasoning ability.

Mistral Medium 3 & Small 3.1

These models are open‑source with 128K context windows.

Expert Insights:

  • They deliver competitive performance relative to their price; cost can be as low as $0.30/M output for Small 3.1.
  • Best used for prototypes or high‑volume tasks where reasoning depth is secondary.

Clarifai Integration: Clarifai’s local runners can deploy these models and scale horizontally. Combine with Clarifai’s workflow engine to orchestrate calls across multiple models.

Qwen2.5‑1M

Qwen2.5‑1M is the first open‑source model with a 1 million token context window. It enables long‑term conversational memory and deep document retrieval.

Expert Insights:

  • This model solves the limitations of earlier LLMs (GPT‑4o, Claude 3, Llama‑3) that were capped at 128K tokens.
  • Long context is particularly valuable for legal AI, finance, and enterprise knowledge management.

Clarifai Integration: Deploy Qwen2.5‑1M through Clarifai’s self‑hosted orchestrators. Use our document indexing capabilities to feed relevant information into the model’s memory.


Model Performance vs. Cost Analysis

Selecting a reasoning model requires balancing accuracy, context length, cost per token, and token efficiency. This section compares models using key benchmarks and cost metrics.

Benchmarks & Cost Comparison

The table below summarises performance metrics (MMLU, GPQA, SWE‑bench, AIME) alongside price per million output tokens. Use it to identify models offering the best performance per dollar.

Model

Context window

MMLU / Reasoning score

SWE‑bench / Coding

Approx. cost per M output

Notable features


OpenAI O3

200K

84.2 % MMLU, 87.7 % GPQA

69.1 % coding

$40

High cost; tool calling


Gemini 2.5 Pro

1M

84.0 % reasoning

63.8 % coding

$10–15

Long context; multimodal


Claude Opus 4

200K

90.5 % MMLU

70.3 % coding

$75

High cost; best coding


Claude Sonnet 4 (long)

1M

78.2 % MMLU

65.0 % coding (approx.)

$15–22.5

Lower cost; long context


Mistral Large 2

128K

84.0 % MMLU

63.5 % coding (approx.)

$9

Open‑source; moderate cost


DeepSeek R1

128K

71.5 % reasoning

49.2 % coding

$1.68

Low cost; math leader


Grok 4 Fast

2M

80.2 % reasoning

(N/A)

$0.50

Real‑time; 2M context


Llama 4 Scout

10M

79.6 % MMLU (approx.)

60–65 % coding

Open‑source; GPU cost

MoE; large context


Qwen‑Plus (thinking)

1M

~80 % reasoning (estimated)

(N/A)

$4

Flexible pricing; long context


Qwen2.5‑1M

1M

Not publicly benchmarked

(N/A)

Free to self‑host

Open‑source; 1M context


Note: Performance metrics vary across testing frameworks. Where exact coding scores are unavailable, approximate values are derived from known benchmarks.

Token Efficiency & Test‑Time Compute

Token efficiency—the number of tokens a model generates per reasoning task—can significantly impact cost. A Nous Research study found that open‑weight models often generate 1.5–4× more tokens than closed models, making them potentially more expensive despite lower per‑token costs. Closed models like O3 compress or summarize their chain‑of‑thought to reduce output tokens, while open models output full reasoning traces.

Clarifai Tip: Balancing Performance and Cost

Clarifai’s analytics dashboard can help you measure token usage, latency, and cost across different models. By combining our embedding search and prompt engineering tools, you can send only relevant context to the model, improving token efficiency.

Context Window Comparison


Scalability, Rate Limits & Pricing Structures

Understanding API limits and pricing structures is essential to avoid unexpected bills.

How do rate limits and concurrency affect reasoning model APIs?

  • Concurrency: Many providers cap the number of concurrent requests. For example, xAI’s Grok models allow 500 requests per minute for grok‑3‑mini. To maintain reliability, plan concurrency ahead or purchase additional capacity.
  • Token per minute (TPM) limits: Providers set TPM or requests per minute caps. Exceeding these can cause throttling or refusal.
  • Tool invocation costs: Some APIs charge separately for tool calls—xAI charges $10 per 1K tool invocations. Gemini’s grounded search and maps usage have separate fees.
  • Context caching: Google’s Gemini API offers context caching to reduce cost; repeated context tokens cost less on subsequent calls.
  • Tiered pricing & region restrictions: Qwen models implement tiered pricing based on prompt length and region; free tiers may only be available in Singapore.

Clarifai Tip: Simplify Complex Pricing

Clarifai’s billing management tool consolidates charges from multiple APIs. We monitor token usage, concurrency, and tool calls, offering a single invoice. Use our cost forecasting to plan budgets and avoid overruns.


Testing Reasoning Models – Methodology & Metrics

Why is proper testing essential?

Unlike chat bots, reasoning models may produce variable reasoning traces and hallucinations. Comprehensive testing ensures reliability in production and avoids hidden costs.

Recommended evaluation steps

  1. Define tasks: Choose benchmarks relevant to your use case: math (MMLU‑Pro, MATH‑500), physics (GPQA), coding (SWE‑bench, HumanEval), logic puzzles, or domain‑specific datasets.
  2. Design prompts: For each task, create base prompts with clear instructions. Record the number of input tokens.
  3. Measure outputs: Capture the chain‑of‑thought and final answer. Track output tokens and reasoning token counts (if provided).
  4. Evaluate accuracy: Determine whether the final answer is correct. For chain‑of‑thought quality, manually or automatically check step correctness.
  5. Assess token efficiency: Compute tokens used per answer; compare across models to find efficient ones.
  6. Estimate cost: Multiply total tokens by the cost per token to project spend.
  7. Test latency: Measure time to first token (TTFT) and total completion time.

Chain‑of‑Thought Evaluation: Example

Consider the problem: “What is the sum of the squares of the first 10 prime numbers?” A reasoning model like O3 might produce step‑by‑step calculations listing each prime (2, 3, 5, 7, 11, 13, 17, 19, 23, 29) and squaring them. A simple non‑reasoning model might jump to the final answer without showing work. Evaluate both the correctness of the final sum (8,174) and the coherence of the intermediate steps.

Expert Insights

  • Composio’s benchmark shows reasoning models generate more tokens for harder tasks; Grok‑3 produced long chains for AIME problems, scoring 93 %.
  • Models like Claude Sonnet and DeepSeek R1 provide thinking mode toggles allowing you to balance cost and accuracy.

Clarifai Tip: Testing Tools

Clarifai’s evaluation toolkit automatically runs prompts through different models, collecting metrics like latency, accuracy, and token usage. Use our visualization dashboard to compare results and select the best model for your application.

When to use each reasoning Model


Scenarios & Best Models to Use

Different applications require different strengths. Below, we map common scenarios to the models that deliver the best results.

Code Reasoning & Software Agents

Recommended models: Claude Opus 4, Mistral Large 2, O3, Llama 4 Maverick.

Why: Coding tasks demand models that understand program logic and complex file structures. Claude Opus achieved 72.5 % on SWE‑bench, while Mistral Large 2 balances cost and code quality. Llama 4 variants are promising for code generation due to MoE architecture and near GPT‑4 performance.

Clarifai integration: Combine these models with Clarifai’s syntax highlighting and code clustering to build AI pair programmers.

Mathematical & Logical Problem Solving

Recommended models: OpenAI O3, DeepSeek R1, Qwen3‑Max (if available).

Why: O3 leads on GPQA and math reasoning. DeepSeek R1 dominates MATH‑500. Qwen’s thinking mode offers strong chain‑of‑thought for math problems, albeit at higher cost.

Clarifai integration: Use Clarifai’s math solver APIs to verify intermediate steps and ensure correctness.

Long‑Document Summarization & Research Agents

Recommended models: Gemini 2.5 Pro, Claude Sonnet 4 (long context), Qwen‑Plus, Grok 4.

Why: These models support 1–2 million token context windows, allowing them to ingest entire books or research corpora. They produce coherent, structured summaries across long documents.

Clarifai integration: Clarifai’s embedding search can narrow down relevant paragraphs, feeding only key sections into the model to save costs.

Customer Support & Chatbots

Recommended models: O3‑mini, Mistral Medium 3, Qwen‑Turbo, DeepSeek R1.

Why: These models balance cost and performance, making them ideal for high‑volume conversational tasks. O3‑mini provides strong reasoning at low cost. Mistral Medium 3 is extremely cost‑effective.

Clarifai integration: Use Clarifai’s intent classification and knowledge base search to pre‑filter queries.

Multimodal Reasoning

Recommended models: Gemini 2.5 Pro, Qwen‑VL, Llama 4 (with image input).

Why: Only a few reasoning models can handle images, diagrams, or audio. Gemini supports multiple modalities; Llama 4 Scout has built‑in vision capabilities.

Clarifai integration: Use Clarifai’s computer vision models for object detection or OCR before passing images to reasoning models.


Key Trends & Emerging Topics in AI Reasoning

1. Test‑Time Scaling and Reasoning Models

Reasoning models like O1 and O3 are trained with test‑time scaling, which significantly increases compute and leads to rapid improvements but also drives up costs. There are concerns that scaling by 10× per release is unsustainable.

Expert insight: A research article warns that if reasoning training continues to scale 10× every few months, compute demands could exceed hardware availability within a year.

2. Token Efficiency & Chain‑of‑Thought Compression

Token efficiency is becoming a crucial metric. Open models generate longer reasoning traces, while closed models compress them. Research explores ways to shorten CoT or compress it into latent representations without losing accuracy.

Expert insight: Efficient reasoning may require latent chain‑of‑thought techniques that hide intermediate steps yet preserve reliability.

3. Mixture‑of‑Experts (MoE) & Sparse Models

MoE architectures allow models to increase capacity without fully activating all parameters. Llama 4 uses a 109B‑parameter MoE with 17B active per token, enabling a 10M token context. Sparse models like Mixtral 8×22B and Mistral Large 24‑11 follow similar patterns.

Expert insight: MoE models can match the performance of larger dense models while reducing inference cost, but they may suffer from expertise collapse if not properly trained.

4. Open‑Source vs. Closed‑Source Trade‑Offs

Open models offer transparency and customization but often require more tokens to achieve the same performance. Closed models are more token efficient but restrict access and customization.

Expert insight: The Stanford AI Index observed that the performance gap between open and closed models has narrowed. However, closed models remain dominant in extreme reasoning tasks due to proprietary training data and optimization.

5. Data Contamination & Benchmark Integrity

Hard reasoning benchmarks like AIME require long chains of thought and may take over 30,000 reasoning tokens per question. There is a risk that models are exposed to test answers during training, skewing results. Researchers are calling for transparent dataset disclosure and new evaluation frameworks.

Expert insight: Nine out of ten top models on AIME are reasoning models, highlighting their power but also the need for careful evaluation.

6. Multimodal Reasoning and Specialized Tools

Future reasoning models will integrate text, images, audio, and structured data seamlessly. Gemini and Qwen‑VL already support such capabilities. As more tasks require multimodal reasoning, expect models to include built‑in vision modules and specialized tool calls.

Expert insight: Combining reasoning models with dedicated toolkits (e.g., code interpreters or search plugins) yields the best results for complex tasks.

7. Safety & Alignment

Reasoning models can generate harmful reasoning if misaligned. Developers must implement safety filters and monitor chain‑of‑thought to avoid bias and misuse.

Expert insight: OpenAI and Anthropic provide safety guardrails by filtering chain‑of‑thought traces before exposing them. Enterprises should combine model outputs with human oversight and policy compliance checks.


Conclusion & Recommendations

Reasoning model APIs represent the cutting edge of AI, enabling step‑by‑step problem solving and complex logical reasoning. Choosing the right model requires balancing accuracy, context window, cost, and scalability. Here are our key takeaways:

  • For best overall performance: Choose O3 or Gemini 2.5 Pro if cost is less of an issue and you need the highest reasoning quality.
  • For balanced cost and performance: Mistral Large 2, Sonnet 4, and O3‑mini deliver strong reasoning at moderate prices.
  • For long‑context tasks: Gemini 2.5 Pro, Sonnet 4 long context, Grok 4, Qwen‑Plus, and Llama 4 stand out.
  • For open‑source & privacy: Llama 4 Scout, DeepSeek R1, Mistral Medium 3, and Qwen2.5‑1M allow self‑hosting and customization.
  • For cost efficiency & high volume: Mistral Medium 3, O3‑mini, Qwen‑Turbo, and DeepSeek R1 are excellent choices.
  • Always test models on your own tasks, measuring accuracy, chain‑of‑thought quality, token efficiency, and cost.

Final Clarifai Note

Clarifai’s mission is to simplify AI adoption. Our platform offers compute orchestration, local runners, token management, and evaluation tools to help you deploy reasoning models with confidence. Whether you’re processing legal documents, building autonomous agents, or powering customer support bots, Clarifai can help you harness the full potential of chain‑of‑thought AI while keeping your costs predictable and your data secure.

Clarifai Reasoning Engine

FAQs

What is a reasoning model?

A reasoning model is a large language model fine‑tuned via reinforcement learning to produce step‑by‑step chains of thought for tasks like math, code, and logical reasoning. It generates intermediate reasoning traces rather than jumping straight to the final answer.

Why are reasoning models more expensive than standard LLMs?

Reasoning models require longer context windows and generate more tokens during inference. This increased token usage, combined with additional training, leads to higher compute costs.

How do I evaluate chain‑of‑thought quality?

Evaluate both the final answer accuracy and the coherence of the reasoning steps. Look for logical errors, hallucinations, or unnecessary steps. Tools like Clarifai’s evaluation toolkit can help.

Can I run reasoning models on my own hardware?

Yes. Open‑source models like Llama 4 Scout, Mistral Medium 3, DeepSeek R1, and Qwen2.5‑1M can be self‑hosted. Clarifai provides local runners for deploying and managing these models on‑premise.

Are multimodal reasoning models available?

Yes. Gemini 2.5 Pro, Qwen‑VL, and Llama 4 support reasoning over text and images (and sometimes audio). Multimodal models are essential for tasks like document comprehension with embedded charts or diagrams.

What are the risks of chain‑of‑thought?

Chain‑of‑thought traces may expose sensitive reasoning or hallucinate incorrect steps. Some providers compress or obfuscate the chain to improve privacy. Always review outputs and implement safety filters.

How can Clarifai help me with reasoning models?

Clarifai offers compute orchestration, model registry, local runners, cost analytics, and evaluation tools. We support multiple reasoning models and help you integrate them into your workflows with minimal friction.