What Are the 3 Types of AI? Narrow, General & Super AI Explained


Quick Summary: What are the three types of artificial intelligence?

  • Answer: There are three capability‑based categories of artificial intelligence: Artificial Narrow Intelligence (ANI) designed for specialised tasks; Artificial General Intelligence (AGI), an aspirational form matching human cognitive abilities across domains; and Artificial Super Intelligence (ASI), a hypothetical level where machines surpass human intelligence. These types coexist with a functional classification that describes how AI systems operate—reactive machines, limited‑memory, theory‑of‑mind and self‑aware AI.

Introduction: Why AI Classification Matters in 2025

Artificial intelligence is no longer just a buzzword; it is a central force reshaping industries, economies and everyday life. Yet with so much hype and jargon, it is easy to lose sight of what AI can really do today versus what might come tomorrow. That is why understanding the three types of AI—narrow, general and super—alongside functional categories like reactive machines and limited‑memory systems is important. These classifications help clarify capabilities, manage expectations and highlight the ethical implications of AI’s rapid progress. They also underpin regulatory debates and investment decisions, with AI attracting $33.9 billion in private investment in 2024 and more than 78 % of organisations using AI.

In this article you will find a deep dive into each AI type, real‑world examples, expert opinions, emerging trends and practical comparisons. We will also explore subtle differences between capability‑based and functional classifications, highlight the latest industry insights and show how Clarifai’s platform empowers organisations to build and deploy AI responsibly.

Quick Digest: What You’ll Learn

  • ANI (Artificial Narrow Intelligence) – what it is, how it powers everyday tools like recommendation engines and self‑driving cars, and where its limitations lie.
  • AGI (Artificial General Intelligence) – why it is a long‑sought goal, what current research milestones look like, and the major hurdles to building truly human‑level AI.
  • ASI (Artificial Super Intelligence) – a speculative realm where machines out‑think humans, sparking debates about ethics, safety and control.
  • Functional Types of AI – how reactive machines, limited‑memory systems, theory‑of‑mind and self‑aware AI relate to the three capability types.
  • Emerging Trends – agentic AI, multimodal models, reasoning‑centric models, Model Context Protocol, retrieval‑augmented generation, on‑device AI and compact models, plus regulatory momentum and ethical considerations.
  • Real‑World Case Studies – from medical diagnostics to autonomous vehicles and agentic assistants.
  • FAQs – common questions about AI types, answered concisely.

Let’s unpack each topic in detail.
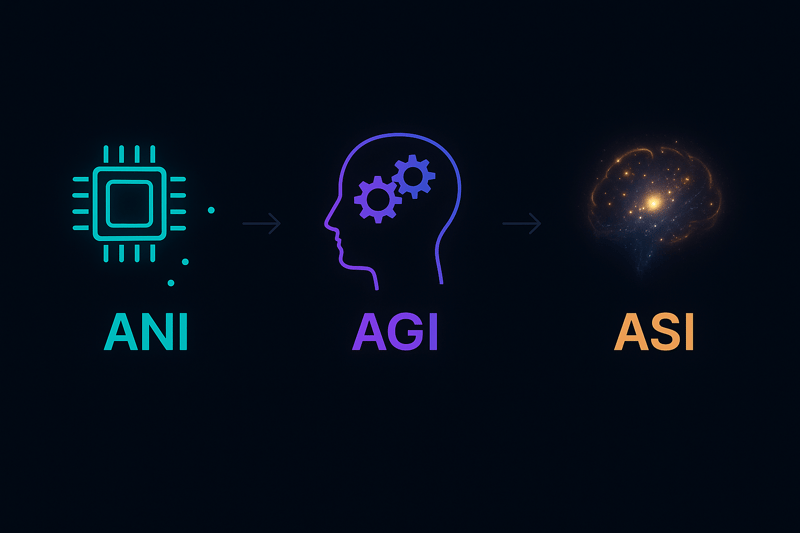
Types of AI

ANI: Artificial Narrow Intelligence — The AI You Use Every Day

What is ANI and Why It Matters

Artificial Narrow Intelligence refers to AI systems designed to perform a specific task or a narrow range of tasks. These systems excel within their domain but cannot generalise beyond it. A recommendation engine that suggests movies on your favourite streaming service, a chatbot that answers banking queries or a self‑driving car’s lane‑keeping module are all examples of ANI. Because ANI focuses on specialised tasks, it accounts for nearly all AI deployed today, from smartphone assistants to industrial automation.

Researchers note that most current AI falls into the reactive or limited‑memory categories—two functional subtypes where systems respond to inputs with pre‑programmed rules or rely on short‑term memory. These align closely with ANI and emphasise that our everyday AI is still far from human‑like cognition.

How ANI Works: Reactive Machines and Limited‑Memory Systems

Reactive machines are the simplest form of AI; they have no memory and respond directly to current inputs. IBM’s Deep Blue chess computer is a classic example: it evaluates the board’s current state and selects the best move based solely on rules and heuristics. Limited‑memory systems extend this by learning from past data to improve performance—a feature used in self‑driving cars that collect sensor data to make lane‑keeping or braking decisions.

In medical diagnostics, limited‑memory AI analyses large datasets of images and patient records to detect tumours or predict disease progression. These models do not understand the concept of “health” but excel at pattern recognition within a specific task.

Strengths and Limitations

ANI’s strength lies in precision and efficiency—machines can outperform humans at repetitive, data‑driven tasks such as parsing radiology images or identifying fraudulent transactions. However, ANI lacks general reasoning and cannot adapt to tasks outside its domain. This narrow focus also makes ANI vulnerable to bias and hallucination, as models sometimes generate plausible but inaccurate responses when asked about unfamiliar topics. Retrieval‑augmented generation (RAG) mitigates these issues by grounding models in verified knowledge bases.

Practical Impact and Clarifai Integration

ANI powers much of our digital world, from voice assistants to customer‑service bots. Clarifai’s platform makes it easier to build and deploy ANI applications at scale, offering compute orchestration and model inference capabilities that accelerate development cycles. For instance, developers can train custom image‑recognition models on Clarifai using local runners, then orchestrate them across cloud or on‑device environments for real‑time inference. This flexibility helps organisations integrate AI without massive infrastructure investments.

Expert Insights

  • Specialised Task Excellence – ANI excels at specific tasks such as image classification, language translation and recommendation systems.
  • Reliance on Data Quality – high‑quality, domain‑relevant data is critical; poor data leads to biased or inaccurate outputs.
  • Integration with RAG – combining ANI with RAG frameworks improves accuracy and reduces hallucinations by grounding responses in trusted documents.

AGI: Artificial General Intelligence — The Aspirational Goal

What Defines AGI?

Artificial General Intelligence describes an AI system capable of understanding, learning and applying knowledge across multiple domains at a level comparable to a human being. Unlike ANI, AGI would exhibit flexibility and adaptability to perform any intellectual task, from solving math problems to composing music, without being explicitly programmed for each task. No AGI exists today; it remains a research milestone that inspires both excitement and skepticism.

Current Research and Milestones

Recent advances hint at AGI’s building blocks. Large language models (LLMs) like GPT‑4 and Gemini demonstrate emergent reasoning capabilities, while reasoning‑centric models such as o3 and Opus 4 can follow logical chains to solve multi‑step problems. These models operate on curated or synthetic datasets that emphasise reasoning, highlighting that training quality—not just scale—matters. Another promising avenue is multimodal AI, where models process text, images, audio and video together. Such integration brings machines closer to human‑like perception and may be essential for AGI.

Challenges and Ethical Considerations

Creating AGI isn’t just an engineering problem; it is also an ethical and philosophical challenge. Researchers must overcome obstacles like common‑sense reasoning, long‑term memory and energy efficiency. Equally important are alignment and safety: how do we ensure AGI respects human values and doesn’t act against our interests? Regulatory bodies worldwide have begun to address these questions, with legislative mentions of AI rising more than 21 % across 75 countries.

Functional Overlap: Theory of Mind and Self‑Aware AI

AGI would likely incorporate theory‑of‑mind capabilities—recognising emotions, intentions and social cues. Current research explores multimodal data to model human behaviours in healthcare and education. True self‑awareness, however, remains speculative. If achieved, AGI could not only understand others but also possess a sense of “self,” opening a new realm of ethical and philosophical questions.

Clarifai’s Role in AGI Research

While AGI is a distant goal, Clarifai supports researchers by providing a versatile platform for experimentation. With compute orchestration, scientists can test different neural architectures and training regimens across cloud and edge environments. Clarifai’s model hub allows easy access to state‑of‑the‑art LLMs and vision models, enabling experiments with multimodal data and reasoning‑centric algorithms. Local runners ensure data privacy and reduce latency, essential for projects exploring long‑term memory and contextual reasoning.

Expert Insights

  • No Existing AGI – AGI remains hypothetical and is not yet realised.
  • Reasoning‑Focused Training – curated datasets and synthetic data that emphasise logical reasoning are critical to progress.
  • Ethics and Alignment – safety, transparency and alignment with human values are as important as technical breakthroughs.

ASI: Artificial Super Intelligence — Beyond Human Intelligence

What Is ASI?

Artificial Super Intelligence refers to a theoretical AI that surpasses human intelligence in every domain—creativity, reasoning, emotional intelligence and social skills. ASI is common in science fiction, where machines gain self‑awareness and outsmart their creators. In reality, ASI remains purely speculative; its existence depends on overcoming the monumental challenge of AGI and then further self‑improving beyond human capabilities.

Potential Capabilities and Risks

ASI could solve complex global problems, optimise resources and innovate at an unprecedented pace. However, the very qualities that make ASI powerful also pose existential risks: misaligned objectives, loss of control and unforeseen consequences. Ethicists and futurists urge proactive governance and research into AI alignment to ensure any future superintelligence acts in humanity’s best interests.

Balanced Perspectives and Ethical Debate

Some experts argue that ASI may never exist due to physical, computational or ethical constraints. Others believe that if AGI is achieved, runaway intelligence could lead to ASI. Regardless of stance, most agree that discussing ASI’s potential today helps shape responsible AI policies and fosters public awareness.

Clarifai’s Commitment to Responsible AI

Clarifai promotes responsible AI practices by offering tools that support transparency, auditability and bias mitigation. Their model inference platform includes explainability features that help developers understand model decisions—an essential component for preventing misuse as AI systems become more sophisticated. Clarifai also partners with academic and policy institutions to foster ethical guidelines and support research on AI safety.

Expert Insights

  • Theoretical Stage – ASI is an academic and philosophical concept; there are no real implementations yet.
  • Ethical Imperatives – discussions about ASI inspire present‑day safety research and policy making.
  • Importance of Alignment – ensuring machines align with human values becomes increasingly critical as AI capabilities grow.

Functional Types of AI: Reactive, Limited‑Memory, Theory‑of‑Mind and Self‑Aware Systems

Why Functional Classification Matters

While capability‑based categories (ANI, AGI, ASI) describe what AI can do, functional classification explains how AI works. The four levels—reactive machines, limited‑memory systems, theory‑of‑mind AI and self‑aware AI—map a cognitive evolution path. Understanding these stages clarifies why most existing AI is still narrow and highlights milestones required for AGI.

Reactive Machines: Rule‑Based Specialists

Reactive machines respond to current inputs without memory. Examples include IBM’s Deep Blue, which calculated chess moves based on the board’s current state. These systems excel at fast, predictable tasks but cannot learn from experience.

Limited‑Memory AI: Learning from the Past

Most modern AI falls into the limited‑memory category, where models leverage past data to improve decisions. Self‑driving cars use sensor data and historical information to navigate; voice assistants like Siri and Alexa adapt to user preferences over time. In healthcare, limited‑memory AI analyses patient histories and imaging to assist with diagnostics.

Theory of Mind: Understanding Others

Theory‑of‑mind AI aims to recognise human emotions, intentions and social cues. Research in this area explores multimodal data—combining facial expressions, voice tone and body language—to enable machines to respond empathetically. While prototypes exist in labs, there are no commercially deployed theory‑of‑mind systems yet.

Self‑Aware AI: Conscious Machines?

Self‑aware AI would possess consciousness and a sense of self. Although some humanoid robots, like “Sophia,” mimic self‑awareness through scripted responses, true self‑aware AI is purely speculative. Achieving this stage would require breakthroughs in neuroscience, philosophy and AI safety.

Clarifai’s Contribution

Clarifai supports functional AI development at all levels. For reactive machines and limited‑memory systems, Clarifai offers out‑of‑the‑box models for vision, language and audio that can be fine‑tuned using local runners and deployed across cloud or on‑device environments. Researchers exploring theory‑of‑mind can leverage Clarifai’s multimodal training tools, combining data from images, audio and text. While self‑aware AI remains theoretical, Clarifai’s ethics initiatives encourage dialogue on responsible innovation.
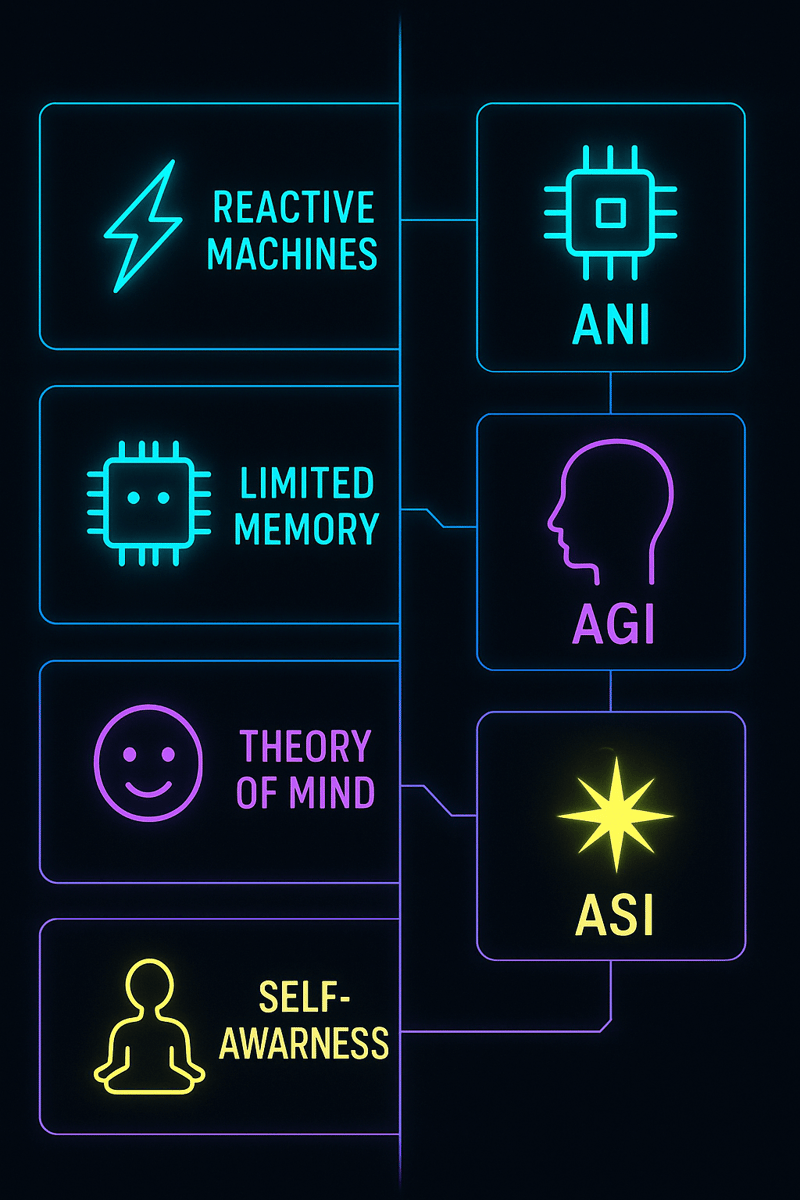
Functional AI Types

Expert Insights

  • Dominance of Limited‑Memory AI – most AI applications today are limited‑memory systems.
  • No Commercial Theory‑of‑Mind AI Yet – research prototypes exist, but consumer products are not available.
  • Self‑Awareness Remains Hypothetical – true machine consciousness is far from reality.

Emerging Trends Shaping AI in 2025 and Beyond

Agentic AI and Autonomous Workflows

Agentic AI refers to systems that act autonomously toward a goal, breaking tasks into sub‑tasks and adapting as conditions change. Unlike chatbots that wait for the next prompt, agentic AI operates like a junior employee—executing multi‑step workflows, accessing tools and making decisions. Current industry reports describe how agents perform HR onboarding, password resets, meeting scheduling and internal analytics. In the near future, agents could monitor finances, generate marketing content or manage e‑commerce recovery tasks.

Clarifai’s platform enables agentic AI by orchestrating multiple models and tools. Developers can use Clarifai’s workflow builder to chain models (e.g., summarisation, classification, sentiment analysis) and integrate external APIs for data retrieval or action execution. This modular approach supports rapid prototyping and deployment of AI agents that can operate autonomously yet remain under human control.

Multimodal AI

Multimodal AI processes multiple data types—text, images, audio and video—within a single model, bringing machines closer to human‑like understanding. Recent models such as GPT‑4.1 and Gemini 2.0 can interpret images, listen to voice notes and analyse text simultaneously. This capability has transformative potential in healthcare—combining radiology images with patient records for comprehensive diagnostics—and in sectors like e‑commerce and customer support.

Clarifai offers multimodal pipelines that allow developers to build applications combining visual, audio and text data. For instance, an insurance claims app could use Clarifai’s computer vision model to assess damage from photos and a language model to process claim narratives.

Reasoning‑Centric Models

Reasoning‑centric models emphasise logic and step‑by‑step reasoning rather than mere pattern recognition. Advancements in models like o3 and Opus 4 allow AI to solve complex tasks, such as financial analysis or logistics optimisation, by breaking down problems into logical steps. Smaller models like Microsoft’s Phi‑2 achieve strong reasoning using curated datasets focused on quality rather than quantity.

Clarifai’s experimentation environment supports training and evaluating reasoning‑centric models. Developers can plug in curated datasets, fine‑tune models and benchmark them against tasks requiring logical inference. Clarifai’s explainability tools aid debugging by revealing the reasoning steps behind model outputs.

Model Context Protocol (MCP) and Modular Agents

Model Context Protocol (MCP) is an open standard that allows AI agents to connect to external systems (files, tools, APIs) in a consistent, secure way. It acts like a universal port for AI, facilitating plug‑and‑play architecture. Instead of writing bespoke integrations, developers use MCP to give agents access to file systems, terminals or databases, enabling multi‑step workflows.

Clarifai’s workflow builder is compatible with MCP principles. Users can design modular pipelines where an AI model reads data from a database, processes it and writes results back, all within a consistent interface. This modularity makes scaling and maintenance easier.

Retrieval‑Augmented Generation (RAG)

Retrieval‑Augmented Generation (RAG) combines language models with external knowledge bases to deliver grounded, accurate responses. Instead of relying solely on pre‑training, RAG systems index documents (policies, manuals, datasets) and retrieve relevant snippets to feed into the model during inference. This reduces hallucinations and ensures answers are up‑to‑date.

Clarifai offers RAG‑enabled workflows that connect language models to company knowledge bases. Developers can build custom retrieval engines, index internal documents and integrate them with generative models, all managed through Clarifai’s platform.

On‑Device AI and Hybrid Inference

On‑device AI shifts inference from the cloud to local devices equipped with neural processing units (NPUs), enhancing privacy, reducing latency and lowering costs. Recent hardware like Qualcomm’s Snapdragon X Elite and Apple’s M‑series chips enable models with over 13 billion parameters to run on laptops or mobile devices. This trend enables offline functionality and real‑time responsiveness.

Clarifai’s local runners support on‑device deployment, allowing developers to run vision and language models directly on edge devices. A hybrid option lets simple tasks execute locally while more complex reasoning is offloaded to the cloud.

Compact Models and Small Language Models

Compact models offer a practical alternative to giant LLMs by focusing on specific tasks with fewer parameters. Examples include Phi‑3.5‑mini, Mixtral 8×7B and TinyLlama. These models perform well when fine‑tuned for narrow domains, require less computation and can be deployed on edge devices or embedded systems.

Clarifai supports training, fine‑tuning and deployment of compact models. This makes AI accessible to organisations without massive compute resources and allows quick prototyping for domain‑specific tasks.

Global Momentum and Regulation

Public and governmental engagement with AI is growing rapidly. Legislative mentions of AI doubled in 2024 and investments surged, with countries like Canada committing $2.4 billion and Saudi Arabia pledging $100 billion. Public sentiment varies: a majority in China and Indonesia view AI as beneficial, while skepticism remains higher in the US and Canada. Regulations aim to ensure responsible deployment, address privacy concerns and mitigate harms like deepfakes.

Clarifai engages with regulators and industry groups to shape ethical guidelines. The platform includes tools for bias detection and compliance documentation, helping organisations meet emerging regulatory requirements.
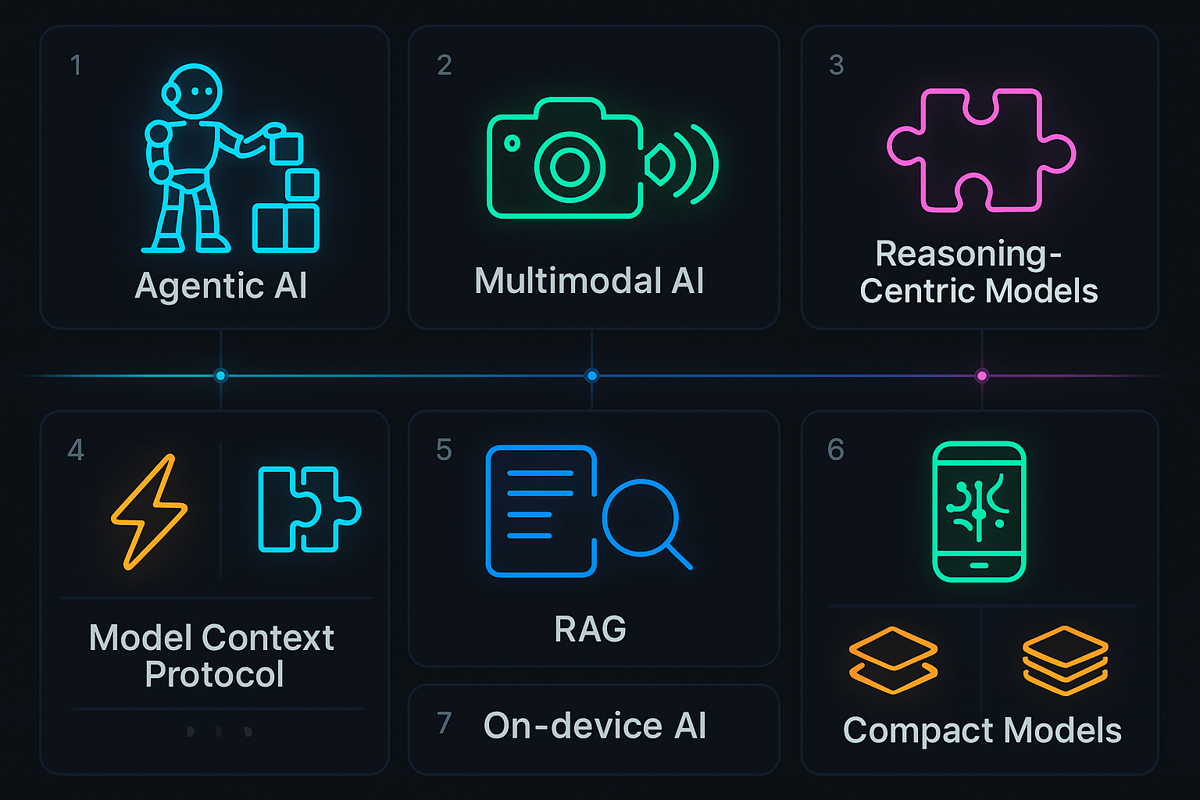
Emerging AI Trends

Comparisons and Step‑by‑Step Guides

Comparison: ANI vs AGI vs ASI

AI Type

Scope

Current Status

Examples

Key Considerations

ANI (Narrow AI)

Performs specific tasks; cannot generalise

Ubiquitous; powers most current AI systems

Recommendation engines, chatbots, self‑driving cars

High accuracy within narrow domains; limited creativity and reasoning

AGI (General AI)

Matches human cognitive abilities across domains

Not yet achieved; active research area

Hypothetical (future advanced multimodal models)

Requires reasoning, long‑term memory and alignment; ethical and technical challenges

ASI (Super AI)

Surpasses human intelligence in all domains

Purely speculative

Fictional AI characters (e.g., HAL 9000)

Raises existential risks and alignment concerns; spurs ethical debate

Comparison: Functional Types vs Capability Types

Functional Type

Corresponding Capability

Characteristics

Reactive Machines

ANI

Rule‑based, no memory; e.g., Deep Blue

Limited‑Memory Systems

ANI

Learn from past data; used in self‑driving cars and medical imaging

Theory‑of‑Mind AI

Towards AGI

Model human emotions and intentions; research stage

Self‑Aware AI

ASI

Possess consciousness; purely hypothetical

Step‑by‑Step: How AI Progresses from Narrow to AGI

  1. Reactive Systems – start with rule‑based programs that react to inputs.
  2. Limited‑Memory Models – introduce learning from past data for improved performance.
  3. Multimodal & Reasoning Models – combine multiple data types and add step‑by‑step reasoning.
  4. Theory‑of‑Mind Abilities – model emotions and social cues for empathetic responses.
  5. Self‑Awareness & Continuous Learning – develop a sense of self and autonomous learning—an area still speculative.

Checklist: Evaluating an AI System’s Type

  • Task Scope – does it perform one task (ANI) or many (AGI)?
  • Adaptability – can it generalise knowledge to new domains?
  • Memory – does it use only current input (reactive) or past data (limited memory)?
  • Reasoning – can it break down problems logically?
  • Human‑Like Understanding – does it interpret emotions and social cues (theory of mind)?
  • Self‑Awareness – does it exhibit consciousness (ASI)?
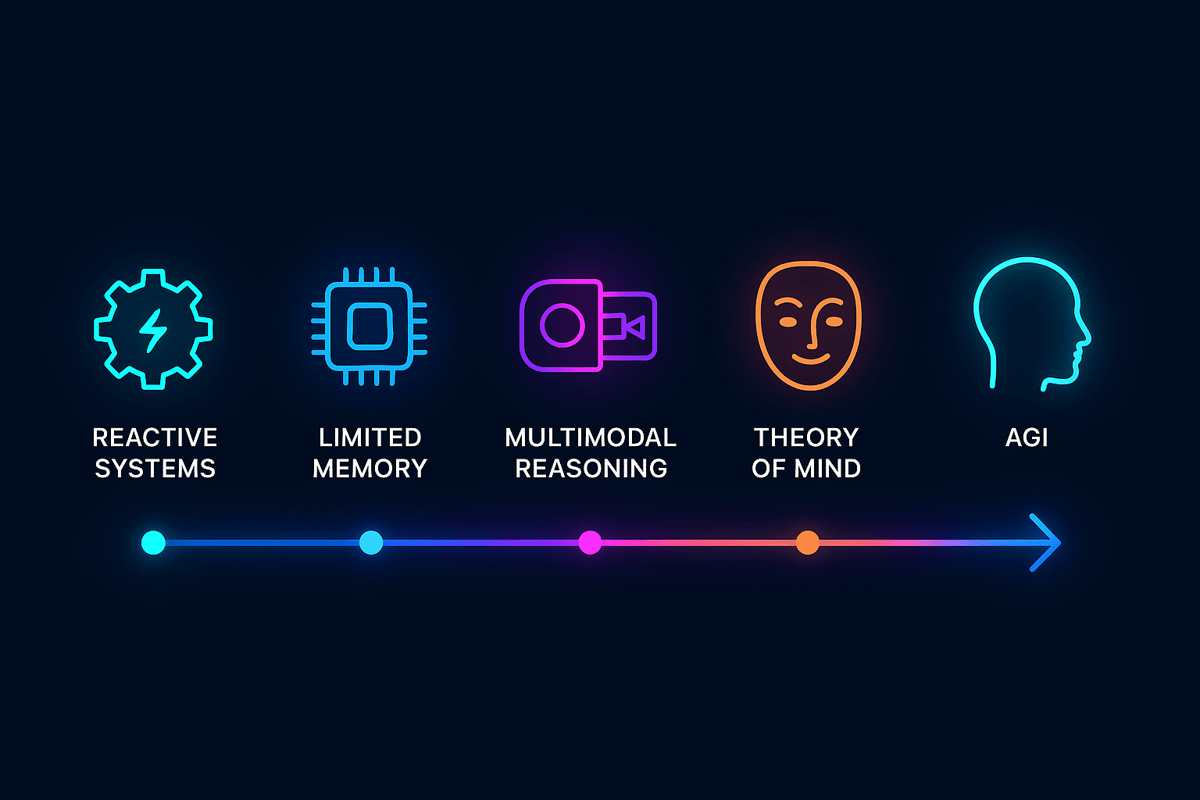
Narrow AI to AGIReal‑World Implications and Case Studies

Limited‑Memory AI in Autonomous Vehicles

Self‑driving cars exemplify limited‑memory AI. They collect data from sensors (cameras, lidar, radar) and historical drives to make decisions on steering, braking and lane changes. While they demonstrate impressive capabilities, accidents highlight the need for better edge‑case handling and ethical decision‑making. Integrating RAG with driving data could improve situational awareness by referencing additional sources, such as road‑work updates or dynamic traffic rules.

AI in Healthcare Diagnostics

AI models assist radiologists in detecting diseases such as cancer by analysing medical images and patient histories. These systems enhance accuracy and speed, but also require rigorous validation and bias monitoring. Clarifai’s compute orchestration enables hospitals to deploy such models locally, ensuring data privacy and reducing latency. For example, a rural clinic can run a model on a local device to analyse X‑rays, then send anonymised results for further consultation.

Agentic AI Pilot in HR & IT Support

Imagine an agentic AI deployed in a mid‑sized company’s HR department. The agent autonomously handles employee onboarding: creating accounts, scheduling training sessions and answering policy questions using a knowledge base. It also manages IT requests, resetting passwords and troubleshooting basic issues. Within months, the agent reduces onboarding time by 40 % and decreases ticket resolution time by 30 %. Using Clarifai’s workflow builder, the company chains multiple models (document classification, summarisation, scheduling) and integrates them with internal HR software through an MCP‑like protocol.

Ethical and Regulatory Cases

California’s AI regulations illustrate the evolving policy landscape. New laws introduced in January 2025 protect user privacy, healthcare data and victims of deepfakes. Globally, legislative mentions of AI increased by 21 %, and countries invested billions to foster responsible AI. Organisations using AI must adapt to these regulations by implementing bias detection, transparency and compliance features—capabilities that Clarifai’s platform provides.

Expert Insights

  • Productivity Effects – a 2023 study showed generative AI improved highly skilled worker performance by nearly 40 % but hindered performance when used outside its capabilities.
  • Healthcare Adoption – reactive and limited‑memory AI systems are prevalent in medical devices and diagnostics.
  • Regulatory Momentum – AI regulation more than doubled from 2023 to 2024, signalling heightened scrutiny.
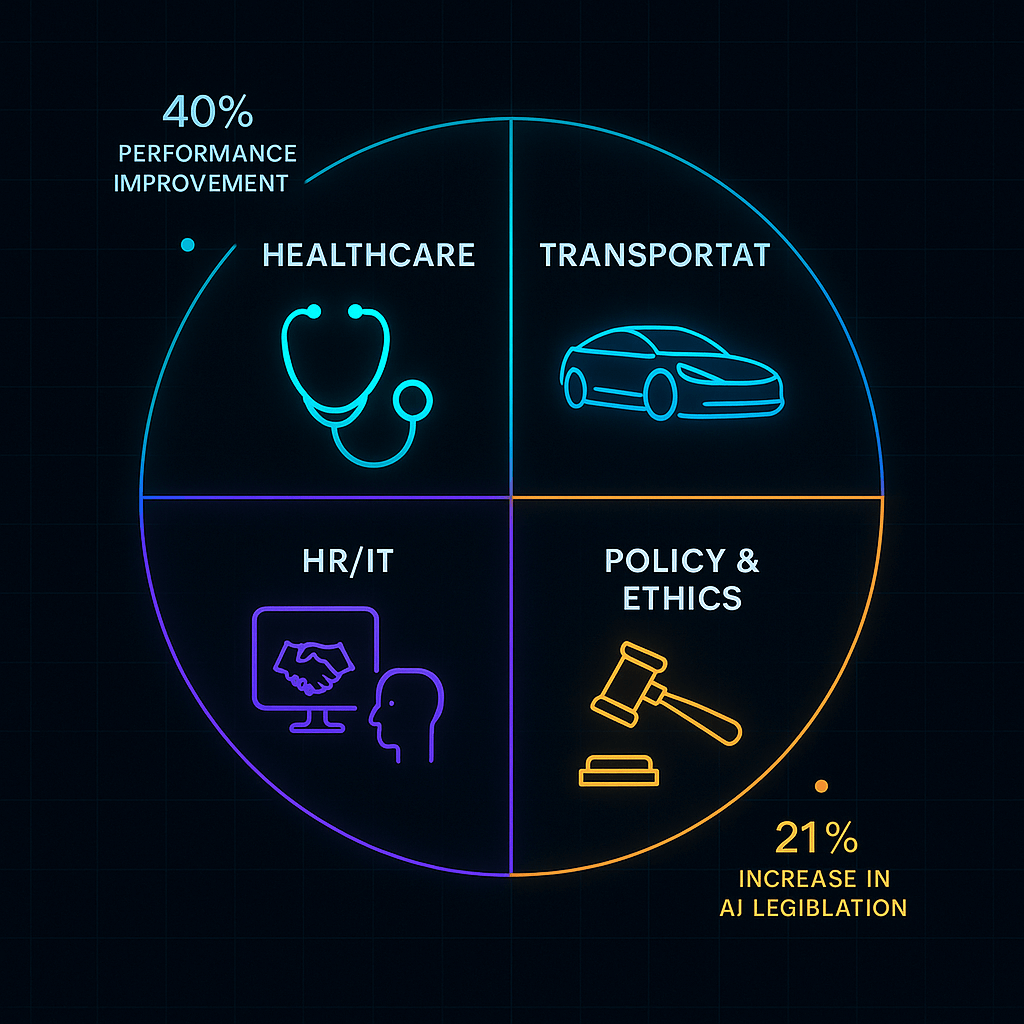
Real World Implications & Case StudiesFuture Outlook & Conclusion

As we progress into the second half of the decade, AI’s influence will only grow. Expect agentic AI to become mainstream, multimodal models to power more natural interactions and on‑device AI to bring intelligence closer to users. Reasoning‑centric models will continue to improve, narrowing the gap between narrow AI and the dream of AGI. Compact models will proliferate, making AI accessible in resource‑constrained environments. Meanwhile, public investments and regulations will shape AI’s trajectory, emphasising responsible innovation and ethical considerations. By understanding the three types of AI and the functional categories, individuals and organisations can navigate this evolving landscape more effectively. With platforms like Clarifai providing powerful tools, the journey from narrow to more general intelligence becomes more accessible—yet always demands vigilance to ensure AI benefits society.

FAQs

What are the 3 types of AI?

The three capability‑based categories are Artificial Narrow Intelligence (ANI), designed for specific tasks; Artificial General Intelligence (AGI), a research goal aiming to match human cognition; and Artificial Super Intelligence (ASI), a hypothetical level where machines surpass human intelligence.

How do the functional types of AI relate to ANI, AGI and ASI?

Reactive machines and limited‑memory systems correspond to ANI, handling specific tasks with or without short‑term memory. Theory‑of‑mind AI, which would understand emotions and social cues, points towards AGI. Self‑aware AI, currently hypothetical, would be necessary for ASI.

Is AGI close to becoming a reality?

Not yet. While large language models and reasoning‑centric approaches show progress, AGI remains hypothetical. Researchers still need breakthroughs in common‑sense reasoning, long‑term memory and alignment.

What is the significance of retrieval‑augmented generation (RAG)?

RAG improves AI accuracy by pulling relevant information from a knowledge base before generating responses. This reduces hallucinations and ensures answers are grounded in up‑to‑date data.

How does on‑device AI differ from cloud AI?

On‑device AI runs models locally on devices equipped with NPUs, enhancing privacy and reducing latency. Cloud AI relies on remote servers. Hybrid approaches combine both for optimal performance.

What role does Clarifai play in the AI ecosystem?

Clarifai provides a comprehensive platform for building, training and deploying AI models. It offers compute orchestration, model inference, multimodal pipelines, RAG workflows and ethics tools. Whether you’re developing narrow AI applications or experimenting with advanced reasoning, Clarifai’s platform supports your journey while emphasising responsible use.


How to Protect Your Brand in an AI-Powered World with Jen Leonard [MAICON 2025 Speaker Series]


MAICON brings together top visionaries and experts in the field of AI during a three-day conference packed with actionable sessions and networking events—all to position you as the change agent your organization (and career) needs. In this ongoing speaker series, we’re featuring these extraordinary leaders, with forward-looking predictions, actionable tips you can use today, and a preview of their MAICON 2025 sessions. Continue reading “How to Protect Your Brand in an AI-Powered World with Jen Leonard [MAICON 2025 Speaker Series]”

How to Make AI Your Smartest Business Strategist with Jen Taylor [MAICON 2025 Speaker Series]


MAICON brings together top visionaries and experts in the field of AI during a three-day conference packed with actionable sessions and networking events—all to position you as the change agent your organization (and career) needs. In this ongoing speaker series, we’re featuring these extraordinary leaders, with forward-looking predictions, actionable tips you can use today, and a preview of their MAICON 2025 sessions. Continue reading “How to Make AI Your Smartest Business Strategist with Jen Taylor [MAICON 2025 Speaker Series]”

LLM Inference Optimization Techniques | Clarifai Guide


Introduction: Why Optimizing Large Language Model Inference Matters

Large language models (LLMs) have revolutionized how machines understand and generate text, but their inference workloads come with substantial computational and memory costs. Whether you’re scaling chatbots, deploying summarization tools or integrating generative AI into enterprise workflows, optimizing inference is crucial for cost control and user experience. Due to the enormous parameter counts of state-of-the-art models and the mixed compute‑ and memory‑bound phases involved, naive deployment can lead to bottlenecks and unsustainable energy consumption. This article from Clarifai—a leader in AI platforms—offers a deep, original dive into techniques that minimize latency, reduce costs and ensure reliable performance across GPU, CPU and edge environments.

We’ll explore the architecture of LLM inference, core challenges like memory bandwidth limitations, batching strategies, multi‑GPU parallelization, attention and KV cache optimizations, model‑level compression, speculative and disaggregated inference, scheduling and routing, metrics, frameworks and emerging trends. Each section includes a Quick Summary, in‑depth explanations, expert insights and creative examples to make complex topics actionable and memorable. We’ll also highlight how Clarifai’s orchestrated inference pipelines, flexible model deployment and compute runners integrate seamlessly with these techniques. Let’s begin our journey toward building scalable, cost‑efficient LLM applications.


Quick Digest: What You’ll Learn About LLM Inference Optimization

Below is a snapshot of the key takeaways you’ll encounter in this guide. Use it as a cheat sheet to grasp the overall narrative before diving into each section.

  • Inference architecture: We unpack decoder‑only transformers, contrasting the parallel prefill phase with the sequential decode phase and explaining why decode is memory‑bound.
  • Core challenges: Discover why large context windows, KV caches and inefficient routing drive costs and latency.
  • Batching strategies: Static, dynamic and in‑flight batching can dramatically improve GPU utilization, with continuous batching allowing new requests to enter mid‑batch.
  • Model parallelization: Compare pipeline, tensor and sequence parallelism to distribute weights across multiple GPUs.
  • Attention optimizations: Explore multi‑query attention, grouped‑query attention, FlashAttention and the next‑gen FlashInfer kernel for block‑sparse formats.
  • Memory management: Learn about KV cache sizing, PagedAttention and streaming caches to minimize fragmentation.
  • Model‑level compression: Quantization, sparsity, distillation and mixture‑of‑experts drastically reduce compute without sacrificing accuracy.
  • Speculative & disaggregated inference: Future‑ready techniques combine draft models with verification or separate prefill and decode across hardware.
  • Scheduling & routing: Smart request routing, decode‑length prediction and caching improve throughput and cost efficiency.
  • Metrics & monitoring: We review TTFT, tokens per second, P95 latency and tools to benchmark performance.
  • Frameworks & case studies: Profiles of vLLM, FlashInfer, TensorRT‑LLM and LMDeploy illustrate real‑world improvements.
  • Emerging trends: Explore long‑context support, retrieval‑augmented generation (RAG), parameter‑efficient fine‑tuning and energy‑aware inference.

Ready to optimize your LLM inference? Let’s dive into each section.


How Does LLM Inference Work? Understanding Architecture & Phases

Quick Summary

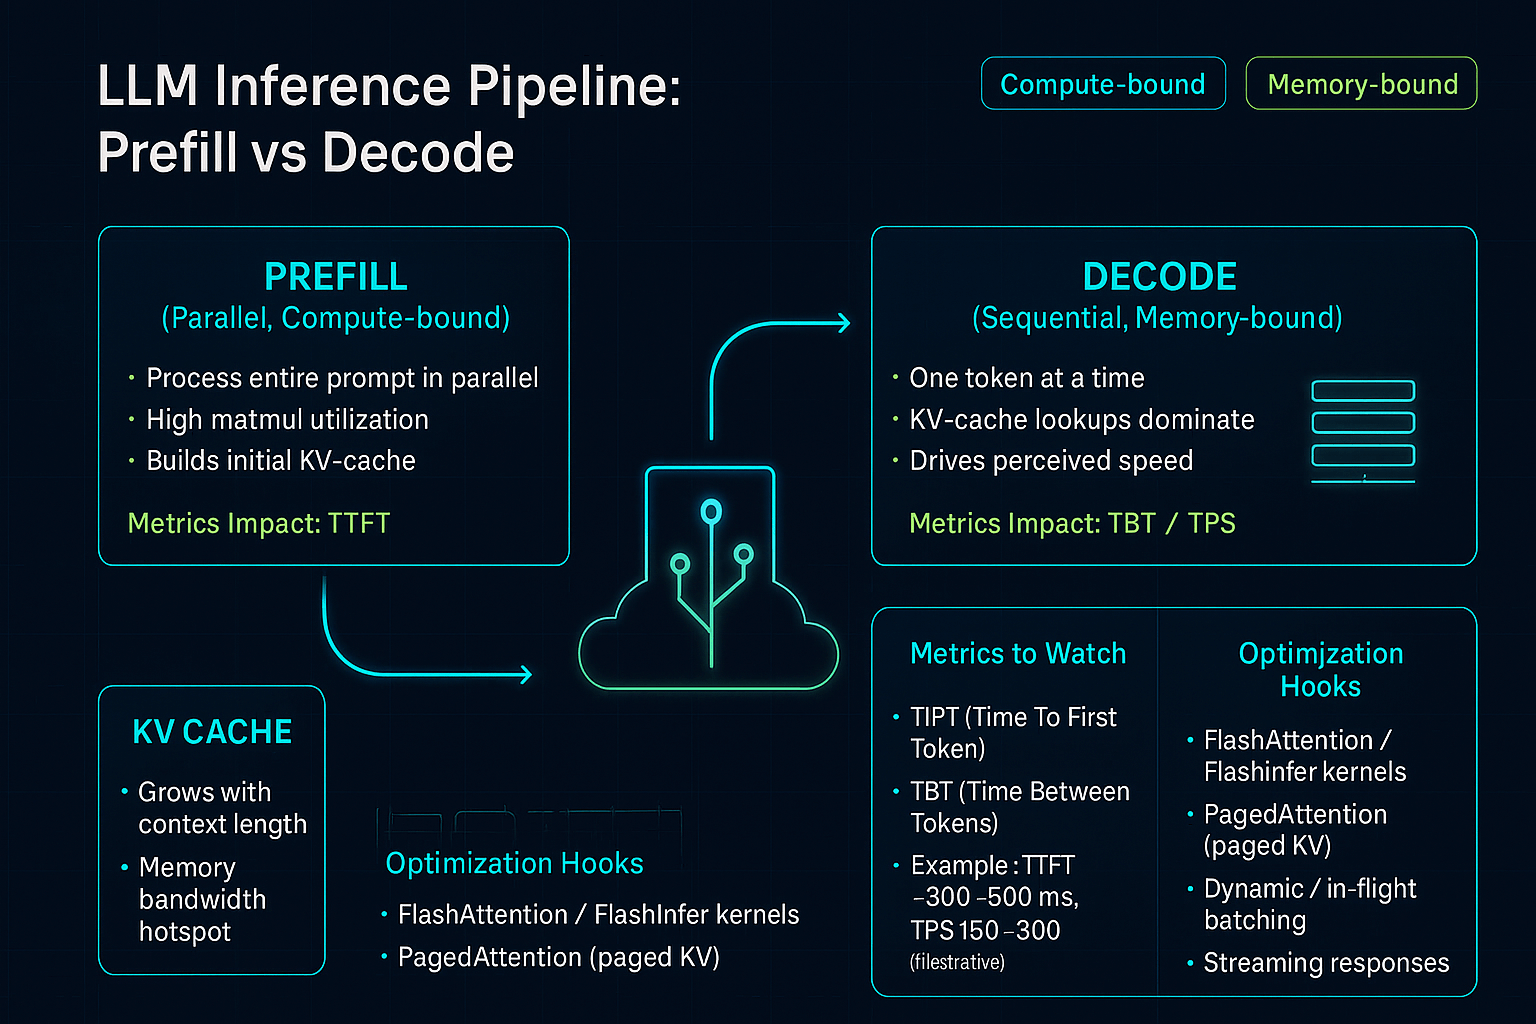
What happens under the hood of LLM inference? LLM inference comprises two distinct phases—prefill and decode—within a transformer architecture. Prefill processes the entire prompt in parallel and is compute‑bound, while decode generates one token at a time and is memory‑bound due to key‑value (KV) caching.

The Building Blocks: Decoder‑Only Transformers

Large language models like GPT‑3/4 and Llama are decoder‑only transformers, meaning they use only the decoder portion of the transformer architecture to generate text. Transformers rely on self‑attention to compute token relationships, but decoding in these models happens sequentially: each generated token becomes input for the next step. Two key phases define this process—prefill and decode.

Prefill Phase: Parallel Processing of the Prompt

In the prefill phase, the model encodes the entire input prompt in parallel; this is compute‑bound and benefits from GPU utilization because matrix multiplications are batched. The model loads the entire prompt into the transformer stack, calculating activations and initial key‑value pairs for attention. Hardware with high compute throughput—like NVIDIA H100 GPUs—excels in this stage. During prefill, memory usage is dominated by activations and weight storage, but it’s manageable compared to later stages.

Decode Phase: Sequential Token Generation and Memory Bottlenecks

Decode occurs after the prefill stage, producing one token at a time; each token’s computation depends on all previous tokens, making this phase sequential and memory‑bound. The model retrieves cached key‑value pairs from previous steps and appends new ones for each token, meaning memory bandwidth—not compute—limits throughput. Because the model cannot parallelize across tokens, GPU cores often idle while waiting for memory fetches, causing underutilization. As context windows grow to 8K, 16K or more, the KV cache becomes enormous, accentuating this bottleneck.

Memory Components: Weights, Activations and KV Cache

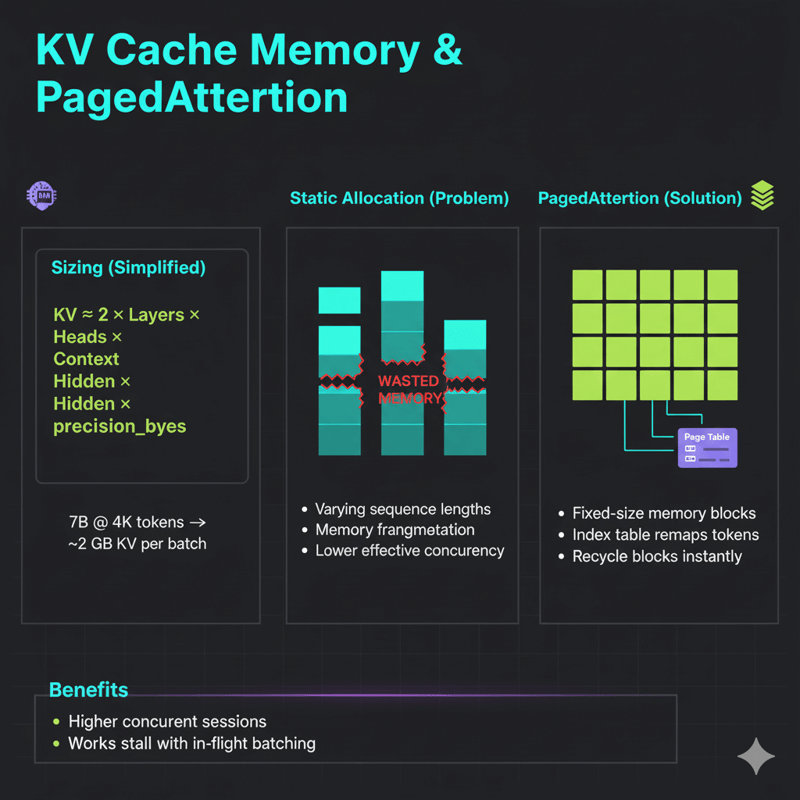
LLM inference uses three primary memory components: model weights (fixed parameters), activations (intermediate outputs) and the KV cache (past key‑value pairs stored for self‑attention). Activations are large during prefill but small in decode; the KV cache grows linearly with context length and layers, making it the main memory consumer. For example, a 7B model with 4,096 tokens and half‑precision weights may require around 2 GB of KV cache per batch.

Creative Example: The Assembly Line Analogy

Imagine an assembly line where the first stage stamps all parts at once (prefill) and the second stage assembles them sequentially (decode). If the assembly stage’s worker must fetch each part from a distant warehouse (KV cache), he will wait longer than the stamping stage, causing a bottleneck. This analogy highlights why decode is slower than prefill and underscores the importance of optimizing memory access.

Expert Insights

  • “Decode latency is fundamentally memory‑bound,” note researchers in a production latency analysis; compute units often idle due to KV cache fetches.
  • The Hathora team found that decode can be the slowest stage for small batch sizes, with latency dominated by memory bandwidth rather than compute.
  • To mitigate this, they recommend techniques like FlashAttention and PagedAttention to reduce memory reads and writes, which we’ll explore later.

Clarifai Integration

Clarifai’s inference engine automatically manages prefill and decode stages across GPUs and CPUs, abstracting away complexity. It supports streaming token outputs and memory‑efficient caching, ensuring that your models run at peak utilization while reducing infrastructure costs. By leveraging Clarifai’s compute orchestration, you can optimize the entire inference pipeline with minimal code changes.

LLM Inference Pipeline


What Are the Core Challenges in LLM Inference?

Quick Summary

Which bottlenecks make LLM inference expensive and slow? Major challenges include huge memory footprints, long context windows, inefficient routing, absent caching, and sequential tool execution; these issues inflate latency and cost.

Memory Consumption and Large Context Windows

The sheer size of modern LLMs—often tens of billions of parameters—means that storing and moving weights, activations and KV caches across memory channels becomes a central challenge. As context windows grow to 8K, 32K or even 128K tokens, the KV cache scales linearly, demanding more memory and bandwidth. If memory capacity is insufficient, the model may swap to slower memory tiers (e.g., CPU or disk), drastically increasing latency.

Latency Breakdown: Where Time Is Spent

Detailed latency analyses show that inference time includes model loading, tokenization, KV‑cache prefill, decode and output processing. Model loading is a one‑time cost when starting a container but becomes significant when frequently spinning up instances. Prefill latency includes running FlashAttention to compute attention across the entire prompt, while decode latency includes retrieving and storing KV cache entries. Output processing (detokenization and result streaming) adds overhead as well.

Inefficient Model Routing and Lack of Caching

A critical yet overlooked factor is model routing: sending every user query to a large model—like a 70B parameter LLM—when a smaller model would suffice wastes compute and increases cost. Routing strategies that select the right model for the task (e.g., summarization vs. math reasoning) can cut costs dramatically. Equally important is caching: not storing or deduplicating identical prompts leads to redundant computations. Semantic caching and prefix caching can reduce costs by up to 90%.

Sequential Tool Execution and API Calls

Another challenge arises when LLM outputs depend on external tools or APIs—retrieval, database queries or summarization pipelines. If these calls execute sequentially, they block the next steps and increase latency. Parallelizing independent API calls and orchestrating concurrency improves throughput. However, orchestrating concurrency manually across microservices is error‑prone.

Environmental and Cost Considerations

Inefficient inference not only slows responses but also consumes more energy and increases carbon emissions, raising sustainability concerns. As LLM adoption grows, optimizing inference becomes essential to maintain environmental stewardship. By minimizing wasted cycles and memory transfers, you reduce both operational expenses and the carbon footprint.

Expert Insights

  • Researchers emphasize that large context windows are among the biggest cost drivers, as each extra token increases KV cache size and memory access.
  • “Poor chunking in retrieval‑augmented generation (RAG) can cause huge context sizes and degrade retrieval quality,” warns an optimization guide.
  • Industry practitioners note that model routing and caching significantly reduce cost-per-query without compromising quality.

Clarifai Integration

Clarifai’s workflow automation enables dynamic model routing by analyzing the user’s query and selecting an appropriate model from your deployment library. With built‑in semantic caching, identical or similar requests are served from cache, reducing unnecessary compute. Clarifai’s orchestration layer also parallelizes external tool calls, ensuring your application remains responsive even when integrating multiple APIs.


How Do Batching Strategies Improve LLM Serving?

Quick Summary

How can batching reduce latency and cost? Batching combines multiple inference requests into a single GPU pass, amortizing computation and memory overhead; static, dynamic and in‑flight batching approaches balance throughput and fairness.

Static Batching: The Baseline

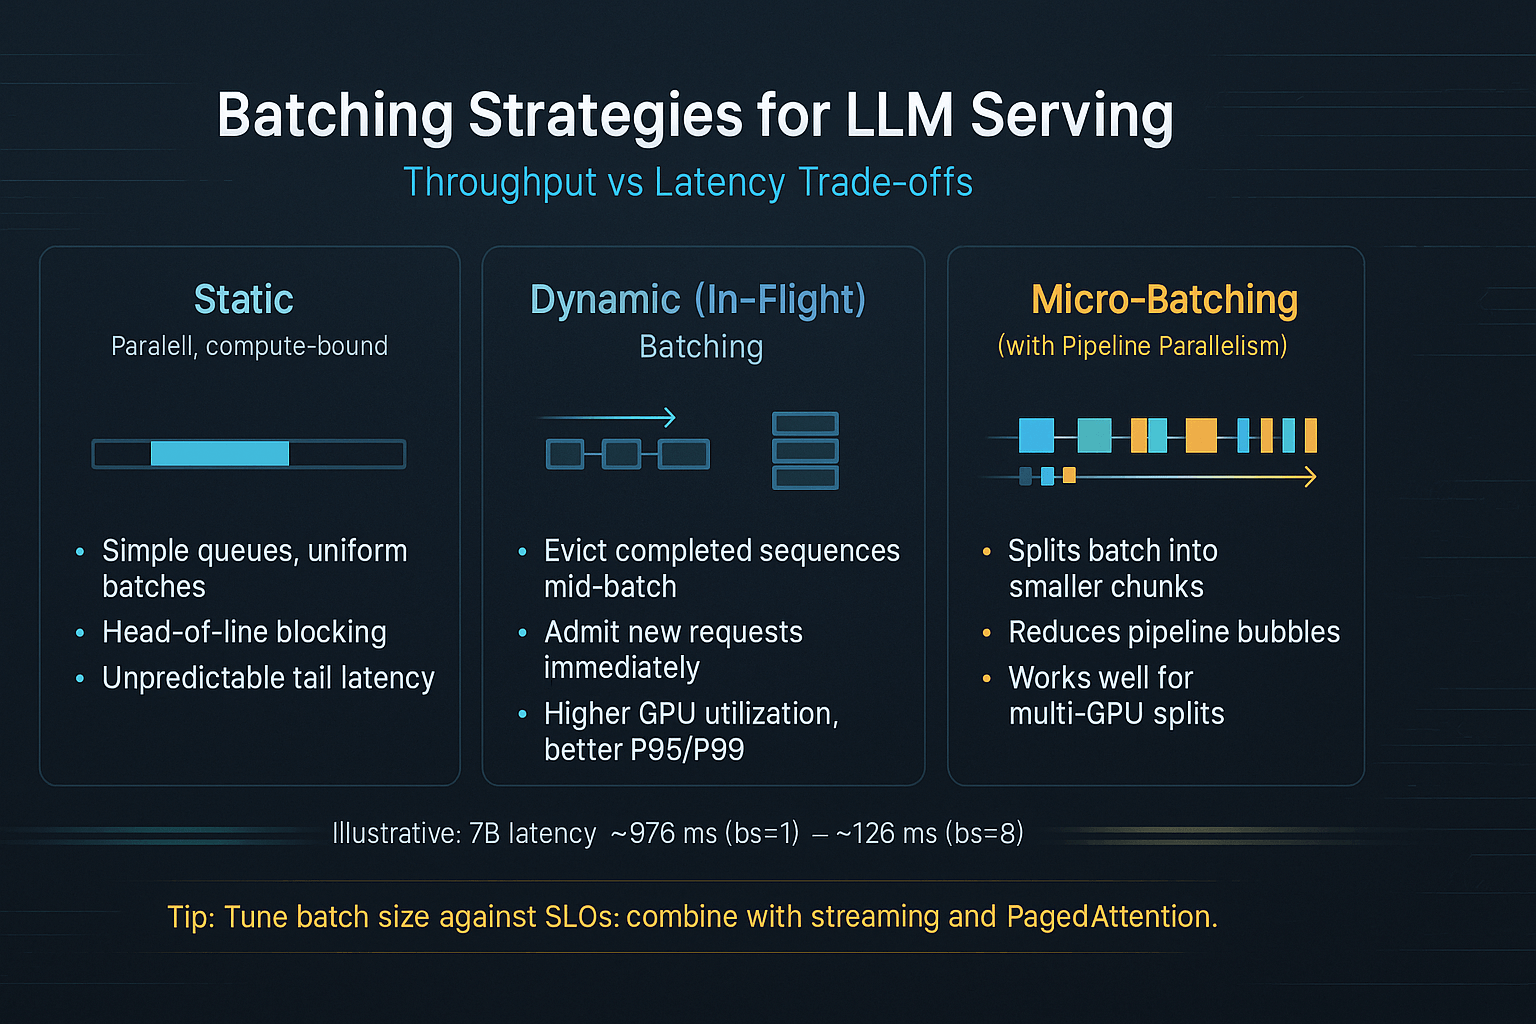
Static batching groups requests of similar length into a single batch and processes them together; this improves throughput because matrix multiplications operate on larger matrices with better GPU utilization. However, static batches suffer from head‑of‑line blocking: the longest request delays all others because the batch cannot finish until all sequences complete. This is particularly problematic for interactive applications where some users wait longer due to other users’ long inputs.

Dynamic or In‑Flight Batching: Continuous Service

To address static batching limitations, dynamic or in‑flight batching allows new requests to enter a batch as soon as space becomes available; completed sequences are evicted, and tokens are generated for new sequences in the same batch. This continuous batching maximizes GPU utilization by keeping pipelines full while reducing tail latency. Frameworks like vLLM implement this strategy by managing the GPU state and KV cache for each sequence, ensuring that memory is reused efficiently.

Micro‑Batching and Pipeline Parallelism

When a model is split across multiple GPUs using pipeline parallelism, micro‑batching further improves utilization by dividing a batch into smaller micro‑batches that traverse pipeline stages simultaneously. Although micro‑batching introduces some overhead, it reduces pipeline bubbles—periods where some GPUs are idle because other stages are processing. This strategy is important for large models that require pipeline parallelism for memory reasons.

Latency vs. Throughput Trade‑Off

Batch size has a direct impact on latency and throughput: larger batches achieve higher throughput but increase per‑request latency. Benchmark studies reveal that a 7B model’s latency can drop from 976 ms at batch size 1 to 126 ms at batch size 8, demonstrating the benefit of batching. However, excessively large batches lead to diminishing returns and potential timeouts. Dynamic scheduling algorithms can determine optimal batch sizes based on queue length, model load and user‑defined latency targets.

Creative Example: The Airport Shuttle Analogy

Imagine an airport shuttle bus waiting for passengers: a static shuttle leaves only when full, causing passengers to wait; dynamic shuttles continuously pick up passengers as seats free up, reducing overall waiting time. Similarly, in‑flight batching ensures that short requests aren’t held hostage by long ones, improving fairness and resource usage.

Expert Insights

  • Researchers observe that continuous batching can reduce P99 latency significantly while maintaining high throughput.
  • A latency study notes that micro‑batching reduces pipeline bubbles when combining pipeline and tensor parallelism.
  • Analysts warn that over‑aggressive batching can harm user experience; therefore, dynamic scheduling must consider latency budgets.

Clarifai Integration

Clarifai’s inference management automatically implements dynamic batching; it groups multiple user queries and adjusts batch sizes based on real‑time queue statistics. This ensures high throughput without sacrificing responsiveness. Furthermore, Clarifai allows you to configure micro‑batch sizes and scheduling policies, giving you fine‑grained control over latency‑throughput trade‑offs.

Batching Strategies for LLM Serving


How to Use Model Parallelization and Multi‑GPU Deployment?

Quick Summary

How can multiple GPUs accelerate large LLMs? Model parallelization distributes a model’s weights and computation across GPUs to overcome memory limits; techniques include pipeline parallelism, tensor parallelism and sequence parallelism.

Why Model Parallelization Matters

Single GPUs may not have enough memory to host a large model; splitting the model across multiple GPUs allows you to scale beyond a single device’s memory footprint. Parallelism also helps reduce inference latency by distributing computations across multiple GPUs; however, the choice of parallelism technique determines the efficiency.

Pipeline Parallelism

Pipeline parallelism divides the model into stages—layers or groups of layers—and assigns each stage to a different GPU. Each micro‑batch sequentially moves through these stages; while one GPU processes micro‑batch i, another can start processing micro‑batch i+1, reducing idle time. However, there are ‘pipeline bubbles’ when early GPUs finish processing and wait for later stages; micro‑batching helps mitigate this. Pipeline parallelism suits deep models with many layers.

Tensor Parallelism

Tensor parallelism shards the computations within a layer across multiple GPUs: for example, matrix multiplications are split horizontally (column) or vertically (row) across GPUs. This approach requires synchronization for operations like softmax, layer normalization and dropout, so communication overhead can become significant. Tensor parallelism works best for extremely large layers or for implementing multi‑GPU matrix multiply operations.

Sequence Parallelism

Sequence parallelism divides work along the sequence dimension; tokens are partitioned among GPUs, which compute attention independently on different segments. This reduces memory pressure on any single GPU because each handles only a portion of the KV cache. Sequence parallelism is less common but useful for long sequences and models optimized for memory efficiency.

Hybrid Parallelism

In practice, large LLMs often use hybrid strategies combining pipeline and tensor parallelism—e.g., using pipeline parallelism for high‑level model partitioning and tensor parallelism within layers. Choosing the right combination depends on model architecture, hardware topology and batch size. Frameworks like DeepSpeed and Megatron handle these complexities and automate partitioning.

Expert Insights

  • Researchers emphasize that micro‑batching is critical when using pipeline parallelism to keep all GPUs busy.
  • Tensor parallelism yields good speedups for large layers but requires careful communication planning to avoid saturating interconnects.
  • Sequence parallelism offers additional savings when sequences are long and memory fragmentation is a concern.

Clarifai Integration

Clarifai’s infrastructure supports multi‑GPU deployment using both pipeline and tensor parallelism; its orchestrator automatically partitions models based on GPU memory and interconnect bandwidth. By using Clarifai’s multi‑GPU runner, you can serve 70B or larger models on commodity clusters without manual tuning.


Which Attention Mechanism Optimizations Speed Up Inference?

Quick Summary

How can we reduce the overhead of self‑attention? Optimizations include multi‑query and grouped‑query attention, FlashAttention for improved memory locality and FlashInfer for block‑sparse operations and JIT‑compiled kernels.

The Cost of Scaled Dot‑Product Attention

Transformers compute attention by comparing each token with every other token in the sequence (scaled dot‑product attention). This requires computing queries (Q), keys (K) and values (V) and then performing a softmax over the dot products. Attention is expensive because the operation scales quadratically with sequence length and involves frequent memory reads/writes, causing high latency during inference.

Multi‑Query Attention (MQA) and Grouped‑Query Attention (GQA)

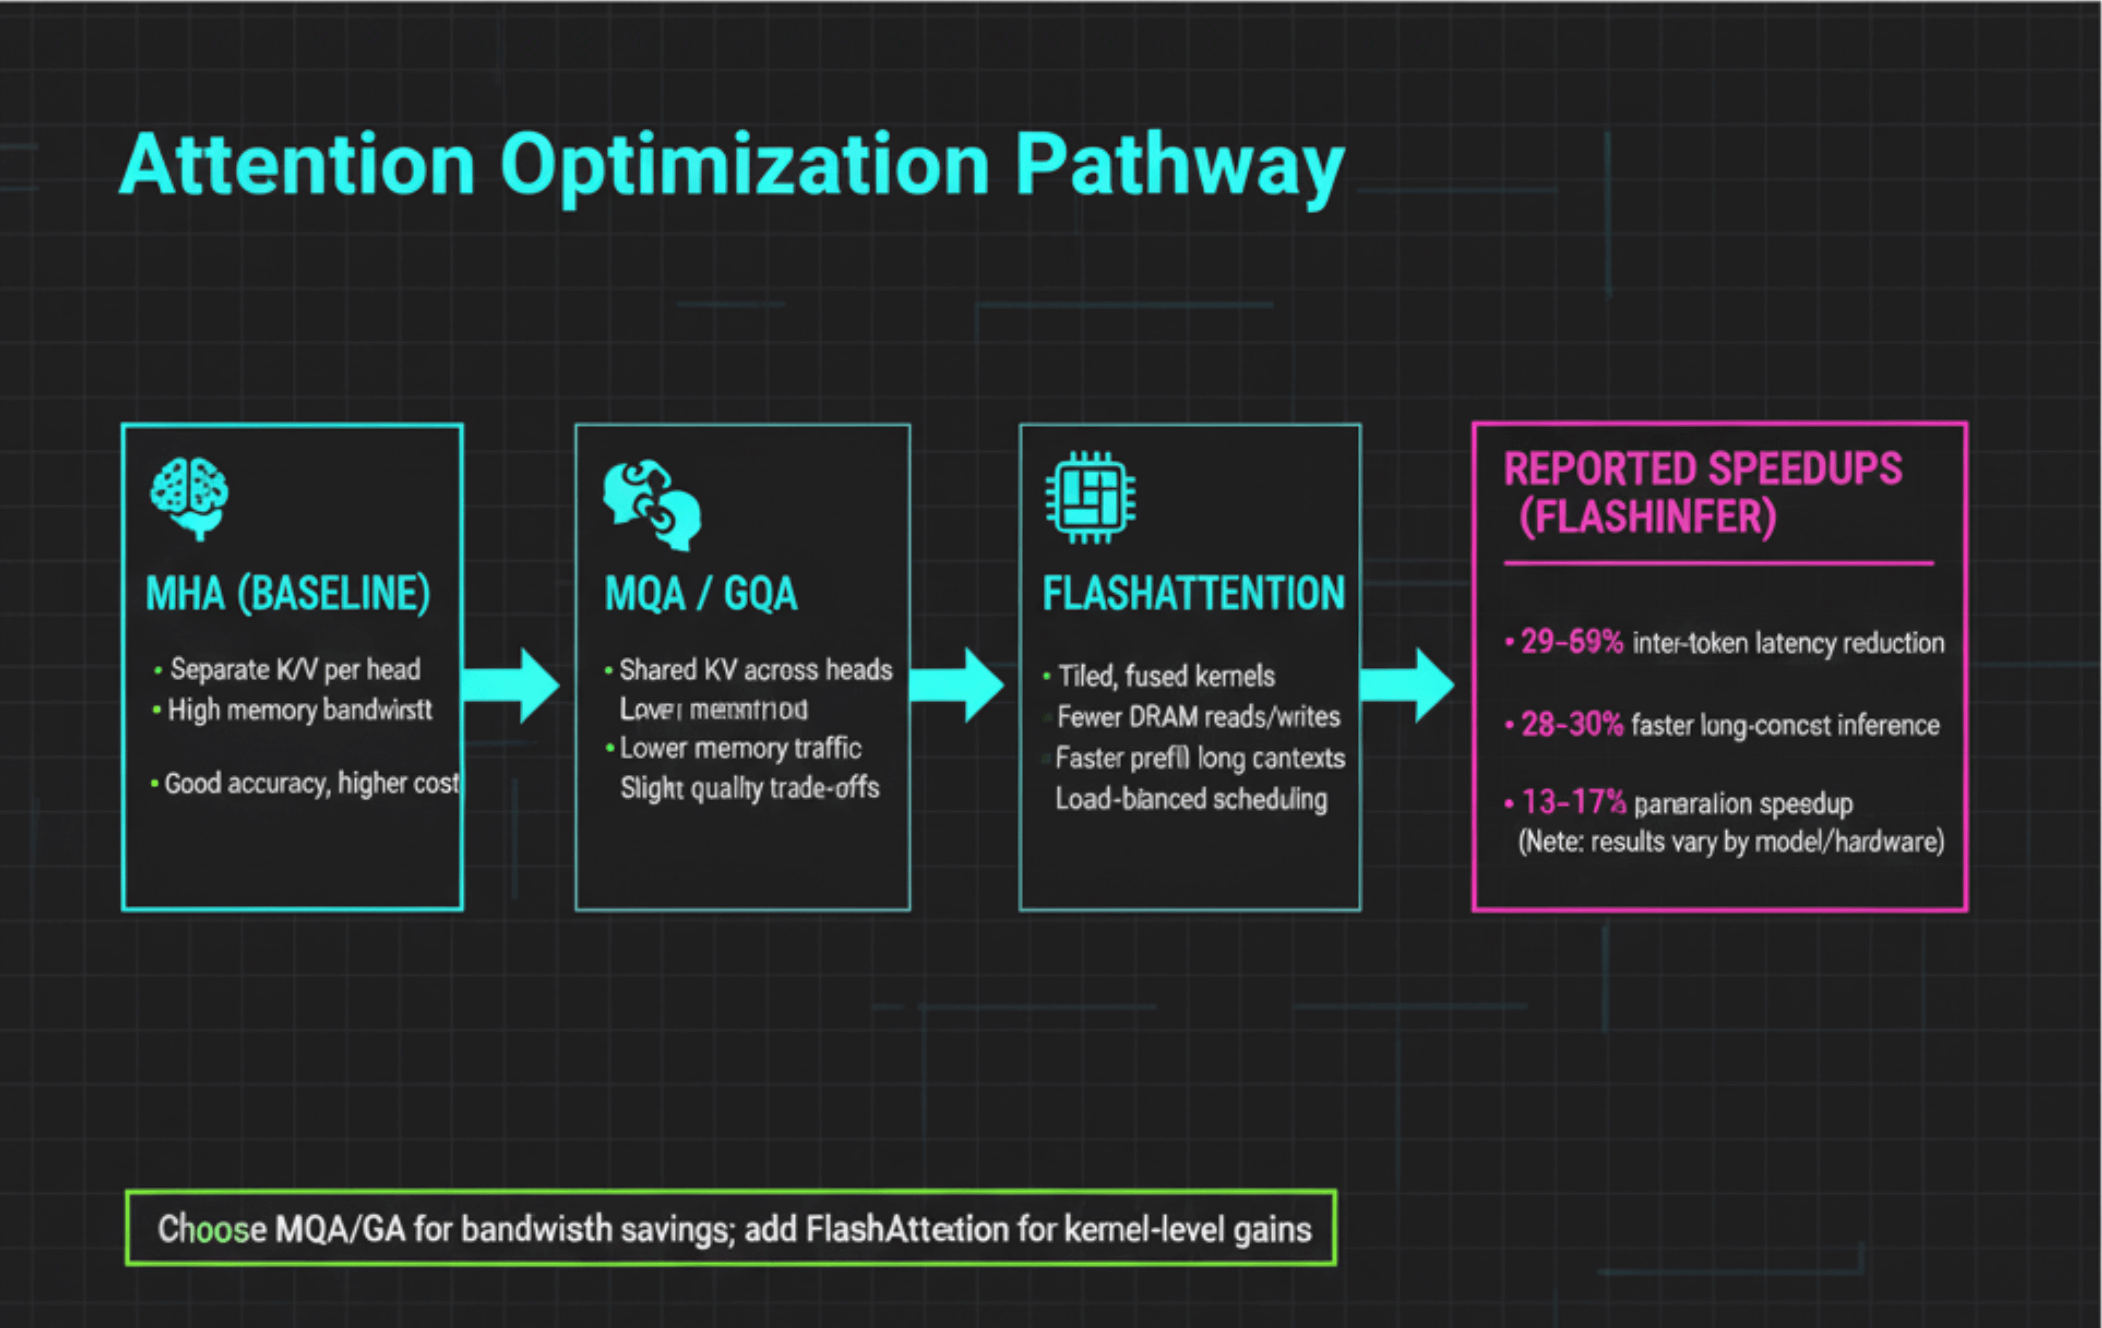
Standard multi‑head attention uses separate key and value projections for each head, which increases memory bandwidth requirements. Multi‑query attention reduces memory usage by sharing keys and values across multiple heads; grouped‑query attention further shares keys/values across groups of heads, balancing performance and accuracy. These approaches reduce the number of key/value matrices, decreasing memory traffic and improving inference speed. However, they may slightly reduce model quality; selecting the right configuration requires testing.

FlashAttention: Fused Operations and Tiling

FlashAttention is a GPU kernel that reorders operations and fuses them to maximize on‑chip memory usage; it calculates attention by tiling the Q/K/V matrices and reducing memory reads/writes. The original FlashAttention algorithm significantly speeds up attention on A100 and H100 GPUs and is widely adopted in open‑source frameworks. It requires custom kernels but integrates seamlessly into PyTorch.

FlashInfer: JIT‑Compiled, Block‑Sparse Attention

FlashInfer builds on FlashAttention with block‑sparse KV cache formats, JIT compilation and load‑balanced scheduling. Block‑sparse formats store KV caches in contiguous blocks rather than contiguous sequences, enabling selective fetches and lower memory fragmentation. JIT‑compiled kernels generate specialized code at runtime, optimizing for the current model configuration and sequence length. Benchmarks show FlashInfer reduces inter‑token latency by 29–69% and long‑context latency by 28–30%, speeding parallel generation by 13–17%.

Creative Example: Library Retrieval Analogy

Imagine a library where each book contains references to every other book; retrieving information requires cross‑referencing all these references (standard attention). If the library organizes references into groups that share index cards (MQA/GQA), librarians need fewer cards and can fetch information faster. FlashAttention is like reorganizing shelves so that books and index cards are adjacent, reducing walking time. FlashInfer introduces block‑based shelving and custom retrieval scripts that generate optimized retrieval instructions on the fly.

Expert Insights

  • Leading engineers note that FlashAttention can cut prefill latency dramatically when sequences are long.
  • FlashInfer’s block‑sparse design not only improves latency but also simplifies integration with continuous batching systems.
  • Choosing between MQA, GQA and standard MHA depends on the model’s target tasks; some tasks like code generation may tolerate more aggressive sharing.

Clarifai Integration

Clarifai’s inference runtime uses optimized attention kernels under the hood; you can select between standard MHA, MQA or GQA when training custom models. Clarifai also integrates with next‑generation attention engines like FlashInfer, providing performance gains without the need for manual kernel tuning. By leveraging Clarifai’s AI infrastructure, you gain the benefits of cutting‑edge research with a single configuration change.


How to Manage Memory with Key‑Value Caching?

Quick Summary

What is the role of the KV cache in LLMs, and how can we optimize it? The KV cache stores past keys and values during inference; managing it efficiently through PagedAttention, compression and streaming is critical to reduce memory usage and fragmentation.

Why KV Caching Matters

Self‑attention depends on all previous tokens; recomputing keys and values for each new token would be prohibitively expensive. The KV cache stores these computations so they can be reused, dramatically speeding up decode. However, caching introduces memory overhead: the size of the KV cache grows linearly with sequence length, number of layers and number of heads. This growth must be managed to avoid running out of GPU memory.

Memory Requirements and Fragmentation

Each layer of a model has its own KV cache, and the total memory required is the sum across layers and heads; the formula is roughly: 2 * num_layers * num_heads * context_length * hidden_size * precision_size. For a 7B model, this can quickly reach gigabytes per batch. Static cache allocation leads to fragmentation when sequence lengths vary; memory allocated for one sequence may remain unused if that sequence ends early, wasting capacity.

PagedAttention: Block‑Based KV Cache

PagedAttention divides the KV cache into fixed‑size blocks and stores them non‑contiguously in GPU memory; an index table maps tokens to blocks. When a sequence ends, its blocks can be recycled immediately by other sequences, minimizing fragmentation. This approach allows in‑flight batching where sequences of different lengths coexist in the same batch. PagedAttention is implemented in vLLM and other inference engines to reduce memory overhead.

KV Cache Compression and Streaming

Researchers are exploring compression techniques to reduce KV cache size, such as storing keys/values in lower precision or using delta encoding for incremental changes. Streaming cache approaches offload older tokens to CPU or disk and prefetch them when needed. These techniques trade compute for memory but enable longer context windows without scaling GPU memory linearly.

Expert Insights

  • The NVidia research team calculated that a 7B model with 4,096 tokens needs ~2 GB of KV cache per batch; for multiple concurrent sessions, memory quickly becomes the bottleneck.
  • PagedAttention reduces KV cache fragmentation and supports dynamic batching; vLLM’s implementation has become widely adopted in open‑source serving frameworks.
  • Compression and streaming caches are active research areas; when fully mature, they may enable 1M-token contexts without exorbitant memory usage.

Clarifai Integration

Clarifai’s model serving engine uses dynamic KV cache management to recycle memory across sessions; users can configure PagedAttention for improved memory efficiency. Clarifai’s analytics dashboard provides real‑time monitoring of cache hit rates and memory usage, enabling data‑driven scaling decisions. By combining Clarifai’s caching strategies with dynamic batching, you can handle more concurrent users without provisioning extra GPUs.

KV Cache Memory Footprint & PagedAttention


What Model‑Level Optimizations Reduce Size and Cost?

Quick Summary

Which model modifications shrink size and accelerate inference? Model‑level optimizations include quantization, sparsity, knowledge distillation, mixture‑of‑experts (MoE) and parameter‑efficient fine‑tuning; these techniques reduce memory and compute requirements while retaining accuracy.

Quantization: Reducing Precision

Quantization converts model weights and activations from 32‑bit or 16‑bit precision to lower bit widths such as 8‑bit or even 4‑bit. Lower precision reduces memory footprint and speeds up matrix multiplications, but may introduce quantization error if not applied carefully. Techniques like LLM.int8() target outlier activations to maintain accuracy while converting the bulk of weights to 8‑bit. Dynamic quantization adapts bit widths on the fly based on activation statistics, further reducing error.

Structured Sparsity: Pruning Weights

Sparsity prunes redundant or near‑zero weights in neural networks; structured sparsity removes entire blocks or groups of weights (e.g., 2:4 sparsity means two of four weights in a group are zero). GPUs can accelerate sparse matrix operations, skipping zero elements to save compute and memory bandwidth. However, pruning must be done judiciously to avoid quality degradation; fine‑tuning after pruning helps recover performance.

Knowledge Distillation: Teacher‑Student Paradigm

Distillation trains a smaller ‘student’ model to mimic the outputs of a larger ‘teacher’ model. The student learns to approximate the teacher’s internal distributions rather than just final labels, capturing richer information. Notable results include DistilBERT and DistilGPT, which achieve about 97% of the teacher’s performance while being 40% smaller and 60% faster. Distillation helps deploy large models to resource‑constrained environments like edge devices.

Mixture‑of‑Experts (MoE) Models

MoE models contain multiple specialized expert sub‑models and a gating network that routes each token to one or a few experts. At inference time, only a fraction of parameters is active, reducing memory usage per token. For example, an MoE model with 20B parameters might activate only 3.6 B parameters per forward pass. MoE models can achieve quality comparable to dense models at lower compute cost, but they require sophisticated routing and may introduce load‑balancing challenges.

Parameter‑Efficient Fine‑Tuning (PEFT)

Methods like LoRA, QLoRA and adapters add lightweight trainable layers on top of frozen base models, enabling fine‑tuning with minimal additional parameters. PEFT reduces fine‑tuning overhead and speeds up inference by keeping the majority of weights frozen. It’s particularly useful for customizing large models to domain‑specific tasks without replicating the entire model.

Expert Insights

  • Quantization yields 2–4× compression while maintaining accuracy when using techniques like LLM.int8().
  • Structured sparsity (e.g., 2:4) is supported by modern GPUs, enabling real‑time speedups without specialized hardware.
  • Distillation offers a compelling trade‑off: DistilBERT retains 97% of BERT’s performance yet is 40% smaller and 60% faster.
  • MoE models can slash active parameters per token, but gating and load balancing require careful engineering.

Clarifai Integration

Clarifai supports quantized and sparse model formats out of the box; you can load 8‑bit models and benefit from reduced latency without manual modifications. Our platform also provides tools for knowledge distillation, allowing you to distill large models into smaller variants suited for real‑time applications. Clarifai’s mixture‑of‑experts architecture enables you to route queries to specialized sub‑models, optimizing compute usage for diverse tasks.


Should You Use Speculative and Disaggregated Inference?

Quick Summary

What are speculative and disaggregated inference, and how do they improve performance? Speculative inference uses a cheap draft model to generate multiple tokens in parallel, which the main model then verifies; disaggregated inference separates prefill and decode phases across different hardware resources.

Speculative Inference: Draft and Verify

Speculative inference splits the decoding workload between two models: a smaller, fast ‘draft’ model generates a batch of token candidates, and the large ‘verifier’ model checks and accepts or rejects these candidates. If the verifier accepts the draft tokens, inference advances several tokens at once, effectively parallelizing token generation. If the draft includes incorrect tokens, the verifier corrects them, ensuring output quality. The challenge is designing a draft model that approximates the verifier’s distribution closely enough to achieve high acceptance rates.

Collaborative Speculative Decoding with CoSine

The CoSine system extends speculative inference by decoupling drafting and verification across multiple nodes; it uses specialized drafters and a confidence‑based fusion mechanism to orchestrate collaboration. CoSine’s pipelined scheduler assigns requests to drafters based on load and merges candidates via a gating network; this reduces latency by 23% and increases throughput by 32% in experiments. CoSine demonstrates that speculative decoding can scale across distributed clusters.

Disaggregated Inference: Separating Prefill and Decode

Disaggregated inference runs the compute‑bound prefill phase on high‑end GPUs (e.g., cloud GPUs) and offloads the memory‑bound decode phase to cheaper, memory‑optimized hardware closer to end users. This architecture reduces end‑to‑end latency by minimizing network hops for decode and leverages specialized hardware for each phase. For example, large GPU clusters perform the heavy lifting of prefill, while edge devices or CPU servers handle sequential decode, streaming tokens to users.

Trade‑Offs and Considerations

Speculative inference adds complexity by requiring a separate draft model; tuning draft accuracy and acceptance thresholds is non‑trivial. If acceptance rates are low, the overhead may outweigh benefits. Disaggregated inference introduces network communication costs between prefill and decode nodes; reliability and synchronization become critical. Nonetheless, these approaches represent innovative ways to break the sequential bottleneck and bring inference closer to the user.

Expert Insights

  • Speculative inference can reduce decode latency dramatically; however, acceptance rates depend on the similarity between draft and verifier models.
  • CoSine’s authors achieved 23% lower latency and 32% higher throughput by distributing speculation across nodes.
  • Disaggregated inference is promising for edge deployment, where decode runs on local hardware while prefill remains in the cloud.

Clarifai Integration

Clarifai is researching speculative inference as part of its upcoming inference innovations; our platform will enable you to specify a draft model for speculative decoding, automatically handling acceptance thresholds and fallback mechanisms. Clarifai’s edge deployment capabilities support disaggregated inference: you can run prefill in the cloud using high‑performance GPUs and decode on local runners or mobile devices. This hybrid architecture reduces latency and data transfer costs, delivering faster responses to your end users.


Why Is Inference Scheduling and Request Routing Critical?

Quick Summary

How can smart scheduling and routing improve cost and latency? Request scheduling predicts decode lengths and groups similar requests, dynamic routing assigns tasks to appropriate models, and caching reduces duplicate computation.

Decode Length Prediction and Priority Scheduling

Scheduling systems can predict the number of tokens a request will generate (decode length) based on historical data or model heuristics. Shorter requests are prioritized to minimize overall queue time, reducing tail latency. Dynamic batch managers adjust groupings based on predicted lengths, achieving fairness and maximizing throughput. Predictive scheduling also helps allocate memory for the KV cache, avoiding fragmentation.

Routing to the Right Model

Different tasks have varying complexity: summarizing a short paragraph may require a small 3B model, while complex reasoning might need a 70B model. Smart routing matches requests to the smallest sufficient model, reducing computation and cost. Routing can be rule‑based (task type, input length) or learned via meta‑models that estimate quality gains. Multi‑model orchestration frameworks enable seamless fallbacks if a smaller model fails to meet quality thresholds.

Caching and Deduplication

Caching identical or similar requests avoids redundant computations; caching strategies include exact match caching (hashing prompts), semantic caching (embedding similarity) and prefix caching (storing partial KV caches). Semantic caching allows retrieval of answers for paraphrased queries; prefix caching stores KV caches for common prefixes in chat applications, allowing multiple sessions to share partial computations. Combined with routing, caching can cut costs by up to 90%.

Streaming Responses

Streaming outputs tokens as soon as they’re generated rather than waiting for the entire output improves perceived latency and allows user interaction while the model continues generating. Streaming reduces “time to first token” (TTFT) and keeps users engaged. Inference engines should support token streaming alongside dynamic batching and caching.

Context Compression and GraphRAG

When retrieval‑augmented generation is used, compressing context via summarization or passage selection reduces the number of tokens passed to the model, saving compute. GraphRAG builds knowledge graphs from retrieval results to improve retrieval accuracy and reduce redundancy. By reducing context lengths, you lighten memory and latency load during inference.

Parallel API Calls and Tools

LLM outputs often depend on external tools or APIs (e.g., search, database queries, summarization); orchestrating these calls in parallel reduces sequential waiting time. Frameworks like Clarifai’s Workflow API support asynchronous tool execution, ensuring that the model doesn’t idle while waiting for external data.

Expert Insights

  • Semantic caching can reduce compute by up to 90% for repeated requests.
  • Streaming responses improve user satisfaction by reducing the time to first token; combine streaming with dynamic batching for optimal results.
  • GraphRAG and context compression reduce token overhead and improve retrieval quality, leading to cost savings and higher accuracy.

Clarifai Integration

Clarifai offers built‑in decode length prediction and batch scheduling to optimize queueing; our smart router assigns tasks to the most suitable model, reducing compute costs. With Clarifai’s caching layer, you can enable semantic and prefix caching with a single configuration, drastically cutting costs. Streaming is enabled by default in our inference API, and our workflow orchestration executes independent tools concurrently.


What Performance Metrics Should You Monitor?

Quick Summary

Which metrics define success in LLM inference? Key metrics include time to first token (TTFT), time between tokens (TBT), tokens per second, throughput, P95/P99 latency and memory usage; monitoring token usage, cache hits and tool execution time yields actionable insights.

Core Latency Metrics

Time to first token (TTFT) measures the delay between sending a request and receiving the first output token; it is influenced by model loading, tokenization, prefill and scheduling. Time between tokens (TBT) measures the interval between consecutive output tokens; it reflects decode efficiency. Tokens per second (TPS) is the reciprocal of TBT and indicates throughput. Monitoring TTFT and TPS helps optimize both prefill and decode phases.

Percentile Latency and Throughput

Average latency can hide tail performance issues; therefore, tracking P95 and P99 latency—where 95% or 99% of requests finish faster—is crucial to ensure consistent user experience. Throughput measures the number of requests or tokens processed per unit time; high throughput is essential for serving many users concurrently. Capacity planning should consider both throughput and tail latency to prevent overload.

Resource Utilization

CPU and GPU utilization metrics show how efficiently hardware is used; low GPU utilization in decode may signal memory bottlenecks, while high CPU usage may indicate bottlenecks in tokenization or tool execution. Memory usage, including KV cache occupancy, helps identify fragmentation and the need for compaction techniques.

Application‑Level Metrics

In addition to hardware metrics, monitor token usage, cache hit ratios, retrieval latencies and tool execution times. High cache hit rates reduce compute cost; long retrieval or tool latency suggests a need for parallelization or caching external responses. Observability dashboards should correlate these metrics with user experience to identify optimization opportunities.

Benchmarking Tools

Open‑source tools like vLLM include built‑in benchmarking scripts for measuring latency and throughput across different models and batch sizes. KV cache calculators estimate memory requirements for specific models and sequence lengths. Integrating these tools into your performance testing pipeline ensures realistic capacity planning.

Expert Insights

  • Focusing on P99 latency ensures that even the slowest requests meet service-level objectives (SLOs).
  • Monitoring token usage and cache hits is critical for optimizing caching strategies.
  • Throughput should be measured alongside latency because high throughput doesn’t guarantee low latency if tail requests lag.

Clarifai Integration

Clarifai’s analytics dashboard provides real‑time charts for TTFT, TPS, P95/P99 latency, GPU/CPU utilization, and cache hit rates. You can set alerts for SLO violations and automatically scale up resources when throughput threatens to exceed capacity. Clarifai also integrates with external observability tools like Prometheus and Grafana for unified monitoring across your stack.


Case Studies & Frameworks: How Do vLLM, FlashInfer, TensorRT‑LLM, and LMDeploy Compare?

Quick Summary

What can we learn from real‑world LLM serving frameworks? Frameworks like vLLM, FlashInfer, TensorRT‑LLM and LMDeploy implement dynamic batching, attention optimizations, multi‑GPU parallelism and quantization; understanding their strengths helps choose the right tool for your application.

vLLM: Continuous Batching and PagedAttention

vLLM is an open‑source inference engine designed for high‑throughput LLM serving; it introduces continuous batching and PagedAttention to maximize GPU utilization. Continuous batching evicts completed sequences and inserts new ones, eliminating head‑of‑line blocking. PagedAttention partitions KV caches into fixed‑size blocks, reducing memory fragmentation. vLLM provides benchmarks showing low latency even at high batch sizes, with performance scaling across GPU clusters.

FlashInfer: Next‑Generation Attention Engine

FlashInfer is a research project that builds upon FlashAttention; it employs block‑sparse KV cache formats and JIT compilation to optimize kernel execution. By using custom kernels for each sequence length and model configuration, FlashInfer reduces inter‑token latency by 29–69% and long‑context latency by 28–30%. It integrates with vLLM and other frameworks, offering state‑of‑the‑art performance improvements.

TensorRT‑LLM

TensorRT‑LLM is an NVIDIA‑backed framework that converts LLMs into highly optimized TensorRT engines; it features dynamic batching, KV cache management and quantization support. TensorRT‑LLM integrates with the TensorRT library to accelerate inference on GPUs using low‑level kernels. It supports custom plugins for attention and offers fine‑grained control over kernel selection.

LMDeploy

LMDeploy (formerly by Alibaba) focuses on serving LLMs using quantization and dynamic batching; it emphasizes compatibility with various hardware platforms and includes a runtime for CPU, GPU and AI accelerators. LMDeploy supports low‑bit quantization, enabling deployment on edge devices. It also integrates request routing and caching.

Comparative Table

Framework

Key Features

Use Cases

vLLM

Continuous batching, PagedAttention, dynamic KV cache management

High‑throughput GPU inference, dynamic workloads

FlashInfer

Block‑sparse KV cache, JIT kernels, integrated with vLLM

Long‑context tasks, parallel generation

TensorRT‑LLM

TensorRT integration, quantization, custom plugins

GPU optimization, low‑level control

LMDeploy

Quantization, dynamic batching, cross‑hardware support

Edge deployment, CPU inference

Expert Insights

  • vLLM’s innovations in continuous batching and PagedAttention have become industry standards; many cloud providers adopt these techniques for production.
  • FlashInfer’s JIT approach highlights the importance of customizing kernels for specific models; this reduces overhead for long sequences.
  • Framework selection depends on your priorities: vLLM excels at throughput, TensorRT‑LLM provides low‑level optimization, and LMDeploy shines on heterogeneous hardware.

Clarifai Integration

Clarifai integrates with vLLM and TensorRT‑LLM as part of its backend infrastructure; you can choose which engine suits your latency and hardware needs. Our platform abstracts away the complexity, offering you a simple API for inference while running on the most efficient engine under the hood. If your use case demands quantization or edge deployment, Clarifai automatically selects the appropriate backend (e.g., LMDeploy).


Emerging Trends & Future Directions: Where Is LLM Inference Going?

Quick Summary

What innovations are shaping the future of LLM inference? Trends include long‑context support, retrieval‑augmented generation (RAG), mixture‑of‑experts scheduling, efficient reasoning, parameter‑efficient fine‑tuning, speculative and collaborative decoding, disaggregated and edge deployment, and energy‑aware inference.

Long‑Context Support and Advanced Attention

Users demand longer context windows to handle documents, conversations and code bases; research explores ring attention, sliding window attention and extended Rotary Position Embedding (RoPE) techniques to scale context lengths. Block‑sparse attention and memory‑efficient context windows like RexB aim to support millions of tokens without linear memory growth. Combining FlashInfer with long‑context strategies will enable new applications like summarizing books or analyzing large code repositories.

Retrieval‑Augmented Generation (RAG) and GraphRAG

RAG enhances model outputs by retrieving external documents or database entries; improved chunking strategies reduce context length and noise. GraphRAG builds graph‑structured representations of retrieved data, enabling reasoning over relationships and reducing token redundancy. Future inference engines will integrate retrieval pipelines, caching and knowledge graphs seamlessly.

Mixture‑of‑Experts Scheduling and MoEfic

MoE models will benefit from improved scheduling algorithms that balance expert load, compress gating networks and reduce communication. Research like MoEpic and MoEfic explores expert consolidation and load balancing to achieve dense‑model quality with lower compute. Inference engines will need to route tokens to the right experts dynamically, tying into routing strategies.

Parameter‑Efficient Fine‑Tuning (PEFT) and On‑Device Adaptation

PEFT methods like LoRA and QLoRA continue to evolve; they enable on‑device fine‑tuning of LLMs using only low‑rank parameter updates. Edge devices equipped with AI accelerators (Qualcomm AI Engine, Apple Neural Engine) can perform inference and adaptation locally. This allows personalization and privacy while reducing latency.

Efficient Reasoning and Overthinking

The overthinking phenomenon occurs when models generate unnecessarily long chains of thought, wasting compute; research suggests efficient reasoning strategies such as early exit, reasoning‑output‑based pruning and input‑prompt optimization. Optimizing the reasoning path reduces inference time without compromising accuracy. Future architectures may incorporate dynamic reasoning modules that skip unnecessary steps.

Speculative Decoding and Collaborative Systems

Speculative decoding will continue to evolve; multi‑node systems like CoSine demonstrate collaborative drafting and verification with improved throughput. Developers will adopt similar strategies for distributed inference across data centers and edge devices.

Disaggregated and Edge Inference

Disaggregated inference separates compute and memory phases across heterogeneous hardware; combining with edge deployment will minimize latency by bringing decode closer to the user. Edge AI chips can perform decode locally while prefill runs in the cloud. This opens new use cases in mobile and IoT.

Energy‑Aware Inference

As AI adoption grows, energy consumption will rise; research is exploring energy‑proportional inference, carbon‑aware scheduling and hardware optimized for energy efficiency. Balancing performance with environmental impact will be a priority for future inference frameworks.

Expert Insights

  • Long‑context solutions are essential for handling large documents; ring attention and sliding windows reduce memory usage without sacrificing context.
  • Efficient reasoning can dramatically lower compute cost by pruning unnecessary chain‑of‑thought reasoning.
  • Speculative decoding and disaggregated inference will continue to push inference closer to users, enabling near‑real‑time experiences.

Clarifai Integration

Clarifai stays on the cutting edge by integrating long‑context engines, RAG workflows, MoE routing and PEFT into its platform. Our upcoming inference suite will support speculative and collaborative decoding, disaggregated pipelines and energy‑aware scheduling. By partnering with Clarifai, you future‑proof your AI applications against rapid advances in LLM technology.


Conclusion: Building Efficient and Reliable LLM Applications

Optimizing LLM inference is a multifaceted challenge involving architecture, hardware, scheduling, model design and system‑level considerations. By understanding the distinction between prefill and decode and addressing memory‑bound bottlenecks, you can make more informed deployment decisions. Implementing batching strategies, multi‑GPU parallelization, attention and KV cache optimizations, and model‑level compression yields significant gains in throughput and cost efficiency. Advanced techniques like speculative and disaggregated inference, combined with intelligent scheduling and routing, push the boundaries of what’s possible.

Monitoring key metrics such as TTFT, TBT, throughput and percentile latency allows continuous improvement. Evaluating frameworks like vLLM, FlashInfer and TensorRT‑LLM helps you choose the right tool for your environment. Finally, staying attuned to emerging trends—long‑context support, RAG, MoE scheduling, efficient reasoning and energy awareness—ensures your infrastructure remains future‑proof.

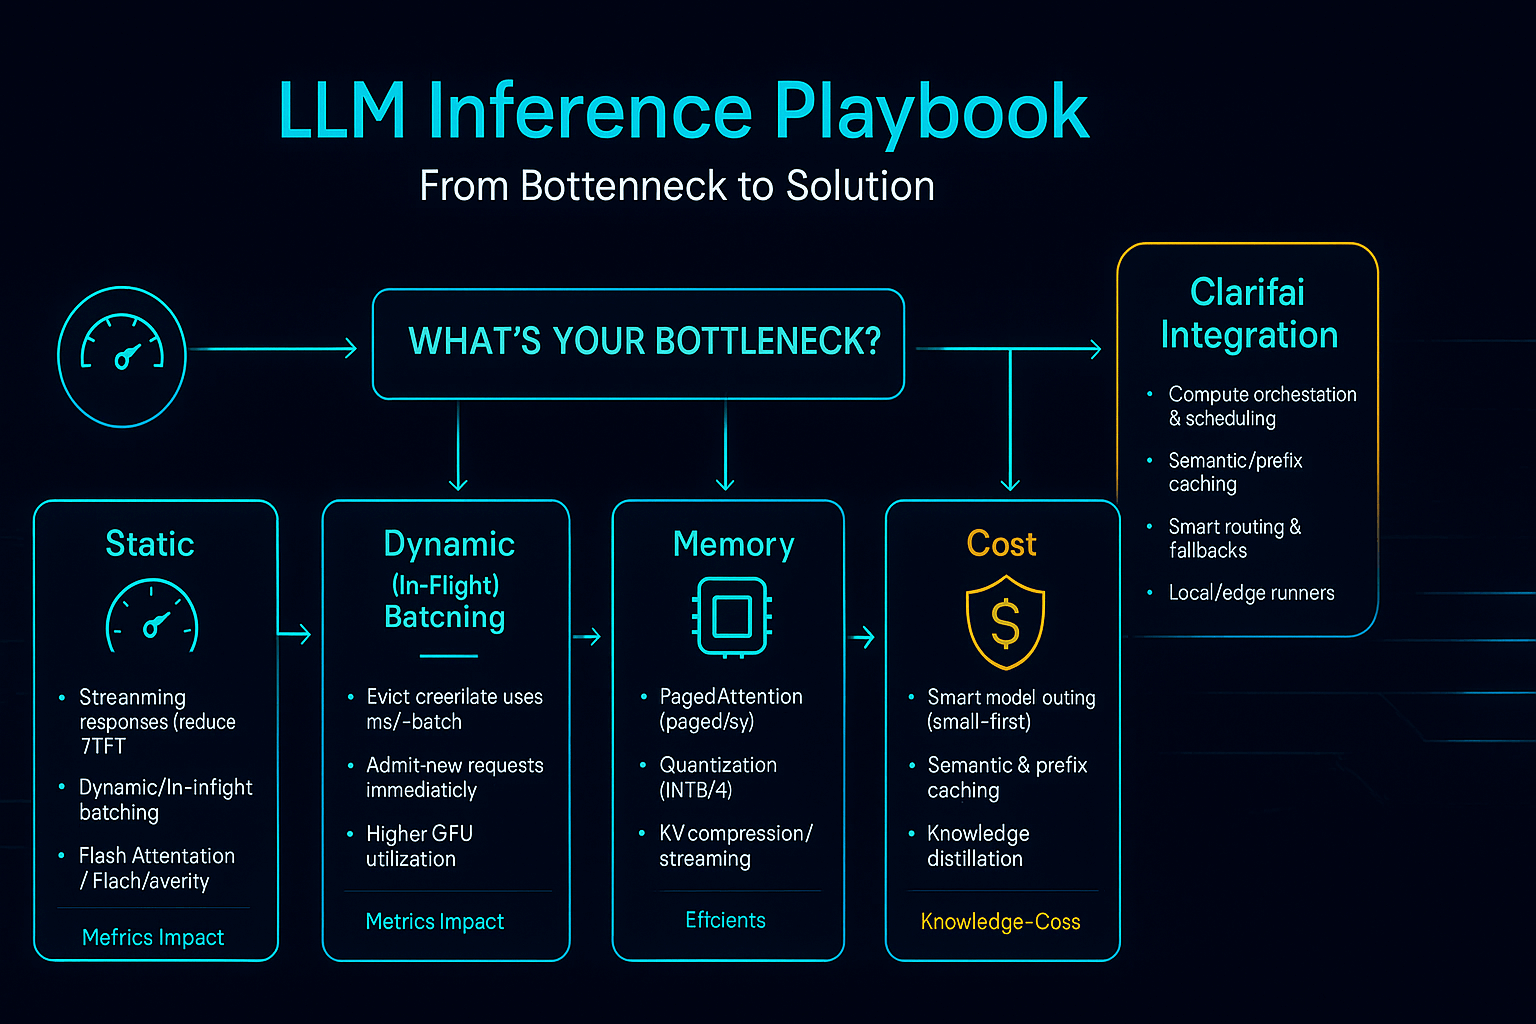
Clarifai offers a comprehensive platform that embodies these best practices: dynamic batching, multi‑GPU support, caching, routing, streaming and metrics monitoring are built into our inference APIs. We integrate with cutting‑edge kernels and research innovations, enabling you to deploy state‑of‑the‑art models with minimal overhead. By partnering with Clarifai, you can focus on building transformative AI applications while we manage the complexity of inference optimization.

LLM Inference Playbook


Frequently Asked Questions

Why is LLM inference so expensive?

LLM inference is expensive because large models require significant memory to store weights and KV caches, and compute resources to process billions of parameters; decode phases are memory‑bound and sequential, limiting parallelism. Inefficient batching, routing and caching further amplify costs.

How does dynamic batching differ from static batching?

Static batching groups requests and processes them together but suffers from head‑of‑line blocking when some requests are longer than others; dynamic or in‑flight batching continuously adds and removes requests mid‑batch, improving GPU utilization and reducing tail latency.

Can I deploy large LLMs on edge devices?

Yes; techniques like quantization, distillation and parameter‑efficient fine‑tuning reduce model size and compute requirements, while disaggregated inference offloads heavy prefill stages to cloud GPUs and runs decode locally.

What is the benefit of KV cache compression?

KV cache compression reduces memory usage by storing keys and values in lower precision or using block‑sparse formats; this allows longer context windows without scaling memory linearly. PagedAttention is an example technique that recycles cache blocks to minimize fragmentation.

How does Clarifai help with LLM inference optimization?

Clarifai provides an inference platform that abstracts away complexity: dynamic batching, caching, routing, streaming, multi‑GPU support and advanced attention kernels are integrated by default. You can deploy custom models with quantization or MoE architectures and monitor performance using Clarifai’s analytics dashboard. Our upcoming features will include speculative decoding and disaggregated inference, keeping your applications at the forefront of AI technology.


How AI-Generated Content Is Destroying Team Productivity


Generative AI was supposed to supercharge productivity. Instead, many companies are grappling with something that researchers are calling “workslop,” or AI-generated output that looks polished but actually creates more work. Continue reading “How AI-Generated Content Is Destroying Team Productivity”

Building AI Agents with Agno and GPT-OSS 120B


Introduction

Modern AI applications increasingly rely on intelligent agents that do more than chat; they reason, search, and collaborate. By using Agno, a lightweight framework, and Clarifai’s GPT-OSS 120B, an open-source large language model accessible through an OpenAI-compatible API, you can create sophisticated agents with minimal setup.

This tutorial walks you through three progressively advanced examples:

  1. A web-search agent that answers current events questions.

  2. A knowledge-based agent that accesses domain-specific information.

  3. A multi-agent system where specialized agents work together.

You will also find instructions for setting up your environment and a link to a Colab notebook with the full code so you can follow along.

Setting Up the Environment

To get started, install Agno along with libraries for search, PDF processing, vector storage, finance data, and the Clarifai SDK:

Make sure you have a Clarifai Personal Access Token (PAT) and set it as an environment variable so your agents can authenticate to access GPT-OSS-120B model from Clarifai.

1. A Simple Agent with Web Search

The first example creates an agent that combines GPT-OSS 120B with DuckDuckGo search to answer questions about recent events. The language model interprets the query, the search tool fetches live information, and the agent then assembles a coherent response.

This straightforward setup demonstrates how easily you can combine reasoning with web search. It serves as the foundation for more complex agents.

2. Adding a Knowledge Base

Real-world applications often require access to proprietary or specialized data. In this example, you’ll build a Thai cuisine expert using a recipes PDF. The process includes:

  • Embedding the document with text-embedding-ada-002 from the Clarifai community. 

  • Storing the vectors in LanceDB for efficient retrieval.

  • Configuring the agent to consult its knowledge base first, and only fall back to web search if necessary.

The agent returns a grounded recipe from the PDF and uses web search as a fallback. This approach is essential for building domain experts that rely on proprietary or internal data sources.

3. Coordinating Multiple Agents

For complex scenarios, multi-agent orchestration can help divide and conquer tasks. Agno supports teams of agents, enabling specialization and collaboration. In this example:

  • A Web Research Agent fetches news and current information.

  • A Financial Analysis Agent pulls stock and market data.

  • A Coordinator synthesizes their outputs into a single response.

Here, each agent plays a distinct role, demonstrating how specialization leads to more comprehensive answers. This architecture is ideal for domains such as market research, technical analysis, or any multi-faceted problem that benefits from teamwork.

Conclusion

This walkthrough showcased how to build progressively more capable agents with Agno and GPT-OSS 120B:

  • Simple Web-Search Agent: A quick way to combine language understanding with live data.

  • Knowledge-Based Domain Expert: An agent that draws from proprietary data and uses web search only when needed.

  • Multi-Agent System: A coordinated approach where specialized agents collaborate to solve complex problems.

Each stage adds new capabilities, enabling you to build more advanced systems. For many use cases, a simple web-search agent may suffice. For specialized assistants or research tools, embedding your own data is crucial. And for multi-domain tasks, orchestrating multiple agents can be incredibly powerful.

There is no one-size-fits-all agent—each implementation can be fully customized based on your specific needs, business objectives, and domain requirements.

You can extend these patterns by building multi-agent teams, integrating domain-specific APIs, or experimenting with different agent designs such as coordinator-agent, collaborative-agent, or specialized-task agents. These approaches enable the creation of flexible, adaptive AI systems that can be tailored to solve complex, real-world challenges efficiently and effectively. To explore the examples in this tutorial, check out this notebook. 

Agentic AI workflows are computationally demanding because they involve multiple agents interacting, reasoning over large contexts, and responding in real time. To operate effectively, these workloads require both high throughput and low latency.

The Clarifai Reasoning Engine provides the computational efficiency required for such workflows. Independent benchmarks by Artificial Analysis on the GPT-OSS-120B model show that it can process over 500 tokens per second with 0.3 seconds to first token, demonstrating the kind of performance that enables responsive and scalable multi-agent systems. You can try out the GPT-OSS-120B model.


What Is Orchestration in Computing? Types, Benefits & Future Trends


Orchestration has become a foundational concept in the digital era, allowing businesses to stitch together everything from container deployments to business processes into a seamless flow. When done well, orchestration transforms scattered tasks into cohesive, automated workflows, unlocking reliability, scalability and cost efficiency. In the AI space, Clarifai leads this orchestration revolution with its compute orchestration platform that works across clouds and on‑premises, helping organizations deploy and run AI efficiently. This article demystifies orchestration in computing, explains how it differs from automation, highlights major tools and use cases, and offers practical guidance for getting started.

Quick Digest: What’s Coming in This Guide

  • What is orchestration? Orchestration coordinates multiple automated tasks and services to deliver an end‑to‑end outcome. It operates like a conductor managing an orchestra, ensuring every component plays its part at the right time.
  • Why now? Companies rely on microservices, containers and hybrid clouds, making manual coordination impossible. Orchestration simplifies deployment, scaling and reliability.
  • Key distinctions: Understand how orchestration differs from automation and choreography, and why these concepts matter.
  • Types and tools: Explore different types of orchestration—containers, workflows, infrastructure—and compare leading tools like Kubernetes, Airflow, Terraform, and Clarifai’s orchestration platform.
  • Benefits and challenges: Learn about the scalability, cost savings and reliability orchestration brings, as well as potential pitfalls like complexity and security risks.
  • Best practices: Discover patterns such as decoupled design, observability, and CI/CD that ensure orchestration success.
  • Emerging trends: Get a glimpse of the future with AI‑driven orchestration, edge computing, multi‑cloud strategies and generative AI that helps design systems.
  • How to start: Follow a step‑by‑step guide and see how Clarifai’s compute orchestration and local runners can simplify your journey.
  • FAQs: Wrap up with answers to common questions.

Understanding Orchestration—Definition, Evolution & Concepts

How Has Orchestration Evolved and What Does It Mean?

In computing, orchestration refers to the automated coordination of multiple tasks, services and resources to achieve a desired outcome. Think of a conductor guiding an orchestra—each musician (task) must play the right note at the right time for the piece (workflow) to come together. Similarly, orchestration tools manage dependencies, sequence tasks, handle failures and scale resources to deliver complex workflows. Initially, teams relied on cron jobs and custom scripts to automate single tasks. As systems grew into distributed architectures with containers and microservices, manual coordination became unsustainable. Modern orchestration emerged to bridge disparate components into unified workflows, making deployment and scaling seamless.

Why Is Orchestration Important in Today’s Digital Landscape?

Companies deploy applications across hybrid clouds, edge devices and on‑premises environments. Manual oversight can’t scale with such complexity. Orchestration solves this by managing lifecycles (start, stop, scale), handling retries, sequencing tasks, monitoring performance and recovering from failures automatically. In the AI domain, Clarifai’s unified control plane orchestrates AI models across different infrastructures, helping customers optimize costs and avoid vendor lock‑in. The modern emphasis on agility and DevOps makes orchestration critical—organizations can deploy changes faster while ensuring reliability.

Expert Insights & Statistics

  • Survey data indicates that more than 80 % of organizations use containers in production, and 87 % run microservices, many managed by orchestration platforms.
  • Dynatrace reports that organizations adopting container orchestration see improved scalability and more than 60 % of infrastructure workloads deployed on Kubernetes.
  • Clarifai states that their compute orchestration can deliver up to 90 % less compute needed, handle 1.6 million inference requests per second, and provide 99.999 % reliability.
  • Expert tip: Think of orchestration as the glue that binds microservices and tasks. Without it, your system is like a group of musicians practicing solo—talented individually but chaotic together.

Creative Example: The Factory Analogy

Imagine a factory assembling smartphones. Each station performs a specific task—cutting glass, installing chips, applying adhesive. If each station works independently, parts pile up or run out. An orchestration system acts like the factory supervisor: it determines when each station should start, stops when needed, handles shortages, and ensures every phone flows smoothly down the line. Similarly, orchestration in computing coordinates tasks so that data moves through pipelines, containers spin up and down, and services communicate reliably.


Orchestration vs. Automation vs. Choreography – Clear Distinctions

What’s the Difference Between Orchestration and Automation?

Automation involves executing a single task or a sequence of static steps automatically—like a script that backs up a database every night. Orchestration, on the other hand, coordinates multiple automated tasks, making decisions based on system state, dependencies and business rules. It ensures tasks run in the correct order, handle failures gracefully and scale up or down based on demand. Think of automation as playing one instrument and orchestration as leading an entire orchestra.

How Does Choreography Fit In?

Choreography relates primarily to event‑driven microservices. In choreography, each service listens for events and reacts independently without a central coordinator. This peer‑to‑peer model can be highly scalable but may introduce complexity if not designed carefully. Orchestration, in contrast, relies on a central controller (the orchestrator) that directs services and coordinates their interactions. Choosing between orchestration and choreography depends on your architecture: orchestration provides visibility and control; choreography offers loose coupling and autonomy.

Expert Insights & Advanced Tips

  • Red Hat experts note that automation is a subset of orchestration; while automation can perform tasks, orchestration adds decision logic and state awareness.
  • Microservice architects often blend both: they use orchestration for complex workflows that need oversight and choreography for event‑driven communication when services must respond quickly to changes.
  • Advanced tip: Avoid coupling your orchestration tool tightly to business logic. Keep business rules separate so you can switch orchestrators without rewriting core services.

Orchestration vs. Automation vs. Choreography


Types of Orchestration in Computing

Orchestration spans multiple domains. Understanding the different types helps you select the right tool for your workload.

Container Orchestration

Container orchestration automates the deployment, scaling and management of containerized applications. Kubernetes leads this space, supporting features such as auto‑scaling, service discovery, rolling updates and fault tolerance. Others include Docker Swarm (simpler but less flexible) and Apache Mesos (used for big data workloads). Clarifai’s compute orchestration integrates with Kubernetes but offers a unified control plane to manage AI workloads across multiple clusters and regions. The platform automatically provisions GPU or TPU resources, handles scaling, and optimizes compute usage.

Workflow or Data Orchestration

Workflow orchestration coordinates tasks across data pipelines, ETL/ELT processes and batch jobs. Tools like Apache Airflow, Dagster, Prefect and Argo Workflows allow you to define Directed Acyclic Graphs (DAGs) that specify task order, dependencies, scheduling and retries. These tools are crucial for data teams running complex pipelines. Clarifai’s orchestration platform enables deploying AI pipelines that include data ingestion, model inference and result post‑processing; you can run them on Clarifai’s shared compute, your VPC or on‑premises servers.

Microservices Orchestration

Microservices orchestration focuses on coordinating multiple services to deliver business processes. Service orchestrators or workflow engines manage API calls, handle retries and enforce business logic. Spring Cloud Data Flow and Camunda are examples, and serverless orchestrators like AWS Step Functions or Azure Durable Functions perform similar roles for event‑driven functions. Clarifai’s platform orchestrates AI microservices (e.g., image recognition, text analysis, custom models) to create complex AI pipelines.

Cloud & Infrastructure Orchestration

Infrastructure orchestration automates the provisioning, scaling and configuration of compute, storage and network resources. Tools like Terraform, AWS CloudFormation and Pulumi allow teams to define infrastructure as code (IaC), manage state and deploy across providers. Clarifai’s compute orchestration simplifies infrastructure management by offering a single control plane to run models on cloud, VPC or on‑premises, with auto‑scaling and cost optimisation.

Business Process Orchestration

Beyond IT, orchestration can coordinate enterprise workflows such as order fulfillment, supply chain management and HR processes. Business Process Management (BPM) platforms and BPMN modeling tools allow analysts to design workflows that cross departmental boundaries. They integrate with systems like ERP and CRM to automate tasks and approvals.

Edge & IoT Orchestration (Emerging)

With the rise of edge computing, orchestrating workloads across thousands of IoT devices becomes critical. Edge orchestration ensures that models run near the data source for low latency while central control manages updates and resource distribution. Research from MDPI highlights emerging frameworks for edge orchestration that use machine learning to predict workloads and schedule tasks. Clarifai’s compute orchestration supports deploying models to edge devices through Local Runners, which allow models to run locally while still being accessible via the Clarifai API.

Expert Insights & Data Points

  • IDC predicts that by 2025, 75 % of enterprise data will be generated at the edge, requiring edge orchestration solutions.
  • Clarifai’s Local Runners enable running models on workstations or on‑premises servers and exposing them through Clarifai’s API; this provides secure, low‑latency inference while using a unified management interface.
  • Step Functions and Durable Functions simplify orchestrating serverless microservices. They handle retries, state machines and parallel execution, making them ideal for event‑driven architecture.

Types of orchestration


Leading Orchestration Tools & Platforms: Comparisons and Lists

Selecting the right orchestration tool depends on your workload, team skills and business goals. This section compares popular options across categories and highlights Clarifai’s unique strengths.

Container Orchestrators

Feature

Kubernetes

Docker Swarm

Apache Mesos

Clarifai Compute Orchestration

Scalability & Ecosystem

Industry standard with a vast ecosystem; runs microservices at scale.

Simpler setup but limited features.

Designed for large clusters; used by big data frameworks.

Built on Kubernetes but provides unified control plane and AI‑optimized scaling.

Ease of Use

Steep learning curve; extensive configuration.

Easier to start; fewer features.

Complex; typically used in research environments.

Abstraction layer hides Kubernetes complexity; automatically optimizes GPU/TPU usage.

Managed Services

EKS (AWS), GKE (Google), AKS (Azure).

Docker Swarm is self‑managed.

Mesos requires self‑hosting.

Clarifai offers shared and dedicated compute, or connects to your own clusters.

Use Cases

General microservices, AI pipelines, hybrid cloud.

Small teams wanting simple container management.

Large‑scale data processing (Hadoop, Spark).

AI/ML workloads, inference at scale, hybrid deployments, cost optimisation.

Note: Clarifai’s platform is not a direct replacement for Kubernetes; it builds on top of it, focusing specifically on orchestrating AI models and inference pipelines. It provides a single control plane for managing compute across environments and adds features like GPU fractioning, batching, autoscaling and serverless provisioning.

Workflow & Data Orchestrators

  • Apache Airflow: Popular open‑source DAG‑based orchestrator. Highly extensible and community‑supported but can be challenging to scale.
  • Prefect: Modern Python‑based orchestrator with declarative flows and a cloud dashboard. Good for data engineering tasks.
  • Dagster: A data‑centric orchestrator with strong type checking and observability features.
  • Argo Workflows: Kubernetes‑native workflow engine, ideal for cloud‑native pipelines. Supports containerized tasks and artifacts.

Clarifai: Allows orchestrating AI workflows by chaining models (e.g., image detection → object classification → text extraction). The platform manages containerization and scaling automatically, so data scientists can focus on building workflows instead of infrastructure.

Infrastructure & IaC Orchestrators

  • Terraform: Cloud‑agnostic tool for defining and provisioning infrastructure. Uses HCL language; state management can be complex.
  • Pulumi: Allows writing IaC in languages like TypeScript, Python and Go; easier integration with existing codebases.
  • Ansible: Agentless configuration management with a large module library; good for provisioning and deploying applications.
  • CloudFormation: AWS‑native orchestration; integrates tightly with AWS resources.

Clarifai: Abstracts infrastructure details by offering a serverless compute layer for AI models. You can deploy models on Clarifai’s shared cloud, dedicated clusters or your own VPC/on‑premises environment, all through a consistent API.

Serverless & Function Orchestrators

  • AWS Step Functions and Azure Durable Functions: Provide state machines for orchestrating serverless functions, handling retries, branching and parallelism.
  • Google Workflows: Similar to Step Functions but integrated with Google Cloud services.

These services are well‑suited for event‑driven microservices and IoT applications. Clarifai can integrate serverless functions within AI pipelines; for example, a Step Function could trigger Clarifai’s inference API.

Expert Insights & Key Statistics

  • DZone reports that 54 % of Kubernetes users adopt it for hybrid/multi‑cloud deployments, 49 % for new cloud‑native apps and 46 % for modernizing existing apps. This shows the versatility of container orchestration.
  • Survey results reveal that 75 % of developers use Kubernetes and 87 % run microservices on it. However, only 54 % of projects are mostly successful, indicating room for improvement.
  • Clarifai’s compute orchestration helps reduce compute costs by fractioning GPUs, batching requests and using spot instances; this can cut expenses by up to 90 %.
  • Fairwinds predicts that cluster consolidation, multi‑cloud strategies and tools like Karpenter will dominate orchestration by 2025.

Benefits & Use Cases of Orchestration

How Does Orchestration Deliver Value?

Scalability & Elasticity

Orchestration automatically scales services based on demand, spinning up additional instances during peak times and scaling down when idle. In container orchestrators like Kubernetes, autoscalers monitor CPU/memory and adjust the number of pods. In Clarifai’s platform, autoscaling works across clusters and regions, handling millions of inference requests per second while minimizing resource use.

Reliability & Fault Tolerance

Orchestrators provide self‑healing capabilities—if a container or service fails, the orchestrator restarts it or reroutes traffic. They manage rolling updates, handle retries and ensure overall system stability. Clarifai’s orchestration offers 99.999 % reliability, ensuring AI services stay available even during infrastructure failures.

Faster Deployment & Time to Market

CI/CD pipelines integrated with orchestration allow developers to push code frequently with confidence. Rolling updates, blue‑green deployments and canary releases ensure zero downtime. By automating deployment tasks, teams can iterate faster.

Cost Optimization & Resource Efficiency

Orchestrators allocate resources efficiently, preventing overprovisioning. Clarifai uses GPU fractioning, batching, autoscaling and spot instances to optimize costs. This means models only use GPU time when needed, significantly reducing expenses.

Multi‑Cloud & Hybrid Operations

Orchestration allows deploying workloads across multiple clouds, on‑premises data centers and edge nodes. This flexibility avoids vendor lock‑in and enables global scalability. Clarifai’s control plane can manage models across your VPC, on‑premises servers and Clarifai’s cloud.

AI/ML & Edge Use Cases

With the growing adoption of AI and IoT, orchestrating models at scale becomes critical. Clarifai’s platform lets you run models at the edge via Local Runners while maintaining central control and monitoring. This ensures low‑latency inference for applications like autonomous vehicles, retail cameras and industrial sensors.

Business Process Automation

Beyond IT, orchestration automates cross‑departmental workflows. For example, an order processing pipeline might orchestrate inventory checks, payment processing and shipping notifications, integrating with ERP and CRM systems.

Expert Insights & Data Points

  • Survey data shows that the microservices orchestration market is projected to reach USD 13.2 billion by 2034 with a 21.2 % CAGR.
  • Dynatrace reports that 63 % of organizations deploy Kubernetes for infrastructure workloads.
  • Industry opinion: Orchestration doesn’t just save money—it enhances innovation by freeing engineers from operational toil. This shift empowers teams to focus on building value.

Benefits of orchestration


Challenges, Risks & When Not to Use Orchestration

Where Does Orchestration Fall Short?

Complexity & Learning Curve

While orchestration simplifies operations, platforms like Kubernetes come with a steep learning curve. Managing clusters, writing YAML manifests and configuring RBAC can be overwhelming for small teams. Developers report that Kubernetes setup and management are resource‑intensive.

Security Risks & Misconfiguration

Misconfigured orchestration can open security holes. Without proper RBAC, network policies and vulnerability scanning, clusters become susceptible to attacks. Survey data reveals that 13 % of developers think orchestration worsens security. Tools like Clarifai include best‑practice security defaults and allow deployment into your own VPC or on‑premises environment without exposing ports.

Cost Overrun & Resource Sprawl

If not monitored, orchestration can lead to wasted resources. Idle pods, over‑provisioned nodes and persistent volumes drive up cloud bills. According to Fairwinds research, 25 % of developers find cost optimization challenging. Clarifai mitigates this by automatically adjusting compute to workload demand.

Latency & Performance Overhead

Adding orchestration layers can introduce latency. Tools need to manage scheduling and context switching. For latency‑sensitive edge applications, over‑orchestration might not be ideal.

Over‑Engineering for Small Projects

For simple monolithic applications, orchestration may be overkill. Microservices and orchestration bring many benefits, but they also introduce complexity. Reports show that not all microservice projects succeed, with only 54 % mostly successful. Evaluate whether your project truly benefits from microservices or if a simpler architecture would suffice.

Vendor Lock‑In

Choosing a proprietary orchestrator can lock you into a single provider. Look for tools supporting open standards. Clarifai addresses this by allowing customers to connect their own compute resources and avoid cloud vendor lock‑in.

Expert Insights & Cautionary Tales

  • Fairwinds survey reveals that the top challenges developers face with Kubernetes include high complexity, cost optimization and security.
  • O’Reilly’s microservices study reports that while many companies adopt microservices, only half find substantial success, underscoring the need for planning and expertise.
  • Advice: Start small. Use managed services or platforms like Clarifai to minimize complexity. Optimize gradually and avoid blindly splitting monoliths.

Best Practices & Architectural Patterns for Orchestration

How to Design Effective Orchestration Architectures

Design for Decoupling & Statelessness

Orchestration works best when services are loosely coupled and stateless. Each service should expose clear APIs and avoid storing state locally. This enables the orchestrator to scale services horizontally without coordination headaches. Use patterns like the Strangler Fig to gradually break monoliths into microservices.

Balance Orchestration & Choreography

Not every interaction needs central orchestration. Use event‑driven architecture where services can react to events independently (choreography) and apply orchestration for complex workflows requiring control. For example, use Step Functions to orchestrate a data pipeline but rely on asynchronous messaging (Kafka) for simple event flows.

Adopt CI/CD & Infrastructure as Code (IaC)

Automate everything: use CI/CD to deploy application code and IaC tools (Terraform, Pulumi) to manage infrastructure. This ensures reproducibility, easier rollbacks and fewer manual errors.

Implement Observability & Monitoring Early

Instrumentation is critical. Deploy metrics, logs and traces to understand performance. According to surveys, 65 % of organizations use Grafana, 62 % use Prometheus and 21 % use Datadog for observability. Clarifai’s platform provides monitoring and cost dashboards, allowing you to track inference usage and performance.

Automate Security & Apply Least Privilege

Enable RBAC, enforce network policies and integrate vulnerability scanning into CI/CD. Tools like OPA (Open Policy Agent) or Kyverno can enforce policies. Clarifai’s compute orchestration allows you to deploy models into your own VPC or on‑premises clusters, controlling ingress and egress ports.

Optimize Costs & Autoscaling

Set resource requests and limits appropriately, use autoscaling policies, and leverage spot instances or pre‑emptible VMs. Clarifai automatically scales compute and uses GPU fractioning and batching to minimize costs.

Document Workflows & Version Control

Use BPMN diagrams or YAML manifests to document workflows. Track changes through version control. This ensures reproducibility and collaboration.

Expert Insights & Research Highlights

  • Researchers apply long short‑term memory (LSTM) networks to predict workloads and inform autoscaling decisions in microservices.
  • Generative AI and large language models (LLMs) are being used to suggest microservice boundaries and optimize orchestration patterns.
  • Fairwinds predicts the rise of cluster consolidation and multi‑cloud orchestration tools like Karpenter.
  • Clarifai automatically handles model containerization and packing, so you focus on building models rather than managing Dockerfiles.

Case Studies & Real‑World Examples

Success Stories of Orchestration

Netflix: Microservices at Scale

Netflix famously migrated from a monolithic architecture to over 700 microservices to support its global streaming service. Kubernetes (via Titus) orchestrates containers to handle millions of concurrent streams, performing rolling updates and autoscaling effortlessly. This transformation enabled Netflix to scale globally, experiment quickly and deliver a high‑quality user experience. While Netflix built its own orchestration, many companies can replicate similar benefits by adopting tools like Kubernetes or Clarifai’s compute orchestration for AI workloads.

Uber: Rapid Feature Integration

Uber transitioned to microservices to reduce feature integration time from three days to three hours. They reorganized 2,200 services into 70 domains, creating a domain‑driven architecture that improved operational efficiency. Orchestration played a key role in coordinating these services and ensuring reliability under heavy load.

Banking & Finance

Financial institutions deploy microservices for transaction processing and risk analysis. Orchestration ensures compliance and auditability. AI models for fraud detection run in orchestrated pipelines, requiring high reliability and low latency.

Retail & E‑Commerce

E‑commerce platforms use orchestration to manage inventory, payments, recommendations and delivery logistics. AI models for image search, product tagging and customer personalization run through orchestrated workflows. Clarifai’s platform can orchestrate these models across cloud and on‑premises, optimizing cost and latency.

Cautionary Tales

  • A startup attempted to adopt microservices too early. The overhead of managing Kubernetes and service communication slowed development, leading to missed deadlines. Eventually, they returned to a monolithic service until their team matured.
  • A research organization ran a data pipeline with numerous dependencies but lacked orchestration. When one task failed, the entire pipeline broke. After adopting a workflow orchestrator (Airflow), they gained visibility into failures and improved reliability.

Expert Insights & Lessons Learned

  • Enterprises need to evaluate readiness before diving into microservices. If team size is small and the domain is stable, a monolith may suffice.
  • Case studies show that success hinges on careful planning, adoption of observability and robust deployment strategies. Merely adopting microservices without culture change leads to failure.

Emerging Trends & Future of Orchestration (2025+ Outlook)

What Innovations Are Shaping Orchestration’s Future?

AI‑Driven & Predictive Orchestration

Machine learning techniques like LSTM and Bi‑LSTM can analyze metrics and predict workloads, enabling orchestrators to scale ahead of demand. Tools such as Karpenter (AWS) and Cluster Autoscaler use predictive algorithms to manage node pools. Clarifai leverages AI to optimize inference workloads, batching requests and scaling clusters efficiently.

Edge & IoT Orchestration

As IoT devices proliferate, orchestrating workloads at the edge becomes crucial. 5G and AI chips enable real‑time processing on devices. Orchestrators must manage remote updates, handle intermittent connectivity and ensure security. Local Runners from Clarifai demonstrate how to run models at the edge while maintaining centralized control.

Multi‑Cloud & Hybrid Orchestration

Organizations increasingly spread workloads across multiple clouds to avoid vendor lock‑in and increase resilience. Tools like Crossplane and Rafay manage multi‑cluster deployments. Clarifai’s orchestration supports multi‑cloud by enabling models to run on Clarifai’s cloud, dedicated clusters or customer VPCs.

Serverless & Function Orchestration

Serverless architectures reduce operational overhead and cost. Future orchestrators will blend container and function orchestration, enabling developers to choose the best compute paradigm for each task.

Generative AI & LLM‑Assisted Design

Generative AI can analyze code and traffic patterns to suggest microservice boundaries, security policies and resource allocation. Imagine an orchestrator that recommends splitting a service into two based on usage or suggests adding a circuit breaker pattern. Clarifai’s AI expertise positions it well to integrate such features into its platform.

Observability & FinOps Evolution

Observability tools will use AI to detect anomalies, foresee capacity bottlenecks and recommend cost savings. FinOps practices will become integral, with orchestrators providing cost dashboards and optimization hints. Clarifai’s cost monitoring helps users track compute spending and efficiency.

Security & Compliance

With increasing threats, zero‑trust architectures, policy‑as‑code and supply chain security will be standard. Orchestrators will integrate scanning and policy engines into the workflow.

Expert Insights & Research Trends

  • Market analysts forecast significant growth for AI‑driven orchestration and edge computing solutions.
  • Fairwinds notes that cluster consolidation and multi‑cloud strategies will drive orchestration adoption.
  • MDPI review highlights research into AI methods for optimizing microservices design and orchestration.

Future of orchestration


Getting Started with Orchestration—Skills, Steps & Resources

What Skills Are Required?

  • Fundamental knowledge of distributed systems: Understand concurrency, networking, service discovery and fault tolerance.
  • Containerization basics: Learn Docker and how to build container images.
  • Programming languages & APIs: Proficiency in languages like Python, Go or Java; familiarity with REST APIs.
  • Infrastructure & Networking: Learn about VPCs, subnets, load balancers and DNS.
  • CI/CD & IaC: Experience with pipelines (Jenkins, GitHub Actions) and IaC tools.
  • Security concepts: Understand RBAC, TLS, secrets management and policy enforcement.

Step‑by‑Step Guide to Implementing Orchestration

  1. Set Up Docker: Install Docker and run a simple container (e.g., Nginx). Create your own container image for a small app.
  2. Deploy to Kubernetes (or Clarifai):
    • Install a local Kubernetes cluster (e.g., minikube) or use a managed service (EKS, GKE).
    • Write a deployment manifest for your container and deploy it. Observe how pods scale and restart.
    • Alternatively, sign up for Clarifai’s platform, upload a model, and run it on shared compute. Clarifai handles containerization and scaling for you.
  3. Define a Workflow: Use Airflow or Dagster to build a simple DAG (e.g., ETL pipeline). Configure dependencies and schedules.
  4. Add Observability: Integrate Prometheus and Grafana or use Clarifai’s built‑in monitoring to track metrics.
  5. Secure & Optimize: Apply RBAC, secrets management and resource limits. Experiment with autoscaling parameters.
  6. Scale to Production: Evaluate multi‑cloud deployment, high availability and backup strategies. Consider using Clarifai for AI workloads to reduce operational burden and access features like GPU fractioning.

Tips for Small Teams

  • Use managed services: For container orchestration, choose a managed Kubernetes (GKE, EKS, AKS) or a specialized AI platform like Clarifai. This reduces operational overhead.
  • Start simple: Begin with a monolith and gradually break off services. Introduce orchestration only where needed.
  • Invest in training: Encourage team members to take Kubernetes and cloud certifications (CKA, CKAD). Clarifai offers documentation and tutorials tailored to AI deployment.
  • Join communities: Engage with open‑source communities (CNCF, Kubernetes Slack) and attend webinars to stay updated.

Clarifai Product Integration – Compute Orchestration & Local Runners

Clarifai offers a compute orchestration platform designed specifically for AI/ML workloads. Here’s how it integrates naturally into your orchestration journey:

  • Unified Control Plane: Manage your AI compute, costs and performance through a single portal. This control plane abstracts underlying Kubernetes complexity and lets you run models on shared or dedicated hardware.
  • Flexible Deployment Options: Deploy models on Clarifai’s cloud, your VPC, or on‑premises clusters. Options include shared SaaS, dedicated SaaS, self‑managed VPC, on‑premises, multi‑site, and full platform deployment.
  • Cost Optimization Features: Clarifai leverages GPU fractioning, batching, autoscaling, and spot instances to reduce compute costs.
  • Local Runners: Run models locally on workstations or servers and expose them via Clarifai’s API. This allows low‑latency inference without sending data to the cloud.
  • Model Management & Packaging: Clarifai handles containerization, model packing and dependency management, so you can focus on building models.
  • Monitoring & Analytics: The platform provides dashboards to monitor inference requests, compute usage and costs, ensuring transparency.
  • Enterprise-Grade Security: Deploy models into your own VPC or on‑premises clusters without exposing ports; Clarifai adheres to security best practices.

By incorporating Clarifai into your orchestration strategy, you gain the benefits of Kubernetes and other orchestrators while leveraging specialized AI optimization and cost control.

Clarifai Compute Orchestration


Frequently Asked Questions

Q1: What is the difference between orchestration and automation?
A: Automation executes repetitive tasks automatically (e.g., backing up a database), whereas orchestration coordinates multiple automated tasks, making decisions based on dependencies and system state. Orchestration involves scheduling, scaling, error handling and complex workflows.

Q2: Do I always need orchestration for microservices?
A: Not necessarily. Small microservice systems can use event‑driven communication without central orchestration. As complexity grows—hundreds of services, multi‑cloud deployments, compliance requirements—an orchestrator becomes essential for reliability and visibility.

Q3: How does Clarifai’s orchestration differ from Kubernetes?
A: Clarifai builds on Kubernetes to provide a unified control plane for AI workloads. It hides Kubernetes complexity, automatically handles containerization and scaling, and optimizes GPU/TPU usage. It also offers specialized features like Local Runners and AI cost dashboards.

Q4: Can I use Clarifai’s local runners without internet access?
A: Yes. Local Runners let you run models on local machines or private clusters and expose them via Clarifai’s API. They operate offline and sync results when connectivity is restored.

Q5: Which orchestrator should I choose for data pipelines?
A: For data pipelines, consider Airflow, Dagster, Argo Workflows or Prefect. If your pipelines involve AI/ML models, Clarifai can orchestrate model inference alongside data processing, providing cost optimization and multi‑cloud deployment.

Q6: What are the upcoming trends in orchestration?
A: Expect AI‑driven scaling, edge & IoT orchestration, multi‑cloud strategies, serverless function orchestration, generative AI assisting design, FinOps integration, and enhanced security.


Conclusion: Orchestrating the Future

Orchestration is more than just a buzzword—it’s the backbone of modern computing, enabling organizations to deliver reliable, scalable and cost‑effective services. By automating coordination across containers, microservices, workflows and infrastructure, orchestration unlocks agility and innovation. However, it also demands careful planning, security and observability. Platforms like Clarifai’s compute orchestration combine best‑in‑class orchestration with AI‑specific optimizations, making it easier for businesses to deploy and run AI workloads anywhere. As the future brings AI‑driven orchestration, edge computing and generative design, embracing orchestration today ensures your systems are ready for tomorrow’s challenges.


How OpenAI and Microsoft’s New Pact Unlocks the Path to AGI


OpenAI is one step closer to a radical transformation. This week, the company signed a “memorandum of understanding” with its biggest backer Microsoft, clearing a major hurdle in the AI lab’s plan to become a for-profit company. Continue reading “How OpenAI and Microsoft’s New Pact Unlocks the Path to AGI”

ML Lifecycle Management Guide: Best Practices & Tools


Machine‑learning models are living organisms—they grow, adapt, and eventually degrade. Managing their lifecycle is the difference between a proof‑of‑concept and a sustainable AI product. This guide shows you how to plan, build, deploy, monitor, and govern models while tapping into Clarifai’s platform for orchestration, local execution, and generative AI.

Quick Digest—What Does This Guide Cover?

  • Definition & Importance: Understand what ML lifecycle management means and why it matters.
  • Planning & Data: Learn how to define business problems and collect and prepare data.
  • Development & Deployment: See how to train, evaluate and deploy models.
  • Monitoring & Governance: Discover strategies for monitoring, drift detection and compliance.
  • Advanced Topics: Dive into LLMOps, edge deployments and emerging trends.
  • Real‑World Stories: Explore case studies highlighting successes and lessons.

What Is ML Lifecycle Management?

Quick Summary: What does the ML lifecycle entail?

  • ML lifecycle management covers the complete journey of a model, from problem framing and data engineering to deployment, monitoring and decommissioning. It treats data, models and code as co‑evolving artifacts and ensures they remain reliable, compliant and valuable over time.

Understanding the Full Lifecycle

Every machine‑learning (ML) project travels through several phases that often overlap and iterate. The lifecycle begins with clearly defining the problem, transitions into collecting and preparing data, moves on to model selection and training, and culminates in deploying models into production environments. However, the journey doesn’t end there—continuous monitoring, retraining and governance are critical to ensuring the model continues to deliver value.

A well‑managed lifecycle provides many benefits:

  • Predictable performance: Structured processes reduce ad‑hoc experiments and inconsistent results.
  • Reduced technical debt: Documentation and version control prevent models from becoming black boxes.
  • Regulatory compliance: Governance mechanisms ensure that the model’s decisions are explainable and auditable.
  • Operational efficiency: Automation and orchestration cut down deployment cycles and maintenance costs.

Expert Insights

  • Holistic view: Experts emphasize that lifecycle management integrates data pipelines, model engineering and software integration, treating them as inseparable pieces of a product.
  • Agile iterations: Leaders recommend iterative cycles – small experiments, quick feedback and regular adjustments.
  • Compliance by design: Compliance isn’t an afterthought; incorporate ethical and legal considerations from the planning stage.

How Do You Plan and Define Your ML Project?

Quick Summary: Why is planning critical for ML success?

  • Effective ML projects start with a clear problem definition, detailed objectives and agreed‑upon success metrics. Without alignment on business goals, models may solve the wrong problem or produce outputs that aren’t actionable.

Laying a Strong Foundation

Before you touch code or data, ask why the model is needed. Collaboration with stakeholders is vital here:

  1. Identify stakeholders and their objectives. Understand who will use the model and how its outputs will influence decisions.
  2. Define success criteria. Set measurable key performance indicators (KPIs) such as accuracy, recall, ROI or customer satisfaction.
  3. Outline constraints and risks. Consider ethical boundaries, regulatory requirements and resource limitations.
  4. Translate business goals into ML tasks. Frame the problem in ML terms (classification, regression, recommendation) while documenting assumptions.

Creative Example – Predictive Maintenance in Manufacturing

Imagine a factory wants to reduce downtime by predicting machine failures. Stakeholders (plant managers, maintenance teams, data scientists) meet to define the goal: prevent unexpected breakdowns. They agree on success metrics like “reduce downtime by 30 %” and set constraints such as “no additional sensors”. This clear planning ensures the subsequent data collection and modeling efforts are aligned.

Expert Insights

  • Stakeholder interviews: Involve not just executives but also frontline operators; they often offer valuable context.
  • Document assumptions: Record what you think is true about the problem (e.g., data availability, label quality) so you can revisit later.
  • Alignment prevents scope creep: A defined scope keeps the team focused and prevents unnecessary features.

How to Engineer and Prepare Data for ML?

Quick Summary: What are the core steps in data engineering?

  • Data engineering includes ingestion, exploration, validation, cleaning, labeling and splitting. These steps ensure that raw data becomes a reliable, structured dataset ready for modeling.

Data Ingestion & Integration

The first task is collecting data from diverse sources – databases, APIs, logs, sensors or third‑party feeds. Use frameworks like Spark or HDFS for large datasets, and document where each piece of data comes from. Consider generating synthetic data if certain classes are rare.

Exploration & Validation

Once data is ingested, profile it to understand distributions and detect anomalies. Compute statistics like mean, variance and cardinality; build histograms and correlation matrices. Validate data with rules: check for missing values, out‑of‑range numbers or duplicate entries.

Data Cleaning & Wrangling

Cleaning data involves fixing errors, imputing missing values and standardizing formats. Techniques range from simple (mean imputation) to advanced (time‑aware imputation for sequences). Standardize categorical values (e.g., unify “USA,” “United States,” “U.S.”) to avoid fragmentation.

Labeling & Splitting

Label each data point with the correct outcome, a task often requiring human expertise. Use annotation tools or Clarifai’s AI Lake to streamline labeling. After labeling, split the dataset into training, validation and test sets. Use stratified sampling to preserve class distributions.

Expert Insights

  • Data quality > Model complexity: A simple algorithm on clean data often outperforms a complex algorithm on messy data.
  • Iterative approach: Data engineering is rarely one‑and‑done. Plan for multiple passes as you discover new issues.
  • Documentation matters: Track every transformation – regulators may require lineage logs for auditing.

Data Pipeline for Machine Learning


How to Perform EDA and Feature Engineering?

Quick Summary: Why do you need EDA and feature engineering?

  • Exploratory data analysis (EDA) uncovers patterns and anomalies that guide model design, while feature engineering transforms raw data into meaningful inputs.

Exploratory Data Analysis (EDA)

Start by visualizing distributions using histograms, scatter plots and box plots. Look for skewness, outliers and relationships between variables. Uncover patterns like seasonality or clusters; identify potential data leakage or mislabeled records. Generate hypotheses: for example, “Does weather affect customer demand?”

Feature Engineering & Selection

Feature engineering is the art of creating new variables that capture underlying signals. Common techniques include:

  • Combining variables (e.g., ratio of clicks to impressions).
  • Transforming variables (log, square root, exponential).
  • Encoding categorical values (one‑hot encoding, target encoding).
  • Aggregating over time (rolling averages, time since last purchase).

After generating features, select the most informative ones using statistical tests, tree‑based feature importance or L1 regularization.

Creative Example – Feature Engineering in Finance

Consider a credit‑scoring model. Beyond income and credit history, engineers create a “credit utilization ratio”, capturing the percentage of credit in use relative to the limit. They also compute “time since last delinquent payment” and “number of inquiries in the past six months.” These engineered features often have stronger predictive power than raw variables.

Expert Insights

  • Domain expertise pays dividends: Collaborate with subject‑matter experts to craft features that capture domain nuances.
  • Less is more: A smaller set of high‑quality features often outperforms a large but noisy set.
  • Beware of leakage: Don’t use future information (e.g., last payment outcome) when training your model.

How to Develop, Experiment and Train ML Models?

Quick Summary: What are the key steps in model development?

  • Model development involves selecting algorithms, training them iteratively, evaluating performance and tuning hyperparameters. Packaging models into portable formats (e.g., ONNX) facilitates deployment.

Selecting Algorithms

Choose models that fit your data type and problem:

  • Structured data: Logistic regression, decision trees, gradient boosting.
  • Sequential data: Recurrent neural networks, transformers.
  • Images and video: Convolutional neural networks (CNNs).

Start with simple models to establish baselines, then progress to more complex architectures if needed.

Training & Hyperparameter Tuning

Training involves feeding labeled data into your model, optimizing a loss function via algorithms like gradient descent. Use cross‑validation to avoid overfitting and evaluate different hyperparameter settings. Tools like Optuna or hyperopt automate search across hyperparameters.

Evaluation & Tuning

Evaluate models using appropriate metrics:

  • Classification: Accuracy, precision, recall, F1 score, AUC.
  • Regression: Mean Absolute Error (MAE), Root Mean Squared Error (RMSE).

Tune hyperparameters iteratively – adjust learning rates, regularization parameters or architecture depth until performance plateaus.

Packaging for Deployment

Once trained, export your model to a standardized format like ONNX or PMML. Version the model and its metadata (training data, hyperparameters) to ensure reproducibility.

Expert Insights

  • No free lunch: Complex models can overfit; always benchmark against simpler baselines.
  • Fairness & bias: Evaluate your model across demographic groups and implement mitigation if needed.
  • Experiment tracking: Use tools like Clarifai’s built‑in tracking or MLflow to log hyperparameters, metrics and artifacts.

How to Deploy and Serve Your Model?

Quick Summary: What are the best practices for deployment?

  • Deployment transforms a trained model into an operational service. Choose the right serving pattern (batch, real‑time or streaming) and leverage containerization and orchestration tools to ensure scalability and reliability.

Deployment Strategies

  • Batch inference: Suitable for offline analytics; run predictions on a schedule and write results to storage.
  • Real‑time inference: Deploy models as microservices accessible via REST/gRPC APIs to provide immediate predictions.
  • Streaming inference: Process continuous data streams (e.g., Kafka topics) and update models frequently.

Infrastructure & Orchestration

Package your model in a container (Docker) and deploy it on a platform like Kubernetes. Implement autoscaling to handle varying loads and ensure resilience. For serverless deployments, consider cold‑start latency.

Testing & Rollbacks

Before going live, perform integration tests to ensure the model works within the larger application. Use blue/green deployment or canary release strategies to roll out updates incrementally and roll back if issues arise.

Expert Insights

  • Model performance monitoring: Even after deployment, performance may vary due to changing data; see the monitoring section next.
  • Infrastructure as code: Use Terraform or CloudFormation to define your deployment environment, ensuring consistency across stages.
  • Clarifai’s edge: Deploy models using Clarifai’s compute orchestration platform to manage resources across cloud, on‑prem and edge.

How to Monitor Models and Manage Drift?

Quick Summary: Why is monitoring essential?

  • Models degrade over time due to data drift, concept drift and changes in the environment. Continuous monitoring tracks performance, detects drift and triggers retraining.

Monitoring Metrics

  • Functional performance: Track metrics like accuracy, precision, recall or MAE on real‑world data.
  • Operational performance: Monitor latency, throughput and resource utilization.
  • Drift detection: Measure differences between training data distribution and incoming data. Tools like Evidently AI and NannyML excel at detecting general drift and pinpointing drift timing respectively.

Alerting & Retraining

Set thresholds for metrics; trigger alerts and remedial actions when thresholds are breached. Automate retraining pipelines so the model adapts to new data patterns.

Creative Example – E‑commerce Demand Forecasting

A retailer’s demand‑forecasting model suffers a drop in accuracy after a major marketing campaign. Monitoring picks up the data drift and triggers retraining with post‑campaign data. This timely retraining prevents stockouts and overstock issues, saving millions.

Expert Insights

  • Amazon’s lesson: During the COVID‑19 pandemic, Amazon’s supply‑chain models failed due to unexpected demand spikes – a cautionary tale on the importance of drift detection.
  • Comprehensive monitoring: Track both input distributions and prediction outputs for a complete picture.
  • Clarifai’s dashboard: Clarifai’s Model Performance Dashboard visualizes drift, performance degradation and fairness metrics.

Monitoring & Drift Detection in ML


Why Do Model Governance and Risk Management Matter?

Quick Summary: What is model governance?

  • Model governance ensures that models are transparent, accountable and compliant. It encompasses processes that control access, document lineage and align models with legal requirements.

Governance & Compliance

Model governance integrates with MLOps by covering six phases: business understanding, data engineering, model engineering, quality assurance, deployment and monitoring. It enforces access control, documentation and auditing to meet regulatory requirements.

Regulatory Frameworks

  • EU AI Act: Classifies AI systems into risk categories. High‑risk systems must satisfy strict documentation, transparency and human oversight requirements.
  • NIST AI RMF: Suggests functions (Govern, Map, Measure, Manage) that organizations should perform throughout the AI lifecycle.
  • ISO/IEC 42001: An emerging standard that will specify AI management system requirements.

Implementing Governance

Establish roles and responsibilities, separate model builders from validators, and create an AI board involving legal, technical and ethics experts. Document training data sources, feature selection, model assumptions and evaluation results.

Expert Insights

  • Comprehensive records: Keeping detailed records of model decisions and interactions helps in investigations and audits.
  • Ethical AI: Governance is not just about compliance – it ensures that AI systems align with organizational values and social expectations.
  • Clarifai’s tools: Clarifai’s Control Center offers granular permission controls and SOC2/ISO 27001 compliance out of the box, easing governance burdens.
    Responsible AI & Governance Frameworks


How to Ensure Reproducibility and Track Experiments?

Quick Summary: Why is reproducibility important?

  • Reproducibility ensures that models can be consistently rebuilt and audited. Experiment tracking centralizes metrics and artifacts for comparison and collaboration.

Version Control & Data Lineage

Use Git for code and DVC (Data Version Control) or Git‑LFS for large datasets. Log random seeds, environment variables and library versions to avoid non‑deterministic results. Keep transformation scripts under version control.

Experiment Tracking

Tools like MLflow, Neptune.ai or Clarifai’s built‑in tracker enable you to log hyperparameters, metrics, artifacts and environment details, and tag experiments for easy retrieval. Use dashboards to compare runs and decide which models to promote.

Model Registry

A model registry is a centralized store for models and their metadata. It tracks versions, performance, stage (staging, production), and references to data and code. Unlike object storage, a registry provides context and supports rollbacks.

Expert Insights

  • Reproducibility is non‑negotiable for regulated industries; auditors may request to reproduce a prediction made years ago.
  • Tags and naming conventions: Use consistent naming patterns for experiments to avoid confusion.
  • Clarifai’s advantage: Clarifai’s platform integrates experiment tracking and model registry, so models move seamlessly from development to deployment.

How to Automate Your ML Lifecycle?

Quick Summary: What role does automation play in MLOps?

  • Automation streamlines repetitive tasks, accelerates releases and reduces human error. CI/CD pipelines, continuous training and infrastructure‑as‑code are key mechanisms.

CI/CD for Machine Learning

Adopt continuous integration and delivery pipelines:

  1. Continuous integration: Automate code tests, data validation and static analysis on every commit.
  2. Continuous delivery: Automate deployment of models to staging environments.
  3. Continuous training: Trigger training jobs automatically when new data arrives or drift is detected.

Infrastructure‑as‑Code & Orchestration

Define infrastructure (compute, networking, storage) using Terraform or CloudFormation to ensure consistent and repeatable environments. Use Kubernetes to orchestrate containers and implement autoscaling.

Clarifai Integration

Clarifai’s compute orchestration simplifies automation: you can deploy your models anywhere (cloud, on‑prem or edge) and scale them automatically. Local runners let you test or run models offline using the same API, making CI/CD pipelines more robust.

Expert Insights

  • Automate tests: ML pipelines need tests beyond unit tests – include checks for data schema and distribution.
  • Small increments: Deploying small changes more frequently reduces risk.
  • Self‑healing pipelines: Build pipelines that react to drift detection by automatically retraining and redeploying.

How to Orchestrate Compute Resources Effectively?

Quick Summary: What is compute orchestration and why is it important?

  • Compute orchestration manages the allocation and scaling of hardware resources (CPU, GPU, memory) across different environments (cloud, on‑prem, edge). It optimizes cost, performance and reliability.

Hybrid Deployment Options

Organizations can choose from:

  • Shared cloud: Pay‑as‑you‑go compute resources managed by providers.
  • Dedicated cloud: Dedicated environments for predictable performance.
  • On‑premise: For data sovereignty or latency requirements.
  • Edge: For real‑time inference near data sources.

Clarifai’s Hybrid Platform

Clarifai’s platform offers a unified control plane where you can orchestrate workloads across shared compute, dedicated environments and your own VPC or edge hardware. Autoscaling and cost optimization features help right‑size compute and allocate resources dynamically.

Cost Optimization Strategies

  • Right‑size instances: Choose instance types matching workload demands.
  • Spot instances: Reduce costs by using spare capacity at discounted rates.
  • Scheduling: Run compute‑intensive tasks during off‑peak hours to save on electricity and cloud fees.

Expert Insights

  • Resource monitoring: Continuously monitor resource utilization to avoid idle capacity.
  • MIG (Multi‑Instance GPU): Partition GPUs to run multiple models concurrently, improving utilization.
  • Clarifai’s local runners keep compute local to reduce latency and cloud costs.

Clarifai’s Compute Orchestration for ML Lifecycle


How to Deploy Models at the Edge and On‑Device?

Quick Summary: What are edge deployments and when are they useful?

  • Edge deployments run models on devices close to where data is generated, reducing latency and preserving privacy. They’re ideal for IoT, mobile and remote environments.

Why Edge?

Edge inference avoids round‑trip latency to the cloud and ensures models continue to operate even if connectivity is intermittent. It also keeps sensitive data local, which may be crucial for regulated industries.

Tools and Frameworks

  • TensorFlow Lite, ONNX Runtime and Core ML enable models to run on mobile phones and embedded devices.
  • Hardware acceleration: Devices like NVIDIA Jetson or smartphone NPUs provide the processing power needed for inference.
  • Resilient updates: Use over‑the‑air updates with rollback to ensure reliability.

Clarifai’s Edge Solutions

Clarifai’s local runners deliver consistent APIs across cloud and edge and can run on devices like Jetson. They allow you to test locally and deploy seamlessly with minimal code changes.

Expert Insights

  • Model size matters: Compress models via quantization or pruning to fit on resource‑constrained devices.
  • Data capture: Collect telemetry from edge devices to improve models over time.
  • Connectivity planning: Implement caching and asynchronous syncing to handle network outages.

What Is LLMOps and How to Handle Generative AI?

Quick Summary: How is LLMOps different from MLOps?

  • LLMOps applies lifecycle management to large language models (LLMs) and generative AI, addressing unique challenges like prompt management, privacy and hallucination detection.

The Rise of Generative AI

Large language models (LLMs) like GPT‑family and Claude can generate text, code and even images. Managing these models requires specialized practices:

  • Model selection: Evaluate open models and choose one that fits your domain.
  • Customisation: Fine‑tune or prompt‑engineer the model for your specific task.
  • Data privacy: Use pseudonymisation or anonymisation to protect sensitive data.
  • Retrieval‑Augmented Generation (RAG): Combine LLMs with vector databases to fetch accurate facts while keeping proprietary data off the model’s training corpus.

Prompt Management & Evaluation

  • Prompt repositories: Store and version prompts just like code.
  • Guardrails: Monitor outputs for hallucinations, toxicity or bias. Use tools like Clarifai’s generative AI evaluation service to measure and mitigate issues.

Clarifai’s Generative AI Offering

Clarifai provides pre‑trained text and image generation models with APIs for easy integration. Their platform allows you to fine‑tune prompts and evaluate generative output with built‑in guardrails.

Expert Insights

  • LLMs can be unpredictable: Always test prompts across diverse inputs.
  • Ethical considerations: LLMs can produce harmful or biased content; implement filters and oversight mechanisms.
  • LLM cost: Generative models require substantial compute. Using Clarifai’s hybrid compute orchestration helps you manage costs while leveraging the latest models.

Why Is Collaboration Essential for MLOps?

Quick Summary: How do teams collaborate in MLOps?

  • MLOps is inherently cross‑functional, requiring cooperation between data scientists, ML engineers, operations teams, product owners and domain experts. Effective collaboration hinges on communication, shared tools and mutual understanding.

Building Cross‑Functional Teams

  • Roles & Responsibilities: Define roles clearly (data engineer, ML engineer, MLOps engineer, domain expert).
  • Shared Documentation: Maintain documentation of datasets, feature definitions and model assumptions in collaborative platforms (Confluence, Notion).
  • Communication Rituals: Conduct daily stand‑ups, weekly syncs and retrospectives to align objectives.

Early Involvement of Domain Experts

Domain experts should be part of planning, feature engineering and evaluation phases to catch mistakes and add context. Encourage them to review model outputs and highlight anomalies.

Expert Insights

  • Psychological safety: Foster an environment where team members can question assumptions without fear.
  • Training: Encourage cross‑training – engineers learn domain context; domain experts gain ML literacy.
  • Clarifai’s Community: Clarifai offers community forums and support channels to help teams collaborate and get expert help.

What Do Real‑World Case Studies Teach Us?

Quick Summary: What lessons come from real deployments?

  • Real‑world case studies reveal the importance of monitoring, edge deployment and preparedness for drift. They highlight how Clarifai’s platform accelerates success.

Ride‑Sharing – Handling Weather‑Driven Drift

A ride‑sharing company monitored travel‑time predictions using Clarifai’s dashboard. When heavy rain caused unusual travel patterns, drift detection flagged the change. An automated retraining job updated the model with the new data, preventing inaccurate ETAs and maintaining user trust.

Manufacturing – Edge Monitoring of Machines

A factory deployed a computer‑vision model to detect equipment anomalies. Using Clarifai’s local runner on Jetson devices, they achieved real‑time inference without sending video to the cloud. Night‑time updates ensured the model stayed current without disrupting production.

Supply Chain – Consequences of Ignoring Drift

During COVID‑19, Amazon’s supply‑chain prediction algorithms failed due to unprecedented demand spikes for household goods, leading to bottlenecks. The lesson: incorporate extreme scenarios into risk management and monitor for unexpected drifts.

Benchmarking Drift Detection Tools

Researchers evaluated open‑source drift tools and found Evidently AI best for general drift detection and NannyML for pinpointing drift timing. Choosing the right tool depends on your use case.

Expert Insights

  • Monitoring pays off: Early detection and retraining saved the ride‑sharing and manufacturing companies from costly errors.
  • Edge vs cloud: Edge deployments cut latency but require strong update mechanisms.
  • Tool selection: Evaluate tools for functionality, scalability, and integration ease.

What Future Trends Will Shape ML Lifecycle Management?

Quick Summary: Which trends should you watch?

  • Responsible AI frameworks (NIST AI RMF, EU AI Act) and standards (ISO/IEC 42001) will shape governance, while LLMOps, federated learning, and AutoML will transform development.

Responsible AI & Regulation

The NIST AI RMF encourages organizations to govern, map, measure and manage AI risks. The EU AI Act categorizes systems by risk and will require high‑risk models to pass conformity assessments. ISO/IEC 42001 is in development to standardize AI management.

LLMOps & Generative AI

As generative models proliferate, LLMOps will become essential. Expect new tools for prompt management, fairness auditing and generative content identification.

Federated Learning & Privacy

Federated learning will enable collaborative training across multiple devices without sharing raw data, boosting privacy and complying with regulations. Differential privacy and secure aggregation will further protect sensitive information.

Low‑Code/AutoML & Citizen Data Scientists

AutoML platforms will democratize model development, enabling non‑experts to build models. However, organizations must balance automation with governance and oversight.

Research Gaps & Opportunities

A systematic mapping study highlights that few research papers tackle deployment, maintenance and quality assurance. This gap offers opportunities for innovation in MLOps tooling and methodology.

Expert Insights

  • Stay adaptable: Regulations will evolve; build flexible governance and compliance processes.
  • Invest in education: Equip your team with knowledge of ethics, law and emerging technologies.
  • Clarifai’s roadmap: Clarifai continues to integrate emerging practices (e.g., RAG, generative AI guardrails) into its platform, making it easier to adopt future trends.

Conclusion – How to Get Started and Succeed

Managing the ML lifecycle is a marathon, not a sprint. By planning carefully, preparing data meticulously, experimenting responsibly, deploying robustly, monitoring continuously and governing ethically, you set the stage for long‑term success. Clarifai’s hybrid AI platform offers tools for orchestration, local execution, model registry, generative AI and fairness auditing, making it easier to adopt best practices and accelerate time to value.

Actionable Next Steps

  1. Audit your workflow: Identify gaps in version control, data quality or monitoring.
  2. Implement data pipelines: Automate ingestion, validation and cleaning.
  3. Track experiments: Use an experiment tracker and model registry.
  4. Automate CI/CD: Build pipelines that test, train and deploy models continuously.
  5. Monitor & retrain: Set up drift detection and automated retraining triggers.
  6. Prepare for compliance: Document data sources, features and evaluation metrics; adopt frameworks like NIST AI RMF.
  7. Explore Clarifai: Leverage Clarifai’s compute orchestration, local runners and generative AI tools to simplify infrastructure and accelerate innovation.

Frequently Asked Questions

Q1: How frequently should models be retrained?
Retraining frequency depends on data drift and business requirements. Use monitoring to detect when performance drops below acceptable thresholds and trigger retraining.

Q2: What differentiates MLOps from LLMOps?
MLOps manages any machine‑learning model’s lifecycle, while LLMOps focuses on large language models, adding challenges like prompt management, privacy preservation and hallucination detection.

Q3: Are edge deployments always better?
No. Edge deployments reduce latency and improve privacy, but they require lightweight models and robust update mechanisms. Use them when latency, bandwidth or privacy demands outweigh the complexity.

Q4: How do model registries improve reproducibility?
Model registries store versions, metadata and deployment status, making it easy to roll back or compare models; object storage alone lacks this context.

Q5: What does Clarifai offer beyond open‑source tools?
Clarifai provides end‑to‑end solutions, including compute orchestration, local runners, experiment tracking, generative AI tools and fairness audits, combined with enterprise‑grade security and support