AI, Automation, and BIM-to-DWG Workflows in ARES 2027 with Anthony Frausto-Robledo


Architosh is well known for its Deep Dive reviews, offering detailed analysis of leading CAD, BIM, and 3D technologies. In its latest feature, “ARES 2027 Deep Dive: AI, Automation and BIM-to-DWG Workflows,” industry analyst Anthony Frausto-Robledo examines how Graebert is redefining DWG-based CAD through artificial intelligence, cloud connectivity, and advanced automation.

According to Frausto-Robledo, the defining story behind this release is clear: “The larger story in this release is AI.” At the center of this transformation is ARES AI Assist (A3), Graebert’s AI-powered CAD assistant, which has evolved from a traditional help tool into what he describes as “an active participant in the CAD workflow.”

A3 AI Assist Brings Artificial Intelligence into CAD Workflows

One of the most significant advancements highlighted in the review is the evolution of ARES AI Assist (A3). Rather than simply providing guidance or support documentation, A3 actively assists users throughout the design process, helping streamline CAD operations and automate repetitive tasks.

As AI continues to reshape professional software, A3 demonstrates how intelligent assistants can improve CAD productivity, simplify workflows, and help architects, engineers, and designers work more efficiently. This development positions ARES 2027 at the forefront of the growing trend toward AI-powered CAD software.

The Power of the ARES Trinity Ecosystem

Frausto-Robledo also emphasizes the strength of Graebert’s ARES Trinity strategy, which delivers a unified “One CAD” experience across desktop, web, and mobile platforms.

Unlike traditional CAD solutions that separate workflows between devices, ARES Trinity enables users to work seamlessly across:

  • Windows
  • macOS
  • Linux
  • Web browsers
  • Tablets
  • Smartphones

This cross-platform approach ensures that design teams can access projects, edit DWG files, and collaborate from virtually anywhere while remaining connected to the same workflows and project data. The result is greater flexibility, improved collaboration, and increased productivity for distributed teams.

BIM-to-DWG Automation Accelerates Documentation

The review also explores the latest enhancements to BIM-to-DWG workflows in ARES 2027. By leveraging BIM data more effectively, ARES helps automate the generation of DWG documentation, reducing the need for manual drafting and repetitive drawing production tasks.

For architecture, engineering, and construction (AEC) professionals, BIM-to-DWG automation offers several advantages:

  • Faster documentation workflows
  • Improved drawing consistency
  • Reduced manual effort
  • Better coordination between BIM models and DWG deliverables
  • Enhanced project efficiency
  • Fewer documentation errors

These improvements help bridge the gap between intelligent BIM models and the production of construction-ready documentation.

Expanding Automation and Cloud-Based CAD Capabilities

Beyond AI and BIM workflows, the Architosh Deep Dive highlights several additional innovations in ARES 2027, including:

  • Online Drawings Automation
  • Autodesk Forma integration
  • Enhanced ARES Kudo Professional capabilities
  • Cloud-based collaboration workflows
  • Cross-platform DWG accessibility

Together, these features demonstrate Graebert’s continued focus on modernizing CAD workflows while maintaining full compatibility with the DWG format that remains central to the AEC industry.

A Bold Vision for the Future of DWG CAD

Frausto-Robledo concludes that ARES 2027 showcases how an innovative CAD developer can rapidly advance the capabilities of DWG-based design software through AI, automation, and cloud technologies.

As he notes, “ARES 2027 demonstrates how a focused competitor can move quickly, differentiate boldly, and continue expanding what native DWG CAD can become.”

With AI-powered assistance, BIM-to-DWG automation, cloud collaboration, and a truly cross-platform CAD ecosystem, ARES 2027 represents a significant step forward for professionals seeking smarter, more connected design workflows.

AWS Cloud Optimization – A Structural Approach


Managing cloud infrastructure efficiently has evolved from a simple budgeting task into a complex engineering challenge. As enterprise workloads scale, traditional cleanup mechanisms, like manually shutting down idle development environments or deleting orphaned snapshots, fail to provide long-term stability. Most AWS cost optimization programs follow a predictable trajectory: an initial savings spike of 15% to 20%, an organizational celebration, and then months of flatlining returns.

The variance between an optimized environment and a wasteful one is an execution gap. According to the Flexera 2026 State of the Cloud Report, estimated cloud waste across enterprises sits at 29%, with over 85% of organizations citing cloud spend management as their primary operational hurdle. Furthermore, data from the AWS State of Cost Efficiency Report reveals a major systemic issue: while the majority of enterprises focus heavily on purchasing rate-discount commitments like Savings Plans, only 47.1% actively execute resource rightsizing.

Focusing on procurement over structural engineering leaves substantial savings entirely unrealized. To establish permanent financial efficiency, organizations must transition from temporary, surface-level cleanups to an engineering-first model. This blog post serves as the technical sequel to our previous discussion, “AWS Cost Optimization: Closing the Hidden Cloud Savings Gap,” where we identified why cosmetic fixes fall short. Below, we break down the five architectural pillars and the realistic execution sequence required to design cost-resilient AWS environments.

The Five Pillars of AWS Cloud Optimization

True cloud optimization requires balancing technical upside against actual implementation friction. As outlined conceptually in image (6).png, sustainable efficiency is achieved when core operational layers cross-pollinate directly with the pillars of the AWS Well-Architected Framework.

Pillar 1: Cost Optimization and Strategic Capacity Engineering

Financial efficiency is rooted in data-driven capacity planning rather than speculative purchasing.

  • Precision Right-Sizing via AWS Compute Optimizer: Rather than relying on basic CPU metrics, we integrate deep memory utilization analytics. AWS performance data indicates that activating granular EC2 memory metrics correlates with an 8% to 30% percentage-point gain in realized savings per recommendation, yet it remains underutilized by over 80% of eligible customers.
  • Commitment-Based Pricing Strategy: For predictable baseline workloads, we architect a dynamic mix of Reserved Instances (RIs) and Savings Plans. Enterprise environments that combine active rightsizing with commitments run roughly 60% of their instances on newer, more efficient hardware and improve their core efficiency metrics four times faster than peers relying on commitments alone.
  • Spot Instances for Fault-Tolerant Workloads: For stateless applications, data-processing pipelines, and batch jobs, utilizing spare cloud capacity via Amazon EC2 Spot Instances slashes compute costs by up to 90% compared to standard On-Demand pricing.

Pillar 2: Compute Modernization and Architectural Efficiency

Compute typically represents roughly 70% of the financial upside in an infrastructure budget, making it the most impactful lever, though it requires incremental, deliberate project execution.

  • Dynamic Auto Scaling: We build proactive target-tracking and predictive scaling policies that scale your footprint out or in based on real-time operational demand, eliminating expenditures on idle compute.
  • Serverless Execution with AWS Lambda: For event-driven microservices or highly variable workloads, shifting to serverless execution removes the overhead of maintaining underlying operating systems and ensures you pay strictly for execution time down to the millisecond.
  • AWS Graviton (ARM) Migration: Moving traditional x86 workloads to custom-designed AWS Graviton processors delivers up to 40% better price-performance. However, the real constraint here is engineering capacity rather than the math. Migrating a production workload requires allocating platform team capacity to refactor, test, and validate the testing surface area before shifting workloads to ARM-based silicon.

Pillar 3: Intelligent Storage and Lifecycle Mechanics

Storage generally accounts for 15% to 20% of the optimization upside. It often faces fewer structural obstacles because most of the work is policy-based rather than architectural.

  • Automated Tiering with S3 Intelligent-Tiering: Because data access habits evolve unpredictably, we implement S3 Intelligent-Tiering. Objects automatically transition across performance and cost-optimized access tiers based on real-time usage, introducing zero operational overhead or data retrieval fees.
  • EBS Upgrades (gp2 to gp3): We systematically modernize block storage by moving Amazon Elastic Block Store (EBS) volumes from gp2 to gp3. AWS storage benchmarks confirm that gp3 delivers an immediate 20% savings per GB-month while completely decoupling provisioned IOPS and throughput from volume size. This is a low-friction, high-return transition.
  • Automated Archive Lifecycle Policies: Cold data should never sit on expensive hot storage tiers. By implementing programmatic lifecycle rules, aging datasets are systematically offloaded to Amazon S3 Glacier Flexible or Deep Archive for ultra-low-cost, secure preservation.

Pillar 4: Network Topology and Data Transfer Engineering

Data transfer fees, NAT Gateway sprawl, and inefficient routing represent the remainder of the optimization surface area. Though often dismissed as a rounding error, network costs compound heavily in enterprise environments with high egress or cross-region replication.

  • Amazon CloudFront CDN: By caching assets globally at edge locations, we drastically reduce origin data transfer out (DTO) expenses while accelerating application delivery speeds for global users.
  • VPC Endpoints and AWS PrivateLink: To eliminate heavy NAT Gateway processing charges, we architect VPC Endpoints. This keeps internal data traffic directed to core services like Amazon S3 or DynamoDB entirely within the private AWS backbone network instead of routing it out across the public internet.
  • AWS Transit Gateway Centralization: For complex, multi-account environments, we consolidate hub-and-spoke networking topologies using Transit Gateway. This cleans up redundant routing paths, eliminates disparate gateway costs, and simplifies multi-account architecture at scale.

Pillar 5: Continuous Governance, Security, and Guardrails

An optimized environment is only as durable as the governance model tracking it. Without guardrails, infrastructure inevitably drifts back to waste within 18 months due to small, compounding anomalies, such as oversized staging environments left running over weekends.

  • AWS Trusted Advisor and AWS Config: We deploy automated monitoring tools that continuously scan cloud infrastructure to flag non-compliant resource allocations, security misconfigurations, and hidden operational cost risks.
  • IAM Least-Privilege and Service Control Policies (SCPs): True optimization requires structural constraint. By creating robust organizational guardrails via SCPs, we prevent development teams from inadvertently spinning up unapproved, high-cost instance classes or unauthorized services.
  • AWS Cost Anomaly Detection and Budgets: Rather than waiting for the end-of-month invoice to review metrics, we embed machine learning-driven anomaly monitors. These sound the alarm the moment an unusual spending pattern occurs, stopping runaway bills before they impact the bottom line.

Moving Toward a Well-Architected Infrastructure

Achieving long-term cloud efficiency is not about executing an isolated cost-cutting project. True cost resilience occurs when optimization is deeply embedded into the baseline of the AWS Well-Architected Framework.

By modernizing compute, applying intelligent policies to storage, optimizing network paths, and implementing automated security guardrails, organizations can break out of the cyclical pattern of short-term fixes. Moving beyond the low-hanging fruit requires shifting ownership away from purely financial or compliance metrics and into the engineering workflow. When cost awareness becomes an intrinsic part of how architectures are built and maintained, the cloud transitions from an unpredictable operational expense into a highly responsive, scalable engine for business growth.

Looking to turn these architectural strategies into real operational savings? BizAcuity specializes in analyzing structural cloud inefficiencies and designing scalable, high-performance environments. Get in touch with us to talk about building an infrastructure that scales with your growth.

You deserve to get in some gaming time this summer, and these travel-friendly gadgets will help with that


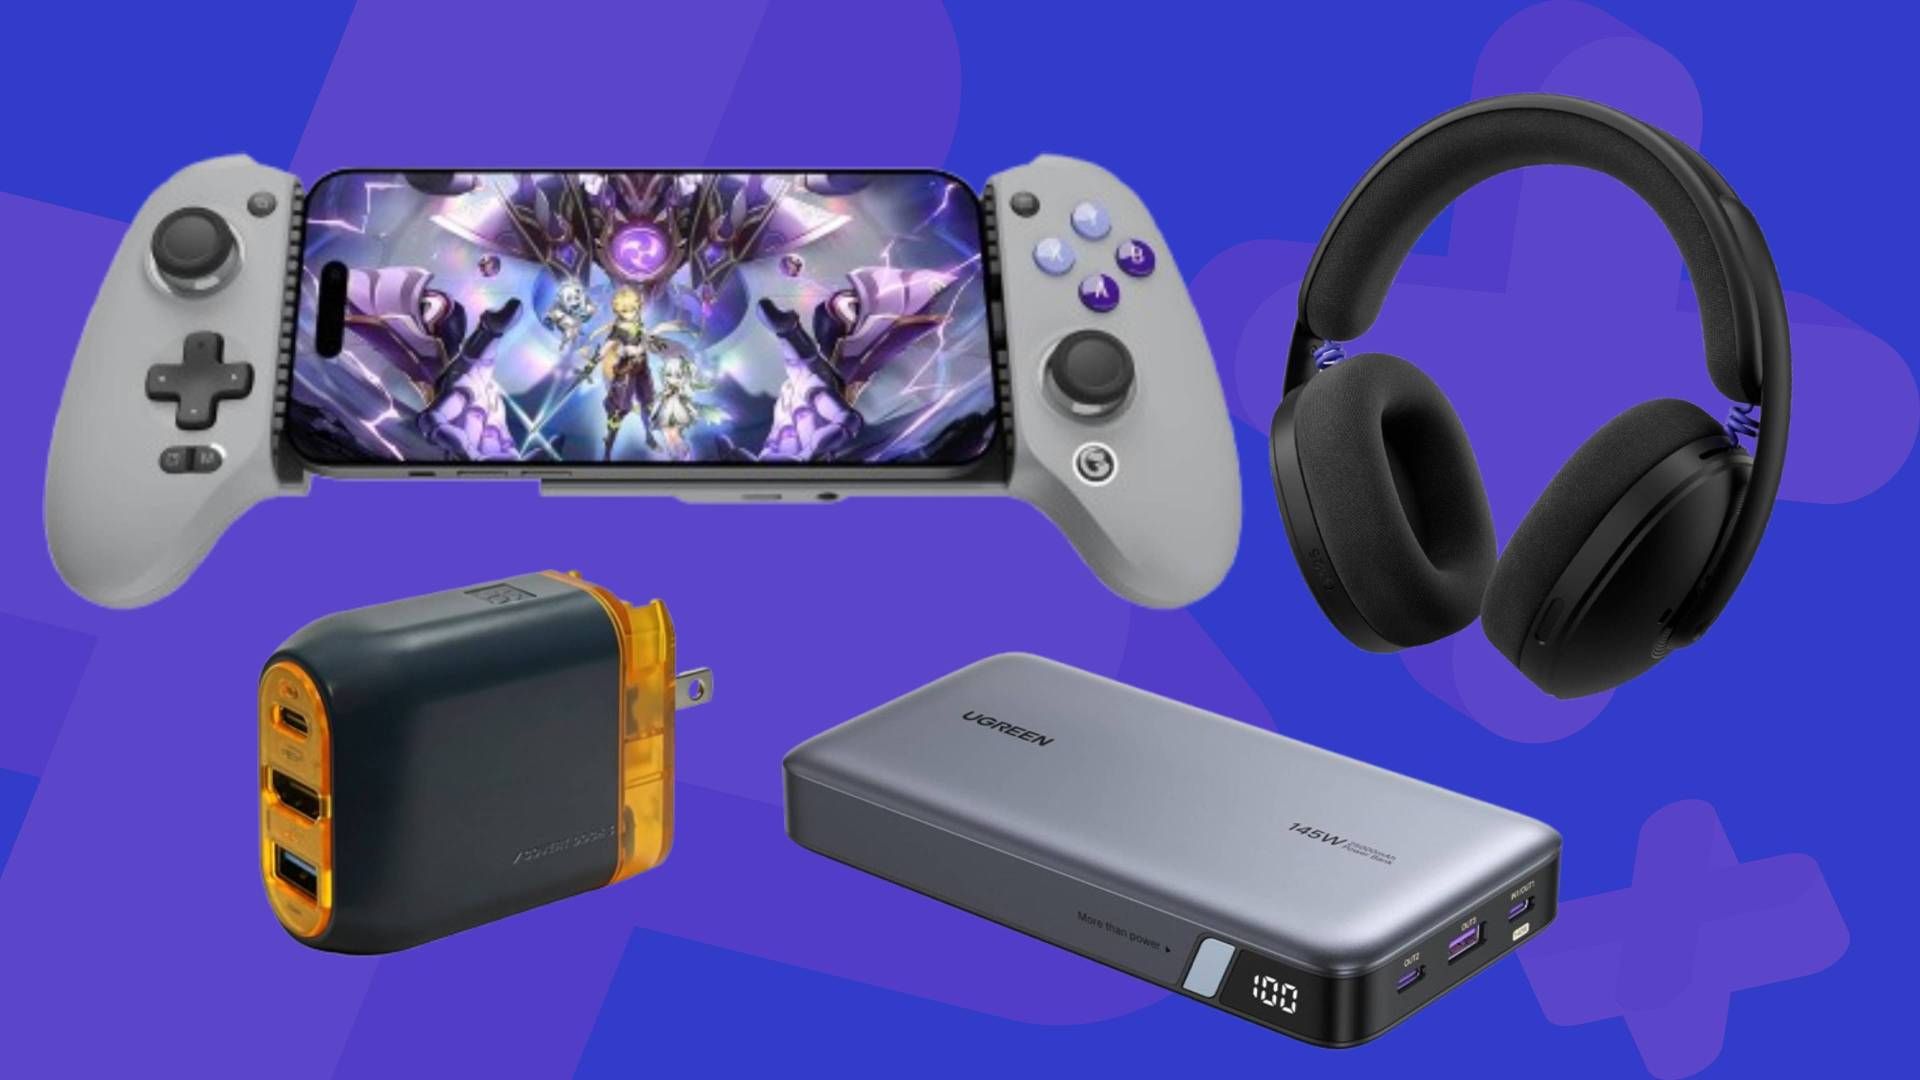
We’re all going on a summer holiday! Well, I’m not. I have a summer of gaming at home in the works, but if you have plans for a trip abroad or have anything else booked that allows you to game on the go, I’ve gathered some travel-friendly gadgets that can help with that.

I don’t want to assume that it’s the Nintendo Switch 2 that’s your summer console of choice. Yet, if it is, I can’t emphasize enough how life-changing a USB-C fan like the Sokelinn-six one I’ve added below really is. They easily fit in the USB-C port at the top of the handheld, and while they can be a bit of a battery drain, they blast a lovely flow of cool air in your face, which helps combat the overbearing summer heat.

Talking of battery woes, a power bank is one of my other travel go-tos, whether it’s for my Switch 2, Steam Deck, or just my smartphone. An option like the U-Green 25,000mAh version I’ve included down below has enough juice to power up a Switch 2, Steam Deck, or your phone, which is important to keep powered up if you’ve got all your travel details and itinerary on there. No matter your vacation gaming plans, I’ve gathered an array of accessories that will help make it a memorable (and equally nerdy) break.

The Friday Roundup – Shooting Exercises and Audio Tips


Videographer with sore knees shooting video.Videographer with sore knees shooting video.

Shoot This for Practice

I stumbled upon this great video for this week’s Friday Roundup that I thought might be of interest.

For many of us, we are mainly involved in documenting things with our videos or perhaps just presenting information and that’s fine.

However some of us may be thinking of taking things a bit more towards the creative side of video as well.

In doing so it is very easy to get caught up in the technicalities of shooting video that is more creative.

The key word here is creative, not technical.

So in the video below there are some exercises you can do as a video maker that are designed to strip out the technical and just concentrate on the creative.


Video Edit by Chat

As I was watching this video showing the new Video Edit by Chat feature in CyberLink PowerDirector, it got me thinking about a few things.

First up, OK, you can manipulate some video to an extreme degree using A.I. these days and we all know that, so thats nice.

But the real light bulb moment for me was when I actually watched this in progress where clearly the video was being uploaded to the A.I. server to be processed.

That made me wonder exactly how much time or effort would I be saving by doing this from inside the video editing app I am using?

Wouldnt it be just as easy to deal directly with the A.I. website myself?

I think these are important points to consider when you are making a choice as to which video editing app you may want to work with.

They are all banging on about A.I. at the moment but really, would you actually use it and if you did, is there really any advantage to having it accessible from inside an editing app you own?

Personally I think its kind of irrelevant and any choice for a video editor should be made on the basis of its ability to just edit the damn video!

Edit video by chat in PowerDirectorEdit video by chat in PowerDirector
Click Here to See the Video

How to Use a Mask to Change the Texture or Color of a Video Element in PowerDirector

This is a fairly complete demonstration of the masking capabilities available in CyberLink PowerDirector.

More importantly it gives a clear understanding as to why certain masking operations are effective in any video editing app and why sometimes, they are not!

Masking still images is easy but when those pesky things keep moving around like in video, things can take an awkward turn.


Audio Editing Tips to Improve Your Videos (Filmora Tutorial)

This is a video from the folks at Filmora covering some of the audio tools available now in Filmora 15.

They make a very important point here about getting the audio right in any video you make.

Less than ideal video will always be forgiven if there is interest in the subject and the audio is good.

Conversely, if the video is of high quality with interest in the subject but the audio is bad, just say goodbye to that viewer!

Nine time out of ten the person watching a video with poor audio will not really pinpoint what it is about the video they dont like.

They just get a sense of something being off and they stop watching.

So it really helps to get that audio as good as you can.


Stop Buying Random Gear for Your YouTube Studio Setup

When most people start out on their video creation journey, they are usually aware that at some point there will have to be a step up in the equipment department!

In fact if you take a quick look around whatever platform you are working on, there will be a ton of things that people promote as being necessary for that quality jump they may be looking for.

Unfortunately, a lot of the time that advice is pretty much random and not really aimed at a sensible progression towards a more professional look.

I know this because I was one of those that was flappin about trying to get my videos looking better.

So in the video below Gabriel covers this subject but more importantly gives a sequence of upgrading that absolutely makes sense.


How To Film Cinematic Videos on the Samsung s26 Ultra (Ultimate Guide)

For about a year or two now there have been quite a few mobile phones capable of shooting in more advanced modes.

By that I mean shooting with total control over the camera settings and more importantly, shooting in LOG format.

If you are not familiar, LOG files end up being just like the MP4 files you are used to but the method of capturing the information from the camera sensor is very different.

Instead of wasting effort trying to make it all look pretty for you as you shoot, a video file shot in LOG is devoted to capturing the most amount of information possible.

After that, when you import into your editing software, you can then manipulate them to your desire.

The beauty of LOG files is that you can engage in very extreme color corrections, color grading and other adjustments and they take it just fine.

Of course all of this technical stuff tends to make people avoid this type of video file capturing but in reality it is not that complicated.

Check the video below for a run-though which, although dedicated to the Samsung s26 Ultra, covers all the bases when shooting in LOG.


If I Had a Dime for Every Time a Director Used This Composition

One of the rules of both photographic and video shooting is the the Rule of Thirds.

Simply put it means that you place your subject or the main focus of the frame at a point to the left or right third of that frame leaving the other two thirds more open.

You can read more about following and breaking that rule here: Breaking Composition Rules in Video but there is one particular breaking of that rule discussed below.

That is to have the subject constantly centered in the frame and by doing so a slightly surreal aspect is introduced.

Then, when you use that center shot in conjunction with motion, either by tracking the camera or the subject moving, along a space shaped like a long hallway you have just created a classic shot.

One of the best proponents of this is Wes Anderson who just loves him some center framing although it is used all over the place and for some very good reasons.

Heres why.


DaVinci Resolve 21 FREE – New Features Effects you dont want to miss

All the talk over the past few weeks about DaVinci Resolve moving up to version 21 has actually been about the paid Studio version of the software.

In fact that version is now at 21.1 I believe having had an update since being released into the wild.

In the meantime the free version has remained at version 20 until… well it appears, until now!

In this video you can get to see what is new and what has been updated in the free version of Resolve 21.


Key Takeaways

  • This article explores creative video-making techniques and encourages focusing on creativity over technicalities.
  • It discusses the new Video Edit by Chat feature in CyberLink PowerDirector, questioning its advantages compared to using A.I. directly.
  • Masking techniques in CyberLink PowerDirector are highlighted for enhancing video editing skills.
  • Audio quality is crucial; good audio can salvage lower-quality video, while bad audio can drive viewers away.
  • The guide also emphasizes understanding advanced shooting techniques, like using LOG format for better video quality.

Improving token efficiency for GitHub Copilot in VS Code


June 17, 2026 by Ryan Caldwell and Bhavya U

With the recent move to usage-based billing for GitHub Copilot, every token in an agentic session matters. They affect your credits, latency, and the context window an agent has left to finish the task. Each new model generation tends to consume more tokens per task than the last, as we’ve witnessed in our own data. This means that harness-level efficiencies are increasingly important to counter this trend. As agents take on longer, more autonomous work, an inefficient harness adds up fast.
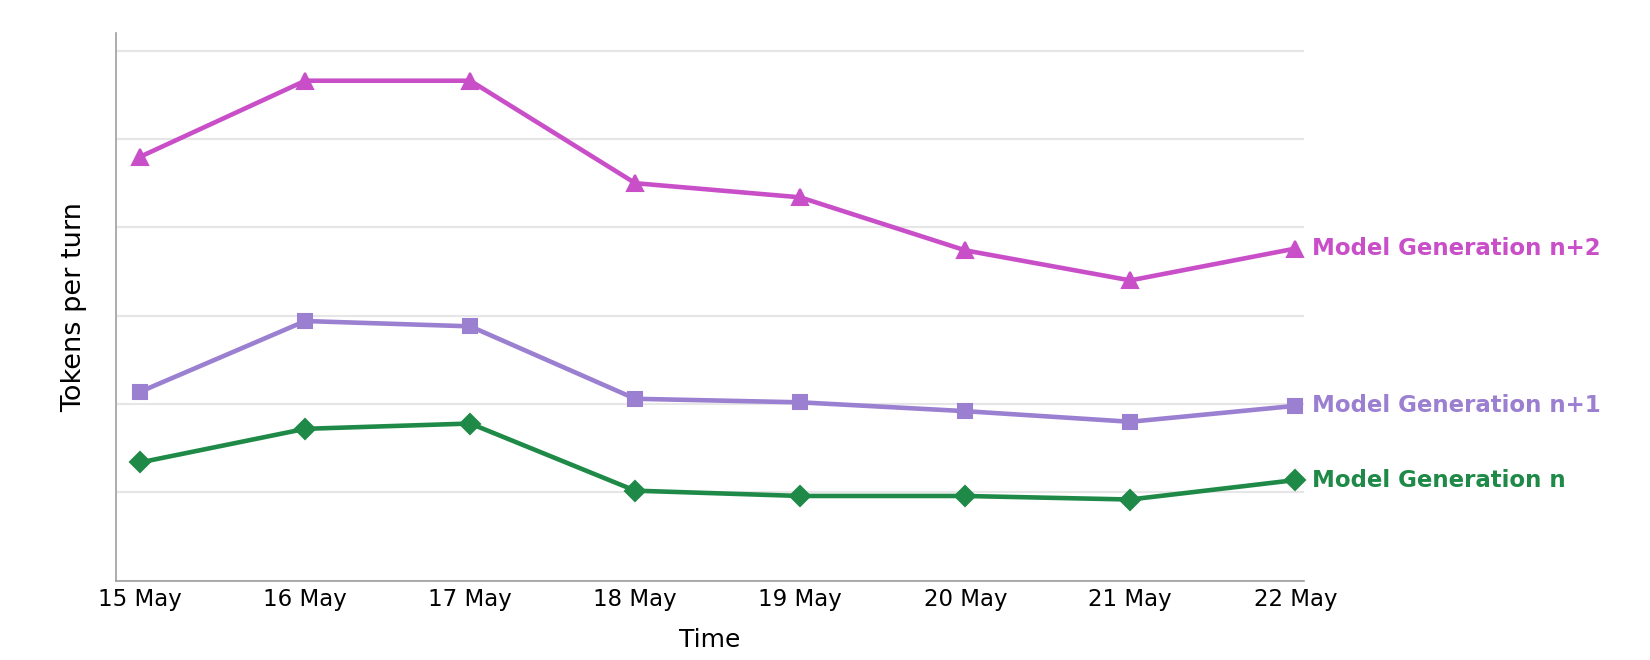
Chart showing tokens per turn increasing across successive model generations

Making the GitHub Copilot agentic harness in VS Code more token-efficient is continuous work, and it’s the best way to counter this trend. For most changes, we run A/B experiments in production and offline evaluations against task suites, confirming that task success rate holds or improves while token usage drops. It’s rarely one big win, usually a steady stream of small ones. Below, we walk through recent gains, first for OpenAI models and then for Anthropic models.

How agentic requests spend tokens

Two costs sit at the heart of every agentic request, and two ideas help us reduce them. Both apply across OpenAI and Anthropic models, even though each provider exposes them differently.
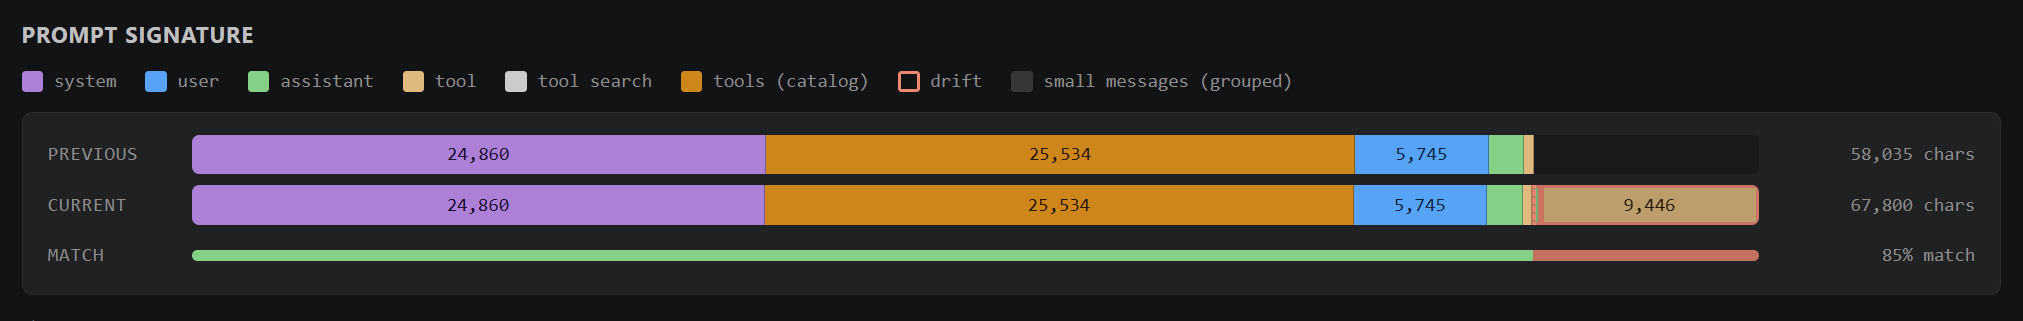
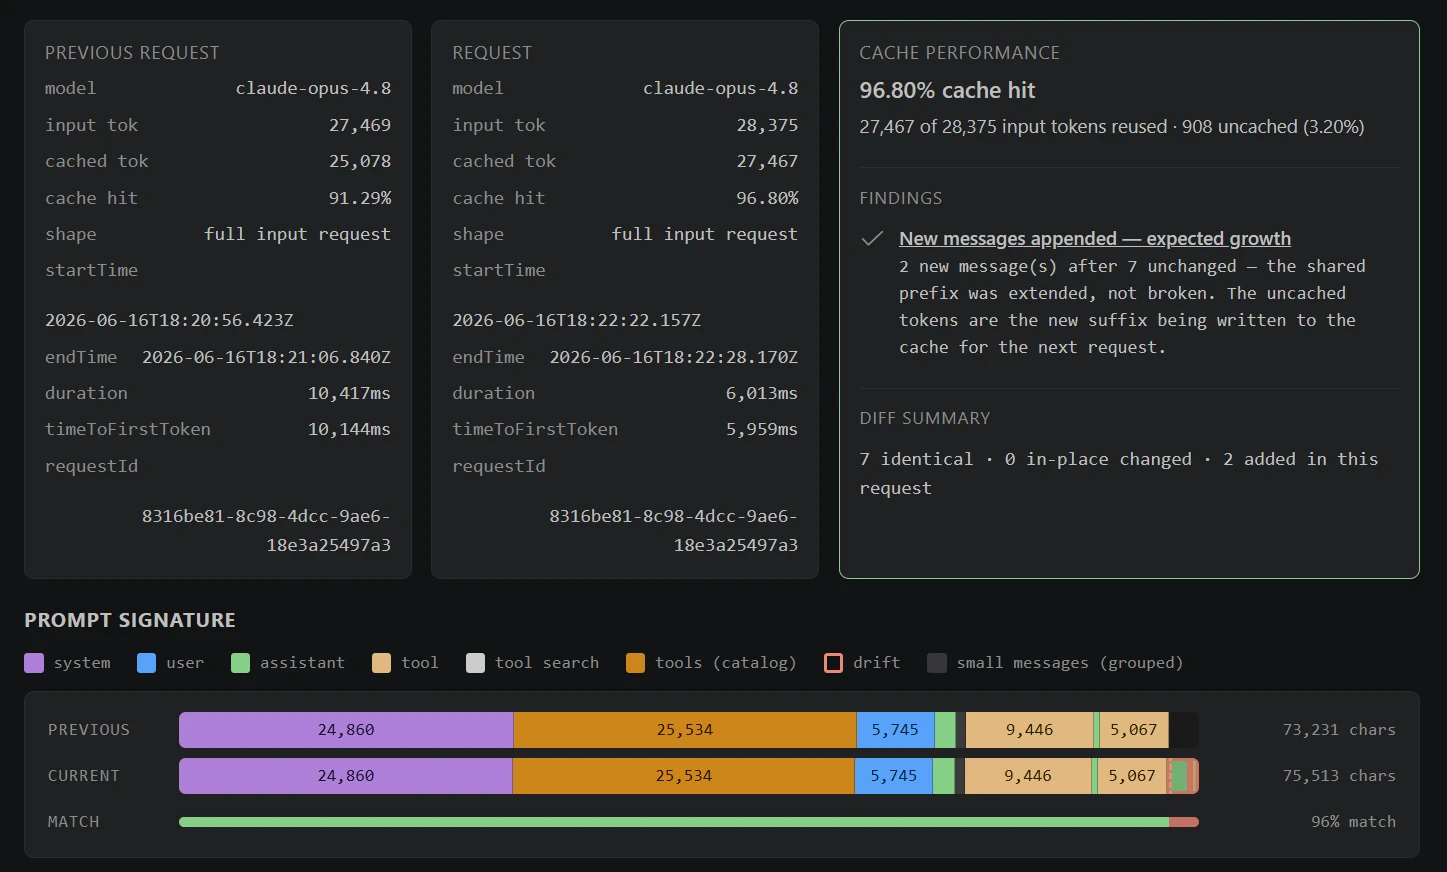
Screenshot of the Cache Explorer showing parts of the prompt in a horizontal stacked bar chart.
Graphical overview of the prompt signature highlighting the different parts of the prompt.

The prompt prefix and caching. In an agentic coding session, a large share of every request repeats across turns: system instructions, tool definitions, repository context, and conversation history. This repeated beginning is the prompt prefix. When requests share the exact same prefix, the inference provider can reuse cached model state instead of recomputing it from scratch on each request. Despite the name, the cached artifact is not a human-readable copy of the prompt. It is the model state computed while processing that prefix, represented internally as key/value tensors. Reusing the prefix cuts both cost (cached tokens can be up to 10 times cheaper) and latency, which is why we work to keep the prompt cache hit-rate high.

Tool-definition overhead. Agents can pull in a large number of tools: those exposed by MCP servers, built-in tools, or extension-provided tools. Each tool is sent to the model with a full definition (a name, a description, and a complete JSON parameter schema), and historically every one was loaded into context on every request. Even when that data is cached, the context window overhead is fixed on each turn and grows as the toolset does.

Tool search. Tool search reduces that overhead by letting the model load tool definitions on demand instead of all at once. Upfront, the model sees only lightweight metadata, the name and description of each deferred tool, and the heavier parameter schemas stay out of context until the model searches for a tool and loads it. Because deferred tools are added at the end of the context window rather than the prefix, the cached prompt prefix stays reusable and the caching gains keep working across turns. The payoff is a leaner context window: the model spends fewer tokens on tools it never uses, leaving more room and budget for the actual task.

Efficiency wins for OpenAI models

For OpenAI models, our recent work focused on reducing usage costs and latency for Copilot users through improved token efficiency. We pursued that through three changes: retaining cached model state for longer, reducing tool-definition overhead, and replacing repeated HTTP requests with persistent WebSocket connections.

Extended prompt caching

OpenAI models cache the prompt prefix automatically: the provider infers the reusable prefix and reuses its model state across requests. That reuse has a direct cost benefit. For most OpenAI models that support cached input pricing, uncached input tokens cost 10 times as much as cached input tokens.

Caching the prefix happens on its own, but how long that cache survives is something we can configure. After careful evaluation, we enabled extended prompt caching for supported models through the prompt_cache_retention body parameter. By default, the cache lives in fast GPU memory, where it is dropped after about 5 to 10 minutes of inactivity (up to an hour in some cases) to make room for other work. Setting "prompt_cache_retention": "24h" moves the cache to slower but roomier GPU-local storage and keeps it for up to 24 hours.

The benefit is simple. With the default cache, a pause of more than a few minutes throws the cache away, so your next request has to reprocess the whole prefix at the full, uncached price. Extended retention keeps the cache warm, so picking up where you left off is still fast and cheap, even after a long break.

After enabling extended prompt caching for supported OpenAI models in VS Code, we measured the following relative increases in cache hit rate. These are relative changes, not percentage-point increases: a 919% increase means the cache hit rate was 10.19 times higher than its previous value.

Time between requests GPT-5.2 GPT-5.3-Codex GPT-5.4
10-20 min +13% +32% +10%
20-30 min +135% +142% +137%
30-40 min +301% +203% +679%
40-60 min +338% +279% +919%

The increase was largest after longer gaps between requests, when cached model state that would otherwise have expired remained available for reuse. In practice, this increase means more of your prompt is processed at the lower cached-input rate, reducing the cost of requests even after longer pauses.

To avoid sending all tool definitions on every request, tool search makes this on-demand. Available to models GPT-5.4 and newer, OpenAI’s native tool search implements this deferral with a defer_loading flag.

Upfront, the model only sees lightweight metadata: the name and description of each deferred function or, when deferred functions are grouped into a namespace, only the namespace’s name and description.

During a four-day VS Code experiment with GPT-5.4 and GPT-5.5, tool search reduced per-turn token utilization, time to first token, and time to complete:

Metric Model Delta
P50 Total tokens used per turn GPT-5.4 -9.81%
P50 Total tokens used per turn GPT-5.5 -8.61%
P50 Time to first token (TTFT) GPT-5.4 -6.88%
P50 Time to first token (TTFT) GPT-5.5 -7.34%
P50 Time to complete (TTC) GPT-5.4 -5.31%
P50 Time to complete (TTC) GPT-5.5 -5.42%

Aggregated across an entire session, total token usage for the median Copilot user decreased by 8.97% with GPT-5.4 and 10.92% with GPT-5.5.

WebSockets

An agentic coding turn can involve many sequential requests to the inference provider; one for each step the model takes as it calls tools and works toward a solution. Even when the underlying HTTP connection is reused, each step remains a separate API request.

Responses API WebSocket mode keeps a persistent connection open and provides a lower-latency continuation path for those sequential requests. On an active connection, OpenAI can also reuse the most recent response state from a connection-local in-memory cache, reducing continuation overhead across long chains of tool calling.

A few months ago, OpenAI announced WebSocket support in the Responses API. Initial documentation showed large latency improvements, so we experimented with it early and saw consistent latency reductions in our own A/B test. This was one of those ideas that feels obvious in retrospect. Agentic coding sessions make repeated requests over a long-lived interaction, which is exactly what WebSockets are designed to handle.

During the initial rollout of WebSockets to VS Code Stable, the latency gains from the A/B experiment held in production. The table below shows the latency gains from WebSockets relative to HTTP during that rollout. Since then, improvements elsewhere in the stack, including improved prompt caching, have further reduced latency and usage costs. For each metric, lower is better:

Tracking metric Percentile GPT-5.3-Codex GPT-5.4
Time to first token (TTFT) p50 -19.46% -16.37%
Time to first token (TTFT) p95 -12.92% -15.78%
Time to complete (by turn) p50 -13.55% -11.74%
Time to complete (by turn) p95 -7.86% -6.26%

We also observed statistically significant relative increases in user engagement. For GPT-5.3-Codex and GPT-5.4, respectively, active users increased by 1.27% and 2.17%, while two-day engagement increased by 1.90% and 3.14%.

These gains led us to make WebSockets the default transport for OpenAI models GPT-5.2 and newer across Copilot products including VS Code, Copilot CLI, the GitHub app, and more.

Efficiency wins for Anthropic models

For Anthropic models, our recent work targeted the same two repeating costs: the prompt prefix we keep warm in cache, and the tool payload we send on every turn. We pursued that through two changes: spending our prompt-cache breakpoints more deliberately, and deferring tool definitions through tool search.

Smarter prompt caching

Anthropic’s prompt caching works differently from the automatic prefix caching that OpenAI models use. Rather than the provider inferring the reusable prefix, the caller places explicit cache_control breakpoints, and the API caches everything up to each marker.

The budget of breakpoints per request is small and fixed, so where you place them matters as much as whether you use them. We reworked our Messages API caching to spend up to four breakpoints deliberately, anchored at the prompt’s most stable boundaries:

  • The end of the tool definitions and the end of the system prompt, the parts that change least between turns.
  • A pair of rolling anchors on the two most recent cacheable messages.

That second, older anchor is a safety net. If the freshest anchor misses (a slow tool call lets its cache lapse, or content drifts slightly), the older anchor still serves a hit covering everything up to it. We typically give up a single exchange instead of cold-starting the whole conversation cache.

These changes produced a steady few-percentage-point increase in cache hit rate. For agentic workloads, where the prefix is long and turns come in quick succession, it now sits at around 94%, which means that only a small fraction of each request’s input has to be recomputed instead of served from cache. This reduces both usage cost and time to first token.

Anthropic’s tool search tool applies the same deferral idea. Tools are marked with defer_loading: true, and alongside the deferred catalog we keep a small, curated set of core tools loaded (reading and editing files, running terminal commands, searching the workspace) so the most common actions never require an extra step.

We first rolled this out using Anthropic’s server-side tool search, where the model searches the deferred catalog on Anthropic’s side and the API expands matches into tool_reference blocks inline. In a seven-day VS Code experiment, deferring tool definitions reduced both prompt-token and total-token usage and trimmed time to first chunk:

Metric Percentile / scope Delta
Time to first chunk p50 (by turn) -2.45%
Total prompt tokens p50 (by turn) -11.30%
Total prompt tokens p95 (by turn) -8.85%
Total prompt tokens p50 (by user) -18.32%
Total tokens p50 (by turn) -11.09%
Total tokens p95 (by turn) -8.74%
Total tokens p50 (by user) -18.03%

For the median Copilot user, overall prompt-token and total-token usage each fell by roughly 18% across a full session.

With the approach proven, we moved the search itself client-side, backing it with the same tools-grouping system we built for VS Code’s reduced toolset. The model still calls a tool_search tool, but instead of Anthropic matching against the deferred catalog, we run the search locally and return tool_reference blocks for the best matches.

The local search is also smarter. Rather than lexical matching over tool names and descriptions, we use our internal Copilot embedding model, the same model that powers our embedding-guided tool routing, to compare the query against vector representations of every available tool. Because it matches intent rather than literal keywords, a request like “find all references to this symbol” surfaces the right tool even when its name and description share no words with the query.

For a deeper look at the grouping and embedding-guided routing behind this, see How we’re making GitHub Copilot smarter with fewer tools.

Moving the search client-side gave us some extra benefits beyond the original token savings:

  • Responsiveness: the search runs locally against cached embeddings, so discovering a tool no longer depends on a server-side search round trip.

  • Dynamic MCP tool discovery: because we own the candidate set, tools that connected MCP servers add or remove mid-session are reflected immediately, without waiting on a fixed server-side catalog.

  • Better quality: the embedding-guided search is more likely to surface the right tool for a given query, which reduces user error and improves task success, as shown in the metrics below.

That responsiveness showed up directly in the numbers. In a two-week VS Code Stable rollout, the client-side tool search reduced latency on top of the token savings already gained from deferral.

Metric Model Delta
Time to first token (p50) Claude Opus 4.6 -1.91%
Time to complete (p50) Claude Opus 4.6 -1.97%
Time to complete (p95) Claude Opus 4.6 -2.57%
Time to complete (p50) Claude Sonnet 4.6 -1.30%
Time to complete (p95) Claude Sonnet 4.6 -3.35%
User error rate Claude Sonnet 4.6 -4.01%

In both variants, deferred tools sit outside the cached prompt prefix, so the prefix is never rewritten and the caching gains above keep working across turns. And once a tool has been discovered, it stays available for the rest of the conversation, so the model does not pay to search for it again.

What’s next

The work above makes our agentic harness leaner: a higher cache hit rate, fewer tool definitions per request, and less transport overhead. The next step is to move whole classes of work off the main agent entirely. We’re building specialized subagents, and exploring custom-trained ones, for narrow tasks like searching the workspace, running commands, and summarizing results. Each runs on the smallest, cheapest model that can do the job, instead of the main model paying for that work in its own context. The result is a lower overall cost per task.

In addition, we’re working to improve transparency around token usage and cache state in the product. This includes flagging actions that quietly drive up cost, such as resuming a session after a long pause with its cache expired, or changing the reasoning effort in the middle of a session. That way, you can make an informed choice before paying for a cache cold start.

Making the agentic harness more token-efficient is ongoing work, and we’ll keep investing, one small win at a time.

Happy coding! 💙
Enchanted by Nature cheats list for The Sims 4


The Sims 4 painted the town green with its outdoorsy, fairy-themed expansion, but if you don’t want to work your way up the faefolk rankings to get to the good stuff, you can use Enchanted by Nature cheats for an easy shortcut. Some fairy features don’t have their own code, but here you’ll find cheats for most Sims 4 careers, skills, and traits that were added with the expansion.

If you need extra guidance, check out our main list of The Sims 4 cheats for a refresher on the basics. And if you’re looking for other expansion commands, we’ve got lists for Businesses & Hobbies cheats and Life & Death cheats.

Enchanted by Nature career cheats

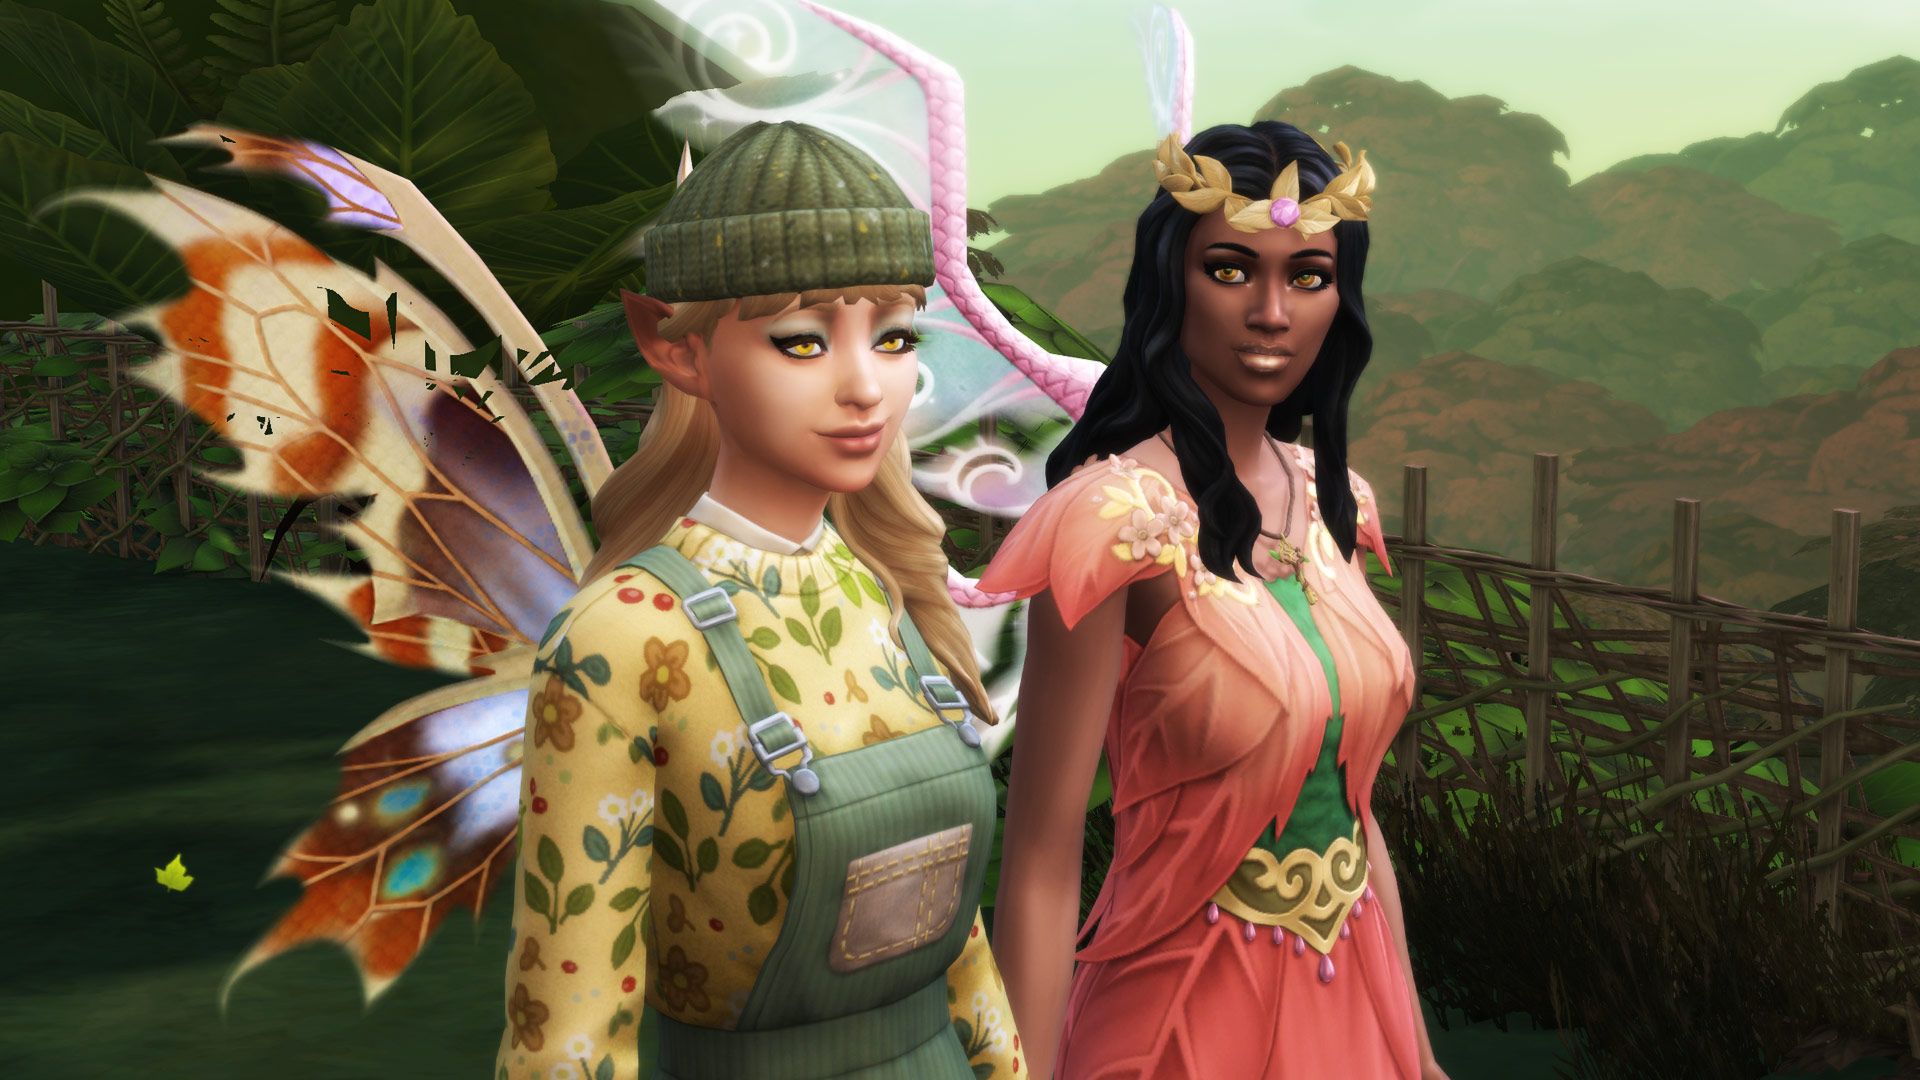
Two fairies talking to each other in The Sims 4: Enchanted by Nature.

(Image credit: Electronic Arts)

Enchanted by Nature added one new career to The Sims 4 with the Naturopath. It’s a handy career for curing ailments, and you can even take things a step further with branching career paths as a Lifestyle Coach or Apothe-curist.

Latest Videos From
Swipe to scroll horizontally

Career

Cheat code

Naturopath

careers.add_career Naturopath

careers.retire Naturopath

careers.promote Naturopath

careers.demote Naturopath

Enchanted by Nature skill cheats

GTA 6 Pre-Orders Open On June 25


It seems like Rockstar is actually sticking to the the November 19 release date.

Rockstar Games parent Take-Two has been pledging for a while that it would kickstart the hype for Grand Theft Auto VI this summer ahead of the November 19 release date. We got our first indication of that marketing machine getting into gear on Thursday, with the news that the publisher will open pre-orders for the massively anticipated game on June 25.

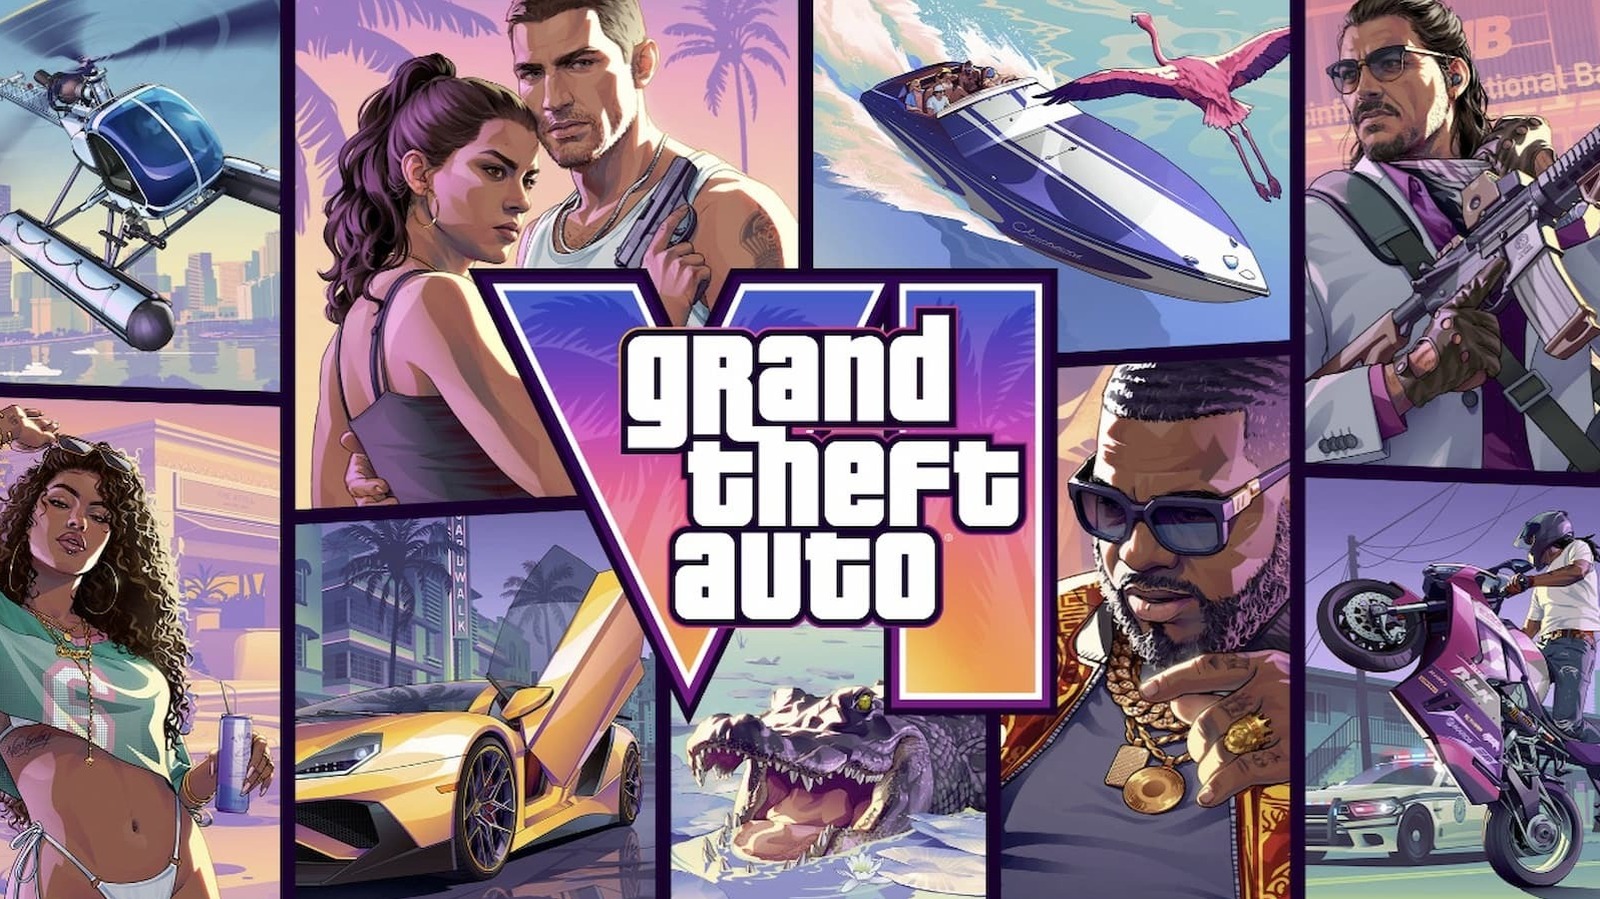
There’s no new trailer as yet — at this point, I would be surprised if Rockstar didn’t release one right just as pre-orders start. Still, it revealed the game’s cover art. It looks just like any other GTA cover, really, with a series of stylized images showing several characters, weapons, vehicles and animals that will populate the new version of Vice City.

The pre-order announcement is a further indication that Rockstar is actually sticking to the November 19 release date following previous delays. The publisher announced those around six months out from the previously planned release dates, and we’re within that window now. So all indications point toward GTA VI actually landing on PlayStation 5 and Xbox Series X/S five months from now.

G-RAID Shuttle with FREE Pelican Case


Get a FREE Pelican Case with Any G-RAID Shuttle – Limited-Time Storage Protection Offer

Need reliable, high-capacity storage for your video production workflow? For a limited time, when you purchase any G-RAID Shuttle, you’ll receive a FREE Pelican case at no additional cost. Designed for filmmakers, video editors, broadcasters, and content creators, G-RAID Shuttle systems deliver the performance and capacity needed for demanding 4K, 8K, and multi-camera productions. Pair that powerful storage with the rugged protection of a Pelican case, and you have a complete solution for transporting and safeguarding your valuable media. Don’t miss this special offer—available while supplies last.

  • Consolidated Backup, Super-fast Access and Real-time Video Editing
  • Transportable, hardware RAID powerhouse
  • Optimized for multi-stream workflows
  • 24TB – 104TB of high performance storage

starting at $4,104.99

w/ FREE Case for a limited time

  • Chase Your Vision from Location to Studio
  • 48TB – 208TB capacities in a transportable design
  • Daisy-chaining for up to 5 additional devices
  • 5-year limited warranty

starting at $6,644.99

w/ FREE Case for a limited time


FUELING CREATIVE AND PROFESSIONAL JOURNEYS

The G-DRIVE range of products delivers premium storage solutions designed for performance and growth. Contact Videoguys at 800-323-235 for free tech advice to find out which G-DRIVE is right for your workflow!

  • Rugged durability
  • Rugged portable backup with an IP54 rain/dust rating and crush resistant up to 1000 lbs
  • USB-C for quick file backups and ready to go with Mac
  • 1TB to 6TB capacity

starting at $194.99

  • Reliable, Premium Storage in a Durable Design
  • Fast, simple backups
  • Mac-ready, Time Machine compatible
  • Pairs with iPad USB Type-C models
  • 6TB – 26TB capacities

starting at $449.99

  • High-performance, 2-bay enterprise-class storage system
  • Pre-configured in RAID 0 & Thunderbolt 3 connectivity
  • Manage your 4K, 8K, and VR video workflows with ease and reliability
  • 6TB – 26TB capacities

starting at $644.99

  • Studio-grade Storage Performance
  • 7200RPM Ultrastar Enterprise-clase hard drives inside
  • RAID 0 out-of-the-box for maximizing efficiency
  • High-performance Thunderbolt 3 interface
  • 16TB – 52TB capacities

starting at $1,469.99


Telegram ban in India sparks a rush to VPNs, rival apps


As India cut off access to messaging app Telegram for a week over concerns about exam-related fraud, users turned to virtual private networks (VPNs) and alternative messaging apps in unusually large numbers.

App intelligence firm Appfigures told TechCrunch that Tuesday, the day India announced the Telegram restriction, marked the biggest day for VPN app downloads in the country since at least the start of 2025. Downloads of major VPN apps rose 49% from a recent daily average of 139,000 to 208,000, the firm said.

Proton VPN and Turbo VPN recorded some of the largest increases. Downloads of Proton VPN on Apple’s App Store in India jumped 113%, while Turbo VPN downloads rose 85%. On Google Play, downloads of Proton VPN climbed 64% and Turbo VPN downloads increased 35%. NordVPN’s App Store downloads increased 41%, while ExpressVPN downloads on Google Play rose 31%.

The surge also pushed several VPN services up India’s app-store charts. Proton VPN climbed from 18th to 5th in Apple’s Utilities rankings between June 16 and June 18, while its Google Play ranking rose from 8th to 2nd in the Tools category, according to Appfigures.

The spike in VPN demand followed India’s decision to temporarily restrict Telegram until June 22 over concerns that fraudsters were using the platform to target candidates ahead of a re-test for the National Eligibility cum Entrance Test (Undergraduate), the country’s largest entrance examination by applicant volume. The Indian government said the measure was needed to prevent the spread of fake exam papers and related scams. Telegram has challenged the order in the Delhi High Court, arguing that authorities should target specific content rather than block the entire platform.

The response extended beyond app-store download data. Proton said daily registrations from India rose 120% above baseline levels on Wednesday, after hourly registrations had already spiked 150% on Tuesday evening following the Telegram restriction. The company described the increase as “extremely noteworthy” given its existing scale in the country.

Canadian VPN service provider Windscribe reported a similar trend. The company told TechCrunch that signups from India peaked roughly 100% above baseline levels, while first-time downloads of its iOS app in the country rose about 89%.

“The spike in India follows the same general trend we see in areas that ban specific apps, introduce age bans or verification requirements, or otherwise restrict internet access,” Rebecca Rosenberg, growth operations manager at Windscribe, said.

Image Credits:Windscribe

The trend was not limited to a handful of VPN providers. Sensor Tower told TechCrunch that downloads across the VPN app category in India rose 10% day-over-day on June 17, reversing a decline seen over the previous two weeks.

Users also appeared to be exploring alternatives to Telegram. Appfigures said downloads of Signal in India rose 72% on Apple’s App Store and 322% on Google Play following the restriction, while Viber’s App Store downloads increased 216%.

Telegram-linked messaging app iMe recorded one of the sharpest jumps. Its Google Play downloads rose from a recent daily average of about 827 to 50,900 on June 16, Appfigures said.

Yet the restriction did not immediately translate into lower Telegram usage. Sensor Tower said Telegram’s daily active users in India rose 17% on the day the measure was announced — the app’s largest day-over-day increase in the country since a widespread outage of Meta’s services in 2021.

Other data points also suggest heightened efforts to access Telegram following the restriction.

Cloudflare Radar Lead Lai Yi Ohlsen told TechCrunch that DNS requests for Telegram domains in India increased sharply over the two days after the measure was announced. The company cautioned that higher DNS traffic does not necessarily indicate successful access to the platform, and could reflect users repeatedly attempting to reach Telegram after it was blocked.

Image Credits:Cloudflare

Telegram pointed to its efforts to cooperate with authorities during hearings in the Delhi High Court this week. Its lawyers said the company had removed channels identified by authorities and questioned the need for a platform-wide restriction affecting what Telegram says are over 150 million users in India.

Government lawyers defended the measure as a temporary, event-linked response tied to the NEET re-test. Solicitor General Tushar Mehta told the court that a permanent ban could raise proportionality concerns but argued the current restriction had a “logical nexus” to the objective being pursued.

After hearing arguments from Telegram and the government on Thursday, the Delhi High Court reserved its order and is expected to deliver its verdict on Friday.

The debate echoes questions raised elsewhere when governments restrict access to major online platforms. Sensor Tower said VPN downloads in the U.S. rose more than 40% week-over-week when TikTok was briefly removed from U.S. app stores in 2025, while Windscribe said it has observed similar patterns following restrictions in countries including Iran and Russia.

When you purchase through links in our articles, we may earn a small commission. This doesn’t affect our editorial independence.

Immigration Services and Relocation Guide


Immigration Services in Slovenia
Photo by Vladimir Srajber

Moving to a new country is complex. You’re navigating visa requirements, housing markets, banking systems, and bureaucratic processes in a language you might not speak.

Slovenia is more approachable than most countries. But without guidance, you’ll waste time and make mistakes.

That’s where professional immigration services come in.

What Immigration Services Actually Do

Professional immigration services in Slovenia help with moving services:

Visa and Residence Permit Applications

  • Advise on appropriate visa type for your situation
  • Prepare documentation
  • Submit applications
  • Handle communication with authorities
  • Manage renewals

Accommodation

  • Find rentals aligned with residence permit requirements
  • Verify landlord legitimacy
  • Ensure proper contracts
  • Handle deposit issues

Banking and Finance

  • Open bank accounts for foreigners
  • Explain Slovenian financial system
  • Help with tax identification

Company Registration

  • If establishing Slovenian company
  • Handle registration process
  • Prepare Articles of Association
  • Manage tax registration

Employment

  • Work permit applications
  • Employment contract preparation
  • Tax and social security guidance

Family and Dependents

  • Spouse/partner residence permits
  • Children education and visas
  • Family reunification

Ongoing Compliance

  • Renewal reminders
  • Address registration updates
  • Tax filing assistance

When You Need Immigration Services

You should consider professional services if:

Uncertain about visa type: Different visas for employees, entrepreneurs, students, digital nomads. Professional guidance ensures right choice.

Non-EU citizen: More complex documentation requirements. Worth professional help.

Bringing family: Multiple applications needed. Professional coordination helps.

Establishing business: Company registration + residence permit together is complex. Services help.

Limited Slovenian language: Services navigate bureaucracy in English.

Time constrained: Services handle paperwork, saving weeks of your time.

You probably don’t need services if:

EU citizen: Residence is relatively straightforward. You might handle alone.

Simple situation: Single person, staying temporarily, clear purpose.

Language comfortable: You speak Slovenian or very comfortable with forms.

Types of Immigration Services Available

Government Services:

  • Administrative Units (upravne enote) handle applications
  • Police handles residence registration
  • Free but slower, require Slovenian language

Private Law Firms:

  • Full immigration law expertise
  • Handle complex cases
  • Cost: €500-2,000 depending on complexity
  • Timeline: Fast, professional

Relocation Agencies:

  • Handle accommodation, banking, bureaucracy
  • Wider services beyond just visa
  • Cost: €300-1,500 for comprehensive package
  • Timeline: Efficient end-to-end process

Online Services:

  • Document preparation templates
  • Guidance for self-service
  • Cost: €50-200
  • Timeline: Self-directed (slower)

Combination Approach:

  • Many people use relocation agency for accommodation/setup
  • Use law firm for visa/residence permit application
  • Total cost: €800-2,500
  • Timeline: Coordinated, professional

The Service Package: What Comprehensive Immigration Service Includes

A good comprehensive service includes:

Pre-arrival consultation (free):

  • Assess your situation
  • Recommend visa type
  • Timeline estimate
  • Cost estimate

Documentation preparation (included):

  • Advise what documents needed
  • Guide on obtaining them
  • Review for completeness
  • Translate (if necessary)

Application submission (included):

  • Submit to appropriate authorities
  • Track application status
  • Communicate with officials on your behalf
  • Receive approval and follow up

Accommodation support (sometimes extra fee):

  • Connect with vetted landlords
  • Review rental agreements
  • Ensure compliance with visa requirements
  • Assist with lease signing

Banking setup (sometimes included):

  • Introduce to banks accepting foreigners
  • Assist with account opening
  • Ensure proper documentation

Post-arrival support (sometimes included):

  • Address registration assistance
  • Help with initial bureaucracy
  • Ongoing check-ins

Cost: Typically €1,000-2,500 for complete package

Red Flags: Avoiding Scams

When choosing immigration services:

Avoid if:

  • They guarantee visa approval (no one can do this)
  • They ask for large upfront payment (€5,000+)
  • They lack official credentials or office address
  • They don’t provide written contract
  • They pressure you to decide immediately
  • They offer “special connections” to authorities

Verify:

  • Check if licensed by Chamber of Attorneys
  • Read customer reviews
  • Ask for references
  • Confirm fixed pricing in writing
  • Ensure they have physical office in Slovenia

The Timeline: How Long Everything Takes

With professional services:

  • Consultation and planning: 1 week
  • Documentation gathering: 1-2 weeks
  • Application submission: 1 week
  • Official processing: 2-4 weeks
  • Residence card issuance: 1 week
  • Total: 4-9 weeks

Without professional services:

  • Same timeline but with potential delays
  • More back-and-forth with authorities
  • Language barriers slow everything
  • Could take 3-6 months

The professional service isn’t just convenience. It accelerates the process significantly.

The Cost Breakdown: What You’re Paying For

Government fees:

  • Application processing: €20-100
  • Residence registration: Free
  • ID card (if needed): €50
  • Total government: €70-150

Professional service fees:

  • Immigration consultation and application handling: €500-1,000
  • Company registration (if needed): €300-500
  • Accommodation assistance: €200-400
  • Banking assistance: €100-200
  • Post-arrival support: €200-300
  • Total professional: €800-2,400

Your personal costs:

  • Accommodation deposits: €500-1,500
  • Travel to Slovenia: €200-1,000
  • Initial living costs: €1,500-2,500
  • Total personal: €2,200-5,000

Total relocation cost: €3,200-7,500

This is reasonable for moving to a new country.

After You Arrive: Ongoing Support

Most reputable services offer ongoing support:

First month:

  • Daily check-ins if needed
  • Help with unexpected issues
  • Advice on local systems

Ongoing:

  • Renewal reminders
  • Tax filing guidance
  • Address updates
  • Permit extensions

Cost: Usually included in initial fee or small monthly fee (€30-50)

Choosing the Right Service

Process:

  1. Identify 2-3 services
  2. Request free consultation
  3. Ask specific questions about your situation
  4. Get written proposal
  5. Compare terms and pricing
  6. Check references
  7. Sign contract
  8. Begin process

Timeline for choosing: 1-2 weeks

The Reality: Is Professional Service Worth It?

For most people moving to Slovenia: Yes.

Reasons:

  • Saves significant time (weeks or months)
  • Reduces errors and rejections
  • Handles complex bureaucracy
  • Provides peace of mind
  • Actual cost is reasonable (€1,000-2,500)

Exceptions:

  • EU citizen, simple situation, comfortable with forms
  • Previous experience with similar countries
  • Language ability and patience for bureaucracy

When Seeking Immigration Services

If you’re planning to move to Slovenia and want professional guidance, immigration services in Slovenia handle the complexity.

The investment in professional help pays for itself through time saved and errors prevented.

For most people relocating to a new country, it’s money well spent.

Start with consultation. Understand your situation. Make the choice.

Moving to Slovenia is achievable. With right support, it’s smooth and straightforward.

Find a Home-Based Business to Start-Up >>> Hundreds of Business Listings.