Should You Turn Your Executives Into AI Avatars?


Databox CEO Peter Caputa recently posted that he is releasing a new video course taught entirely by his AI double. The avatar, powered by the popular AI video tool HeyGen, looks and sounds just like him, delivering hours of expert content on his behalf. Continue reading “Should You Turn Your Executives Into AI Avatars?”

Top Tools, Benefits & AI Trends


Cloud Orchestration: The Heart of Modern DevOps and AI Pipelines

Cloud orchestration is the most important part of modern DevOps and AI pipelines. It does more than just automate things; it also organizes the provisioning, configuration, and sequencing of cloud resources, APIs, and services into dependable workflows.

DataCamp says that orchestration is a progression beyond task automation (such as making a VM or installing software) to “end-to-end, policy-driven workflows that span multiple services, environments, or even cloud providers.” The idea is to eliminate manual steps, reduce errors, and accelerate innovation.

Rising Complexity in Resource Management

Managing resources becomes much more complicated as businesses start using microservices, multi-cloud methods, and AI workloads.

Scalr says that by 2025, 89% of businesses will utilize more than one cloud provider. In 2024, container management revenue is predicted to reach $944 million, with AI/ML integration driving demand for smart workload placement.

This blog clears up the confusion about cloud orchestration, compares the best solutions, and explores new developments

Quick Insights: The global cloud orchestration market is projected to grow from $14.9 billion in 2024 to $41.8 billion by 2029 (CAGR 23.1%)

Summary of Contents

  • What Cloud Orchestration Means & Why It Matters—Definitions, differences from automation, and why orchestration is critical for DevOps, AI and hybrid‑cloud.
  • Types of Orchestration Tools—Infrastructure-as-Code (IaC), configuration management, workflow orchestration, and container orchestration.
  • Top Tools & Platforms for 2025 – Deep dives into Clarifai, Kubernetes, Nomad, Terraform, Ansible, CloudBolt, , and others. Comparisons of strengths, weaknesses, pricing, and ideal use cases.
  • How Orchestration Works & Best Practices—Patterns like sequential vs. scatter‑gather, error handling, GitOps, service discovery, and security.
  • Benefits, Challenges & Use Cases – Real-world examples across retail, data pipelines, AI model deployment and IoT.
  • Emerging Trends & Future of Orchestration – Generative AI, AI‑driven resource optimisation, edge computing, serverless, zero trust and no‑code orchestration.
  • Clarifai’s Approach & Getting Started – How Clarifai’s orchestration makes AI pipelines simple, plus a step‑by‑step guide to building your own workflows.
  • FAQs – Answers to common questions about orchestration vs. automation, tool selection, security, and future trends.

Introduction: The Role of Cloud Orchestration

Cloud infrastructure used to revolve around simple automation scripts—launch a virtual machine (VM), install dependencies, deploy an application. As digital estates grew and software architecture embraced microservices, that paradigm no longer suffices. Cloud orchestration adds a coordinating layer: it sequences tasks across multiple services (compute, storage, networking, databases, and APIs) and enforces policies such as security, compliance, error handling and retries. DataCamp emphasises that orchestration “combines these steps together into end‑to‑end workflows” while automation handles individual tasks. In practice, orchestration is essential for DevOps, continuous delivery and AI workloads because it provides:

  • Consistency and repeatability. Declarative templates ensure the same infrastructure is provisioned every time, reducing human error.
  • Speed and agility. Orchestrated pipelines deliver changes faster. DataCamp notes that orchestration reduces manual errors and speeds up deployments.
  • Compliance and governance. Policies such as access controls and naming conventions are enforced automatically, aiding audits and regulatory compliance.
  • Multi‑cloud and hybrid support. Orchestration tools abstract provider‑specific APIs so teams can work across AWS, Azure, Google Cloud and private clouds.

Quick Summary: Why Orchestration Matters

In short, orchestration moves us from ad‑hoc scripts to codified workflows that deliver agility and stability at scale. Without orchestration, a modern digital business quickly falls into “snowflake” environments, where each deployment is slightly different and debugging becomes painful. Orchestration tools help unify operations, enforce best practices and free engineers to focus on high‑value work.

Expert Insight

Sebastian Stadil, CEO of Scalr: “Organisations need orchestration not just to provision resources but to manage their entire lifecycle, including cost controls and predictive scaling. The market will grow from roughly $14 billion in 2023 to up to $109 billion by 2034 as AI/ML integration and edge computing drive adoption”.


How Cloud Orchestration Works—Patterns & Mechanisms

You can make systems that work well if you know how orchestration engines really work. An orchestration platform usually works like this:

  1. Get a request
    This may be something a user does, like deploying a new environment, or it could be a scheduled trigger, like nightly ETL.
  2. Plan the workflow
    The orchestrator reads a declarative template or DAG, finds dependencies, and makes a plan for how to run the tasks.
  3. Do things
    It works with cloud APIs, containers, databases, and other services that are not part of the cloud. Tasks might run one after the other, at the same time (scatter-gather), or based on conditional logic.
  4. Handle mistakes and retry
    Workflow engines provide built-in ways to handle failures, timeouts, rollbacks, and retries. Some even enable compensating actions (Saga pattern).
  5. Aggregate results and respond
    The orchestrator puts together the outputs when the jobs are done and either sends the results back or starts the next step.
  6. Monitor and log everything
    Telemetry, tracing, and observability are very important for finding problems and checking operations.
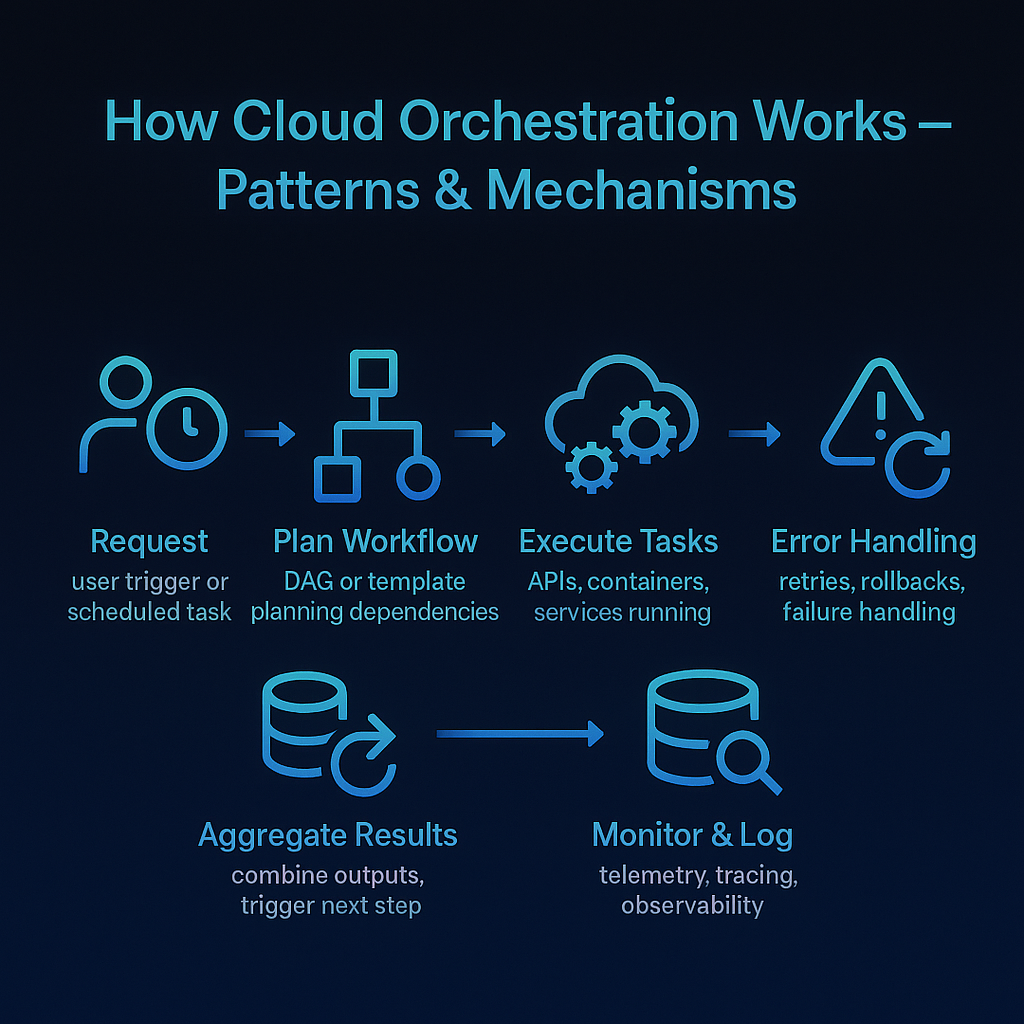
 

Quick Summary: How Cloud Orchestration Works
Orchestration engines trigger, plan, and execute tasks across systems. They handle retries, sequencing, and monitoring—using patterns like sequential workflows, scatter-gather, and Saga for reliability.

Patterns to Know

  • Sequential workflow: Do tasks one after the other; typical when dependencies are strict.
  • Parallel / Scatter-Gather: Start several processes at the same time and combine the results. Helpful for microservices or fan-out operations.
  • Event-driven orchestration: React to events in real time, like queuing messages. Common in serverless and IoT situations.
  • Saga pattern: In complicated transactions, each step includes a compensation mechanism to maintain consistency.
  • GitOps and Desired State: Git commits drive changes to infrastructure/configuration, and controllers ensure actual state matches the desired state.

Service Discovery & Gateways

Orchestrators in microservice setups often use service discovery mechanisms (like Consul, etcd, or Zookeeper) and API gateways to route requests.

  • Service discovery: Automatically updates endpoints when services grow or shrink.
  • Gateways: Centralize authentication, rate limiting, and observability across different services.

Expert Opinion

DataCamp says that container orchestration solutions integrate seamlessly with CI/CD pipelines, service meshes, and observability tools to manage deployment, scaling, networking, and the entire lifecycle. Integration with telemetry is essential to detect and fix issues automatically.
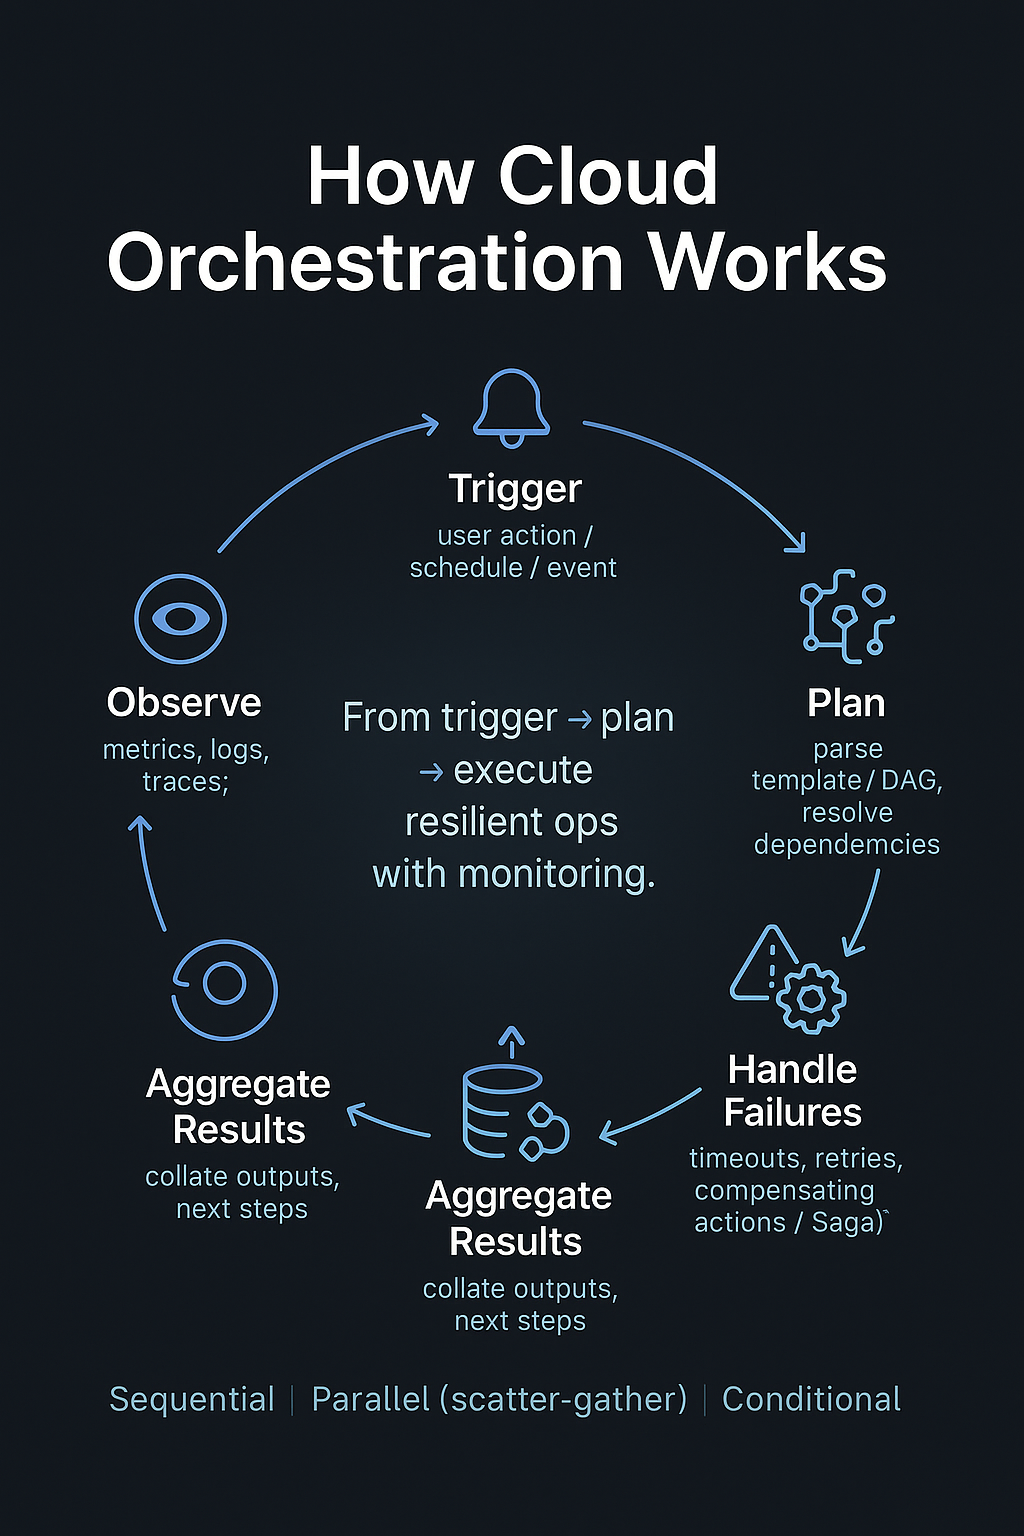
Cloud Orchestration lifecycle

Benefits of Cloud Orchestration

Cloud orchestration isn’t just “nice to have”; it adds real value to your organization:

1. Faster and more reliable deployments.

By codifying infrastructure and workflows, you eliminate manual steps and human errors. DataCamp notes that orchestration accelerates deployments, improves consistency, and reduces mistakes—leading to faster feature releases and happier customers.

Organizations using orchestration and automation report a 30–50% reduction in deployment times (Gartner).

2. Better Resource Usage and Cost Control

Orchestrators intelligently schedule workloads, spinning up resources only when needed and scaling them down when idle. Scalr says AI/ML integration enables smart task placement and anticipatory scaling. Paired with FinOps platforms like Clarifai’s cost controls, you can track spending and stay within budgets.

3. Better Security and Compliance

Automation enforces security baselines consistently and reduces misconfiguration risks.

  • IaC tools like CloudFormation detect drift.
  • Platforms like Puppet provide full compliance reports.
  • Identity management and zero-trust architectures combined with orchestration make cloud operations safer.

4. Multi-Cloud and Hybrid Agility

Orchestration hides provider-specific APIs, enabling portable workloads across AWS, Azure, GCP, on-prem, and edge environments.

Terraform, Crossplane, and Kubernetes unify operations across providers—critical since 89% of businesses use multiple clouds.

5. Developer Productivity and Innovation

Declarative templates and visual designers free developers from repetitive plumbing tasks.

  • They can focus on innovation rather than setup.
  • Clarifai’s low-code pipeline builder lets AI engineers build complex inference workflows without extensive coding.

Quick Summary: What are the benefits of cloud orchestration?
Orchestration delivers faster deployments, cost optimization, reduced errors, enhanced security, and improved developer productivity—critical for businesses scaling in a multi-cloud world.

Challenges & Considerations

While orchestration offers huge benefits, it also introduces complexity and organizational changes.

  • Learning curve: Tools like Kubernetes and Terraform require time to master.
  • Process changes: Teams may need to adopt GitOps or DevOps methodologies.
  •  Complexity must be “just right” for your use case.
  • Vendor Lock-In: Some platforms may limit portability.
  • Latency & Performance: Orchestration adds overhead; low-latency apps (e.g., gaming) need edge optimization.
  • Security & Misconfiguration Risks: Centralized control can spread mistakes quickly; use policy-as-code, RBAC, and compliance scanning.
  • Cost Management: Uncontrolled orchestration can inflate resource costs—FinOps practices are critical.

Quick Insight: 95% of organizations experienced an API or cloud security incident in the last 12 months (Postman API Security Report 2024).

Quick Summary: What are the challenges of cloud orchestration?

The main hurdles are tool complexity, vendor lock-in, misconfigurations, and rising costs. Security orchestration and zero-trust frameworks are essential for minimizing risks.
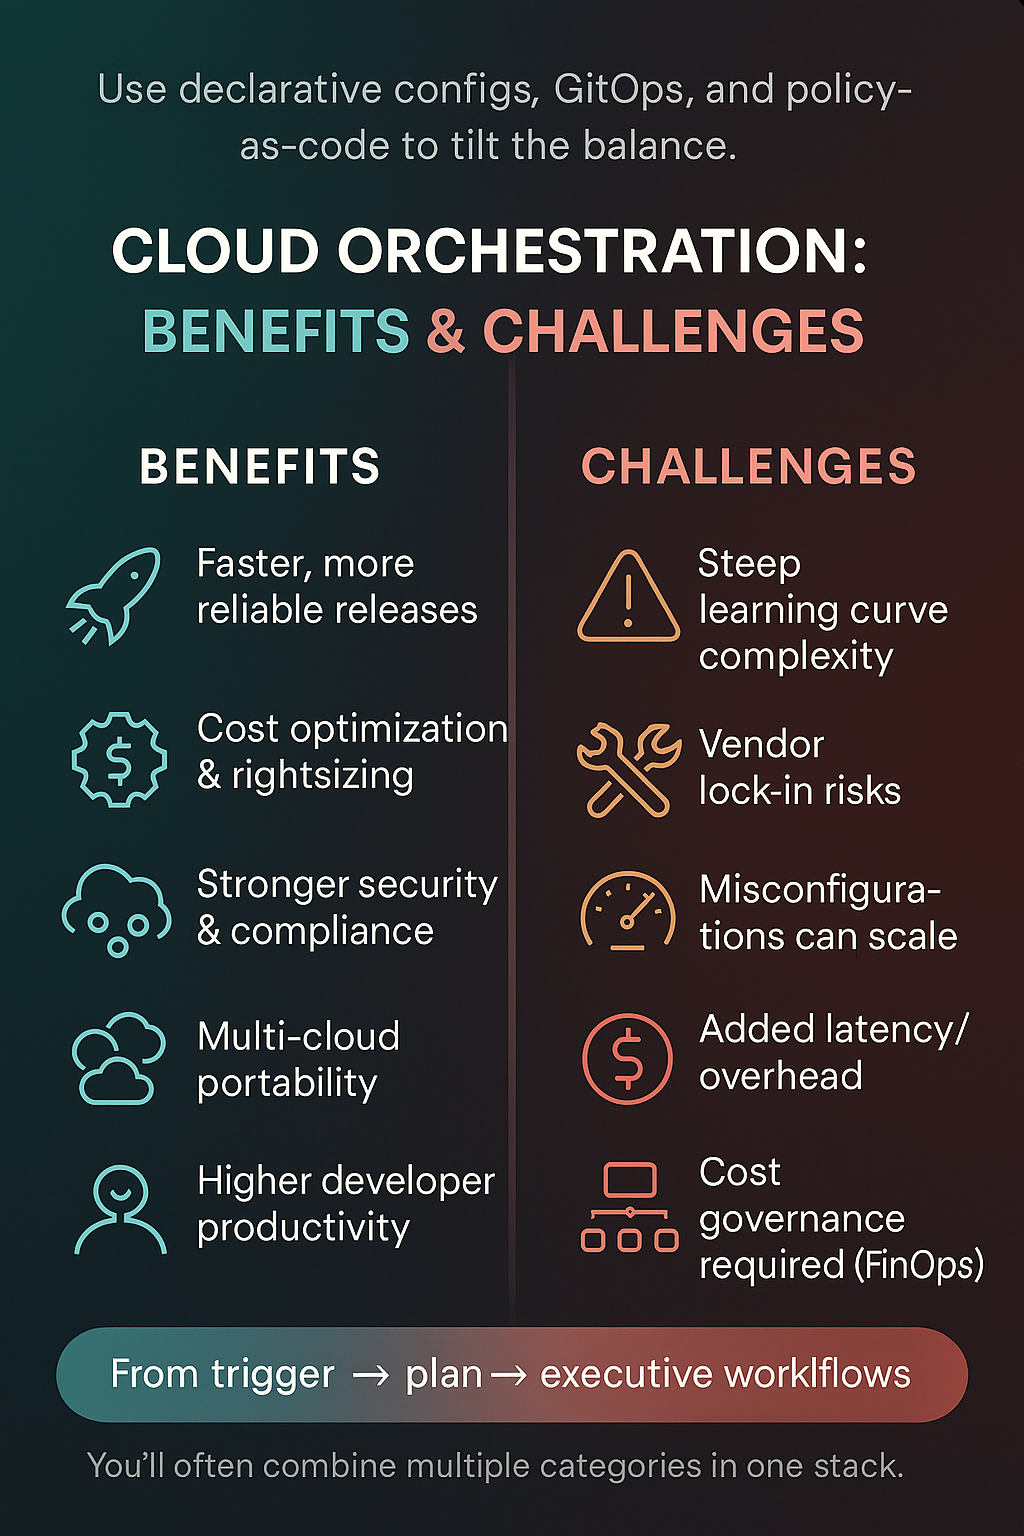
Cloud Orchestration Benefits and Challenges


Key Components & Architecture

A typical cloud orchestration architecture includes:

  1. Client/Application. User interface or CLI triggers actions.
  2. API Gateway. Routes requests, handles authentication, rate limiting, logging and policy enforcement.
  3. Workflow Engine/Controller. Parses templates or DAGs, schedules tasks, tracks state, manages retries and timeouts.
  4. Service Registry & Discovery. Maintains a registry of services and endpoints (e.g., Consul, etcd) for dynamic routing.
  5. Executors/Agents. Agents or runners on target machines or containers (e.g., Ansible modules, Nomad clients) perform tasks.
  6. Data Stores. Maintain state, logs and metrics (e.g., S3, DynamoDB, MySQL).
  7. Monitoring & Observability. Collects metrics, traces and logs for visibility; integrates with Prometheus, Grafana, Datadog.
  8. Policy & Governance Layer. Applies RBAC, cost policies and compliance rules. Tools like Scalr and Spacelift emphasise this layer.
  9. External Services & Edge Nodes. Orchestrators also integrate with SaaS APIs, DBaaS, message queues and edge devices (K3s, local runners like Clarifai’s platform).

This layered architecture allows you to swap components as needs evolve. For example, you can use Terraform for IaC, Ansible for configuration, Airflow for workflows and Kubernetes for containers, all coordinated through a common gateway and observability stack.

Quick Summary: What are the key components & architecture of cloud orchestration?

 A typical orchestration stack includes a workflow engine, service discovery, observability, API gateways, and policy enforcement layers—all working together to streamline operations.


Types of Cloud Orchestration Tools

Not all orchestration solutions solve the same problem. Tools typically fall into four categories, though there is overlap in many products.

Infrastructure‑as‑Code (IaC) Tools

IaC tools manage cloud resources through declarative templates. They specify what the infrastructure should look like (VMs, networks, load balancers) rather than how to create it. DataCamp notes that IaC ensures consistency, repeatability and auditability, making deployments reliable. Leading IaC platforms include:

  1. HashiCorp Terraform. A cloud‑agnostic language (HCL) with 200+ providers, state management and a large module ecosystem. It supports GitOps workflows and is widely used for multi‑cloud provisioning.
  2. AWS CloudFormation. AWS’s native IaC service using YAML/JSON templates with drift detection and stack sets. Ideal for deep AWS integration.
  3. Azure Resource Manager (ARM) & Bicep. Microsoft’s declarative templates for Azure; Bicep provides a simplified language.
  4. Google Cloud Deployment Manager. Declarative templates for Google Cloud; integrates with Cloud Functions.
  5. Scalr & Spacelift. Platforms that layer governance, cost controls and policy enforcement on top of Terraform modules.

Configuration Management Tools

Configuration management ensures that servers and services maintain the desired state—software versions, permissions, network settings. DataCamp describes these tools as enforcing system state consistency and security policies. Key players are:

  1. Ansible. Agentless automation using YAML playbooks; low learning curve and broad module support.
  2. Puppet. Declarative model with an agent/puppet master architecture; excels in compliance‑heavy environments.
  3. Chef. Ruby‑based system using cookbooks for configuration and test‑driven infrastructure.
  4. SaltStack (Salt). Event‑driven architecture enabling fast, parallel execution of commands; ideal for large scale.
  5. Google Cloud Config Connector (Kubernetes CRDs) and Kustomize for Kubernetes-specific config.

Workflow Orchestration Platforms

Workflow orchestrators sequence multiple tasks—API calls, microservices, data pipelines—and manage dependencies, retries and conditional logic. DataCamp lists these tools as essential for ETL processes, data pipelines, and multi‑cloud workflows. Leading platforms include:

  1. Apache Airflow & Prefect. Popular open‑source workflow engines for data pipelines with DAG (Directed Acyclic Graph) representation.
  2. AWS Step Functions. Serverless state machine engine that coordinates AWS services and microservices with built‑in error handling.
  3. Azure Logic Apps & Durable Functions. Visual designer and code‑based orchestrators for integrating SaaS services and Azure resources.
  4. Google Cloud Workflows. YAML‑based serverless orchestration engine that sequences Google Cloud and external API calls, with retries and conditional logic.
  5. Netflix Conductor & Cadence, Argo Workflows (Kubernetes native), Morpheus, and CloudBolt—enterprise platforms with governance and multi‑cloud support.

Container Orchestration Platforms

Containers make applications portable, but orchestrating them at scale requires specialized platforms. DataCamp emphasises that container orchestrators handle deployment, networking, autoscaling and lifecycle of clusters. Major options:

  1. Kubernetes (K8s). The de facto standard with declarative YAML, horizontal pod autoscaling and self‑healing. Scalr notes that K8s’ v1.32 update (“Penelope”) improves multi‑container pod resource management and security.
  2. Docker Swarm. Built into Docker; simple to set up and resource‑light; best for small clusters.
  3. Red Hat OpenShift. Enterprise distribution of Kubernetes with integrated CI/CD, enhanced security and multi‑tenant management.
  4. Rancher. Multi‑cluster Kubernetes management with intuitive UI.
  5. HashiCorp Nomad. Lightweight orchestrator for containers, VMs and binaries; ideal for mixed workloads.
  6. K3s (lightweight K8s for edge), Docker Compose, Amazon ECS, and Service Fabric for specialized needs.

Quick Summary: Tool Types

  • IaC defines infrastructure; think Terraform & CloudFormation.
  • Configuration management enforces server state; Ansible and Puppet shine here.
  • Workflow orchestration stitches together tasks and microservices; Airflow and Step Functions are common.
  • Container orchestration manages deployment and scaling of containers; Kubernetes dominates but alternatives like Nomad and K3s exist.

Expert Insight

Don Kalouarachchi, Developer & Architect : “Categories of orchestration tools overlap, but distinguishing them helps identify the right mix for your environment. Workflow orchestrators manage dependencies and retries, while container orchestrators manage pods and services”.
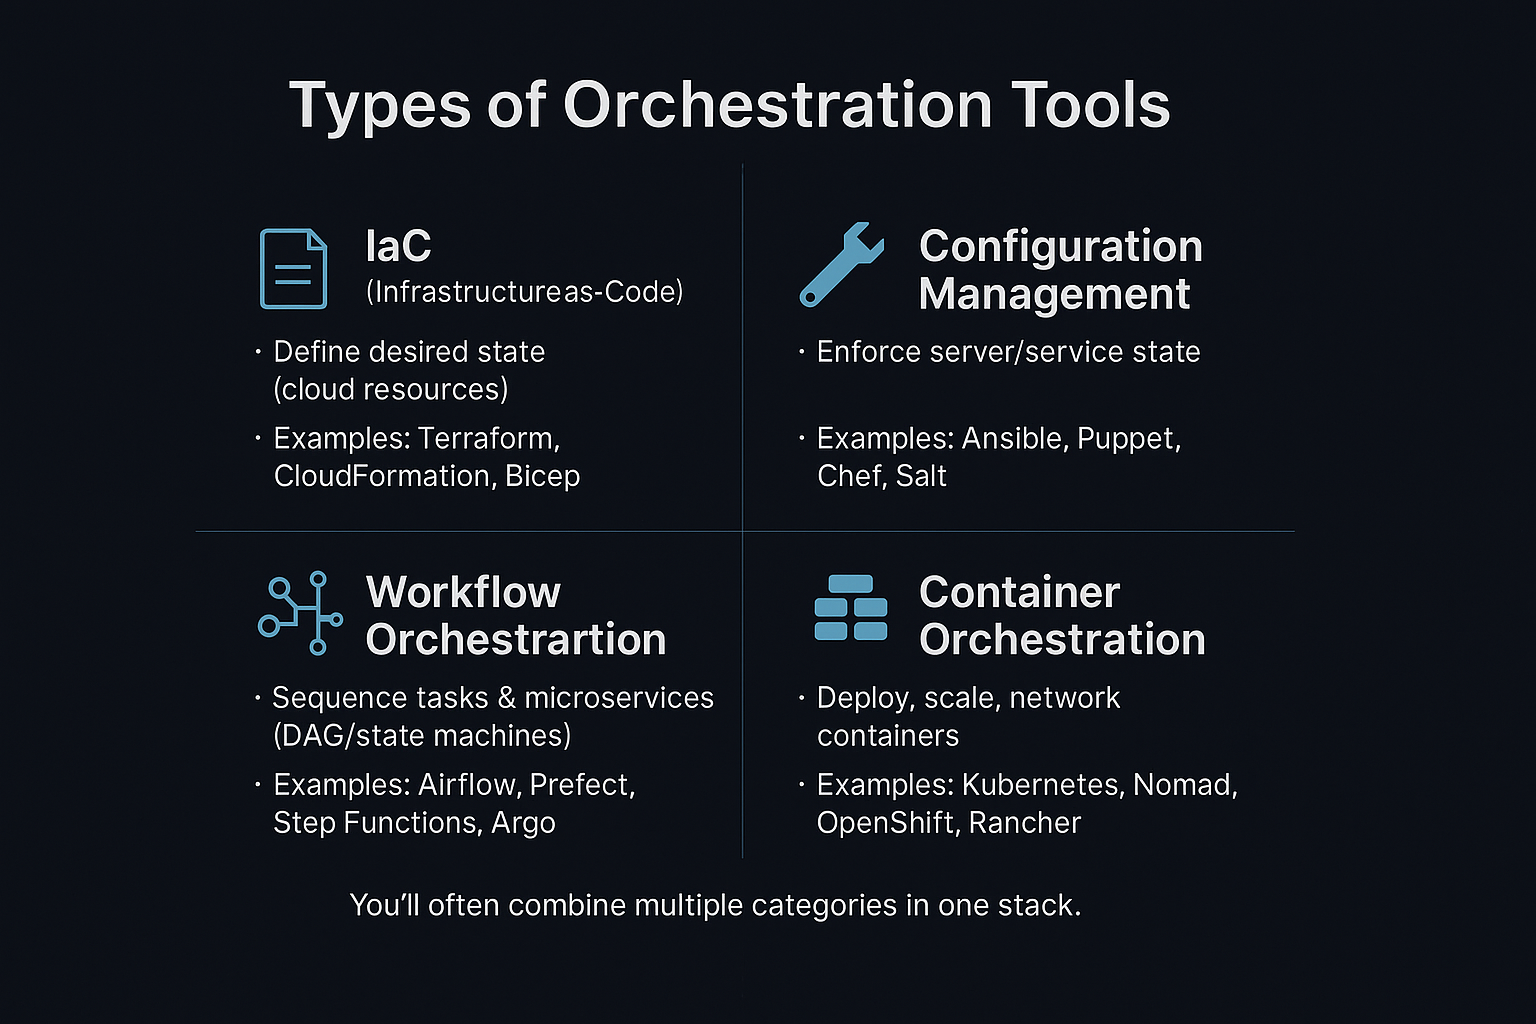
types of orchestration Tools

Top Cloud Orchestration Tools for 2025

In this section we compare the most influential tools across categories. We highlight features, pros and cons, pricing and ideal use cases. While scores of platforms exist, these are the ones dominating conversations in 2025.

Clarifai: AI‑First Orchestration & Model Inference

Why mention Clarifai in a cloud orchestration article? Because AI workloads are increasingly orchestrated across heterogeneous resources—GPUs, CPUs, on‑prem servers and edge devices. Clarifai offers a unique compute orchestration platform that handles model training, fine-tuning, and inference pipelines. Key capabilities:

  • Model orchestration across clouds and hardware. Clarifai orchestrates GPU nodes, CPU fallback, and serverless tasks, automatically selecting the optimal environment based on workload and cost.
  • Local runners. Developers can run models locally or on‑prem for latency-sensitive tasks, then seamlessly scale to the cloud for large‑batch processing.
  • Low‑code pipeline builder. Visual and API-based interfaces allow you to chain data ingestion, preprocessing, model inference, and post-processing using Clarifai’s AI model marketplace plus your own models.
  • Integrated cost control and monitoring. Because compute resources are often expensive, Clarifai provides real‑time metrics and budgets, aligning with FinOps principles.

Ideal for: Organizations deploying AI at scale (image recognition, NLP, generative models) that need to orchestrate compute across cloud and edge. By integrating Clarifai into your orchestration stack, you can handle both infrastructure and model life‑cycle within a single platform.

Kubernetes: The Container King

Primary use: Container orchestration.

  • Features. Declarative configuration; horizontal pod autoscaling; self‑healing; advanced networking; huge ecosystem of operators, service mesh, observability and CI/CD integrations.
  • Strengths. Unmatched scalability and reliability; vendor‑agnostic; strong community; cloud providers offer managed services (EKS, AKS, GKE).
  • Weaknesses. Steep learning curve and operational complexity; resource‑intensive for small projects.
  • Pricing. Control plane is free on Azure AKS and GKE up to a threshold; managed services typically charge ~$0.10 per cluster hour.
  • Ideal for: Large-scale microservices, high availability, multi‑region clusters, AI model serving.

Quick summary & expert tip. If you want the broadest ecosystem and vendor independence, Kubernetes is still the gold standard—but invest in training and managed services to tame complexity.

Docker Swarm: Simplicity First

  • Primary use: Lightweight container orchestration.
  • Features. Native to Docker; simple CLI; automatic load balancing; minimal resource overhead.
  • Strengths. Easy to get started; integrates seamlessly with existing Docker workflows; good for small dev/test clusters.
  • Weaknesses. Limited scalability and enterprise features compared to Kubernetes; ecosystem less vibrant.
  • Pricing. Open source; minimal operational costs.
  • Ideal for: Prototyping, small teams and resource‑constrained environments.

Red Hat OpenShift: Enterprise Kubernetes

  • Features. Based on Kubernetes but adds enterprise‑grade security, built‑in CI/CD (Tekton, OpenShift Pipelines), service mesh and multi‑tenant controls.
  • Strengths. Turnkey solution with opinionated defaults; compliance and governance built in; Red Hat support.
  • Weaknesses. Premium pricing (~$5,000 per core pair annually) and heavy; may feel locked into Red Hat ecosystem.
  • Ideal for: Regulated industries, large enterprises needing reliability and support.

Rancher: Multi‑Cluster Management

  • Features. Centralized management of multiple Kubernetes clusters; RBAC, user interface and pipelines.
  • Strengths. Balances features and usability; cost‑effective relative to OpenShift.
  • Weaknesses. Less enterprise support; still requires underlying Kubernetes expertise.
  • Ideal for: Companies with multiple clusters across on‑prem, edge and cloud.

HashiCorp Nomad: Lightweight and Flexible

  • Features. Schedules containers, VMs and binaries; supports multi‑region clusters; integrates with Consul and Vault.
  • Strengths. Simple architecture; works well for mixed workloads; low operational overhead.
  • Weaknesses. Smaller community; fewer built‑in features compared to Kubernetes.
  • Ideal for: Teams using HashiCorp ecosystem or requiring flexibility across container and VM workloads.

Terraform: Multi‑Cloud Provisioning

  • Category: IaC and orchestration engine.
  • Features. Declarative HCL templates; state management; 200+ providers; modules; remote backend; GitOps integration.
  • Strengths. Cloud‑agnostic; huge ecosystem; fosters collaboration via Terraform Cloud.
  • Weaknesses. Requires understanding of state and module design; limited imperative logic (but modules and functions help).
  • Pricing. Free open source; Terraform Cloud charges after 500 resources.
  • Ideal for: Multi‑cloud provisioning, GitOps workflows, repeatable infrastructure patterns.

Ansible: Agentless Automation

  • Category: Configuration management and orchestration.
  • Features. YAML playbooks; over 5,000 modules; idempotent tasks; push‑based design.
  • Strengths. Quick learning curve; works over SSH without agents; flexible for configuration and app deployment.
  • Weaknesses. Limited state management compared to Puppet/Chef; performance issues at scale.
  • Pricing. Open source; Ansible Automation Platform costs ~$137 per node per year.
  • Ideal for: Rapid automation, cross‑platform tasks, bridging between IaC and application deployment.

Puppet: Compliance‑Focused Configuration

  • Category: Configuration management.
  • Features. Declarative manifest language; agent‑based; strong compliance and reporting.
  • Strengths. Mature; ideal for large enterprises; integrates with ServiceNow and incident management.
  • Weaknesses. Steeper learning curve; centralised master can be a bottleneck.
  • Pricing. Puppet Enterprise around ~$199 per node per year.
  • Ideal for: Regulated environments requiring auditable change management.

Chef, SaltStack and Other Config Tools

Chef’s Ruby‑based approach offers high flexibility but demands Ruby knowledge. SaltStack’s event‑driven architecture delivers fast parallel execution; however, its initial configuration is complex. Each of these tools has passionate communities and is suitable for particular use cases (e.g., large HPC clusters or event-driven operations).

CloudBolt, Morpheus and Scalable Orchestration Platforms

Beyond open‑source tools, enterprise platforms like CloudBolt, Morpheus, Cycle.io and Spacelift offer orchestration as a service. They typically provide UI‑driven workflows, policy engines, cost management and plug‑ins for various clouds. CloudBolt emphasises governance and self-service provisioning, while Spacelift layers policy-as-code and compliance on top of Terraform. These platforms are worth considering for organisations that need guardrails, FinOps and RBAC without building custom frameworks.

Quick Summary of Top Tools

Tool

Category

Strengths

Weaknesses

Ideal Use

Pricing (approx.)

Kubernetes

Container

Unmatched ecosystem, scaling, reliability

Complex, resource‑intensive

Large microservices, AI serving

Managed clusters ~$0.10/hour per cluster

Nomad

Container/VM

Lightweight, supports VMs & binaries

Smaller community

Mixed workloads

Open source

Terraform

IaC

Cloud‑agnostic, 200+ providers

State management complexity

Multi‑cloud provisioning

Free; Cloud plan variable

Ansible

Config

Agentless, low learning curve

Scale limitations

Rapid automation

Free; ~137/node/year

Puppet

Config

Compliance & reporting

Agent overhead

Regulated enterprises

~199/node/year

CloudBolt

Enterprise

Self-service, governance

Licensing cost

Enterprises needing guardrails

Proprietary

Clarifai

AI orchestration

Model/compute orchestration, local runners

Domain-specific

AI pipelines

Usage-based


Expert Tips

  • Start with declarative tools. Terraform or CloudFormation provide baseline consistency; layering Ansible or SaltStack adds configuration nuance.
  • Adopt managed services. Use EKS, AKS or GKE for Kubernetes to reduce operational burden; similarly, Clarifai handles compute orchestration so you can focus on models.
  • Consider FinOps. Tools like CloudBolt and Clarifai’s cost controls help align resource usage with budgets.

Leading Tools & Platforms: Deep Dive

Beyond the summary above, let’s explore additional players shaping the orchestration ecosystem.

Crossplane & GitOps Controllers

Crossplane is an open‑source framework that extends Kubernetes with Custom Resource Definitions (CRDs) to manage cloud infrastructure. It decouples the control plane from the data plane, allowing you to define cloud resources as Kubernetes objects. By embracing GitOps, Crossplane brings infrastructure and application definitions into a single repository and ensures drift reconciliation. It competes with Terraform and is gaining popularity for Kubernetes‑native environments.

Spacelift & Scalr: Policy‑as‑Code Platforms

Spacelift and Scalr build on top of Terraform and other IaC engines, adding enterprise features like RBAC, cost controls, drift detection, and policy‑as‑code (Open Policy Agent). Scalr’s article emphasises that the orchestration market is growing because companies demand such governance layers. These tools are suited to organisations with multiple teams and compliance requirements.

Morpheus & CloudBolt: Unified Cloud Management

These platforms provide unified dashboards to orchestrate resources across private and public clouds, integrate with service catalogs (e.g., ServiceNow), and manage lifecycle operations. CloudBolt, for instance, emphasises governance, self‑service provisioning and automation. Morpheus extends this with cost analytics, network automation and plugin frameworks.

Prefect & Airflow: Modern Workflow Engines

While Airflow has long been the standard for data pipelines, Prefect offers a more modern design with emphasis on asynchronous tasks, Pythonic workflow definitions and dynamic DAG generation. They support hybrid deployment (cloud and self-hosted), concurrency and retries. Dagster and Luigi are additional options with strong type systems and data orchestration features.

Argo CD & Flux: GitOps for Kubernetes

Argo CD and Flux implement GitOps principles, continuously reconciling the actual state of Kubernetes clusters with definitions in Git. They integrate with Argo Workflows for CI/CD and support automated rollbacks, progressive delivery and observability. This automation ensures that clusters remain in desired state, reducing configuration drift.

AI‑Focused Platforms: Flyte, Kubeflow & Clarifai

AI workloads pose unique challenges: data preprocessing, model training, hyperparameter tuning, deployment and monitoring. Kubeflow extends Kubernetes with ML pipelines and experiment tracking; Flyte orchestrates data, model training and inference across multi‑cloud; Clarifai simplifies this further by offering pre‑built AI models, model customization and compute orchestration all under one roof. In 2025, AI teams increasingly adopt these domain‑specific orchestrators to accelerate research and productionisation.

Edge & IoT Orchestration

As sensors and devices proliferate, orchestrating workloads at the edge becomes crucial. Lightweight distributions like K3s, KubeEdge and OpenYurt enable Kubernetes on resource‑constrained hardware. Azure IoT Hub and AWS IoT Greengrass extend orchestration to device management and event processing. Clarifai’s local runners also support inference on edge devices for low‑latency computer vision tasks.

Best Practices for Cloud Orchestration & Microservice Deployment

  1. Design for Failure. Assume that components will fail; implement retries, timeouts and circuit breakers. Use chaos engineering to test resilience.
  2. Adopt Declarative and Idempotent Definitions. Use IaC and Kubernetes manifests; avoid imperative scripts. This ensures reproducibility and drift detection.
  3. Implement GitOps & Policy‑as‑Code. Store all config and policies in Git; use tools like OPA (Open Policy Agent) to enforce RBAC, naming conventions and cost limits.
  4. Use Service Discovery & Centralize Secrets. Tools like Consul or etcd maintain service endpoints; secret managers (Vault, AWS Secrets Manager) avoid hardcoding credentials.
  5. Leverage Observability & Tracing. Integrate metrics, logs and traces; adopt distributed tracing to debug workflows. Use dashboards and alerting for proactive monitoring.
  6. Right‑Size Complexity. Scalr advises to match orchestration complexity to real needs, balancing self‑hosted vs. managed services. Don’t adopt Kubernetes for simple workloads if Docker Swarm suffices.
  7. Secure by Design. Embrace zero‑trust principles and encryption in transit and at rest. Use identity federation (OIDC) for authentication; implement least privilege RBAC. Scalr notes that security orchestration is growing to $8.5 billion by 2030 with zero trust models becoming standard.
  8. Focus on Cost Optimisation. Use autoscaling, rightsizing and spot instances. Tools like CloudBolt or Clarifai integrate cost dashboards to prevent bill shock.
  9. Train & Upskill Teams. Provide training on IaC, Kubernetes and GitOps; invest in cross-functional DevOps capabilities.
  10. Plan for Edge & AI. Evaluate K3s, Flyte and Clarifai if your workloads involve IoT or AI; design for data locality and latency.

Quick Summary: What are the Best Practices for Cloud Orchestration & Microservice deployment? Use declarative configs, GitOps, and observability tools; design for failure; enforce security with zero-trust; and right-size complexity to your organization’s maturity.

Use Cases & Real‑World Examples

Retail & E‑Commerce

A global retailer uses cloud orchestration to manage seasonal traffic spikes. Using Terraform and Kubernetes, they provision additional nodes and deploy microservices that handle checkout, inventory and recommendations. Workflow orchestrators like Step Functions manage order processing: verifying payment, reserving stock and triggering shipping services. By codifying these workflows, the retailer scales reliably during Black Friday and reduces cart abandonment due to downtime.

Financial Services & Governance

A bank must comply with stringent regulations. It adopts Puppet for configuration management and OpenShift for container orchestration. IaC templates enforce encryption, network policies and drift detection; policy‑as‑code ensures only approved resources are created. Workflows orchestrate risk analysis, fraud detection and KYC checks, integrating with AI models for anomaly detection. The result: faster loan approvals while maintaining compliance.

Data Pipelines & ETL

A media company ingests petabytes of streaming data. Airflow orchestrates extraction from streaming services, transformation via Spark on Kubernetes and loading into a data warehouse. Prefect monitors for failures and re-runs tasks. The company uses Terraform to provision data clusters on demand and scales down after processing. This architecture enables near‑real‑time analytics and personalised recommendations.

AI Model Serving & Computer Vision

A logistics firm uses Clarifai to orchestrate computer vision models that detect damaged packages. When a package image arrives from a warehouse camera, Clarifai’s pipeline triggers preprocessing (resize, normalize), runs a detection model on the optimal GPU or CPU, flags anomalies and writes results to a database. The orchestrator scales across cloud and on‑prem GPUs, balancing cost and latency. With local runners at warehouses, inference happens in milliseconds, reducing shipping errors and returns.

IoT & Edge Manufacturing

An industrial manufacturer deploys sensors on factory equipment. Using K3s on small edge servers, the company runs microservices for sensor ingestion and anomaly detection. Nomad orchestrates workloads across x86 and ARM devices. Data is aggregated and processed at the edge, with only insights sent to the cloud. This reduces bandwidth, meets latency requirements and improves uptime.

Emerging Trends & Future of Cloud Orchestration

The next few years will reshape orchestration as AI and cloud technologies converge.

AI‑Driven Orchestration

Scalr notes that AI/ML integration is a key growth driver. We are seeing smart orchestrators that use machine learning to predict load, optimise resource placement and detect anomalies. For example, Ansible Lightspeed assists in writing playbooks using natural language, and Kubernetes Autopilot automatically tunes clusters. AI agents are emerging that can design workflows, adjust scaling policies and remediate incidents without human intervention. This trend will accelerate as generative AI and large language models mature.

Edge & Hybrid Cloud Expansion

Edge computing is becoming mainstream. Scalr emphasises that next‑generation orchestration extends beyond data centres to edge environments with lightweight distributions like k3s. Orchestrators must handle intermittent connectivity, limited resources and diverse hardware. Tools like KubeEdge, AWS Greengrass, Azure Arc and Clarifai’s local runners enable consistent orchestration across edge and cloud.

 By 2027, 50% of enterprise-managed data will be created and processed at the edge (Gartner).

Security-as-Code & Zero Trust

Security orchestration is projected to become an $8.5 billion market by 2030. Zero‑trust architectures treat every connection as untrusted, enforcing continuous verification. Orchestrators will embed security policies at every step—encryption, token rotation, vulnerability scanning and runtime protection. Policy‑as‑code will become mandatory.

Serverless & Event‑Driven Architectures

Serverless computing offloads infrastructure management. Orchestrators like Step Functions, Azure Durable Functions and Google Cloud Workflows handle event-driven flows with minimal overhead. As serverless matures, we’ll see hybrid orchestration that combines containers, VMs, serverless and edge functions seamlessly.

Low/No‑Code Orchestration

Businesses want to democratise automation. Low‑code platforms (e.g., Mendix, OutSystems) and no‑code workflow builders are emerging for non‑developers. Clarifai’s visual pipeline editor is an example. Expect more drag‑and‑drop interfaces with AI‑powered suggestions and natural language prompts for building workflows.

FinOps & Sustainable Orchestration

Cloud costs are a major challenge—84 % of organisations cite cloud spend management as significant. Orchestrators will integrate cost analytics, predictive budgeting and sustainability metrics. Green computing considerations (e.g., selecting regions with renewable energy) will influence scheduling decisions.

Quick Insight: By 2025, 65% of enterprises will integrate AI/ML pipelines with cloud orchestration platforms (IDC).
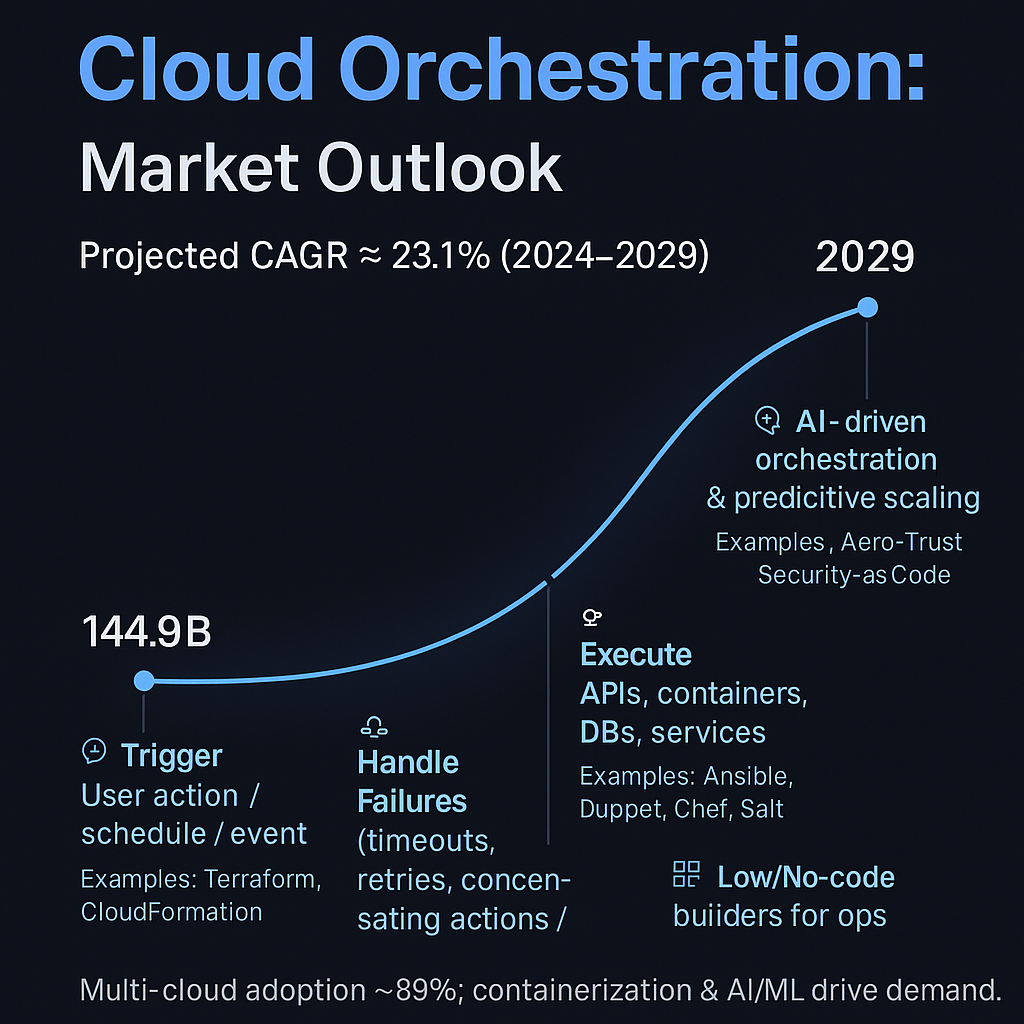
Cloud Orchestration Market Outlook

Clarifai’s Approach to Cloud & AI Orchestration

Clarifai is best known as an AI platform, but its compute orchestration capabilities make it a compelling choice for AI‑driven organisations. Here’s how Clarifai stands out:

  1. Unified AI & Infrastructure Orchestration. Clarifai orchestrates not only model inference but also the underlying compute resources. It abstracts away GPU/CPU clusters, letting you specify latency or cost constraints and automatically selecting the right hardware.
  2. Model Marketplace & Customization. Users can mix pre‑trained models (vision, NLP) with their own fine‑tuned models. Orchestration pipelines handle data ingestion, feature extraction, model invocation and post‑processing. The platform supports multi‑modal tasks (e.g., text + image) and chain of prompts for generative AI.
  3. Local Runners & Edge Support. For low‑latency tasks, Clarifai runs models on edge devices or on‑prem servers. The orchestrator ensures that data stays local when required and synchronises results to the cloud when connectivity allows.
  4. Low‑Code Experience. A visual pipeline builder allows business users to build AI workflows by connecting blocks; developers can extend with Python or REST APIs. This democratizes AI orchestration.
  5. Security & Compliance. Clarifai meets enterprise requirements with encryption, RBAC and audit logs. The platform can be deployed in secure environments for sensitive data.

By integrating Clarifai into your orchestration strategy, you can handle both infrastructure and AI workflows holistically—important as AI becomes core to every digital business.

Quick Insight: AI orchestration platforms like Clarifai enable teams to deploy multi-model AI pipelines up to 5x faster compared to manual orchestration 

Getting Started: Step‑by‑Step Guide to Implementing Orchestration

1. Assess Your Needs & Goals

Identify pain points: Are deployments slow? Do you need multi‑cloud portability? Do data pipelines fail frequently? Clarify business outcomes (e.g., faster releases, cost reduction, better reliability). Determine which workloads require orchestration (infrastructure, configuration, data, AI, edge).

2. Choose the Right Categories of Tools

Select IaC (e.g., Terraform, CloudFormation) for infrastructure provisioning. Add configuration management (Ansible, Puppet) for server state. Use workflow orchestrators (Airflow, Prefect, Step Functions) for multi‑step processes. Adopt container orchestrators (Kubernetes, Nomad) for microservices. If you have AI workloads, evaluate Clarifai or Kubeflow.

3. Design Contracts & Templates

Write declarative templates using HCL, YAML or JSON. Version them in Git. Define naming conventions, tagging policies and resource hierarchies. For microservices, design APIs and adopt the single responsibility principle—each service handles one function. Document expected inputs/outputs and error conditions.

4. Build & Test Workflows

Start with simple pipelines—provision a VM, deploy an app, run a database migration. Use CI/CD to validate changes automatically. Add error handling and timeouts. For data pipelines, visualise DAGs to identify bottlenecks. For AI, build sample inference workflows with Clarifai.

5. Integrate Observability & Policy

Set up monitoring (Prometheus, Datadog) and distributed tracing (OpenTelemetry). Define policies for security (IAM roles, secrets), cost limits and environment naming. Tools like Scalr or Spacelift can enforce policies automatically. Clarifai offers built‑in monitoring for AI pipelines.

6. Automate Security & Compliance

Integrate vulnerability scanning (e.g., Trivy), secret rotation and configuration compliance checks into workflows. Adopt zero‑trust models: treat every component as potentially compromised. Use network policies and micro‑segmentation.

7. Iterate & Scale

Continuously evaluate workflows, identify bottlenecks and add optimisations (e.g., autoscaling, caching). Extend pipelines to new teams and services. For cross‑cloud expansion, ensure templates abstract providers. For edge use cases, adopt K3s or Clarifai’s local runners. Train teams and gather feedback.

8. Explore AI‑Driven Enhancements

Leverage AI to generate templates, detect anomalies and recommend cost optimisations. Keep an eye on emerging open‑source projects like OpenAI’s function calling, LangChain for connecting LLMs to orchestration workflows, and research from fluid.ai on agentic orchestration for self‑healing systems.

FAQs on Cloud Orchestration

  1. How is cloud orchestration different from automation?

Automation refers to executing individual tasks without human intervention, such as creating a VM. Orchestration coordinates multiple tasks into a structured workflow. DataCamp explains that orchestration combines steps into end‑to‑end processes that span multiple services and clouds.

  1. Which category of orchestration tool should I start with?

It depends on your needs: start with IaC (Terraform, CloudFormation) for infrastructure provisioning; add configuration management (Ansible, Puppet) to enforce server state; use workflow orchestrators (Airflow, Step Functions) to manage dependencies; and adopt container orchestrators (Kubernetes) for microservices. Often, you’ll use several together.

  1. Are managed services worth the cost?

Yes, if you value reduced operational burden and reliability. Managed Kubernetes (EKS, AKS, GKE) charges around $0.10 per cluster hour, but frees teams to focus on apps. Managed Clarifai pipelines handle model scaling and monitoring. However, weigh vendor lock‑in and custom requirements.

  1. How do I handle multi‑cloud governance?

Adopt IaC to abstract provider differences. Use platforms like Scalr, Spacelift or CloudBolt to enforce policies across clouds. Implement tagging, cost budgets and policy‑as‑code. Tools like Clarifai also offer cost dashboards for AI workloads. Security frameworks (e.g., FedRAMP, ISO) should be encoded into templates.

  1. What role does AI play in orchestration?

AI enables predictive scaling, anomaly detection, natural language playbook generation and autonomous remediation. Scalr highlights AI/ML integration as a key growth driver. Tools like Ansible Lightspeed and Clarifai’s pipeline builder incorporate generative AI to simplify configuration and optimize performance.

  1. Do I need Kubernetes for every application?

No. Kubernetes is powerful but complex. If your workloads are simple or resource-constrained, consider Docker Swarm, Nomad, or managed services. As Scalr advises, match orchestration complexity to your actual needs.

  1. What trends should I watch in 2025 and beyond?

Key trends include AI‑driven orchestration, edge computing expansion, security‑as‑code and zero‑trust architectures, serverless/event‑driven workflows, low/no‑code platforms, and FinOps integration. Generative AI will increasingly assist in building and managing workflows, while sustainability considerations will influence resource scheduling.


Conclusion

Cloud orchestration is the backbone of modern digital operations, enabling consistency, speed, and innovation across multi‑cloud, microservice, and AI environments. By understanding the categories of tools and their strengths, you can design an orchestration strategy that aligns with your goals. Kubernetes, Terraform, Ansible, and Clarifai represent different layers of the stack—containers, infrastructure, configuration, and AI—each essential for a complete solution. Future trends such as AI‑driven resource optimization, edge computing, and zero‑trust security will continue to redefine what orchestration means. Embrace declarative definitions, policy‑as‑code, and continuous learning to stay ahead.


Benchmarking Speed, Scale, and Cost Efficiency


11.8_blog_hero (1)

This blog post focuses on new features and improvements. For a comprehensive list, including bug fixes, please see the release notes.

GPT-OSS-120B: Benchmarking Speed, Scale, and Cost Efficiency

Artificial Analysis has benchmarked Clarifai’s Compute Orchestration with the GPT-OSS-120B model—one of the most advanced open-source large language models available today. The results underscore Clarifai as one of the top hardware and GPU-agnostic engines for AI workloads where speed, flexibility, efficiency and reliability matter most. 

What the benchmark shows (P50, last 72h; single query, 1k-token prompt):

  • High throughput: 313 output tokens per second—among the very fastest measured in this configuration.

  • Low latency: 0.27s time-to-first-token (TTFT), so responses begin streaming almost instantly.

  • Compelling price/performance: Placed in the benchmark’s “most attractive quadrant” (high speed + low price).

Pricing that scales:

Clarifai offers GPT-OSS-120B at $0.09 per 1M input tokens and $0.36 per 1M output tokens. Artificial Analysis displays a blended price (3:1 input:output) of just $0.16 per 1M tokens, placing Clarifai significantly below the $0.26–$0.28 cluster of competitors while matching or exceeding their performance.

Below is a comparison of output speed versus price across major providers for GPT-OSS-120B. Clarifai stands out in the “most attractive quadrant,” combining high throughput with competitive pricing.

Output Speed vs Price (10 Sep 25)  (2)

Output Speed vs. Price

This chart compares latency (time to first token) against output speed. Clarifai demonstrates one of the lowest latencies while maintaining top-tier throughput—placing it among the best-in-class providers.

Latency vs Output Speed (10 Sep 25)  (1)

Latency vs. Output Speed

Why GPT-OSS-120B Matters

As one of the leading open-source “GPT-OSS” models, GPT-OSS-120B represents the growing demand for transparent, community-driven alternatives to closed-source LLMs. Running a model of this scale requires infrastructure that can not only deliver high speed and low latency, but also keep costs under control at production scale. That’s exactly where Clarifai’s Compute Orchestraction makes a difference.

Why This Benchmark Matters

These results are more than numbers—they show how Clarifai has engineered every layer of the stack to optimize GPU utilization. With CO, multiple models can run on the same GPUs, workloads scale elastically, and enterprises can squeeze more value out of every accelerator. The payoff is fast, reliable, and cost-efficient inference that can support both experimentation and large-scale deployment.

Check the full benchmarks on Artificial Analysis here. 

Here’s a quick demo of how to access the GPT-OSS-120B model in the Playground.

Local Runners

Local Runners let you develop and run models on your own hardware—laptops, workstations, edge boxes—while making them callable through Clarifai’s cloud API. Clarifai handles the public URL, routing, and authentication; your model executes locally and your data stays on your machine. It behaves like any other Clarifai‑hosted model.

Why teams use Local Runners

  • Build where your data and tools live. Keep models close to local files, internal databases, and OS‑level utilities.

  • No custom networking. Start a runner and get a public URL—no port‑forwarding or reverse proxies.

  • Use your own compute. Bring your GPUs and custom setups; the platform still provides the API, workflows, and governance around them.

New: Ollama Toolkit (now in the CLI)

We’ve added an Ollama Toolkit to the Clarifai CLI so you can initialize an Ollama‑backed model directory in one command (and choose any model from the Ollama library). It pairs perfectly with Local Runners—download, run, and expose an Ollama model via a public API with a minimal setup.

The CLI supports --toolkit ollama plus flags like --model-name, --port, and --context-length, making it trivial to target specific Ollama models.

Example workflow: run Gemma 3 270M or GPT‑OSS- 20B locally and serve it through a public API

  1. Pick a model in Ollama.

    • Gemma 3 270M (tiny, fast; 32K context): gemma3:270m. 

    • GPT‑OSS 20B (OpenAI open‑weight, optimized for local use): gpt-oss:20b. 

  2. Initialize the project with the Ollama Toolkit.
    Use the command above, swapping --model-name for your pick (e.g., gpt-oss:20b). This will create a new model directory structure that is compatible with the Clarifai platform. You can customize or optimize the generated model by modifying the 1/model.py file as needed.

  3. Start your Local Runner.
    From the model directory:


    The runner registers with Clarifai and exposes your local model via a public URL; the CLI prints a ready‑to‑run client snippet. 

  4. Call it like any Clarifai model.
    For example (Python SDK):

    Behind the scenes, the API call is routed to your machine; results return to the caller over Clarifai’s secure control plane.


Deep dive: We published a step‑by‑step guide that walks through running Ollama models locally and exposing them with Local Runners. Check it out here.

Try it on the Developer Plan

You can start for free, or use the Developer Plan—$1/month for the first year—which includes up to 5 Local Runners and unlimited runner hours.

Check out the full example and setup guide in the documentation here.

Billing

We’ve made billing more transparent and flexible with this release. Monthly spending limits have been introduced: $100 for Developer and Essential plans, and $500 for the Professional plan. If you need higher limits, you can reach out to our team.

We’ve also added a new credit card pre-authorization process. A temporary charge is applied to verify card validity and available funds — $50 for Developer, $100 for Essential, and $500 for Professional plans. The amount is automatically refunded within seven days, ensuring a seamless verification experience.

Control Center

  • The Control Center gets even more flexible and informative with this update. You can now resize charts to half their original size on the configure page, making side-by-side comparisons smoother and layouts more manageable.
  • Charts are smarter too: the Stored Inputs Cost chart now correctly shows the average cost for the selected period, while longer date ranges automatically display weekly aggregated data for easier readability. Empty charts display meaningful messages instead of zeros, so you always know when data isn’t available.
  • We’ve also added cross-links between compute cost and usage charts, making it simple to navigate between these views and get a complete picture of your AI infrastructure.

Additional Changes 

  • Python SDK: Fixed Local Runner CLI command, updated protocol and gRPC versions, integrated secrets, corrected num_threads defaults, added stream_options validation, prevented downloading original checkpoints, improved model upload and deployment, and added user confirmation to prevent Dockerfile overwrite during uploads.
    Check all SDK updates here.
  • Platform Updates: Added a public resource filter to quickly view Community-shared resources, improved Playground error messaging for streaming limits, and extended login session duration for Google and GitHub SSO users to seven days.
    Find all platform changes here.

Ready to start building?

With Local Runners, you can now serve models, MCP servers, or agents directly from your own hardware without uploading model weights or managing infrastructure. It’s the fastest way to test, iterate, and securely run models from your laptop, workstation, or on-prem server. You can read the documentation to get started, or check out the blog to see how to run Ollama models locally and expose them via a public API.


How to Turn Employee AI Use into a Strategic Advantage with Brian Madden [MAICON 2025 Speaker Series]


MAICON brings together top visionaries and experts in the field of AI during a three-day conference packed with actionable sessions and networking events—all to position you as the change agent your organization (and career) needs. In this ongoing speaker series, we’re featuring these extraordinary leaders, with forward-looking predictions, actionable tips you can use today, and a preview of their MAICON 2025 sessions. Continue reading “How to Turn Employee AI Use into a Strategic Advantage with Brian Madden [MAICON 2025 Speaker Series]”

How to Run AI Models Locally (2025): Tools, Setup & Tips


Running AI models on your machine unlocks privacy, customization, and independence. In this in‑depth guide, you’ll learn why local AI is important, the tools and models you need, how to overcome challenges, and how Clarifai’s platform can help you orchestrate and scale your workloads. Let’s dive in!

Quick Summary

Local AI lets you run models entirely on your hardware. This gives you full control over your data, reduces latency, and often lowers costs. However, you’ll need the right hardware, software, and strategies to tackle challenges like memory limits and model updates.

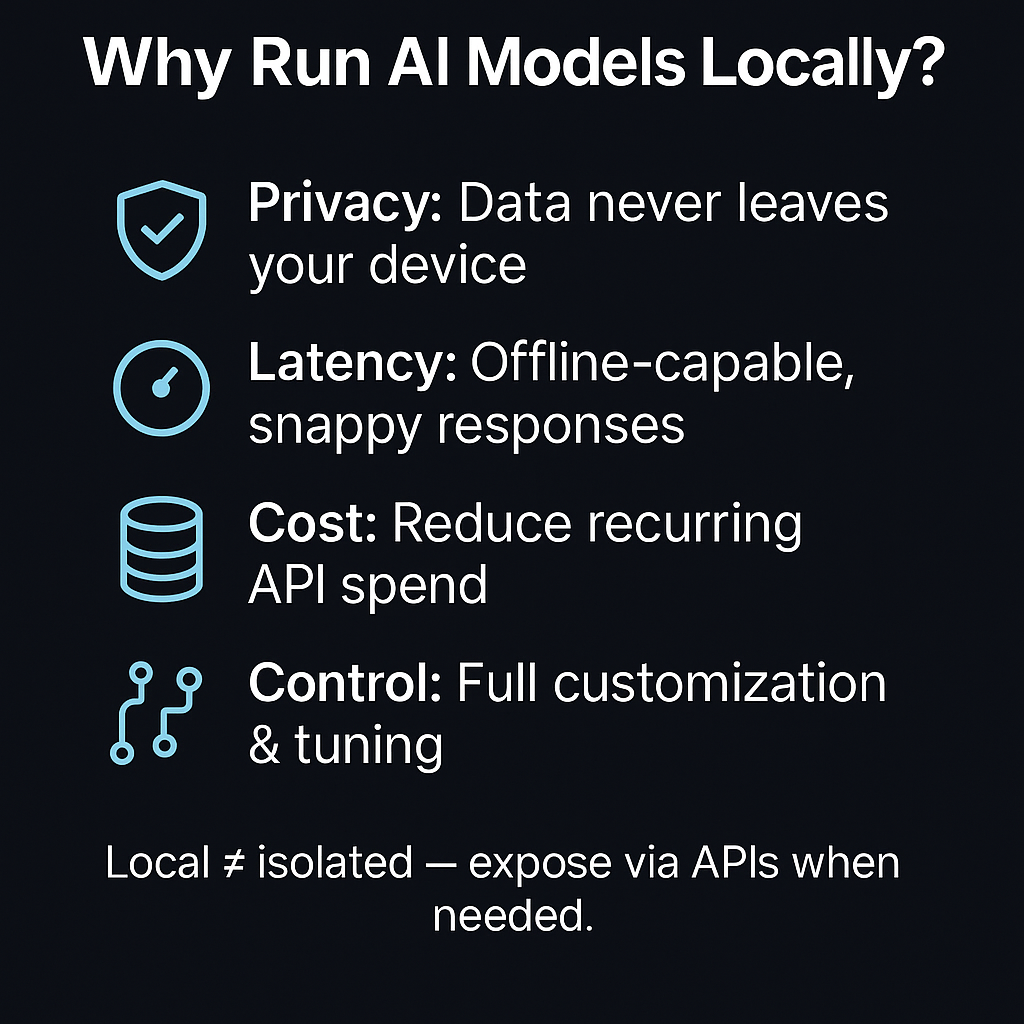
Why Run AI Models Locally?

There are many great reasons to run AI models on your own computer:

  1. Data Privacy
    Your data never leaves your computer, so you don’t have to worry about breaches, and you meet stringent privacy rules.
  2. Offline Availability
    You don’t have to worry about cloud availability or internet speed when working offline.
  3. Cost Savings
    You can stop paying for cloud APIs and run as many inferences as you want without extra cost.
  4. Full Control
    Local settings let you make small changes and adjustments, giving you control over how the model works.

Pros and Cons of Local Deployment

While local deployment offers many benefits, there are pros and cons:

  • Hardware Limitations: If your hardware isn’t powerful enough, some models can’t be executed.
  • Resource Needs: Huge models require powerful GPUs and a lot of RAM.
  • Dependency Management: You must track program dependencies and handle updates yourself.
  • Energy Usage: If models run continuously, they can consume significant energy.

Expert Insight

AI researchers highlight that the appeal of local deployment stems from data ownership and reduced latency. A Mozilla.ai article notes that hobbyist developers and security‑conscious teams prefer local deployment because the data never leaves their device and privacy remains uncompromised.

Quick Summary:

Local AI is ideal for those who prioritize privacy, control, and cost efficiency. Be aware of the hardware and maintenance requirements, and plan your deployments accordingly.

Why run Ai Models Locally


What You Need Before Running AI Models Locally

Before you start, ensure your system can handle the demands of modern AI models.

Hardware Requirements

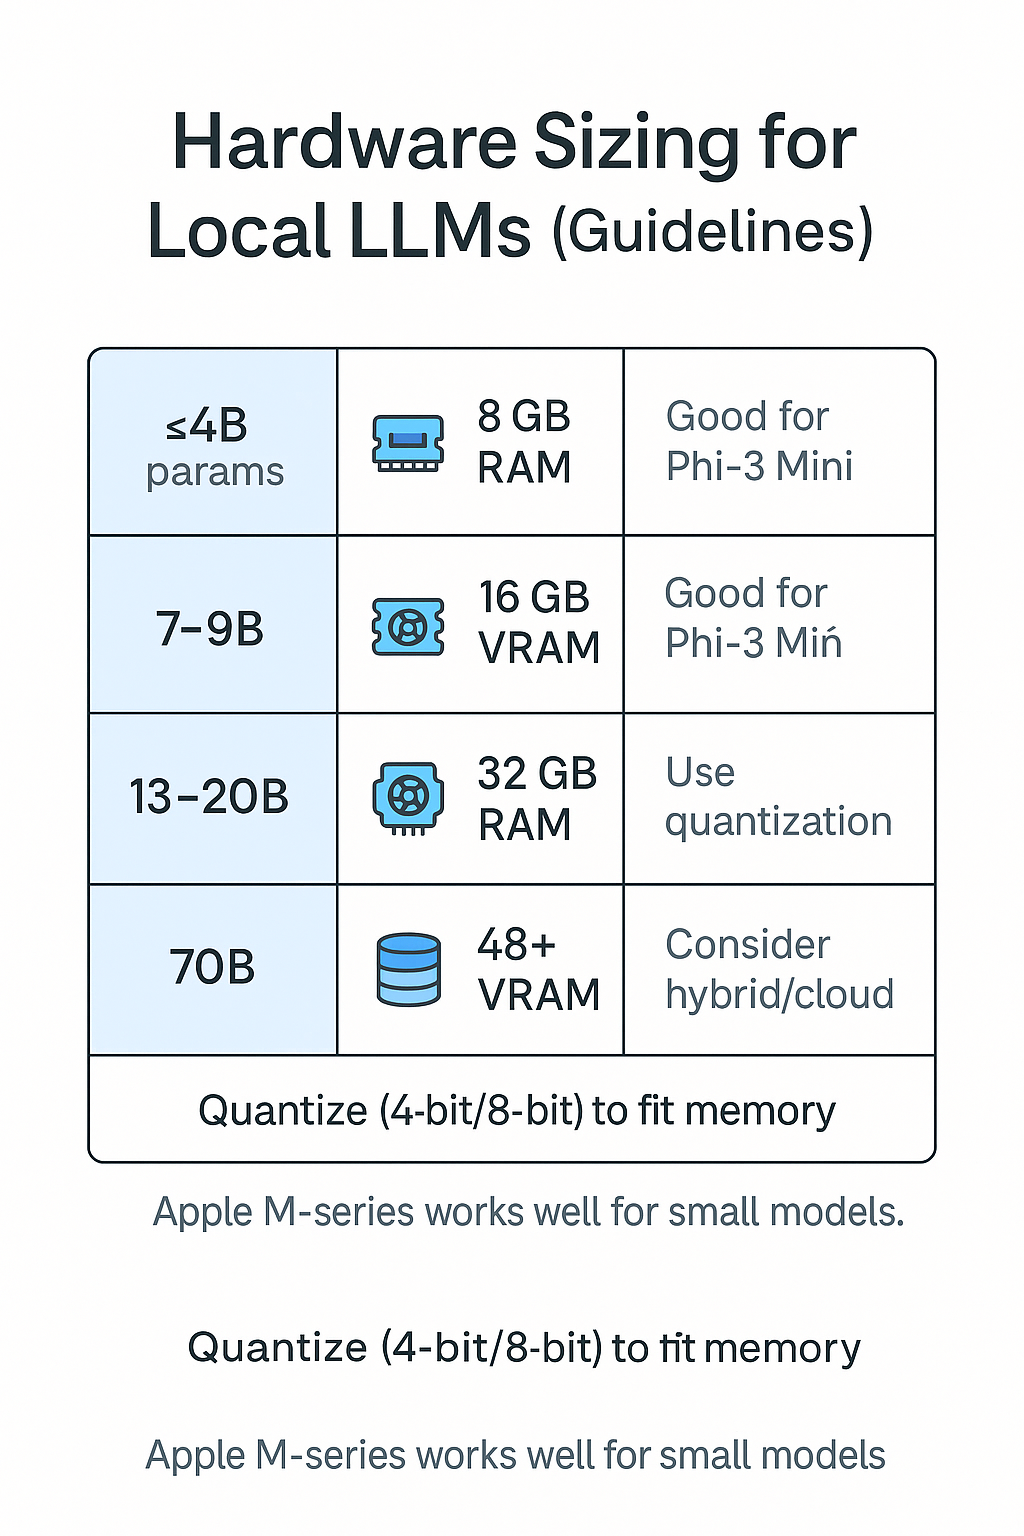
  • CPU & RAM: For smaller models (under 4B parameters), 8 GB RAM may suffice; larger models like Llama 3 8B require around 16 GB RAM.
  • GPU: An NVIDIA GTX/RTX card with at least 8–12 GB of VRAM is recommended. GPUs accelerate inference significantly. Apple M‑series chips work well for smaller models due to their unified memory architecture.
  • Storage: Model weights can range from a few hundred MB to several GB. Leave room for multiple variants and quantized files.

Software Prerequisites

  • Python & Conda: For installing frameworks like Transformers, llama.cpp, or vLLM.
  • Docker: Useful for isolating environments (e.g., running LocalAI containers).
  • CUDA & cuDNN: Required for GPU acceleration on Linux or Windows.
  • llama.cpp / Ollama / LM Studio: Choose your preferred runtime.
  • Model Files & Licenses: Ensure you adhere to license terms when downloading models from Hugging Face or other sources.

Note: Use Clarifai’s CLI to upload external models: the platform allows you to import pre‑trained models from sources like Hugging Face and integrate them seamlessly. Once imported, models are automatically deployed and can be combined with other Clarifai tools. Clarifai also offers a marketplace of pre-built models in its community.

 Expert Insight

Community benchmarks show that running Llama 3 8B on mid‑range gaming laptops (RTX 3060, 16 GB RAM) yields real‑time performance. For 70B models, dedicated GPUs or cloud machines are necessary. Many developers use quantized models to fit within memory limits (see our “Challenges” section).

Quick Summary

Invest in adequate hardware and software. An 8B model demands roughly 16 GB RAM, while GPU acceleration dramatically improves speed. Use Docker or conda to manage dependencies and check model licenses before use.

Hardware Sizing for Local LLMs


How to Run a Local AI Model: Step‑By‑Step

Running an AI model locally isn’t as daunting as it seems. Here’s a general workflow.

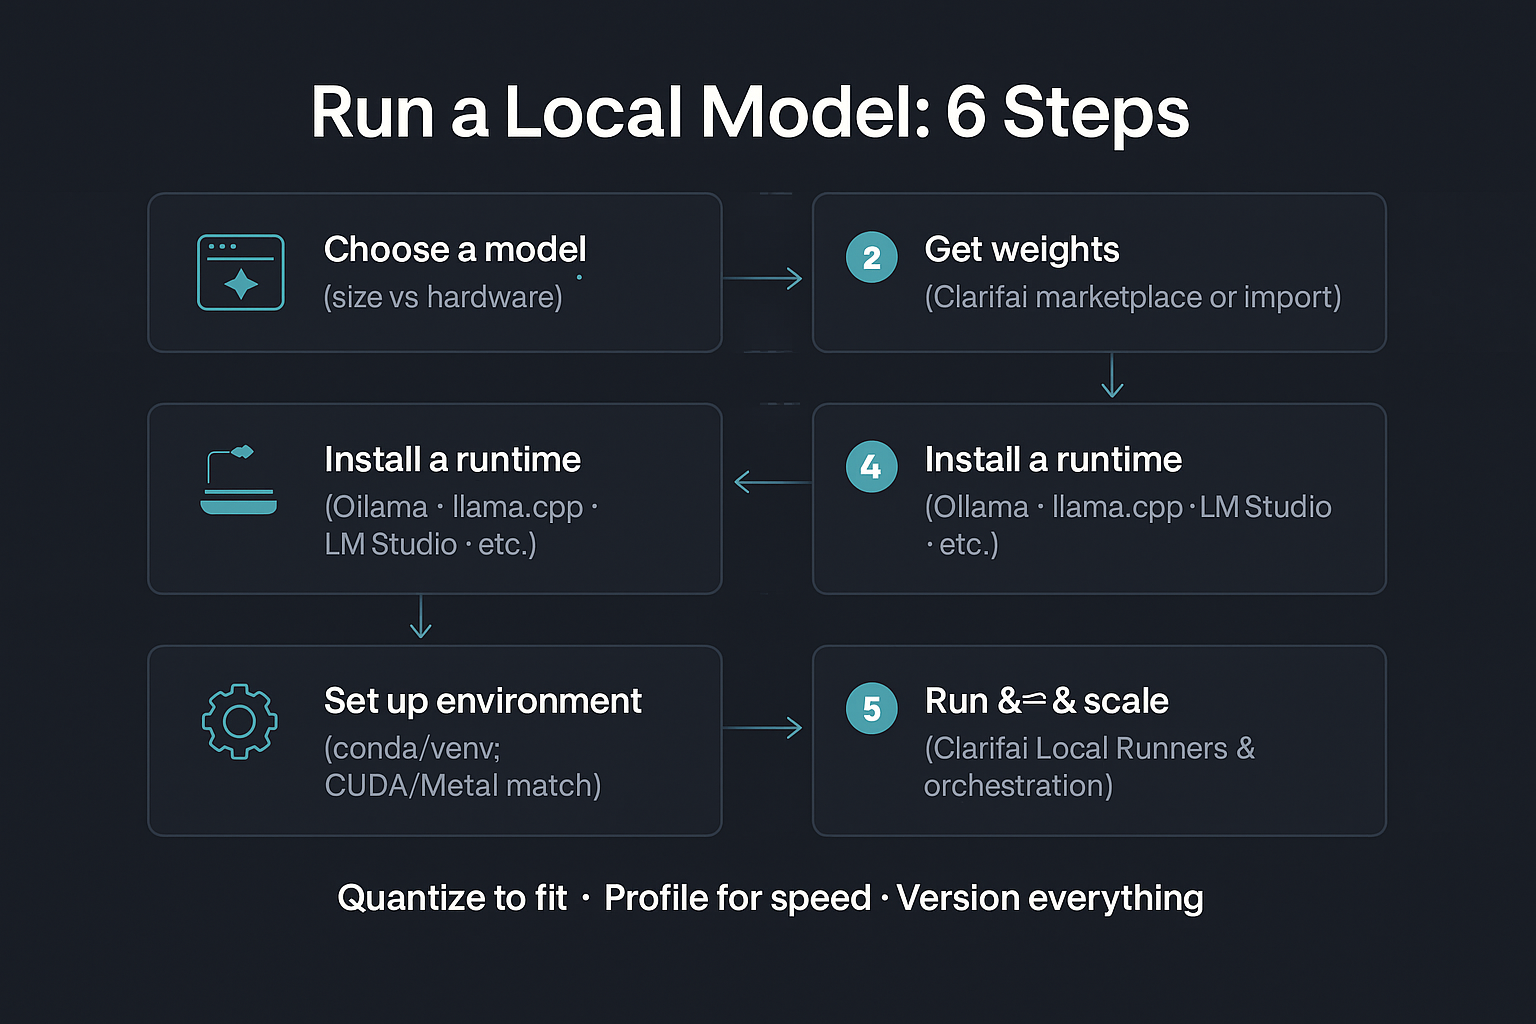
1. Choose Your Model

Decide whether you need a lightweight model (like Phi‑3 Mini) or a larger one (like Llama 3 70B). Check your hardware capability.

  1. Download or import the model:
  • Instead of defaulting to Hugging Face, browse Clarifai’s model marketplace.
  • If your desired model isn’t there, use the Clarifai Python SDK to upload it—whether from Hugging Face or built from scratch

3. Install a Runtime:

Choose one of the tools described below. Each tool has its own installation process (CLI, GUI, Docker).

llama.cpp: A C/C++ inference engine supporting quantized GGUF models.

git clone https://github.com/ggerganov/llama.cpp

cd llama.cpp

make

./main -m path/to/model.gguf -p”Hello, world!”

Ollama: The easiest CLI. You can run a model with a single command:

ollama run qwen:0.5b

  •  It supports over 30 optimized models.
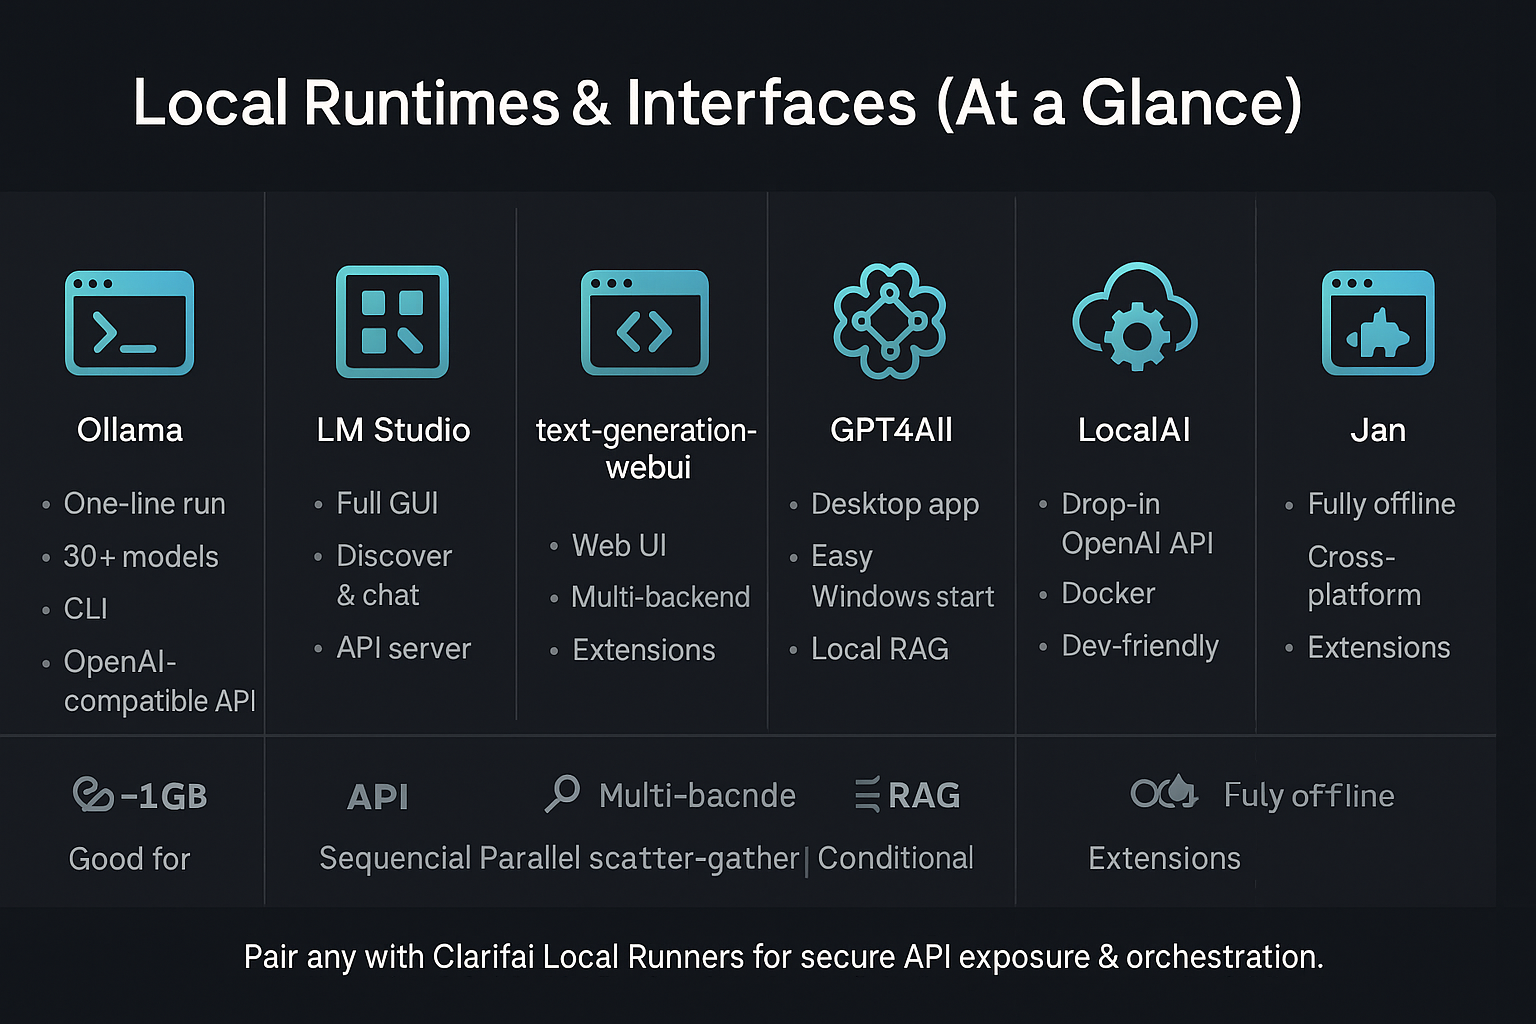
  • LM Studio: A GUI‑based solution. Download the installer, browse models via the Discover tab, and start chatting.
  • text‑generation‑webui: Install via pip or use portable builds. Start the web server and download models within the interface.
  • GPT4All: A polished desktop app for Windows. Download, select a model, and start chatting.

LocalAI: For developers wanting API compatibility. Deploy via Docker:

docker run -ti –name local-ai -p 8080:8080 localai/localai:latest-cpu

  •  It supports multi‑modal and GPU acceleration.
  • Jan: A fully offline ChatGPT alternative with a model library for Llama, Gemma, Mistral, and Qwen.

4. Set Up an environment

Use conda to create separate environments for each model, preventing dependency conflicts. When using GPU, ensure CUDA versions match your hardware.

5. Run & test

Launch your runtime, load the model, and send a prompt. Adjust parameters like temperature and max tokens to tune generation. Use logging to monitor memory usage.

6. Scale & orchestrate.

When you need to move from testing to production or expose your model to external applications, leverage Clarifai Local Runners. They allow you to connect models on your hardware to Clarifai’s enterprise-grade API with a single command. Through Clarifai’s compute orchestration, you can deploy any model on any environment—your local machine, private cloud, or Clarifai’s SaaS—while managing resources efficiently.

Expert Tip

Clarifai’s Local Runners can be started with clarifai model local-runner, instantly exposing your model as an API endpoint while keeping data local. This hybrid approach combines local control with remote accessibility.

Quick Summary

The process involves choosing a model, downloading weights, selecting a runtime (like llama.cpp or Ollama), setting up your environment, and running the model. For production, Clarifai Local Runners and compute orchestration let you scale seamlessly.

Run a Local Model -  steps


Top Local LLM Tools & Interfaces

Different tools offer various trade‑offs between ease of use, flexibility, and performance.

Ollama—One‑Line Local Inference

Ollama shines for its simplicity. You can install it and run a model with one command. It supports over 30 optimized models, including Llama 3, DeepSeek, and Phi‑3. The OpenAI‑compatible API allows integration into apps, and cross‑platform support means you can run it on Windows, macOS, or Linux.

  • Features: CLI‑based runtime with support for 30+ optimized models, including Llama 3, DeepSeek, and Phi‑3 Mini. It provides an OpenAI-compatible API and cross-platform support.
  • Benefits: Fast setup and active community. It is ideal for rapid prototyping.
  • Challenges: Limited GUI; more suited to terminal‑comfortable users. Larger models may require additional memory.
  • Personal Tip: Combine Ollama with Clarifai Local Runners to expose your local model via Clarifai’s API and integrate it into broader workflows.

 Expert Tip: “Developers say that Ollama’s active community and frequent updates make it a fantastic platform for experimenting with new models.”

Top Local LLM Tools & Interfaces


LM Studio – Intuitive GUI

LM Studio offers a visual interface that non‑technical users will appreciate. You can discover, download, and manage models within the app, and a built‑in chat interface keeps a history of conversations. It even has performance comparison tools and an OpenAI‑compatible API for developers.

  • Features: Full GUI for model discovery, download, chat interface, and performance comparison. Includes an API server.
  • Benefits: No command line required; great for non‑technical users.
  • Challenges: More resource‑intensive than minimal CLIs; limited extension ecosystem.
  • Personal Tip: Use LM Studio to evaluate different models before deploying to a production environment via Clarifai’s compute orchestration, which can then handle scaling
Expert Tip:

Use the Developer tab to expose your model as an API endpoint and adjust advanced parameters without touching the command line.


text‑generation‑webui – Feature‑Rich Web Interface

This versatile tool provides a web‑based UI with support for multiple backends (GGUF, GPTQ, AWQ). It’s easy to install via pip or download a portable build. The web UI allows chat and completion modes, character creation, and a growing ecosystem of extensions.

  • Benefits: Flexible and extensible; portable builds allow easy installation.
  • Challenges: Requires configuration for optimal performance; some extensions may conflict.
  • Personal Tip: Use the RAG extension to build local retrieval‑augmented applications, then connect to Clarifai’s API for hybrid deployments.

Expert Tip:

Leverage the knowledge base/RAG extensions to load custom documents and build retrieval‑augmented generation workflows.


GPT4All – Desktop Application

GPT4All targets Windows users. It comes as a polished desktop application with preconfigured models and a user‑friendly chat interface. Built‑in local RAG capabilities enable document analysis, and plugins extend functionality.

  • Benefits: Ideal for Windows users seeking an out‑of‑the‑box experience.
  • Challenges: Lacks an extensive model library compared to others; primarily Windows-only.
  • Personal Tip: Use GPT4All for everyday chat tasks, but consider exporting its models to Clarifai for production integration.

Expert Tip

Use GPT4All’s settings panel to adjust generation parameters. It’s a favorable choice for offline code assistance and knowledge tasks.


LocalAI —Drop-In API Replacement

LocalAI is the most developer‑friendly option. It supports multiple architectures (GGUF, ONNX, PyTorch) and acts as a drop‑in replacement for the OpenAI API. Deploy it via Docker on CPU or GPU, and plug it into agent frameworks.

  • Benefits: Highly flexible and developer‑oriented; easy to plug into existing code.
  • Challenges: Requires Docker; initial configuration may be time‑consuming.
  • Personal Tip: Run LocalAI in a container locally and connect it via Clarifai Local Runners to enable secure API access across your team.
 Expert Tip

Use LocalAI’s plugin system to extend functionality—for example, adding image or audio models to your workflow.


Jan—The Comprehensive Offline Chatbot

Jan is a fully offline ChatGPT alternative that runs on Windows, macOS, and Linux. Powered by Cortex, it supports Llama, Gemma, Mistral, and Qwen models and includes a built‑in model library. It has an OpenAI‑compatible API server and an extension system.

  • Benefits: Works on Windows, macOS, and Linux; fully offline.
  • Challenges: Fewer community extensions; limited for large models on low‑end hardware.
  • Personal Tip: Use Jan for offline environments and hook its API into Clarifai’s orchestration if you later need to scale.

Expert Tip

Enable the API server to integrate Jan into your existing tools. You can also switch between remote and local models if you need access to Groq or other providers.

Tool

Key Features

Benefits

Challenges

Personal Tip

Ollama

CLI; 30+ models

Fast setup; active community

Limited GUI; memory limits

Pair with Clarifai Local Runners for API exposure

LM Studio

GUI; model discovery & chat

Friendly for non‑technical users

Resource-heavy

Test multiple models before deploying via Clarifai

text‑generation‑webui

Web interface; multi‑backend

Highly flexible

Requires configuration

Build local RAG apps; connect to Clarifai

GPT4All

Desktop app; optimized models

Great Windows experience

Limited model library

Use for daily chats; export models to Clarifai

LocalAI

API‑compatible; multi‑modal

Developer‑friendly

Requires Docker & setup

Run in a container, then integrate via Clarifai

Jan

Offline chatbot with model library

Fully offline; cross‑platform

Limited extensions

Use offline; scale via Clarifai if needed


Best Local Models to Try (2025 Edition)

Best Local Models to try

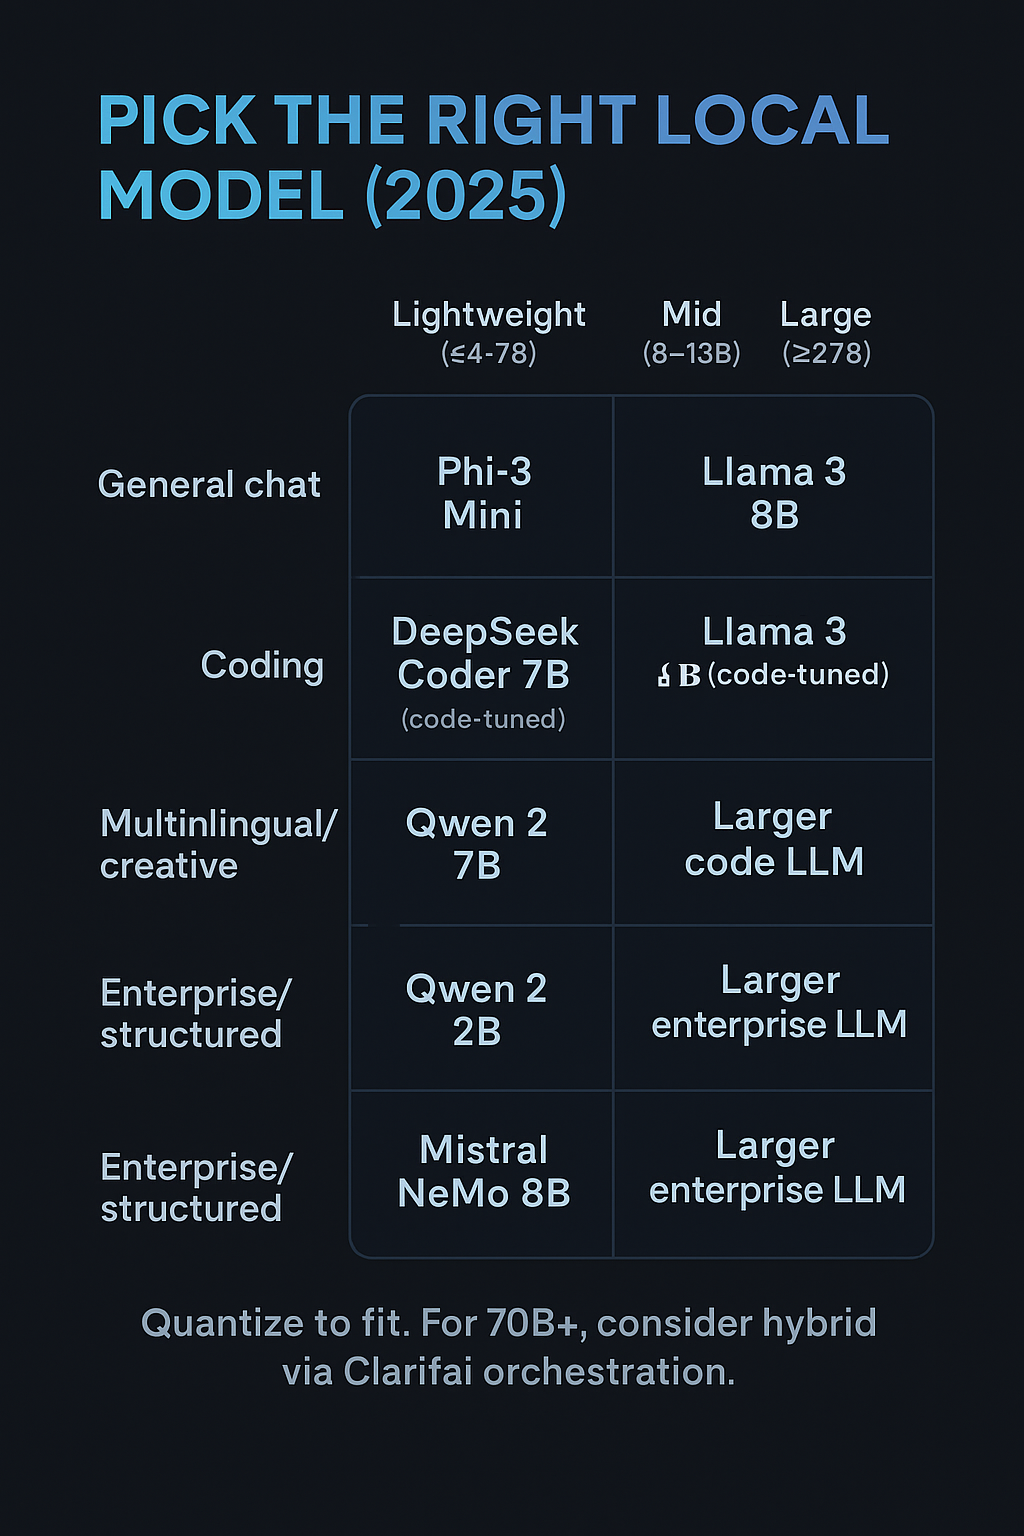
Choosing the right model depends on your hardware, use case, and desired performance. Here are the top models in 2025 with their unique strengths.

Llama 3 (8B & 70B)

Meta’s Llama 3 family delivers strong reasoning and multilingual capabilities. The 8B model runs on mid‑range hardware (16 GB RAM), while the 70B model requires high‑end GPUs. Llama 3 is optimized for dialogue and general tasks, with a context window up to 128 K tokens.

  • Features: Available in 8 B and 70 B parameter sizes. The 3.2 release extended the context window from 8 K to 128 K tokens. Optimized transformer architecture with a tokenizer of 128 K tokens and Grouped‑Query Attention for long contexts.
  • Benefits: Excellent at dialogue and general tasks; 8 B runs on mid‑range hardware, 70 B delivers near‑commercial quality. Supports code generation and content creation.
  • Challenges: The 70 B version requires high‑end GPUs (48+ GB VRAM). Licensing may restrict some commercial uses.
  • Personal Tip: Use the 8 B version for local prototyping and upgrade to 70 B via Clarifai’s compute orchestration if you need higher accuracy and have the hardware.

Expert Tip: Use Clarifai compute orchestration to deploy Llama 3 across multiple GPUs or in the cloud when scaling from 8B to 70B models.


Phi‑3 Mini (4K)

Microsoft’s Phi‑3 Mini is a compact model that runs on basic hardware (8 GB RAM). It excels at coding, reasoning, and concise responses. Because of its small size, it’s perfect for embedded systems and edge devices.

  • Features: Compact model with about 4 K parameters (approx. 3.8 GB footprint). Designed by Microsoft for reasoning, coding, and conciseness.
  • Benefits: Runs on basic hardware (8 GB RAM); fast inference makes it ideal for mobile and embedded use.
  • Challenges: Limited knowledge base; shorter context window than larger models.
  • Personal Tip: Use Phi‑3 Mini for quick code snippets or educational tasks, and pair it with local knowledge bases for improved relevance

 Expert Tip: Combine Phi‑3 with Clarifai’s Local Runner to expose it as an API and integrate it into small apps without cloud dependency.


DeepSeek Coder (7B)

DeepSeek Coder specializes in code generation and technical explanations, making it popular among developers. It requires mid‑range hardware (16 GB RAM) but offers strong performance in debugging and documentation.

  • Features: Trained on a massive code dataset, focusing on software development tasks. Mid‑range hardware with about 16 GB RAM is sufficient.
  • Benefits: Excels at generating, debugging, and explaining code; supports multiple programming languages.
  • Challenges: General reasoning may be weaker than larger models; lacks multilingual general knowledge.
  • Personal Tip: Run the quantized 4‑bit version to fit on consumer GPUs. For collaborative coding, use Clarifai’s Local Runners to expose it as an API.
 Expert Tip:

Use quantized versions (4‑bit) to run DeepSeek Coder on consumer GPUs. Combine with Clarifai Local Runners to manage memory and API access.


Qwen 2 (7B & 72B)

Alibaba’s Qwen 2 series offers multilingual support and creative writing skills. The 7B version runs on mid‑range hardware, while the 72B version targets high‑end GPUs. It shines in storytelling, summarization, and translation.

  • Features: Offers sizes from 7 B to 72 B, with multilingual support and creative writing capabilities. The 72 B version competes with top closed models.
  • Benefits: Strong at summarization, translation, and creative tasks; widely supported in major frameworks and tools.
  • Challenges: Large sizes require high‑end GPUs. Licensing may require credit to Alibaba.
  • Personal Tip: Use the 7 B version for multilingual content; upgrade to 72 B via Clarifai’s compute orchestration for production workloads.
Expert Tip

Qwen 2 integrates with many frameworks (Ollama, LM Studio, LocalAI, Jan), making it a flexible choice for local deployment.


Mistral NeMo (8B)

Mistral’s NeMo series is optimized for enterprise and reasoning tasks. It requires about 16 GB RAM and offers structured outputs for business documents and analytics.

  • Features: Enterprise‑focused model with approximately 8 B parameters, a 64 K context window, and strong reasoning and structured outputs.
  • Benefits: Ideal for document analysis, business applications, and tasks requiring structured output.
  • Challenges: Not yet as widely supported in open tools; community adoption still growing.
  • Personal Tip: Deploy Mistral NeMo through Clarifai’s compute orchestration to leverage automatic resource optimization
Expert Tip

Leverage Clarifai compute orchestration to run NeMo across multiple clusters and take advantage of automatic resource optimization.

Gemma 2 (9 B & 27 B)

  • Features: Released by Google; supports 9 B and 27 B sizes with an 8 K context window. Designed for efficient inference across a range of hardware.
  • Benefits: Performance on par with larger models; integrates easily with frameworks and tools such as Llama.cpp and Ollama.
  • Challenges: Limited to text; no multimodal support; the 27B version may require high‑end GPUs.
  • Personal Tip: Use Gemma 2 with Clarifai Local Runners to benefit from its efficiency and integrate it into pipelines.


Model

Key Features

Benefits

Challenges

Personal Tip

Llama 3 (8 B & 70 B)

8 B & 70 B; 128 K context

Versatile; strong text & code

70 B needs high‑end GPU

Prototype with 8 B; scale via Clarifai

Phi‑3 Mini

~4 K parameters; small footprint

Runs on 8 GB RAM

Limited context & knowledge

Use for coding & education

DeepSeek Coder

7 B; code‑specific

Excellent for code

Weak general reasoning

Use 4‑bit version

Qwen 2 (7 B & 72 B)

Multilingual; creative writing

Strong translation & summarization

Large sizes need GPUs

Start with 7 B; scale via Clarifai

Mistral NeMo

8 B; 64 K context

Enterprise reasoning

Limited adoption

Deploy via Clarifai

Gemma 2 (9 B & 27 B)

Efficient; 8 K context

High performance vs. size

No multimodal support

Use with Clarifai Local Runners


Other Notables

  • Qwen 1.5: Offers sizes from 0.5 B to 110 B, with quantized formats and integration with frameworks like llama.cpp and vLLM.
  • Falcon 2: Multilingual with vision-to-language capability; runs on a single GPU.
  • Grok 1.5: A multimodal model combining text and vision with a 128 K context window.
  • Mixtral 8×22B: A sparse Mixture‑of‑Experts model; efficient for multilingual tasks.
  • BLOOM: 176 B parameter open‑source model supporting 46 languages.

Each model brings unique strengths. Consider task requirements, hardware and privacy needs when selecting.

Quick Summary:

In 2025, your top choices include Llama 3, Phi‑3 Mini, DeepSeek Coder, Qwen 2, Mistral NeMo, and several others. Match the model to your hardware and use case.


Common Challenges and Solutions When Running Models Locally

Memory Limitations & Quantization

Large models can consume hundreds of GB of memory. For example, DeepSeek‑R1 is 671B parameters and requires over 500 GB RAM. The solution is to use distilled or quantized models. Distilled models like Qwen‑1.5B reduce size dramatically. Quantization compresses model weights (e.g., 4‑bit) at the expense of some accuracy.

Dependency & Compatibility Issues

Different models require different toolchains and libraries. Use virtual environments (conda or venv) to isolate dependencies. For GPU acceleration, match CUDA versions with your drivers.

Updates & Maintenance

Open‑source models evolve quickly. Keep your frameworks updated, but lock version numbers for production environments. Use Clarifai’s orchestration to manage model versions across deployments.

Ethical & Safety Considerations

Running models locally means you are responsible for content moderation and misuse prevention. Incorporate safety filters or use Clarifai’s content moderation models through compute orchestration.

Expert Insight

Mozilla.ai emphasizes that to run huge models on consumer hardware, you must sacrifice size (distillation) or precision (quantization). Choose based on your accuracy vs. resource trade‑offs.

Quick Summary

Use distilled or quantized models to fit large LLMs into limited memory. Manage dependencies carefully, keep models updated, and incorporate ethical safeguards.


Advanced Tips for Local AI Deployment

GPU vs CPU & Multi‑GPU Setups

While you can run small models on CPUs, GPUs provide significant speed gains. Multi‑GPU setups (NVIDIA NVLink) allow sharding larger models. Use frameworks like vLLM or deepspeed for distributed inference.

Mixed Precision & Quantization

Employ FP16 or INT8 mixed‑precision computation to reduce memory. Quantization techniques (GGUF, AWQ, GPTQ) compress models for CPU inference.

Multimodal Models

Modern models integrate text and vision. Falcon 2 VLM can interpret images and convert them to text, while Grok 1.5 excels at combining visual and textual reasoning. These require additional libraries like diffusers or vision transformers.

API Layering & Agents

Expose local models via APIs to integrate with applications. Clarifai’s Local Runners provide a robust API gateway, letting you chain local models with other services (e.g., retrieval augmented generation). You can connect to agent frameworks like LangChain or CrewAI for complex workflows.

Expert Insight

Clarifai’s compute orchestration allows you to deploy any model on any environment, from local servers to air‑gapped clusters. It automatically optimizes compute via GPU fractioning and autoscaling, letting you run large workloads efficiently.

Quick Summary

Advanced deployment includes multi‑GPU sharding, mixed precision, and multimodal support. Use Clarifai’s platform to orchestrate and scale your local models seamlessly.


Hybrid AI: When to Use Local and Cloud Together

Not all workloads belong fully on your laptop. A hybrid approach balances privacy and scale.

 When to Use Cloud

  • There are large models or long context windows that exceed local resources.
  • Burst workloads requiring high throughput.
  • Cross‑team collaboration where centralized deployment is beneficial.

When to Use Local

  • Sensitive data that must remain on‑premises.
  • Offline scenarios or environments with unreliable internet.
  • Rapid prototyping and experiments.

Clarifai’s compute orchestration provides a unified control plane to deploy models on any compute, at any scale, whether in SaaS, private cloud, or on‑premises. With Local Runners, you gain local control with global reach; connect your hardware to Clarifai’s API without exposing sensitive data. Clarifai automatically optimizes resources, using GPU fractioning and autoscaling to reduce compute costs.

Expert Insight

Developer testimonials highlight that Clarifai’s Local Runners save infrastructure costs and provide a single command to expose local models. They also stress the convenience of combining local and cloud resources without complex networking.

Quick Summary

Choose a hybrid model when you need both privacy and scalability. Clarifai’s orchestrated solutions make it easy to blend local and cloud deployments.


FAQs: Running AI Models Locally

Q1. Can I run Llama 3 on my laptop?
You can run Llama 3 8B on a laptop with at least 16 GB RAM and a mid‑range GPU. For the 70B version, you’ll need high‑end GPUs or remote orchestration.

Q2. Do I need a GPU to run local LLMs?
A GPU dramatically improves speed, but small models like Phi‑3 Mini run on CPUs. Quantized models and int8 inference enable CPU usage.

Q3. What is quantization, and why is it important?
Quantization reduces model precision (e.g., from 16‑bit to 4‑bit) to shrink size and memory requirements. It’s essential for fitting large models on consumer hardware.

Q4. Which local LLM tool is best for beginners?
Ollama and GPT4All offer the most user‑friendly experience. Use LM Studio if you prefer a GUI.

Q5. How can I expose my local model to other applications?
Use Clarifai Local Runners; start with clarifai model local-runner to expose your model via a robust API.

Q6. Is my data secure when using local runners?
Yes. Your data stays on your hardware, and Clarifai connects via an API without transferring sensitive information off‑device.

Q7. Can I mix local and cloud deployments?
Absolutely. Clarifai’s compute orchestration lets you deploy models in any environment and seamlessly switch between local and cloud.


Conclusion

Running AI models locally has never been more accessible. With a plethora of powerful models—from Llama 3 to DeepSeek Coder—and user‑friendly tools like Ollama and LM Studio, you can harness the capabilities of large language models without surrendering control. By combining local deployment with Clarifai’s Local Runners and compute orchestration, you can enjoy the best of both worlds: privacy and scalability.

As models evolve, staying ahead means adapting your deployment strategies. Whether you’re a hobbyist protecting sensitive data or an enterprise optimizing costs, the local AI landscape in 2025 provides solutions tailored to your needs. Embrace local AI, experiment with new models, and leverage platforms like Clarifai to future-proof your AI workflows.

Feel free to explore more on the Clarifai platform and start building your next AI application today!


How to Create AI Teammates That Work For You with Liza Adams [MAICON 2025 Speaker Series]


MAICON brings together top visionaries and experts in the field of AI during a three-day conference packed with actionable sessions and networking events—all to position you as the change agent your organization (and career) needs. In this ongoing speaker series, we’re featuring these extraordinary leaders, with forward-looking predictions, actionable tips you can use today, and a preview of their MAICON 2025 sessions. Continue reading “How to Create AI Teammates That Work For You with Liza Adams [MAICON 2025 Speaker Series]”

What Is API Orchestration & How Does It Work?


Modern software isn’t built from a single block; it’s assembled from a constellation of services. Each login, payment, or data fetch involves multiple calls to disparate systems. API orchestration is the glue that makes these services work together smoothly. Rather than letting clients juggle dozens of API calls, an orchestration layer sequences calls, transforms data and enforces business logic to deliver a single, coherent response. This article dives deep into the concept of API orchestration, contrasts it with related patterns, explores benefits and challenges, surveys emerging trends, and shows how Clarifai’s AI platform brings orchestration to model inference. Along the way, expert insights and real‑world examples help demystify this critical building block of distributed systems.

Quick overview

Before diving into each section, here’s a high‑level roadmap of what follows:we start with a definition of API orchestration and why it matters. We then compare orchestration to integration, aggregation, and choreography. Next we explain how orchestration works, describe its architectural components, list major orchestration tools, and outline best practices. Use-case examples illustrate orchestration in action, while the challenges section highlights pitfalls to avoid. Finally, we look at emerging trends, explore how Clarifai orchestrates AI models, provide a step‑by‑step implementation guide, and answer common questions.


Introduction—The Role of API Orchestration

What is API orchestration?

Think of API orchestration as a digital conductor. Instead of a customer or client application making multiple calls to various services, an orchestration layer coordinates those services in the right order and with the right data. Imagine API orchestration as the maestro that coordinates a multitude of digital instruments, ensuring they play in harmony. This layer not only connects APIs, it defines the flow between them—sequencing calls, transforming inputs/outputs, handling errors and applying business rules.

Why do we need it?

The explosion of microservices and third‑party APIs means that even simple user journeys involve many moving parts. Postman’s 2024 State of API report found that 95 % of organizations experienced API security issues in the past year, highlighting the complexity and risk of managing many endpoints. In a world where a mobile app might contact separate services for user profile data, order history and payment processing, orchestration offers several advantages:

  • Simplifies clients: the client makes a single request instead of multiple calls.
  • Centralizes business logic: all sequencing rules and data transformations live in one place.
  • Improves resilience: the orchestrator can handle retries, fallbacks and compensation when services fail.
  • Enhances security: authentication, rate limiting and other cross‑cutting concerns can be enforced centrally.

Ultimately, API orchestration reduces complexity for consumers while making distributed systems more manageable and secure.

Expert insight: The digital symphony

Fernando Doglio notes that API orchestration isn’t just about connecting systems; it’s about conducting the performance. Imagine ordering food via a delivery app—the app needs to authenticate you, check inventory, process payment and schedule delivery. Orchestration ensures these steps happen in the correct order and that each API knows when and how to play its part.


API Orchestration vs. Integration, Aggregation and Choreography

Defining related concepts

API integration is about connecting two systems so they can exchange data—think of an e‑commerce site integrating with a payment gateway. API aggregation combines responses from multiple APIs into a single response, typically in parallel. API orchestration goes further: it sequences calls, applies conditional logic and transforms data between steps.

A helpful analogy is the difference between building roads (integration), merging traffic from multiple roads (aggregation) and directing the traffic lights and intersections (orchestration). API orchestration choreographs integrated APIs into a well‑structured workflow—it’s not enough to connect systems; you must control the order and logic of interactions.

Choreography vs. orchestration

In the microservices world, choreography is another pattern in which services emit events and react to events from others. There’s no central controller; each service knows its role. Choreography can enable loosely coupled systems but may obscure flow control. The Alokai article on microservices notes that choreography resembles an ant colony, where each service broadcasts state changes. This approach suits highly independent services but can make debugging difficult. Orchestration, by contrast, uses a centralized service or workflow engine to steer the flow. It simplifies understanding, monitoring and debugging at the cost of a central point of control.

Example: e‑commerce order process

 When a customer places an order, the platform must check inventory, process payment and schedule shipping. Integration alone could connect these services, but only orchestration ensures the steps happen sequentially. If inventory isn’t available, the payment should not be processed. If payment fails, the order should not be recorded. Orchestration manages these conditional flows and handles errors gracefully.

Expert insight: The API7 workflow pattern

API7 frames orchestration as a workflow pattern. Their example uses an API gateway to manage a “Create Order” process: the gateway first checks stock, then authorizes payment, then creates the order. Each step can depend on the previous one, and errors trigger alternative paths. This pattern highlights the importance of sequencing and conditional logic, distinguishing orchestration from simple aggregation.


How API Orchestration Works—Patterns & Mechanisms

Components of an orchestration layer

At its core, an API orchestrator sits between clients and multiple backend services. When a request arrives:

  1. Receive request: The orchestration layer (often an API gateway or workflow engine) receives a single client call.
  2. Decompose & plan: It determines which services must be invoked and in what sequence based on the requested action.
  3. Execute workflow: The orchestrator calls the first service, processes the response, and uses that data to call subsequent services. It may transform or merge payloads, handle conditional logic and catch errors.
  4. Assemble response: After all steps complete successfully (or appropriate compensations are executed on failure), the orchestrator compiles a single response to the client.

The API7 underscores that orchestration often involves stateful workflows, where the output of one call becomes the input for the next and the gateway handles conditional logic, error handling and retries.

Patterns and sequencing

Common orchestration patterns include:

  • Workflow sequencing: Steps must be executed in a specific order (e.g., verify availability → process payment → create order).
  • Scatter‑gather (aggregation): Multiple services are called in parallel and their results combined. While this is sometimes considered an aggregation pattern, many orchestrators support both sequential and parallel branches.
  • Conditional logic: The next step depends on the result of a prior call (e.g., if stock is insufficient, abort; otherwise continue).
  • Compensation/rollback: If a later step fails, the orchestrator can trigger compensating actions to undo previous work (e.g., refund payment).

Where orchestration happens

Orchestration can be implemented in several places:

  • API gateway: Some API gateways (e.g., Apache APISIX, Kong, Tyk) include orchestration plugins that sequence calls. API7 notes that this approach centralizes business logic at the gateway, offloading complexity from microservices.
  • Workflow engine: Platforms like Camunda, Prefect, Netflix Conductor and AWS Step Functions provide dedicated workflow engines that orchestrate APIs. These often support visual modelling (BPMN) and advanced error handling.
  • Custom service: In some architectures, a bespoke orchestrator is developed using frameworks like Node.js, Python or Java to orchestrate calls. This offers flexibility but requires more maintenance.

Under the hood: service discovery & rate limiting

Effective orchestration relies on supporting mechanisms:

  • Service discovery: Tools like Consul, etcd and ZooKeeper help the orchestrator locate services dynamically.
  • Rate limiting and caching: The orchestration layer can apply rate limits, caching and authentication to protect backend services.
  • Data transformation: As Cyclr’s article explains, the orchestration layer can reformat payloads to match different API requirements and merge or split responses.

Expert insight: Microservice orchestration

The Alokai article draws parallels between API orchestration and microservice orchestration. It notes that an orchestrator (e.g., Kubernetes) acts as a central brain ensuring each microservice executes its part, tracking status and managing inter‑service communication. Though container orchestration and API orchestration operate at different layers, both ensure that loosely coupled services work together without cascading failures.


Benefits of API Orchestration

API orchestration provides tangible advantages for both developers and end‑users. Here are some of the most significant benefits.

Improved automation and efficiency

By coordinating multi‑step workflows behind the scenes, orchestration eliminates manual intervention.  Automating workflows—such as order processing—makes processes faster and reduces errors. Instead of developers writing custom code in each microservice to call others, the orchestrator handles sequencing, retries and data transformations.

Enhanced customer experience

Users expect seamless interactions. When using a ride‑sharing app, they don’t notice that separate APIs handle geolocation, payment and driver matching. Well‑orchestrated APIs ensure that these calls happen quickly and in the right order, creating a smooth experience.

Agility and scalability

Modern organizations must adapt quickly to new requirements. API orchestration simplifies adding or replacing services. By isolating business logic in a workflow engine or gateway, teams can integrate new services without rewriting client code.  Effective orchestration provides agility and scalability, enabling organizations to respond to changing market demands.

Centralized security and governance

The orchestration layer can enforce consistent policies across all API calls, including authentication, authorization, rate limiting, logging and monitoring. Cyclr highlights that an orchestration layer can handle OAuth flows and implement role‑based permissions, ensuring only the appropriate data is exposed. Centralization reduces the risk of misconfigured endpoints.

Reduced client complexity and latency

When the client makes multiple calls, network latency accumulates. API7 calls this a “chatty client” problem—each call involves network overhead. By orchestrating calls at the gateway, the client sends a single request and receives a single response, decreasing round‑trip time.

Integrating legacy systems

Legacy or mixed API types (REST, SOAP, GraphQL) can be hard to combine. The orchestration layer can normalize data structures and manage flows between modern and legacy services, enabling businesses to modernize gradually without a complete rewrite.

Expert insight: Security statistics

A stark example of what happens without central control is the Twilio Authy data breach. In July 2024, threat actors exploited an unsecured API endpoint, accessing 33 million phone numbers. Salt Security’s research suggests that API attacks will increase tenfold by 2030. A robust orchestration layer helps mitigate such risks by enforcing authentication and monitoring at a single choke point.


Key Components & Architecture of API Orchestration

Building blocks

A typical orchestration architecture comprises several interconnected parts:

  1. Client or consumer: The application requesting a business function (web app, mobile app, another service).
  2. API gateway/orchestration layer: The entry point that receives requests, applies policies and routes calls. It may also implement orchestration logic itself.
  3. Workflow engine (optional): For complex flows, a workflow engine such as Camunda, Prefect or AWS Step Functions manages sequencing, state and error handling.
  4. Microservices/back‑end APIs: Services providing business capabilities (inventory, payment, shipping, authentication).
  5. Service discovery & registry: A registry (Consul, etcd, ZooKeeper) helps the orchestrator locate services dynamically.
  6. Observability & logging: Tracing, metrics and logging tools (Prometheus, Grafana, Jaeger) give visibility into call chains.
  7. Data stores & messaging: Databases and message brokers (Kafka, RabbitMQ) handle state and asynchronous communication.
  8. External partners: Third‑party APIs (payment gateways, email services) often integrated through orchestration.

Orchestration vs. container orchestration

It’s important to distinguish API orchestration from container orchestration. The latter focuses on deploying and managing containers using tools like Kubernetes, Docker Swarm and Apache Mesos. These orchestrators ensure containers are scheduled, scaled and healed automatically. API orchestration, by contrast, orchestrates the business workflow across services. Yet the two meet when orchestrated services run in containers; Kubernetes provides the runtime environment while an API orchestration layer coordinates calls between containerized microservices.

Loosely coupled services

The Alokai article stresses that loose coupling is the cornerstone of resilient architectures. Services must communicate via well‑defined APIs without dependency entanglement, enabling one service to fail or be replaced without cascading issues. Orchestration enforces this discipline by centralizing interactions instead of embedding call logic inside services.

Cross‑cutting concerns

Centralizing cross‑cutting concerns is another architectural benefit. API7 emphasises that authentication, authorization, rate limiting, and logging should be implemented consistently at the gateway. This not only strengthens security but simplifies compliance and auditing.

Expert insight: BPMN and visual modelling

Camunda uses Business Process Model and Notation (BPMN) to create clear, visual workflows that orchestrate APIs. This approach allows developers and business stakeholders to collaborate on designing the orchestration logic, reducing misunderstandings and aligning implementation with business objectives.


Leading Tools and Platforms for API Orchestration

The orchestration landscape includes API gateways, workflow engines and integration platforms. Each type serves different needs.

API gateways with orchestration capabilities

  • Apache APISIX (API7): An open‑source, high‑performance API gateway. APISIX supports custom plugins for aggregation and workflow orchestration, centralizing business logic at the gateway.
  • Kong/Tyk/Gravitee: Popular gateways offering rate limiting, authentication and some orchestration features. Tyk and Gravitee provide developer portals and policy management.
  • AWS API Gateway/Google Cloud Endpoints/Azure API Management: Managed gateways in cloud environments. Some support step‑function integrations for orchestration.

Workflow engines & integration platforms

  • Camunda: A process orchestration platform using BPMN for modelling. It integrates REST and GraphQL connectors and supports human tasks.
  • Prefect/Apache Airflow/Argo Workflows: Popular orchestration frameworks for data and machine‑learning pipelines. Prefect emphasises fault‑tolerant workflows; Airflow is widely used in data engineering; Argo is Kubernetes‑native.
  • Netflix Conductor: An open‑source workflow orchestration engine used by Netflix to coordinate microservices. It supports dynamic workflows, retries and versioning.
  • AWS Step Functions/Azure Logic Apps/Google Workflows: Serverless orchestrators that allow pay‑per‑use execution. TechTarget notes that serverless API architectures reduce latency and cost by running closer to the end user.
  • MuleSoft/Apigee: Enterprise integration platforms that combine API management with orchestration and analytics. Apigee is known for its analytics and security features.
  • Zapier/IFTTT: No‑code platforms enabling simple API orchestration for non‑technical users. They’re suited for small workflows and rapid prototypes.

Container orchestration & event‑driven platforms

  • Kubernetes, Docker Swarm, Apache Mesos: Manage container deployment and scaling. While not API orchestrators themselves, they underpin microservices that are orchestrated.
  • AsyncAPI/GraphQL: Not tools but specifications. TechTarget notes that diversification of API standards—GraphQL and AsyncAPI alongside REST—is a major trend. Orchestrators must handle these protocols seamlessly.

Clarifai’s orchestration features

Clarifai stands out by offering compute orchestration and model inference orchestration. It provides a marketplace of pre‑trained models (e.g., image classification, object detection, OCR) and allows developers to chain them together into pipelines. Clarifai’s local runners let organisations host models on their infrastructure or at the edge, preserving privacy. In the next section dedicated to Clarifai we explore these capabilities in depth.

Expert insight: Platform synergy

Combining a capable API gateway with a workflow engine and a container orchestrator delivers a powerful stack. For instance, you might use APISIX to handle authentication and routing, Camunda to model the workflow, and Kubernetes to deploy the microservices. This approach centralizes security, simplifies scaling and offers visual control over business logic.


Best Practices for API Orchestration & Microservice Deployment

Implementing orchestration effectively requires both architectural discipline and operational diligence.

Follow microservice best practices

Ambassador Labs outlines nine best practices for microservice orchestration. Key recommendations include:

  • Package services in containers: Use Docker containers for portability and consistent environments.
  • Leverage container orchestrators: Deploy containers with Kubernetes, Docker Swarm or Mesos to automate placement, scaling and healing.
  • Adopt asynchronous communication: Wherever possible, use message queues to decouple services and improve resilience.
  • Isolate data storage: Each microservice should manage its own database, preventing shared schemas and enabling independent scaling.
  • Implement service discovery: Use tools like Consul to enable dynamic resolution of service addresses.
  • Use an API gateway: Centralize routing, authentication and policy enforcement to simplify services.
  • Externalize configuration: Manage configuration separately (e.g., via a configuration server or Kubernetes ConfigMap) for consistency across environments.
  • Design for failure: Build in retries, timeouts and fallback paths; incorporate chaos engineering to test resilience.
  • Apply the single responsibility principle: Keep services focused; orchestration should not be embedded in business services.

Design first and centralize policies

API7 advises a design‑first approach using specifications like OpenAPI to define service contracts before coding. This ensures everyone understands how services should interact. Additionally, cross‑cutting concerns—authentication, rate limiting, logging—should be centralized in the gateway or orchestration layer. This simplifies maintenance and reduces the attack surface.

Embrace observability & tracing

When a single client request triggers numerous downstream calls, observability becomes critical. API7 recommends enabling detailed logging, distributed tracing and metrics so you can debug and monitor complex integrations. Tools like Jaeger, Zipkin, Prometheus and Grafana can visualize call chains and latencies.

Prioritize security

Given the prevalence of API breaches, enforcing security at multiple layers is vital. Implement OAuth or JWT authentication, SSL/TLS encryption, rate limiting and anomaly detection at the gateway. Consider adopting zero‑trust architecture—every request must be authenticated and authorized. Use API auditing tools to detect shadow APIs and misconfigurations.

Test and version your workflows

Orchestration workflows should be versioned so updates can be rolled out without breaking existing clients. Employ continuous testing with mocks and integration tests to validate each flow. Simulate failure scenarios to ensure compensation logic works.

Expert insight: Observability as a strategic investment

Salt Security predicts that API attack frequency will grow tenfold by 2030. Investing in observability not only aids debugging but also helps detect anomalies and intrusions early. Effective monitoring complements security measures, giving you confidence in your orchestration strategy.


Use Cases & Real‑World Examples

Concrete examples bring orchestration to life. Here are some scenarios where orchestration proves invaluable.

E‑commerce order fulfillment

When a customer checks out, multiple services must coordinate:

  1. Inventory check: Query the inventory service to ensure the product is in stock.
  2. Payment authorization: If stock is available, call the payment service to charge the customer.
  3. Order creation: Create an order record and update the inventory count.
  4. Shipping: Schedule a shipment with the logistics service.

Ride‑sharing app workflow

A ride request triggers several APIs: geolocation to find nearby drivers, payment to estimate cost, driver assignment and live tracking. Effective orchestration ensures these calls occur quickly and in the right order, providing a smooth user experience.

API7’s “Create Order” workflow

API7’s example shows how an API gateway orchestrates an order creation: check inventory, process payment and then write the order. Conditional logic ensures that if payment fails, inventory is not adjusted and the client is informed.

AI model pipelines with Clarifai

In AI/ML applications, orchestration is key. Consider an image processing pipeline:

  1. Data ingestion: Fetch images from a data source (e.g., camera or storage).
  2. Preprocessing: Resize or normalize images.
  3. Model inference: Run object detection, classification or segmentation models.
  4. Postprocessing: Filter results, apply business rules, store outcomes.

Clarifai’s platform allows developers to chain these steps using compute orchestration. You can combine multiple models (e.g., object detection followed by text recognition) and run them locally using local runners for privacy. Workflows may include third‑party APIs such as payment gateways for monetizing AI results or sending notifications.

Integrating legacy systems

Cyclr highlights that an orchestration layer can normalize data structures between different API types and integrate outdated services. For example, a manufacturer might mix SOAP, REST and GraphQL services. The orchestrator translates requests and responses, enabling modern clients to interact with legacy systems seamlessly.

AI‑orchestrated IoT manufacturing

 envisions AI agents autonomously discovering sensor APIs in a factory and composing workflows for data ingestion, analysis and alerting. When a sensor API fails, the agent reroutes through alternatives without downtime. This scenario demonstrates how AI‑powered orchestration reduces integration time from months to minutes while ensuring continuous operation.

Expert insight: The shift from API consumers to API architects

 argues that AI agents are moving beyond API consumption; they now design, optimize, and maintain integrations themselves. This autonomous orchestration not only accelerates innovation but also creates a self‑optimizing digital nervous system for enterprises. Early adopters gain speed, resilience and market agility.


Challenges & Considerations—Security, Observability and Governance

Security vulnerabilities

APIs are a prime target for attackers. Twilio’s Authy breach, where an unsecured endpoint exposed 33 million phone numbers, illustrates the consequences of lax security. Without orchestration, organizations must embed authentication and authorization logic in each service, increasing the risk of misconfiguration. Centralizing these controls in an orchestration layer mitigates vulnerabilities but doesn’t eliminate them.

Complexity and debugging

Distributed systems are hard to reason about. When a single request fans out to dozens of services, tracing failures becomes challenging. Without proper observability, debugging an orchestration workflow can feel like searching for a needle in a haystack. Invest in tracing, logging and metrics to get a clear view of each step.

Latency and performance

Orchestration introduces additional hops between the client and services. If not designed carefully, it can add latency. Combining synchronous calls with heavy transformations may slow down responses. Use asynchronous or event‑driven patterns where possible and leverage caching to improve performance.

Error handling and compensation

Multi‑step workflows require robust error handling. A failure in step 3 may require rolling back steps 1 and 2. Designing compensation logic is tricky; for example, after payment authorization, refunding a charge might involve additional API calls. Tools like Saga patterns and step functions can help implement compensations.

Governance and compliance

Centralizing API flows raises questions about data governance and compliance. Orchestrators often process sensitive data (payment details, personal information), so they must comply with regulations like GDPR and HIPAA. Ensure encryption in transit and at rest, enforce data retention policies and audit access.

Cost and vendor lock‑in

Using managed orchestration services (e.g., AWS Step Functions) can be cost‑effective but may tie you to a single cloud provider. Weigh the benefits of managed services against potential lock‑in and evaluate open‑source alternatives for portability.

Expert insight: Zero‑trust and AI‑driven security

TechTarget predicts that API security will take centre stage, with new standards and AI‑powered monitoring systems emerging to detect threats in real time. Integrating AI‑driven security into the orchestration layer can help identify anomalous behavior and enforce zero‑trust principles—every request is authenticated and authorized.


Emerging Trends & Future of API Orchestration

Generative AI and AI agents

Large language models are reshaping API development and orchestration. TechTarget notes that AI can generate API specifications from natural language descriptions, accelerating development. AI agents can also analyze logs and telemetry to identify bottlenecks, propose optimizations and even modify orchestrations autonomously. Postman’s 2024 report found that 54 % of respondents used ChatGPT or similar tools for API development.

Diversification of API standards

GraphQL, AsyncAPI and REST will coexist in most organizations. GraphQL allows clients to fetch exactly the data they need; AsyncAPI standardizes event‑driven and message‑based APIs. Orchestration layers must support these protocols and convert between them.

Serverless and edge orchestration

TechTarget predicts that serverless API architectures will see increased adoption, especially when combined with edge computing. By running API logic closer to users, latency drops and costs become pay‑per‑use. However, monitoring and security become more complex across distributed edge locations.

Low/no‑code orchestration platforms

Citizen developers and business users increasingly use no‑code tools like Zapier or Microsoft Power Automate to create integrations. Orchestration products are evolving to offer visual workflow builders, templates and AI‑assisted suggestions, democratizing integration while still requiring governance.

Autonomous API orchestration

 envisions a future where AI agents continuously discover new APIs, design workflows, and reroute around failures without human intervention. In this scenario, the API layer becomes a living, self‑optimizing digital nervous system. While still emerging, this trend promises faster innovation cycles and improved resilience.

Expert insight: Preparing for diversification

TechTarget emphasises that as API standards diversify, API management platforms must evolve to handle multiple protocols and event‑driven architectures. Investing in tooling that abstracts protocol differences and provides unified monitoring will help organisations stay ahead of this trend.


Clarifai’s Approach to API Orchestration & Model Inference

Orchestrating AI workflows

Clarifai is known for its extensive catalog of computer‑vision and natural‑language models. But beyond single API calls, Clarifai offers compute orchestration that lets developers build multi‑stage AI pipelines. For example, you might:

  1. Use an object detection model to locate regions of interest in an image.
  2. Feed those regions into a classification model to identify specific objects.
  3. Apply OCR to extract text from regions containing labels.
  4. Use a language model to translate or summarise the text.

With Clarifai’s orchestration tools, these steps can be defined visually or via a declarative workflow. The platform takes care of running models in the right order, passing outputs between them and returning a unified result.

Local runners and privacy

Data privacy is a growing concern. Clarifai’s local runners allow organisations to host models on their own infrastructure or at the edge, ensuring sensitive data never leaves controlled environments. This is crucial in industries like healthcare and finance. Orchestration can involve hybrid workflows that combine on‑prem models with cloud services.

Low‑code pipeline builder

Clarifai provides a low‑code interface for designing AI pipelines. Users can drag and drop models, define branching logic, and connect external APIs (e.g., a payment gateway to monetise AI results). This democratizes AI and integration, enabling product managers or analysts to build sophisticated workflows without deep coding knowledge.

Subtle calls‑to‑action

If you’re orchestrating complex AI workflows, explore Clarifai’s compute orchestration and Model Runner offerings. They provide a ready‑made environment to build, deploy and scale AI pipelines without managing infrastructure. You can sign up for a free account to experiment with orchestration in your own environment.

Expert insight: AI meets orchestration

Clarifai’s ability to combine multiple AI models and external APIs demonstrates the convergence of AI engineering and API orchestration. As generative AI and computer vision become ubiquitous, platforms that simplify the integration and sequencing of models will become indispensable.


Getting Started—A Step‑by‑Step Guide to Implementing API Orchestration

1. Identify candidate workflows

Begin by mapping business processes that span multiple services. Look for pain points where clients make multiple API calls or where failures cause inconsistencies. Examples include order processing, user onboarding, content moderation and AI pipelines.

2. Document APIs and design the contract

Adopt a design‑first approach using OpenAPI to describe each service’s endpoints, request/response formats and authentication methods. Clear contracts help you define orchestration logic and ensure services conform to expectations.

3. Choose an orchestration pattern

Decide whether the workflow is primarily sequential, parallel (aggregation) or a mix. For sequential flows with conditional logic, consider a workflow engine (Camunda, Prefect, Step Functions). For simple aggregations, an API gateway may suffice.

4. Select tools

Pick an API gateway to enforce security and routing. If you need visual workflows or human tasks, choose a workflow engine (Camunda, Prefect, Step Functions). For AI pipelines, platforms like Clarifai provide built‑in orchestration and model inference. For containerized services, orchestrate deployment with Kubernetes or Docker Swarm.

5. Implement and test the workflow

Use the chosen tool to define the orchestration. Represent steps and branches clearly, preferably using a visual notation like BPMN. Write unit and integration tests. Simulate failures to ensure compensating actions run correctly.

6. Monitor and iterate

Deploy the orchestrated workflow in a staging environment and monitor logs, metrics and traces. Check latency, error rates and throughput. Iterate on the design to remove bottlenecks and improve resilience.

7. Roll out gradually

Start by orchestrating non‑critical flows or a subset of services. Gradually increase coverage and complexity. Provide documentation and training so developers understand how to invoke the orchestration layer.

8. Integrate AI and analytics

Leverage AI to optimize your workflows. Use predictive analytics to anticipate traffic spikes and scale automatically. Consider AI‑powered observability tools to detect anomalies. For AI pipelines, integrate Clarifai models and compute orchestration as part of your workflows.

Expert insight: Start small, scale wisely

Ambassador Labs suggests adopting orchestration incrementally—begin with one workflow and expand once you establish patterns and tools. Combine this with a design‑first approach and strong observability to avoid being overwhelmed by complexity.


FAQs on API Orchestration

Q1: How does API orchestration differ from API integration and aggregation?
API integration connects two services so they can exchange data. API aggregation combines responses from multiple services, usually in parallel. API orchestration sequences calls, applies logic and transforms data; it’s a superset of integration and often includes aggregation.

Q2: When should I use orchestration instead of choreography?
Use orchestration when you need centralized control over the order of operations, conditional logic, error handling and compensation. Choreography suits systems with highly autonomous services and simple event flows.

Q3: Does orchestration improve security?
Yes. By centralizing authentication, authorization, rate limiting and logging, the orchestrator reduces the chances of misconfigured endpoints. However, orchestration itself must be secured and monitored to prevent attacks.

Q4: What orchestration tools are best for small teams?
For lightweight workflows, API gateways like APISIX or Tyk with orchestration plugins may suffice. Prefect or AWS Step Functions provide managed workflow orchestration with minimal setup. Low‑code tools like Zapier suit non‑technical users.

Q5: How does Clarifai fit into orchestration?
Clarifai offers compute orchestration for AI pipelines, enabling developers to chain multiple models and external APIs without building orchestration logic from scratch. Its local runners let you run models on your own infrastructure for privacy and control.

Q6: What is the future of API orchestration?
Expect diversification of API standards (GraphQL, AsyncAPI), greater adoption of serverless and edge architectures, and the rise of AI‑driven orchestration where agents design and optimize workflows. Security and observability will remain top priorities.

Q7: Do I need container orchestration to use API orchestration?
Not necessarily, but container orchestration (e.g., Kubernetes) complements API orchestration by managing service deployment, scaling and resilience. Together, they provide a robust platform for microservice applications.


Conclusion

API orchestration is more than an integration pattern—it’s a strategic capability that helps modern organisations manage complexity, improve customer experiences and accelerate innovation. By acting as the conductor of distributed systems, orchestration layers sequence calls, enforce business logic, centralize security and simplify development. As trends like generative AI, edge computing and autonomous API agents reshape the landscape, investing in flexible orchestration tools and adopting best practices will keep your architecture future‑proof. Platforms like Clarifai demonstrate how orchestration extends beyond traditional APIs into AI/ML workflows, enabling businesses to deliver smarter, more personalised experiences. Whether you’re orchestrating an e‑commerce checkout or chaining AI models, the principles of orchestration—clarity, security and adaptability—remain the same.


What Is Model Deployment? Strategies & Best Practices


Machine learning models often need a helping hand to truly thrive. Creating a top-tier model in a notebook is certainly a noteworthy accomplishment. However, it only truly adds value to the business once that model is able to provide predictions within a production environment. This is the moment when we bring our models to life. Model deployment involves bringing trained models into real-world settings, allowing them to be utilized by actual users and systems to guide decisions and actions.

In numerous organizations, the process of deployment often becomes a hurdle. 

A survey from 2022 highlighted that as many as 90% of machine-learning models fail to make it to production because of various operational and organizational challenges.

 Bringing models to life goes beyond simply coding; it demands a strong foundation, thoughtful preparation, and approaches that harmonize risk with flexibility. This guide takes you on a journey through the lifecycle of model deployment, exploring various serving paradigms and looking closely at popular deployment strategies like shadow testing, A/B testing, multi-armed bandits, blue-green, and canary deployments. It also includes aspects like packaging, edge deployment, monitoring, ethics, cost optimization, and emerging trends such as LLMOps. Along the way, we’ll weave in gentle suggestions for Clarifai’s offerings to illustrate how contemporary solutions can make these intricate tasks easier.

Explore Clarifai Models

The Deployment Lifecycle: From Experiment to Production

Before selecting a deployment strategy, it’s important to grasp the larger lifecycle context in which deployment occurs. An ordinary machine learning workflow involves gathering data, training the model, evaluating its performance, deploying it, and then monitoring its effectiveness. MLOps takes the core ideas of DevOps and applies them to the world of machine learning. By emphasizing continuous integration, continuous deployment, and continuous testing, it helps ensure that models are consistently and reliably brought into production. Let’s take a closer look at the important steps.

1. Design and Experimentation

The adventure starts with data scientists exploring ideas in a safe space. We carefully gather datasets, thoughtfully engineer features, and train our models with precision. We use evaluation metrics such as accuracy, F1 score, and precision to assess our candidate models. Right now, the model isn’t quite prepared for practical application.

Important factors to keep in mind:

  • Ensuring data quality and consistency is crucial; if the data is incomplete or biased, it can jeopardize a model right from the beginning. Thorough validation allows us to identify and address problems right from the start.
  • Creating reproducible experiments involves versioning code, data, and models, which allows for future audits and ensures that experiments can be replicated effectively.
  • When planning your infrastructure, it’s important to consider the hardware your model will need—like CPU, GPU, and memory—right from the experimentation phase. Also, think about where you’ll deploy it: in the cloud, on-premises, or at the edge.

2. Model Training

After identifying models with great potential, we train them extensively using robust infrastructure designed for production. This step includes providing the complete dataset to the selected algorithm, refining it as needed, and ensuring that all essential artifacts (like model weights, logs, and training statistics) are collected for future reference and verification.

Important factors to keep in mind:

  • Scalability: It’s important to ensure that training jobs can operate on distributed clusters, particularly when dealing with large models or datasets. Managing resources effectively is essential.
  • Keeping track of experiments: By recording training parameters, data versions, and metrics, teams can easily compare different runs and gain insights into what is effective.
  • Early stopping and regularization are valuable strategies that help keep our models from becoming too tailored to the training data, ensuring they perform well in real-world scenarios.
  • Choosing between GPU and CPU for hardware utilization—and keeping an eye on how hardware is being used—can significantly impact both training time and expenses.

3. Evaluation & Validation

Before a model is launched, it needs to undergo thorough testing. This involves checking the model’s performance through cross-validation, adjusting settings for optimal results with hyperparameter tuning, and ensuring fairness with thorough audits. In critical areas, we often put our models through stress tests to see how they perform in unusual situations and challenging scenarios.

An essential aspect of this stage involves evaluating the model in a setting that closely resembles actual operational conditions. This is where Clarifai’s Local Runners make a meaningful impact.

Local Runners provide you with the opportunity to test models right in your own setup, creating a completely isolated space that mirrors how things work in production. No matter if you’re working in a virtual private cloud, a traditional data center, or a secure air-gapped environment, you can easily set up Public Endpoints locally. This allows for smooth API-based validation using real data, all while ensuring your data remains private and compliant.

Why this matters for model validation:

  • Confidential and safe assessment of important models prior to launch
  • Quicker testing phases with immediate, on-site analysis
  • Achieving true production parity means the model performs just like it will in real-world scenarios.
  • Facilitates approaches such as shadow testing without depending on the public cloud

By bringing together Local Runners and Public Endpoint abstraction, teams can mimic real-world traffic, evaluate performance, and assess outputs against current models—all before launching in production.

Clarifai Local Runners

4. Packaging & Containerisation

After a model successfully completes validation, it’s time to prepare it for deployment. Our aim is to ensure that the model can easily adapt and be consistently replicated in various settings.

  • ONNX for portability: The Open Neural Network Exchange (ONNX) provides a common model format that enhances flexibility. It’s possible to train a model using PyTorch and then seamlessly export it to ONNX, allowing for inference in another framework. ONNX empowers you to avoid being tied down to a single vendor.
  • Containers for consistency: Tools such as Docker bundle the model, its dependencies, and environment into a self-contained image. Containers stand out because they don’t need a complete operating system for every instance. Instead, they share the host kernel, making them lightweight and quick to launch. A Dockerfile outlines the process for building the image, and the container that emerges from it operates the model with all the necessary dependencies in place.
  • Managing dependencies: Keep a record of each library version and hardware requirement. Not capturing dependencies can result in unexpected outcomes in production.
  • With Clarifai integration, you can effortlessly deploy models and their dependencies, thanks to the platform’s automated packaging features. Our local runners allow you to experiment with models in a containerized setup that reflects Clarifai’s cloud, making sure that your results are consistent no matter where you are.

Clarifai: Seamless Packaging with Pythonic Simplicity

Clarifai makes it easy for developers to package models using its user-friendly Python interface, allowing them to prepare, version, and deploy models with just a few simple commands. Rather than spending time on manual Dockerfile configurations or keeping tabs on dependencies, you can leverage the Clarifai Python SDK to:

  • Sign up and share your models
  • Effortlessly bundle the necessary dependencies
  • Make the model accessible through a public endpoint

This efficient workflow also reaches out to Local Runners. Clarifai effortlessly replicates your cloud deployment in a local containerized environment, allowing you to validate and run inference on-premises with the same reliability and performance as in production.

Benefits:

  • No need for manual handling of Docker or ONNX
  • Quick iterations through straightforward CLI or SDK calls
  • A seamless deployment experience, whether in the cloud or on local infrastructure.

With Clarifai, packaging shifts focus from the complexities of DevOps to enhancing model speed and consistency.Clarifai Compute Orchestration - Model Deployment

5. Deployment & Serving

Deployment is all about bringing the model to life and making it available for everyone to use. There are various approaches, ranging from batch inference to real-time serving, each offering its own set of advantages and disadvantages. Let’s explore these ideas further in the next section.

6. Monitoring & Maintenance

Once they’re up and running, models require ongoing attention and care. They encounter fresh data, which may lead to shifts in data patterns, concepts, or the overall domain. We need to keep an eye on things to spot any drops in performance, biases, or system problems. Keeping an eye on things also helps us refine our triggers for retraining and continuously enhance our processes.

With Clarifai integration, you gain access to Model Performance Dashboards and fairness analysis tools that monitor accuracy, drift, and bias. This ensures you receive automated alerts and can easily manage compliance reporting.

Clarifai Control center

Section 2: Packaging, Containerisation & Environment Management

A model’s behavior can vary greatly depending on the environment, especially when the dependencies are not the same. Packaging and containerization ensure a stable environment and make it easy to move things around.

Standardizing Models with ONNX

The Open Neural Network Exchange (ONNX) serves as a shared framework for showcasing machine learning models. You can train a model with one framework, like PyTorch, and then easily deploy it using a different one, such as TensorFlow or Caffe2. This flexibility ensures you’re not confined to just one ecosystem.

Benefits of ONNX:

  • Models can be executed on various hardware accelerators that are compatible with ONNX.
  • It makes it easier to connect with serving platforms that might have a preference for certain frameworks.
  • It ensures that models remain resilient to changes in frameworks over time.

Containers vs Virtual Machines

Docker brings together the model, code, and dependencies into a single image that operates consistently across different environments. Containers utilize the host operating system’s kernel, which allows them to be lightweight, quick to launch, and secure. Containers offer a more efficient way to isolate processes compared to virtual machines, which require a full operating system for each instance and virtualize hardware.

Key concepts:

  • Dockerfile: A script that outlines the base image and the steps needed to create a container. It guarantees that builds can be consistently recreated.
  • Image: A template created using a Dockerfile. This includes the model code, the necessary dependencies, and the runtime environment.
  • Container: An active version of an image. With Kubernetes, you can easily manage your containers, ensuring they scale effectively and remain highly available.

Dependency & Environment Management

To prevent issues like “it works on my machine”:

  • Consider utilizing virtual environments, like Conda or virtualenv, to enhance your development process.
  • Keep track of library versions and system dependencies by documenting them in a requirements file.
  • Outline the hardware needs, comparing GPU and CPU.

With Clarifai integration, deploying a model is a breeze. The platform takes care of containerization and managing dependencies for you, making the process seamless and efficient. By using local runners, you can replicate the production environment right on your own servers or even on edge devices, guaranteeing that everything behaves the same way across different settings.

Section 3: Model Deployment Strategies: Static and Dynamic Approaches

Selecting the best deployment strategy involves considering aspects such as your comfort with risk, the amount of traffic you expect, and the objectives of your experiments. There are two main types of strategies: static, which involves manual routing, and dynamic, which utilizes automated routing. Let’s dive into each technique together.

Static Strategies

Shadow Evaluation

A shadow deployment involves introducing a new model that runs alongside the existing live model. Both models handle the same requests, but only the predictions from the live model are shared with users. The results from the shadow model are kept for future comparison.

  • Advantages:
    • Minimal risk: Because users don’t see the predictions, any shortcomings of the shadow model won’t affect them.
    • The new model is put to the test using actual traffic, ensuring that the user experience remains unaffected.
  • Drawbacks:
    • Running two models at the same time can significantly increase computing expenses.
    • There’s no feedback from users: It’s unclear how they might respond to the predictions made by the new model.
  • Use case: This is ideal for high-risk applications like finance and healthcare, where ensuring the safety of a new model before it reaches users is crucial.

A/B Testing

A/B testing, often referred to as champion/challenger testing, involves rolling out two models (A and B) to distinct groups of users and evaluating their performance through metrics such as conversion rate or click-through rate.

  • Methodology: We start by crafting a hypothesis, such as “model B enhances engagement by 5%,” and then we introduce the models to various users. Statistical tests help us understand if the differences we observe really matter.
  • Advantages:
    • Genuine user insights: Actual users engage with each model, sharing valuable behavioral data.
    • Through controlled experiments, A/B testing allows us to confirm our ideas regarding changes to the model.
  • Drawbacks:
    • The potential impact on users: Inaccurate predictions could lead to a less enjoyable experience for a while.
    • We’re focusing on just two models for now, as testing several at once can get quite complicated.
  • Use case: This application is ideal for systems that recommend products and for marketing efforts, where understanding user behavior plays a crucial role.

Blue-Green Deployment

In a blue-green deployment, we keep two identical production environments running side by side: the blue environment, which is the current one, and the green environment, which is the new one ready to go. The initial flow of traffic heads towards blue. The latest version has been rolled out to the green environment and is currently being tested with live production traffic in a staging setup. After validation, traffic is directed to green, while blue serves as a backup.

  • Advantages:
    • No interruptions: Users enjoy a seamless experience throughout the transition.
    • Simple rollback: Should the new version encounter issues, traffic can swiftly switch back to blue.
  • Drawbacks:
    • Managing two environments can lead to unnecessary duplication, which often means higher costs and resource demands.
    • Managing complex states: It’s essential to ensure that shared components, like databases, are in sync with one another.
  • Use case: Businesses that value dependability and need to avoid any interruptions (such as banking and e-commerce).

Canary Deployment

A canary deployment introduces a new model to a select group of users, allowing for careful observation of any potential issues before expanding to everyone. Traffic is gradually building for the new model as trust begins to develop.

  • Steps:
    • Direct a small portion of traffic to the new model.
    • Keep an eye on the metrics and see how they stack up against the live model.
    • If the performance aligns with our expectations, let’s gradually boost the traffic; if not, we can revert to the previous state.
  • Advantages:
    • Genuine user testing with low risk: Just a small group of users experiences the new model.
    • Adaptability: We can adjust traffic levels according to performance metrics.
  • Drawbacks:
    • Needs attentive oversight: Swiftly spotting problems is crucial.
    • We understand that some users might experience less than optimal results if the new model has any issues.
  • Use case: Online services where fast updates and swift reversions are essential.

Rolling Deployment

In a rolling deployment, the updated version slowly takes the place of the previous one across a group of servers or containers. For instance, when you have five pods operating your model, you could update one pod at a time with the latest version. Rolling deployments strike a balance between canary releases, which gradually introduce changes to users, and recreate deployments, where everything is replaced at once.

  • Advantages:
    • Our services are always on, ensuring you have access whenever you need it.
    • Gradual rollout: You can keep an eye on metrics after each group is upgraded.
  • Drawbacks:
    • Gradual implementation: Complete replacement requires time, particularly with extensive clusters.
    • The system should make sure that sessions or transactions continue smoothly without any interruptions during the rollout.

Feature Flag Deployment

Feature flags, also known as feature toggles, allow us to separate the act of deploying code from the moment we actually release it to users. A model or feature can be set up but not made available to all users just yet. A flag helps identify which user groups will experience the new version. Feature flags allow us to explore and test different models without the need to redeploy code each time.

  • Advantages:
    • Take charge: You have the ability to turn models on or off in real time for particular groups.
    • Quick rollback: A feature can be disabled immediately without needing to revert a deployment.
  • Drawbacks:
    • Managing flags at scale can be quite a challenge, adding layers of complexity to operations.
    • Unseen technical challenges: Outdated flags can clutter our codebases.
  • Clarifai integration: With Clarifai’s integration, you can easily utilize their API to manage various model versions and direct traffic according to your specific needs. Feature flags can be set up at the API level to determine which model responds to specific requests.

Recreate Strategy

The recreate strategy involves turning off the current model and launching the updated version. This method is the easiest to implement, but it does come with some downtime. This approach could work well for systems that aren’t mission-critical or for internal applications where a brief downtime is manageable.


Dynamic Strategies

Multi-Armed Bandit (MAB)

The multi-armed bandit (MAB) approach is a sophisticated strategy that draws inspiration from reinforcement learning. It seeks to find a harmonious blend between exploring new possibilities (trying out various models) and leveraging what works best (utilizing the top-performing model). In contrast to A/B testing, MAB evolves continuously by learning from the performance it observes.

The algorithm intelligently directs more traffic to the models that are showing great results, all while keeping an eye on those that are still finding their footing. This flexible approach enhances important performance metrics and speeds up the process of finding the most effective model.

  • Advantages:
    • Ongoing improvement: Traffic is seamlessly directed to more effective models.
    • Collaborate with various options: You have the ability to assess multiple models at the same time.
  • Drawbacks:
    • It involves using an online learning algorithm to fine-tune allocations.
    • We need to focus on gathering data in real-time and making decisions swiftly to meet our infrastructure demands.
  • Use case: Systems for personalisation that allow for rapid observation of performance metrics, such as ad click-through rates.

Nuances of Feature Flags & Rolling Deployments

While feature flags and rolling deployments are widely used in software, their use in machine learning deserves a closer look.

Feature Flags for ML

Having detailed control over which features are shown allows data scientists to experiment with new models or features among specific groups of users. For example, an online shopping platform might introduce a new recommendation model to 5% of its most engaged users by using a specific flag. The team keeps an eye on conversion rates and, when they see positive results, they thoughtfully ramp up exposure over time. Feature flags can be paired with canary or A/B testing to design more advanced experiments.

It’s important to keep a well-organized record of flags, detailing their purpose and when they will be phased out. Consider breaking things down by factors like location or device type to help minimize risk. Clarifai’s API has the ability to direct requests to various models using metadata, functioning like a feature flag at the model level.

Rolling Deployments in ML

We can implement rolling updates right at the container orchestrator level, like with Kubernetes Deployments. Before directing traffic to ML models, make sure that the model state, including caches, is adequately warmed up. As you carry out a rolling update, keep an eye on both system metrics like CPU and memory, as well as model metrics such as accuracy, to quickly identify any regressions that may arise. Rolling deployments can be combined with feature flags: you gradually introduce the new model image while controlling access to inference with a flag.


Edge & On-Device Deployment

Some models don’t operate in the cloud. In fields like healthcare, retail, and IoT, challenges such as latency, privacy, and bandwidth limitations might necessitate running models directly on devices. The FSDL lecture notes provide insights into frameworks and important factors to consider for deploying at the edge.

Frameworks for Edge Deployment

  • TensorRT is NVIDIA’s library designed to enhance deep-learning models for GPUs and embedded devices, seamlessly working with applications like conversational AI and streaming.
  • Apache TVM transforms models into efficient machine code tailored for different hardware backends, making deployment both portable and optimized.
  • TensorFlow Lite: Transforms TensorFlow models into a compact format designed for mobile and embedded applications, while efficiently managing resource-saving optimizations.
  • PyTorch Mobile allows you to run TorchScript models seamlessly within your iOS and Android applications, utilizing quantization techniques to reduce model size.
  • Core ML and ML Kit are the frameworks from Apple and Google that enable on-device inference.

Model Optimisation for the Edge

Techniques like quantisation, pruning, and distillation play an essential role in minimizing model size and enhancing speed. For instance, MobileNet employs downsampling methods to ensure accuracy is preserved while adapting to mobile devices. DistilBERT cuts down the number of parameters in BERT by 50%, all while keeping 95% of its performance intact.

Deployment Considerations

  • When selecting hardware, it’s important to pick options that align with the needs of your model. Address hardware limitations from the start to prevent significant redesigns down the line.
  • It’s essential to test the model on the actual device before rolling it out. This ensures everything runs smoothly in the real world.
  • Fallback mechanisms: Create systems that allow us to revert to simpler models when the primary model encounters issues or operates at a slower pace.
  • With Clarifai’s on-prem deployment, you can run models directly on your local edge hardware while using the same API as in the cloud. This makes integration easier and guarantees that everything behaves consistently.

Section 4: Model Serving Paradigms: Batch vs Real-Time

How does a model provide predictions in practice? We have a variety of patterns, each designed to meet specific needs. Getting to know them is essential for ensuring that our deployment strategies resonate with the needs of the business.

Batch Prediction

In batch prediction, models create predictions in advance and keep them ready for future use. A marketing platform might analyze customer behavior overnight to forecast potential churn and save those insights in a database.

  • Advantages:
    • Streamlined: With predictions created offline, there’s a reduction in complexity.
    • When it comes to low latency demands, batch predictions don’t require immediate responses. This allows you to plan and execute jobs during quieter times.
  • Drawbacks:
    • Outdated outcomes: Users consistently encounter predictions from the most recent batch run. If your data evolves rapidly, the forecasts could become less relevant.
    • Batch processing has its limitations and isn’t the best fit for scenarios such as fraud detection or providing real-time recommendations.

Model-In-Service

The model is integrated directly into the same process as the application server. Predictions are created right within the web server’s environment.

  • Advantages:
    • Make the most of what you already have: There’s no need to set up additional serving services.
  • Drawbacks:
    • Resource contention: When large models use up memory and CPU, it can impact the web server’s capacity to manage incoming requests.
    • Rigid scaling: The server code and model grow in tandem, regardless of whether the model requires additional resources.

Model-As-Service

This approach separates the model from the application. The model is set up as an independent microservice, providing a REST or gRPC API for easy access.

  • Advantages:
    • Scalability: You have the flexibility to select the best hardware (like GPUs) for your model and scale it on your own terms.
    • Dependability: If the model service encounters an issue, it won’t automatically bring down the main application.
    • Reusability: Different applications can utilize the same model service.
  • Drawbacks:
    • Extra delays: When network calls are made, they can introduce some overhead that might affect how users experience our service.
    • Managing infrastructure can be challenging: it involves keeping another service running smoothly and ensuring effective load balancing.
  • Clarifai integration: With Clarifai integration, you can access deployed models via secure REST endpoints, ensuring a seamless and safe experience. This model-as-service approach offers auto-scaling and high availability, allowing teams to focus on what truly matters instead of getting bogged down by low-level infrastructure management.

Section 5: Safety, Ethics & Compliance in Model Deployment

Creating AI that truly serves humanity means we need to think about ethics and compliance at every step of the journey. Deploying models enhances their effectiveness, highlighting the importance of safety even further.

Data Privacy & Security

  • Ensuring compliance: Implement models that align with regulations like GDPR and HIPAA. This involves making sure that data is anonymized, pseudonymized, and stored securely.
  • Keep your data and model parameters safe, whether they’re stored away or being transferred. Implement secure API protocols such as HTTPS and ensure that access control measures are strictly enforced.

Bias, Fairness & Accountability

  • Assessing fairness: Review how models perform among different demographic groups. Solutions such as Clarifai’s fairness assessment offer valuable insights to identify and address unequal impacts.
  • Be open about the training process of our models, the data they rely on, and the reasoning behind the decisions we make. This builds trust and encourages responsibility.
  • Evaluating potential risks: Understand possible consequences before launching. For applications that carry significant risks, such as hiring or credit scoring, it’s important to perform regular audits and follow the appropriate standards.

Model Risk Management

  • Set up governance frameworks: Clearly outline the roles and responsibilities for approving models, providing sign-off, and overseeing their performance.
  • Keep a record of model versions, training data, hyperparameters, and deployment choices to ensure transparency and accountability. These logs play an essential role in our investigations and help ensure we meet compliance requirements.
  • Clarifai integration: We’re excited to share that our integration with Clarifai ensures a secure experience, as their platform meets ISO 27001 and SOC 2 compliance standards. It offers detailed access controls, keeps track of audit logs, and provides role-based permissions, along with tools for fairness and explainability to ensure compliance with regulatory standards.

Cost Optimisation & Scalability

Putting models into production comes with costs for computing, storage, and ongoing maintenance. Finding the right balance between cost and reliability involves considering various important factors.

Scaling Strategies

  • Horizontal vs vertical scaling: When it comes to scaling, you have two options: you can either add more instances to distribute the load horizontally or invest in more powerful hardware to enhance performance vertically. Horizontal scaling offers flexibility, while vertical scaling might be easier but comes with restrictions.
  • Autoscaling: Implement a system that intuitively adjusts the number of model instances in response to varying traffic levels. Our cloud partners and Clarifai’s deployment services are designed to effortlessly support autoscaling.
  • Serverless inference: With serverless inference, you can leverage functions-as-a-service like AWS Lambda and Google Cloud Functions to run your models efficiently, ensuring you only pay for what you use and keeping idle costs to a minimum. They work great for tasks that need quick bursts of activity, but there might be some delays to consider.
  • GPU vs CPU: When comparing GPUs and CPUs, it’s clear that GPUs enhance the speed of deep learning inference, although they come with a higher price tag. For smaller models or when the demand isn’t too high, CPUs can do the job just fine. With tools like NVIDIA Triton, you can efficiently support multiple models at once.
  • Batching and micro-batching: Combining requests into batches, or even micro-batches, can significantly lower the cost for each request on GPUs. Yet, it does lead to higher latency.

Cost Monitoring & Optimisation

  • Spot instances and reserved capacity: Cloud providers provide cost-effective computing options for those willing to embrace flexibility or make long-term commitments. Utilize them for tasks that aren’t mission-critical.
  • Caching results: For idempotent predictions (e.g., text classification), caching can reduce repeated computation.
  • Observability: Monitor compute utilisation; scale down unused resources.
  • Clarifai integration: Clarifai’s compute orchestration engine automatically scales models based on traffic, supports GPU and CPU backends, and offers cost dashboards to track spending. Local runners allow on-prem inference, reducing cloud costs when appropriate.

Choosing the Right Deployment Strategy

With multiple strategies available, how do you decide? Consider the following factors:

  • Risk tolerance: If errors carry high risk (e.g., medical diagnoses), start with shadow deployments and blue-green to minimise exposure.
  • Speed vs safety: A/B testing and canary deployments enable rapid iteration with some user exposure. Rolling deployments offer a measured balance.
  • User traffic volume: Large user bases benefit from canary and MAB strategies for controlled experimentation. Small user bases might not justify complex allocation algorithms.
  • Resource availability: Blue-green strategies involve keeping two environments up and running. If resources are tight, using canary or feature flags might be a more practical approach.
  • Measurement capability: When you can swiftly capture performance metrics, MAB can lead to quicker enhancements. When we lack dependable metrics, opting for simpler strategies feels like a more secure choice.
  • Decision tree: Let’s begin by considering your risk tolerance: if it’s high, you might want to explore options like shadow or blue-green. Moderate → canary or A/B testing. Low → rolling or reimagining. For continuous improvement, think about MAB.
  • Clarifai integration: With Clarifai’s deployment interface, you can easily test various models side-by-side and smoothly manage the traffic between them as needed. Our integrated experimentation tools and APIs simplify the process of implementing canary, A/B, and feature-flag strategies, eliminating the need for custom routing logic.

Emerging Trends & Future Directions

LLMOps and Foundation Models

When it comes to deploying large language models such as GPT, Claude, and Llama, there are some important factors to keep in mind. These systems demand significant resources and need effective ways to manage prompts, handle context, and ensure safety measures are in place. Deploying LLMs frequently includes using retrieval-augmented generation (RAG) alongside vector databases to ensure that responses are anchored in precise knowledge. The emergence of LLMOps—essentially MLOps tailored for large language models—introduces tools that enhance prompt versioning, manage context effectively, and establish safeguards to minimize hallucinations and prevent harmful outputs.

Serverless GPUs & Model Acceleration

Cloud providers are rolling out serverless GPU options, allowing users to access GPUs for inference on a pay-as-you-go basis. When we bring micro-batching into the mix, we can really cut down on costs without sacrificing speed. Moreover, inference frameworks such as ONNX Runtime and NVIDIA TensorRT enhance the speed of model serving across various hardware platforms.

Multi-Cloud & Hybrid Deployment

To steer clear of vendor lock-in and fulfill data-sovereignty needs, numerous organizations are embracing multi-cloud and hybrid deployment strategies. Platforms such as Kubernetes and cross-cloud model registries assist in overseeing models across AWS, Azure, and private cloud environments. Clarifai offers flexible deployment options, allowing you to utilize its API endpoints and on-premises solutions across multiple cloud environments.

Responsible AI & Model Cards

The future of deployment is about balancing performance with a sense of responsibility. Model cards provide insights into how a model is meant to be used, its limitations, and the ethical aspects to consider. New regulations might soon call for comprehensive disclosures regarding AI applications that are considered high-risk. Platforms such as Clarifai are seamlessly weaving together documentation workflows and automated compliance reporting to meet these essential needs.


Conclusion & Actionable Next Steps

Bringing models to life connects the world of data science with tangible results in everyday situations. When organizations take the time to grasp the deployment lifecycle, pick the right serving approach, package their models effectively, choose suitable deployment strategies, and keep an eye on their models after they go live, they can truly unlock the full potential of their machine-learning investments.

Key Takeaways

  • Think ahead and plan for deployment from the beginning: It’s essential to integrate infrastructure, data pipelines, and monitoring into your initial strategy, rather than treating deployment as an afterthought.
  • Select a serving approach that aligns with your needs for latency and complexity: opt for Batch processing for offline tasks, utilize model-in-service for straightforward setups, or go with model-as-service for a scalable and reusable architecture.
  • For seamless portability, leverage ONNX and Docker to maintain consistent performance across different environments.
  • Choose a deployment strategy that fits your comfort level with risk: Static approaches such as shadow or blue-green help reduce risk, whereas dynamic methods like MAB speed up the optimization process.
  • Keep a close eye on everything: Stay on top of model, business, and system metrics, and be ready to retrain or revert if you notice any changes.
  • Integrate ethics and compliance: Honor data privacy, promote fairness, and keep clear audit trails.
  • Stay ahead by embracing the latest trends: LLMOps, serverless GPUs, and responsible AI frameworks are transforming how we deploy technology. Keeping yourself informed is key to staying competitive.

Next Steps

  • Take a closer look at your current deployment process: Spot any areas where packaging, strategy, monitoring, or compliance might be lacking.
  • Select a deployment strategy: Refer to the decision tree above to find the strategy that best aligns with your product’s requirements.
  • Establish a system for monitoring and alerts: Create user-friendly dashboards and define thresholds for important metrics.
  • Experience Clarifai’s deployment solutions firsthand: Join us for a trial and dive into our compute orchestration, model registry, and monitoring dashboards. The platform provides ready-to-use pipelines for canary, A/B, and shadow deployments.
  • Grab your free deployment checklist: This helpful resource can guide your team through preparing the environment, packaging, choosing a deployment strategy, and monitoring effectively.

Bringing machine-learning models to life can be challenging, but with the right approaches and resources, you can transform prototypes into production systems that truly provide value. Clarifai’s comprehensive platform makes this journey easier, enabling your team to concentrate on creativity instead of the technical details.

Clarifai Model Deployment


Frequently Asked Questions (FAQs)

Q1: What’s the difference between batch prediction and real-time serving? Batch prediction processes offline tasks that create predictions and save them for future use, making it perfect for scenarios where quick responses aren’t critical. Real-time serving offers instant predictions through an API, creating engaging experiences, though it does necessitate a stronger infrastructure.

Q2: How do I decide between A/B testing and multi-armed bandits? Implement A/B testing when you’re looking to conduct controlled experiments that are driven by hypotheses, allowing for a comparison between two models. Multi-armed bandits excel in continuous optimization across various models, especially when performance can be assessed rapidly.

Q3: What is data drift and how can I detect it? Data drift happens when the way your input data is distributed shifts over time. Identify drift by looking at statistical characteristics such as means and variances, or by employing metrics like the KS statistic and D1 distance to assess differences in distributions.

Q4: Do feature flags work for machine-learning models? Absolutely. Feature flags allow us to control which model versions are active, making it easier to introduce changes slowly and revert quickly if needed. These tools are particularly handy when you want to introduce a new model to targeted groups without the need for redeployment.

Q5: How does Clarifai help with model deployment? Clarifai offers a seamless platform that brings together automated deployment, scaling, and resource management, along with a model registry for version control and metadata. It also includes inference APIs that function as a model-as-a-service and monitoring tools featuring performance dashboards and fairness audits. It also enables local runners for on-prem or edge deployments, making sure performance remains consistent no matter the environment.

Q6: What are some considerations for deploying large language models (LLMs)? Managing prompts, context length, and safety filters for LLMs is essential. Deployment frequently includes retrieval-augmented generation to provide well-founded responses and may utilize serverless GPU instances to enhance cost efficiency. Services like Clarifai’s generative AI offer user-friendly APIs and safeguards to ensure that LLMs are used responsibly.