A new beginning for Windows PCs starts tomorrow with the launch of NVIDIA RTX Spark — one PC built for creators, gamers and AI agents. All are invited to celebrate with NVIDIA and partners at launch events around the world.
Share Your Spark
Every PC has a story. What was your first Windows PC, and what did it spark a love for? Join the celebration online by sharing responses with #ShareYourSpark for a chance to win an ASUS ProArt P14 RTX Spark laptop signed by NVIDIA founder and CEO Jensen Huang. See the campaign and official rules.
See What Reviewers Are Saying
From local AI workflows to creative apps and gaming, see what reviewers are saying about RTX Spark — then experience it at a launch celebration.
“The fact that NVIDIA, Microsoft and their partners have delivered such a capable, compatible and polished platform even in its first at-bat should put the rest of the PC industry on notice.” — Tom’s Hardware
“I tested NVIDIA’s RTX Spark for gaming and local AI – the performance absolutely stunned me.” — TrustedReviews, UK
“I’m very happy to report that performance is actually looking really good when it comes to AI, gaming and creative workflows.” — Microcenter
“[RTX Spark] is a different species of computer that has arrived early. It is a statement of intent from NVIDIA about where computing is going — trading raw benchmarking crowns for the ability to carry a self-rewriting, fully autonomous, CUDA-accelerated digital brain in your backpack.” — Tom’s Guide
“One of the most impressive parts of the launch is how many apps NVIDIA has worked with to ensure optimisation with the Spark technology.” —Creative Bloq
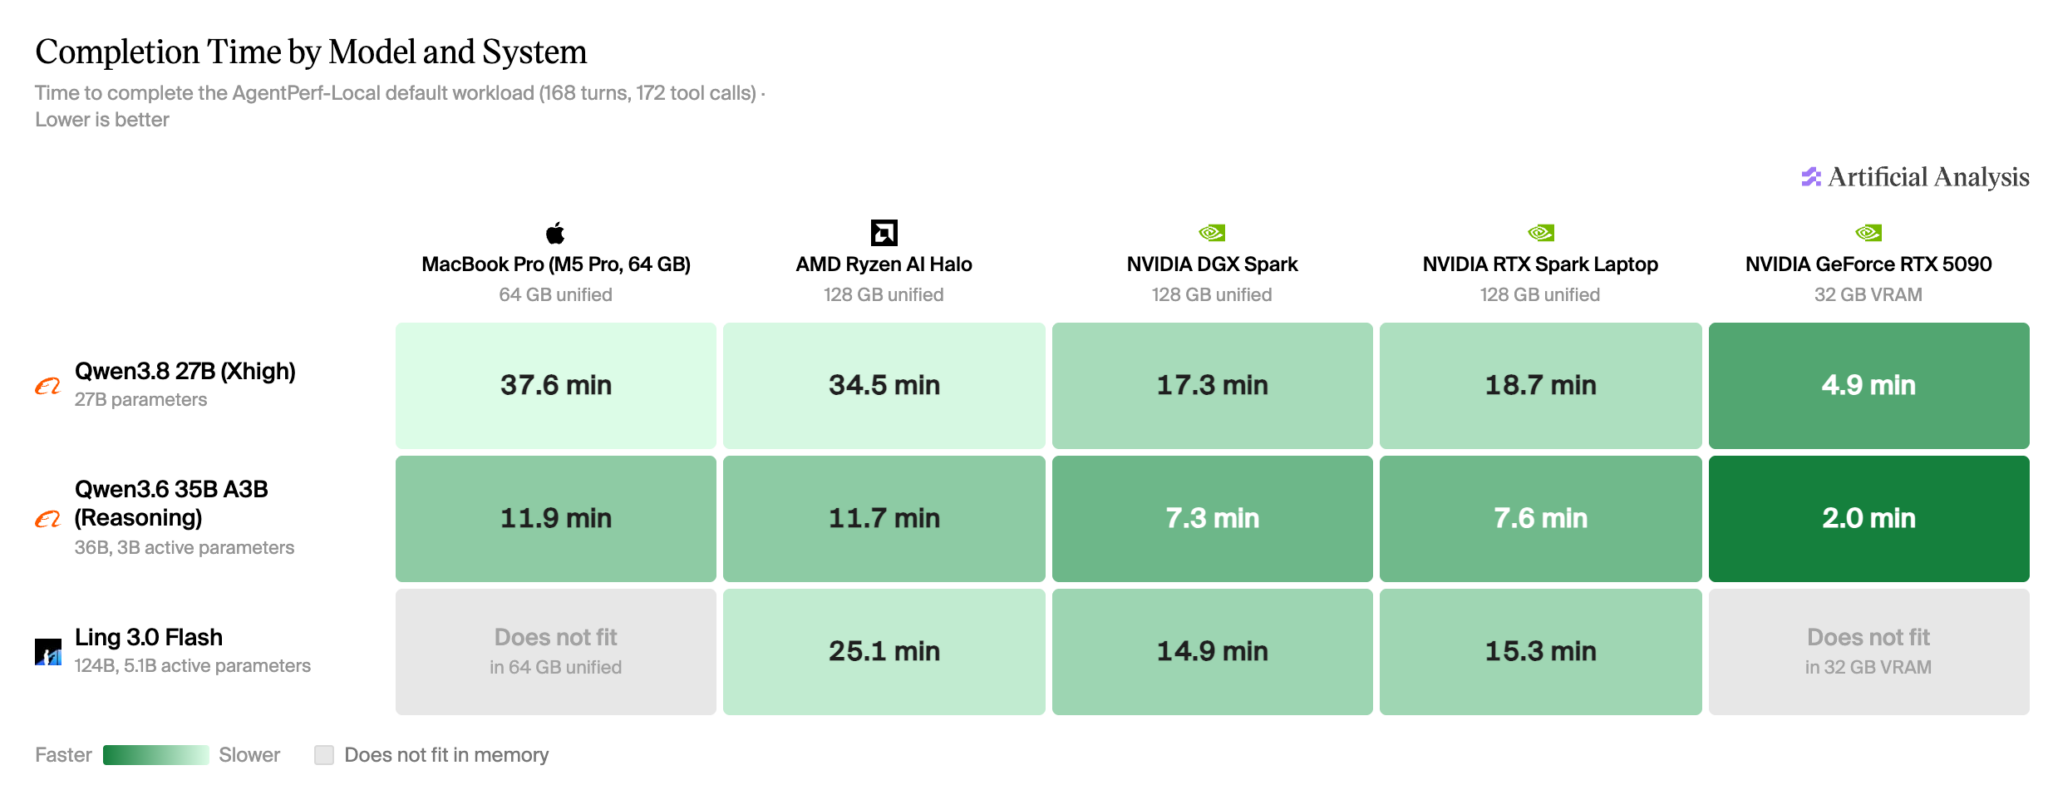
Independent testing from Artificial Analysis offers an early look at the powerful local AI performance RTX Spark brings to a laptop.
Join the Launch Celebrations
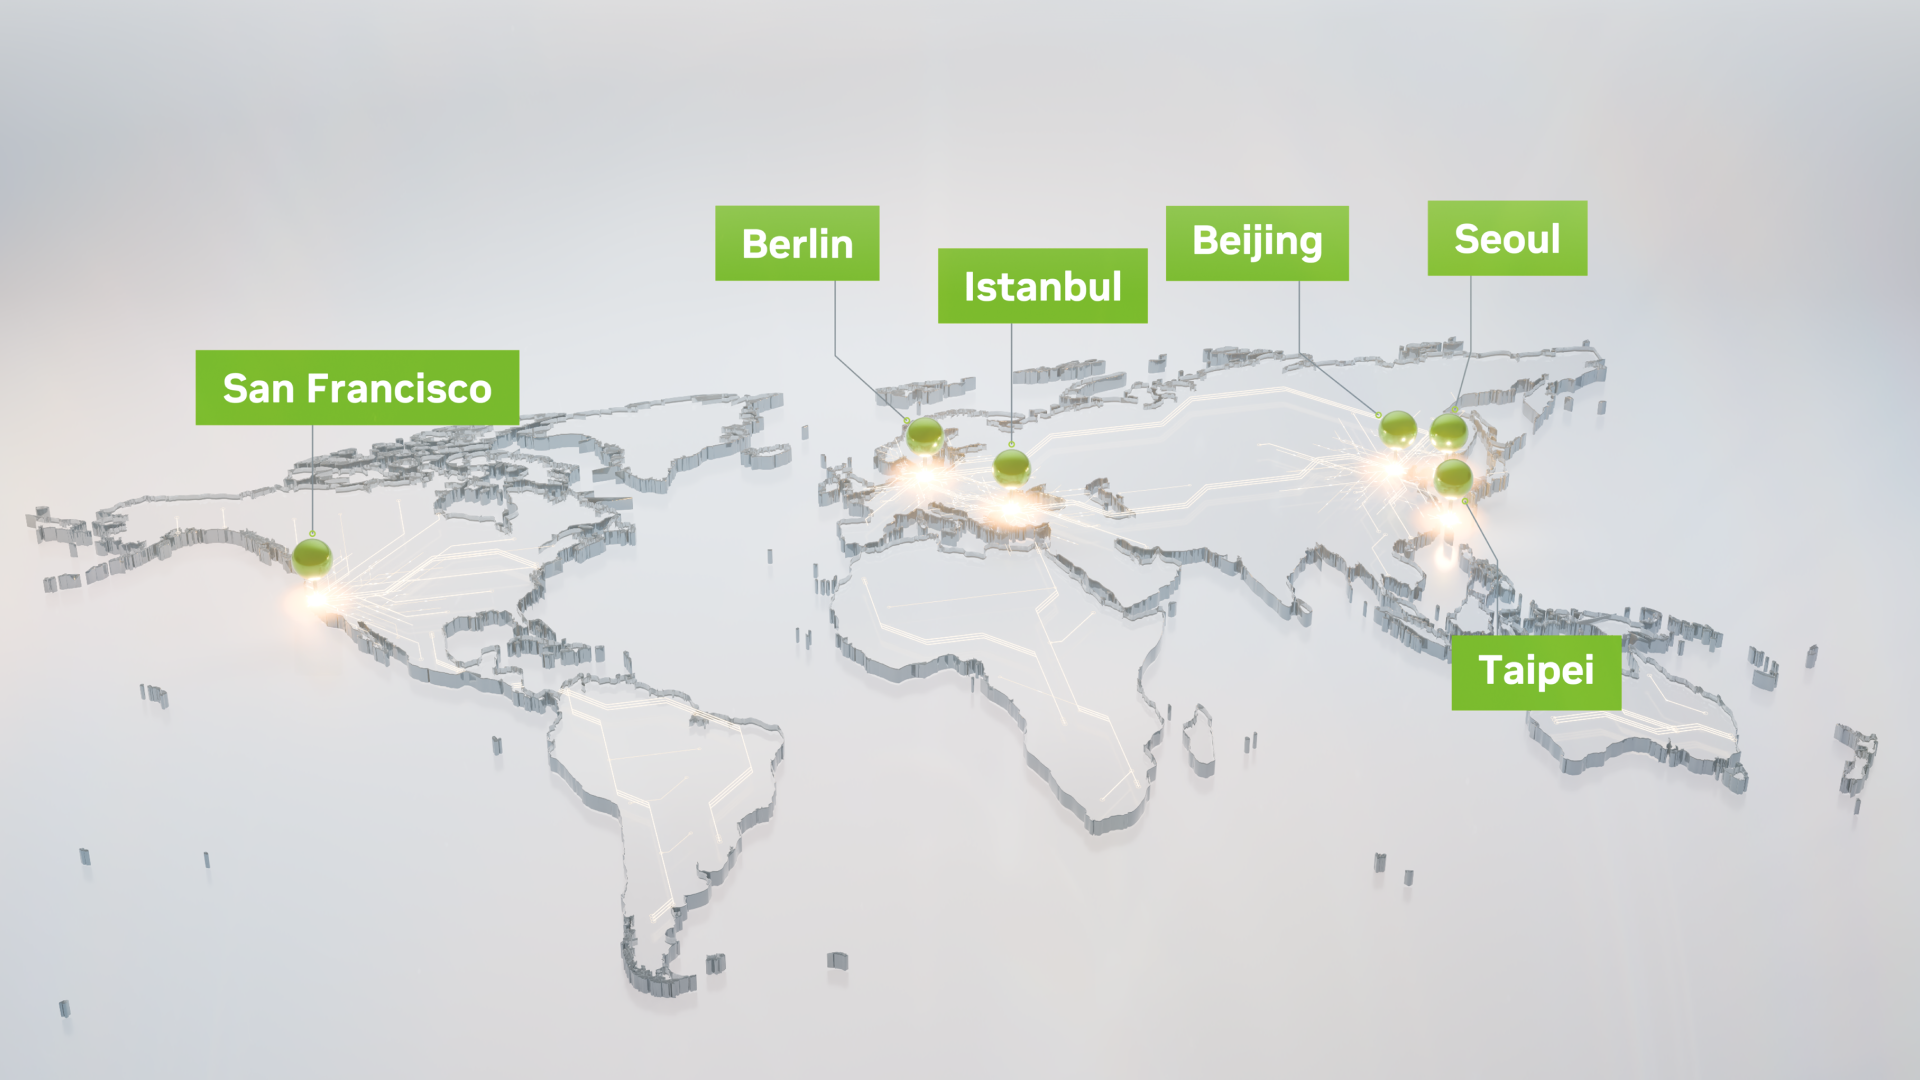
On Friday, Oct. 16, get hands on with RTX Spark at launch events around the world. Explore demos for creating, developing and gaming, connect with fellow enthusiasts and discover what local AI can do.
Times below are local. Follow each event’s entry instructions. Space is limited.
San Francisco — Best Buy, 1717 Harrison Street, 10 a.m.-12 p.m. Try hands-on demos, meet iJustine and hear fireside conversations with local tech founders. Free, first-come, first-served entry; no ticket required. Event details.
Berlin — Xperion at Saturn, Alexanderplatz 3, 7-10:30 p.m. Explore hands-on demos and stage programming with creators and developers. Registration required. RSVP.
Taipei — Muse Garden, No. 88 Yanchang Road. Join an evening of demos, music and AI community discussions, with shopping and networking continuing until 10:15 p.m. Registration required.
Beijing — JD MALL Beijing Shuangjing Store, No. 31 Guangqu Road. Check in begins at 7 p.m. Launch celebration starts at 8 p.m., followed by hands-on demos. Event concludes at 9:30 p.m. Register through WeChat.
Istanbul — Vatan Bilgisayar Topkapı, Mevlana Caddesi No. 138. Explore hands-on demos and local creator programming. Walk-in entry; no advance registration required.
Seoul — COEX East Lobby, 513 Yeongdong-daero. Hands-on demos begin at 7 p.m., with gaming and AI creator programming from 8 p.m. Event concludes at 9:30 p.m. No advance registration required.
As AI agents move from experiments into everyday development, increasingly capable open models are shrinking to fit on more devices, giving builders more to run locally.
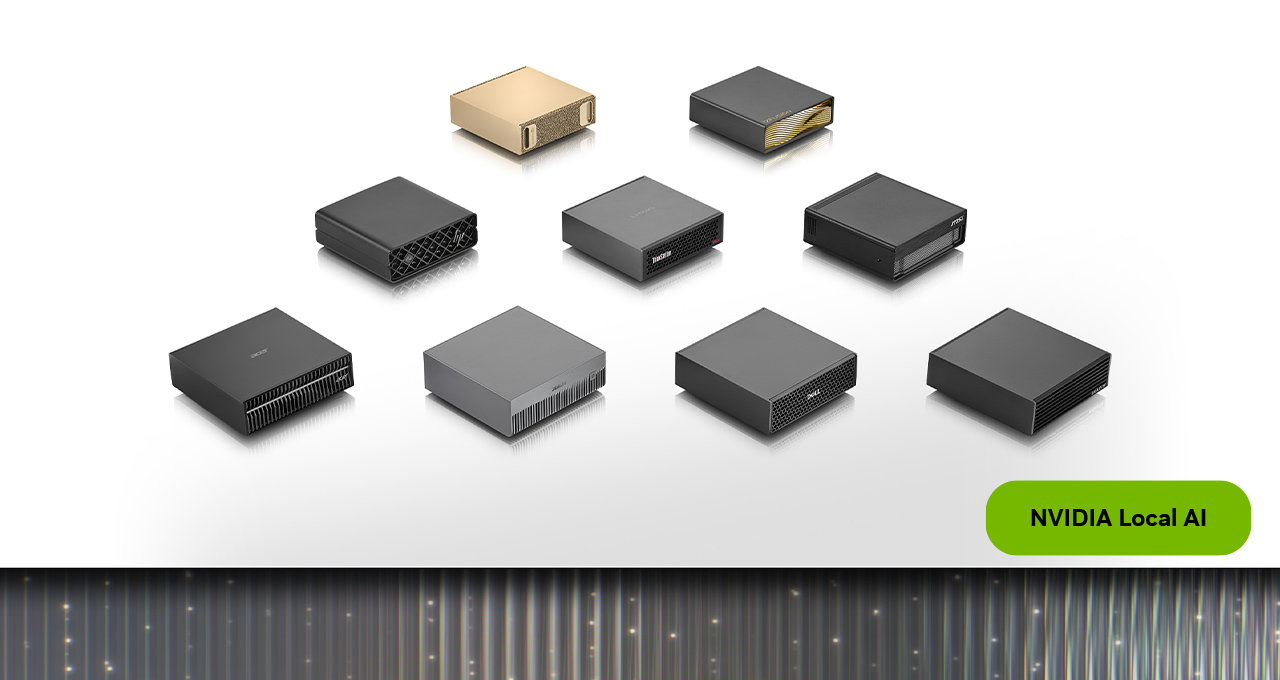
Coming this month, NVIDIA DGX Spark will be available with 64GB of unified memory from top manufacturer partners — Acer, ASUS, Dell, Gigabyte, HP and MSI — giving developers, researchers and AI enthusiasts a new configuration with DGX OS and the NVIDIA AI software stack ready to use from day one.
The new SKU runs capable local agents on device — privately, without cloud dependency. And when workloads grow, two units can cluster together via NVIDIA Sync Cluster Assistant without any additional setup.
A New Starting Point for Personal AI Supercomputing
DGX Spark combines NVIDIA Grace Blackwell compute, unified memory, NVIDIA ConnectX-7 networking and an NVIDIA CUDA-accelerated AI software stack in one system. It’s a complete local AI platform for agents, inference, fine-tuning, data science and edge development.
The compact, personal AI supercomputer provides a place to experiment with models and developers’ own data without turning to a cloud instance for every task.
The new 64GB configuration, available exclusively from manufacturer partners, keeps the platform at an accessible price point while retaining the GB10 Grace Blackwell Superchip, DGX OS and full NVIDIA AI software stack — same as the 128GB model. It supports up to 100-billion-parameter models and the agentic applications built on them, fully on device.
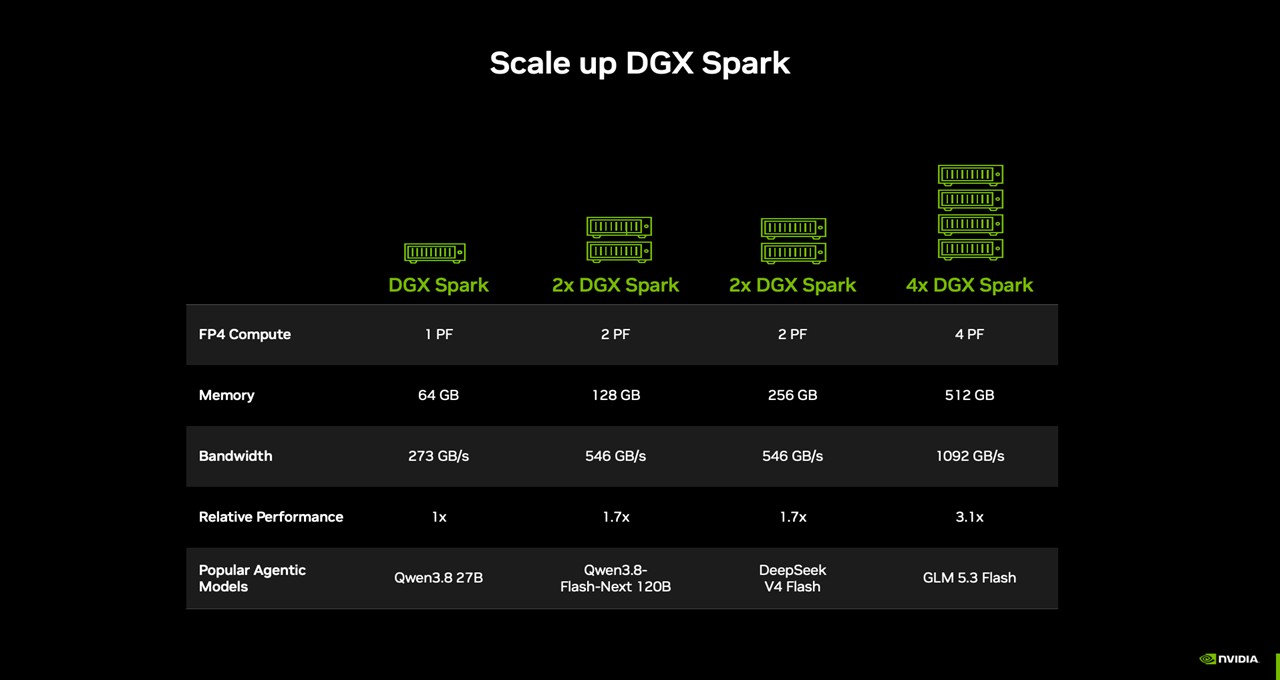
Two 64GB units clustered together don’t just double the memory. In NVIDIA’s Qwen 3.8 27B test, two clustered 64 GB systems delivered up to 1.7x performance compared with a single system, with room to keep scaling as workloads demand.
DGX Spark ships ready for agent development from day one — NVIDIA Agent Toolkit, CUDA-X AI libraries, Nemotron open models, and popular runtimes like Ollama, vLLM, and PyTorch with CUDA are all supported out of the box. Developers can go from power-on to running models in minutes.
Developers can start with the memory their projects need today and build on a platform designed to seamlessly scale multi-node clusters for larger workloads as their pipelines grow.
Every DGX Spark ships with a built-in NVIDIA ConnectX-7 NIC right out of the box. Plus, two units can connect directly with a QSFP cable, pooling their memory to 128GB and expanding model support to up to 200 billion parameters while delivering twice the memory bandwidth and up to 1.7x the performance.
The NVIDIA Sync app configures this multi-node cluster seamlessly. The cluster assistant feature detects connected units, validates device configuration and configures the ConnectX-7 network, so developers can focus on their work rather than the infrastructure. Every node runs the same NVIDIA software stack, so nothing needs to be reconfigured when scaling from one unit to two.
And coming at the end of the month, NVIDIA Sync Model Launcher makes running local AI as simple as clicking a few buttons. Developers can download and launch Qwen3.8 27B on a single DGX Spark system or a cluster, with NVIDIA Sync configuring the model to run across connected devices and making it accessible from users’ laptops. The launcher will also set up OpenCode to use the model, so developers can start coding in their browser.
Developer Use Cases on DGX Spark
The new DGX Spark 64GB configuration supports practical work from day one. With up to 100-billion-parameter models running entirely on device, developers and enthusiasts can start with a single system for models that fit within its memory, or connect multiple DGX Spark systems with NVIDIA Sync Cluster Assistant for workloads that need more memory and compute.
Here are three workflow examples:
Run an AI agent around the clock: Keep a coding or research agent running on DGX Spark, ready to review code, analyze documents or carry out multistep tasks. A cluster provides additional capacity for larger models, longer context windows or multiple agents working at once.
Power AI apps on your everyday PC: Run a language- or image-generation model on DGX Spark while using an agent or creative application on laptops or desktops. DGX Spark handles the model inference, freeing PCs for other work.
Scale when the work grows: When a single task outgrows one unit — running a larger model, a longer context window or concurrent agent requests — two DGX Spark 64GB systems connected over the 200 GbE fabric via NVIDIA Sync Cluster Assistant pool their memory to 128GB. The same workflow that ran on one unit scales to two without reconfiguring the software environment.
Get Started With DGX Spark
DGX Spark 64GB is available from Acer, ASUS, Dell, Gigabyte, HP and MSI on Friday, Oct. 23, starting at $4,999.
To get started:
Download a supported inference framework — llama.cpp, Ollama, vLLM or LM Studio.
Download the recommended local model for the workflow.
To scale to two units, connect them via their NVIDIA ConnectX-7 ports and launch NVIDIA Sync Cluster Assistant — it configures the network and routes workloads automatically.
Explore playbooks onbuild.nvidia.com/spark for DGX Spark. The following playbooks are coming soon to 64GB devices:
Serve LLMs With vLLM
Run OpenClaw With a Local LLM
Connect Multiple DGX Sparks for Distributed Workloads
New Windows PCs powered by NVIDIA RTX Spark are coming this month from Acer, ASUS, Dell, HP, Lenovo, Microsoft and MSI. Sign up for the RTX Spark newsletter to receive future updates.
Alibaba’s Qwen-Image-2.1 brings image generation and editing together in a lightweight, open-weight model. It runs locally on NVIDIA RTX GPUs, DGX Spark and DGX Station, giving creators more ways to create and refine images on their own hardware.
Frontier intelligence is going local. At IFA 2026, NVIDIA, Microsoft and its partners are teaming up to provide faster inference and new tools that make agents easier to set up and run locally on NVIDIA hardware. New compact NVIDIA RTX Spark Windows PCs are also coming in October to give AI enthusiasts, developers and creators more ways to run capable agents locally and securely.
Today’s announcements include:
Simplified local AI support for NVIDIA GPUs is coming in Hermes Agent, OpenClaw and Perplexity Portable Computer.
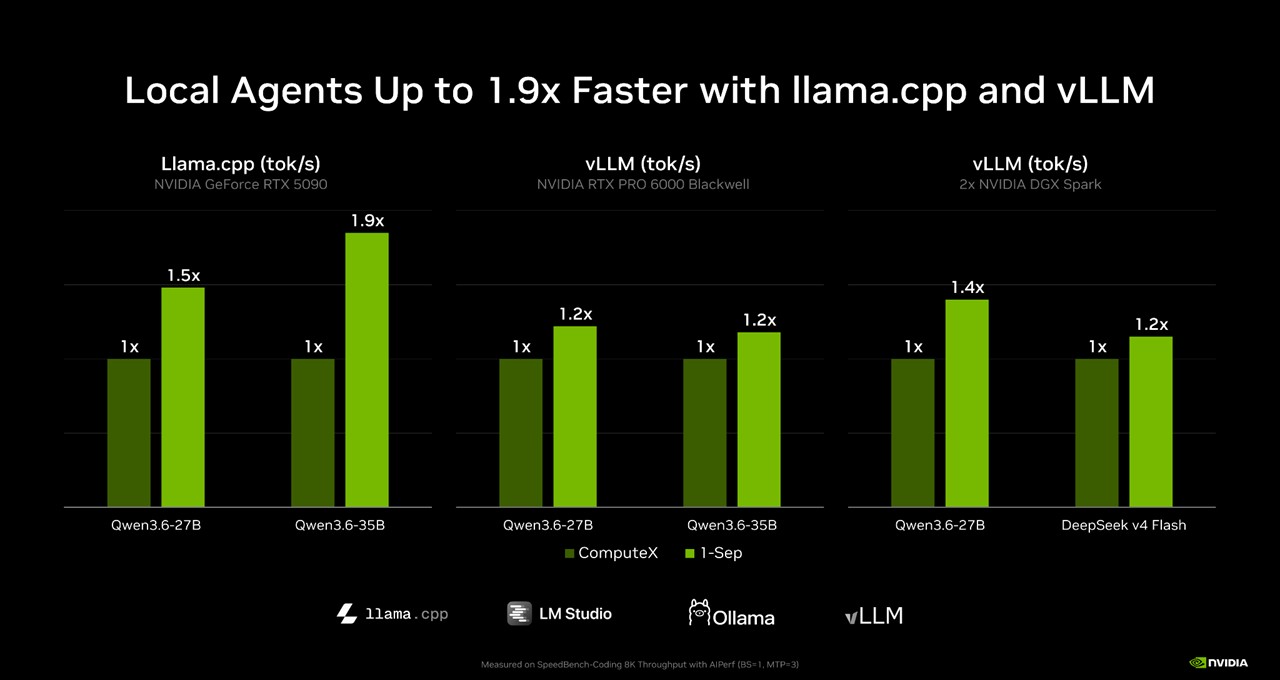
Up to 1.9x faster local inference — new llama.cpp and vLLM optimizations are available now directly and through LM Studio and Ollama.
NVIDIA PAIR — a Personal AI Router tool that intelligently distributes AI inference across the PCs on a user’s local network.
NVIDIA RTX Spark arrives in October — with new Windows PCs from Lenovo and Acer. Electronic Arts, Embark and Ubisoft are among the latest game publishers and developers bringing their blockbuster titles to NVIDIA RTX Spark.
Nemotron 3.5 Lightning — which can run on NVIDIA RTX PCs, RTX PRO Workstations, DGX Spark and Jetson — is a 30-billion parameter model that has been launched. Get started with Nemotron 3.5 Lightning today.
Z.ai’s GLM-5.3-Flash is a multimodal mixture-of-experts (MoE) model that’s bringing agentic AI to DGX Station.
Qwen has released Qwen3.8-Flash-Next, an open weight multimodal MoE model, which can run locally on DGX Spark and DGX Station, along with Qwen3.8-27B, a 27-billion-parameter open model optimized for local agentic and coding workloads on NVIDIA GPUs.
LTX’s LTX 2.5 is an open-world video generation model optimized for NVIDIA RTX GPUs, DGX Spark and DGX Station, with new NVFP4, FastVideo and ComfyUI enhancements for faster, more memory-efficient local generation.
MiniMax-H3is an open-weight video generation model with synchronized audio that can run locally on NVIDIA GPUs through ComfyUI. FastVideo teamed up with NVIDIA researchers to improve this further by releasing FastH3 — an open-weight, four-step distilled version that improves performance by 7x. Optimized FastVideo recipes for NVIDIA RTX GPUs and DGX Spark are coming soon.
Meta’s Muse Glimmer is a 30-billion-parameter open-weight model for coding and agentic workloads that can run locally on GeForce RTX PCs, DGX Spark, DGX Station and Jetson. NVIDIA has also released NVFP4 quantization with DGX Spark support for more memory-efficient local deployment.
DeepSeek v4 Flash is a 284-billion-parameter MoE model with 13 billion active parameters that can run locally on 2x DGX Spark cluster and DGX Station.
A Simpler Start for Local Agents
Getting a local agent up and running with local models required some effort — choosing a model, finding a compatible inference server, dialing in quantization settings and keeping everything updated. That friction is disappearing on RTX and DGX systems.
Three of the most widely used agent apps will offer simplified local model setup on Windows, each built on llama.cpp and incorporating NVIDIA’s latest inference optimizations. The new setup experiences are designed to reduce manual configuration and make it easier to get local agents up and running.
Last month, Perplexity introduced its Portable Computer agent, giving users a simple way to run Perplexity locally on Linux systems like NVIDIA DGX Spark with the models, orchestration and tools packaged into a single app experience.
Perplexity Portable Computer is available on NVIDIA RTX GPUs with at least 24GB VRAM running on Linux, with support on Windows coming soon, bringing that same streamlined setup to a broader group of PC users. Users can run complete workflows locally without consuming credits, while selectively escalating parts of a task to one of 15+ frontier models in the cloud when additional research or reasoning is needed. Portable Computer asks for permission before sending content to the cloud, helping users keep sensitive information on their device. Here’s some example use-cases:
Engineering: Review open PRs in a connected GitHub repo and sort them into ready, blocked, stale, and needs review, each tagged with the next step. Docs that fell out of sync with the latest merge get caught and fixed, with a PR opened for the changes.
Finance: Point the agent at two years of brokerage summaries, consolidated 1099s and tax returns and have it trace the recurring holdings creating the most avoidable fees and tax drag, with every figure cited to the exact file and page — all without a document ever reaching a chatbot.
Startups: Ask why activation went flat, and the agent analyzes the funnel export locally to find where new signups drop off between install and first completed task, then posts the top insights straight to the team’s Slack channel.
Hermes Agent — developed by Nous Research — is a general-purpose agent used by millions that excels at reliability and self-improvement. Model- and provider-agnostic, Hermes is built to run all day on local systems, making RTX PCs, RTX PRO workstations and DGX Spark a natural fit.
Configuring a local model in Hermes will provide users with one-click setup across RTX and DGX systems on Windows. The agent will automatically detect the NVIDIA GPU, select an appropriate model and configuration, and run it through integrated llama.cpp with NVIDIA inference optimizations already in place, eliminating manual model downloads and tuning. Support for Linux is coming soon.
Once it is running, Hermes works the way it does anywhere else. It uses tools, maintains context across tasks, remembers information between sessions and creates reusable skills over time, allowing the agent to become more capable with continued use. Running the model locally on a GPU keeps performance fast while keeping data on the system.
One-click local model setup is available now on Windows, with support coming soon to Linux. Learn more about Hermes Agent.
OpenClaw has become one of the defining projects of the open-agent movement — the largest AI project on GitHub, with more than 380K stars and a fast-growing community that’s building tools and skills across research, engineering, project management and everyday productivity.
NVIDIA, Microsoft and OpenClaw have been working together to make that experience easier to set up on Windows PCs. To reduce onboarding friction, the OpenClaw Windows App simplifies the process of setting up an optimized local model on any RTX GPU with at least 24GB of VRAM.
Learn more in the OpenClaw blog.
Faster Inference Gives Local Agents a Boost
Inference performance is critical to keeping local agents responsive. NVIDIA is continuing to collaborate with the open-source llama.cpp and vLLM communities to accelerate agentic workloads across local NVIDIA platforms.
llama.cpp delivers up to 1.9x higher throughput through kernel optimizations on a GeForce RTX 5090, enhanced speculative decoding techniques and faster prefill.
vLLM delivers 1.2x on RTX PRO 6000 Blackwell Workstation Edition and up to 1.4x on two DGX Spark clusters. New XQA attention kernels in FlashInfer and backend optimizations help to accelerate inference across both platforms.
These gains are available on the llama.cpp and vLLM inferencing backends.
Users can also experience these via the LM Studio and Ollama applications.
Tap Idle PCs for More Local AI Compute With NVIDIA PAIR
More than half of U.S. households have two or more PCs, and much of that computing power sits idle throughout the day. NVIDIA Personal AI Router (PAIR) is a free, open source software tool that puts those systems to work together for local AI.
Agentic workflows often break complex tasks into smaller jobs that can run in parallel, but performance can slow when every request is competing for the same GPU. PAIR automatically discovers compatible PCs on a local network and routes independent inference requests to whichever system has capacity. It works with Ollama and LM Studio and can adapt as devices join or leave the network.
For example, a user could ask Hermes to create a “Sunday Reset” plan by sorting through a cluttered inbox and prioritizing what needs attention now, what can wait and what can be skipped. Hermes can split that work across multiple subagents, while PAIR distributes those jobs across available PCs instead of having them all wait on a single GPU.
The result is more compute for local agents, with more tasks running in parallel and the flexibility to move AI workloads to another PC while the main system is being used for gaming, creating or other work.
The NVIDIA PAIR beta is available for Windows, macOS and Linux through both graphical and terminal interfaces, supporting NVIDIA GeForce RTX 20 Series GPUs and newer, NVIDIA RTX PRO workstation GPUs (Turing architecture and newer), NVIDIA DGX Spark and Apple M4 or newer silicon.
Powerful On Device Photo Editing With Cyberlink PhotoDirector AI PC Mode on RTX Spark
Open image and video models enable artists to experiment with Creative AI models on PCs. This enables artists to iterate and explore concepts and ideas, without the dreaded token anxiety and keep more of their creative work private and on-device.
CyberLink’s new PhotoDirector AI PC Mode is one of the first applications to integrate these diffusion models directly into a creative software, and turn them into a creative tool at the finger tips of the artists. Coming to PhotoDirector 365 and optimized for NVIDIA RTX Spark when it launches, AI PC Mode users are getting AI-powered editing tools for generative editing, image enhancement, object and distraction removal, background removal and replacement, portrait refinement and the creation of entirely new visuals — with the flexibility to choose between local or cloud processing, depending on the task.
On NVIDIA GPUs, PhotoDirector uses TensorRT-RTX and FP8 to accelerate local AI.
NVIDIA RTX Spark is coming this October— and at IFA 2026, partners are showing off their hardware. At IFA, newly announced designs join the existing six OEMs shipping in October. Acer showed its compact desktop RTX Spark concept, and Lenovo announced its Yoga Pro 9n and Yoga 9n 2-in-1.
RTX Spark is a new beginning for Windows PCs. One PC built for creators, gamers and AI agents. With a powerful 1 Petaflop RTX Blackwell GPU, up to 128GB of unified memory and a highly efficient 20-core Grace CPU, RTX Spark delivers incredible performance and efficiency. This superchip enables high performance thin laptops with all day battery life and compact desktops to power always-on agents. Paired with the new Windows Agent framework, it enables agents that run safely in the background under OS level control.
Last week at Gamescom, Electronic Arts, Embark and Ubisoft were among the latest game publishers and developers bringing their blockbuster titles to NVIDIA RTX Spark Windows PCs. They join the publishers that announced RTX Spark support at COMPUTEX in May, including KRAFTON, NetEase, Riot Games and XBOX. Read more.
Sign up to be notified when RTX Spark laptops and desktops are available.
#ICYMI: More Updates From NVIDIA Local AI
🎮 NVIDIA Brings New RTX Tech and Games to Gamescom — NVIDIA released DLSS 4.5 Ray Reconstruction, featuring a new second-generation transformer model for improved image quality in ray-traced and path-traced games. Gamescom also brought new RTX announcements for titles including 007 First Light, CONTROL Resonant and Gears of War: E-Day, plus expanded game support for the upcoming NVIDIA RTX Spark.
🐋Introducing DeepSeek Harness — DeepSeek’s new open source harness pairs with DeepSeek-V4-Flash to power local agentic coding workflows on NVIDIA DGX Station and multi-DGX Spark setups.
📊MLPerf Client v2.0 Expands AI PC Benchmarking — MLCommons released MLPerf Client v2.0, developed in collaboration with NVIDIA and other industry leaders. The update adds new benchmarks for agentic AI and image generation, alongside expanded LLM testing for real-world local AI workloads.