Spain-Based Startups Advance Regional Innovation With Barcelona Supercomputing Center


The Barcelona Supercomputing Center (BSC)’s AI Factory Accelerator Programme, now in full operation following a pilot initiative, gives startups access to sovereign compute, technical support and training to support innovation across industries. 

Many of these companies are also members of the NVIDIA Inception program for cutting-edge startups — and as of today, access to some of the BSC AI Factory services are available through the NVIDIA Inception portal. 

NVIDIA Inception complements the BSC AI Factory Accelerator Programme by providing members with training through NVIDIA Deep Learning Institute open courses, business mentoring, venture capital connections and other resources.

An upcoming extension of MareNostrum 5 — BSC’s public infrastructure serving scientific and technological innovation, powered by NVIDIA accelerated computing — will deliver supercomputing access through the BSC AI Factory and other AI Factories across Europe. BSC AI Factory is among Europe’s first AI factories and the first in Spain, and has delivered more than 800 services to private and public-sector clients since its April 2025 launch.


Three Inception members were recently named the BSC AI Factory Accelerator Programme’s AI Champions at the pilot initiative’s demo day:

Qatium’s water-network platform — already used by more than 250 utilities in 16 countries — is now in early production with its Neural Water Intelligence technology, powered by proprietary AI models trained on MareNostrum 5. Built on NVIDIA accelerated computing, the NVIDIA cuGraph library, the NVIDIA PhysicsNeMo framework and NVIDIA Nemotron open models, the technology helps water utilities make better operational decisions every day.

OneCareAI, a research spin-off from BSC, used NVIDIA NIM microservices to develop technology designed to identify signs of hidden atrial fibrillation — an irregular heart rhythm — in seemingly normal ECGs, helping clinicians identify patients who may be at risk of stroke before one occurs.

Avatia built a voice-first, multi-agent system that provides pharmaceutical companies with agentic coworkers that support sales representatives and give doctors transparent, curated information about medicines, ultimately helping the right treatment reach the right patient sooner. The system taps into NVIDIA NIM microservices, the NVIDIA Nemotron 3 open model family and the open source NVIDIA NeMo Curator library.

Other BSC AI Factory startups — Agrikola AI, Elna Health, Lokutor, Montevive AI, Oppy, Pack2Earth and Up2Smart — span precision agriculture, medical imaging and knowledge access, speech services, enterprise security, sales intelligence and sustainable packaging.

The cohort reflects the breadth of what advanced intelligence can now unlock: preventing strokes, detecting breast cancer subtypes before biopsy, putting medical knowledge at doctors’ fingertips faster, replacing petroleum-based plastic with biobased compostable materials, protecting crops with robots instead of chemicals and more.

Learn more about NVIDIA Inception and the BSC AI Factory Accelerator Programme.
 

Amid Ecosystem Adoption, NVIDIA Opens Vera Rubin Architecture to Help Scale AI Factories Worldwide


As AI factories grow from megawatts to gigawatts, building them takes more than advanced computing. Open standards are helping the industry scale AI infrastructure faster, more efficiently and more reliably.

At the Open Compute Project (OCP) Global Summit, taking place in the San Jose McEnery Convention Center, NVIDIA announced new partnerships and contributions aimed at creating a common foundation for next-generation AI infrastructure. 

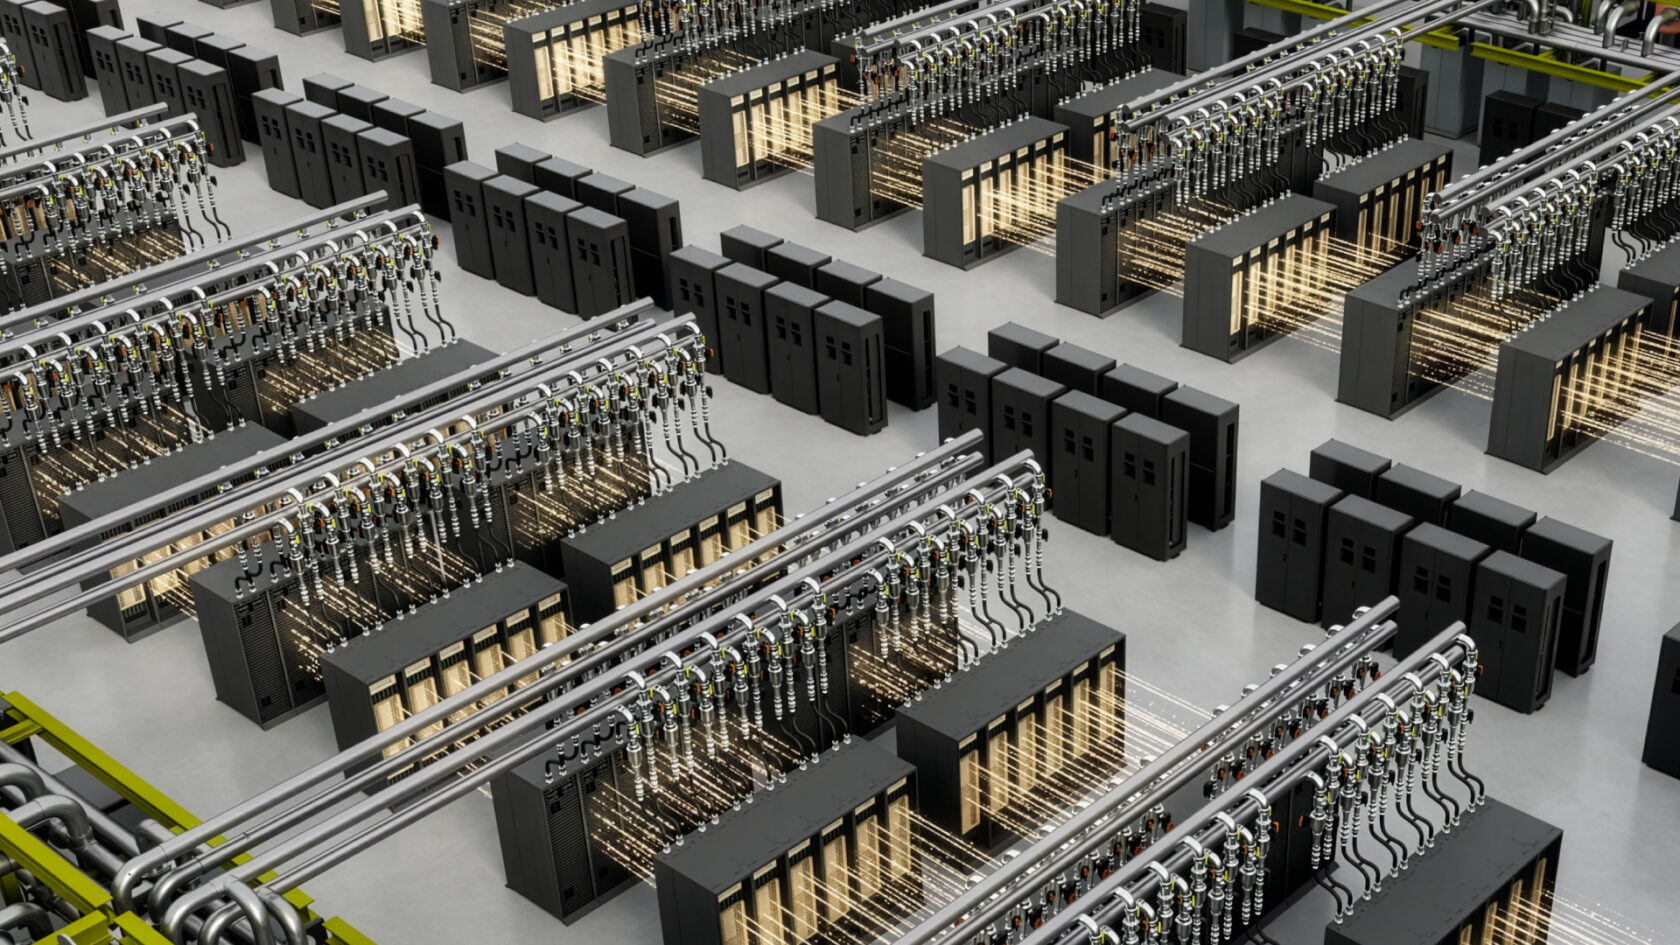
NVIDIA contributed key NVIDIA Vera Rubin rack and compute tray designs to OCP through the open NVIDIA MGX architecture, giving system builders a common foundation for developing next-generation AI factory infrastructure.

Together, these efforts span the AI factory itself, the utility grid that powers it and the rack-scale architecture at the heart of modern accelerated computing.

NVIDIA and Partners Announce Open Architecture Advances 

At the OCP event, NVIDIA and partners made a handful of announcements: 

  • NVIDIA and hyperscalers published open standards for next-generation AI factories, including AI factory design standards and grid resilience. 
  • NVIDIA launched new open source software components for NVIDIA DSX AI Factory. 
  • Meta and NVIDIA advanced open AI networking with NVIDIA Spectrum-X Ethernet SuperNIC and Spectrum-6 innovations.
  • Visionbay introduced an 800V DC AI factory design for the Vera Rubin era.
  • NVIDIA and Cisco announced the Ultra-Dense Small Form Factor Pluggable (USFP) standard, the industry’s first module ​for 400Gb/s-based networking fabrics.
  • NVIDIA and Google announced Falcon Transport support on future NVIDIA ConnectX-10 SuperNICs and BlueField DPUs.

Before a packed audience, Ian Buck, vice president of hyperscale and high-performance computing at NVIDIA, discussed how open infrastructure is becoming a critical ingredient for scaling AI factories worldwide. 

The news at OCP spotlights how NVIDIA’s extreme codesign combined with open standards is accelerating deployment, improving power efficiency and driving tokens-per-watt performance.


Vera Rubin AI Factories Advance With MGX Rack Contributions at OCP 🔗

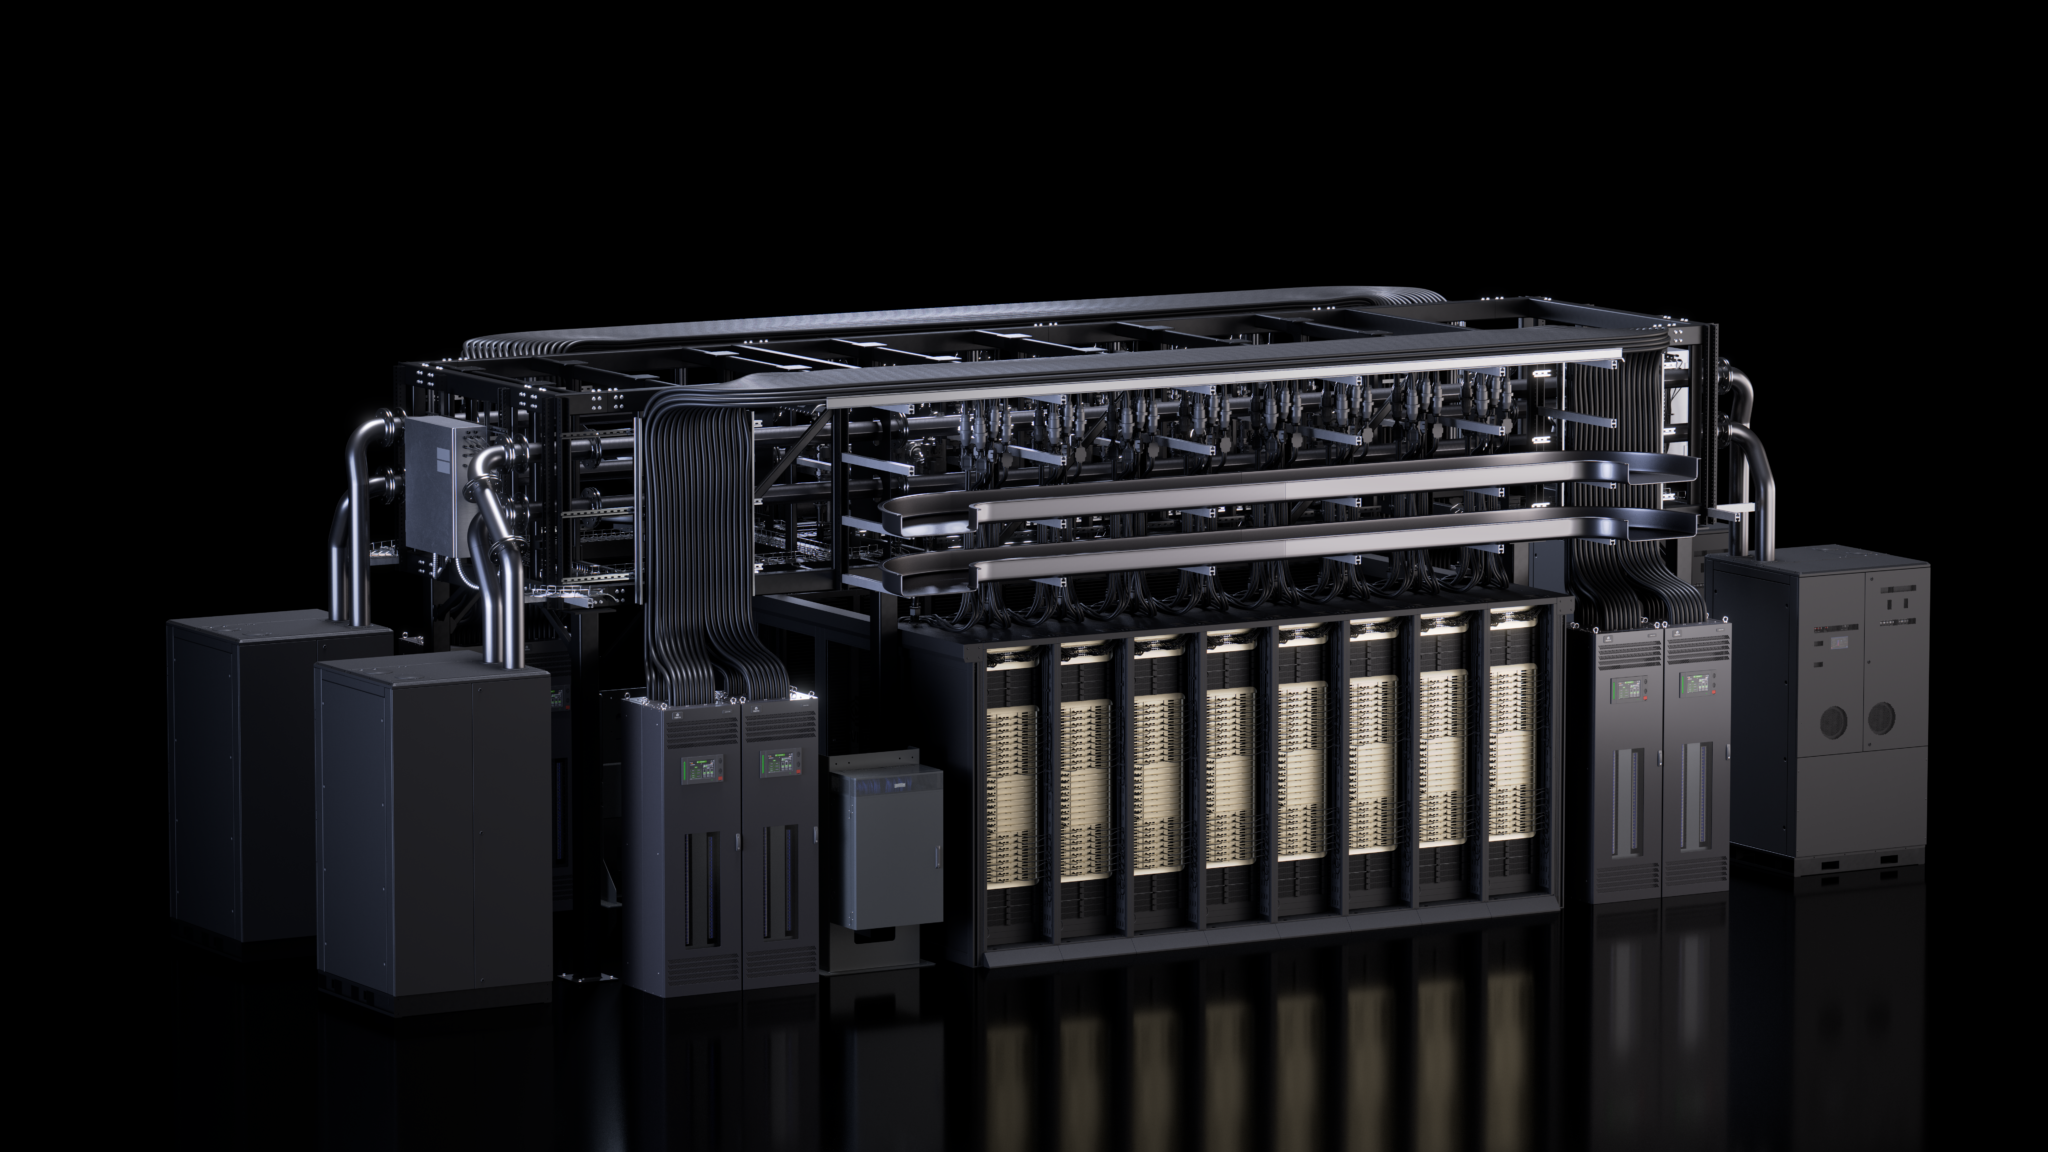
NVIDIA joined industry leaders in contributing to the third-generation MGX AI data center reference design through OCP’s Open DC Initiative.

Combined with open liquid-cooling technologies such as MQD and MQDB, the effort helps turn proven AI factory designs into industry standards that others can adopt, manufacture and scale.

For NVIDIA Vera Rubin AI factories, the updated MGX 1.2 specification extends the open architecture for AI factories with rack-scale blind-mate liquid cooling, interoperable rack-scale interconnect infrastructure and a liquid-cooled 5,000A busbar designed for higher-power AI systems. It also adds native 19-inch equipment support and higher-density rack designs.

MGX 1.2 further expands modularity with configurable I/O bays, fanless liquid-cooled compute trays, standardized power and cooling interfaces, and a common infrastructure that helps ecosystem partners build interoperable accelerated computing platforms. It improves assembly, test and service times to streamline manufacturing and field service to enable faster and more efficient infrastructure buildout. The architecture supports rack deployments up to 250kW while simplifying serviceability, deployment and infrastructure reuse.

The Vera CPU rack design specification extends the NVIDIA MGX open architecture beyond accelerated computing, providing a purpose-built platform for the growing agentic AI era. While Vera Rubin NVL72 serves as the foundation for large-scale training and inference, the NVIDIA Vera CPU rack is designed to support tool calling, orchestration and sandboxed execution, helping AI agents interact with applications, data and services in real time.

Built on the third-generation NVIDIA MGX rack architecture, the Vera CPU rack shares the same rack-scale design principles that unite compute, networking, power and cooling into a common modular platform. This approach enables partners to deploy specialized infrastructure while benefiting from a shared ecosystem, simplified integration and a consistent foundation for next-generation AI factories.


NVIDIA Launches New Open Source Software Components for DSX AI Factory 🔗

NVIDIA DSX AI factory platform applies extreme codesign to unify computing, networking, power, cooling, facilities and software, helping AI factories operate as a single optimized system, maximizing AI output within available infrastructure constraints. At the center of this unified system is DSX OS, the open operating layer that turns the DSX architecture into coordinated, repeatable operations at scale.

At OCP, NVIDIA expanded DSX OS with open source components for configuring networks, validating clusters, managing racks and provisioning bare metal: 

  • NVIDIA Config Manager: Automates switch configurations at scale, allowing customers to deploy, validate and maintain consistent AI factory network fabrics with minimal to zero manual intervention/
  • NVIDIA Cluster Readiness Engine: Helps eliminate costly job crashes by stress-testing GPU clusters with real workload simulations to guarantee hardware health before training begins
  • NVIDIA Rack Management Service: Offers a rack hardware abstraction and operations solutions that treats racks as first-class units for improved AI factory scale firmware management.
  • Cluster API Provider for NVIDIA Infrastructure Controller: Accelerates bare-metal deployment and tenant onboarding, turning raw AI hardware into production-ready clusters in hours instead of days.

Developed from NVIDIA’s experience running NVIDIA DGX Cloud, these open source components enable cloud providers and software partners to integrate AI factory capabilities directly into their multi-tenant platforms. 

Developers can visit the DSX AI Factory Github page to explore and contribute to both the new and existing open source software components from NVIDIA DSX AI Factory platform.
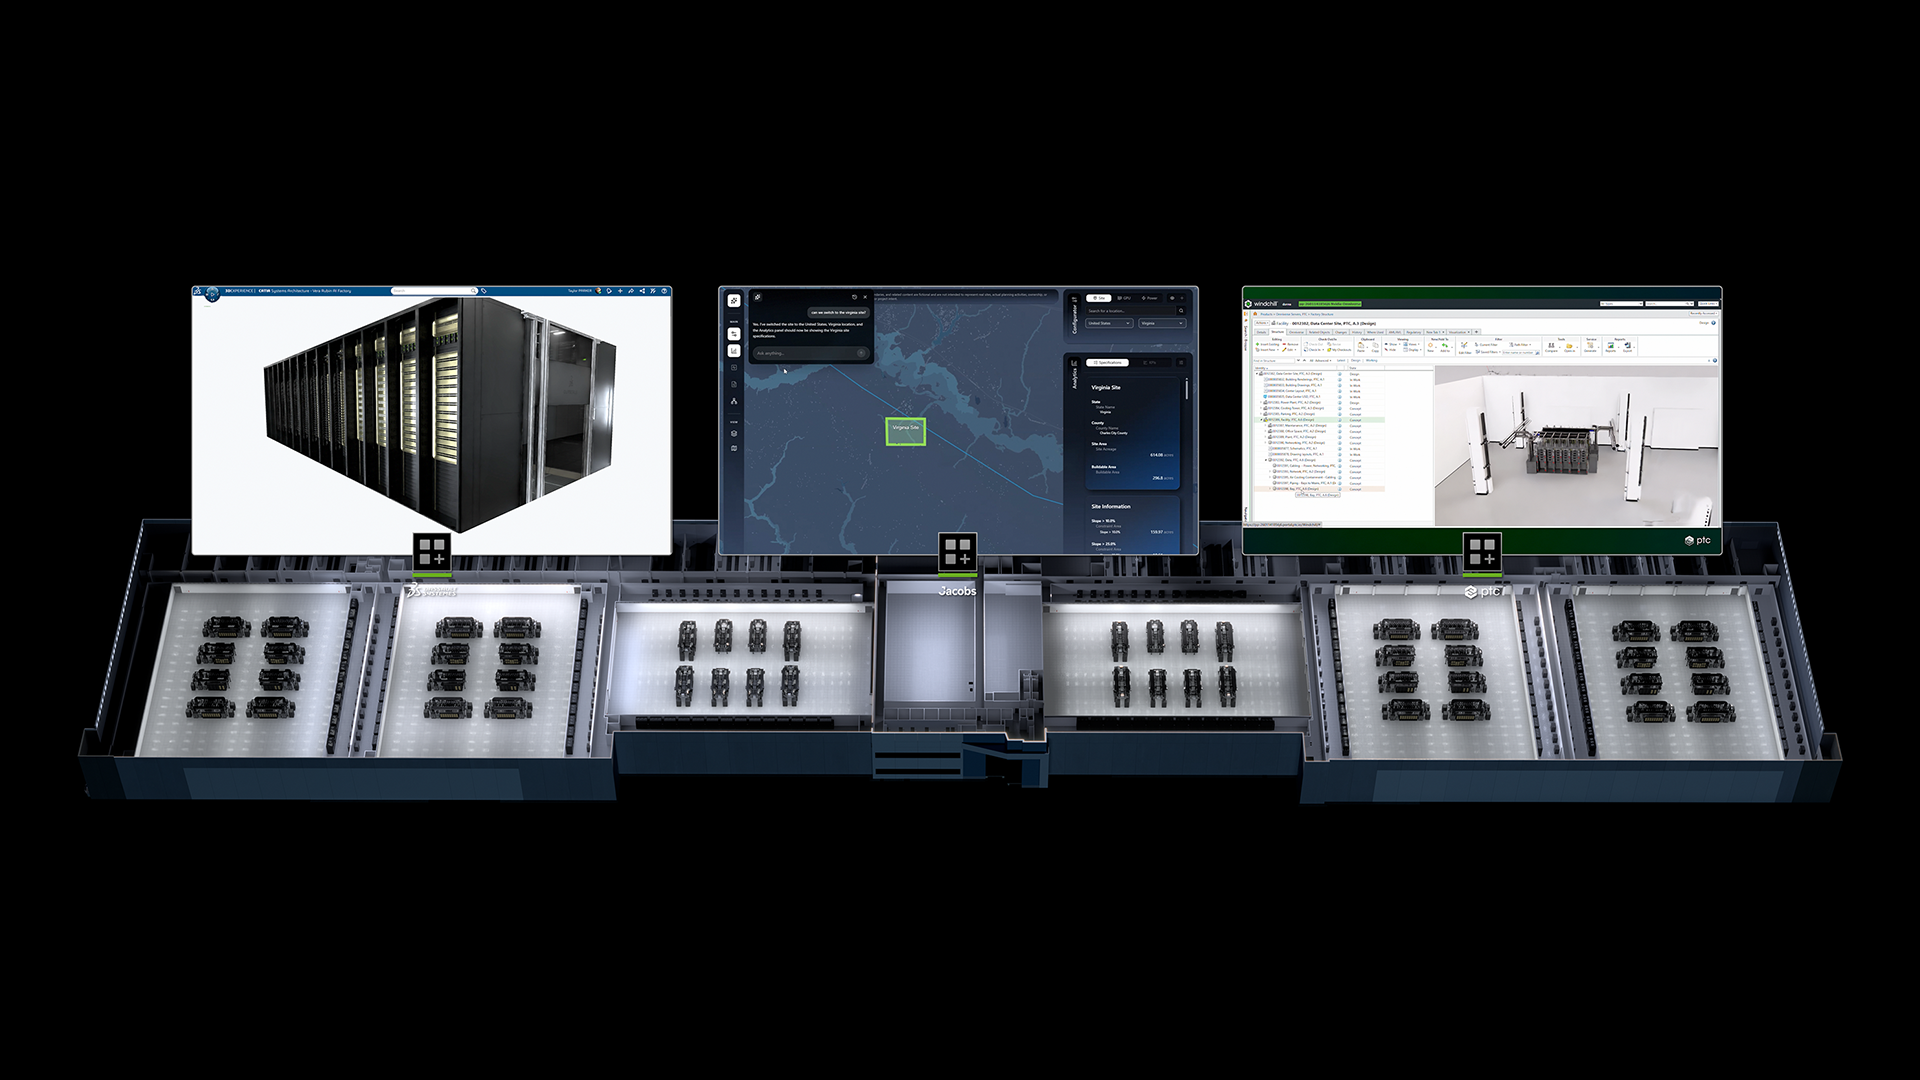


NVIDIA and Hyperscalers Publish Open Standards for Next-Generation AI Factories 🔗

For AI infrastructure to scale globally, it needs more than advanced hardware — it needs a common foundation that the entire industry can build on.

At OCP, NVIDIA joined AMD, Google and Meta to publish a new open specification that establishes that foundation. The Open Data Center Specification v0.7 defines a unified blueprint for next-generation AI factory facility design — from power architecture to cooling infrastructure to physical layout. 

The OCP Grid Resilience Specification, published by Google, Meta, Microsoft and NVIDIA, establishes how large-scale AI infrastructure should behave during utility grid disturbances: staying connected, responding automatically and restoring to near-full load within less than two seconds.

With these standards now open, manufacturers around the world have a common target to build for. Equipment makers, colocation providers and data center operators can begin designing, fabricating and delivering the infrastructure layer that powers AI factories under construction globally — without waiting for proprietary specifications from individual customers.

Being NVIDIA DSX reference design-compatible, these specifications provide a validated, deployable implementation of both specs, from facility layout and power architecture to the software that monitors and responds to grid signals in real time. For operators building Vera Rubin AI factories, there’s now a straight line from open community standard to a running system.


Visionbay.ai Designs 800VDC AI Factory for the Vera Rubin Era 🔗

As AI factories grow larger and more powerful, one challenge looms over them all: delivering enough power to the accelerated computing systems driving the next generation of AI.

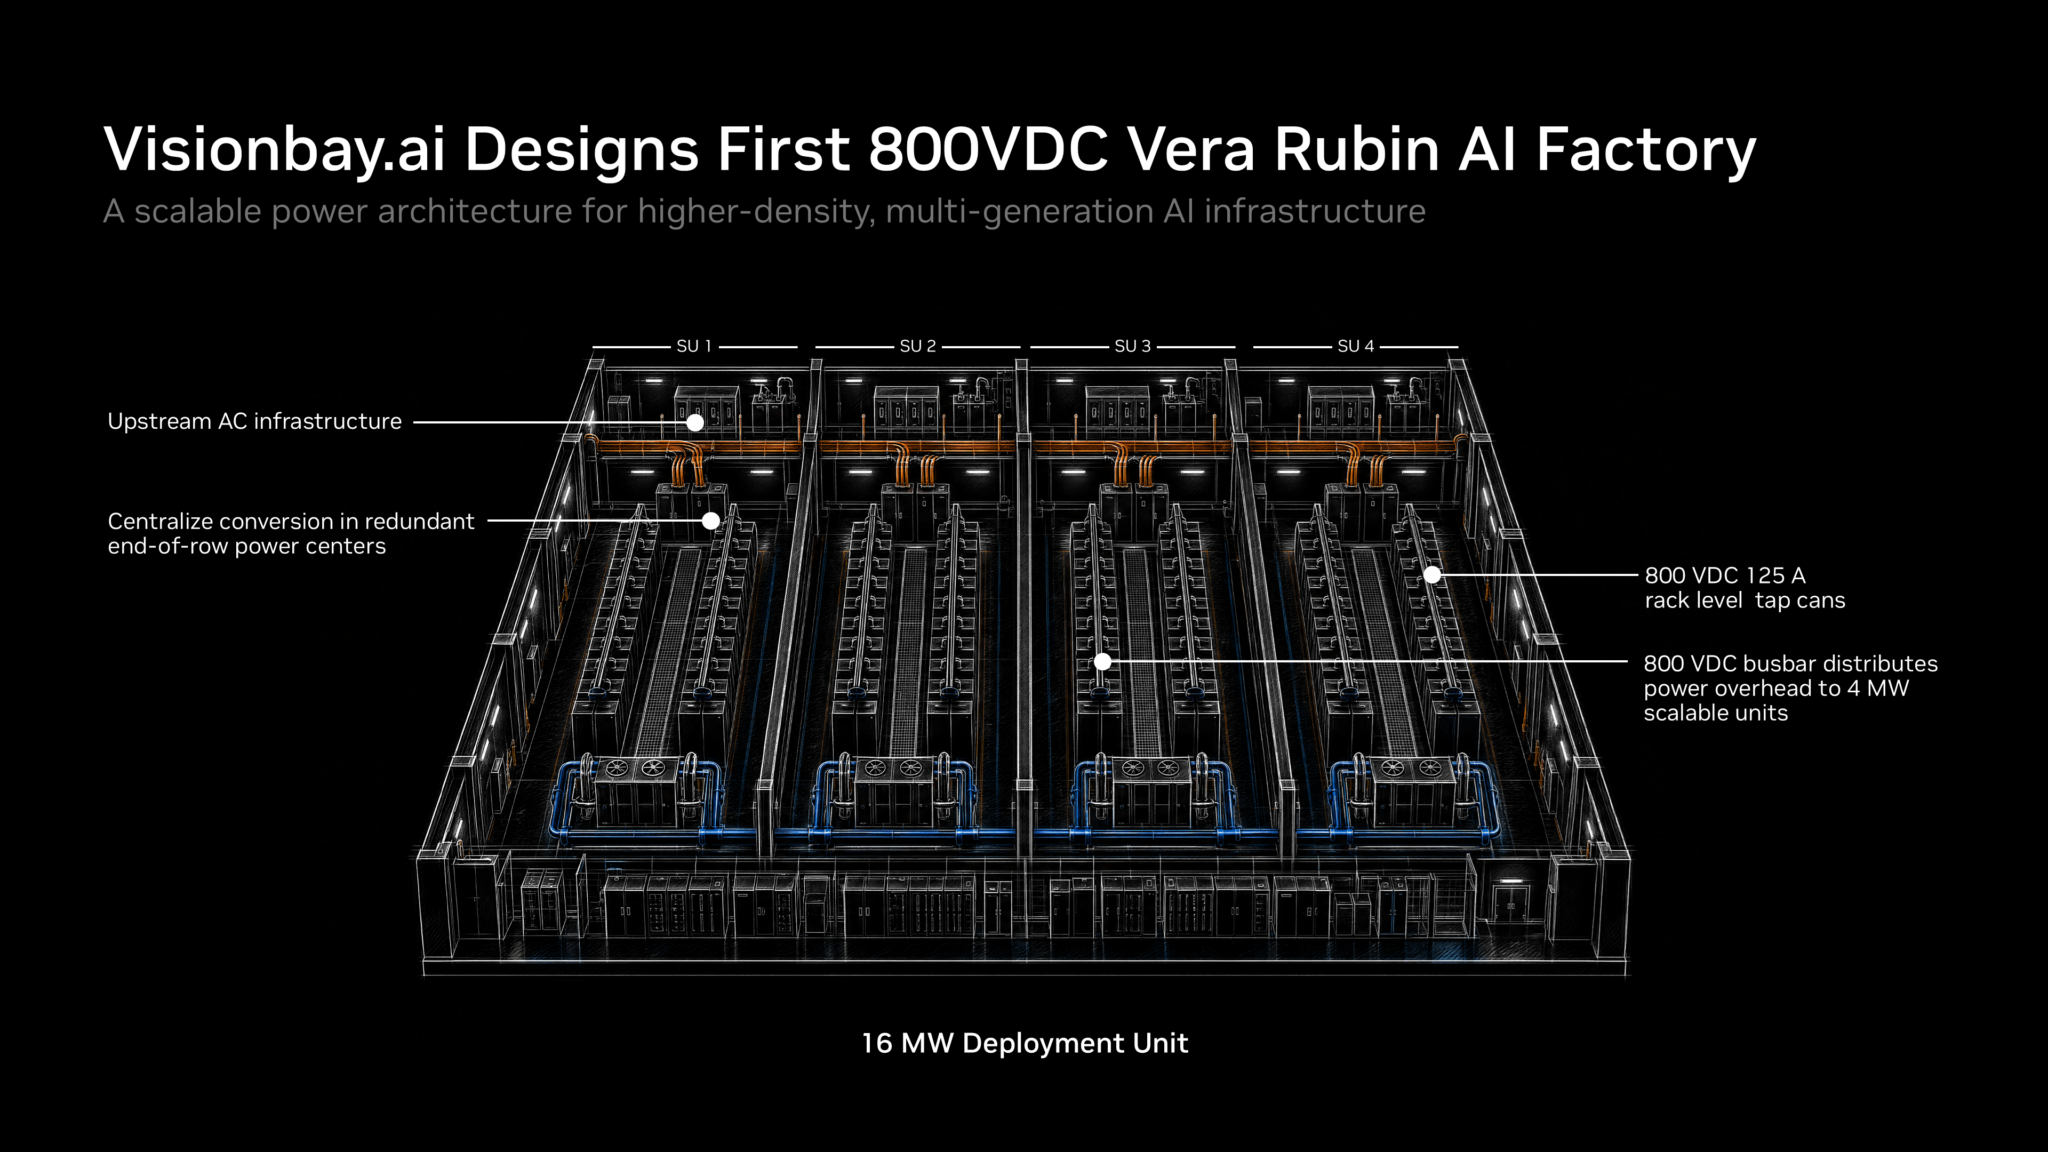
At OCP, Visionbay unveiled plans for K-1, a next-generation AI factory platform designed around an 800 VDC architecture and built with future NVIDIA Vera Rubin deployments in mind. The project combines NVIDIA’s 800 VDC reference architecture with power and thermal technologies from Vertiv to create a scalable foundation for high-density AI infrastructure.

The design addresses a growing industry challenge. As AI training, inference and reasoning workloads expand, rack power densities continue to rise. Traditional low-voltage power distribution becomes increasingly difficult to scale, requiring more copper, more cabling and more power-conversion equipment.

By adopting NVIDIA’s 800 VDC architecture, K-1 creates a path toward higher-density AI infrastructure while preserving flexibility for existing deployments. Rather than requiring a complete transition on day one, the platform is designed to phase in 800 VDC distribution where it delivers the greatest benefit, helping operators prepare for future generations of accelerated computing without extensive facility redesign.

The architecture is designed around cluster-level power centers that centralize AC-to-DC conversion and distribute 800 VDC closer to compute resources. The approach simplifies downstream power delivery, supports modular expansion and creates repeatable building blocks for future AI factory growth.

K-1 also reflects the system-level design philosophy behind NVIDIA AI factories, where power, cooling and computing are engineered together. With support for liquid-cooled infrastructure, scalable power distribution and future Vera Rubin-class deployments, the project demonstrates how ecosystem partners are translating NVIDIA’s AI factory architecture into deployable infrastructure designed for the next era of accelerated computing.
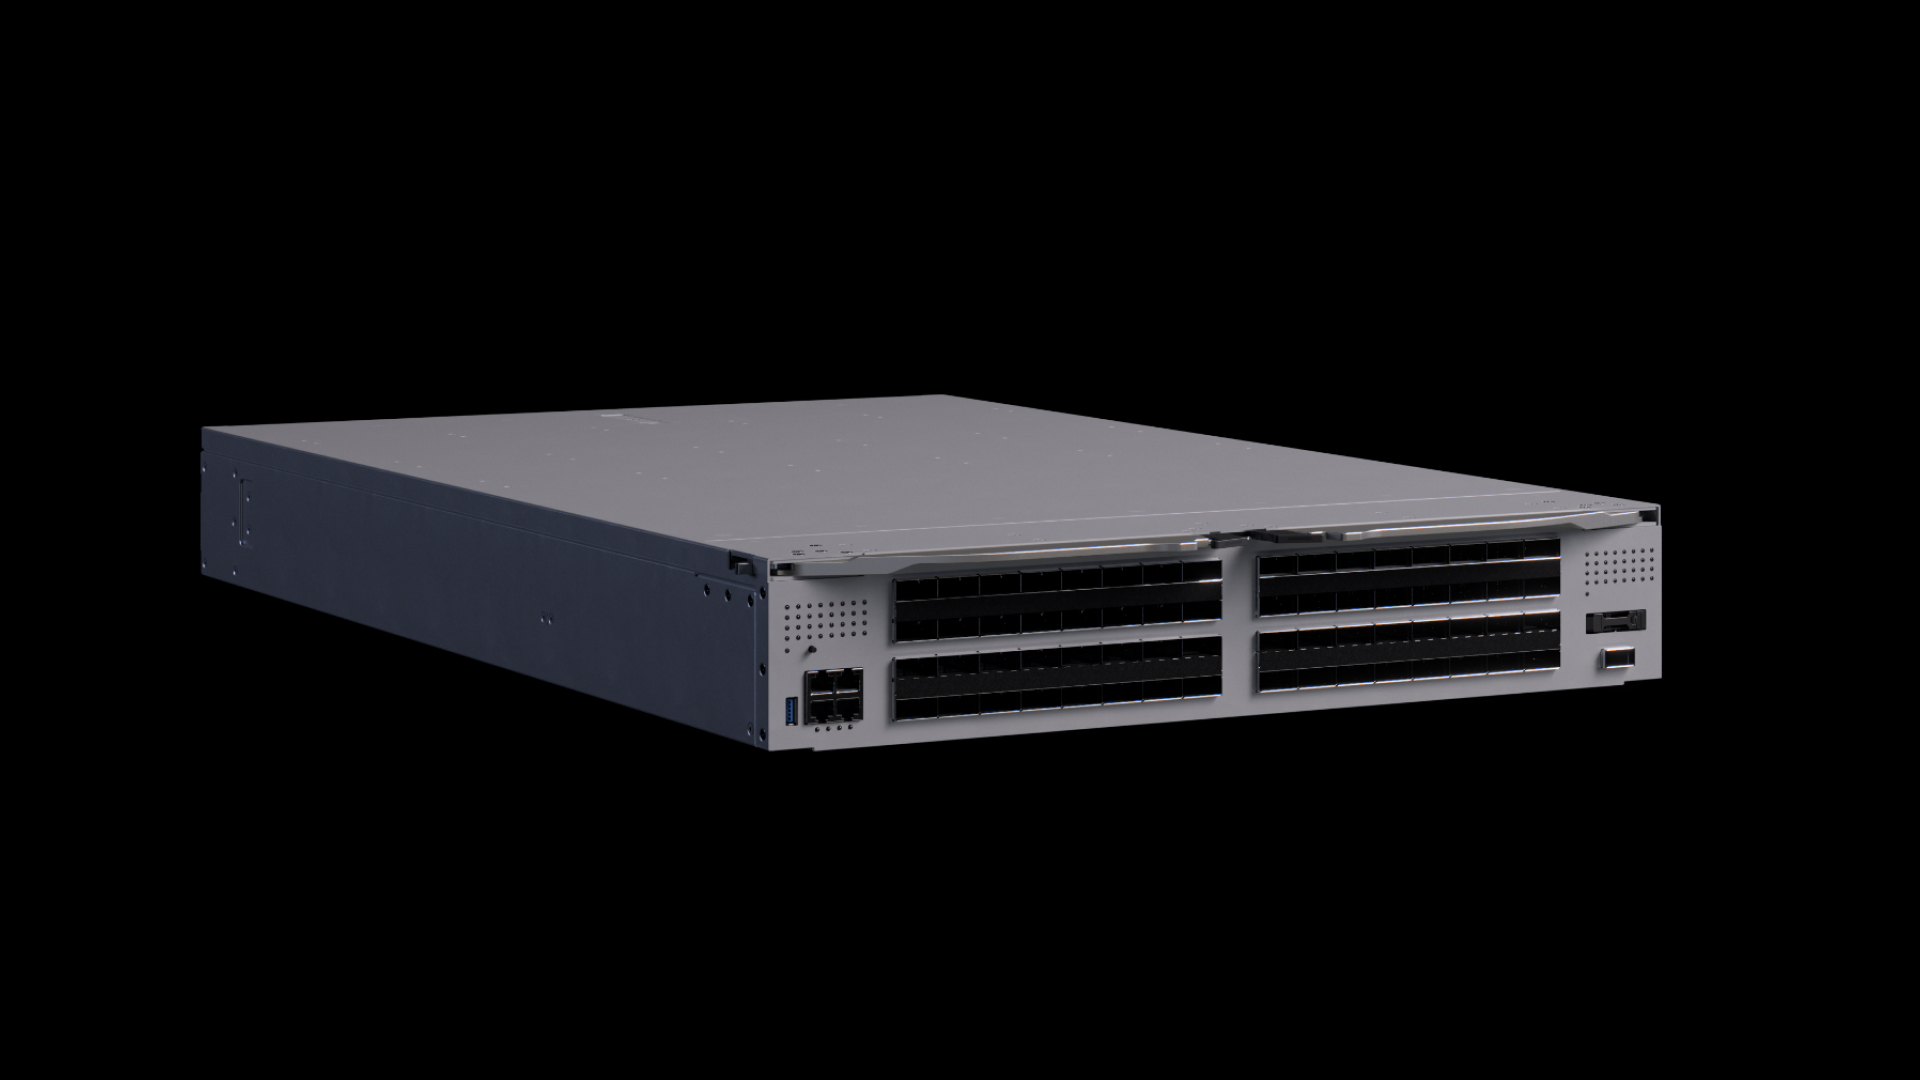


At the event, Meta and NVIDIA announced that Meta is adopting NVIDIA Spectrum-6 102.4Tb/s Ethernet switches to build larger, higher-performance NVIDIA Vera Rubin AI factories on open networking. 

Spectrum-6 delivers twice the switching capacity and per-lane bandwidth of Spectrum-4, and provides a lossless Ethernet AI fabric at 200G per lane, with high effective bandwidth and performance isolation that keeps one job’s traffic from slowing another’s.

Meta’s Spectrum-6-based switch, N-IceCube, slots into IcePack, Meta’s 100T, liquid-cooled rack. N-IceCube runs the Facebook Open Switching System (FBOSS), Meta’s open source network operating system that contributed to OCP to support efficient networking at hyperscale. 

FBOSS is built on the Switch Abstraction Interface, an OCP standard NVIDIA helped develop, providing a vendor-independent way of controlling switch hardware. Together, these technologies support agentic AI factories of more than 100,000 GPUs that train and serve massive mixture-of-experts models.

The announcement marks the next step in a collaboration that combines Meta’s experience operating AI infrastructure at hyperscale with NVIDIA’s networking technology.

At the heart of this collaboration is Spectrum-X Multiplane technology, enabled by Spectrum-6 switches and ConnectX-9 SuperNICs. Multiplane distributes GPU traffic in hardware across up to eight independent network planes, enabling AI factories to scale beyond 100,000 GPUs with fewer switch tiers and lower infrastructure costs. Multiple paths between GPUs improve network utilization and resilience: when a component fails, traffic shifts to the remaining planes, keeping GPUs productive and AI applications running, even at reduced bandwidth.

Meta and NVIDIA worked together to strengthen that resilience through deployment experience and rapid engineering iteration. The teams validated improvements across on-premises and cloud environments. 

“We are excited about our close partnership with NVIDIA in making multiplane fabrics operationally scalable and performant, a critical requirement both for our own infrastructure builds and for our joint cloud partners,” said Omar Baldonado, senior director of data center and AI networking at Meta. “Extending FBOSS to Spectrum ASICs means we can run that same software stack across our fabrics, and Meta’s new Spectrum-based switch, N-IceCube, brings that into Icepack – our liquid-cooled 102.4T network rack for scale-out that connects upcoming generations of accelerators in our fleet.”

Together, Meta and NVIDIA are developing an architecture and operational playbook that other AI infrastructure operators can adopt, turning lessons from demanding production workloads into more scalable, resilient and efficient AI factories.


With USFP, NVIDIA and Cisco Reinvent Pluggable Optics for AI Factory Scale 🔗

As AI factories scale to support larger models and surging inference demand, every component of the infrastructure stack must deliver more performance, efficiency and simplicity — right down to the network connection itself. 

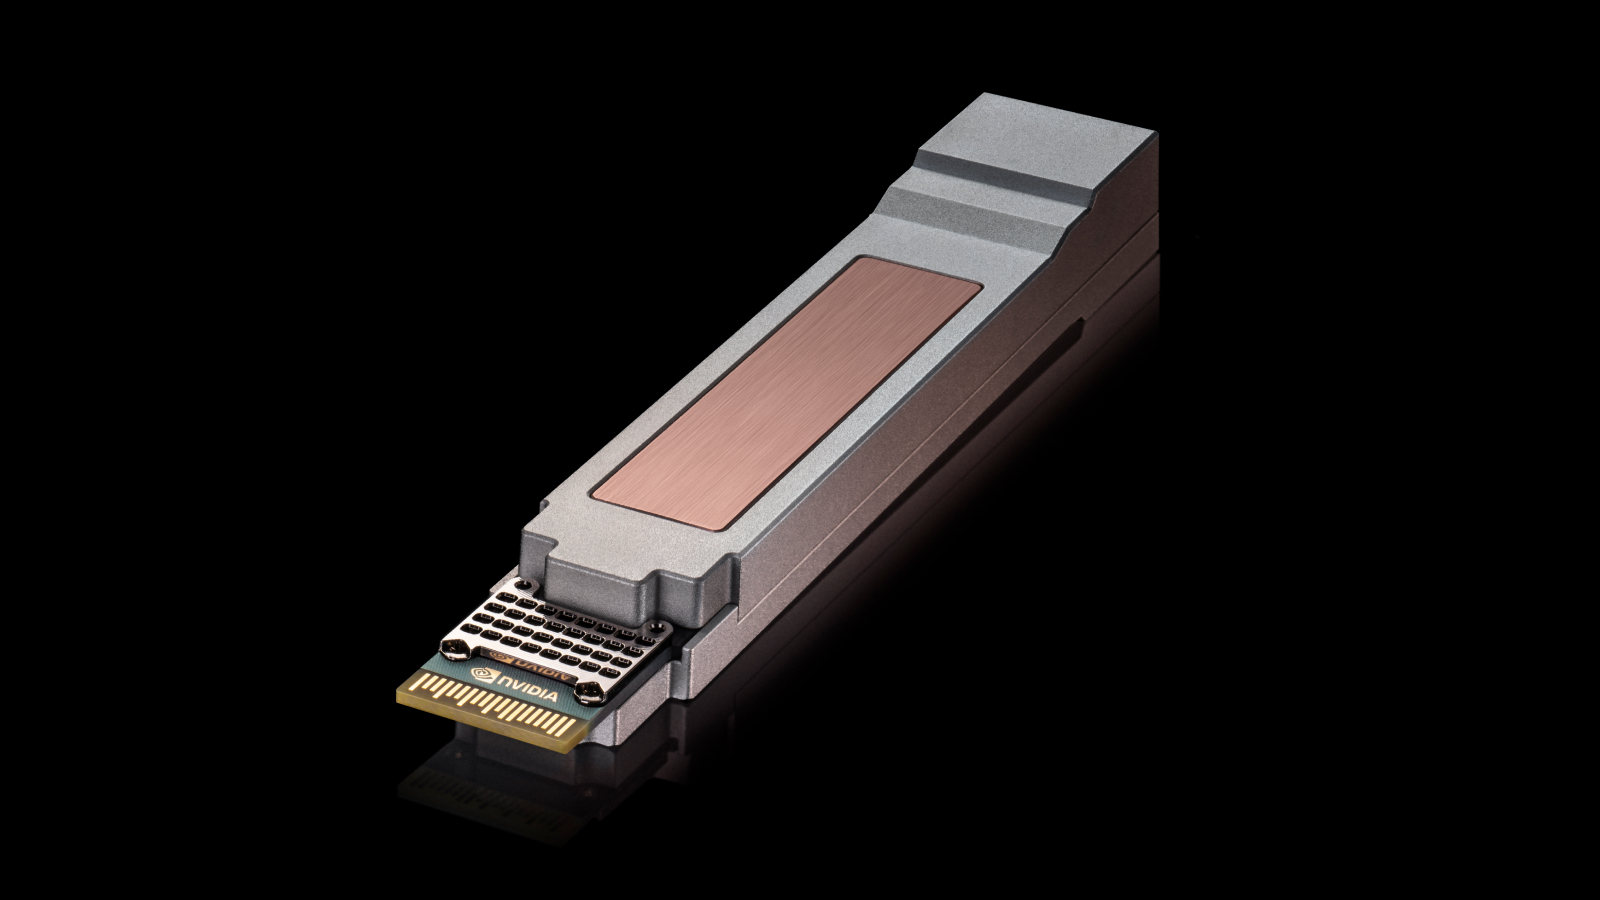
At OCP, NVIDIA and Cisco announced plans for USFP, a new optical pluggable transceiver module form factor designed to help AI factory builders scale next-generation AI fabrics while improving bandwidth density and power efficiency.

With approximately the same footprint as the widely adopted 200Gb/s-per-lane OSFP form factor, USFP will provide a path to 400Gb/s-per-lane networking and will extend a transceiver-based deployment model already proven across generations of data center networks. Packing 16 full-duplex lanes with plans to scale up to 32 lanes, USFP will deliver four times the bandwidth density of traditional 200Gb/s-per-lane pluggable optics. 

The result is the ability to connect more compute resources without adding network tiers that can increase latency, power consumption and complexity.

The new form factor is designed for the scale and efficiency demands of next generation AI factories, supporting higher-bandwidth fabrics while preserving the flexibility and serviceability that have made pluggable optics a mainstay of modern data centers. It also will deliver roughly 1.3x greater power efficiency, helping operators move more data with less energy.   

To help drive an open ecosystem, NVIDIA and Cisco are collaborating with TE Connectivity and Amphenol on cages, connectors and modules, with plans to advance USFP through a community-led, multi-source effort. Together, the companies are laying the foundation for more scalable, efficient and interoperable AI factory networking.
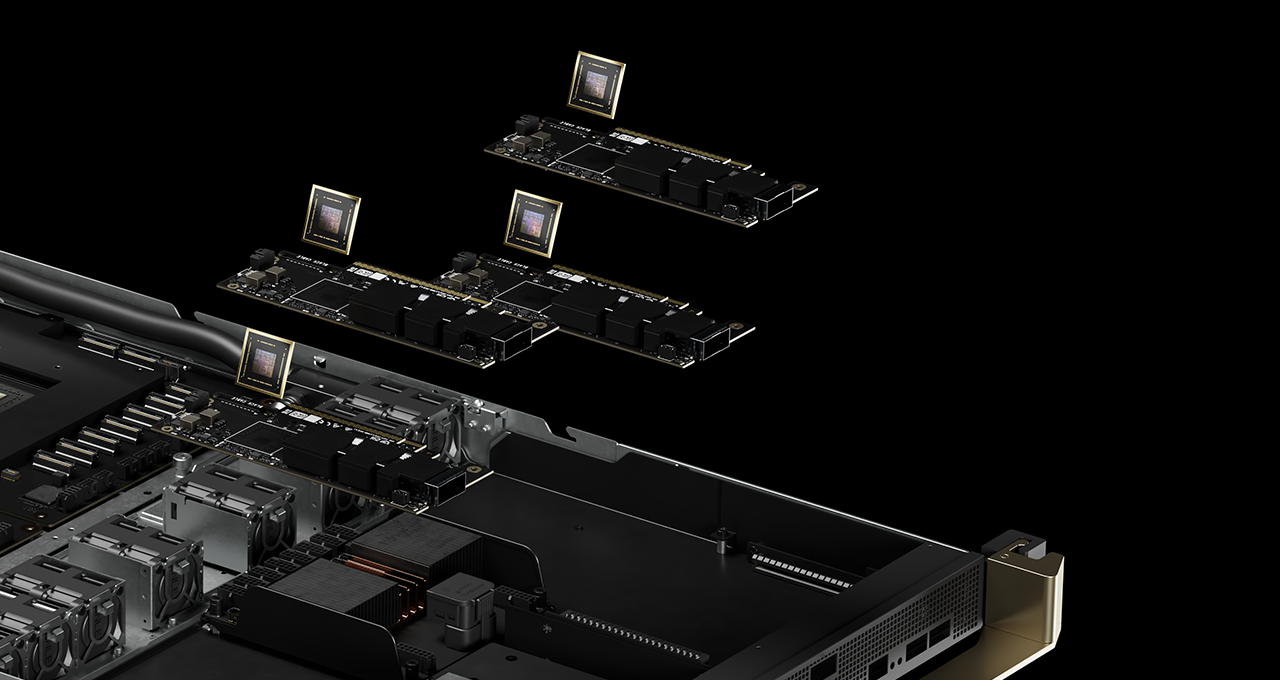


Google Falcon Transport Supports NVIDIA ConnectX-10 for Interoperable AI Networking 🔗

NVIDIA and Google also announced Falcon Transport support on future NVIDIA ConnectX-10 SuperNICs and BlueField DPUs, helping improve network efficiency for large-scale AI infrastructure. 

Falcon is a transport protocol designed to deliver data reliably over Ethernet networks, which can otherwise drop packets under congestion. It supports AI and storage workloads through multipath load balancing, programmable congestion control, hardware loss recovery and per-connection security.

This collaboration combines NVIDIA hardware acceleration with DOCA software to implement Falcon and extend NVIDIA networking to Google’s data center transport. NVIDIA and Google NICs can communicate over a common transport while applications retain standard RDMA programming interfaces.

By distributing traffic across paths, adapting to congestion, recovering dropped packets and protecting connections, Falcon helps workloads make better use of available bandwidth and maintain predictable performance as Ethernet fabrics scale.

Learn more by joining NVIDIA at OCP.
NVIDIA DGX Spark 64GB Gives Developers More Ways to Build and Scale Local AI


Local AI is becoming more useful by the token.

As AI agents move from experiments into everyday development, increasingly capable open models are shrinking to fit on more devices, giving builders more to run locally. 

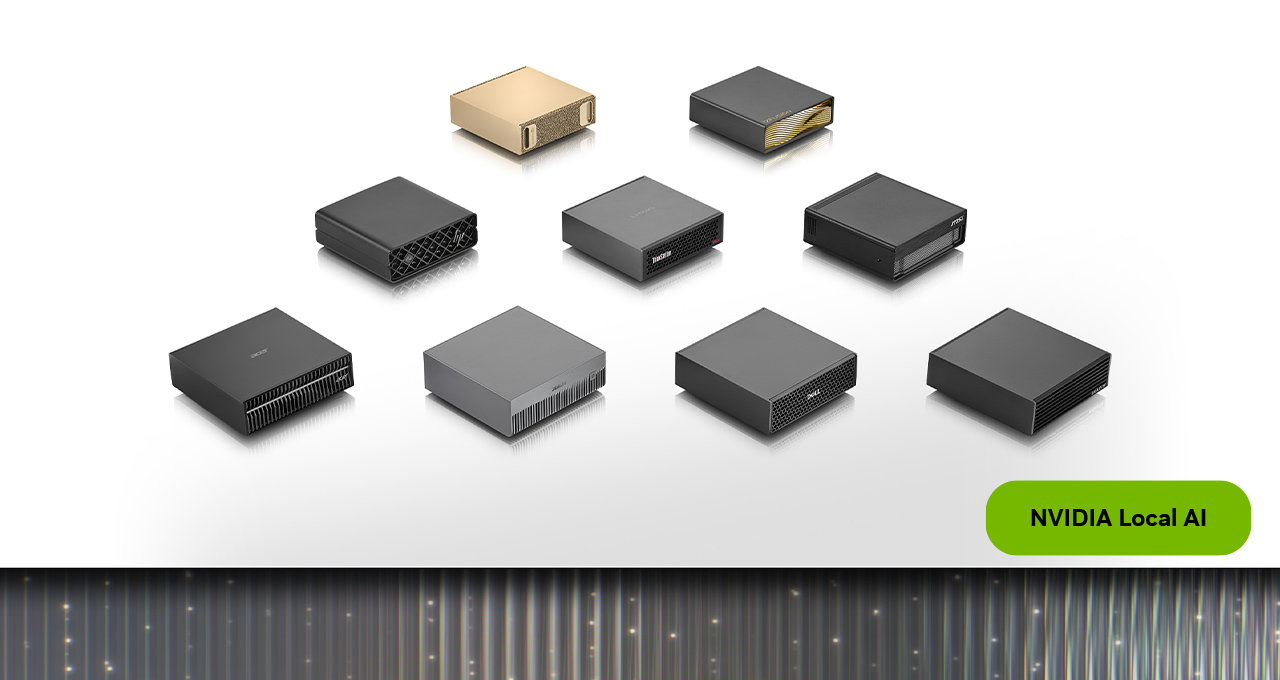
Coming this month, NVIDIA DGX Spark will be available with 64GB of unified memory from top manufacturer partners — Acer, ASUS, Dell, Gigabyte, HP and MSI — giving developers, researchers and AI enthusiasts a new configuration with DGX OS and the NVIDIA AI software stack ready to use from day one.

The new SKU runs capable local agents on device — privately, without cloud dependency. And when workloads grow, two units can cluster together via NVIDIA Sync Cluster Assistant without any additional setup.

A New Starting Point for Personal AI Supercomputing

DGX Spark combines NVIDIA Grace Blackwell compute, unified memory, NVIDIA ConnectX-7 networking and an NVIDIA CUDA-accelerated AI software stack in one system. It’s a complete local AI platform for agents, inference, fine-tuning, data science and edge development.

The compact, personal AI supercomputer provides a place to experiment with models and developers’ own data without turning to a cloud instance for every task.

The new 64GB configuration, available exclusively from manufacturer partners, keeps the platform at an accessible price point while retaining the GB10 Grace Blackwell Superchip, DGX OS and full NVIDIA AI software stack — same as the 128GB model. It supports up to 100-billion-parameter models and the agentic applications built on them, fully on device. 

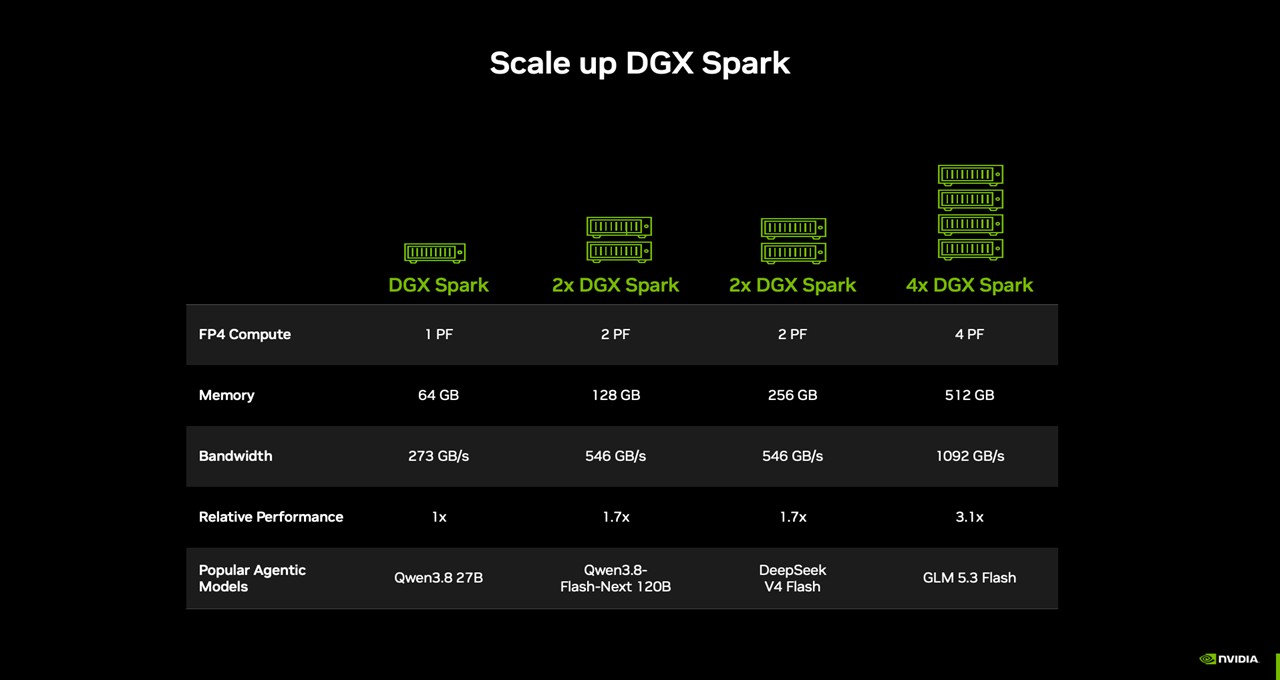
Two 64GB units clustered together don’t just double the memory. In NVIDIA’s Qwen 3.8 27B test, two clustered 64 GB systems delivered up to 1.7x performance compared with a single system, with room to keep scaling as workloads demand.

DGX Spark ships ready for agent development from day one — NVIDIA Agent Toolkit, CUDA-X AI libraries, Nemotron open models, and popular runtimes like Ollama, vLLM, and PyTorch with CUDA are all supported out of the box. Developers can go from power-on to running models in minutes.

Blender is among the first major creator application providers to support the platform, with a prebuilt, downloadable installer coming soon.

Scale Up With NVIDIA Sync Cluster Assistant

Developers can start with the memory their projects need today and build on a platform designed to seamlessly scale multi-node clusters for larger workloads as their pipelines grow. 

Every DGX Spark ships with a built-in NVIDIA ConnectX-7 NIC right out of the box. Plus, two units can connect directly with a QSFP cable, pooling their memory to 128GB and expanding model support to up to 200 billion parameters while delivering twice the memory bandwidth and up to 1.7x the performance.

The NVIDIA Sync app configures this multi-node cluster seamlessly. The cluster assistant feature detects connected units, validates device configuration and configures the ConnectX-7 network, so developers can focus on their work rather than the infrastructure. Every node runs the same NVIDIA software stack, so nothing needs to be reconfigured when scaling from one unit to two.

And coming at the end of the month, NVIDIA Sync Model Launcher makes running local AI as simple as clicking a few buttons. Developers can download and launch Qwen3.8 27B on a single DGX Spark system or a cluster, with NVIDIA Sync configuring the model to run across connected devices and making it accessible from users’ laptops. The launcher will also set up OpenCode to use the model, so developers can start coding in their browser.

Developer Use Cases on DGX Spark 

The new DGX Spark 64GB configuration supports practical work from day one. With up to 100-billion-parameter models running entirely on device, developers and enthusiasts can start with a single system for models that fit within its memory, or connect multiple DGX Spark systems with NVIDIA Sync Cluster Assistant for workloads that need more memory and compute. 

Here are three workflow examples:

  • Run an AI agent around the clock: Keep a coding or research agent running on DGX Spark, ready to review code, analyze documents or carry out multistep tasks. A cluster provides additional capacity for larger models, longer context windows or multiple agents working at once.
  • Power AI apps on your everyday PC: Run a language- or image-generation model on DGX Spark while using an agent or creative application on laptops or desktops. DGX Spark handles the model inference, freeing PCs for other work. 
  • Scale when the work grows: When a single task outgrows one unit — running a larger model, a longer context window or concurrent agent requests — two DGX Spark 64GB systems connected over the 200 GbE fabric via NVIDIA Sync Cluster Assistant pool their memory to 128GB. The same workflow that ran on one unit scales to two without reconfiguring the software environment.

Get Started With DGX Spark 

DGX Spark 64GB is available from Acer, ASUS, Dell, Gigabyte, HP and MSI on Friday, Oct. 23, starting at $4,999.

To get started:

  • Download a supported inference framework — llama.cpp, Ollama, vLLM or LM Studio.
  • Download the recommended local model for the workflow.
  • To scale to two units, connect them via their NVIDIA ConnectX-7 ports and launch NVIDIA Sync Cluster Assistant — it configures the network and routes workloads automatically.

For agentic AI playbooks on DGX Spark, visit the NemoClaw, OpenClaw, Hermes Agent and OpenShell pages on build.nvidia.com. 

#ICYMI: More Updates From NVIDIA Local AI

Explore playbooks on build.nvidia.com/spark for DGX Spark. The following playbooks are coming soon to 64GB devices:

  • Serve LLMs With vLLM
  • Run OpenClaw With a Local LLM
  • Connect Multiple DGX Sparks for Distributed Workloads

New Windows PCs powered by NVIDIA RTX Spark are coming this month from Acer, ASUS, Dell, HP, Lenovo, Microsoft and MSI. Sign up for the RTX Spark newsletter to receive future updates. 

Alibaba’s Qwen-Image-2.1 brings image generation and editing together in a lightweight, open-weight model. It runs locally on NVIDIA RTX GPUs, DGX Spark and DGX Station, giving creators more ways to create and refine images on their own hardware.

Follow NVIDIA RTX Spark on X, Instagram, TikTok and Facebook — and stay informed by subscribing to the NVIDIA Local AI newsletter. Follow NVIDIA Workstation on LinkedIn and X. 

See notice regarding software product information.


How Open Science Can Help Researchers Prepare for the Next Pandemic


When COVID-19 emerged, scientists had a crucial advantage: Decades of prior research on coronaviruses meant they understood the virus’ key proteins well enough to design vaccines in record time. The next pandemic may not offer the same head start. 

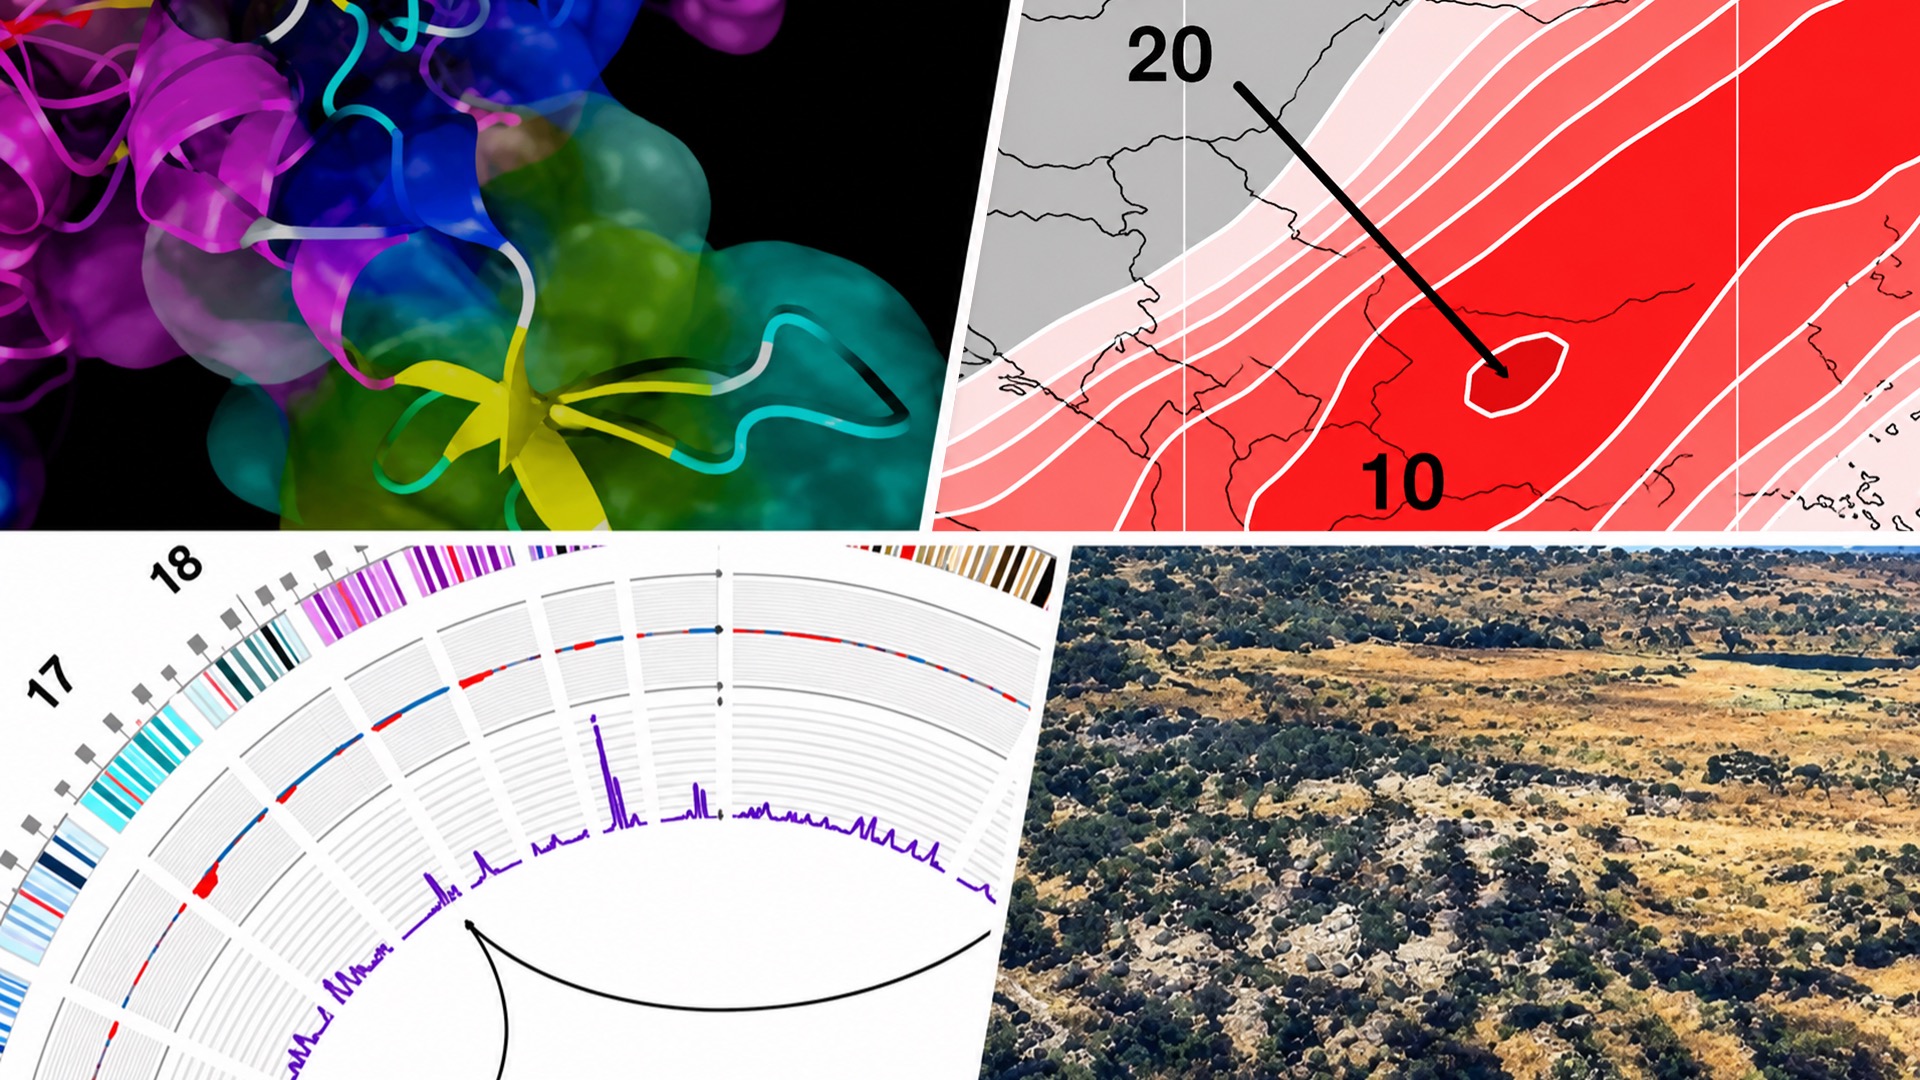
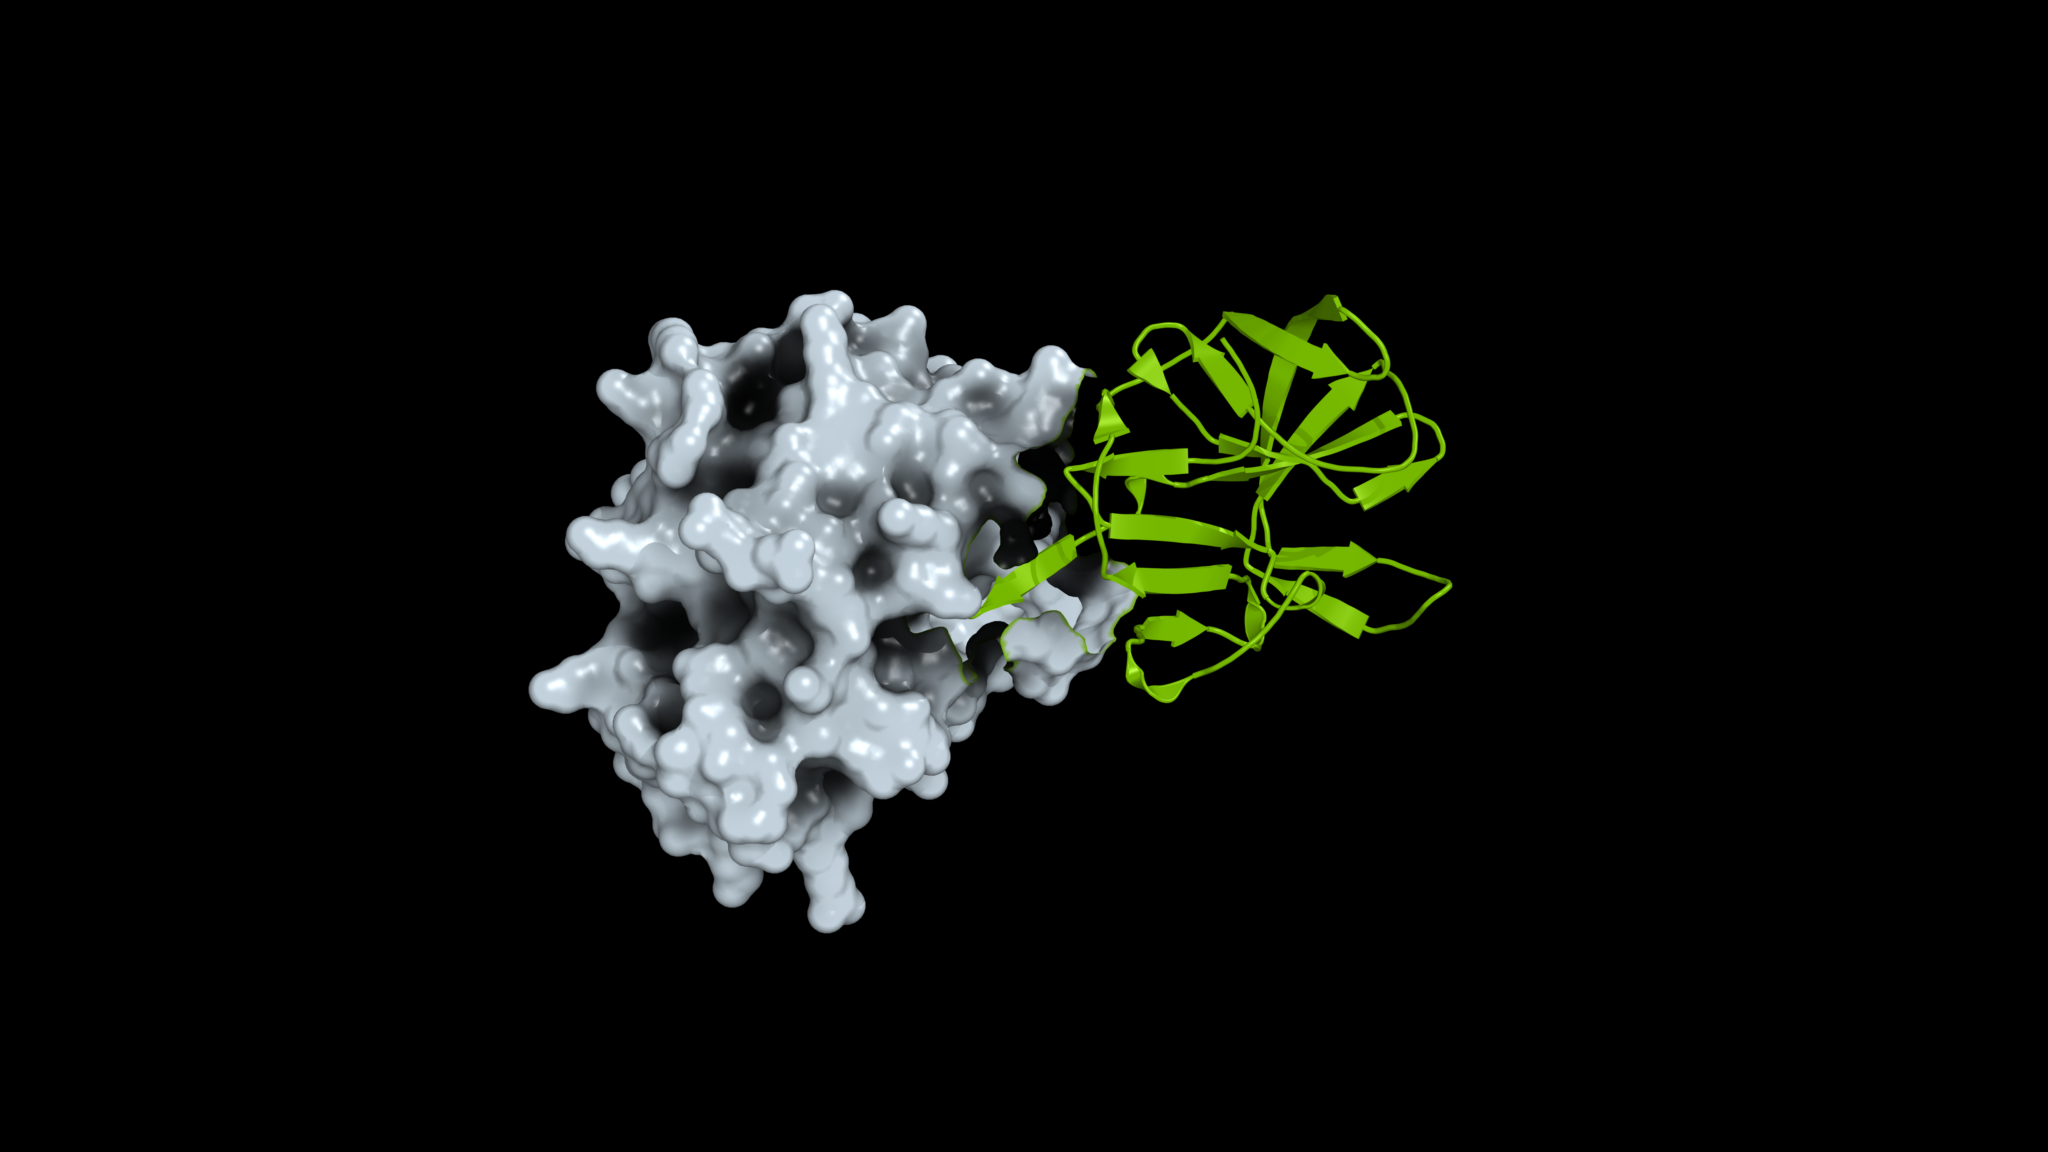
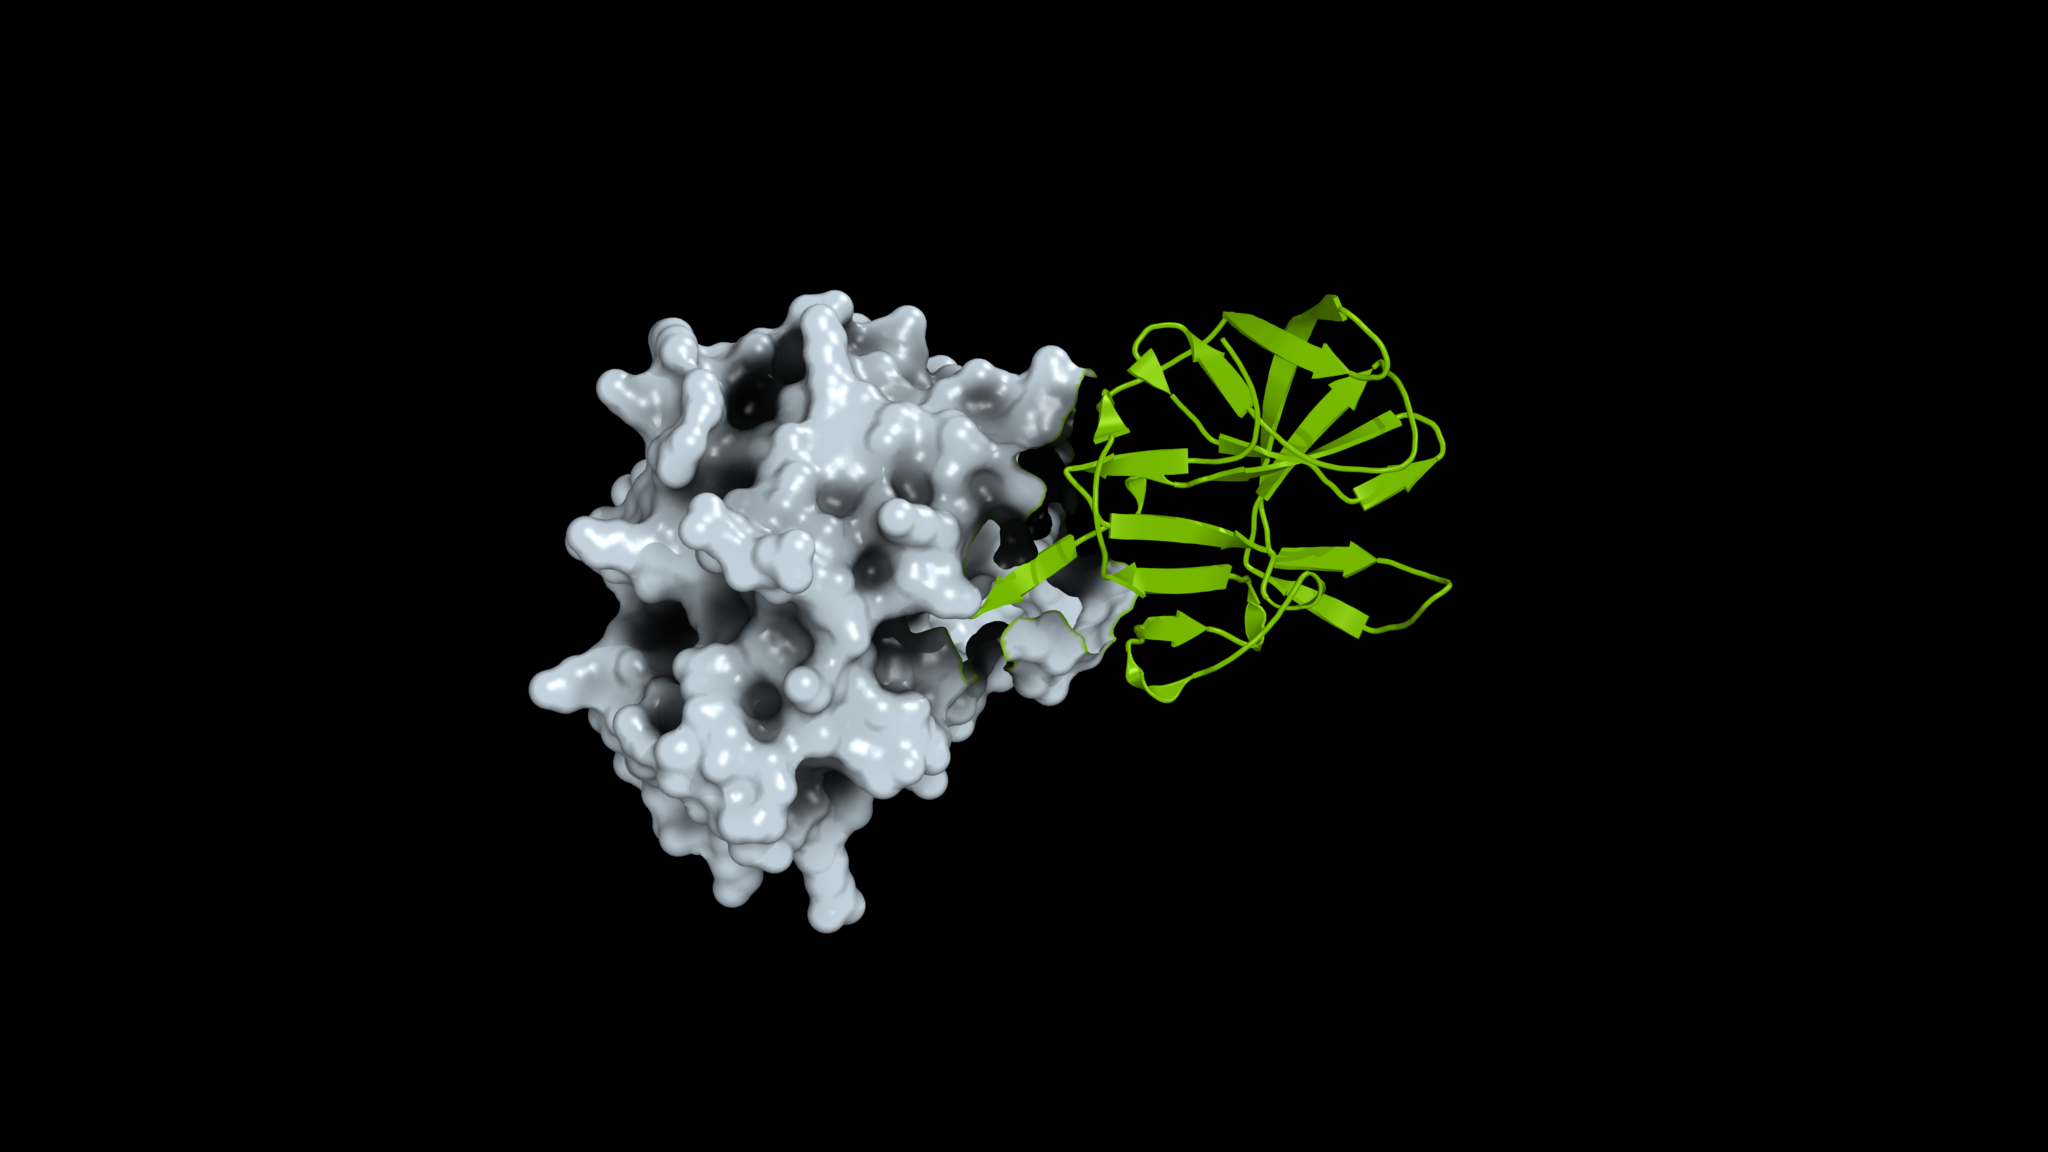
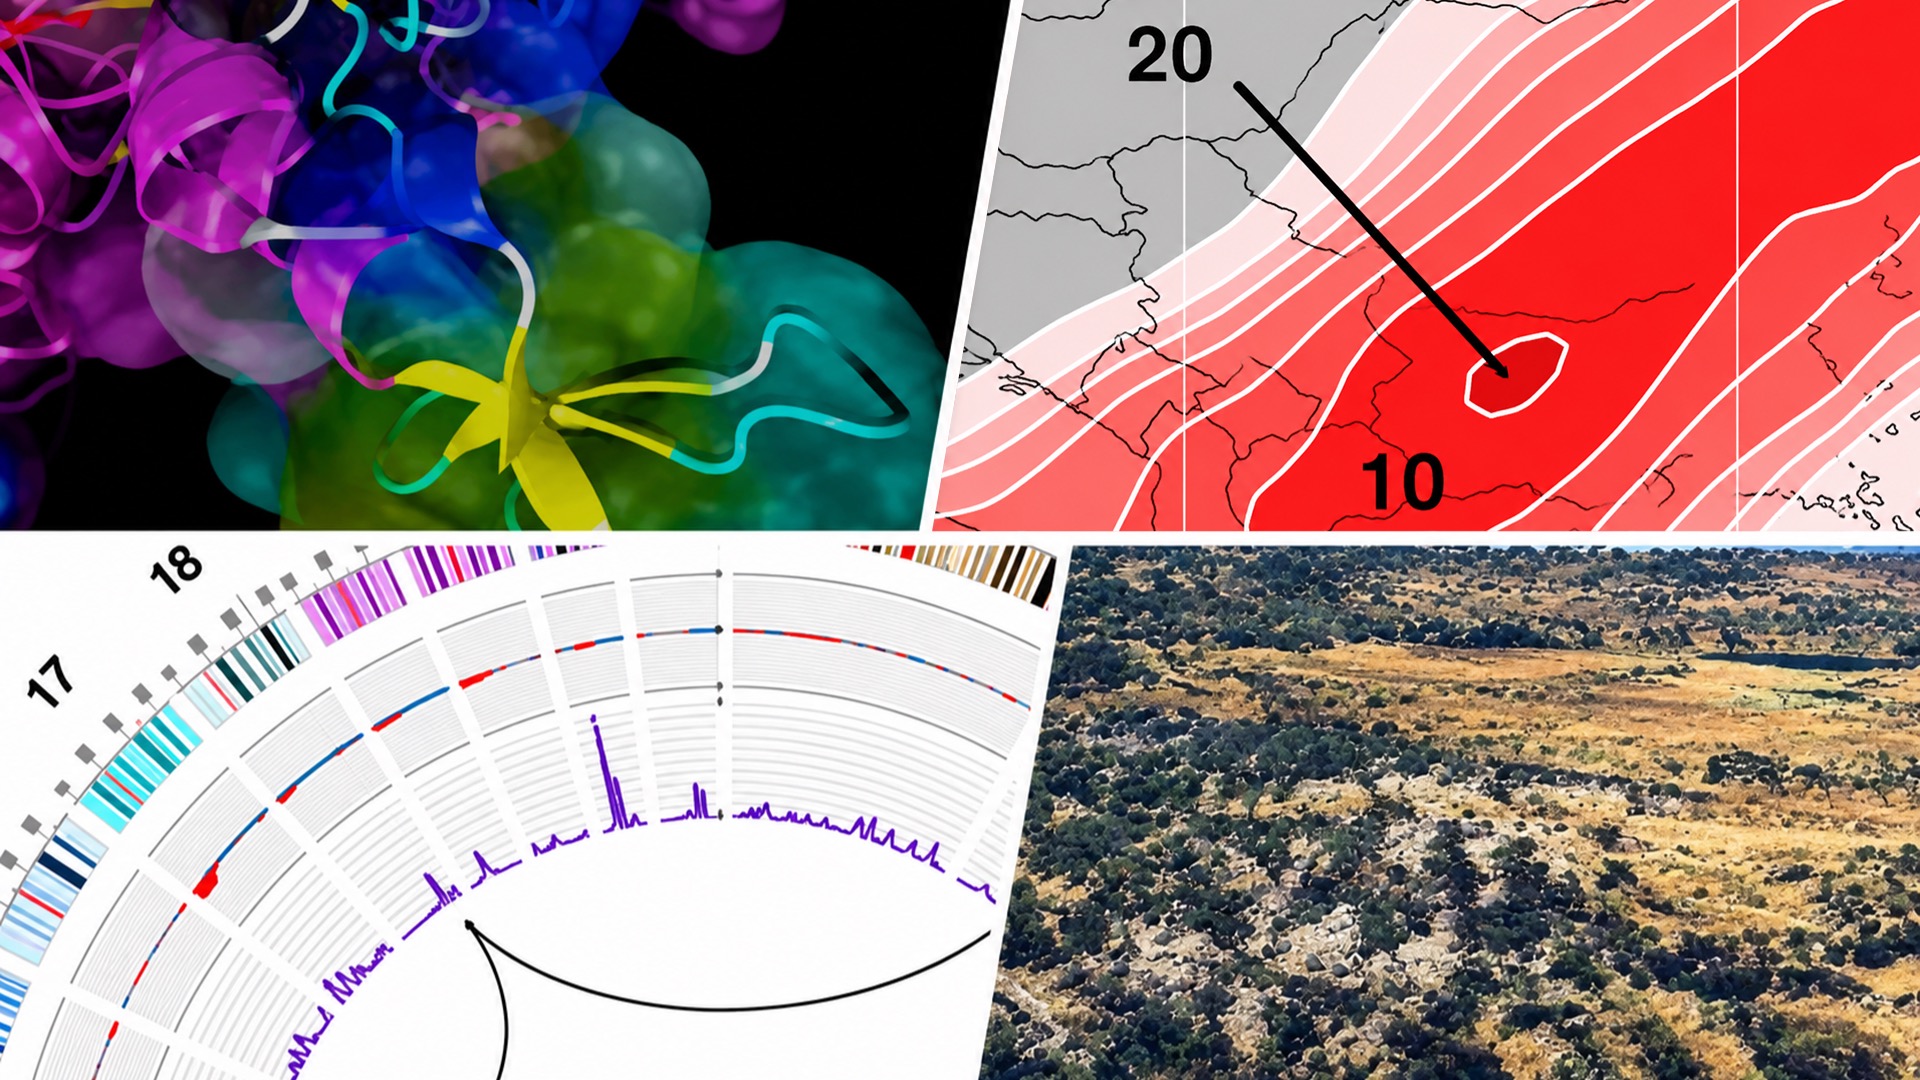
To help improve the odds, NVIDIA has joined a coalition of global research organizations, including Google DeepMind and the European Molecular Biology Laboratory’s European Bioinformatics Institute (EMBL-EBI), to release predicted 3D structures for the protein complexes of more than 2,800 viruses — openly available to any scientist, anywhere, through the AlphaFold Database.

The structures in the newly released dataset were inferred using AlphaFold2 — Google DeepMind’s AI model for predicting how proteins fold into 3D shapes — with optimization from NVIDIA BioNeMo Inference Runtime. This allowed the team to scale inference to thousands of viral proteomes, predicting the complexes, or groups of interacting proteins, encoded within each virus. 

“Our ambition with the AlphaFold Database has always been to democratize access to foundational biology at scale,” said Risha Patel, life sciences partnerships manager at Google DeepMind. “This collaboration to bring thousands of viral complexes into the database will equip scientists around the world with insights they need to help prepare for future outbreaks.”

NVIDIA is also openly releasing the BioNeMo Structure Prediction Pipeline, the GPU-accelerated workflow used to generate the dataset, so researchers can go from protein sequence to predicted 3D structure for their own targets.

Preparation for the next pandemic must begin now. An analysis by the Center for Global Development estimates a roughly 50% chance of the world facing a pandemic as severe as COVID-19 by 2050.

“When the next pandemic happens, there may be something that comes out of the blue, and we’ll be lacking the knowledge we had for COVID,” said Joe Grove, professor of molecular virology at the Medical Research Council-University of Glasgow Centre for Virus Research and a collaborator on the project. “What we’re trying to do is stockpile some of that knowledge ahead of time.”

About 30% of the protein interactions being added to the database are completely new to science, showing interaction shapes that have never been documented in the Protein Data Bank, the main repository of experimentally determined protein structures. This translates to new insights for the biological community to explore and harness to generate new knowledge.

“This database is an engine for hypothesis generation,” said Chris Dallago, applied research science team lead in digital biology at NVIDIA. “We’re enabling biologists and the AI community to investigate protein interactions, not just as single molecules but as complexes, so the whole field can move forward.”

Predicting Complex Protein Structures

Most proteins don’t work alone — they come together in complexes of multiple molecules to perform sophisticated functions. Those structures are often what a vaccine or drug must target to disrupt viral function. 

Understanding the 3D structure of the COVID-19 virus’ spike protein, for example, proved foundational to vaccine design. For thousands of other viruses, no such structural knowledge exists today. This dataset begins to fill that gap.

Traditional methods for determining protein structures — crystallizing proteins and shooting X-rays at them — can take years and cost thousands of dollars per structure. AlphaFold2, which was optimized with NVIDIA BioNeMo to efficiently run on NVIDIA GPUs, predicts a structure in minutes and can be run in bulk. Scientists can then verify high-confidence predictions through experimental methods. 

For this project, the team systematically worked through the protein structures of viral families known to infect humans, from common-cold viruses to emerging threats like Mpox. 

A Global Collaboration With Global Access

The collaboration spans the Coalition for Epidemic Preparedness Innovations, EMBL-EBI, Google DeepMind, NVIDIA, Seoul National University, Sungkyunkwan University, the Swiss Institute of Bioinformatics and the University of Glasgow. 

The dataset release — coinciding with a United Nations General Assembly meeting convened by the World Economic Forum on pandemic prevention, preparedness and response taking place this week in New York City — contributes to the AlphaFold Database, which now holds more than 260 million protein and protein complex predictions covering nearly every cataloged protein known to science.

“Making this data open is critical for understanding viral diagnostics and developing treatments and vaccines,” said Jo McEntyre, interim director of EMBL-EBI. “The dataset also covers lesser-studied viruses and lowers the barriers for scientists in low-resource settings who are confronting outbreaks firsthand.”

Predictions in the open dataset are labeled by confidence. The structures show what viral complexes may look like and how individual proteins might interact within a viral proteome. 

Overall, the new data represents a major contribution to the information available for scientists across digital biology and disease research.

“When I did my Ph.D., there were no structures for any of the proteins we were investigating. It was like working in the dark — we had to guess what was going on,” said Grove. “This dataset is a powerful tool for all the researchers doing their Ph.D.s now, giving them high-quality structural data that’s going to accelerate fundamental science.”

Explore the viral protein complex dataset on the AlphaFold Database Pandemic Preparedness Portal, predict structures for protein targets with the BioNeMo Structure Prediction Pipeline, and learn more about NVIDIA BioNeMo.

University of Manchester Uses NVIDIA Earth-2 to Forecast Air Pollution Across the UK


Air pollution is a serious public health risk, contributing to an estimated 30,000 deaths in the U.K. alone last year. Data-driven insights can help — but computing air quality with traditional chemistry-based models is expensive, which limits how detailed they can be and how regularly they can be run. 

David Topping, a professor in the University of Manchester’s department of Earth and environmental science, saw that the NVIDIA Earth-2 family of open AI models and tools had cracked a related problem for weather forecasting — and asked whether the same generative frameworks could work for pollution fields.

“The biggest challenge is the compute required to forecast air quality,” said Topping. “Once you put chemistry into weather models, they get really, really slow. So I said, why don’t we try using the generative frameworks that NVIDIA develops for climate and weather for pollution fields?”

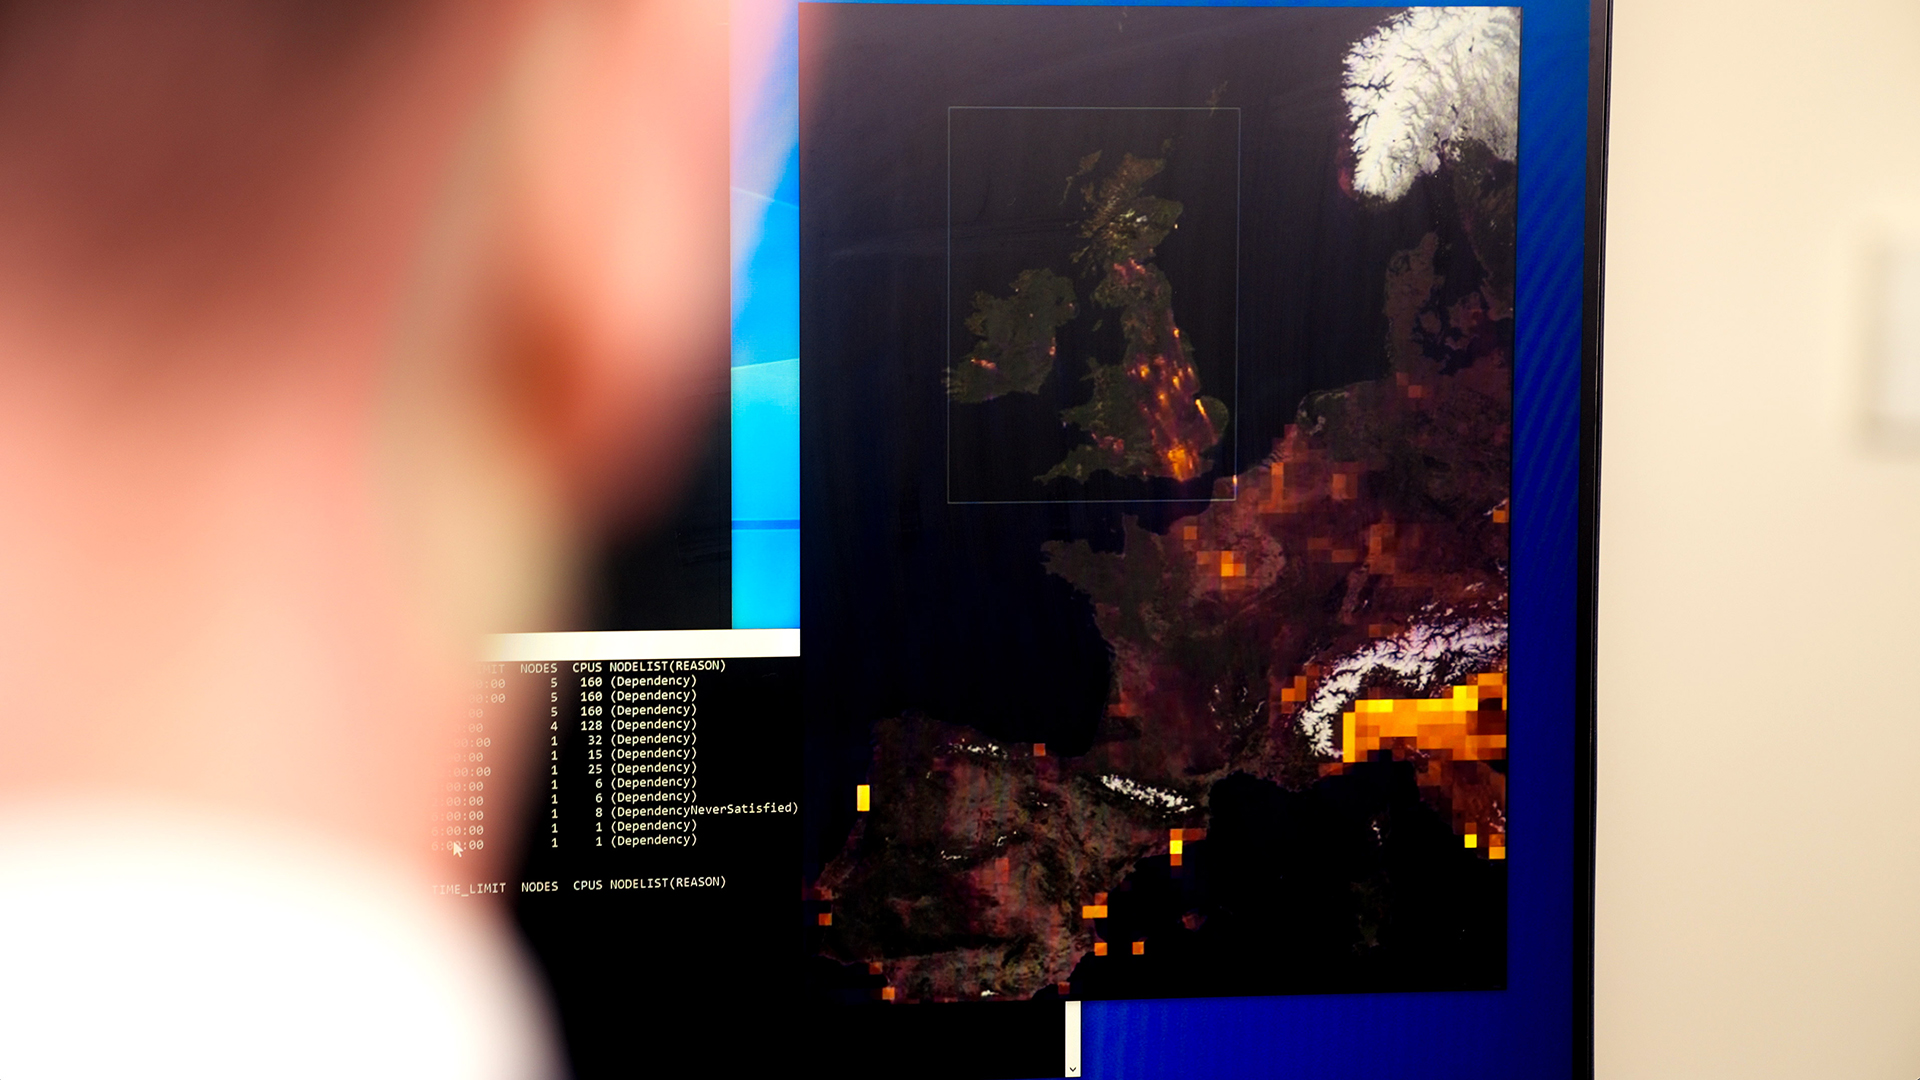
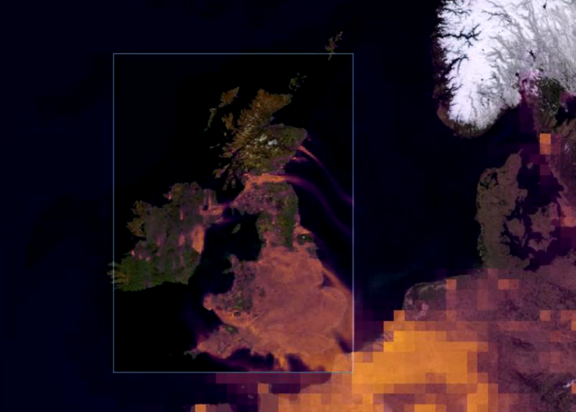
Working with the NVIDIA Earth-2 team, Topping and colleagues generated training data from existing chemistry-climate simulations, then trained Earth-2 CorrDiff — a generative downscaling model — on Isambard-AI, the U.K.’s national AI supercomputer in Bristol. 

The model worked on the first attempt. 

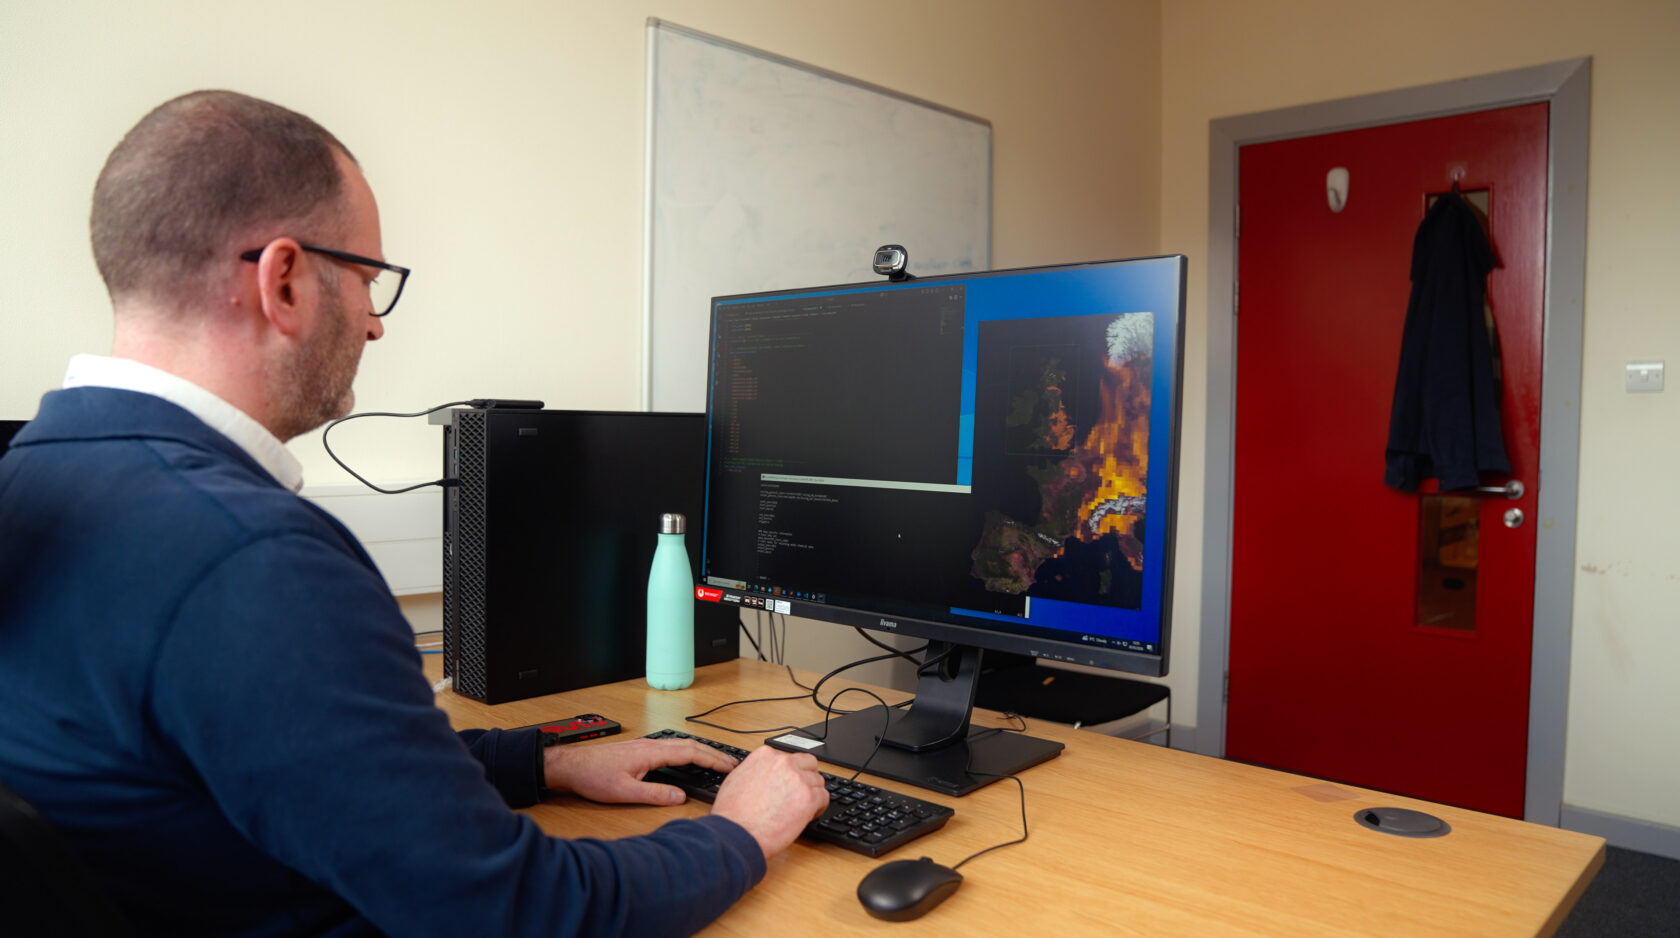
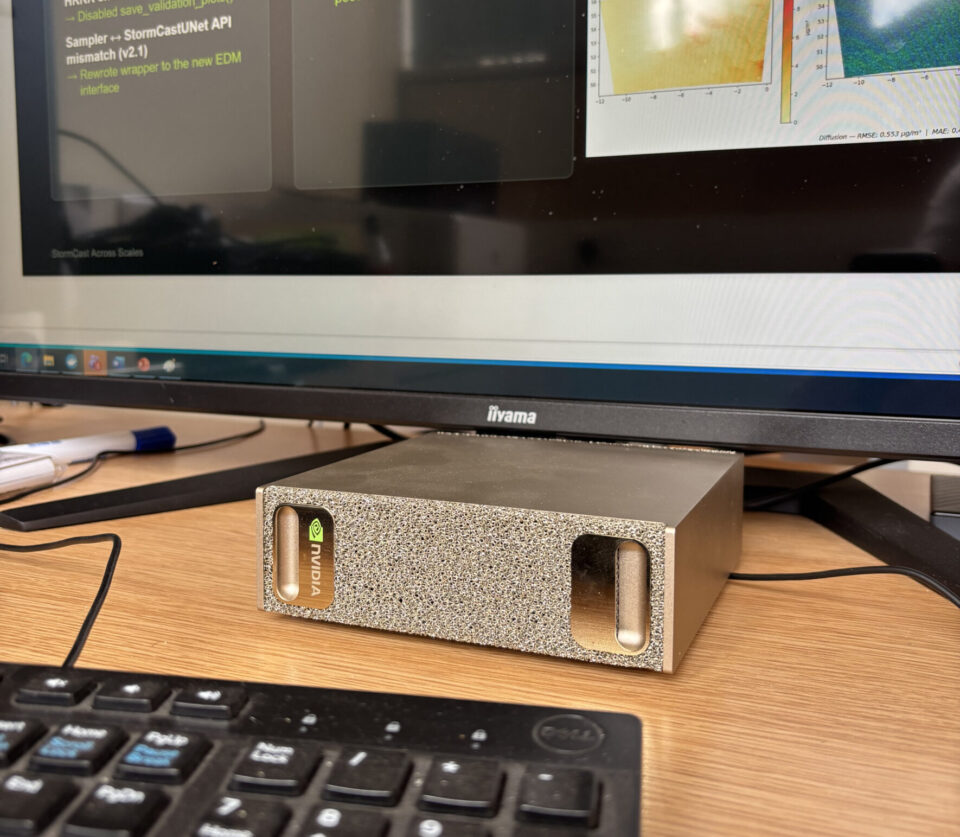
The team has since added Earth-2 StormCast, a model that enables time-dependent forecasts that directly use air quality observations, and showed the test-training and inference workflows running on the NVIDIA DGX Spark personal AI supercomputer.

“To improve human health, it’s essential that we understand the impact of environmental stressors in the air we breathe,” said Topping. “Our U.K.-wide pollution model allows us to model potential future scenarios, such as predicting what would happen if different pollution-related government policy changes went into effect.

Video credit: Bristol Centre for Supercomputing (BriCS) @ University of Bristol

Another potential application is proactive air quality insights for healthcare organizations. Topping envisions a scenario where regional and national healthcare services could reach out to patients with conditions like asthma to let them know that air pollution is going to be high in their area tomorrow, or next week. 

The team is also exploring how the air pollution model could pair with data from edge AI devices to ingest real-time air quality data and drive real-time decision making, such as in the event of a wildfire. 

“The fact that this model trained in two days on Isambard-AI — and can now run on a DGX Spark sitting on a desk — changes who can do this science and how quickly,” said Niall Robinson, developer relations manager for weather and climate at NVIDIA. “We’re just at the beginning of what these open workflows can do globally.” 

“The ability to switch from one NVIDIA framework to another was really impressive,” said Hao Zhang, a doctoral student at the University of Manchester who trained StormCast on Isambard-AI. “We’re only just starting to explore how to use these frameworks in different ways to model complex pollution fields.”

From National Supercomputer to the Desktop


To retrain the Earth-2 model for air pollution, Topping and the team used a year’s worth of U.K. pollution data simulated at hourly intervals to generate a detailed, U.K.-wide pollution model at a resolution of 2-3 square kilometers.

Running on a single, eight-GPU node on Isambard-AI — the U.K.’s most powerful AI supercomputer, packed with 5,448 NVIDIA GH200 Grace Hopper Superchips delivering 21 exaflops of AI performance — the process took just two days.

“Earth-2 CorrDiff has shown an incredibly efficient use of the world-class NVIDIA hardware inside Isambard-AI,” said Simon McIntosh-Smith, director of the Bristol Centre for Supercomputing at University of Bristol and cofounder of Isambard-AI. “It’s fitting that, for a climate-based project, the GPU hours used were relatively low, requiring less power from the supercomputer to run the workloads.”

In addition to providing a look back at air pollution over the past year, the model can help predict future air pollution scenarios for the U.K. The team plans to further increase the resolution of its model by incorporating additional open data, enabling researchers to understand air pollution at street scale.  

The same generative pollution workflow also runs on the NVIDIA GB10 Grace Blackwell superchip-powered DGX Spark desktop AI system for inference and smaller training runs. Topping now has an DGX Spark system in his office retraining models.

“You can now invest a few thousand dollars to get started developing powerful AI models,” Topping said.

Open Science, Agentic Future

The team plans to release open source training data and workflows for the pollution models will be released so that similar models can be trained for other countries and regions. 

“Our aim is to offer this workflow to the entire world,” he said. “We hope that every global country and every major city with a small burst of supercomputer AI time will be able to produce their own detailed pollution models with their own local data.” 

Looking five years out, Topping sees the endpoint as something simpler still: an agentic interface where a clinician or government agency asks the question and the chain of models handles everything else. 

“With better open access to air quality observations, someone could ask our pollution model running on DGX Spark: what’s the pollution going to be like in this neighborhood tomorrow?” he said. “And a whole chain of interactions will deliver an answer, grounded on the science these frameworks represent.”

Learn more about NVIDIA Earth-2 climate and weather AI.

Sparks Fly: NVIDIA Accelerates Local AI at IFA 2026


Frontier intelligence is going local. At IFA 2026, NVIDIA, Microsoft and its partners are teaming up to provide faster inference and new tools that make agents easier to set up and run locally on NVIDIA hardware. New compact NVIDIA RTX Spark Windows PCs are also coming in October to give AI enthusiasts, developers and creators more ways to run capable agents locally and securely. 

Today’s announcements include:

  • Simplified local AI support for NVIDIA GPUs is coming in Hermes Agent, OpenClaw and Perplexity Portable Computer.
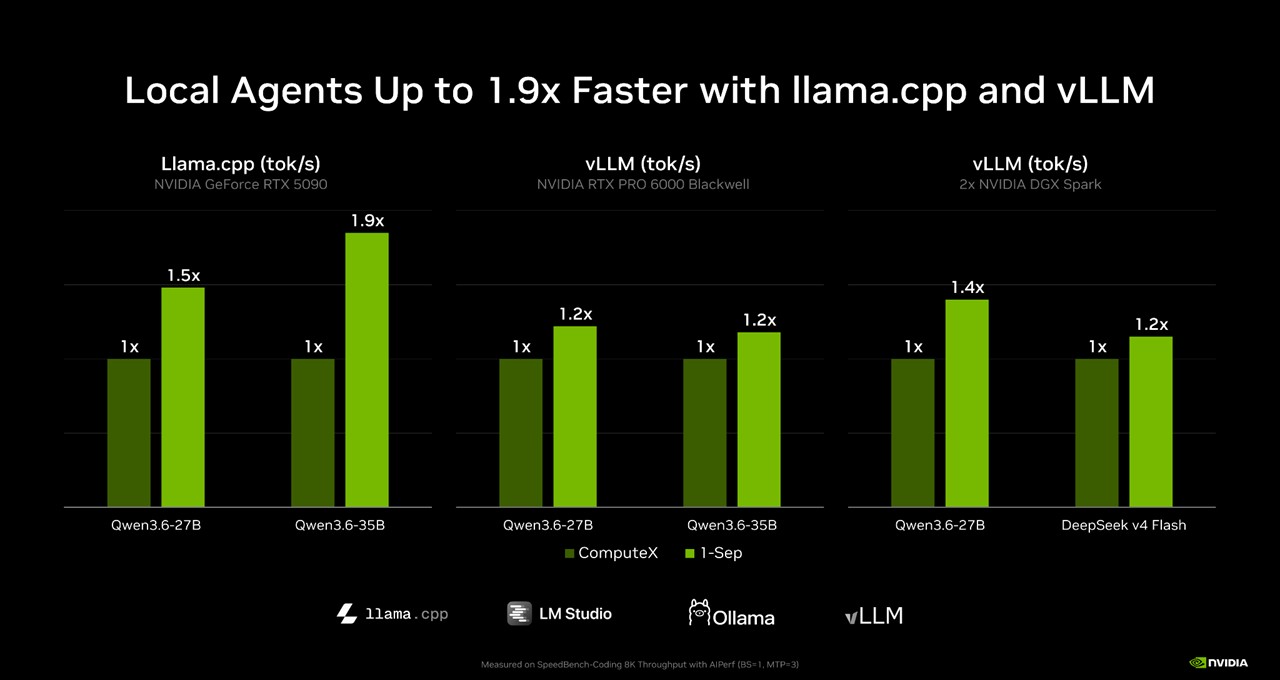
  • Up to 1.9x faster local inference — new llama.cpp and vLLM optimizations are available now directly and through LM Studio and Ollama. 
  • NVIDIA PAIR — a Personal AI Router tool that intelligently distributes AI inference across the PCs on a user’s local network.
  • NVIDIA RTX Spark arrives in October  — with new Windows PCs from Lenovo and Acer. Electronic Arts, Embark and Ubisoft are among the latest game publishers and developers bringing their blockbuster titles to NVIDIA RTX Spark.

Also, August was a busy month for local AI:

  • Nemotron 3.5 Lightning — which can run on NVIDIA RTX PCs, RTX PRO Workstations, DGX Spark and Jetson — is a 30-billion parameter model that has been launched. Get started with Nemotron 3.5 Lightning today. 
  • Z.ai’s GLM-5.3-Flash is a multimodal mixture-of-experts (MoE) model that’s bringing agentic AI to DGX Station.
  • Qwen has released Qwen3.8-Flash-Next, an open weight multimodal MoE model, which can run locally on DGX Spark and DGX Station, along with Qwen3.8-27B, a 27-billion-parameter open model optimized for local agentic and coding workloads on NVIDIA GPUs. 
  • LTX’s LTX 2.5 is an open-world video generation model optimized for NVIDIA RTX GPUs, DGX Spark and DGX Station, with new NVFP4, FastVideo and ComfyUI enhancements for faster, more memory-efficient local generation.
  • MiniMax-H3 is an open-weight video generation model with synchronized audio that can run locally on NVIDIA GPUs through ComfyUI. FastVideo teamed up with NVIDIA researchers to improve this further by releasing FastH3 — an open-weight, four-step distilled version that improves performance by 7x. Optimized FastVideo recipes for NVIDIA RTX GPUs and DGX Spark are coming soon.
  • Meta’s Muse Glimmer is a 30-billion-parameter open-weight model for coding and agentic workloads that can run locally on GeForce RTX PCs, DGX Spark, DGX Station and Jetson. NVIDIA has also released NVFP4 quantization with DGX Spark support for more memory-efficient local deployment.
  • DeepSeek v4 Flash is a 284-billion-parameter MoE model with 13 billion active parameters that can run locally on 2x DGX Spark cluster and DGX Station.

A Simpler Start for Local Agents

Getting a local agent up and running with local models required some effort — choosing a model, finding a compatible inference server, dialing in quantization settings and keeping everything updated. That friction is disappearing on RTX and DGX systems.

Three of the most widely used agent apps will offer simplified local model setup on Windows, each built on llama.cpp and incorporating NVIDIA’s latest inference optimizations. The new setup experiences are designed to reduce manual configuration and make it easier to get local agents up and running. 

Last month, Perplexity introduced its Portable Computer agent, giving users a simple way to run Perplexity locally on Linux systems like NVIDIA DGX Spark with the models, orchestration and tools packaged into a single app experience.

Perplexity Portable Computer is available on NVIDIA RTX GPUs with at least 24GB VRAM running on Linux, with support on Windows coming soon, bringing that same streamlined setup to a broader group of PC users. Users can run complete workflows locally without consuming credits, while selectively escalating parts of a task to one of 15+ frontier models in the cloud when additional research or reasoning is needed. Portable Computer asks for permission before sending content to the cloud, helping users keep sensitive information on their device. Here’s some example use-cases:

  • Engineering: Review open PRs in a connected GitHub repo and sort them into ready, blocked, stale, and needs review, each tagged with the next step. Docs that fell out of sync with the latest merge get caught and fixed, with a PR opened for the changes.
  • Finance: Point the agent at two years of brokerage summaries, consolidated 1099s and tax returns and have it trace the recurring holdings creating the most avoidable fees and tax drag, with every figure cited to the exact file and page — all without a document ever reaching a chatbot.
  • Startups: Ask why activation went flat, and the agent analyzes the funnel export locally to find where new signups drop off between install and first completed task, then posts the top insights straight to the team’s Slack channel.

Try Portable Computer today.

Hermes Agent — developed by Nous Research — is a general-purpose agent used by millions that excels at reliability and self-improvement. Model- and provider-agnostic, Hermes is built to run all day on local systems, making RTX PCs, RTX PRO workstations and DGX Spark a natural fit.

Configuring a local model in Hermes will provide users with one-click setup across RTX and DGX systems on Windows. The agent will automatically detect the NVIDIA GPU, select an appropriate model and configuration, and run it through integrated llama.cpp with NVIDIA inference optimizations already in place, eliminating manual model downloads and tuning. Support for Linux is coming soon.

Once it is running, Hermes works the way it does anywhere else. It uses tools, maintains context across tasks, remembers information between sessions and creates reusable skills over time, allowing the agent to become more capable with continued use. Running the model locally on a GPU keeps performance fast while keeping data on the system.

One-click local model setup is available now on Windows, with support coming soon to Linux. Learn more about Hermes Agent.

OpenClaw has become one of the defining projects of the open-agent movement — the largest AI project on GitHub, with more than 380K stars and a fast-growing community that’s building tools and skills across research, engineering, project management and everyday productivity.

NVIDIA, Microsoft and OpenClaw have been working together to make that experience easier to set up on Windows PCs. To reduce onboarding friction, the OpenClaw Windows App simplifies the process of setting up an optimized local model on any RTX GPU with at least 24GB of VRAM.

Learn more in the OpenClaw blog.

Faster Inference Gives Local Agents a Boost

Inference performance is critical to keeping local agents responsive. NVIDIA is continuing to collaborate with the open-source llama.cpp and vLLM communities to accelerate agentic workloads across local NVIDIA platforms.

llama.cpp delivers up to 1.9x higher throughput through kernel optimizations on a GeForce RTX 5090, enhanced speculative decoding techniques and faster prefill. ​

vLLM delivers 1.2x on RTX PRO 6000 Blackwell Workstation Edition and up to 1.4x on two DGX Spark clusters. New XQA attention kernels in FlashInfer and backend optimizations help to accelerate inference across both platforms.

These gains are available on the llama.cpp and vLLM inferencing backends. 

Users can also experience these via the LM Studio and Ollama applications.

Tap Idle PCs for More Local AI Compute With NVIDIA PAIR

More than half of U.S. households have two or more PCs, and much of that computing power sits idle throughout the day. NVIDIA Personal AI Router (PAIR) is a free, open source software tool that puts those systems to work together for local AI.

Agentic workflows often break complex tasks into smaller jobs that can run in parallel, but performance can slow when every request is competing for the same GPU. PAIR automatically discovers compatible PCs on a local network and routes independent inference requests to whichever system has capacity. It works with Ollama and LM Studio and can adapt as devices join or leave the network.

For example, a user could ask Hermes to create a “Sunday Reset” plan by sorting through a cluttered inbox and prioritizing what needs attention now, what can wait and what can be skipped. Hermes can split that work across multiple subagents, while PAIR distributes those jobs across available PCs instead of having them all wait on a single GPU.

The result is more compute for local agents, with more tasks running in parallel and the flexibility to move AI workloads to another PC while the main system is being used for gaming, creating or other work.

The NVIDIA PAIR beta is available for Windows, macOS and Linux through both graphical and terminal interfaces, supporting NVIDIA GeForce RTX 20 Series GPUs and newer, NVIDIA RTX PRO workstation GPUs (Turing architecture and newer), NVIDIA DGX Spark and Apple M4 or newer silicon.

Check out the NVIDIA tech blog to get started with NVIDIA PAIR. 

Powerful On Device Photo Editing With Cyberlink PhotoDirector AI PC Mode on RTX Spark

Open image and video models enable artists to experiment with Creative AI models on PCs.  This enables artists to iterate and explore concepts and ideas, without the dreaded token anxiety and keep more of their creative work private and on-device.

CyberLink’s new PhotoDirector AI PC Mode is one of the first applications to integrate these diffusion models directly into a creative software, and turn them into a creative tool at the finger tips of the artists. Coming to PhotoDirector 365 and optimized for NVIDIA RTX Spark when it launches, AI PC Mode users are getting AI-powered editing tools for generative editing, image enhancement, object and distraction removal, background removal and replacement, portrait refinement and the creation of entirely new visuals — with the flexibility to choose between local or cloud processing, depending on the task.

On NVIDIA GPUs, PhotoDirector uses TensorRT-RTX and FP8 to accelerate local AI.

Start using Cyberlink’s PhotoDirector 365 photo editing software and learn more about PhotoDirector AI PC Mode, launching with RTX Spark in October.

NVIDIA RTX Spark Windows PCs Arrive October 2026

NVIDIA RTX Spark is coming this October— and at IFA 2026, partners are showing off their hardware. At IFA, newly announced designs join the existing six OEMs shipping in October. Acer showed its compact desktop RTX Spark concept, and Lenovo announced its Yoga Pro  9n and Yoga 9n 2-in-1.  

RTX Spark is a new beginning for Windows PCs. One PC built for creators, gamers and AI agents. With a powerful 1 Petaflop RTX Blackwell GPU, up to 128GB of unified memory and a highly efficient 20-core Grace CPU, RTX Spark delivers incredible performance and efficiency. This superchip enables high performance thin laptops with all day battery life and compact desktops to power always-on agents. Paired with the new Windows Agent framework, it enables agents that run safely in the background under OS level control.

Last week at Gamescom, Electronic Arts, Embark and Ubisoft were among the latest game publishers and developers bringing their blockbuster titles to NVIDIA RTX Spark Windows PCs. They join the publishers that announced RTX Spark support at COMPUTEX in May, including KRAFTON, NetEase, Riot Games and XBOX. Read more.

Sign up to be notified when RTX Spark laptops and desktops are available.

#ICYMI: More Updates From NVIDIA Local AI 

🎮 NVIDIA Brings New RTX Tech and Games to Gamescom — NVIDIA released DLSS 4.5 Ray Reconstruction, featuring a new second-generation transformer model for improved image quality in ray-traced and path-traced games. Gamescom also brought new RTX announcements for titles including 007 First Light, CONTROL Resonant and Gears of War: E-Day, plus expanded game support for the upcoming NVIDIA RTX Spark.

🐋Introducing DeepSeek Harness — DeepSeek’s new open source harness pairs with DeepSeek-V4-Flash to power local agentic coding workflows on NVIDIA DGX Station and multi-DGX Spark setups.

📊MLPerf Client v2.0 Expands AI PC Benchmarking — MLCommons released MLPerf Client v2.0, developed in collaboration with NVIDIA and other industry leaders. The update adds new benchmarks for agentic AI and image generation, alongside expanded LLM testing for real-world local AI workloads.

Follow NVIDIA RTX Spark on X, Instagram, TikTok and Facebook — and stay informed by subscribing to the NVIDIA Local AI newsletter. Follow NVIDIA Workstation on LinkedIn and X. 

See notice regarding software product information.


NVIDIA and CrowdStrike Strengthen Agentic Cybersecurity Frontier


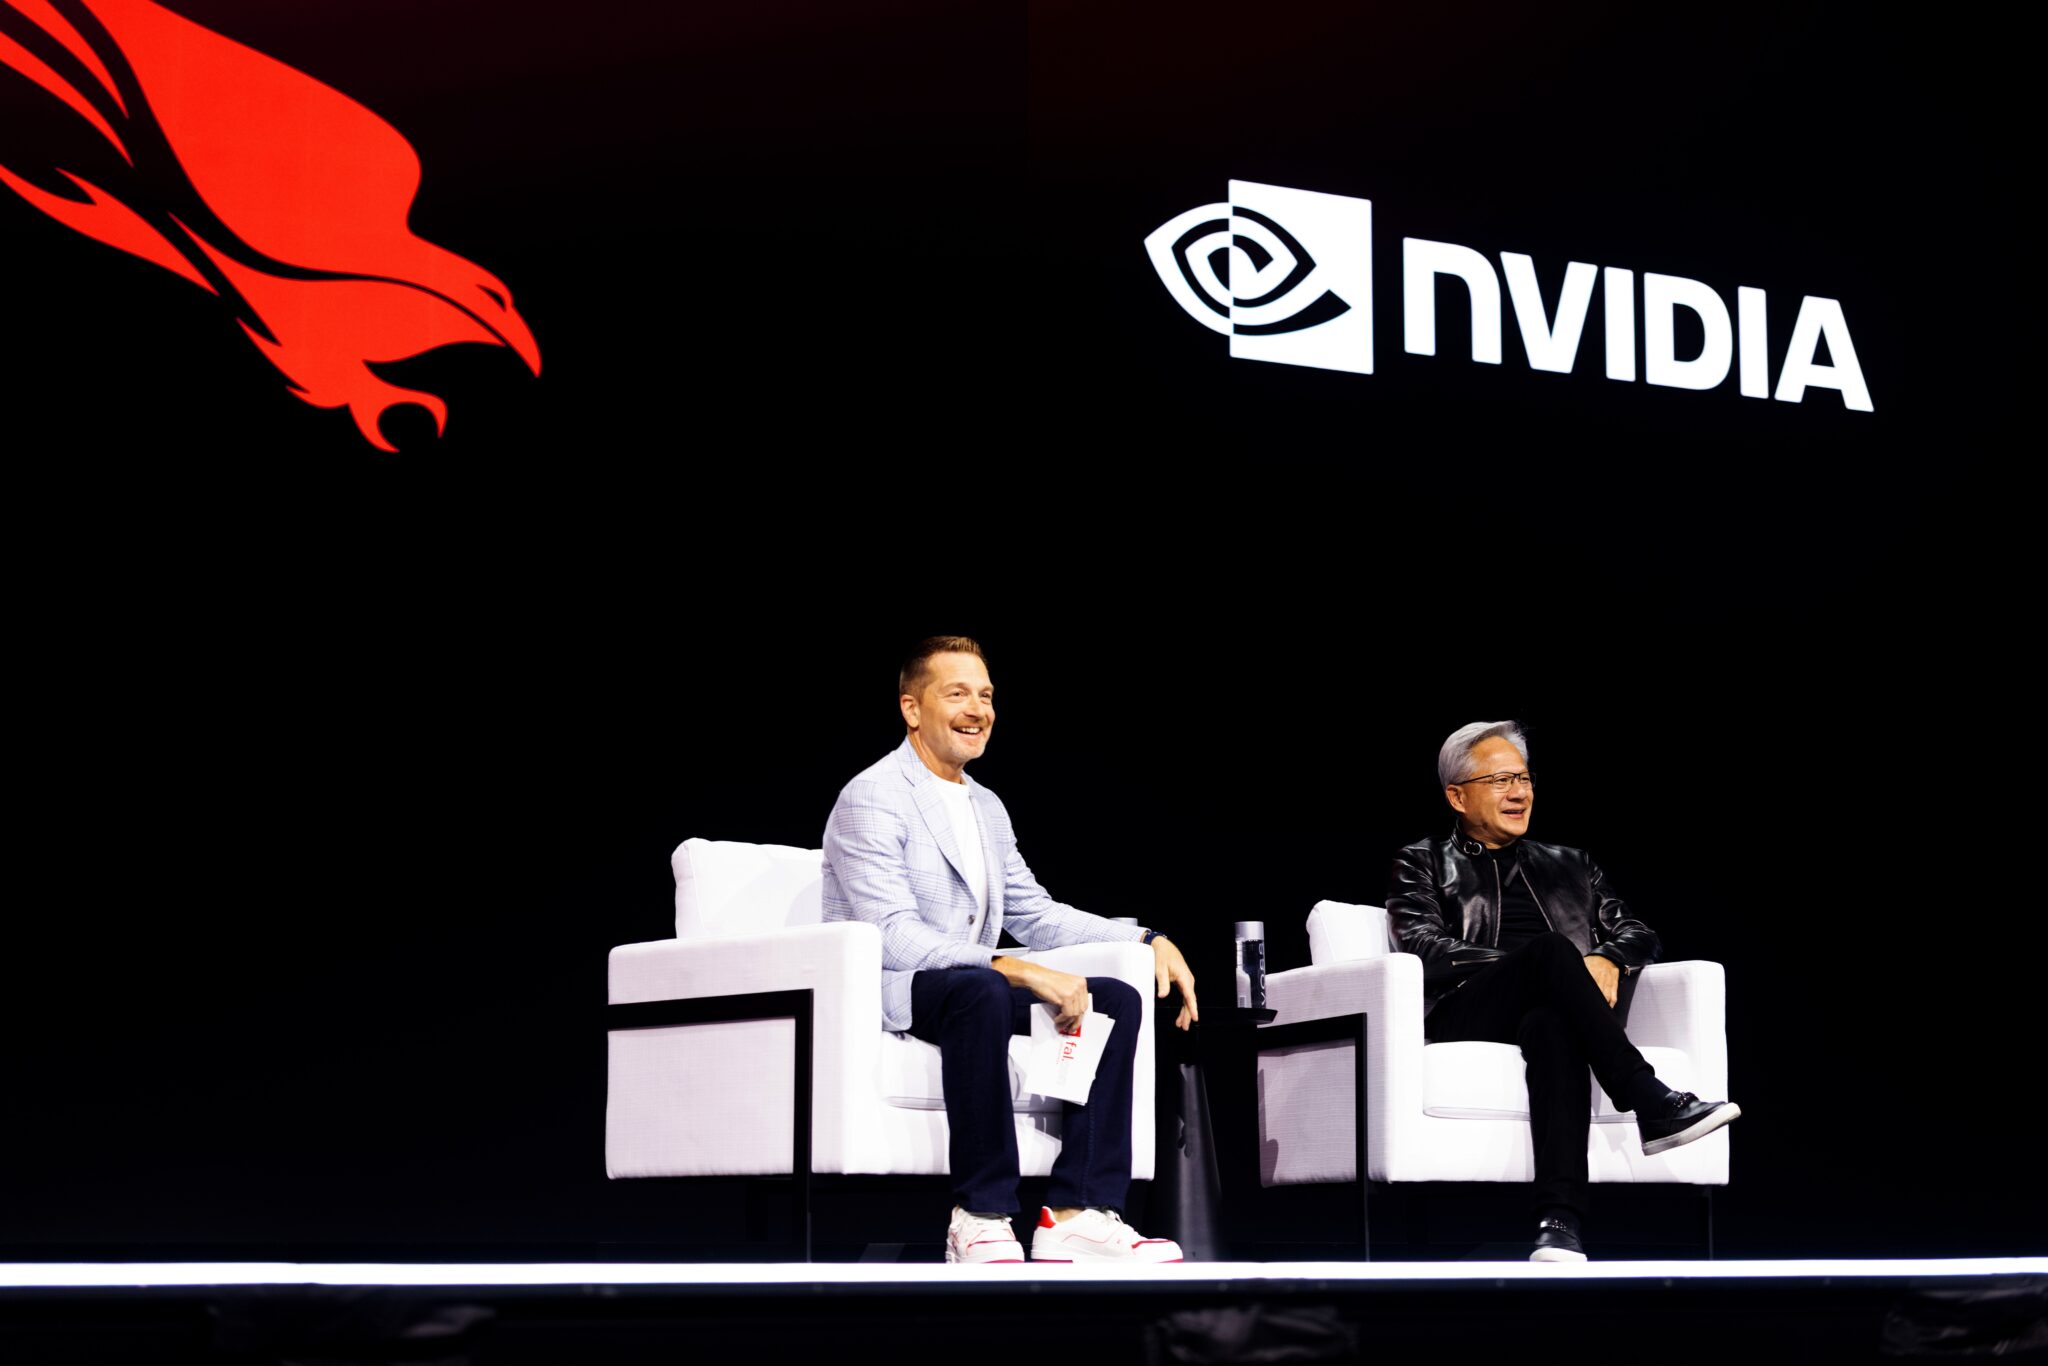
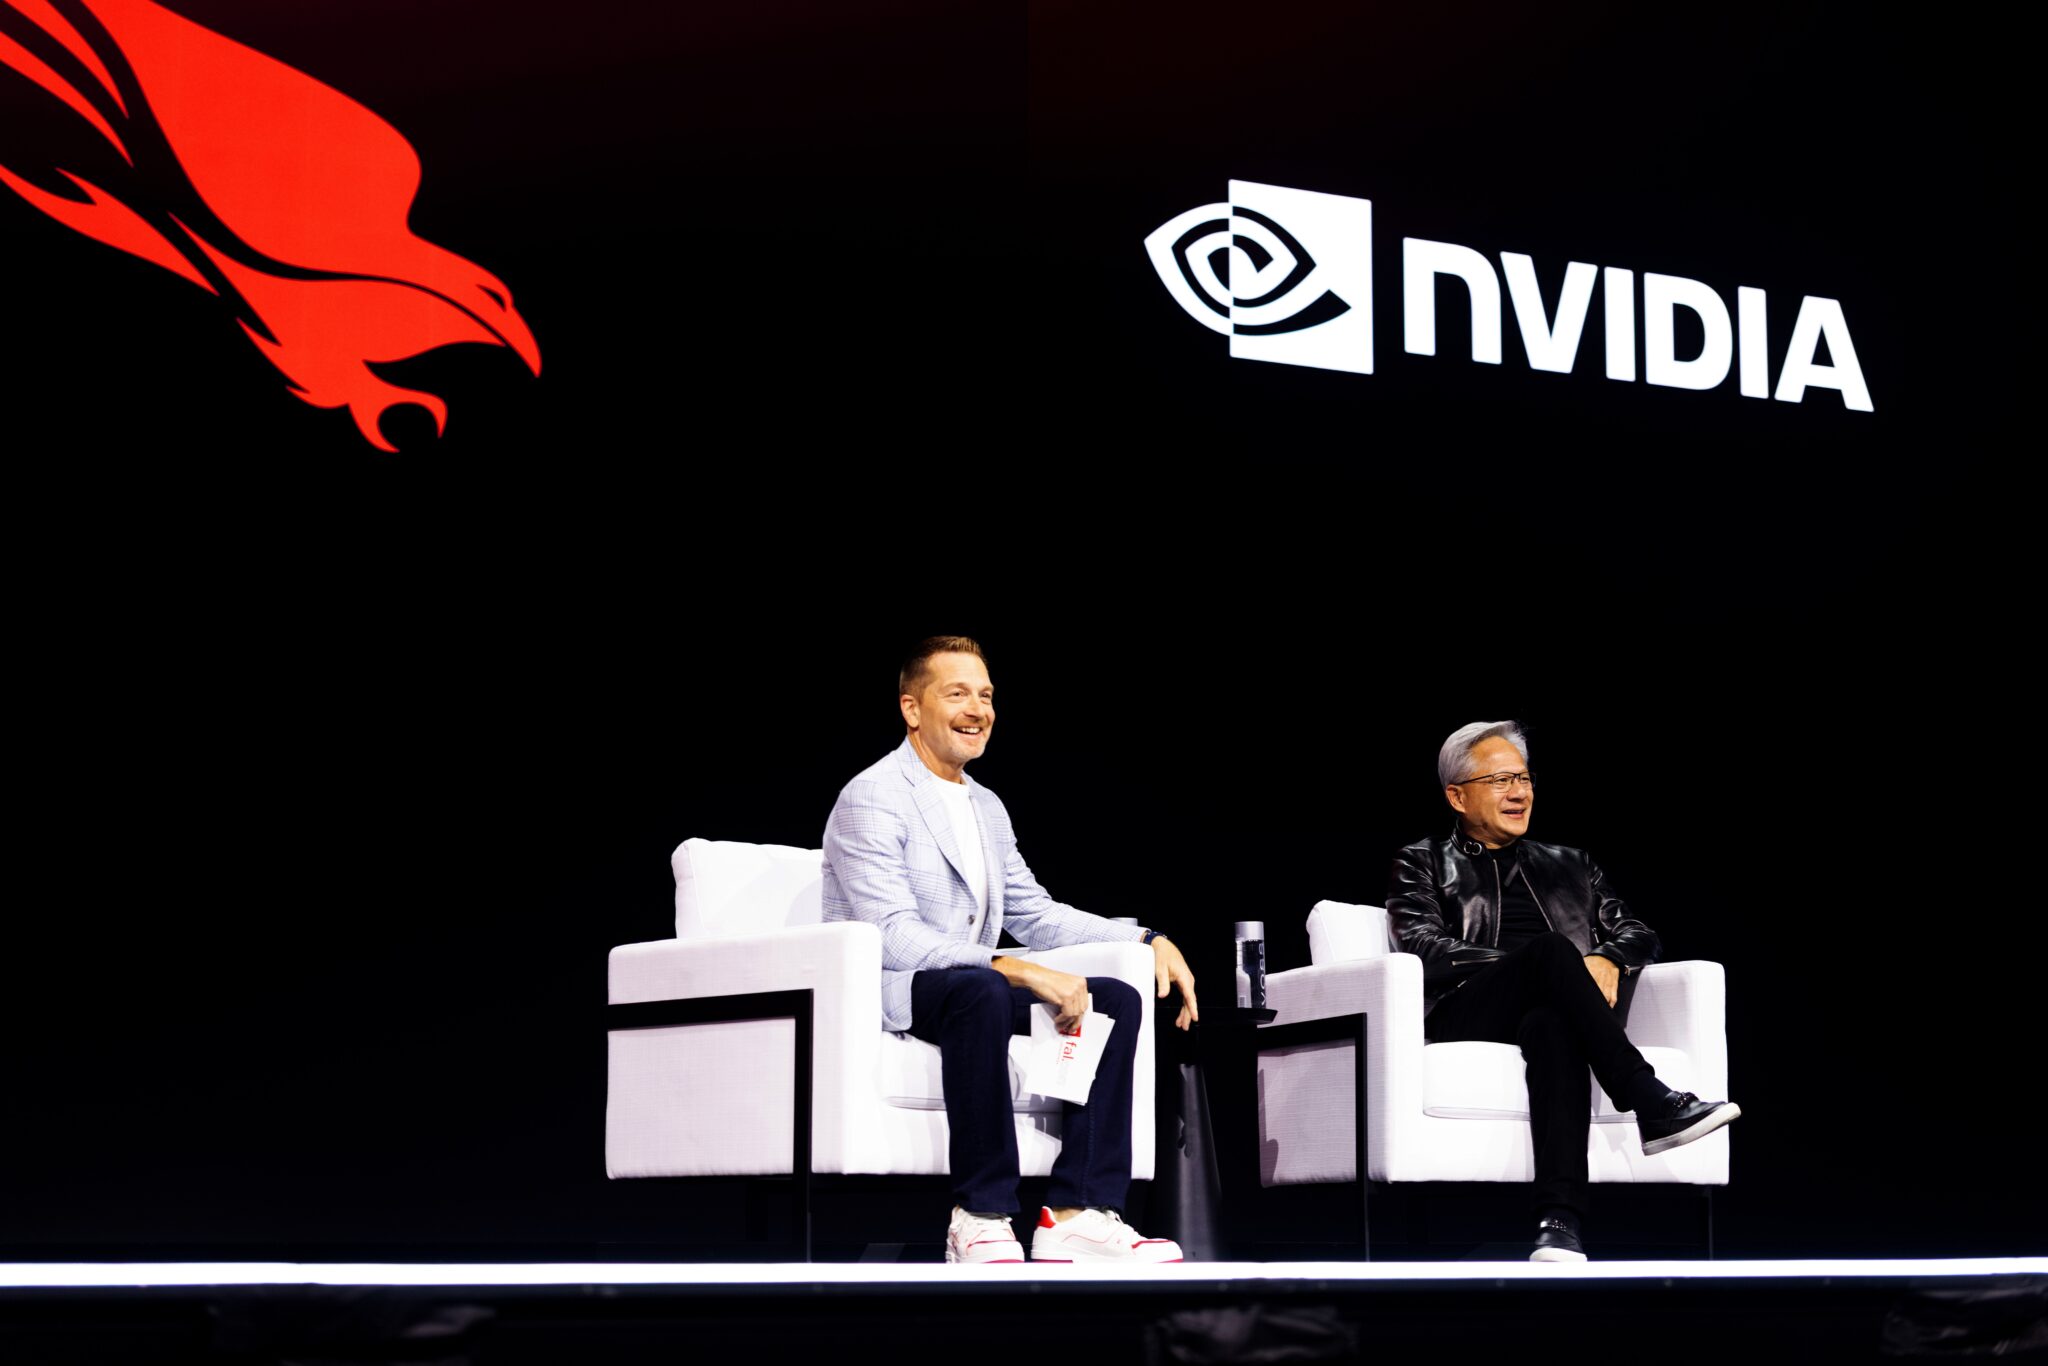
“We’re at an inflection point in cybersecurity,” Jensen Huang told a sold-out crowd at CrowdStrike’s Fal.Con 2026 in Las Vegas Tuesday. Attacks are now automated. Defense has to be, too. 

The NVIDIA founder and CEO joined CrowdStrike CEO and founder George Kurtz to announce CrowdStrike SafeMind, its agentic cybersecurity system developed by the CrowdStrike Cyber Superintelligence Lab.

“This is the beginning of a new age of cybersecurity,” Huang told the crowd of 10,000 security professionals. “On the one hand, the adversaries are going to be more armed than ever. On the other hand, all of you are going to be more armed than ever.” 

SafeMind combines CrowdStrike’s purpose-built, beyond frontier-capable models and customized agentic harnesses, with defensive models built on NVIDIA Nemotron, in a continuous coevolution loop where offense and defense repeatedly challenge and improve each other. 

CrowdStrike also announced CrowdStrike Falcon IQ to operationalize Project QuiltWorks through agentic workload automation and expanded its CrowdStrike Guardian AI safety solution.

“We have asymmetric advantages because we have a large community of cybersecurity experts who want to work with each other and keep the world safe,” Huang told the crowd. 

CrowdStrike’s annual conference drew security leaders from financial services, healthcare, the public sector and critical infrastructure.

“The real gap that I saw was that the attackers had frontier AI, and the defenders didn’t,” Kurtz told them. “And that changes now.”

SafeMind

CrowdStrike built SafeMind’s defensive model using NVIDIA Nemotron open models, post-trained with CrowdStrike’s cyber experience and threat data. The SafeMind models are paired with proprietary cybersecurity harnesses optimized to work as an agentic stack.

The result ships natively in the CrowdStrike Falcon platform as SafeMind, CrowdStrike’s agentic cybersecurity system. SafeMind brings offensive and defensive AI together in a continuous coevolution loop, where each side adapts to and strengthens the other. This process continuously hardens the security of the customer environment until attacks are unsuccessful.

“Your decade and a half of security data that we can train on — we can take a frontier model and make it essentially a super AGI that is incredibly good at cybersecurity,” Huang told Kurtz.

“Together with NVIDIA, we built cybersecurity’s first complete agentic system for cybersecurity, including the first frontier models and harness purpose-built for defenders,” Kurtz said. “This isn’t a copilot baked into someone else’s intelligence. It’s not a chatbot with a security skin. It is a frontier-class model built and trained by CrowdStrike on our data in partnership with NVIDIA.”

NVIDIA Nemotron 3 Ultra orchestrates the defensive agent harness. A fine-tuned Nemotron 3 Super powers SafeMind’s rule-generation sub-agent. 

By post-training Nemotron with CrowdStrike data, CrowdStrike internal evaluations showed that the Blue Solano model — based on Nemotron 3 Super — delivered higher accuracy rates than leading frontier models at 99% lower cost. 

While SafeMind can operate as a complete system, the models can be used independently to empower defenders to stay ahead of the adversary. Security experts can also pair their own models with CrowdStrike’s custom harnesses, giving customers the flexibility to use the right models and capabilities for their environment.

“The harness is essentially the exoskeleton of the large language model,” Huang said. “The large language model is the brain. The exoskeleton turns it into an agent — and this exoskeleton doesn’t have to be the same shape and capability for every domain.”

When AI Is the Defense

AI-enabled attacks rose 89% in the past year, and the fastest eCrime breakout time has reached 27 seconds, according to CrowdStrike. Human-speed response isn’t defense. It’s documentation.

“There are many applications in the world where you must have the ability to fine-tune, to post-train — to create an AI that is super good at a particular domain,” Huang said. “Nemotron was created for precisely that. Completely free. Incredibly fast. You have the ability to have an asymmetric advantage against whatever comes your way.”

With open Nemotron as the base, CrowdStrike’s security teams post-trained on their own threat data without sending it to an outside provider, and customized the AI to their environment. 

That’s not possible with a closed frontier model, and in security, the ability to inspect what’s defending matters. 

Red vs. Blue

NVIDIA announced its work testing the CrowdStrike SafeMind models and harnesses in a high-fidelity cyber agent environment running as a simulation of the NVIDIA network. 

The testing runs SafeMind in an offensive-defensive loop for adversarial coevolution. An offensive red-team agent finds the exploit, a blue-team defensive agent closes it and the findings become actionable detections to block attacks. 

The red-agent harness runs Recon, Assault and Compromise sub-agents executing attack paths inside the cyber agent environment. The blue-agent harness monitors via Falcon sensors, generates detection candidates, validates them and promotes them. 

CrowdStrike built the test environment with NVIDIA: a digital twin of NVIDIA’s own accelerated computing infrastructure, validated against NVIDIA’s real threat landscape.

“The basic framework of SafeMind — an adversarial model acting on a digital twin of the environment, with a defender model in a continuous cat-and-mouse loop, eventually learning how to secure itself — this basic framework applies to robotics, edge computing, enterprise computing and just about everything,” Huang said.

CrowdStrike also announced Falcon IQ. NVIDIA Nemotron models help to power the agentic engine at the heart of Charlotte AI AgentWorks, CrowdStrike’s no-code agent development platform where Falcon IQ runs. 

Falcon IQ uses more than 50 agents working together as a unified agentic workforce to automate the most time-intensive workflows in assessment, prioritization and remediation. 

Partners use Falcon IQ to deliver customized findings, recommendations and executive outputs to customers. Charlotte AI AgentWorks enables every Falcon user to build their own agentic security workforce.

The Full Stack

CrowdStrike has thousands of customer organizations generating trillions of daily security events. 

With NVIDIA’s full-stack accelerated computing platform, the collaboration runs from the chips up through the models to the harnesses acting on what those models find. For Kurtz, that’s the point. 

“The crowd in CrowdStrike,” Kurtz added, “is the asymmetry that puts the defenders in a unique position to defeat the adversary.”

Universitas Gadjah Mada, Indosat and NVIDIA Open Indonesia’s First University AI Center to Develop Local AI Talent


Indonesia is taking charge of its AI future.

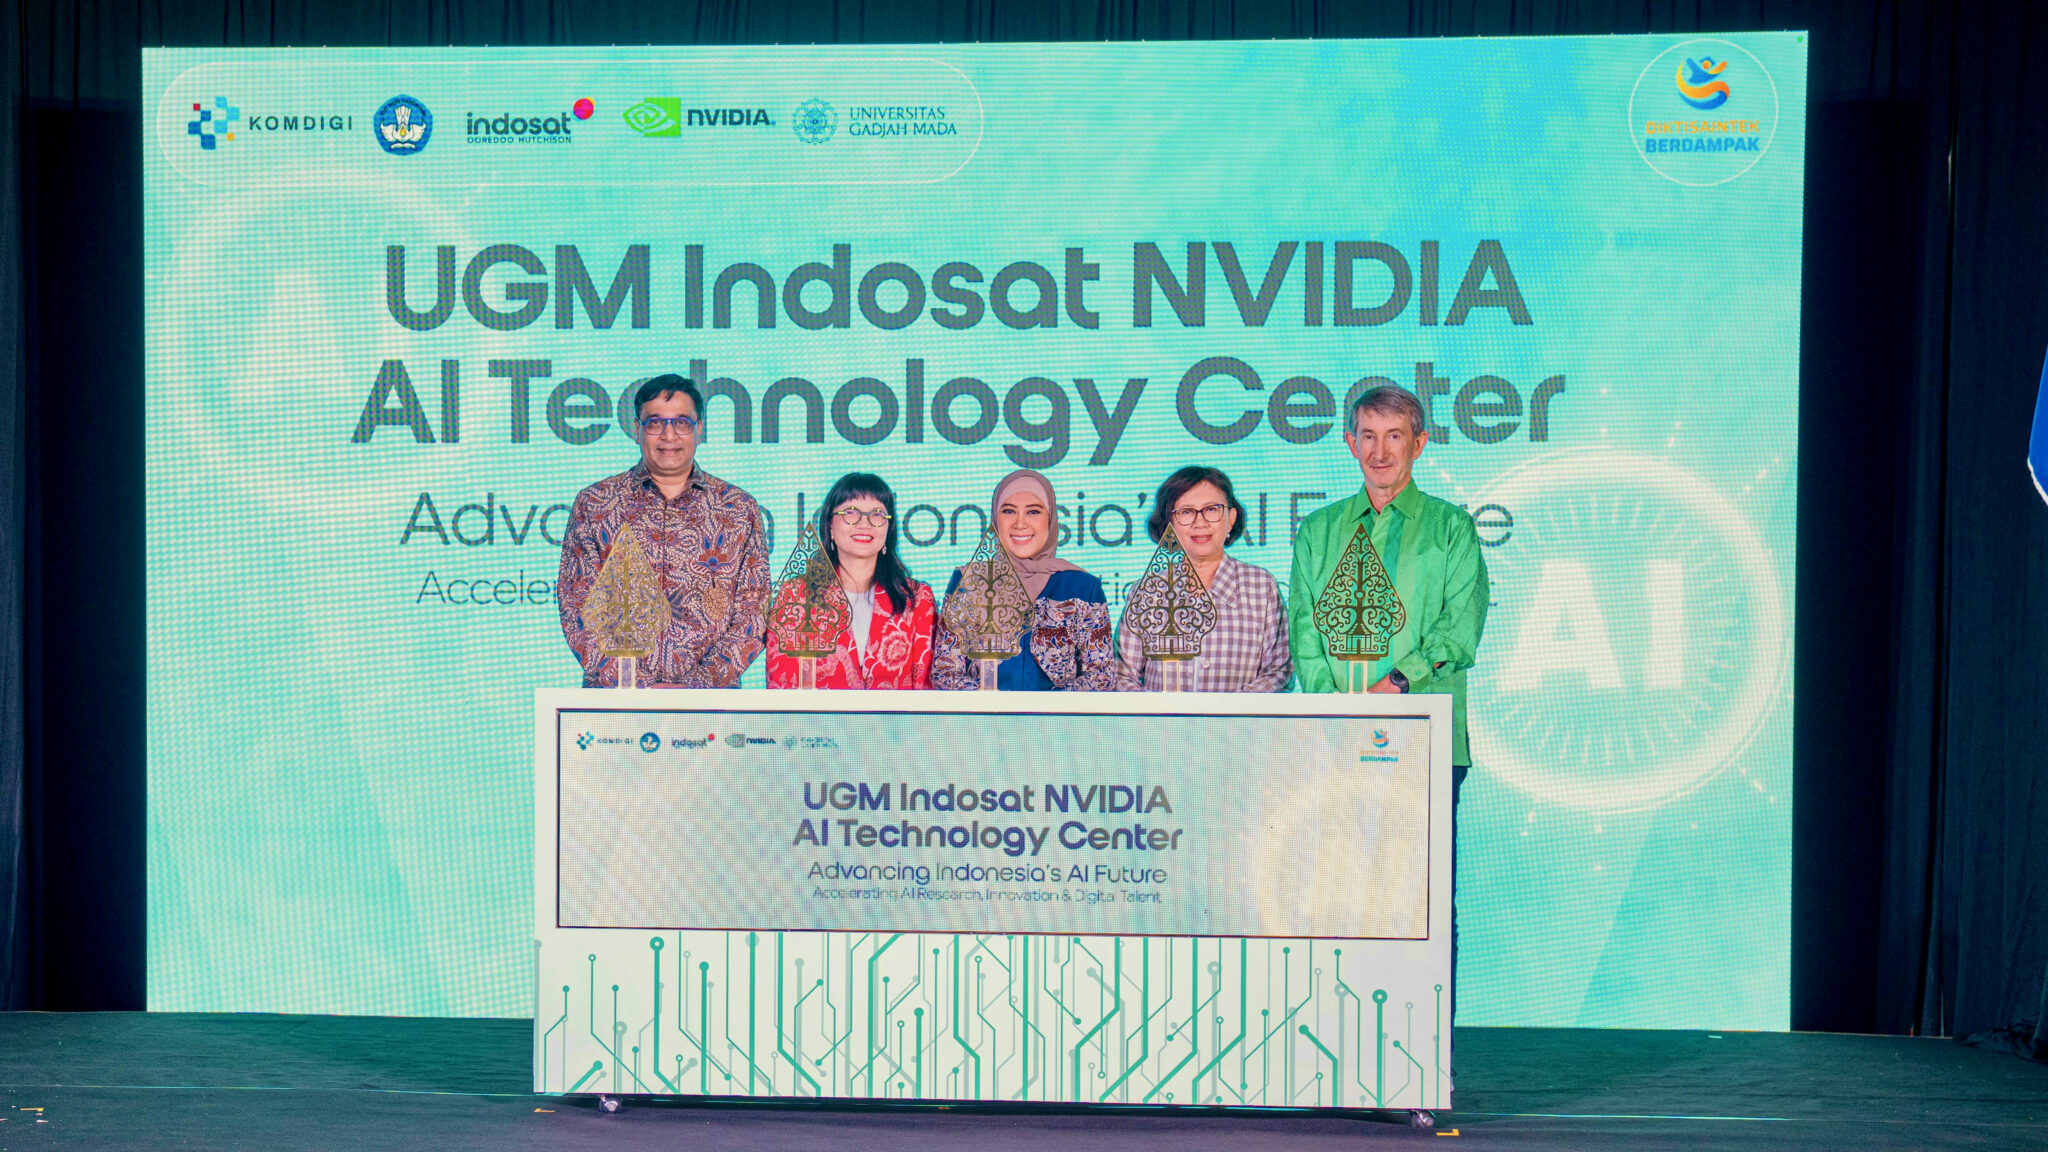
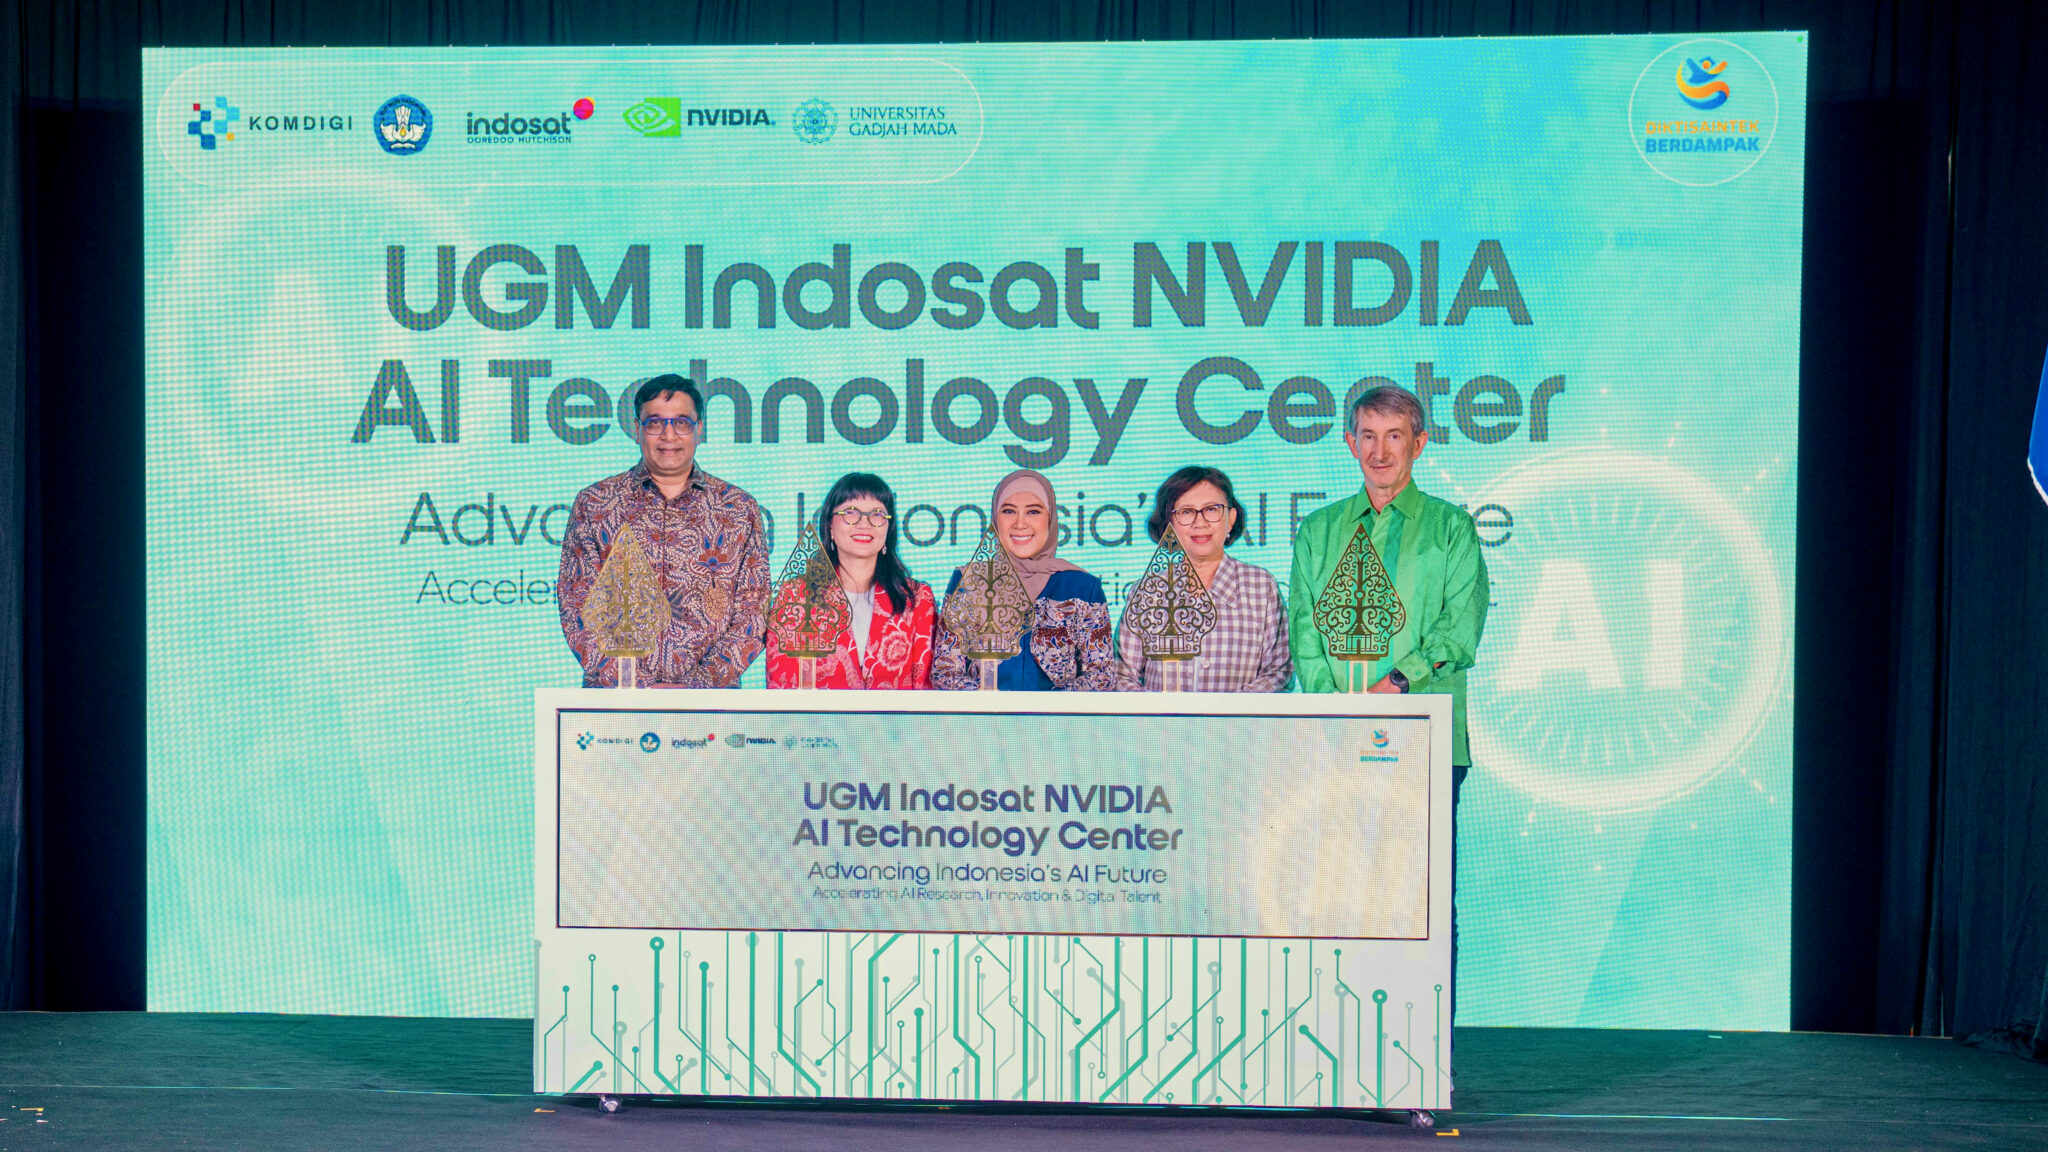
This week, the Ministry of Communication and Digital Affairs (Komdigi), Indosat Ooredoo Hutchison (Indosat or IOH), NVIDIA and Universitas Gadjah Mada (UGM) launched the UGM Indosat NVIDIA AI Technology Center (NVAITC) in Yogyakarta — the country’s first university-based AI technology center. Established under Indonesia’s AI Center of Excellence initiative, UGM Indosat NVAITC brings government, industry and academia together to develop AI that addresses Indonesia’s most urgent national priorities.

“The Indonesia AI Center of Excellence reflects our long-term vision to position Indonesia as a nation that not only adopts AI but also develops and contributes AI innovations to the world,” said Meutya Hafid, Indonesia’s Minister of Communication and Digital Affairs. “Through initiatives like this, we are laying the foundations of Indonesia’s AI sovereignty and ensuring AI becomes a driver of economic growth, national competitiveness and solutions to Indonesia’s most pressing challenges.”

“UGM is committed to supporting Indonesia’s AI ambitions through education, research, and innovation that deliver real societal impact,” said Prof. dr. Ova Emilia, Ph.D. “This initiative supports national priorities in higher education, research downstreaming and talent development by accelerating the adoption of AI and preparing future-ready Indonesian talent.”

Compute That Belongs to the Country

Powered by NVIDIA’s full-stack AI platform and GPU Merdeka — Indosat’s sovereign GPU-as-a-service platform — UGM Indosat NVAITC gives UGM’s researchers and students access to enterprise-grade accelerated computing, AI software, open source, pretrained models, development frameworks and technical mentorship. It also connects Indonesian researchers to a worldwide ecosystem of expertise.

“At Indosat, we believe no Indonesian should be left behind in the AI era,” said Vikram Sinha, president director and CEO of Indosat Ooredoo Hutchison. “Through UGM Indosat NVAITC, we are bringing the best of global AI technologies and expertise to Indonesia, while expanding access for the ecosystem of researchers, students, startups, and innovators across the country. By strengthening AI readiness and empowering Indonesian talent, we aim to support the government’s vision for AI and help position Indonesia not only as a user of AI technologies, but as a nation that develops and contributes AI innovations to the world.”

The opportunity is real. Indonesia is the world’s fourth-most populous country, with researchers and developers working on problems of scale and urgency. What they’ve historically lacked is access to the compute, models and infrastructure to move from insight to impact.

“Indonesia is home to an extraordinary community of researchers, developers and innovators with the potential to shape the future of AI,” said Marc Hamilton, vice president of solutions architecture and engineering at NVIDIA. “From healthcare and agriculture to disaster preparedness, the opportunities for AI to drive real change are immense. Through UGM Indosat NVIDIA AI Technology Center, NVIDIA is committed to equipping Indonesian talent with NVIDIA Nemotron open models and expertise to turn that potential into innovation with local and global impact.”

AI for Indonesian Challenges

Three initial projects define what this center is for, focused on healthcare, agriculture and natural disaster response.

Indonesia records over 1 million new tuberculosis (TB) cases every year. TB is curable — but it kills when it goes undetected. Detection in rural and underserved areas has depended on equipment and expertise unavailable at the community level. UGM’s Faculty of Medicine Public Health and Nursing team, led by dr. Dian Kesumapramudya Nurputra, M.Sc, Ph.D, SpA , is developing an AI-powered electronic screening technology — eNose-TB — that screens for TB by analyzing breath samples. The goal: affordable, fast, accessible screening that reaches patients in remote clinics and villages — no specialist or expensive lab required. 

“As researchers, we have always believed that technology developed in Indonesia can solve Indonesian challenges,” said Dian. “Through the center, access to world-class AI infrastructure and expertise will help us accelerate our research and bring us closer to our dream of developing affordable and accessible healthcare technologies that can improve lives across Indonesia.”

Agriculture employs nearly 30% of Indonesia’s workforce. SmartAgri uses multimodal AI — combining satellite imagery, sensor data and local agricultural knowledge — alongside edge computing to deliver precision farming for Indonesian terrain, crops and smallholders. These AI-powered recommendations help farmers know exactly when and how to irrigate, delivering impact that compounds over time.

Indonesia sits on the Pacific Ring of Fire, facing more natural disaster risk than almost anywhere on earth. Tech4Disaster is building a geospatial AI platform using NVIDIA accelerated computing to process satellite and sensor data at speed — giving communities and emergency responders earlier warning, better situational awareness and faster coordination tools when disaster strikes.

Learn more about the UGM Indosat NVIDIA AI Technology Center.

Tech Visionary Says the Big AI Labs Don’t Get What People Want


Tim O’Reilly’s yardstick for measuring the worth of a company, person, or society has long been create more value than you capture. It’s no surprise that O’Reilly—publisher, internet pioneer, VC, conference organizer, and dispenser of tech wisdom—is applying that metric to the way people design and use AI. Specifically, he’s pushing for a future where open-source AI is an elixir for the masses. He worries that, like Microsoft in the 1990s, today’s hyperscalers are trying to lock users into their products. So he is promoting efforts to open-source AI technology—not only making critical technical details such as neural-net weights accessible, but unlocking the whole stack of an AI system, giving control to designers and users.

O’Reilly sees AI as a new creative medium, which he uses extensively—and even has a blog about his chats with it. During our conversation, we discovered that we disagree about AI’s role in producing original content. Guess who took which side.

STEVEN LEVY: You are all in on open-source AI. Make your case.

TIM O’REILLY: First, let’s make sure we’re talking about the same thing. When most people talk about open-source AI, they’re really just talking about open-weight models. It’s much bigger than that. In the ’90s, when everybody else was focused on open-source licenses, I was like, “No, no, it’s about the architecture of the system. Does it enable participation?”

Why is that needed?

The big labs are reading the future wrong. They have told themselves a narrative where having the biggest, best model is the key to the future. Big models like Claude are optimizing for particular use cases, but they aren’t necessarily the use cases that people want. I want to embed my own special sauce. The most important thing is having a clean separation between the model, the harness, and the application. And right now we’re not getting that. They built an architecture of control rather than an architecture of freedom and participation, so they have the ability to track you.

Isn’t it against the interests of big companies to give up control?

Oh, it’s totally against their interests. But that doesn’t mean that they’re making the right strategic decision. For a long time, the latest and greatest models were really better for everything. Now they’re better for some things and worse for others. People are talking a lot about how Fable and Sol are worse writers than the lower-level models. [Note: Anthropic and OpenAI would disagree.] The breakthroughs that we’re getting in so-called frontier AI are actually pushing us further away from what ordinary people are going to need. We could win frontier AI here in the US, and China will kick our ass because they have lower-level models diffused widely through society. The goal is to give people the ability to innovate freely, to paint outside the lines.

People worry that open-source software can be a security risk, since bad actors will be able to jump the frontier model’s guardrails.

All of the cybersecurity incidents we’ve seen are from the frontier models. So risks like cybersecurity and the ability to develop pathogens are actually an argument for slowing down the frontier models more than an argument for restricting open-weight models.

So you feel that with open source the AI powers will no longer be dominant?

I don’t predict the future. but I will say the world is proceeding the way that I hoped it would. What if the big frontier models end up like mainframes or supercomputers—aimed at really hard problems, which are not actually the thing that gets diffused throughout society? People are building things like Pi, an open-source [agentic] harness. One of the things we’re working on at my nonprofit, the AI Disclosures Project, is the idea of an open-memory consortium. Mark Zuckerberg’s thesis is, he’s going to lock you in because Meta will give you the AI that knows you best. The open-source vision needs to say no to this. Open source can give you the ability to switch models, switch providers, and maintain all the context that it needs.

NVIDIA Open Sources First GPU-Accelerated Medical Physics Simulation Framework


Before a healthcare robot can be useful in the real world, it has to learn how the physical world pushes back. Anatomy varies. Instruments bend, press, slip and interact with tissue. Imaging can be noisy or incomplete. And the rare, edge scenarios developers most need to understand don’t appear on schedule.

That creates one of the biggest bottlenecks in healthcare robotics: obtaining the enormous amount of varied data developers need to train, test and improve robot behavior.  

NVIDIA Medical Physics Simulation framework — a new open source, GPU-accelerated capability within NVIDIA Isaac for Healthcare — announced today, helps medical robotics developers model anatomy-device interaction, generate hard-to-capture scenarios, test in silico, and train or evaluate robot policies before hardware-heavy testing. 

The framework brings together anatomy and medical device behavior with sensor simulation and robot learning so teams can create reusable simulation environments instead of rebuilding custom scenes for every workflow, saving developers time and bringing innovations to market faster. 

Because Medical Physics Simulation is open source, healthcare robotics developers can inspect the framework, adapt it to their own devices and workflows, and build on a GPU-accelerated foundation that works seamlessly with the broader NVIDIA stack.

Open source is especially important in healthcare because teams need transparency into the data, models and weights that shape system behavior. Access to open models and model weights can help developers reproduce results, evaluate performance across different anatomies and scenarios, identify limitations and build evidence for regulatory review. 

A Virtual Training Ground for Medical Robots

For physical AI, experience is data in motion. Developers need to train robots to operate properly even when anatomy changes, devices behave differently, conditions shift or a policy fails unexpectedly.

Medical Physics Simulation helps developers simulate anatomy, device contact, friction and sensor inputs, then test in interactions and environments to evaluate how robots perform across those changes. Powered by NVIDIA CUDA and part of Isaac for Healthcare — built on the NVIDIA Warp, Newton and Cosmos simulation and generative AI technologies — the framework can run hundreds of parallel simulation environments, helping teams explore more scenarios and identify failure modes earlier in development. 

For robot builders, this turns simulation from a bespoke engineering project into reusable infrastructure. The difference now is scale: benchmarks show 8,192 robot-training environments running in parallel with GPU-native simulation cut training from over five hours to under two minutes. 

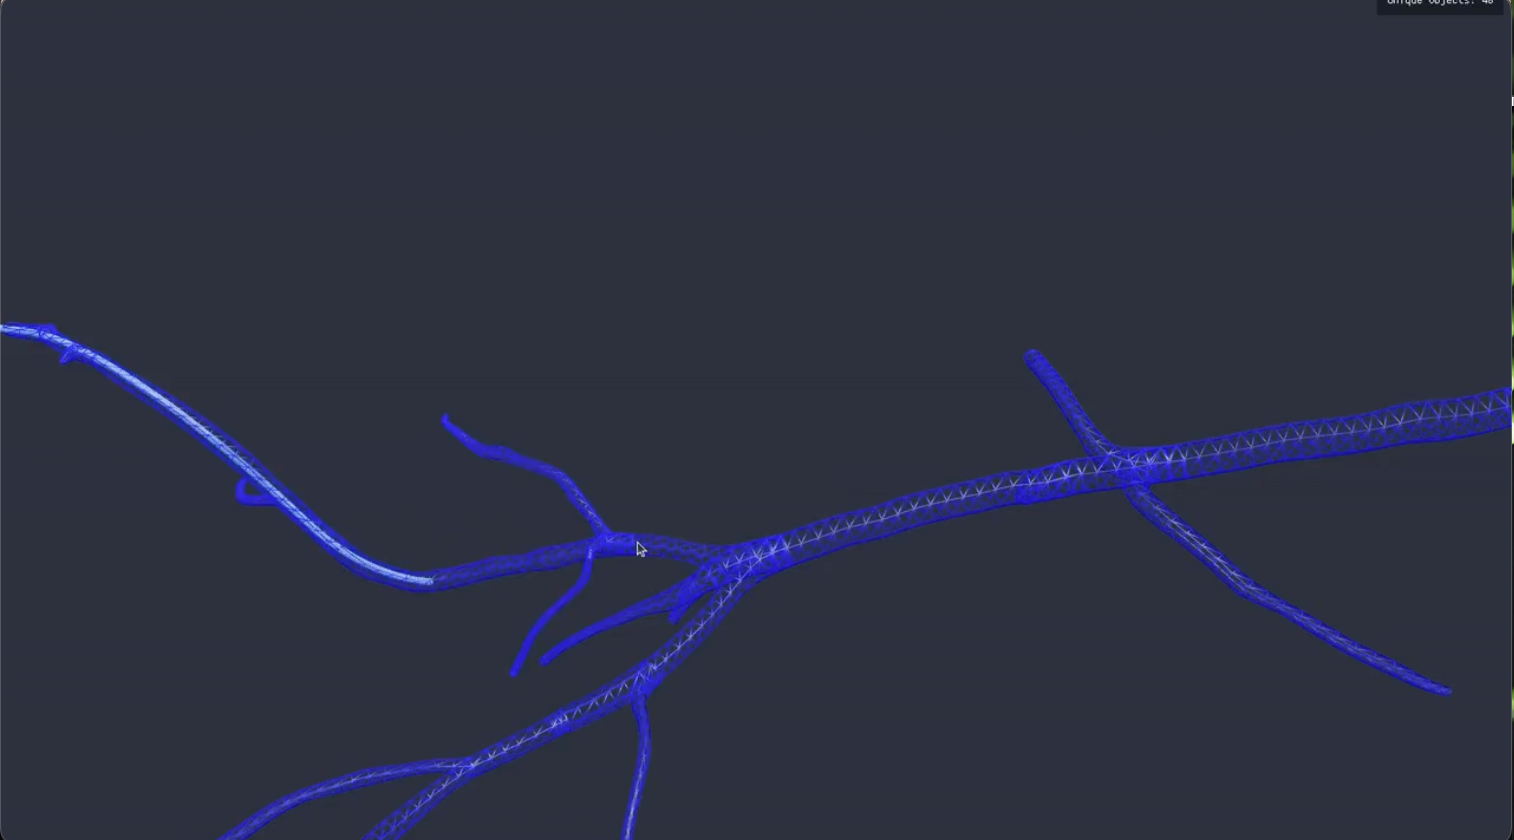
With this framework, developers can connect vascular anatomy, flexible instruments such as catheters and guidewires, simulated X-ray imaging and reinforcement learning. The framework is designed to extend beyond that example to additional devices, anatomies, sensors and healthcare robotics domains.

Medical Physics Simulation brings together classical physics simulation and generative AI physics simulation. Classical simulation helps model known physical rules, such as device contact, friction and motion. NVIDIA Cosmos-H Dreams, the real-time generative AI physics simulation capability within Medical Physics Simulation, helps model visual scene dynamics learned from procedural data.

Together, these approaches give developers a richer way to build and test healthcare robotics systems in virtual environments before moving to physical prototypes and lab testing.

An Ecosystem Building the Future of Medical Robotics

Medical robotics leaders are already applying simulation-driven development to solve specific surgical challenges.

CMR Surgical and Cambridge Consultants, part of Capgemini, are using Cosmos-H-Dreams to implicitly learn interaction physics for soft-tissue surgical procedures and generate patient-specific simulations. CMR contributed nearly 500 hours of anonymized clinical data from its Versius Surgical Robotic System to the Open-H Embodiment open dataset, benefiting procedures including cholecystectomy, prostatectomy, hernia repair and hysterectomy.

“Open source models allow us to build on shared knowledge, accelerating responsible innovation and, ultimately, gives us the potential to deliver more consistent care and better outcomes for patients worldwide,” said Chris Fryer, chief technology officer at CMR Surgical.

Johnson & Johnson MedTech is using Isaac for Healthcare’s Medical Physics Simulation and a Cosmos-based foundation model to build digital twins of its endoluminal MONARCH platform for urology, modeling complex anatomy and kidney-stone scenarios.

XCath is using the Medical Physics Simulation for endovascular autonomy policy training. Inner Logic is accelerating the evolution of medical technology with synthetic data, validating device mechanics and producing in silico evidence to support regulatory pathways with NVIDIA Medical Physical Simulation.

Medtronic Structural Heart is exploring applying Medical Physics Simulation with simulated X-ray sensing to generate data for catheter navigation research.

A New Layer in the Isaac for Healthcare Stack

As a modular capability within NVIDIA Isaac for Healthcare, Medical Physics Simulation can be used on its own or alongside digital twin pipelines, medical sensor simulation, the NVIDIA Isaac Lab open robot-learning framework and NVIDIA open models and policies.

Developers can explore the open source Medical Physics Simulation framework, review available reference workflows and start building simulation environments for their own devices, anatomies and healthcare robotics applications.