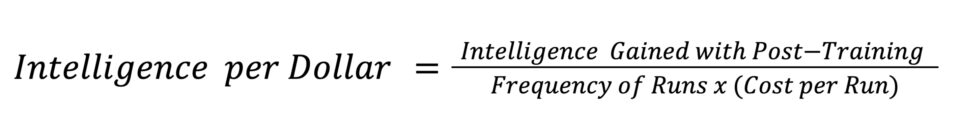
Skild AI Taps NVIDIA Physical AI to Teach Robots New Tasks From a Single Video


Manufacturing floors, warehouses and production lines rarely stay fixed — tasks change, layouts shift and new products arrive, and most robots can’t keep up without significant reprogramming.

Skild AI’s new S1 robot foundation model helps address this, designed to learn previously unseen, long-horizon tasks from a single video demonstration. The model, launched last week, uses video as input to understand and execute the task without updating its weights or undergoing task-specific post-training — a technique called in-context learning.  

Skild built S1 and conducted the research on NVIDIA AI infrastructure, part of a broader collaboration spanning synthetic data generation, model training, simulation and real-world physical AI deployment. The companies are working together to move adaptable robot intelligence from the lab into factories and other dynamic operating environments.

“Learning by experience, and not preprogramming, is the step change that has happened in robotics,” said Deepak Pathak, cofounder and CEO of Skild AI. “NVIDIA Isaac Lab and NVIDIA Cosmos technologies help Skild create the scalable, diverse experience its robots need to learn across many scenarios and embodiments.”

The launch comes as the company reached a $100 million annual revenue run rate 10 months after its first commercial deployment. In that time, Skild has built more than 60 deployment partnerships with work spanning manufacturing, logistics, inspection, security, food preparation and other applications. 

Learning New Work From One Video

Most industrial robots are built for fixed jobs, so each new product, process or layout requires more data, retraining and validation.

S1 takes a different approach: An operator records a video of the desired task and provides it to the model as a prompt. It interprets the demonstrated intent, objects and sequence, then maps them into actions for the robot in front of it — with no retraining — and often for a task not covered by its pretraining dataset. 

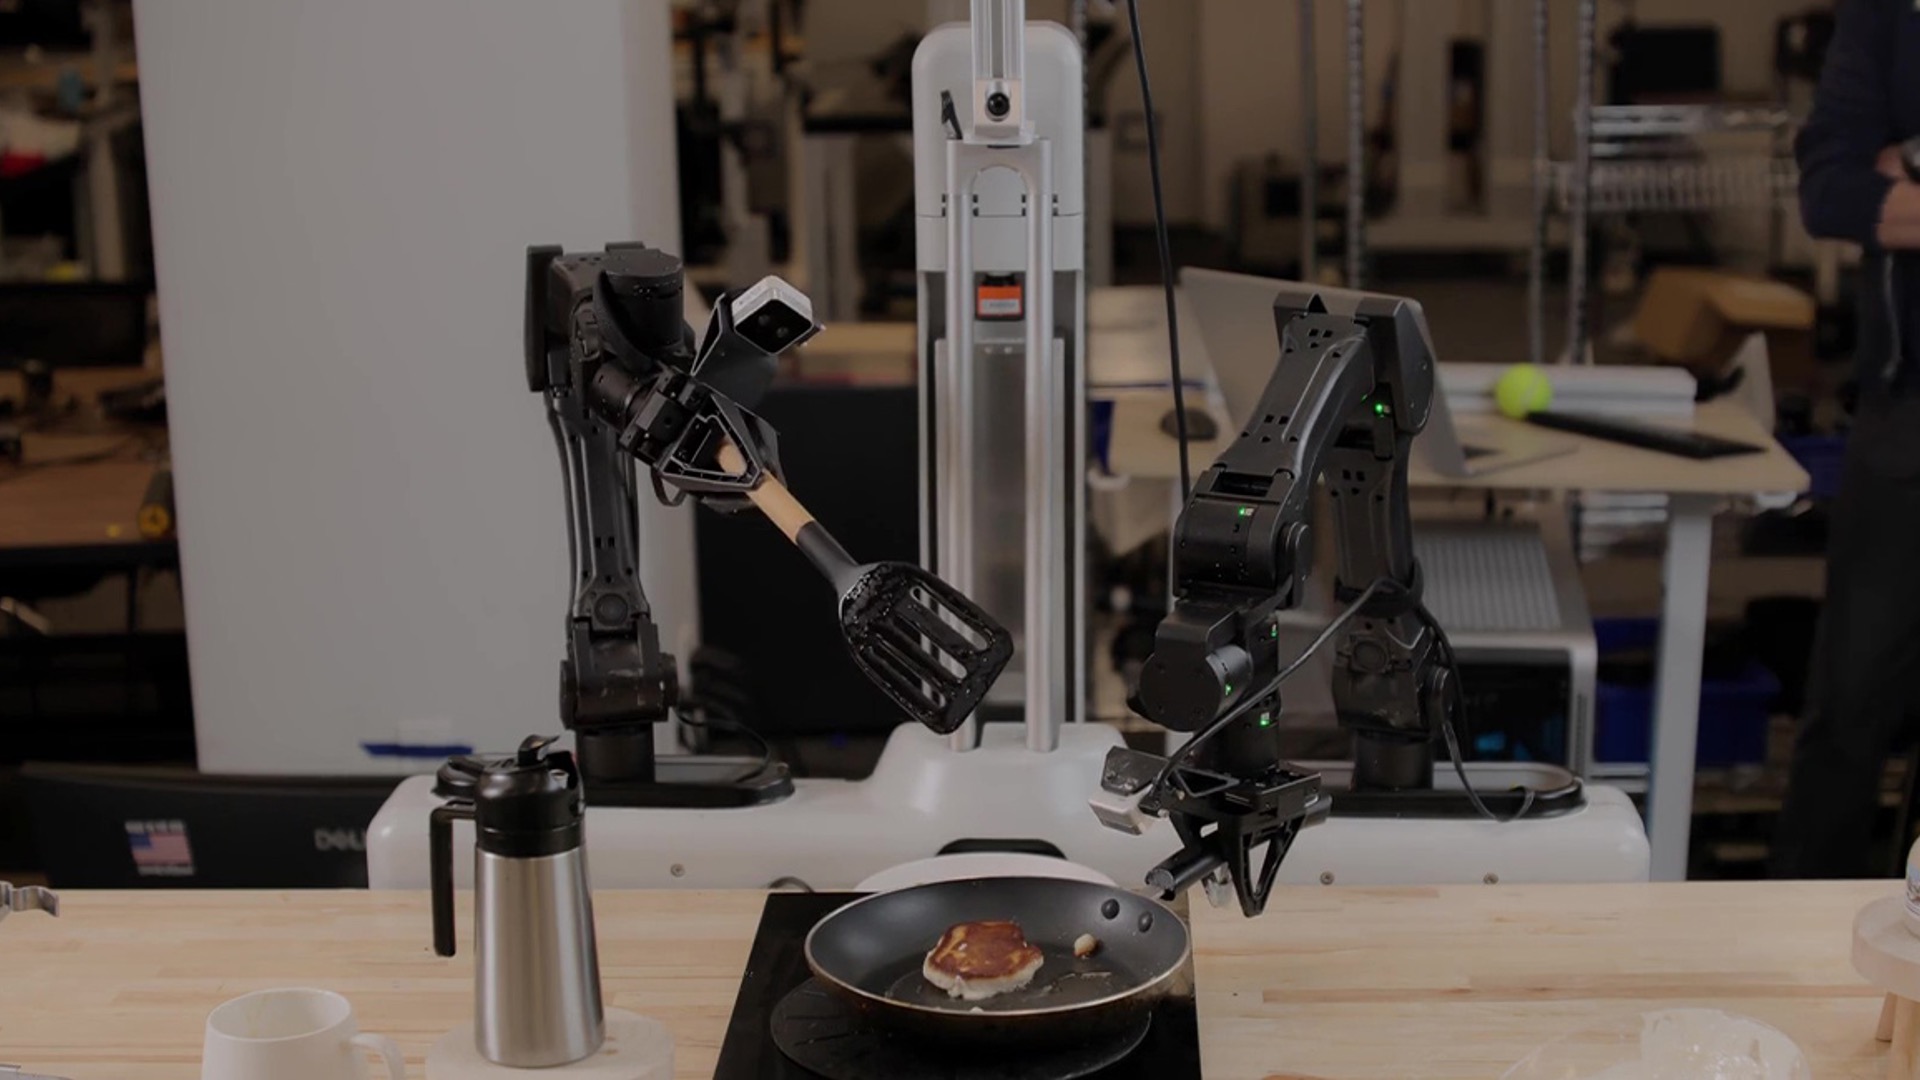
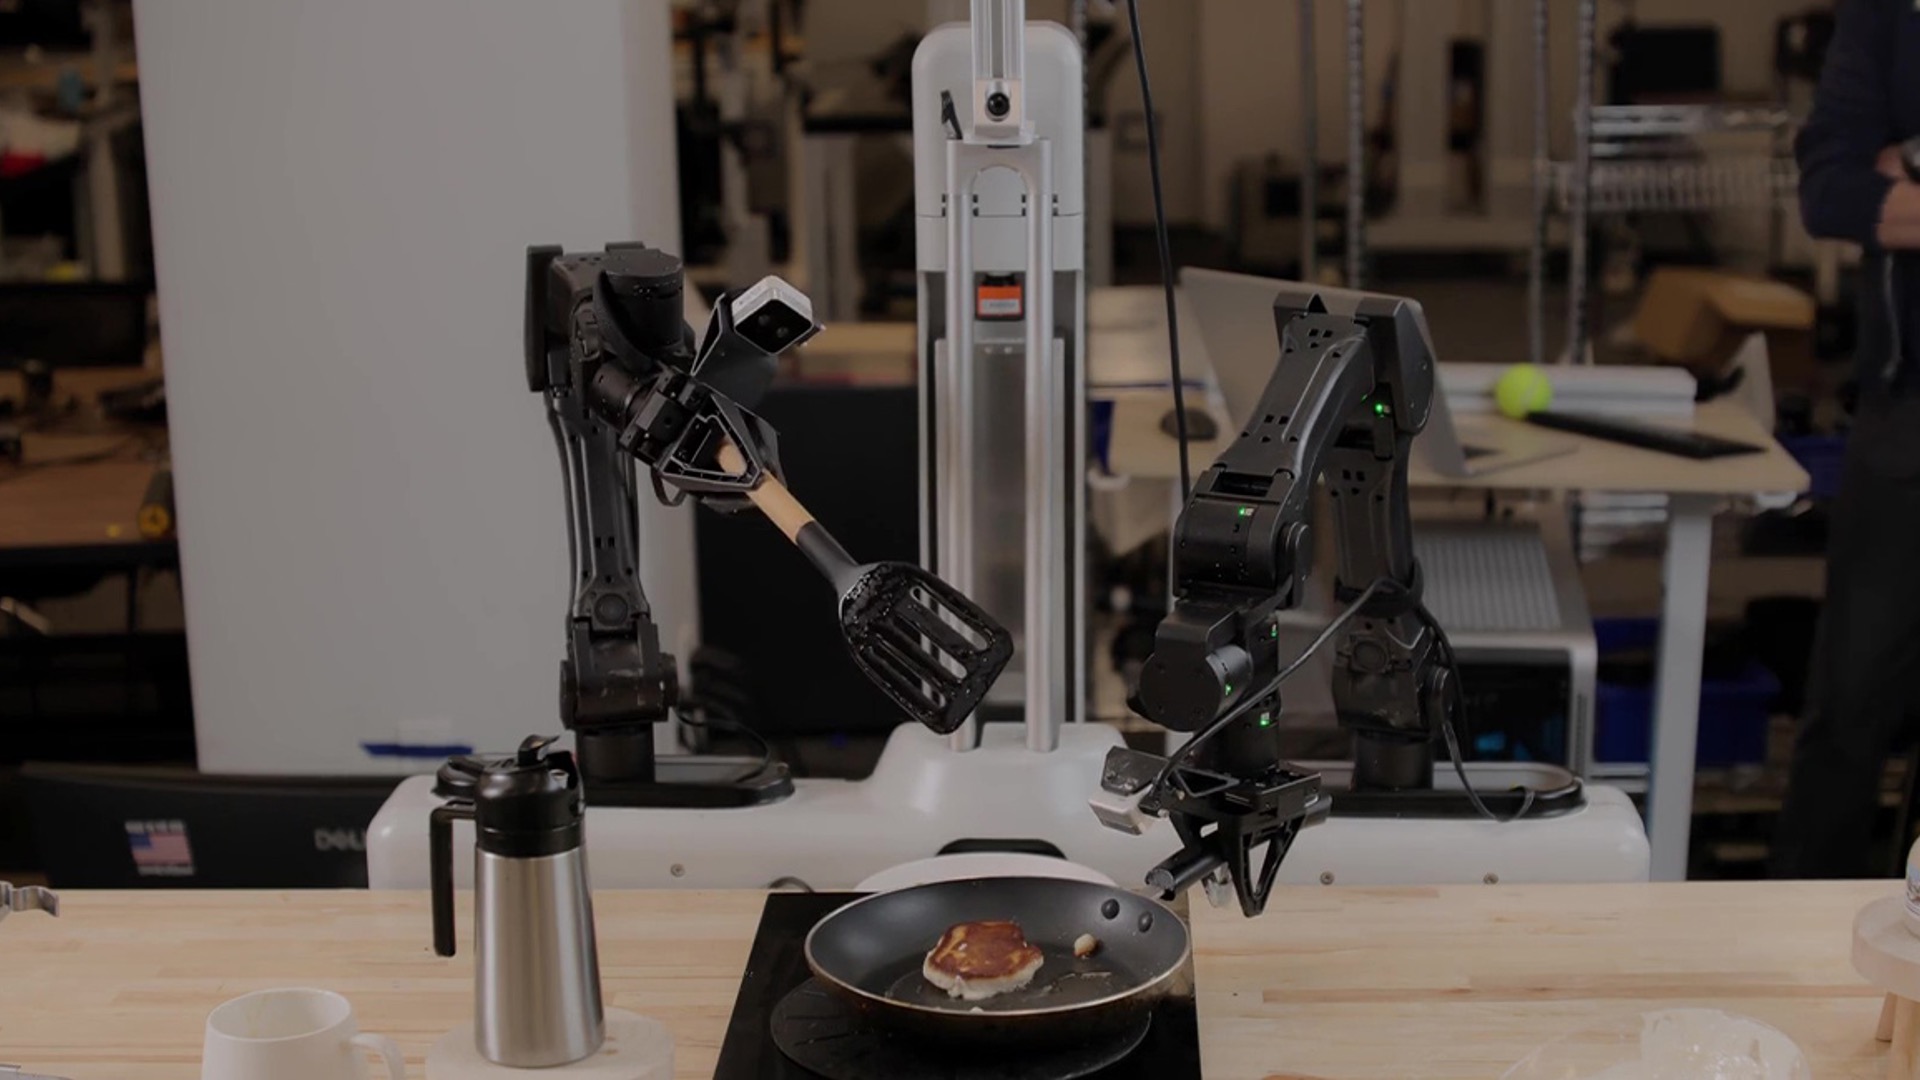
S1 can perform unfamiliar tasks lasting up to 10 minutes, including plant potting, pancake making, pour-over coffee brewing and kit assembly. These tasks can span dozens of manipulation steps and require the robot to compose skills in sequences it hasn’t previously performed. 


In one plant-potting test, the Skild AI team moved from recording the demonstration to autonomous execution on hardware in just 11 minutes. The model can also adjust when objects move, recover from errors and combine skills in sequences that weren’t explicitly programmed.

In Skild’s tests on new, multistep tasks, its S1 robot succeeded about 66% of the time at each step, compared with 9% for a similar AI system — a more than sevenfold improvement. Skild also estimates that showing the robot one short video example can be as useful as giving it roughly 380 hands-on training examples. A person collecting those examples manually could take 50-100 hours.

From Research to Factory Work

S1 breaks the cycle of needing to constantly retrain robots for new factors by letting operators demonstrate new tasks directly without requiring a new dataset or training run for every change. Where customer agreements permit, experience from Skild’s commercial deployments can inform the broader model and help accelerate future deployments.

That work is already in action on the factory floor. Skild, NVIDIA and Foxconn are deploying the Skild Brain on dual-arm manipulators for high-precision assembly of NVIDIA Blackwell systems. In one demonstrated workflow, a robot installs a busbar and limit block, fastens 16 screws and adapts to disturbances across a multistep task. The work requires precise motion, contact-aware control, sequence tracking and recovery when the scene differs from the plan.


NVIDIA Technology Across the Development Cycle

NVIDIA accelerated computing gives Skild the scale to train its shared robot brain using simulation, human video, teleoperation and, where permitted, deployment data. NVIDIA Cosmos open world foundation models help diversify training data and turn video into structured descriptions, while Cosmos Curator helps annotate, filter and organize data at scale.

Skild is extensively using NVIDIA’s open simulation frameworks to train and validate its robot brain before real-world deployment. NVIDIA Omniverse libraries and the NVIDIA Isaac Sim framework provide physically based virtual environments for generating data, testing edge cases and validating behaviors.

Skild further strengthens the skills of its brain through reinforcement learning in Isaac Lab, an open modular robot learning framework. Powered by the Newton physics engine, Isaac Lab helps Skild’s engineers accurately model various physical parameters, such as forces, contact, collision and pressure, and reduce the simulation-to-reality gap.

Skild and NVIDIA are also jointly developing new GPU-accelerated simulation solvers that quickly and accurately model how robots physically touch, grip and manipulate solid objects. They’ll soon be made available to all developers as part of Newton. 

As models move toward production, NVIDIA Nsight tools help engineers find performance bottlenecks during training, and the NVIDIA TensorRT software development kit optimizes inference so robots can respond quickly in the physical world. Together, these technologies connect the data, simulation, training and deployment stages instead of treating them as separate systems.

Read Skild AI’s S1 research and explore the NVIDIA Isaac robotics platform.
Firebird Launches CIS Region’s Largest AI Factory in Armenia


The global buildout of AI infrastructure reached a new milestone today — Firebird, an emerging AI cloud, launched the CIS region’s largest AI factory in Armenia, establishing a new AI computing hub powered by NVIDIA accelerated computing and Dell Technologies high-performance AI infrastructure

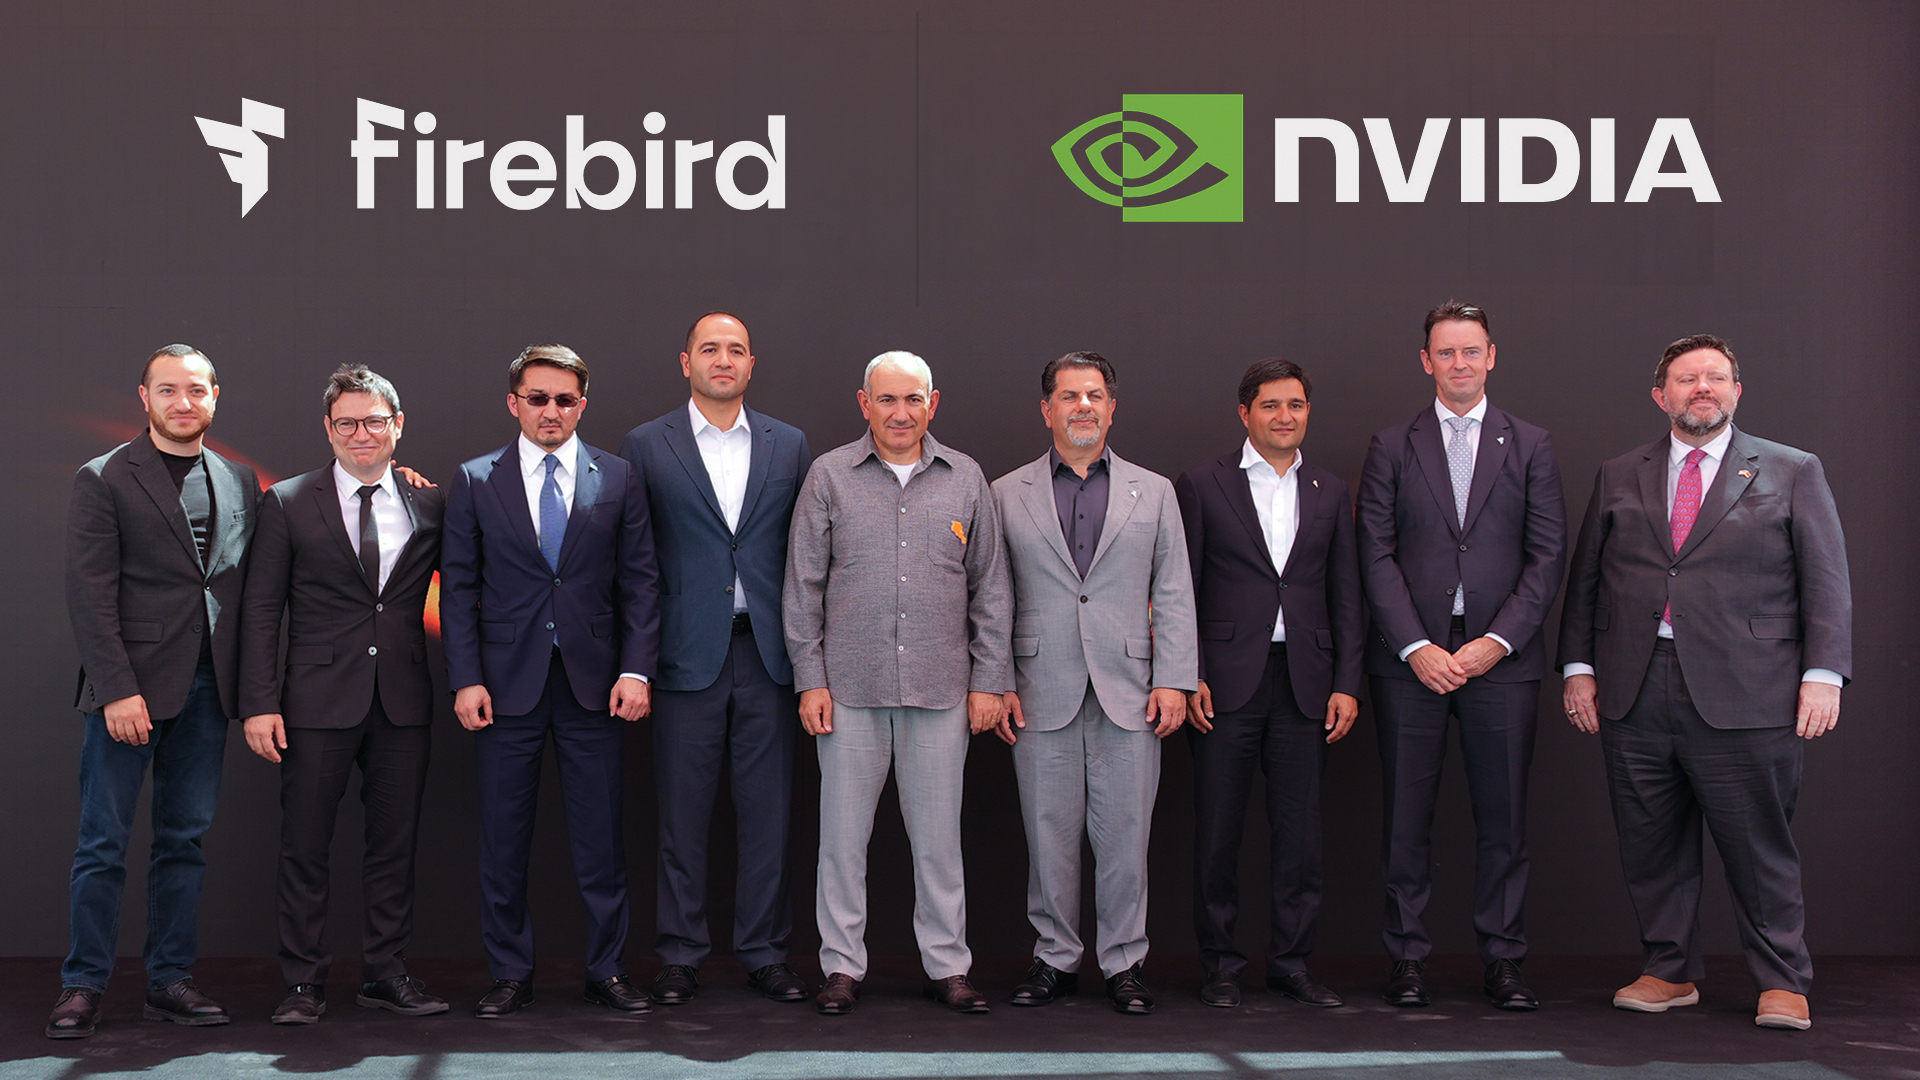
Nikol Pashinyan, prime minister of the Republic of Armenia; Zhaslan Madiyev, deputy prime minister of the Republic of Kazakhstan; and David Allen, U.S. chargé d`affaires, a.i. in Armenia, attended the AI factory opening ceremony. 

AI factories are the foundational infrastructure for the AI era, providing the computing capacity needed to train, fine-tune and deploy AI models for every domain at scale.

Building the Infrastructure to Create Intelligence at Home

While AI services are available globally, countries also need the capacity to develop and run AI for their own languages, industries and national priorities. Firebird’s AI factory brings that capacity to Armenia, giving developers, startups, enterprises, universities and public institutions the compute to build and scale AI at home.

Firebird plans to deploy more than 70,000 NVIDIA Rubin and Blackwell GPUs and 300 megawatts of AI infrastructure capacity in Armenia by the end of 2027, accelerating the country’s development as a center for AI research, advanced computing and innovation. 

“Our ambition for what we are building in the next 2 years or so is roughly 2 gigawatts of capacity around the world. We’re very focused on merging into frontier markets,” said Alexander Yesayan, co-founder of Firebird.

At this scale, energy efficiency is essential. Built on the NVIDIA DSX platform, this AI factory integrates accelerated computing, networking, power and cooling as one codesigned system. Firebird’s AI factory is designed from the ground up to turn compute into revenue. With DSX, it can run up to 40% more GPUs on the same footprint, producing more tokens per dollar and extracting more value from every megawatt of capacity.

A Magnet for Global AI, a Catalyst for Local Innovation

Firebird’s ambitions extend beyond a single site. With NVIDIA’s support, the company is pursuing an approximately 2-gigawatt AI infrastructure roadmap spanning Armenia, Kazakhstan and additional markets. 

Firebird also announced that NVIDIA intends to invest in the company, following an earlier investment by CoreWeave this year. These investments will help Firebird expand its global infrastructure and operational footprint, and support its efforts to establish the largest and most advanced compute clusters across frontier markets.

Delivered in just over six months, the Armenia AI factory demonstrates Firebird’s ability to turn ambitious infrastructure plans into operational AI capacity with exceptional speed.

Schneider Electric provides the power infrastructure supporting Firebird’s AI factory in Hrazdan, helping Firebird meet its accelerated deployment schedule by rapidly delivering and setting up critical systems, including medium- and low-voltage switchgear, three-phase uninterruptible power supply systems and rack enclosures. This keeps the power buildout moving at the pace of the compute and provides a reliable foundation to bring NVIDIA accelerated computing online at scale.

To support the facility’s thermal needs, Vertiv provided a cooling architecture combining chilled-water technology, advanced controls and Vertiv TrimCooler technology for efficient heat rejection. Vertiv’s iCOM CWM Chilled Water Manager centrally coordinates cooling resources, improving visibility, efficiency and responsiveness as demand shifts with AI workloads.

Early demand is coming from AI-native companies including Perplexity, which is working with Firebird to access high-performance AI infrastructure for its AI agent platform and answer engine. 

As AI becomes essential infrastructure worldwide, Firebird’s expansion can help make the CIS region a magnet for global companies building and running AI — and a catalyst for local developers, researchers and enterprises. 

Powered by NVIDIA’s total AI factory platform — reference architecture, accelerated computing, networking and AI software — and deployed on Dell PowerEdge servers, the new Firebird AI factory will help Armenia’s builders turn energy into intelligence and connect their innovations to the global AI economy.


NVIDIA Vera Rubin Maximizes Intelligence per Dollar for Post-Training


Think of a professional athlete. What separates elite performers is what happens between games: continuous refinement, adjusting to new opponents and sharpening skills based on what the last game exposed.

Agentic AI works the same way. A model is no longer asked for an answer. It’s given a goal and has to keep adapting as environments shift, edge cases emerge and tools change. Unlike a generative model responding to a prompt, an agentic model must plan, use different tools and recover from problems it encounters mid-run.

That’s why post-training, the phase that refines a model after initial training on raw data, is no longer a one-time finishing step. It’s continuous, because the environment that agentic models operate in shifts fast. The tools an agent uses can change week to week. Edge cases surface in production that no test set anticipated. Each deployment brings its own codebase, policies and environment.

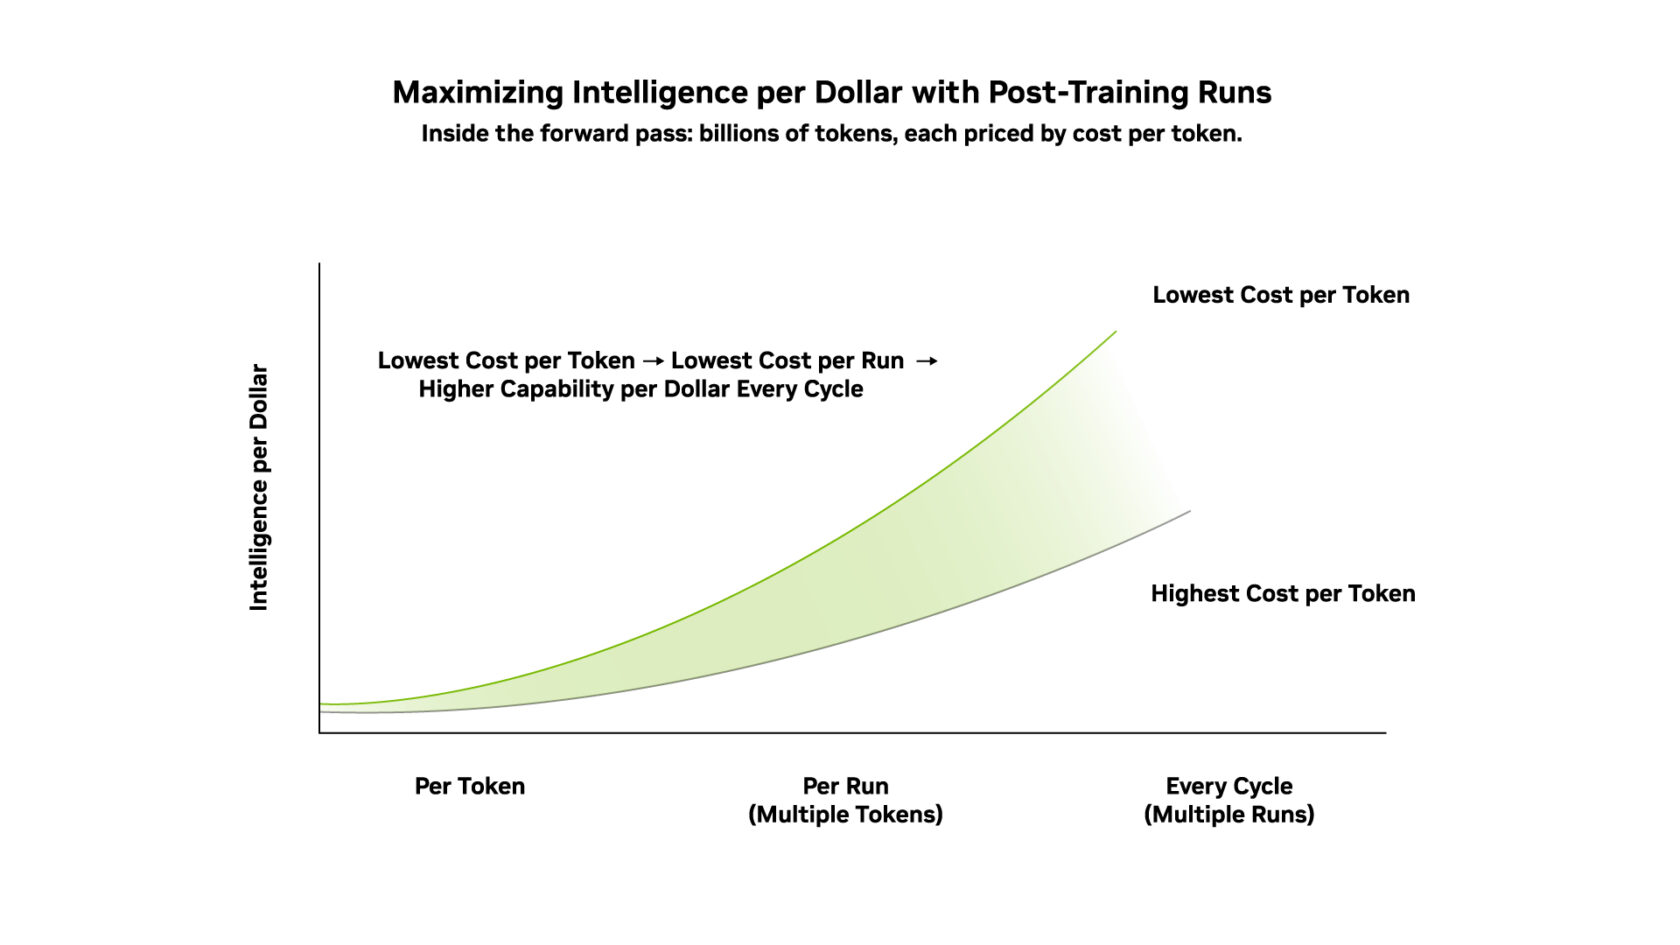
Post-training runs loop back from production as new problems surface. The compute footprint grows not because any single run is larger, but because the runs never stop. Agentic AI introduces a new compute pattern for post-training, making it the central workload of the agentic era and the primary driver of intelligence per dollar.

The goal of post-training is to maximize intelligence per dollar by maximizing the yield of every forward and backward pass in the continuous learning cycle. The forward pass — inference — is measured in cost per token. That means that every improvement to cost per token flows directly into intelligence per dollar. 

Agentic Post-Training Demystified

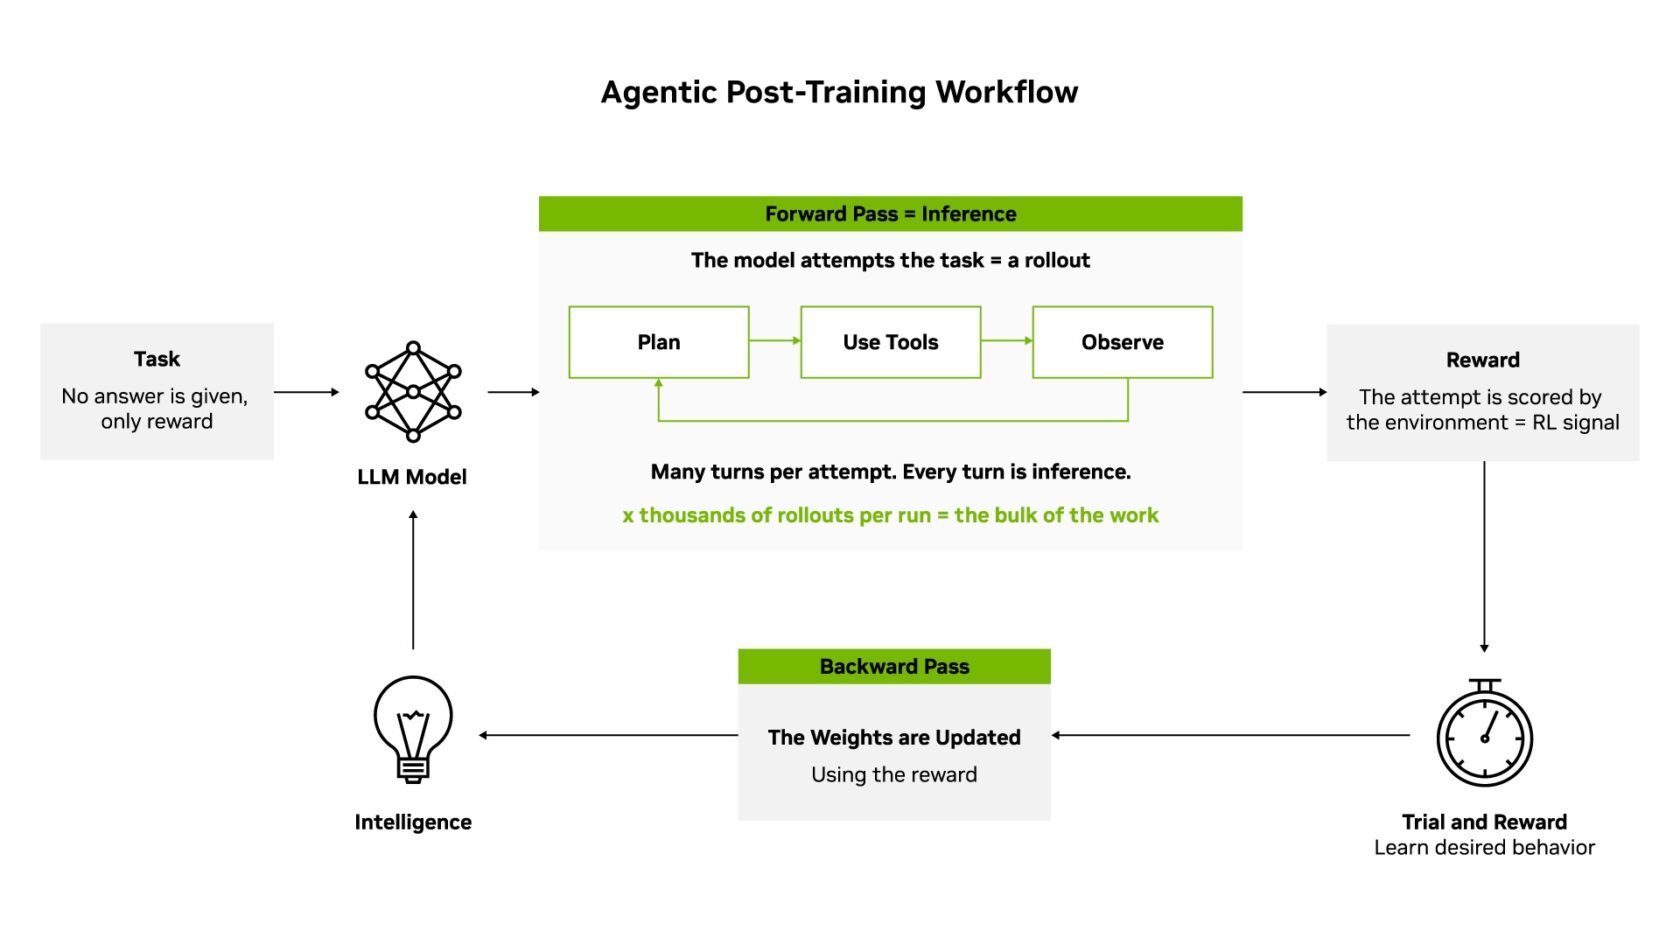
Post-training is where intelligence is built. In pretraining, the model learns to predict the next token, which gives it fluency but not intelligence. Post-training is where it learns to write code, plan a multistep task, use a search tool and recover when something goes wrong. Inference is what comes after: the model working on the job, priced in cost per token.

Because there’s no answer key to memorize, only a reward, the model learns by reinforcement learning (RL) techniques. When given a task, it writes out an attempt — the forward pass — the same work it does on the job. The attempt is scored, and the lesson updates the model’s weights — the backward pass. Across millions of attempts, intelligence grows.

Each step is compute intensive, and running this loop at scale is an orchestration problem: thousands of environments generating rollouts in parallel, rewards being verified and updated weights flowing back into training with accelerators fully utilized. NVIDIA NeMo open libraries, such as NeMo Gym for training environments and NeMo RL for distributed post-training, turn post-training from bespoke research code into repeatable infrastructure. 

Why Intelligence per Dollar Extends Cost per Token 

If inference is the revenue engine, post-training is the multiplier: the more capable the model, the higher the value of every token served. 

Cost per token is the key metric for the inference factory: the all-in cost of delivering 1 million tokens. Intelligence per dollar sits one layer up, answering a different question: what does it cost to build a model worth serving, and keep it worth serving as its environment changes?

The two are nested, not competing. AI infrastructure that lowers cost per token also lowers the cost of every point of intelligence built into the model. And every point of intelligence built in raises the value of every token the inference factory serves. 

In other words, cost per token measures operating yield; intelligence per dollar measures whether the investment in model intelligence is paying off. 

Maximizing Intelligence per Dollar: Post-Training Nemotron 3 Ultra

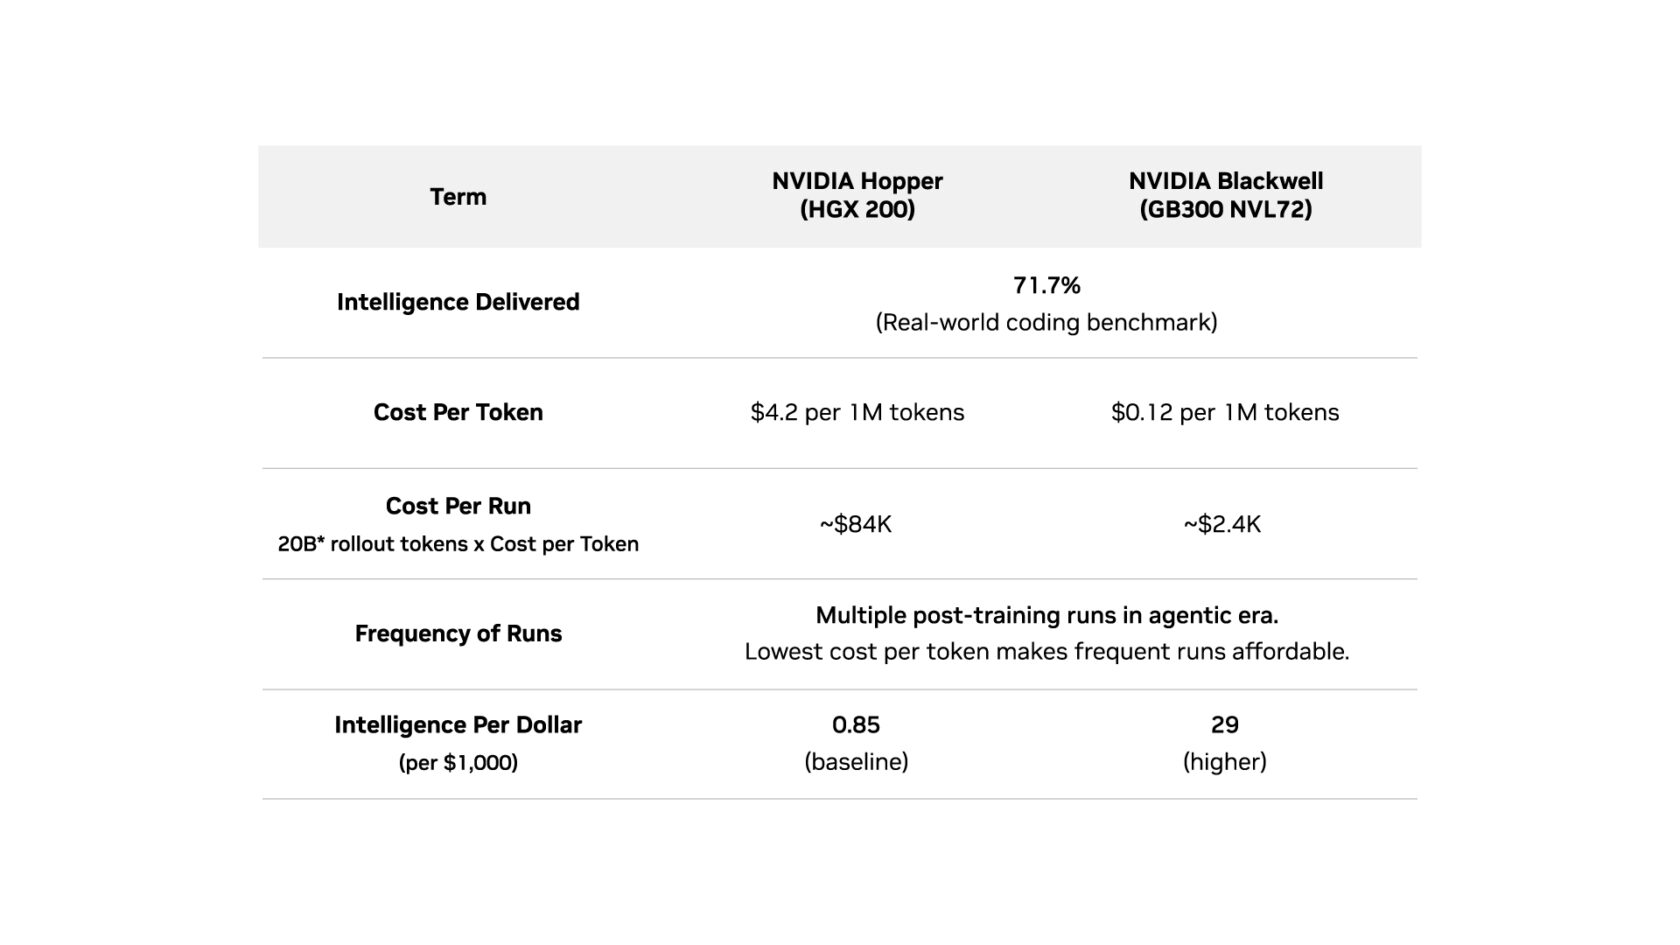
NVIDIA Nemotron 3 Ultra — an open weight, 550-billion-parameter mixture-of-experts (MoE) model, offers verifiable benchmarks and a fully disclosed post-training recipe run on NeMo RL. It scored 71.7% on a standard real-world coding benchmark, SWE-bench verified, where it produced a working fix for roughly seven in 10 real software bugs from open source projects, each one checked against the project’s own tests.  

Illustrative 20 billion rollout tokens, based on prior-generation Nemotron 3 Super’s ~1.2 million rollouts at ~10,000 tokens each, scaled up for the larger Ultra model. Intelligence per dollar between platforms is independent of this assumption; the absolute values scale with the token count.

The NVIDIA Blackwell platform lowers cost per run and makes the frequent post-training the agentic era demands economically viable. That intelligence is reaped across every token served.

The NVIDIA Vera Rubin platform extends the trajectory further, training the largest models with one-fourth the GPUs of the Blackwell generation. It was codesigned from end to end to maximize intelligence per dollar for the agentic post-training load: more rollouts per run, more environments in play and post-training cycles that never stop.

Post-Training Workflows in Action

Prime Intellect’s Lab continuously post-trains frontier open models on NVIDIA Blackwell and uses NVIDIA Dynamo for inference orchestration. With Vera Rubin, Prime Intellect plans to scale reinforcement learning environments, generate more rollouts per run and accelerate training-to-inference iteration loops to maximize intelligence per dollar for businesses.

Prime Intellect has optimized its sandbox infrastructure to integrate with NVIDIA Vera CPUs, enabling low-latency, energy-efficient reinforcement learning. Open source tools and models such as NVIDIA Nemotron and NVIDIA NeMo Gym are also integrated into its software stack. When comparing realistic RL sandbox workloads against alternative x86 architectures, Prime Intellect found that Vera delivers, on average, 30% greater throughput per CPU.

Perplexity’s RL post-training stack runs asynchronously across hundreds of NVIDIA GPUs, with an RDMA-based weight transfer engine that syncs trillion-parameter models in under two seconds between training and inference compute nodes. The resulting post-trained Qwen3 235B models are then served on NVIDIA GB200 NVL72 systems.

Together AI provides post-training as a service, including supervised fine-tuning, RL and direct preference optimization. The service is delivered via a feature-rich application programming interface and software development kit that supports the full range of post-training on its AI Native Cloud platform. It has been running on NVIDIA’s platform and optimized kernel libraries, and is looking to harness the Vera Rubin platform next.

Learn more about NVIDIA Vera Rubin, the platform for AI factories to maximize intelligence per dollar across workloads. And explore NVIDIA’s full-stack platform for training frontier models.

NVIDIA Blackwell Leads on First Agentic AI Infrastructure Benchmark


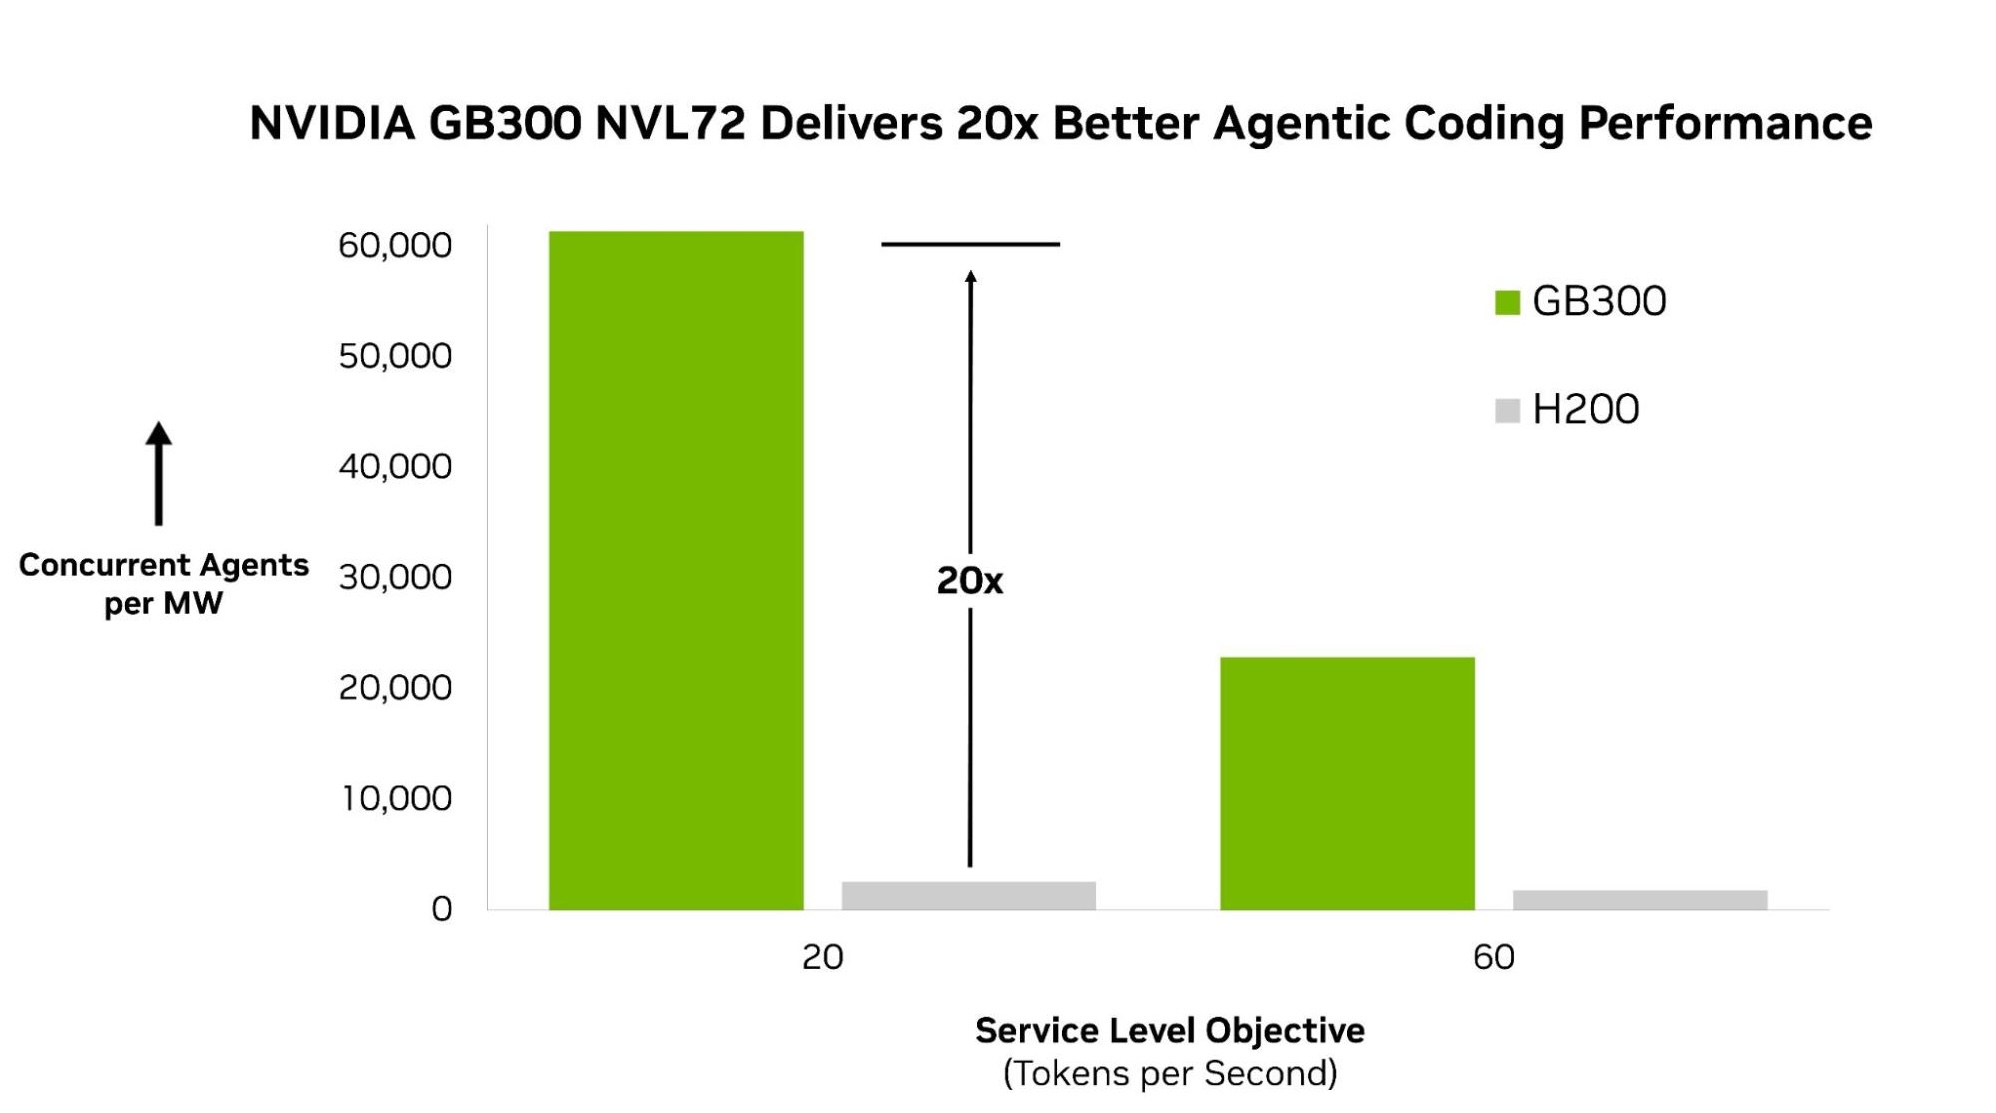
AgentPerf from Artificial Analysis, the industry’s first agentic AI benchmark, gives developers, enterprises and infrastructure providers a clear way to compare systems for agentic AI. In the first round of published results, the NVIDIA Blackwell Ultra NVL72 platform delivers leading performance across the agentic AI workloads tested, running 20x more agents per megawatt than NVIDIA Hopper.

Agentic AI is a fundamentally different workload than conversational AI. A single chat completion is a sprint: one large language model (LLM) call, one response. An agent functions more like a relay: It breaks a goal into many steps and keeps going until the task is done. 

Agents chain together multiple LLM calls and tool calls to gather context, observe, reason and act.

That results in dozens to hundreds of LLM calls chained together, each passing growing context to the next, with tool calls like code compile and execution, database search and web browsing at every handoff. The complexity isn’t additive; it’s multiplicative. 

The distinction matters enormously for performance measurement. Existing AI inference benchmarks measure one LLM call: how fast an LLM responds to a single request and how many simultaneous requests a system can handle. They weren’t designed for agentic workloads, where chained LLM calls, tool call delays and growing context stress accelerated computing systems in fundamentally different ways than a single LLM call ever could. 

For companies building and deploying agents at scale, it’s important to understand how responsive agents are, how many can be deployed simultaneously and how much useful work AI infrastructure can deliver for every dollar and watt invested.

NVIDIA GB300 NVL72 Runs 20x More Agents per Megawatt

In this first round, AgentPerf measures agentic performance with DeepSeek V4 Pro, a large mixture-of-experts (MoE) model that represents the class of frontier models powering today’s most capable agents. On this workload, NVIDIA GB300 NVL72 delivers the highest performance in the benchmark, running up to 20x more agents per megawatt than the NVIDIA HGX H200 system.

NVIDIA GB300 NVL72 supports far more concurrent agents per megawatt than NVIDIA H200 at both service-level objectives of 20 and 60 tokens per second per agent.

The performance advantage comes from extreme codesign across the full stack. GB300 NVL72 connects 72 GPUs into a single rack-scale system, enabling large MoE models like DeepSeek V4 Pro to distribute model execution efficiently at scale. 

CUDA kernels accelerate this further by overlapping communication and compute, so the cost of coordinating across experts is absorbed rather than added to latency. 

NVIDIA TensorRT LLM sustains efficiency as concurrent agent sessions scale. For example, it separates the processing of inputs from the generation of outputs so each can be optimized independently. 

These results are grounded in a benchmark methodology built from the ground up to reflect how agentic AI actually works in production.

Artificial Analysis AgentPerf: Built on Real-World Agentic Workloads

AgentPerf is built based on real coding agent trajectories: an agent receives a task, reads files, writes and edits code, executes commands and iterates based on the results — all drawn from real public code repositories across 12+ programming languages. The long sequence lengths, tool call patterns and delays are all representative of real-world coding workflows. 

AgentPerf then measures how many of these agentic tasks a platform can support simultaneously while meeting defined performance thresholds for responsiveness and output token rate. Tool calls are not executed but simulated using representative CPU processing time, so differences in results reflect accelerated computing performance only. 

The results translate directly into infrastructure decisions: how many concurrent agentic tasks can be run per accelerator and per megawatt of power. For enterprises deploying AI agents at scale, those numbers determine how much productive work a given infrastructure investment can actually deliver.

NVIDIA Ecosystem Partners Harness Blackwell’s Leading Performance

Leading inference providers including Baseten, DeepInfra and Together AI are already serving agentic workloads on frontier models such as DeepSeek V4 Pro on NVIDIA Blackwell and powering production agentic applications today. 

Together AI powers real-time inference for Cursor, an AI-powered agentic coding platform, on NVIDIA Blackwell. Cursor’s agents debug issues, generate features and execute refactors while developers continue working.  

DeepInfra powers Pam.ai, an AI workforce platform for car dealerships, which deploys agents to book service appointments, handle calls and run outbound sales campaigns, entirely on NVIDIA Blackwell. 

As NVIDIA and the open source ecosystem continue to optimize inference software, performance and efficiency on agentic workloads will only improve. The NVIDIA Vera Rubin architecture is now in full production, bringing the next generation of infrastructure capacity to meet the growing demands of agentic AI at scale. 

Dive deeper into AgentPerf’s methodology and NVIDIA’s full-stack optimizations for agentic AI in this technical blog.

How the UK Is Turning Sovereign AI Ambition Into Action With NVIDIA Technologies


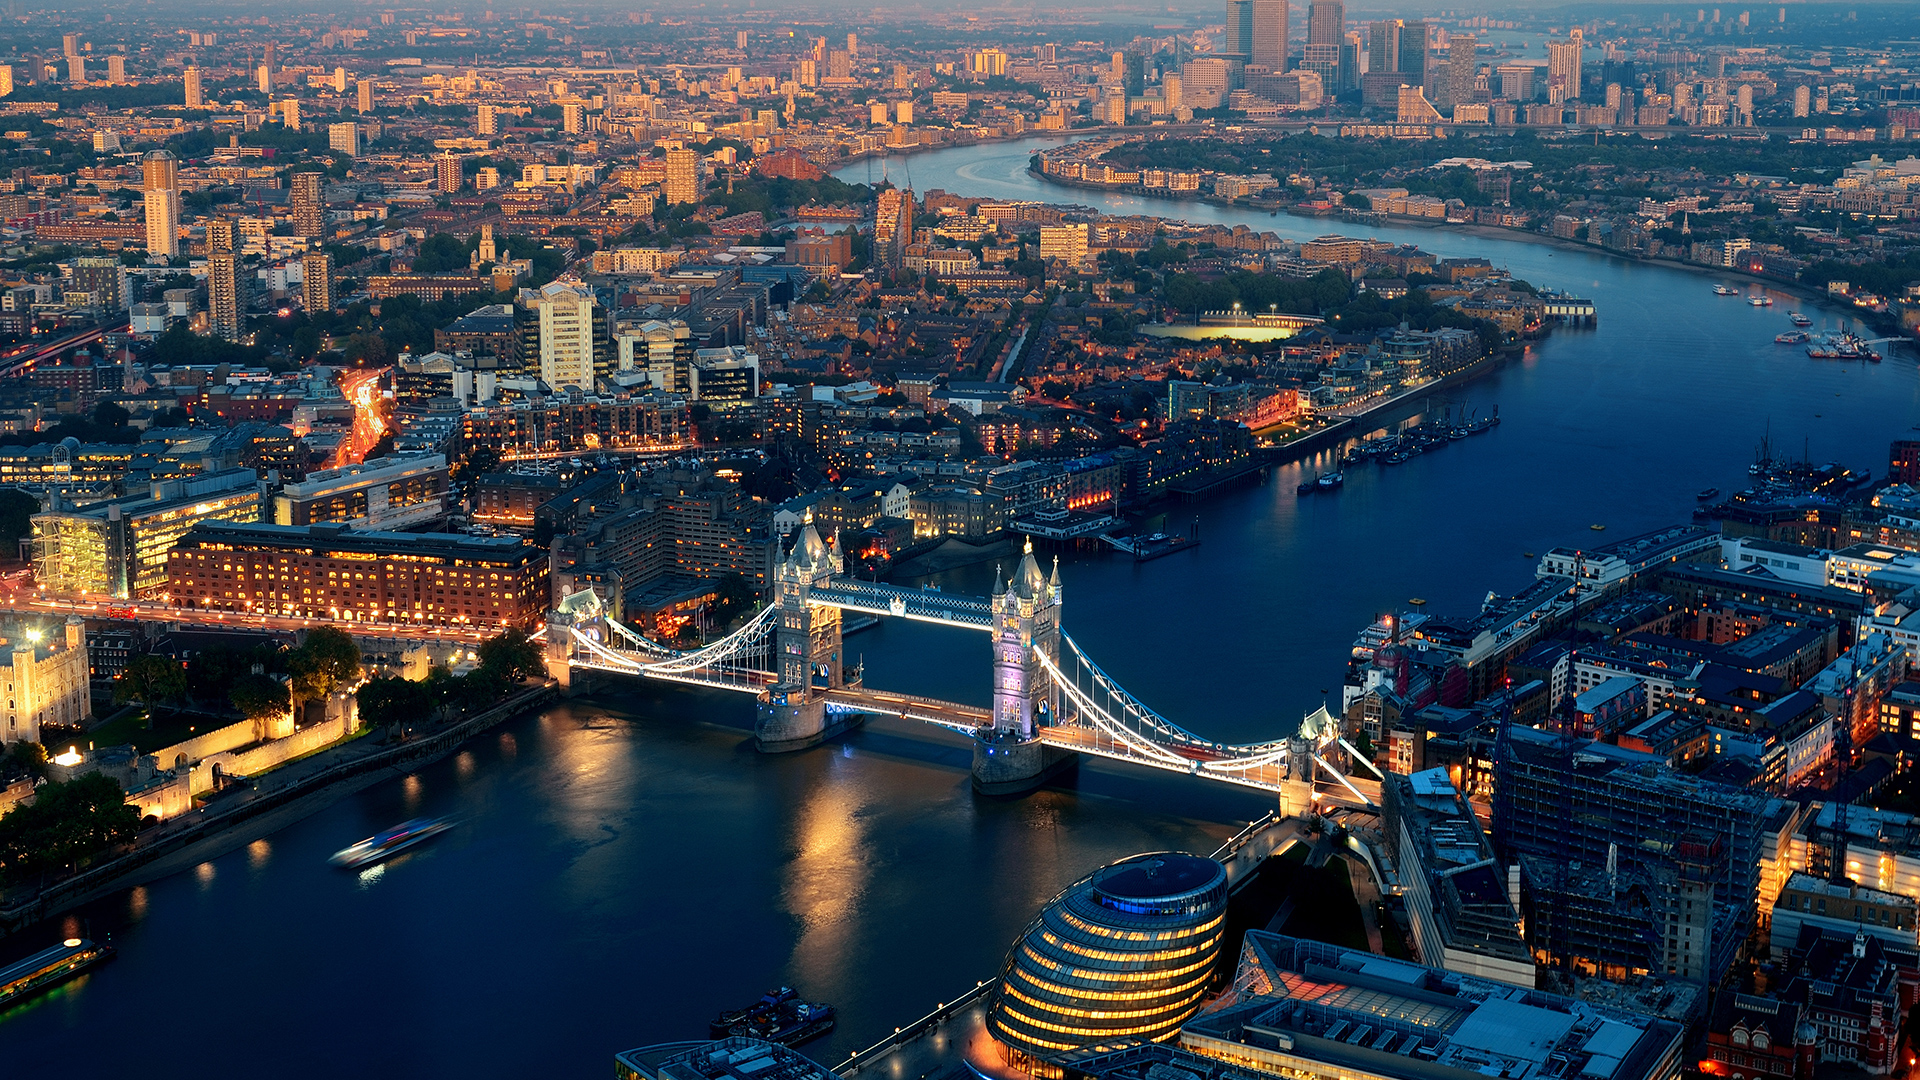
A year ago at London Tech Week, NVIDIA founder and CEO Jensen Huang and U.K. Prime Minister Keir Starmer made a declaration: the U.K. would be an AI maker, not an AI taker. 

At this year’s event, NVIDIA and its partners are showcasing how that commitment is producing real momentum across the nation’s infrastructure, startups and enterprises. 

U.K. technology leaders are innovating across healthcare and life sciences, coding, agentic AI, inference and more — all running on sovereign AI deployments.

AI Minister Kanishka Narayan said: “A year ago, we said the UK would be an AI maker, not an AI taker. Today we’re delivering on that with sovereign compute powering British startups to push the boundaries of what AI can do, from drug discovery to healthcare to robotics. This is what it looks like when a country backs its own talent with the infrastructure to match.

“NVIDIA’s decision to invest billions here is a reflection of the strength of what’s being built in Britain. We are determined to make sure the next generation of AI breakthroughs happens in this country, and we have everything we need to make it happen.”

Commitment to Compute

Over the past year, the number of AI cloud providers planning to deploy AI infrastructure on U.K. soil has doubled. 

Nebius has announced plans to expand customers and cloud capabilities with three new deployments of advanced NVIDIA AI infrastructure, as the NVIDIA AI Cloud ecosystem partner continues to build out its commercial and AI R&D hub in London. Combined, the deployments are expected to reach 65 megawatts when fully ramped up in 2027.

CoreWeave is building in the U.K. Government’s AI Growth Zones, and seven more NVIDIA AI Cloud ecosystem partners have plans in the pipeline. BT and Nscale announced plans to build sovereign AI data centers across three existing BT sites in the U.K., combining NVIDIA AI infrastructure, Nscale’s full stack and BT’s trusted nationwide connectivity backbone. 

From Fund to Frontier

Central to that sovereign compute story is Isambard-AI — the U.K.’s most powerful computer. Built on 5,400 NVIDIA GH200 Grace Hopper Superchips and running entirely on zero-carbon electricity, it’s the engine behind some of the U.K.’s most ambitious AI research. 

The U.K. government’s Sovereign AI Fund is putting that capability to work by backing homegrown companies and providing the domestic infrastructure needed to scale their ambitions. 

Among its first recipients is Ineffable Intelligence, which recently announced a collaboration with NVIDIA to build the future of reinforcement learning infrastructure. 

Other recipients include four U.K.-based NVIDIA Inception startups, each pushing the AI frontier using Isambard-AI. These startups are:

Cosine Builds Sovereign Coding Platform

Cosine is building an end-to-end sovereign AI coding platform for highly regulated industries such as financial services, critical infrastructure and national security. Using Isambard, Cosine is training a new, large-parameter, mixture-of-experts, multimodal agentic LLM for natively handling data types beyond text and image. 

“Access to Isambard enables the project, full stop,” said Alistair Pullen, cofounder and CEO of Cosine. “We already have the people who know how to do this. We have the data. We have the infrastructure and the training. The thing we’ve never had is this level of compute.”

Cursive Trains Self-Improving AI Systems

Cursive is building self-improving AI systems that learn continuously from real-world data, enabling them to operate autonomously over long periods of time. This is unlocked through new memory-augmented architectures with dramatically larger context windows, currently in development using the Sovereign AI Fund resources. In addition, the team recently adopted the NVIDIA Megatron-LM framework for distributed training at scale.

“The Sovereign AI Fund is more than just processing power — it’s a statement about investing in AI in the U.K.,” said Talfan Evans, cofounder and CEO of Cursive. “Sovereignty is actually now a buying criterion — and it’s a challenge to tap into the resources we uniquely have as U.K. and European companies.”

Doubleword Optimizes Inference to Deliver Abundant Intelligence Tokens

Doubleword, the U.K.’s first dedicated inference lab, optimizes every layer of the AI stack to maximize what it calls “IQ per dollar.” The company deploys open models including NVIDIA Nemotron 3 Super 120B and builds on the NVIDIA Dynamo inference framework. 

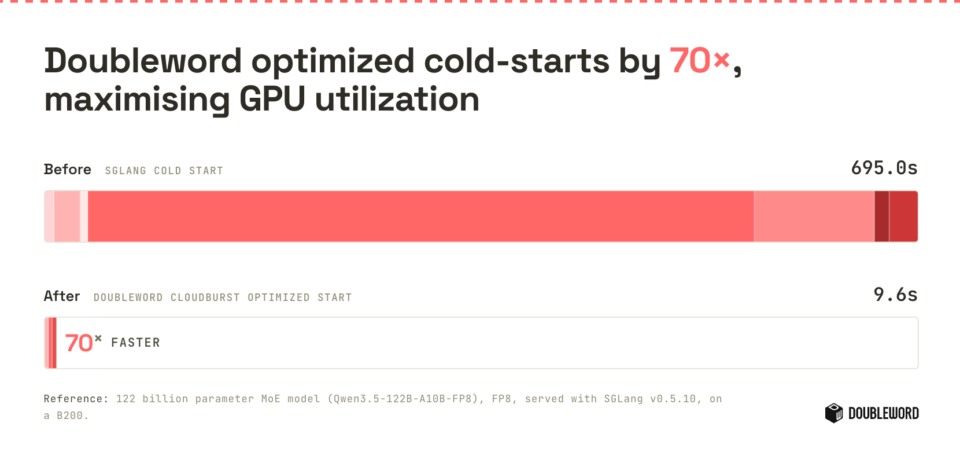
On Isambard, Doubleword’s early results achieved 70x faster model cold starts — aka model loading times — and 4x lossless KV cache compression, critical advancements for long-running agentic workloads. The result: inference at 90-95% lower costs than other leading inference providers.

Image courtesy of Doubleword.

“Sovereign AI is most impactful at the inference layer,” said Meryem Arik, cofounder and CEO of Doubleword. “Inference is when you’re actually getting the value from the model — we want that value created in the U.K., with U.K. compute and U.K. data centers.”

Prima Mente Uses Foundation Models to Study Alzheimer’s and More

Prima Mente builds biological foundation models to identify new biomarkers, subtypes and drug targets of Alzheimer’s, Parkinson’s and ALS. With its Isambard allocation, the company is developing Pleiades 2, a foundation model combining five biological data modalities. 

Achieving nearly 3x speedups in model training with NVIDIA Blackwell GPUs, Prima Mente also uses NVIDIA Parabricks for genomic data processing and NVIDIA Transformer Engine for model optimization.

“Research shows Alzheimer’s might be 25 different subgroups of disease, and we want to help by using AI to identify these subtypes and the biology within the cells as they change,” said Hannah Madan, cofounder of Prima Mente.

Video courtesy of Nebius and Prima Mente.

AI Talent, Policy and Production

NVIDIA’s £2 billion investment in the U.K. startup ecosystem — in collaboration with leading venture capital firms — is bringing new capital and advanced AI infrastructure to major U.K. hubs including London, Oxford, Cambridge and Manchester. 

U.K. membership in the NVIDIA Inception program has increased by 50% over the past year. AI-native companies like Doubleword, Synthesia and PolyAI are scaling globally from U.K. roots. 

At last year’s London Tech Week, NVIDIA announced a collaboration with the U.K Department for Science, Innovation and Technology on 6G and AI skills. The 6G collaboration has seeded testbeds at four U.K. universities. In May, the NVIDIA Deep Learning Institute (DLI) delivered two new courses — added to support the nation’s wireless research community — to participants from over 30 U.K. universities.

Plus, as part of this AI skills collaboration, NVIDIA DLI courses are offered as part of QA’s AI Apprenticeships in England. 

And the NVIDIA Developer Program now includes more than 200,000 U.K. developers. 

The Sovereign AI Forum, which launched last year with seven charter members, convened the country’s AI leadership to turn policy into deployment roadmaps. Over the past year, the Forum has welcomed dozens of participants across government, industry and the startup community — turning policy into deployment roadmaps.

And enterprise AI is moving from pilot to production:

  • Apian is building digital twins of two National Health Service hospitals, combining autonomous devices, ground robots, computer vision and robotic simulation.
  • Deliverance AI is helping regulated enterprises to run, govern and scale AI agents inside their own environment — through a single control plane. The Agentic Operating System is built for organizations where data sovereignty is non-negotiable.
  • Glass Futures has installed an AI-driven digital twin of its glass furnace capable of testing and predicting new, optimal ways to make glass. The digital twin taps into NVIDIA accelerated computing and the NVIDIA PhysicsNeMo framework.
  • Orbital Industries has announced codesigned, NVIDIA Vera Rubin DSX AI Factory-compliant AI infrastructure that accelerates time to first token.
  • Reading Football Club is partnering with Stelia to establish an AI Centre of Excellence, combining Stelia’s full-stack AI platform with accelerated compute infrastructure from NVIDIA and Lenovo.

It all reflects momentous progress in U.K. AI leadership — and offers a glimpse of where it’s heading.

Join NVIDIA at London Tech Week.

NVIDIA and Google Cloud Empower the Next Wave of AI Builders


At this year’s Google I/O conference, NVIDIA and Google Cloud are accelerating the work of more than 100,000 developers in the companies’ joint developer community, which provides curated learning paths, hands-on labs and events that help them build using the full-stack NVIDIA AI platform on Google Cloud. 

Launched at Google I/O last year, the community brings together developers, data scientists and machine learning engineers who want to sharpen their AI skills on the latest NVIDIA and Google Cloud technologies. 

New additions for the community are rolling out this year, including a learning path for using the JAX library on NVIDIA GPUs, a new NVIDIA Dynamo codelab focused on inference optimizations, as well as monthly developer livestreams

Over the last year, the community has become a go‑to hub for AI builders using NVIDIA‑accelerated tools for data science and machine learning. The result has been production‑ready retrieval-augmented generation applications on Google Kubernetes Engine (GKE) and instrumenting observability for agent workloads. 

These AI builders are also experimenting with new large language model research and prototyping hybrid on‑premises and cloud inference for real‑world use cases like sports analytics and enterprise data pipelines. 

Building With Google DeepMind’s Gemma, NVIDIA Nemotron and Open Frameworks

NVIDIA and Google Cloud are equipping developers with learning resources and hands-on labs that combine NVIDIA libraries, open models and tools with Google Cloud’s AI platform — so they can build optimized, production‑ready AI applications faster.

For example, developers can accelerate data science and analytics with the NVIDIA cuDF library in Google Colab Enterprise or Dataproc, or deploy multi-agent applications by combining Google DeepMind’s Gemma 4 models, NVIDIA Nemotron open models and Google Agent Development Kit with Google Cloud G4 VMs powered by NVIDIA RTX PRO 6000 Blackwell GPUs in Google Cloud Run or with spot instances. 

NVIDIA and Google Cloud work closely across open frameworks like JAX so developers can build, scale and productize JAX workloads on NVIDIA AI infrastructure on Google Cloud — from single‑GPU experiments to multi‑rack deployments — while getting strong performance and a consistent experience. 

This work extends to Google Cloud AI Hypercomputer, where the MaxText framework uses these JAX optimizations to train large models efficiently on NVIDIA GPUs.

Building on the same foundation, NVIDIA Dynamo on GKE helps developers optimize large-scale inference — including mixture-of-experts models — so they can serve AI applications more efficiently with NVIDIA accelerated infrastructure on Google Cloud.

To help developers get hands-on with these capabilities, a new learning path on running and scaling JAX on NVIDIA GPUs and a new NVIDIA Dynamo on GKE inference codelab will become available next month for members in the Google Cloud and NVIDIA developer community.

Advancing Responsible AI With Google DeepMind’s SynthID and NVIDIA Cosmos

AI agents are increasingly built from a system of AI models — combining proprietary and open source models that reason, plan and act on users’ behalf. 

Amid this shift, trust and transparency are foundational, so developers and organizations can understand how these systems work and what they generate.

NVIDIA was the first industry partner to collaborate with Google DeepMind on SynthID, an AI watermarking technology that embeds robust digital watermarks directly into AI‑generated content, which helps preserve the integrity of outputs from NVIDIA Cosmos world foundation models available on build.nvidia.com.

Cosmos models provide rich 3D perception and simulation capabilities for robots, autonomous machines and other physical AI systems, while SynthID brings content transparency to the imagery and video they rely on. 

Together, they help preserve the integrity of AI‑generated content so developers can build and deploy agentic applications more responsibly across cloud, edge and real‑world environments.

Building on a Full-Stack NVIDIA and Google Cloud Platform

This year, Google I/O is putting the spotlight on new agentic experiences and tools for developers — and NVIDIA and Google Cloud are focused on ensuring builders have the infrastructure, software and learning resources they need to make the most of them. 

For developers in the community building on NVIDIA and Google Cloud, the skills and tools they learn can scale, effortlessly taking projects from prototype to enterprise‑grade workloads. 

At Google Cloud Next, Google Cloud and NVIDIA expanded their full‑stack platform to help developers train, deploy and operationalize agents on Google Cloud. This collaboration includes work on NVIDIA Vera Rubin-powered A5X instances, Google DeepMind Gemini models and more, and is being harnessed by leading AI labs and enterprises including OpenAI, Thinking Machine Labs, Schrodinger, Salesforce, Snap and Crowdstrike. Learn more in this blog.

Join the NVIDIA and Google Cloud developer community to connect with other builders and stay up to date on new tools, developer events and programs.

OpenAI’s New GPT-5.5 Powers Codex on NVIDIA Infrastructure


AI agents have revolutionized developer workflows, and their next frontier is knowledge work: processing information, solving complex problems, coming up with new ideas and driving innovation. 

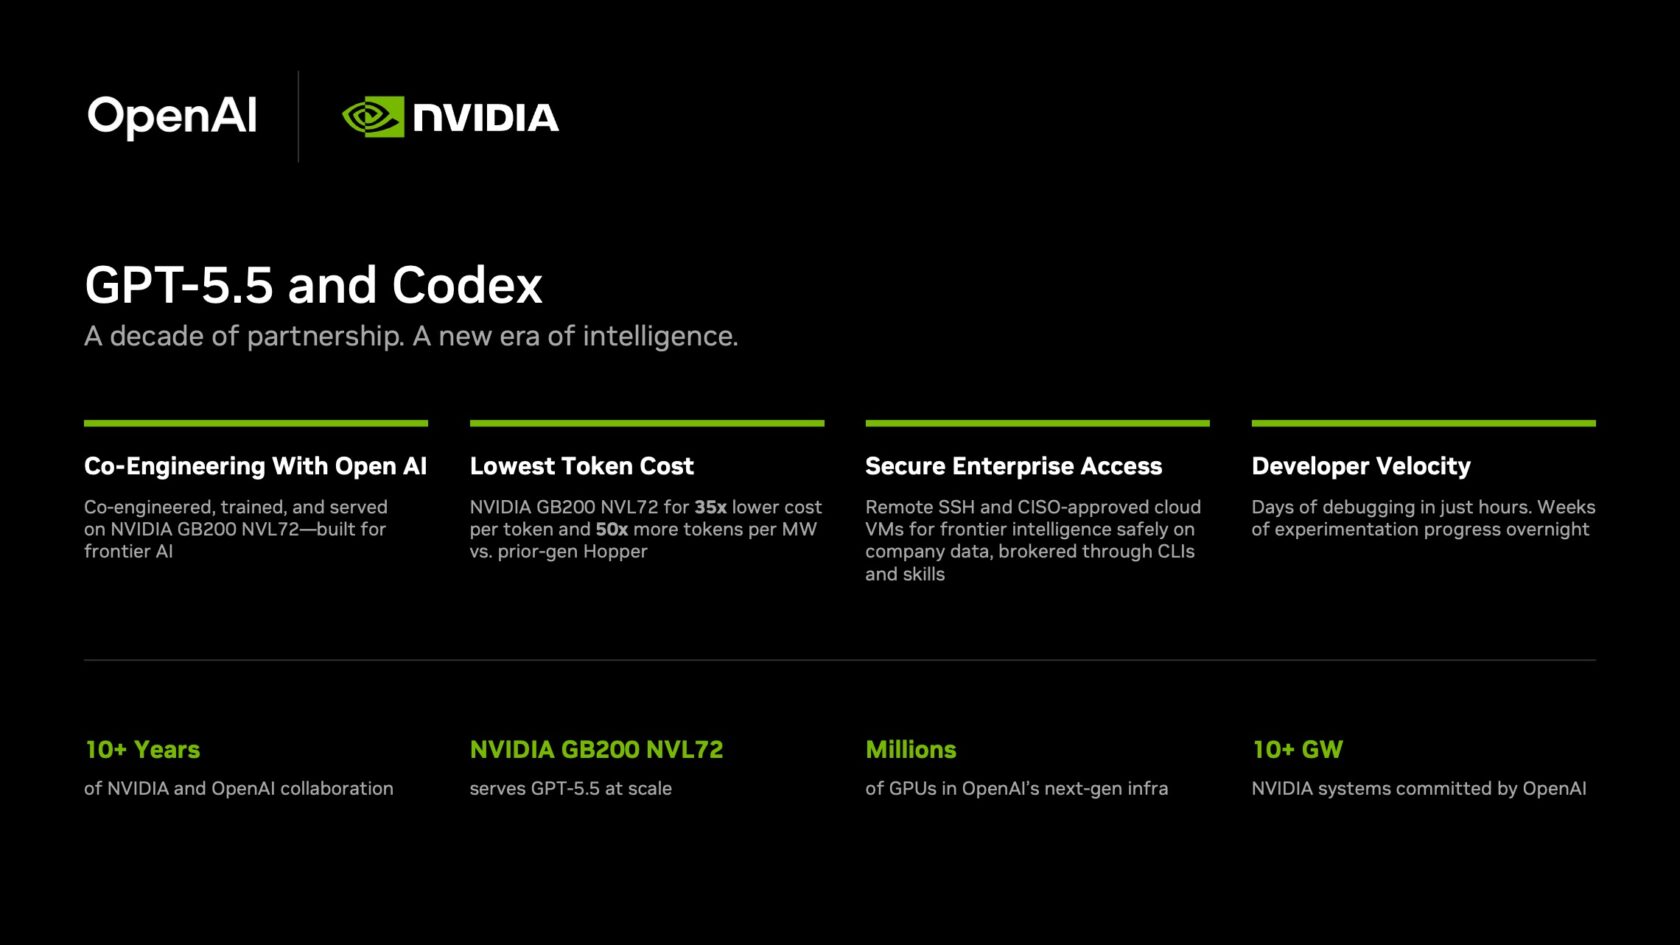
Codex, OpenAI’s agentic coding application, is enabling this new frontier. It’s now powered by GPT-5.5, OpenAI’s latest frontier model, which runs on NVIDIA GB200 NVL72 rack-scale systems. 

Over 10,000 NVIDIANs — across engineering, product, legal, marketing, finance, sales, HR, operations and developer programs — are already using GPT-5.5-powered Codex to achieve, in their words, “mind-blowing” and “life-changing” results. 

NVIDIA engineers have had access to GPT-5.5 through the Codex app for a few weeks, and the gains are measurable. Served on GB200 NVL72, which is capable of delivering 35x lower cost per million tokens and 50x higher token output per second per megawatt compared with prior-generation systems — economics that make frontier-model inference viable at enterprise scale.

Debugging cycles that once stretched across days are closing in hours. Experimentation that previously required weeks is turning into overnight progress in complex, multi-file codebases. Teams are shipping end-to-end features from natural-language prompts, with stronger reliability and fewer wasted cycles than earlier models. 

OpenAI’s stunning progress is just the latest example of NVIDIA’s work with every frontier model company — not just to accelerate the use of AI agents inside NVIDIA, but to help the company’s partners build the world’s best, lowest cost and most power efficient models for everyone.

As NVIDIA founder and CEO Jensen Huang told employees in a company-wide email urging everyone to use Codex: “Let’s jump to lightspeed. Welcome to the age of AI.”

A Deployment Built for Enterprise Security 

Just like humans, every agent needs its own dedicated computer. 

To ensure seamless operation within secure enterprise environments, the Codex app supports remote Secure Shell (SSH) connections to approved cloud virtual machines, allowing agents to work with real company data without exposing it externally. 

So to ensure maximum security and auditability, NVIDIA IT rolled out cloud virtual machines (VMs) for every employee to run their agent safely. This provides a dedicated sandbox for the agent to operate at its maximum capabilities while maintaining full auditability. Users can control the Codex agent running in the cloud VM from a user interface that every employee is familiar with.

A zero-data retention policy governs NVIDIA’s deployment, and agents access production systems with read-only permissions through command-line interfaces and Skills — the same agentic toolkit NVIDIA uses to run automation workflows across the company.

A Decade of Full-Stack Collaboration

The GPT-5.5 launch and the Codex rollout reflect more than 10 years of collaboration between NVIDIA and OpenAI. The partnership began in 2016, when Huang hand-delivered the first NVIDIA DGX-1 AI supercomputer to OpenAI’s San Francisco headquarters.

Since then, the two companies have worked closely across the full AI stack. 

NVIDIA was a day-zero partner for OpenAI’s gpt-oss open-weight model launch, optimizing model weights for NVIDIA TensorRT-LLM and ecosystem frameworks including vLLM and Ollama. 

OpenAI has committed to deploying more than 10 gigawatts of NVIDIA systems for its next-generation AI infrastructure — a buildout that will put millions of NVIDIA GPUs at the foundation of OpenAI’s model training and inference for years ahead.

And OpenAI and NVIDIA are early silicon and codesign partners: OpenAI provides feedback that informs NVIDIA’s hardware roadmap, and in turn gains early access to new architectures. That relationship produced a concrete milestone — the joint bring-up of the first GB200 NVL72 100,000-GPU cluster. The cluster completed multiple large-scale training runs and set a new benchmark for system-level reliability at frontier scale.

GPT-5.5 is the product of that infrastructure running at full strength. 

Learn more in OpenAI’s announcement.

India Fuels Its AI Mission With NVIDIA


India is the nexus of AI innovation this week as the host of the AI Impact Summit, which brings together global heads of state and industry to chart the future of AI.

At the summit, taking place in New Delhi, industry leaders, government agencies, educational institutions and startups are sharing how they’re working with NVIDIA to drive the AI industrial revolution in the world’s most populous country.

These initiatives support the IndiaAI Mission, a government effort that’s infusing India’s AI ecosystem with over $1 billion to bolster the nation’s compute capacity and foster the development of sovereign AI datasets, frontier models and applications. The mission also supports AI education, startup innovation and frameworks for trustworthy AI.

Read how NVIDIA is supporting IndiaAI Mission priorities including:

NVIDIA Cloud Partners Boost India AI Infrastructure

To achieve its AI ambitions, India is investing heavily in its computing infrastructure. Under the IndiaAI Compute Pillar, the nation is building out its AI cloud offerings with systems including tens of thousands of NVIDIA GPUs.

NVIDIA is collaborating with next‑generation cloud providers Yotta, L&T and E2E Networks to deliver advanced AI factories to meet India’s growing need for AI compute and enable it to develop AI models and services that drive innovation.

  • Yotta is a hyperscale data center and cloud provider building large‑scale sovereign AI infrastructure for India, branded as Shakti Cloud, powered by over 20,000 NVIDIA Blackwell Ultra GPUs. Its campuses in Navi Mumbai and Greater Noida deliver GPU‑dense, high‑bandwidth AI cloud services on a pay‑per‑use model, designed to make advanced AI training and inference affordable and compliant for Indian enterprises and public sector customers.
  • Larsen & Toubro (L&T) is building sovereign, gigawatt-scale NVIDIA AI factory infrastructure in India to reinforce the country’s position as a global AI powerhouse in alignment with the IndiaAI Mission. The roadmap includes initial expansions in Chennai to 30 megawatts as well as a new 40-megawatt facility in Mumbai. These facilities will power sovereign cloud workloads and hyperscale deployments, delivering secure, energy‑efficient infrastructure for advanced AI applications.
  • E2E Networks is building an NVIDIA Blackwell GPU cluster on its TIR platform, hosted at the L&T Vyoma Data Center in Chennai. The TIR cloud compute platform will feature NVIDIA HGX B200 systems and NVIDIA Enterprise software as well as NVIDIA Nemotron open models to supercharge sovereign development across agentic AI, healthcare, finance, manufacturing and agriculture.

India’s AI cloud infrastructure will host workloads as well as manufacture intelligence for model training, fine-tuning and high‑scale inference. Capacity within these data centers will be reserved for model builders, startups, researchers and enterprises to build, fine-tune and deploy AI in India.

Further expanding access to NVIDIA AI infrastructure in India, Netweb Technologies is launching its Tyrone Camarero AI Supercomputing systems built on the NVIDIA Grace Blackwell architecture. The NVIDIA GB200 NVL4 platforms — manufactured in India by Netweb under the government’s “Make in India” mission — feature four NVIDIA Blackwell GPUs and two NVIDIA Grace CPUs to power scientific computing, model training and inference.

NVIDIA and India AI-Native Companies Build the Nation’s Frontier AI Models

Another key goal of the IndiaAI Mission — led by its Innovation Center Pillar — is to develop and deploy foundation models trained on India-specific data and domestic AI infrastructure.

For a nation as multilingual as India — with 22 constitutionally recognized languages and over 1,500 more recorded by the country’s census — frontier AI models are a powerful tool to help its more than 1.4 billion residents interact with technology in their primary language.

Organizations across the country are building AI applications with NVIDIA Nemotron to support public-sector services, financial systems and enterprise operations in multiple languages.

NVIDIA Nemotron open models, datasets, tools and libraries enable organizations to build frontier speech, language and multimodal models at scale and across languages for government, consumer and enterprise applications. It includes India-specific datasets like Nemotron-Personas-India, an open dataset built from publicly available census data using NeMo Data Designer that includes 21 million fully synthetic Indic personas to enable population-scale sovereign AI development.

Adopters in India of Nemotron — and NeMo Curator, an open library for multilingual and multimodal data curation — include:

  • BharatGen, a sovereign AI initiative supported by the Government of India aimed at strengthening the country’s multilingual and multimodal AI ecosystem. As part of this effort, BharatGen has developed a 17-billion-parameter mixture-of-experts (MoE) model from the ground up, using the NVIDIA NeMo framework for pretraining and the NeMo RL library for post-training. The open source models are designed to power applications across public services, agriculture, security and cultural preservation.
  • Chariot, a company building AI systems for speech and multimodal communication. Using the NeMo framework, Chariot is developing an 8-billion-parameter model for real-time text to speech, supporting applications that improve accessibility and digital interaction across consumer and enterprise use cases.
  • Commotion, backed by Tata Communications, which has developed an AI operating system to automate complex enterprise workflows. By integrating NVIDIA Nemotron models and speech capabilities, the platform enables governed, production-grade AI deployments, helping enterprises scale AI across critical business operations.
  • CoRover.ai, which has deployed NVIDIA Nemotron Speech open models and NVIDIA Riva libraries for end-to-end, ultralow-latency speech AI — including the NVIDIA Riva Whisper v3 model for multilingual automatic speech recognition in English, Hindi and Gujarati. Powering customer service applications for the Indian Railway Catering and Tourism Corporation, CoRover’s platform supports around 10,000 concurrent users and more than 5,000 daily ticket bookings.
  • Gnani.ai, which offers enterprises a multilingual agentic AI platform that can interact with customers through voice and text. Gnani is building a 14-billion-parameter speech-to-speech model built on NVIDIA Nemotron Speech models, datasets and NeMo libraries including NeMo libraries through NVIDIA Cloud Partner E2E Networks — with plans to expand to a 32-billion-parameter model. By fine-tuning the NVIDIA Nemotron Speech model for Indic languages, Gnani has achieved a 15x reduction in inference costs, enabling the company to scale to support more than 10 million calls per day for customers in telecom, banking and hospitality.
  • National Payments Corporation of India (NPCI), which operates India’s retail payment and settlement systems and is deploying AI models to support digital financial services. Building on its production deployment of the AI-powered UPI Help Assistant — a pilot initiative for India’s Unified Payments Interface (UPI) — NPCI is exploring training FiMi, a financial model for India, using the NVIDIA Nemotron 3 Nano model and its own datasets. The model, fine-tuned with the NeMo framework, will support multilingual customer service across India’s banking ecosystem.
  • Sarvam.ai, a leader in full-stack sovereign generative AI that provides enterprise-grade multimodal, speech-to-text, text-to-speech, translation and reasoning models. The company is open sourcing its Sarvam-3 series of text and multimodal large language model variants, trained for 22 Indic languages, English math and code. Sarvam is using NeMo Curator to construct high-quality multilingual training data while adopting a subset of NVIDIA Nemotron datasets. The foundation models were pre-trained from scratch across 3B, 30B and 100B parameter sizes using the NVIDIA NeMo framework and Megatron-LM, and post-trained with NeMo RL. Training was conducted on NVIDIA H100 GPUs through NVIDIA Cloud Partners, including Yotta. With these sovereign models, Sarvam.ai’s new Pravah platform enables production-grade inference for Indian government and enterprise applications.
  • Soket.ai, which is using a modern large-model training stack on open NVIDIA Nemotron technologies, including NVIDIA Megatron and NVIDIA NeMo. These open source components enable scalable experimentation, training stability and efficient GPU usage, while preserving full control over the model’s data, design and life cycle.
  • Tech Mahindra, which has developed an 8-billion-parameter foundation model tailored for Indian languages and dialects. The model, built with Nemotron, is being designed for use in classrooms, where it can help make educational materials available in a wider range of Indian languages including Hindi, Maithili and Dogri. The team generated synthetic data with Nemotron libraries and tools such as NeMo Data Designer and conducted supervised fine-tuning with NeMo AutoModel.
  • Zoho, which is advancing its Zia LLM platform with proprietary models built using NVIDIA NeMo on the NVIDIA Blackwell and Hopper platforms, integrated across its software-as-a-service applications. This privacy-first architecture delivers contextual, production-grade AI for critical business workflows like customer relation management and finance, ensuring technology sovereignty and enterprise security at a global scale.

Developers building sovereign AI systems can access NVIDIA Nemotron and NeMo today. Nemotron models can be deployed anywhere on NVIDIA-accelerated infrastructure — including on NVIDIA DGX Spark, which is now available in India through qualified partners including PNY, RP tech India, Tech Data, a TD SYNNEX Company, as well as on NVIDIA Marketplace. A version manufactured in India as part of the “Make in India” initiative is available through Netweb.

DGX Spark also runs sovereign AI models by Indian model builders including Sarvam.ai.

Government and Academic Partnerships to Support Research in AI for Science and Engineering

Under its Application Development Initiative Pillar, the IndiaAI Mission is supporting high-impact AI applications — and its Startup Financing Pillar aims to democratize funding availability for AI entrepreneurs across the country.

NVIDIA is collaborating with government agencies, research institutions, venture capital firms and startups to advance projects aligned with these goals.

NVIDIA is collaborating with the Anusandhan National Research Foundation (ANRF), a statutory body under the Indian government, to spur even more cutting-edge AI research across the nation’s leading academic institutions. The initiative will support ANRF’s AI for Science & Engineering program and future AI programs.

NVIDIA will offer ANRF grantee institutions complimentary access to NVIDIA AI Enterprise software and specialized technical mentorship through the NVIDIA AI Technology Center. The collaboration will also include AI bootcamps, workshops and hackathons to strengthen India’s AI research ecosystem.

NVIDIA is also partnering with prominent venture capital firms including Peak XV, Z47, Elevation Capital,, Nexus Venture Partners and Accel India to identify and fund promising startups of all stages that are building AI solutions for India and international use. More than 4,000 of India’s AI startups are already part of the NVIDIA Inception program.

For more from the India AI Summit, learn how NVIDIA and global industrial software leaders are partnering with India’s largest manufacturers — and how India’s global systems integrators are building enterprise AI agents with NVIDIA.