Top 8 Benefits of 3D Golf Course Modeling and Rendering with Freelance Services & Design Companies


Golf course design has traditionally been a highly calculated process involving a lot of planning, aesthetic vision, and a deep understanding of the game itself, but innovation in technology has started using 3D modeling and rendering into the fray as a revolutionary tool to produce detailed, high-fidelity visualizations of golf courses before a single blade of grass is ever planted. 

Freelancers and design service companies are now using advanced tools to develop golf course models. Among the advantages of these models is the ability to bring ideas to life for designers, developers, and investors, offering quite a wide range of benefits.

Cad Crowd is the leading agency that can help you connect with 3D modeling and 3D rendering experts, providing services to your firm. Consisting of over 94,000 freelancers, we pride ourselves on our ability to give reasonable service rates while still exceeding your highest standards. Whether you’re looking for innovative solutions, new concept design, strategic insights, or top-tier execution, CAD Crowd has the expertise and the talent to bring your vision to life.

In today’s article, we will discuss the top eight benefits of 3D golf course modeling and rendering, and how freelance 3D rendering services and specialized design companies are revolutionizing the view on the visualization, design, and construction of golf courses.


🚀 Table of contents


RELATED: 10 awesome vehicle designs from the Cad Crowd gallery

Understanding 3D golf course modeling and rendering

3D golf course modeling and rendering is a particular type of computer-aided design process that can be achieved through 3D landscape rendering services, which produce ultra-high resolution, photorealistic images of golf courses. It allows designers, developers, and facility managers to visualize the details of the layout, terrain, and environmental features of the golf course during pre-planning or before any renovation work.

From 3D modeling, every part of the course is well thought out by the designers, including the fairways, bunkers, water hazards, and surrounding landscapes. Then, the rendering process incorporates realistic textures, lighting, and perspectives to mimic how the course would appear and represent the actual environment. This allows stakeholders to make rational decisions regarding design changes, landscaping, and even marketing presentations.

The union of 3D modeling and rendering boosts the mutual understanding of architects with clients on possible views concerning the course of action and elevates the process in planning and development to ensure that all the minutest details coalesce into the overall vision. Take a look at the benefits that 3D golf course modeling and rendering have to offer:
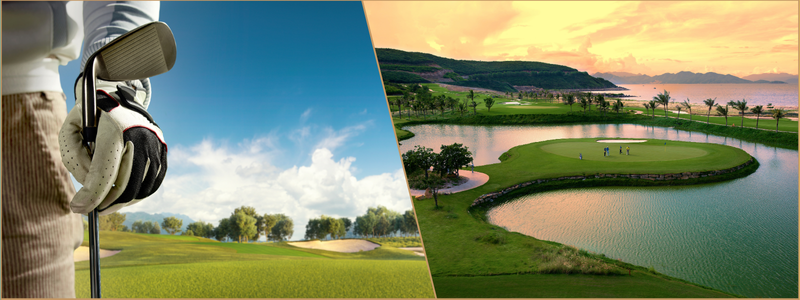
3D Golf Course Modeling and Rendering

RELATED: How engineering & 3D design contests give companies a competitive edge

Enhanced visualization and design accuracy

Probably the most significant advantage of 3D golf course modeling is its ability to deliver precise, realistic visuals through detailed renderings from 3D architectural visualization services. Two-dimensional blueprints cannot communicate depth, slope, and scale as effectively as 3D renderings. A freelance designer with expertise in CAD modeling and architectural visualization can produce photorealistic representations of how the course will appear, accurately showcasing every contour, hazard, and green.

Once accurate topographic information is in place, 3D models look just like the real terrain in every detail. As such, designers and clients should be able to walk through the virtual course and feel the elevation changes in their design. This will enable them to determine the flow of holes into one another. It is that level of immersion that results in a visual look that is absolutely stunning and will play as they want.

The challenge of redesigning a golf course arises simply because one has to iterate on the basis of architects’, developers’, or even prospective investors’ feedback. It can be pretty long and costly to correct the physical model or 2D drawings. 

3D modeling is more flexible

Particular components of the course may be easily altered by freelance CAD designers and companies specializing in 3D CAD design services. Changes in the fairway layout or adjustments to bunker depth can be quickly tweaked without an overhaul. With 3D CAD models, revisions are efficient and cost-effective, enabling several design iterations before finalizing the ideal version.

Natural integration

A golf course is not a set of holes but rather an experience in nature. The 3D modeling and rendering can be applied to integrate the course into the environment, thus ensuring it blends with nature. This integration will ensure sustainability while making the course visually more appealing to the people.

Using very high-resolution environmental data, land survey drawing experts can simulate how a golf course will interface seamlessly with natural elements, such as forests, rivers, or hills. Leveraging these specialized services allows for detailed environmental analysis, predicting how design choices affect ecosystems and surroundings. This culminates in an effortless merging of the artificial with the natural—each hole is not merely a design feature but an integrated part of the broader environment. In this sense, 3D modeling and environmental engineering help designers create sustainable golf courses that minimize ecological disruption while enhancing the golfer’s experience.

Improved stakeholder communication

In the process of developing golf courses, most of the time, several investors, architects, developers, and the local government are involved. In this case, communicating sophisticated design ideas using traditional media forms such as 2D plans or technical documents often risks that the concept will not be achieved or will fail to communicate adequately. 3D modeling and rendering offer a much clearer and more compelling means of communicating design intent.

A 3D model gives freelance designers the opportunity to share a real-to-life and immersive representation of the course with the stakeholders. This will make it easier to conceptualize the design and even give feedback. It will certainly ensure everyone is on the same page, thereby making delays minimal and timelines toward project approvals lighter. Be it pitching to investors or having your permits from your local authorities, it may be that only a well-crafted 3D render utilizing 3D rendering services will seal the deal.

Pre-construction marketing and investor confidence
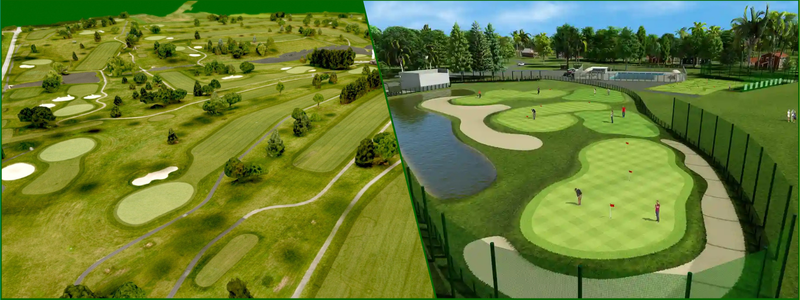
3D Golf Course Modeling and Rendering

RELATED: Featured freelance CAD designer portfolio on Cad Crowd

Often, developers will seek to secure investors, or simply future members of the golf course, to fund the project before it is even commenced. A 3D rendering could be very valuable in marketing efforts for building such a project. Detailed 3D models will let potential investors see accurately what the finished course will look like, including realistic textures, lighting, and environmental features. This will help build confidence in the project by giving a very tangible vision of the end product.

Freelance design companies develop high-quality visualizations and virtual tours that developers can present to potential investors or to promote their golf course projects. The ability to show a course before setting foot will attract investors and excite prospective members, hence increasing the chances of raising funds for the venture.

Customization and personalization of golf course

Each golf course is unique, and 3D modeling will allow for a great deal of personalization. Whether the developer desires to incorporate specific natural features or emphasizes a certain architectural style, 3D modeling will allow for detailing all aspects of the course design to fit the client’s vision. Lastly, freelance CAD designers are also adept at designing some weird custom elements within a 3D environment. A signature hole with a panoramic water hazard or a dramatic elevation shift can also be done quickly. This level of personalization helps developers in designing unique courses in a very competitive golf course design market. This level of detailing is often provided by CAD design experts.

Proper planning and construction feasibility

Golf course design requires one crucial factor, which is that the course must be aesthetic yet feasible to construct. 3D modeling can pick up some of the issues that may come up with the actual design process, such as problems with drainage, grading complexities, or infringement of existing land features.

Using 3D models, freelance designers and special design companies study the topography and design the course in minute detail. For example, 3D models can model water flow across the course during the rainy season; thus, the designers have proper designs for rainfall drainage systems. Thus, by being proactive about such issues, developers can avoid expensive delays during the construction period. This proactive approach often involves hiring freelance design services.

RELATED: 3D modeling software or CAD programs: What should my designer use?

Virtual reality andinteractive experiences

One of the most exciting advancements in 3D golf course modeling is incorporating it into virtual reality (VR) technology. Freelance designers are becoming more and more leery of putting such VR experiences in design presentations to allow clients and other stakeholders to walk “the course” before it actually exists. Using a headset, users can actually walk through or even “golf” the course in real time, feeling every detail of the design from a player’s perspective.

With this interactive experience, stakeholders can move beyond the static 3D model of the course. Not only will they have an immersive first-person view of the course under development but also see at a level of interactivity that supports the overall presentation and, in some way, offers some critical insights into the details of how the course will be played, giving them scope to adjust as players, developers, and course architects respond. This level of interactive presentation is often a service offered by freelance 3D modeling.

With golf courses, freelance services illustrate this to a great extent, comprising enhanced visualization and integration with the environment while offering cheap design revisions as well as interactive VR scenarios. Freelance designers and specialized design firms offer exactly the necessary experience in producing individual designs with beautiful layouts that can meet the highest standards in the appearance and functionality of each golf course.

RELATED: How does product prototyping with 3D modeling help grow sales and save R&D money?

How Cad Crowd can help

Whether it’s a wannabe developer looking to pitch to interested investors or a golf course architect working hard to be perfect in his design, just like Tiger Woods is in his game, 3D modeling is starting to revolutionize the face of golf course design once and for all. Combine it with talented freelancers or specialized firms to bring your vision to life, creating courses that are as gorgeous to behold as they are beautiful in play.

3D golf course modeling and rendering offer numerous benefits, especially when entrusted to and carried out by reliable freelance services and design companies. Here at Cad Crowd, we will make sure that you get in touch with top talents who can come up with mind-blowing golf course designs. Get a free quote today. 

author avatar

MacKenzie Brown is the founder and CEO of Cad Crowd. With over 18 years of experience in launching and scaling platforms specializing in CAD services, product design, manufacturing, hardware, and software development, MacKenzie is a recognized authority in the engineering industry. Under his leadership, Cad Crowd serves esteemed clients like NASA, JPL, the U.S. Navy, and Fortune 500 companies, empowering innovators with access to high-quality design and engineering talent.

Connect with me: LinkedIn ✦ X ✦ Cad Crowd

Official Xbox Podcast: GDC Indie Games Deep Dive


The post Official Xbox Podcast: GDC Indie Games Deep Dive appeared first on Xbox Wire.

I tried GPT-5.4, and most answers were really good – but a few had me concerned


I tested GPT-5.4, and the answers were really good - just not always what I asked

Elyse Betters Picaro / ZDNET

Follow ZDNET: Add us as a preferred source on Google.


ZDNET’s key takeaways

  • GPT-5.4 Thinking delivers deeper analysis than earlier ChatGPT models.
  • It has strong reasoning, but it sometimes answers questions you didn’t ask.
  • Formatting and image generation lag behind the text quality.

It’s a new month, and a new AI version number. It’s called GPT-5.4 Thinking. This latest release, which OpenAI issued last week, isn’t your run-of-the-mill ChatGPT incremental update.

Also: OpenAI’s new GPT-5.4 clobbers humans on pro-level work in tests – by 83%

Oh, no. Instead of jumping from 5.2 to 5.3, for this release the company jumped all the way to 5.4. And instead of offering a general purpose release, the company released GPT-5.4 Thinking, a more cognitively prepared model designed for bigger thoughts and challenges.

GPT-5.4 Thinking is available for the programming Codex tool, the API, and for paid ChatGPT plans. For this article, I used the $20-per-month ChatGPT Plus plan to put it through its paces.

That presented me with a bit of a challenge. Normally, when I test a ChatGPT version, I run it through a series of mixed tests. Some are quick, and some are a bit more detailed. The prompts are usually just a few lines long. The responses usually lend themselves to being included in an article.

But this Thinking model required deeper dives, with more comprehensive challenges. As such, not only are the prompts more involved, but the responses are far too extensive to include in the article. Instead, I’m providing links into each test session. When you follow the links, you’ll be able to see the entire response in depth. Usually, a shared transcript opens at the end of the transcript, so scroll back to the top to get the full contents of that discussion.

Also: How to switch from ChatGPT to Claude: Transferring your memories and settings is easy

Before we jump into the four challenges I presented to GPT-5.4 Thinking, I’ll give you a quick TL;DR conclusion about my experience. There’s some good and bad, but mostly good.

  • The good: Text-based responses are really good. Most of the challenges I gave it were answered thoughtfully. I didn’t catch it in any hallucinations. I got constructive value from every answer.
  • The bad: Unfortunately, sometimes it answered questions that differed from what I asked. Images and formatting left much to be desired. When it came to image generation, clearly the AI did not use an advanced model. You’ll see what I mean, but basically it’s like the model just didn’t listen. Formatting was weird. It likes very long numbered lists. You can see them in the chat transcripts.

Overall, I would definitely use the GPT-5.4 Thinking model for bigger challenges and questions. I was pretty impressed, although I definitely wasn’t a fan of the formatting. It also needs continuous management to keep it on track.

Now, let’s dive into each of the tests.

Test 1: Aircraft carrier in the sky

I started off with an image generation challenge. The starting prompt was “Create an image of an aircraft carrier flying in the sky, held up by four upward-facing turbo-propellors in round fan housings, carrying a squadron of fighter jets on its deck.”

Also: I stopped using ChatGPT for everything: These AI models beat it at research, coding, and more

I started with this because previous image generation tests, across a number of AIs, didn’t get it right. They almost always face the propellors to the rear of the carrier. Gemini Nano Banana 2 oddly put the propellors in front, with the carrier moving into the forward-facing thrust. Sometimes, we just don’t want to know.

In any case, right out of the gate, with the model set to GPT-5.4 Thinking, ChatGPT returned this image.

carrier-1.png

Screenshot by David Gewirtz/ZDNET

As you can see, it has the same problem. Although if you look closely at it, the props face the back of the aircraft, and there are visual thrust beams shooting downward. You win some. You lose some.

But then, I had a thought. This is the thinking model, so what if I asked it to design a helicarrier? What would it come up with? I specified the characteristics of the craft, and then added on these instructions: “Design such a vehicle, particularly explaining its structure and how it will be held aloft, along with any constraints or issues, as well as any tactical advantages”

I got back a long, well-considered answer. I particularly liked the section where it explained why “four downward-facing turbo-propellers are a weak solution.” It said they look dramatic, but it outlined a series of solid engineering reasons why they’re a bad idea from an aircraft construction point of view.

Also: ChatGPT’s cheapest subscription comes to the US: I compared Go to Plus and Pro

It also went on to discuss flight deck operations and various constraints in terms of practicality. In particular, it properly focused on the weight-to-power issue, which basically means it’ll take way too much power to hold something that big and heavy aloft.

Overall, the analysis and conclusions were great, although I was disappointed it didn’t mention either the USS Akron or USS Macon, which were early 20th century aircraft-launching dirigibles that actually worked (until they crashed). A modern dirigible would be a valid design option, yet GPT-5.4 Thinking didn’t mention that approach.

After GPT-5.4 Thinking created the detailed design spec, I again prompted for an image. I said, “Draw me a picture of the most probable design based on your existing analysis.”

And, wouldn’t you know it? The AI gave me back the exact same image as the one I got before it did any design work. That’s what I meant when I said the model just didn’t listen. I did try a bunch of different prompting approaches, but it never really worked out.

Although I tried a number of extremely detailed image specifications, none came out any better than the originals. My last attempt was to tell it I wanted an engineering-quality rendering.

carrier2.png

Screenshot by David Gewirtz/ZDNET

The AI used a variation of the previous image, but simply added labels that didn’t quite match the picture or were made up of pure gibberish (as in “Retenuif truss fornaing. reueirid stucana tearsport”).

So, it gets points for good design analysis, but not so much for image generation.

You can follow the entire chat transcript here.

Test 2: Boston tech and history travel itinerary

I started this test with a prompt taken word-for-word from my previous sets of tests: “Imagine you are a travel advisor. I want a week-long vacation in Boston in March focused on technology and history. What itinerary would you recommend?”

I found the results workable, but uninspired. It initially divided the days into history-focused days and tech-focused days, rather than by location around Boston. After a few rounds of discussion, it did combine destinations by location, which made more sense.

In terms of places to visit, it did all the highlights. It covered key historical locations, as well as the excellent science museums in Boston. I will give the AI credit. While there are a ton of interesting tech-related locations in the outer Boston area, it restricted its selection to those in Boston and Cambridge proper.

Also: Is ChatGPT Plus still worth your $20? I compared it to the Free, Go, and Pro plans – here’s my advice

I was happy to see the AI provide planning notes, including recommendations for how to replan the schedule for indoor-only activities if the weather turned bad. Since I asked for an itinerary in March, bad weather is certainly something important to plan for.

The Thinking model came into play when it was used to plan for both a fairly pricey vacation, and an alternative one on a student budget. It did particularly well pointing out budget eating options, and provided a day-to-day cumulative cost estimate, as well as cost estimates for each category.

It did the same with where to stay. It recommended hotels based on a centralized location to all of the recommended stops, as well as a less costly (less costly for Boston) option for budget travelers.

My biggest complaint, initially, was formatting. The AI just presented a huge list indexed by number. You can see that in the session transcript. I had to specifically ask for better formatting. While the revised formatting it gave me was an improvement, it was still less than ideal.

Also: I used these viral Gemini prompts to find the cheapest flight possible – here are the results

Net-net. If you’re traveling, GPT-5.4 Thinking will give you good information. It will be up to you to parse that information and make travel decisions. You can follow the entire chat transcript here.

Test 3: Social media in society

Here’s where GPT-5.4 Thinking begins to really shine. When I asked GPT-5.2, “Do you think social media has improved or worsened communication in society?” I got back a two-line answer. Both thoughts were coherent and appropriate, but it was ultimately unfulfilling.

For GPT-5.4 Thinking, I extended the question, saying “Provide an analysis of both sides, improved or worsened in depth, and then take a side, take a position, and defend your position.”

I got back a very well-considered response. The AI started off with a TL;DR, saying that social media has both bettered and worsened communication, but “on balance, I think it has worsened communication in society.”

Also: How to learn ChatGPT in an hour – for free

It then goes into a 1,300-word detailed analysis about why. It explores where social media has strengthened societal communications and then looks at where social media has had a deleterious effect. I have to give props to GPT-5.4 Thinking. It’s a very good read.

I gave the AI a follow-up question, asking how society should handle the impact of social media. I specified it fairly clearly, and gave the AI a variety of difficult-to-answer questions, difficult mostly because they’re fundamentally unanswerable questions.

Props again. GPT-5.4 Thinking deconstructed the prompt, explored the various issues, and knit together a compelling and supportable answer. I definitely recommend you read the entire transcript, which you can do right here.

Test 4: Explain GPT-5.4 using educational constructivism

The AI did not follow my instructions, but it did give a very interesting answer to a question I didn’t ask.

One of the tests I use for free chatbots is this prompt: “Explain educational constructivism to a five-year-old.” Very roughly speaking, educational constructivism is the theory of education that says you learn best by doing. I have long contended (and taught) that the only way you can learn programming is by actually writing code, which is a tangible example of educational constructivism in action.

In any case, I prompted GPT-5.4 Thinking, “Explain the new GPT 5.4 model using educational constructivism.”

Also: I’m a ChatGPT power user: Here are 7 useful settings that are turned off by default

Look at that prompt carefully, because GPT-5.4 Thinking clearly didn’t. The prompt invites the AI to explain GPT-5.4 through “doing” activities. Ideally, it would have proposed a series of exercises for the user to carry out, each of which would have helped demonstrate some of the model’s new capabilities.

But that’s not where GPT-5.4 Thinking went. Instead, it generated a 700-word thesis about how GPT-5.4 Thinking supports constructivism. It then offered to “recast this in one of three ways: as a classroom analogy, as a ZDNET-style plain-English explainer, or as a short comparison between GPT-4-era models and GPT-5.4.”

Also: ChatGPT’s new Lockdown Mode can stop prompt injection – here’s how it works

I let it do that, and its examples were adequate, and while they did answer the prompt GPT-5.4 Thinking suggested, the AI did not use “learn by doing” anywhere in its answers.

You know how a political candidate is sometimes asked something in a debate, but rather than answering the question, it goes off and just recites its own talking points? That’s what this response felt like. The answer it gave was good. It just wasn’t an answer to the question I asked.

You can follow the entire chat transcript here.

Overall recommendation

I have often characterized ChatGPT as a bright college student in need of good supervision. I would characterize GPT-5.4 Thinking as a very bright grad student who definitely needs good supervision.

Every answer I got back from GPT-5.4 Thinking was quite good in its own right. But in half my tests, the AI didn’t answer the question it was asked.

You can get it to give you good responses, but you have to fairly relentlessly correct the AI to keep it on point. That gets old. It could lead to misinterpretation. Because the answers are so good and written so confidently, it can be easy to get caught up in the AI’s answer, even if the answer is not to the question that it was asked.

Also: The best AI chatbots of 2026: Expert tested and reviewed

I don’t know if this my-way-or-the-highway approach to answering questions is an artifact of the “thinking” model or GPT-5.4 itself. I strongly recommend OpenAI carefully look at this issue, because the last thing we want is a super-popular chatbot unleashed on the world that insists on ignoring the questions it was asked, answering tangentially adjacent questions it was never asked, and taking on tasks that are fundamentally not what it was instructed to do.

Additionally, I’m concerned about the claim that GPT-5.4 Thinking can do professional tasks. If the AI can’t render an engineering-quality image, it’s hard to believe the AI can meet or exceed the performance of a human engineer. That said, there’s no doubt the model can help professionals get their work done, as long as they are very diligent in monitoring results.

Whenever I see results like this, I become increasingly concerned about a world overrun by AI agents. Yes, the AI may sometimes know better. Humans definitely need help. But I’d really like AIs to follow our instructions. I’m not ready to accept it as our AI overlord just yet.

What do you think? Have you tried GPT-5.4 Thinking yet, or another “reasoning” style AI model? Did it give you deeper or more useful answers than earlier versions, or did you find yourself having to steer it back to the actual question?

How important are things like formatting and image generation compared to the quality of the analysis itself? Do you think more powerful “thinking” models will make AI more helpful or harder to control? Let us know in the comments below.


You can follow my day-to-day project updates on social media. Be sure to subscribe to my weekly update newsletter, and follow me on Twitter/X at @DavidGewirtz, on Facebook at Facebook.com/DavidGewirtz, on Instagram at Instagram.com/DavidGewirtz, on Bluesky at @DavidGewirtz.com, and on YouTube at YouTube.com/DavidGewirtzTV.


Anthropic sues Defense Department over supply chain risk designation


Anthropic has made good on its promise to challenge the Department of Defense in court after the agency labeled it a supply chain risk late last week.

The Claude-maker filed a complaint against the Department on Monday. The complaint comes after a weeks-long conflict between Anthropic and the DOD over whether the military should have unrestricted access to Anthropic’s AI systems. Anthropic had two firm red lines: it didn’t want its technology to be used for mass surveillance of Americans and didn’t believe it was ready to power fully autonomous weapons with no humans making targeting and firing decisions.

Defense Secretary Pete Hegseth argued that the Pentagon should have access to AI systems for “any lawful purpose.” A supply chain risk label is usually reserved for foreign adversaries, and requires any company or agency that does work with the Pentagon to certify that it doesn’t use Anthropic’s models. 

Anthropic called the DOD’s actions “unprecedented and unlawful” in a complaint filed in San Francisco federal court. “The Constitution does not allow the government to wield its enormous power to punish a company for its protected speech.”

This story is developing. Please check back for updates.

Macbook Air’s storage drive shows impressive speed gain, even beating the MacBook Pro


The MacBook Air has always been the sensible choice — great battery, light enough to forget it’s in your bag. What it’s never been is the one that makes MacBook Pro owners feel slightly embarrassed. Until now, apparently.

When Apple switched the M5 MacBook Air to PCIe 4.0 NAND flash, it didn’t just make it faster than its predecessor — it made it faster than some M4 Pro MacBook Pro models too.

Benchmark numbers that raise eyebrows

NotebookCheck’s hands-on review of the 13-inch M5 MacBook Air, using the Blackmagic Disk Speed Test, puts the numbers on the table:

Model Read (5GB) Write (5GB) vs. M5 Air (Read) vs. M5 Air (Write)
MacBook Pro 14 M5 6,752.1 MB/s 6,194.2 MB/s +4.31% faster −5.57% slower
MacBook Air 13 M5 6,473.4 MB/s 6,558.6 MB/s — —
MacBook Pro 16 M4 Pro 5,401.3 MB/s 6,713.2 MB/s −19.85% slower +2.30% faster
MacBook Air 15 M4 2,904.0 MB/s 3,023.9 MB/s −122.91% slower −116.89% slower

On reads, the M5 Air clears the M4 Pro MacBook Pro 16 by nearly 20%. On writes, the M4 Pro edges back by just 2.3% — a gap so small it wouldn’t show up in any real-world task you threw at it.

The quiet upgrade Apple didn’t talk about much

The jump over the M4 MacBook Air is where things get a little hard to believe. Over 122% faster on reads, nearly 117% faster on writes. That’s not a spec sheet footnote — two drives this far apart don’t feel like the same product category.

Day-to-day, it adds up faster than you’d expect. That big RAW wedding shoot that used to grind away on import? Done before you’ve poured your coffee. ProRes footage off the internal drive no longer feels like a gamble.

And if you’re running local AI models, the difference between waiting and not waiting is exactly this kind of storage speed. For a laptop that starts at $1,099, none of this was supposed to be part of the conversation. Apple barely mentioned it at launch, which — in hindsight — was a strange call.

Top Cost-Efficient Small Models for AI APIs


Introduction

API builders have seen an explosion of model choices.
Gigantic language models once dominated, but the past two years have seen a surge of small language models (SLMs)—systems with tens of millions to a few billion parameters—that offer impressive capabilities at a fraction of the cost and hardware footprint.

As of March 2026, pricing for frontier models still ranges from $15–$75 per million tokens, but cost‑efficient mini models now deliver near‑state‑of‑the‑art accuracy for under $1 per million tokens. Clarifai’s Reasoning Engine, for example, produces 544 tokens per second and charges only $0.16 per million tokens—two important metrics that signal how far the industry has come.

This guide unpacks why small models matter, compares the leading SLM APIs, introduces a practical framework for selecting a model, explains how to deploy them (including on your own hardware through Clarifai’s Local Runners), and highlights cost‑optimization techniques. We close with emerging trends and frequently asked questions.

Quick digest: Small language models (SLMs) are between roughly 100 million and 10 billion parameters and use techniques like distillation and quantization to achieve 10–30× cheaper inference than large models. They excel at routine tasks, deliver latency improvements, and can run locally for privacy. Yet they also have limitations—reduced factual knowledge and narrower reasoning depth—and require thoughtful orchestration.


Why small models are reshaping API economics

  • Definition and scale: Small language models typically have a few hundred million to 10 billion parameters. Unlike frontier models with hundreds of billions of parameters, SLMs are intentionally compact so they can run on consumer‑grade hardware. Anaconda’s analysis notes that SLMs achieve more than 60 % of the performance of models 10× their size while requiring less than 25 % of the compute resources.
  • Why now: Advances in distillation, high‑quality instruction‑tuning and post‑training quantization have dramatically lowered the memory footprint—4‑bit precision reduces memory by around 70 % while maintaining accuracy. The cost per million tokens for top small models has dropped below $1.
  • Economic impact: Clarifai reports that its Reasoning Engine offers throughput of 544 tokens per second and a time‑to‑first‑answer of 3.6 seconds at $0.16 per million tokens, outperforming many competitors. NVIDIA estimates that running a 3B SLM is 10–30× cheaper than its 405B counterpart.

Benefits and use cases

  • Cost efficiency: Inference costs scale roughly linearly with model size. IntuitionLabs’ pricing comparison shows that GPT‑5 Mini costs $0.25 per million input tokens and $2 per million output tokens, while Grok 4 Fast costs $0.20 and $0.50 per million input/output tokens—orders of magnitude below premium models.
  • Lower latency and higher throughput: Smaller architectures enable rapid generation. Label Your Data reports that SLMs like Phi‑3 and Mistral 7B deliver 250–200 tokens per second with latencies of 50–100 ms, whereas GPT‑4 produces around 15 tokens per second with 800 ms latency.
  • Local and edge deployment: SLMs can be deployed on laptops, VPC clusters or mobile devices. Clarifai’s Local Runners allow models to run inside your environment without sending data to the cloud, preserving privacy and eliminating per‑token cloud charges. Binadox highlights that local models provide predictable costs, improved latency and customization.
  • Privacy and compliance: Running models locally or in a hybrid architecture keeps data on premises. Clarifai’s hybrid orchestration keeps predictable workloads on‑premises and bursts to the cloud for spikes, reducing cost and improving compliance.

Trade‑offs and limitations (Negative knowledge)

  • Reduced knowledge depth: SLMs have less training data and lower parameter counts, so they may struggle with rare facts or complex multi‑step reasoning. The Clarifai blog notes that SLMs can underperform on deep reasoning tasks compared with larger models.
  • Shorter context windows: Some SLMs have context limits of 32 K tokens (e.g., Qwen 0.6B), though newer models like Phi‑3 mini offer 128 K contexts. Longer contexts still require larger models or specialized architectures.
  • Prompt sensitivity: Smaller models are more sensitive to prompt format and may produce less stable outputs. Techniques like prompt engineering and chain‑of‑thought style cues help mitigate this but demand experience.

Expert insight

“We see enterprises using small models for 80 % of their API calls and reserving large models for complex reasoning. This hybrid workflow cuts compute costs by 70 % while meeting quality targets,” explains a Clarifai solutions architect. “Our customers use our Reasoning Engine for chatbots and local summarization while routing high‑stakes tasks to larger models via compute orchestration.”

Quick summary

Question: Why are small models gaining traction for API developers in 2026?

Summary: Small language models offer significant cost and latency advantages because they contain fewer parameters. Advances in quantization and instruction‑tuning allow SLMs to deliver 10–30× cheaper inference, and pricing for top models has dropped to less than $1 per million tokens. They enable on‑device deployment, reduce data privacy concerns and deliver high throughput, but they may struggle with deep reasoning and have shorter context windows.


Top cost‑efficient small models and their capabilities

Selecting the right SLM requires understanding the competitive landscape. Below is a snapshot of notable models as of 2026, summarizing their size, context limits, pricing and strengths. (Note: prices reflect cost per million input/output tokens.)

Model & provider

Parameters & context

Cost (per 1M tokens)

Strengths & considerations

GPT‑5 Mini

~13B params, 128 K context

$0.25 in / $2 out

Near frontier performance (91 % on AIME math); robust reasoning; moderate latency; available via Clarifai’s API through compute orchestration.

GPT‑5 Nano

~7B params

$0.05 in / $0.40 out

Extremely low cost; good for high‑volume classification and summarization; limited factual knowledge; shorter context.

Claude Haiku 4.5

~10B params

$1 in / $5 out

Balanced performance and safety; strong summarization; higher price than some competitors.

Grok 4 Fast (xAI)

~7B params

$0.20 in / $0.50 out

High throughput; tuned for conversational tasks; lower cost; less accurate on niche domains.

Gemini 3 Flash (Google)

~12B params

$0.50 in / $3 out

Optimized for speed and streaming; good multimodal support; mid‑range pricing.

DeepSeek V3.2‑Exp

~8B params

$0.28 in / $0.42 out

Price halved in late 2025; strong reasoning and coding capabilities; open‑source compatibility; extremely cost‑efficient.

Phi‑3 Mini (Microsoft)

3.8B params, 128 K context

around $0.30 per million

High throughput (~250 tokens/s); good multilingual support; sensitive to prompt format.

Mistral 7B / Mixtral 8×7B

7B and mixture model

$0.25 per million

Popular open‑source; strong coding and reasoning for its size; mixture‑of‑experts variant improves context; context windows of 32–64 K; local deployment friendly.

Gemma (Google)

2B and 7B

Open‑source (Gemma 2B runs on 2 GB GPU)

Good safety alignment; efficient for on‑device tasks; limited reasoning beyond simple tasks.

Qwen 0.6B

0.6B params, 32 K context

Generally free or very low cost

Very small; ideal for classification and routing; limited reasoning and knowledge.

What the numbers mean

  • Cost per million tokens sets the baseline. Economy models like GPT‑5 Nano at $0.05 per million input tokens drive down cost for high‑volume tasks. Premium models like Claude Haiku or Gemini Flash charge up to $5 per million output tokens. Clarifai’s own Reasoning Engine charges $0.16 per million tokens with high throughput.
  • Throughput & latency determine responsiveness. KDnuggets reports that providers like Cerebras and Groq deliver hundreds to thousands of tokens per second; Clarifai’s engine produces 544 tokens/s. For interactive applications like chatbots, throughput above 200 tokens/s yields a smooth experience.
  • Context length affects summarization and retrieval tasks. Newer SLMs such as Phi‑3 and GPT‑5 Mini support 128 K contexts, while earlier models might be limited to 32 K. Large context windows allow summarizing long documents or supporting retrieval‑augmented generation.

Negative knowledge

  • Do not assume small models are universally accurate: They may hallucinate or provide shallow reasoning, especially outside training data. Always test with your domain data.
  • Beware of hidden costs: Some vendors charge separate rates for input and output tokens; output tokens often cost up to 10× more than input, so summarization tasks can become expensive if not managed.
  • Model availability and licensing: Open‑source models may have permissive licenses (e.g., Gemma is Apache 2), but some commercial SLMs restrict usage or require revenue sharing. Verify the license before embedding.

Expert insights

  • “Clients often start with high‑profile models like GPT‑5 Mini, but for classification pipelines we frequently switch to DeepSeek or Grok Fast because their cost per token is significantly lower and their accuracy is sufficient,” says a machine learning engineer at a digital agency.
  • A data scientist at a healthcare startup notes: “By deploying Mixtral 8×7B on Clarifai’s Local Runner, we eliminated cloud egress fees and improved privacy compliance without changing our API calls.”

Quick summary

Question: Which small models are most cost‑efficient for API usage in 2026?

Summary: Models like Grok 4 Fast (≈$0.20/$0.50 per million tokens), GPT‑5 Nano (≈$0.05/$0.40), DeepSeek V3.2‑Exp, and Clarifai’s Reasoning Engine (≈$0.16 for blended input/output) are among the most cost‑efficient. They deliver high throughput and good accuracy for routine tasks. Higher‑priced models (Claude Haiku, Gemini Flash) offer advanced safety and multimodality but cost more. Always weigh context length, throughput, and licensing when selecting.


Selecting the right small model for your API: the SCOPE framework

Choosing a model is not just about price. It requires balancing performance, cost, deployment constraints and future needs. To simplify this process, we introduce the SCOPE framework—a structured decision matrix designed to help developers evaluate and choose small models for API use.

The SCOPE framework

  1. S – Size and memory footprint
  • Evaluate parameter count and memory requirements. A 2B‑parameter model (e.g., Gemma 2B) can run on a 2 GB GPU, whereas 13B models require 16–24 GB memory. Quantization (INT8/4‑bit) can reduce memory by 60–87 %; Clarifai’s compute orchestration supports GPU fractioning to further minimize idle capacity.
  • Consider your hardware: if deploying on mobile or at the edge, choose models under 7 B parameters or use quantized weights.
  • C – Cost per token and licensing
    • Look at the input and output token pricing and whether the vendor bills separately. Evaluate your expected token ratio (e.g., summarization may have high output tokens).
    • Confirm licensing and commercial terms—open‑source models often offer free usage but may lack enterprise support. Clarifai’s platform offers unified billing across models, with budgets and throttling tools.
  • O – Operational constraints and environment
    • Determine where the model will run: cloud, on‑prem, hybrid or edge.
    • For on‑premise or VPC deployment, Clarifai’s Local Runners enable running any model on your own hardware with a single command, preserving data privacy and reducing network latency.
    • In a hybrid architecture, keep predictable workloads on‑prem and burst to the cloud for spikes. Compute orchestration features like autoscaling and GPU fractioning reduce compute costs by over 70 %.
  • P – Performance and accuracy
    • Examine benchmark scores (MMLU, AIME) and tasks like coding or reasoning. GPT‑5 Mini achieves 91 % on AIME and 87 % on internal intelligence measures.
    • Assess throughput and latency metrics. For user‑facing chat, models delivering ≥200 tokens/s will feel responsive.
    • If multilingual or multimodal support is essential, verify that the model supports your required languages or modalities (e.g., Gemini Flash has strong multimodal capabilities).
  • E – Expandability and ecosystem
    • Consider how easily the model can be fine‑tuned or integrated into your pipeline. Clarifai’s compute orchestration allows uploading custom models and mixing them in workflows.
    • Evaluate the ecosystem around the model: support for retrieval‑augmented generation, vector search, or agent frameworks.

    Decision logic (If X → Do Y)

    • If your task is high‑volume summarization with strict cost targets → Choose economy models like GPT‑5 Nano or DeepSeek and apply quantization.
    • If you require multilingual chat with moderate reasoning → Select GPT‑5 Mini or Grok 4 Fast and deploy via Clarifai’s Reasoning Engine for fast throughput.
    • If your data is sensitive or must remain on‑prem → Use open‑source models (e.g., Mixtral 8×7B) and run them via Local Runners or a hybrid cluster.
    • If your application occasionally needs high‑level reasoning → Implement a tiered architecture where most queries go to an SLM and complex ones route to a premium model (covered in the next section).

    Negative knowledge & pitfalls

    • Overfitting to benchmarks: Do not choose a model solely based on headline scores—benchmark differences of 1–2 % are often negligible compared with domain‑specific performance.
    • Ignoring data privacy: Using a cloud‑only API for sensitive data may breach compliance. Evaluate hybrid or local options early.
    • Failing to plan for growth: Under‑estimating context requirements or user traffic can lead to migration headaches later. Choose models with room to grow and an orchestration platform that supports scaling.

    Quick summary

    Question: How can developers systematically choose a small model for their API?

    Summary: Apply the SCOPE framework: weigh Size, Cost, Operational constraints, Performance and Expandability. Base your decision on hardware availability, token pricing, throughput needs, privacy requirements and ecosystem support. Use conditional logic—if you need high‑volume classification and privacy, choose a low‑cost model and deploy it locally; if you need moderate reasoning, consider mid‑tier models via Clarifai’s Reasoning Engine; for complex tasks, adopt a tiered approach.


    Deploying small models: local, edge and hybrid architectures

    Once you’ve selected an SLM, the deployment strategy determines operational cost, latency and compliance. Clarifai offers multiple deployment modalities, each with its own trade‑offs.

    Local and on‑premise deployment

    • Local Runners: Clarifai’s Local Runners let you connect models to Clarifai’s platform on your own laptop, server or air‑gapped network. They provide a consistent API for inference and integration with other models. Setup requires a single command and no custom networking rules.
    • Benefits: Data never leaves your environment, ensuring privacy. Costs become predictable because you pay for hardware and electricity, not per‑token usage. Latency is minimized because inference happens near your data.
    • Implementation: Deploy your selected SLM (e.g., Mixtral 8×7B) on a local GPU. Use quantization to reduce memory. Use Clarifai’s control center to monitor performance and update versions.
    • When not to use: Local deployment requires upfront hardware investment and may lack elasticity for traffic spikes. Avoid it when workloads are highly variable or when you need global access.

    Hybrid cloud and compute orchestration

    • Hybrid architecture: Clarifai’s hybrid orchestration keeps predictable workloads on‑prem and uses cloud for overflow. This reduces cost because you pay only for cloud usage spikes. The architecture also improves compliance by keeping most data local.
    • Compute orchestration: Clarifai’s orchestration layer supports autoscaling, batching and spot instances; it can reduce GPU usage by 70 % or more. The platform accepts any model and deploys it across GPU, CPU or TPU hardware, on any cloud or on‑prem. It handles routing, versioning, reliability (99.999 % uptime) and traffic management.
    • Operational considerations: Set budgets and throttle policies through Clarifai’s control center. Integrate caching and dynamic batching to maximize GPU utilization and reduce per‑request costs. Use FinOps practices—commitment management and rightsizing—to govern spending.

    Edge deployment

    • Edge devices: SLMs can run on mobile devices or IoT hardware using quantized models. Gemma 2B and Qwen 0.6B are ideal because they require only 2–4 GB memory.
    • Use cases: Real‑time voice assistants, privacy‑sensitive monitoring and offline summarization.
    • Constraints: Limited memory and compute mean you must use aggressive quantization and possibly drop context length.

    Negative knowledge & failure scenarios

    • Under‑utilized GPUs: Without proper batching and autoscaling, GPU resources sit idle. Clarifai’s compute orchestration mitigates this by fractioning GPUs and routing requests.
    • Network latency in hybrid setups: Bursting to cloud introduces network overhead; use local or edge strategies for latency‑critical tasks.
    • Version drift: Running models locally requires updating weights and dependencies regularly; Clarifai’s versioning system helps but still demands operational diligence.

    Quick summary

    Question: What deployment strategies are available for small models?

    Summary: You can deploy SLMs locally using Clarifai’s Local Runners to preserve privacy and control costs; hybrid architectures leverage on‑prem clusters for baseline workloads and cloud resources for spikes, with Clarifai’s compute orchestration providing autoscaling, GPU fractioning and unified control; edge deployment brings inference to devices with limited hardware using quantized models. Each approach has trade‑offs in cost, latency and complexity—choose based on data sensitivity, traffic variability and hardware availability.


    Cost optimization strategies with small models and multi‑tier architectures

    Even small models can become expensive when used at scale. Effective cost management combines model selection, routing strategies and FinOps practices.

    Model tiering and routing

    Clarifai’s cost‑control guide suggests classifying models into premium, mid‑tier and economy based on price—premium models cost $15–$75 per million tokens, mid‑tier models $3–$15 and economy models $0.25–$4. Redirecting the majority of queries to economy models can cut costs by 30–70 %.

    S.M.A.R.T. Tiering Matrix (adapted from Clarifai’s S.M.A.R.T. framework)

    • S – Simplicity of task: Determine if the query is simple (classification), moderate (summarization) or complex (analysis).
    • M – Model cost & quality: Map tasks to model tiers. Simple tasks → economy models; moderate tasks → mid‑tier; complex tasks → premium.
    • A – Accuracy tolerance: Define acceptable accuracy thresholds. For tasks requiring >95 % accuracy, use mid‑tier or fallback to premium.
    • R – Routing logic: Implement logic in your API to direct each request to the appropriate model based on predicted complexity.
    • T – Thresholds & fallback: Establish thresholds for when to upgrade to a higher tier if the economy model fails (e.g., if summarization confidence <0.8, reroute to GPT‑5 Mini).

    Operational steps

    1. Classify incoming queries: Use a small classifier or heuristics to assess complexity.
    2. Route to the cheapest adequate model: Economy by default; mid‑tier if classification predicts moderate complexity; premium only when necessary.
    3. Cache and re‑use results: Cache frequent responses to avoid unnecessary inference.
    4. Batch and rate‑limit: Group multiple requests to maximize GPU utilization and implement throttling to control burst traffic.
    5. Monitor and refine: Track costs, latency and quality. Adjust thresholds and routing rules based on real‑world performance.

    FinOps practices for APIs

    • Rightsizing hardware and models: Use quantized models to reduce memory footprint by 60–87 %.
    • Commitment management: Take advantage of reserved instances or spot markets when using cloud GPUs; Clarifai’s orchestration automatically leverages spot GPUs to lower costs.
    • Budgets and throttling: Set per‑project budgets and throttle policies via Clarifai’s control center to avoid runaway costs.
    • Version control and observability: Monitor token utilization and model performance to identify when a smaller model is sufficient.

    Negative knowledge

    • Don’t “over‑save”: Using the cheapest model for every request might harm user experience. Poor accuracy can result in higher downstream costs (manual corrections, reputational damage).
    • Avoid single‑vendor lock‑in: Diversify models across vendors to mitigate outages and pricing changes. Clarifai’s platform is vendor‑agnostic.

    Quick summary

    Question: How can developers control inference costs when using small models?

    Summary: Implement a tiered architecture that routes simple queries to economy models and reserves premium models for complex tasks. Clarifai’s S.M.A.R.T. matrix suggests mapping simplicity, model cost, accuracy requirements, routing logic and thresholds. Combine this with FinOps practices—quantization, autoscaling, budgets and caching—to cut costs by 30–70 % while maintaining quality. Avoid extremes; always balance cost with user experience.


    Emerging trends and future outlook for small models (2026 and beyond)

    The SLM landscape is evolving rapidly. Several trends will shape the next generation of cost‑efficient models.

    Hyper‑efficient quantization and hardware acceleration

    Research on post‑training quantization shows that 4‑bit precision reduces memory footprint by 70 % with minimal quality loss, and 2‑bit quantization may emerge through advanced calibration. Combined with specialized inference hardware (e.g., tensor cores, neuromorphic chips), this will enable models with billions of parameters to run on edge devices.

    Mixture‑of‑experts (MoE) and adaptive routing

    Modern SLMs such as Mixtral 8×7B leverage MoE architectures to dynamically activate only a subset of parameters, improving efficiency. Future APIs will adopt adaptive routing: tasks will trigger only the necessary experts, further lowering cost and latency. Hybrid compute orchestration will automatically allocate GPU fractions to the active experts.

    Coarse‑to‑fine AI pipelines

    Agentic systems will increasingly employ coarse‑to‑fine strategies: a small model performs initial parsing or classification, then a larger model refines the output if needed. This pipeline mirrors the tiering approach described earlier and could be standardized via API frameworks. Clarifai’s reasoning engine already enables chaining models into workflows and integrating your own models.

    Regulatory and ethical considerations

    As AI regulations tighten, running models locally or in regulated regions will become paramount. SLMs enable compliance by keeping data in‑house. At the same time, model providers will need to maintain transparency about training data and safe alignment, creating opportunities for open‑source community models like Gemma and Qwen.

    Emerging players and price dynamics

    Competition among providers like OpenAI, xAI, Google, DeepSeek and open‑source communities continues to drive prices down. IntuitionLabs notes that DeepSeek halved its prices in late 2025 and low‑cost models now offer near frontier performance. This trend will persist, enabling even more cost‑efficient APIs. Expect new entrants from Asia and open‑source ecosystems to release specialized SLMs tailored for programming, languages and multi‑modal tasks.

    Quick summary

    Question: What trends will shape small models in the coming years?

    Summary: Advances in quantization (4‑bit and below), mixture‑of‑experts architectures, adaptive routing and specialized hardware will drive further efficiency. Coarse‑to‑fine pipelines will formalize tiered inference, while regulatory pressure will push more on‑prem and open‑source adoption. Pricing competition will continue to drop costs, democratizing AI even further.


    Frequently asked questions (FAQs)

    What’s the difference between small language models (SLMs) and large language models (LLMs)?

    Answer: The main difference is size: SLMs contain hundreds of millions to about 10 billion parameters, whereas LLMs may exceed 100 billion. SLMs are 10–30× cheaper to run, support local deployment and have lower latency. LLMs offer broader knowledge and deeper reasoning but require more compute and cost.

    Are small models accurate enough for production?

    Answer: Modern SLMs achieve impressive accuracy. GPT‑5 Mini scores 91 % on a challenging math contest, and models like DeepSeek V3.2‑Exp deliver near frontier performance. However, for critical tasks requiring extensive knowledge or nuance, larger models may still outperform. Implementing a tiered architecture ensures complex queries fall back to premium models when necessary.

    How can I run a small model on my own infrastructure?

    Answer: Use Clarifai’s Local Runners to connect a model hosted on your hardware with Clarifai’s API. Download the model (e.g., Mixtral 8×7B), quantize it to fit your GPU or CPU, and deploy it with a single command. You’ll get the same API experience as in the cloud but without sending data off premises.

    Which factors influence the cost of an API call?

    Answer: Costs depend on input and output tokens, with many vendors charging differently for each; model tier, where premium models can be >10× more expensive; deployment environment (local vs cloud); and operational strategy (batching, caching, autoscaling). Using economy models by default and routing complex tasks to higher tiers can reduce costs by 30–70 %.

    How do I decide between on‑prem, hybrid or cloud deployment?

    Answer: Consider data sensitivity, traffic variability, latency requirements and budget. On‑premise is ideal for privacy and stable workloads; hybrid balances cost and elasticity; cloud offers speed of deployment but may incur higher per‑token costs. Clarifai’s compute orchestration lets you mix and match these environments.


    Conclusion

    The rise of small language models has fundamentally changed the economics of AI APIs. With prices as low as $0.05 per million tokens and throughput approaching hundreds of tokens per second, developers can build cost‑efficient, responsive applications without sacrificing quality. By applying the SCOPE framework to choose the right model, deploying through Local Runners or hybrid architectures, and implementing cost‑optimization strategies like tiering and FinOps, organizations can harness the full power of SLMs.

    Clarifai’s platform—offering the Reasoning Engine, Compute Orchestration and Local Runners—simplifies this journey. It lets you combine models, deploy them anywhere, and manage costs with fine‑grained control. As quantization techniques, adaptive routing and mixture‑of‑experts architectures mature, small models will become even more capable. The future belongs to efficient, flexible AI systems that put developers and budgets first.


    NVIDIA and Partners Show That Software-Defined AI-RAN Is the Next Wireless Generation


    AI-RAN is moving from lab to field, showing that a software-defined approach is the only viable way to build future AI-native wireless networks.

    Ahead of Mobile World Congress (MWC), running March 2-5 in Barcelona, NVIDIA and Nokia announced new AI-RAN collaborations with top telecom operators across Europe, Asia and North America, powered by NVIDIA AI-RAN platforms. Industry pioneers T-Mobile U.S., SoftBank and Indosat Ooredoo Hutchison (IOH) passed implementation milestones, taking NVIDIA-powered AI-RAN outdoors and over the air.

    New benchmarking results from partners like SynaXG showed that AI-RAN running on NVIDIA platforms delivers high-speed, carrier-grade performance — meaning extreme reliability — across multiple 5G spectrum bands. And over 20 AI-RAN Alliance demos built on NVIDIA platforms will be showcased at MWC, highlighting how AI is boosting 5G performance and efficiency, and unlocking new edge AI applications.

    All of this represents momentum and convergence toward a common, software-defined foundation that will set the stage for secure, open and AI-native 6G systems.

    AI-RAN Goes From Lab to Live

    Top telecom operators and partners are using NVIDIA platforms to bring AI-RAN to commercial deployment. 

    T-Mobile U.S. demonstrated concurrent AI and RAN processing on NVIDIA AI-RAN platform using Nokia’s CUDA-accelerated RAN software. In T-Mobile’s over-the-air field environment, Nokia’s AirScale massive multiple-input and multiple-output (MIMO) radio in the 3.7GHz band supported commercial devices running applications like video streaming, generative AI and AI-powered video captioning, alongside 5G. 

    SoftBank’s AITRAS live field trial achieved an industry-first, 16-layer massive MIMO using fully software-defined 5G running on NVIDIA’s AI-RAN platform, marking an important technical milestone toward AI-RAN commercialization. 

    IOH has implemented software-defined 5G with Nokia’s vRAN software on NVIDIA AI-RAN platforms, moving from proof of concept to pre-commercial field validation. This milestone was showcased at MWC through Southeast Asia’s first AI-powered 5G call, where AI and network intelligence operated seamlessly to enable secure, real-time cross-border connectivity, including responsive remote control of a robotic dog over the live 5G network. This achievement demonstrates IOH’s readiness to scale AI-native network capabilities and bring intelligent connectivity to communities across Indonesia.

    SynaXG demonstrated fully software-defined AI-RAN using NVIDIA AI Aerial — a suite of accelerated computing platforms, software libraries and tools to build, train, simulate and deploy AI-native wireless networks — running 4G, 5G in both sub-6GHz [FR1] and millimeter wave [FR2] spectrum bands, alongside agentic AI workloads, on a single NVIDIA GH200 server. This marks the world’s first implementation of AI-RAN on FR2 bands.

    SynaXG’s setup activated 20 component carriers with both a centralized unit (CU) and distributed unit (DU) on one platform, achieving a throughput of 36 Gbps and under 10 milliseconds latency. These breakthrough results highlight AI-RAN-based 5G performance as well as seamless orchestration between AI and RAN workloads.

    Tripled Pace of AI-RAN Innovation

    This year’s MWC will see triple the number of AI-RAN innovations over last year, with 26 out of 33 AI-RAN Alliance demos built using NVIDIA AI Aerial and a software-defined architecture.

    Some of these demos include:

    • DeepSig is reinventing how devices “speak” to networks by letting AI learn a smarter signal format at both ends of the link — the communications channel that connects two devices. An AI‑native air interface jointly learns how to best encode and decode signals using neural techniques at the device and base station, removing pilot overheads and adapting to site‑specific channels. Early results on NVIDIA platforms show up to about 2x higher throughput and better spectral and energy efficiency from the same spectrum.
    • SUTD, NVIDIA and partners will show how robots and autonomous vehicles can distribute their “thinking” across the device, edge and cloud — bringing split-inferencing from concept to implementation. By deciding in real time where each AI task runs, the demos prove how AI-RAN can meet tight latency, privacy and coverage service-level agreements to scale physical AI and vision language models through the network edge.
    • zTouch Networks and partners built an AI-RAN orchestration blueprint showing how operators can safely share GPUs across AI and RAN workloads. By using NVIDIA Multi-Instance GPU technology, the blueprint steers resources in real time, maximizing GPU utilization and improving energy management while ensuring RAN quality of service. This is a key step for making multi-tenant AI-RAN solutions ready for commercial use, so operators can turn GPU capacity into revenue.
    • Northeastern University and SoftBank will demonstrate an AI switching solution for NVIDIA AI Aerial that flips seamlessly and without data loss between AI and classic algorithms for channel estimation. This selects, in real time, the best possible processing solution at all times depending on conditions, improving stability and throughput while proving AI can coexist with classical approaches.

    “AI-RAN is emerging as a unifying architecture for future radio networks,” said Alex Choi, chair of the AI-RAN Alliance. “By aligning operators, vendors and researchers around software-defined, GPU-accelerated architectures, we are boosting innovation, validating new concepts quickly and building the foundation for AI-native 6G, now.”

    As intelligence moves into the physical world, autonomous systems such as robots and cars depend on AI-RAN networks to see, sense, reason and act.

    Capgemini is working within Project ULTIMO, a Horizon Europe-funded initiative, to show how AI-RAN can support large-scale autonomous mobility services across European cities. Autonomous shuttles equipped with the NVIDIA Jetson Orin module process sensor data locally, while select video and telemetry streams are sent over 5G to agentic AI applications on NVIDIA AI-RAN servers. These workloads handle scene understanding, incident and safety detection, and accessibility insights at scale, while mission-critical 5G gets priority access to GPU resources.

    A Growing Ecosystem

    A growing ecosystem of partners is forming around NVIDIA-powered AI-RAN platforms, enabling operators to choose from a range of deployment solutions. NVIDIA Aerial RAN Computer (ARC) platforms harness the NVIDIA Grace CPU and a variety of GPUs, providing a high-performance, energy-efficient compute foundation for AI-native RAN infrastructure.

    • Quanta Cloud Technology (QCT) is announcing commercial off-the-shelf AI-RAN products that support NVIDIA ARC platforms and Nokia software, giving operators standardized building blocks for AI-RAN.
    • Supermicro is extending support across the full NVIDIA AI-RAN portfolio, including NVIDIA ARC-Pro and NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs, as well as ARC-Compact systems with Nokia software.
    • WNC has introduced a new AI-optimized indoor and outdoor open radio unit, integrated with NVIDIA AI Aerial Testbed and NVIDIA ARC platforms, that supports 5GA and 6G use cases.
    • Eridan has launched a 4T4R O-RU along with its 2T2R O-RU, which was integrated with NVIDIA AI Aerial, and a DU running on the NVIDIA DGX Spark desktop supercomputer, combining spectrally efficient radios with GPU-based baseband processing to create a powerful and portable outdoor base station.
    • LITEON has completed integration of its sub-6 GHz and millimeter wave radio units with NVIDIA AI Aerial, and has expanded its collaboration with ecosystem partners like Supermicro and SynaXG to accelerate AI-RAN commercialization.

    Laying the Foundation for Open, Secure, AI-Native 6G

    NVIDIA’s latest State of AI in Telecom report showed that the industry is stepping up AI-native RAN and 6G investments — signaling a major intercept ahead of the traditional 6G deployment cycle, with 77% of respondents anticipating a much faster time to deployment of this new AI-native wireless network architecture.

    This latest progress on software-defined AI-RAN is setting the stage for secure, open and AI-native 6G systems.

    NVIDIA has already open sourced NVIDIA Aerial CUDA-accelerated RAN libraries, fueling the pace of AI-RAN innovation. NVIDIA has also now joined the OCUDU (Open CU DU) Ecosystem Foundation, hosted by the Linux Foundation, contributing to open source RAN software development to accelerate research and commercialization for next-generation wireless networks.

    Learn more by meeting NVIDIA and partners at Mobile World Congress. Explore key insights from the State of AI in Telecom survey.

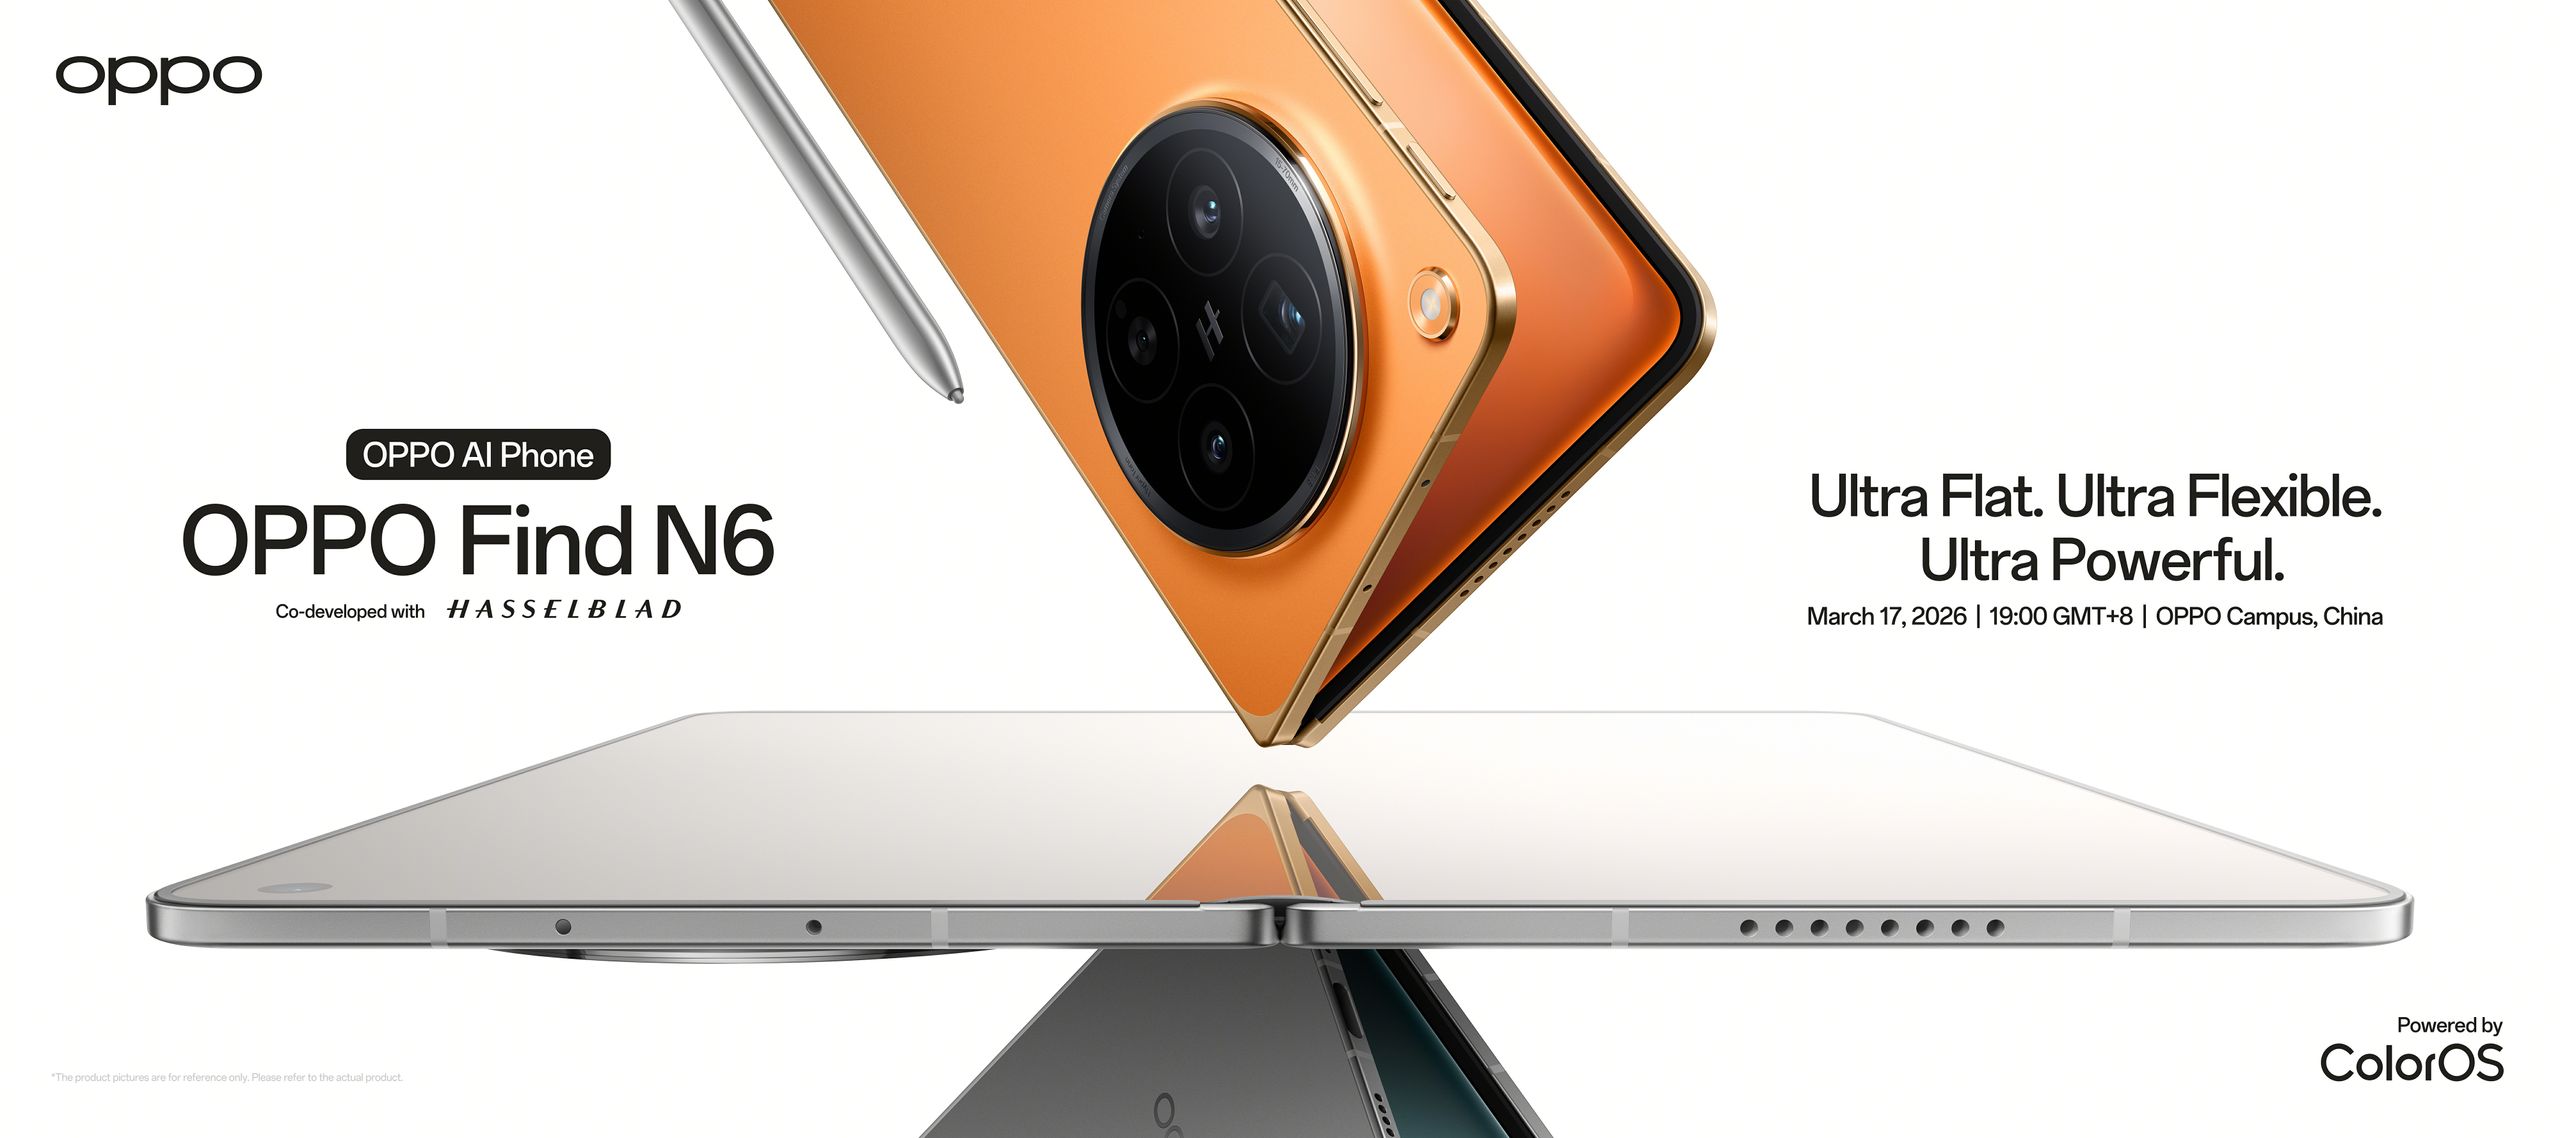
    OPPO Find N6 is launching globally March 17, and I’m very excited about this feature


    OPPO hasn’t put a foot wrong in the last 15 months, and the Find X9 Pro continues to be my favorite Android phone. The brand is switching gears to talk about its foldable plans, with the Find N6 slated to launch globally on March 17. OPPO’s Find N5 is still going strong, and I’m excited to see what the N6 has to deliver.

    While OPPO isn’t sharing too many details at this point, the brand is touting a new Zero-Feel Crease panel as a key feature. If you’ve used a book-style foldable in the past, you’ll know that there’s a visible crease along the middle — there’s no way to avoid that because of the hinge. Well, OPPO says the Find N6 will come with a crease that isn’t noticeable in daily use, and that is a bold claim, one I’ll be putting to the test once I get my hands on the foldable.

    Long-Distance Relocation Without Pausing Your Business


    Long-Distance RelocationLong-Distance Relocation
    Photo by RDNE Stock project

    You can feel the pressure the moment when your lists start growing at the same time. One is your client work, the other is everything you own. Your desk becomes a packing station, and your brain keeps flipping between invoices and bubble wrap. That constant switching is usually what makes a move feel harder than it has to be.

    Relocating while running a home based business gets calmer when you protect the work that pays the bills first. Using a broker like Coastal Moving Services can help coordinate an interstate move by connecting you with FMCSA authorized carriers, which is useful when timing and handling matter. From there, the focus is keeping your operations predictable while the rest of life is in boxes. You are building continuity, not chasing perfection.

    Set Your Business Continuity Plan

    Start with a short list of what cannot break for more than a day. Think client communication, order fulfillment, payroll, and access to your files. Write down your “must run” tasks and the tools each one needs, then circle the tasks tied to revenue. This gives you a clean target when everything else starts competing for attention.

    Next, choose a moving window that respects your business calendar for your long-distance relocation. If you have launches, renewals, or seasonal spikes, move outside that week even if it costs a bit more. Many owners also benefit from setting a “quiet week” where they avoid new projects and focus on delivery only. It is easier to keep promises when you stop stacking fresh ones.

    After that, map your transition in three phases: before pickup, travel days, and first week after arrival. Give each phase one main goal, such as “prep without dropping response time” or “restore the work setup by day two.” If you work with contractors or a VA, define who covers customer replies during the travel gap of a long-distance relocation. A simple responsibility list is often enough to prevent missed messages and duplicate work.

    Finally, set up a tiny, portable office that stays untouched until you arrive. Include your laptop, charger, hotspot, headset, and a power strip, plus one notebook for quick notes. Add spare logins and two factor backup codes in your password manager, not on paper. If your work depends on quick replies, this kit becomes your safety net.

    Build A Realistic Move Inventory

    A long-distance relocation feels chaotic when you pack by rooms instead of by functions. Your office is not a single room, it is a workflow, and the workflow needs to survive the trip. Start an inventory with three groups: “carry with me,” “ship early,” and “ship last.” Keep it lean, and update it in short bursts so it does not become another job.

    Your “carry with me” group should cover the next five business days. Include your main device, backup drive, payment or banking access, and any item you cannot replace quickly. If you do photo or video work, that might also include lenses and storage cards. If you sell products, include the simplest set of packing supplies so you can still ship a few urgent orders.

    Your “ship early” group is anything you can live without now, but you will want fast after you land. That often means spare monitors, a printer, long cables, and non urgent stock. Label these boxes by outcome, not location, like “billing setup” or “shipping station.” Clear labels save you from ripping open ten boxes while a client waits.

    Your “ship last” group is your production gear and core tools. Pack these closer to move day so they stay in use and stay in sight. Photograph high value items, capture serial numbers, and store receipts in one folder. Treat this like basic risk control, because replacement can be slow when you are mid move.

    Choose Legit Moving Support

    Interstate moving is regulated, so verifying roles and registration matters. Confirm who is the carrier and who is the broker, then ask for the details in writing. You can also check basics through FMCSA resources like Protect Your Move when you want a clear view of your options and common pitfalls. That small step helps you avoid mix ups around responsibility and timing.

    Once the company is vetted for your long-distance relocation, focus on the estimate language. Ask what the price assumes about inventory, stairs, distance from truck to door, and packing support. Request the pickup range and delivery range, and ask what happens if the schedule shifts. You are not trying to interrogate anyone, you are removing uncertainty that can break your work week.

    It also helps to ask one practical question that reveals how the process really runs. Who is your point of contact on pickup day, and who updates you during transit. If your business depends on receiving stock or equipment on a tight date, ask how they handle time sensitive deliveries. Clarity here is often what separates a calm move from a stressful one.

    When you compare quotes, compare the structure, not only the final number. Watch for vague line items like “materials” or “labor” with no limits or quantities. Be careful if a company pushes you to pay a large deposit immediately, or avoids written terms. The FTC’s guidance on avoiding scams when hiring a moving company is a good reminder of common warning signs and safer checks.

    Pack Smart For Fewer Lost Work Hours

    Packing is not only about protection, it is also about recovery time. The goal is getting you back to billable work quickly, even if the house is still half unpacked. Pack your work setup in layers, starting with “day one,” then “week one,” then “later.” This prevents the classic problem of having a desk but no cables, or a router but no power strip.

    For electronics, choose simple, consistent habits. Put cables in labeled bags and tape one bag to the box it belongs to. Take quick photos of your current setup, especially where cables and adapters connect. If you need special software or licenses, confirm access before move week so you are not resetting passwords from a hotel room.

    If you ship products, plan for a short shipping pause without going silent. Update your order processing notes, set a temporary handling time, and draft two customer response templates. Many owners keep customer service steady by scheduling emails ahead of time and batching replies twice a day. That rhythm keeps trust intact without keeping you glued to your inbox.

    If you work with paper, treat it like it is fragile equipment. Pack active client files in one sealed bin that stays with you, not on the truck. Scan what you can and store it in a secure cloud folder, with access on your phone. A little redundancy goes a long way when the move schedule changes.

    Protect Client Relationships Through Communication

    Most clients do not mind that you are relocating. They mind surprises, slow replies, and missed commitments. A small communication plan prevents that, even if your week gets messy. Set one “response window” for each day during move week, and keep it consistent.

    Send a short note to active clients a week before the move, if it affects your availability. Keep it plain, and focus on what stays the same, like deadlines and response times. If you need a slower turnaround for two days, say it early and offer an alternative, such as a scheduled call slot. Clear expectations beat long explanations every time.

    If you get leads through your website, create a backup plan for intake. Make sure your contact form goes to two inboxes, or routes to a team member. If you use a phone number for sales, confirm that call forwarding will work during travel during a long-distance relocation. These details are boring, yet they protect revenue while your life is in transit.

    If you want a quick, low effort checklist, use this one:

    • Set daily reply windows and stick to them during move week.
    • Pre write two or three client updates and save them as templates.
    • Keep your portable office kit with you at all times.

    Rebuild Your Work Setup First

    A long-distance relocation is not finished when the truck leaves; it is finished when your business day feels normal again. On day one, aim for internet, power, and one cleared work surface. On day two, aim for your full workflow, including payment access, file access, and basic shipping if you sell products. When those pieces are in place, the rest of the house can catch up later.

    Keep your first week intentionally light if you can. Group calls into blocks so you have long stretches for setup, troubleshooting, and recovery. If you have a team, schedule a short daily check in, then get back to execution. Consistency matters more than intensity during that week.

    Do a quick audit while details are fresh. Compare your inventory list to what arrived, and photograph any damage right away. Keep all paperwork in one folder, including estimates, bills of lading, and receipts. If something feels off, address it quickly while timelines and contacts are still clear.

    A calm business move is not one where every detail goes perfectly. It is one where your essentials stayed close, your clients stayed informed, and your setup returned fast. Protect continuity first, then let the rest of the unpacking happen at a normal pace.

    Find a Home-Based Business to Start-Up >>> Hundreds of Business Listings.

    Tim Cook Says Two Things Matter Most at Apple Ahead of Company’s 50th Anniversary


    CBS Sunday Morning correspondent David Pogue interviewed Apple’s CEO Tim Cook ahead of the company’s 50th anniversary on April 1, 2026.

    Tim Cook Apple Park
    In the interview, Cook revealed the two things that are “essential” to Apple: people and culture.

    “Yes, we have a lot of intellectual property and so forth, and that is important, but it’s people that create that intellectual property,” said Cook. “It’s the culture that creates the innovation with the intellectual property.”

    “I think it’s very difficult to replicate culture,” added Cook. “It takes a long time, because you have to hire the right people. And then those people have to hire the right people, and you have to build a complete organization.”

    That culture then has to be sustained as life changes and technology evolves, he said.

    Cook concluded that Apple is a “party of one.”

    “I think Apple is such a unique place, it’s not possible to replicate it,” he said. “I know a lot of different companies, and I think Apple is just in a party of one.”

    Pogue is the author of the new book Apple: The First 50 Years, set to be released this Tuesday.

    From the book’s official description:

    In time for Apple’s 50th anniversary, CBS Sunday Morning correspondent David Pogue tells the iconic company’s entire life story: how it was born, nearly died, was born again under Steve Jobs, and became, under CEO Tim Cook, the most valuable company in the world. The book features full-color photos, new facts that correct the record and illuminate its subversive culture, and fresh interviews with the legendary figures who shaped Apple into what it is today.

    An excerpt from the book, focused on Steve Jobs and Apple’s “Think Different” campaign, is available on the CBS News website.