Wordle today: The answer and hints for March 12, 2026


Today’s Wordle answer should be easy to solve if you have a good nose.

If you just want to be told today’s word, you can jump to the bottom of this article for today’s Wordle solution revealed. But if you’d rather solve it yourself, keep reading for some clues, tips, and strategies to assist you.

Where did Wordle come from?

Originally created by engineer Josh Wardle as a gift for his partner, Wordle rapidly spread to become an international phenomenon, with thousands of people around the globe playing every day. Alternate Wordle versions created by fans also sprang up, including battle royale Squabble, music identification game Heardle, and variations like Dordle and Quordle that make you guess multiple words at once. 

Wordle eventually became so popular that it was purchased by the New York Times, and TikTok creators even livestream themselves playing.

What’s the best Wordle starting word?

The best Wordle starting word is the one that speaks to you. But if you prefer to be strategic in your approach, we have a few ideas to help you pick a word that might help you find the solution faster. One tip is to select a word that includes at least two different vowels, plus some common consonants like S, T, R, or N.

What happened to the Wordle archive?

The entire archive of past Wordle puzzles was originally available for anyone to enjoy whenever they felt like it, but it was later taken down, with the website’s creator stating it was done at the request of the New York Times. However, the New York Times then rolled out its own Wordle Archive, available only to NYT Games subscribers.

Is Wordle getting harder?

It might feel like Wordle is getting harder, but it actually isn’t any more difficult than when it first began. You can turn on Wordle‘s Hard Mode if you’re after more of a challenge, though.

Here’s a subtle hint for today’s Wordle answer:

One of the five senses.

Does today’s Wordle answer have a double letter?

The letter L appears twice.

Today’s Wordle is a 5-letter word that starts with…

Today’s Wordle starts with the letter S.

The Wordle answer today is…

Get your last guesses in now, because it’s your final chance to solve today’s Wordle before we reveal the solution.

Drumroll please!

The solution to today’s Wordle is…

SMELL

Don’t feel down if you didn’t manage to guess it this time. There will be a new Wordle for you to stretch your brain with tomorrow, and we’ll be back again to guide you with more helpful hints. Are you also playing NYT Strands? See hints and answers for today’s Strands.

Reporting by Chance Townsend, Caitlin Welsh, Sam Haysom, Amanda Yeo, Shannon Connellan, Cecily Mauran, Mike Pearl, and Adam Rosenberg contributed to this article.

If you’re looking for more puzzles, Mashable’s got games now! Check out our games hub for Mahjong, Sudoku, free crossword, and more.

Not the day you’re after? Here’s the solution to yesterday’s Wordle.

Overwatch co-creator Jeff Kaplan on his exit from Activision-Blizzard: ‘It was the biggest f**k you moment I’ve had in may career’


Overwatch co-creator Jeff Kaplan was the public face of Overwatch before he left Activision-Blizzard in 2021. If you were interested in videogames between 2014 and 2021, it’s likely you’ll recognise his face. In a new interview on the Lex Fridman podcast, Kaplan details for the first time how and why he left Activision-Blizzard, and it’s not pretty.

The way Kaplan explains it, the good ship Overwatch started to buckle when unreasonable expectations were placed on the Overwatch League, a hugely hyped esports league founded in 2017 and closed in 2024.

Clarifai vs Other Inference Providers: Groq, Fireworks, Together AI


Introduction

The AI landscape of 2026 is defined less by model training and more by how effectively we serve those models. The industry has learned that inference—the act of deploying a pre‑trained model—is the bottleneck for user experience and budget. The cost and energy footprint of AI is soaring; global data‑centre electricity demand is projected to double to 945 TWh by 2030, and by 2027 nearly 40 % of facilities may hit power limits. These constraints make efficiency and flexibility paramount.

This article pivots the spotlight from a simple Groq vs. Clarifai debate to a broader comparison of leading inference providers, while placing Clarifai—a hardware‑agnostic orchestration platform—at the forefront. We examine how Clarifai’s unified control plane, compute orchestration, and Local Runners stack up against SiliconFlow, Hugging Face, Fireworks AI, Together AI, DeepInfra, Groq and Cerebras. Using metrics such as time‑to‑first‑token (TTFT), throughput and cost, along with decision frameworks like the Inference Metrics Triangle, Speed‑Flexibility Matrix, Scorecard, and Hybrid Inference Ladder, we guide you through the multifaceted choices.

Quick digest:

  • Clarifai offers a hybrid, hardware‑agnostic platform with 313 TPS, 0.27 s latency and the lowest cost in its class. Its compute orchestration spans public cloud, private VPC and on‑prem, and Local Runners expose local models through the same API.
  • SiliconFlow delivers up to 2.3× faster speeds and 32 % lower latency than leading AI clouds, unifying serverless and dedicated endpoints.
  • Hugging Face provides the largest model library with over 500 000 open models, but performance varies by model and hosting configuration.
  • Fireworks AI is engineered for ultra‑fast multimodal inference, offering ~747 TPS and 0.17 s latency at a mid‑range cost.
  • Together AI balances speed (≈917 TPS) and cost with 0.78 s latency, focusing on reliability and scalability.
  • DeepInfra prioritizes affordability, delivering 79–258 TPS with wide latency spread (0.23–1.27 s) and the lowest price.
  • Groq remains the speed specialist with its custom LPU hardware, offering 456 TPS and 0.19 s latency but limited model selection.
  • Cerebras pushes the envelope in wafer‑scale computing, achieving 2 988 TPS with 0.26 s latency for open models, at a higher entry cost.

We will explore why Clarifai stands out through its flexible deployment, cost efficiency and forward‑looking architecture, then compare how the other players suit different workloads.

Understanding inference provider categories

Why multiple categories exist

Inference providers fall into distinct categories because enterprises have varying priorities: some need the lowest possible latency, others need broad model support or strict data sovereignty, and many want the best cost‑performance ratio. The categories include:

  1. Hybrid orchestration platforms (e.g., Clarifai) that abstract infrastructure and deploy models across public cloud, private VPC, on‑prem and local hardware.
  2. Full‑stack AI clouds (SiliconFlow) that bundle inference with training and fine‑tuning, providing unified APIs and proprietary engines.
  3. Open‑source hubs (Hugging Face) that offer vast model libraries and community‑driven tools.
  4. Speed‑optimized platforms (Fireworks AI, Together AI) tuned for low latency and high throughput.
  5. Cost‑focused providers (DeepInfra) that sacrifice some performance for lower prices.
  6. Custom hardware pioneers (Groq, Cerebras) that design chips for deterministic or wafer‑scale inference.

Metrics that matter

To fairly assess these providers, focus on three primary metrics: TTFT (how quickly the first token streams back), throughput (tokens per second after streaming starts), and cost per million tokens. Visualize these metrics using the Inference Metrics Triangle, where each corner represents one metric. No provider excels at all three; the triangle forces trade‑offs between speed, cost and throughput.

Expert insight: In public benchmarks for GPT‑OSS‑120B, Clarifai posts 313 TPS with a 0.27 s latency at $0.16/M tokens. SiliconFlow achieves 2.3× faster inference and 32 % lower latency than leading AI clouds. Fireworks AI reaches 747 TPS with 0.17 s latency. Together AI delivers 917 TPS at 0.78 s latency, while DeepInfra trades performance for cost (79–258 TPS, 0.23–1.27 s). Groq’s LPUs provide 456 TPS with 0.19 s latency, and Cerebras leads throughput with 2 988 TPS.

Where benchmarks mislead

Benchmark charts can be deceiving. A platform may boast thousands of TPS but deliver sluggish TTFT if it prioritizes batching. Similarly, low TTFT alone doesn’t guarantee good user experience if throughput drops under concurrency. Hidden costs such as network egress, premium support, and vendor lock‑in also influence real‑world decisions. Energy per token is emerging as a metric: Groq consumes 1–3 J per token while GPUs consume 10–30 J—critical for energy‑constrained deployments.

Clarifai: Flexible orchestration and cost‑efficient performance

Platform overview

Clarifai positions itself as a hybrid AI orchestration platform that unifies inference across clouds, VPCs, on‑prem and local machines. Its compute orchestration abstracts containerisation, autoscaling and time slicing. A unique feature is the ability to run the same model via public cloud or through a Local Runner, exposing the model on your hardware via Clarifai’s API with a single command. This hardware‑agnostic approach means Clarifai can orchestrate NVIDIA, AMD, Intel or emerging accelerators.

Performance and pricing

Independent benchmarks show Clarifai’s hosted GPT‑OSS‑120B delivering 313 tokens/s throughput with a 0.27 s latency, at a cost of $0.16 per million tokens. While this is slower than specialized hardware providers, it is competitive among GPU platforms, particularly when combined with fractional GPU utilization and autoscaling. Clarifai’s compute orchestration automatically scales resources based on demand, ensuring smooth performance during traffic spikes.

Deployment options

Clarifai offers multiple deployment modes, allowing enterprises to tailor infrastructure to compliance and performance needs:

  1. Shared SaaS: Fully managed serverless environment for curated models.
  2. Dedicated SaaS: Isolated nodes with custom hardware and regional choice.
  3. Self‑managed VPC: Clarifai orchestrates inference inside your cloud account.
  4. Self‑managed on‑premises: Connect your own servers to Clarifai’s control plane.
  5. Multi‑site & full platform: Combine on‑prem and cloud nodes with health‑based routing and run the control plane locally for sovereign clouds.

This range ensures that models can move seamlessly from local prototypes to enterprise production without code changes.

Local Runners: bridging local and cloud

Local Runners enable developers to expose models running on local machines through Clarifai’s API. The process involves selecting a model, downloading weights and choosing a runtime; a single CLI command creates a secure tunnel and registers the model. Strengths include data control, cost savings and the ability to debug and iterate rapidly. Trade‑offs include limited autoscaling, concurrency constraints and the need to secure local infrastructure. Clarifai encourages starting locally and migrating to cloud clusters as traffic grows, forming a Local‑Cloud Decision Ladder:

  1. Data sensitivity: Keep inference local if data cannot leave your environment.
  2. Hardware availability: Use local GPUs if idle; otherwise lean on the cloud.
  3. Traffic predictability: Local suits stable traffic; cloud suits spiky loads.
  4. Latency tolerance: Local inference avoids network hops, reducing TTFT.
  5. Operational complexity: Cloud deployments offload hardware management.

Advanced scheduling & emerging techniques

Clarifai integrates cutting‑edge techniques such as speculative decoding, where a draft model proposes tokens that a larger model verifies, and disaggregated inference, which splits prefill and decode across devices. These innovations can reduce latency by 23 % and increase throughput by 32 %. Smart routing assigns requests to the smallest sufficient model, and caching strategies (exact match, semantic and prefix) cut compute by up to 90 %. Together, these features make Clarifai’s GPU stack rival some custom hardware solutions in cost‑performance.

Strengths, weaknesses and ideal use cases

Strengths:

  • Flexibility & orchestration: Run the same model across SaaS, VPC, on‑prem and local environments with unified API and control plane.
  • Cost efficiency: Low per‑token pricing ($0.16/M tokens) and autoscaling optimize spend.
  • Hybrid deployment: Local Runners and multi‑site routing support privacy and sovereignty requirements.
  • Evolving roadmap: Integration of speculative decoding, disaggregated inference and energy‑aware scheduling.

Weaknesses:

  • Moderate latency: TTFT around 0.27 s means Clarifai may lag in ultra‑interactive experiences.
  • No custom hardware: Performance depends on GPU advancements; doesn’t match specialized chips like Cerebras for throughput.
  • Complexity for beginners: The breadth of deployment options and features may overwhelm new users.

Ideal for: Hybrid deployments, enterprise environments needing on‑prem/VPC compliance, developers seeking cost control and orchestration, and teams who want to scale from local prototyping to production seamlessly.

Quick summary

Clarifai stands out as a flexible orchestrator rather than a hardware manufacturer. It balances performance and cost, offers multiple deployment modes and empowers users to run models locally or in the cloud under a single interface. Advanced scheduling and speculative techniques keep its GPU stack competitive, while Local Runners address privacy and sovereignty.

Major contenders: strengths, weaknesses and target users

SiliconFlow: All‑in‑one AI cloud platform

Overview: SiliconFlow markets itself as an end‑to‑end AI platform with unified inference, fine‑tuning and deployment. In benchmarks, it delivers 2.3× faster inference speeds and 32 % lower latency than leading AI clouds. It offers serverless and dedicated endpoints and a unified OpenAI‑compatible API with smart routing.

Pros: Proprietary optimization engine, full‑stack integration and flexible deployment options. Cons: Learning curve for cloud infrastructure novices; reserved GPU pricing may require upfront commitments. Ideal for: Teams needing a turnkey platform with high speed and integrated fine‑tuning.

Hugging Face: Open‑source model hub

Overview: Hugging Face hosts over 500 000 pre‑trained models and provides APIs for inference, fine‑tuning and hosting. Its transformers library is ubiquitous among developers.

Pros: Massive model variety, active community and flexible hosting (Inference Endpoints and Spaces). Cons: Performance and cost vary widely depending on the selected model and hosting configuration. Ideal for: Researchers and developers needing diverse model choices and community support.

Fireworks AI: Speed‑optimized multimodal inference

Overview: Fireworks AI specialises in ultra‑fast multimodal deployment. The platform uses custom‑optimised hardware and proprietary engines to maintain low latency—around 0.17 s—with 747 TPS throughput. It supports text, image and audio models.

Pros: Industry‑leading inference speed, strong privacy options and multimodal support. Cons: Smaller model selection and higher price for dedicated capacity. Ideal for: Real‑time chatbots, interactive applications and privacy‑sensitive deployments.

Together AI: Balanced throughput and reliability

Overview: Together AI provides reliable GPU deployments for open models such as GPT‑OSS 120B. It emphasizes consistent uptime and predictable performance over pushing extremes.

Performance: In independent tests, Together AI achieved 917 TPS with 0.78 s latency at a cost of $0.26/M tokens.

Pros: Strong reliability, competitive pricing and high throughput. Cons: Latency is higher than specialized platforms; lacks hardware innovation. Ideal for: Production applications needing consistent performance, not necessarily the fastest TTFT.

DeepInfra: Cost‑efficient experiments

Overview: DeepInfra offers a simple, scalable API for large language models and charges $0.10/M tokens, making it the most budget‑friendly option. However, its performance varies: 79–258 TPS and 0.23–1.27 s latency.

Pros: Lowest price, supports streaming and OpenAI compatibility. Cons: Lower reliability (around 68–70 % observed), limited throughput and long tail latencies. Ideal for: Batch inference, prototyping and non‑critical workloads where cost matters more than speed.

Groq: Deterministic custom hardware

Overview: Groq’s Language Processing Unit (LPU) is designed for real‑time inference. It integrates high‑speed on‑chip SRAM and deterministic execution to minimize latency. For GPT‑OSS 120B, the LPU delivers 456 TPS with 0.19 s latency.

Pros: Ultra‑low latency, high throughput per chip, cost‑efficient at scale. Cons: Limited model catalog and proprietary hardware require lock‑in. Ideal for: Real‑time agents, voice assistants and interactive AI experiences requiring deterministic TTFT.

Cerebras: Wafer‑scale performance

Overview: Cerebras invented wafer‑scale computing with its WSE. This architecture enables 2 988 TPS throughput and 0.26 s latency for GPT‑OSS 120B.

Pros: Highest throughput, exceptional energy efficiency and ability to handle massive models. Cons: High entry cost and limited availability for small teams. Ideal for: Research institutions and enterprises with extreme scale requirements.

Comparative table (extended)

Provider TTFT (s) Throughput (TPS) Cost (USD/M tokens) Model Variety Deployment Options Ideal For
Clarifai ~0.27 313 0.16 High: hundreds of OSS models + orchestration SaaS, VPC, on‑prem, local Hybrid & enterprise deployments
SiliconFlow ~0.20 (2.3× faster than baseline) n/a n/a Moderate Serverless, dedicated Teams needing integrated training & inference
Hugging Face Varies Varies Varies 500 000+ models SaaS, spaces Researchers, community
Fireworks AI 0.17 747 0.26 Moderate Cloud, dedicated Real‑time multimodal
Together AI 0.78 917 0.26 High (open models) Cloud Reliable production
DeepInfra 0.23–1.27 79–258 0.10 Moderate Cloud Cost‑sensitive batch
Groq 0.19 456 0.26 Low (select open models) Cloud only Deterministic real‑time
Cerebras 0.26 2 988 0.45 Low Cloud clusters Massive throughput

Note: Some providers do not publicly disclose cost or latency; “n/a” indicates missing data. Actual performance depends on model size and concurrency.

Decision frameworks and reasoning

Speed‑Flexibility Matrix (expanded)

Plot each provider on a 2D plane: the x‑axis represents flexibility (model variety and deployment options), and the y‑axis represents speed (TTFT & throughput).

  • Top‑right (high speed & flexibility): SiliconFlow (fast & integrated), Clarifai (flexible with moderate speed).
  • Top‑left (high speed, low flexibility): Fireworks AI (ultra low latency) and Groq (deterministic custom chip).
  • Mid‑right (moderate speed, high flexibility): Together AI (balanced) and Hugging Face (depending on chosen model).
  • Bottom‑left (low speed & low flexibility): DeepInfra (budget option).
  • Extreme throughput: Cerebras sits above the matrix due to its unmatched TPS but limited accessibility.

This visualization highlights that no provider dominates all dimensions. Providers specializing in speed compromise on model variety and deployment control; those offering high flexibility may sacrifice some speed.

Scorecard methodology

To select a provider, create a Scorecard with criteria such as speed, flexibility, cost, energy efficiency, model variety and deployment control. Weight each criterion according to your project’s priorities, then rate each provider. For example:

Criterion Weight Clarifai SiliconFlow Fireworks AI Together AI DeepInfra Groq Cerebras
Speed (TTFT + TPS) 10 6 9 9 7 3 8 10
Flexibility (models + infra) 8 9 6 6 8 5 3 2
Cost efficiency 7 8 6 5 7 10 5 3
Energy efficiency 6 6 7 6 5 5 9 8
Model variety 5 8 6 5 8 6 2 3
Deployment control 4 10 5 7 6 4 2 2
                 
Weighted Score — 226 210 203 214 178 174 171

In this hypothetical example, Clarifai scores high on flexibility, cost and deployment control, while SiliconFlow leads in speed. The choice depends on how you weight your criteria.

Five‑step decision framework (revisited)

  1. Define your workload: Determine latency requirements, throughput needs, concurrency and whether you need streaming. Include energy constraints and regulatory obligations.
  2. Identify must‑haves: List specific models, compliance requirements and deployment preferences. Clarifai offers VPC and on‑prem; DeepInfra may not.
  3. Benchmark real workloads: Test each provider with your actual prompts to measure TTFT, TPS and cost. Chart them on the Inference Metrics Triangle.
  4. Pilot and tune: Use features like smart routing and caching to optimize performance. Clarifai’s routing assigns requests to small or large models.
  5. Plan redundancy: Employ multi‑provider or multi‑site strategies. Health‑based routing can shift traffic when one provider fails.

Negative knowledge and cautionary tales

  • Assume multi‑provider fallback: Even providers with high reliability suffer outages. Always plan for failover.
  • Beware of egress fees: High throughput can incur significant network costs, especially when streaming results.
  • Don’t ignore small models: Small language models can deliver sub‑100 ms latency and 11× cost savings. They often suffice for tasks like classification and summarization.
  • Avoid vendor lock‑in: Proprietary chips and engines limit future model options. Clarifai and Together AI minimise lock‑in via standard APIs.
  • Be realistic about concurrency: Benchmarks often assume single‑user scenarios. Ensure your provider scales gracefully under concurrent loads.

Emerging trends and forward outlook

Small models and energy efficiency

Small language models (SLMs) ranging from hundreds of millions to about 10 B parameters leverage quantization and selective activation to reduce memory and compute requirements. SLMs deliver sub‑100 ms latency and 11× cost savings. Distillation techniques narrow the reasoning gap between SLMs and larger models. Clarifai supports running SLMs on Local Runners, enabling on‑device inference where power budgets are limited. Energy efficiency is critical: specialized chips like Groq consume 1–3 J per token versus GPUs’ 10–30 J, and on‑device inference uses 15–45 W budgets typical for laptops.

Speculative and disaggregated inference

Speculative inference uses a fast draft model to generate candidate tokens that a larger model verifies, improving throughput and reducing latency. Disaggregated inference splits prefill and decode across different hardware, allowing the memory‑bound decode phase to run on low‑power devices. Experiments show up to 23 % latency reduction and 32 % throughput increase. Clarifai plans to support specifying draft models for speculative decoding, demonstrating its commitment to emerging techniques.

Agentic AI, retrieval and sovereignty

Agentic systems that autonomously call tools require fast inference and secure tool access. Clarifai’s Model Context Protocol (MCP) supports tool discovery and local vector store access. Hybrid deployments combining local storage and cloud inference will become standard. Sovereign clouds and stricter regulations will push more deployments to on‑prem and multi‑site architectures.

Future predictions

  • Hybrid hardware: Expect chips blending deterministic cores with flexible GPU tiles—NVIDIA’s acquisition of Groq hints at such integration.
  • Proliferation of mini models: Providers will release “mini” versions of frontier models by default, enabling on‑device AI.
  • Energy‑aware scheduling: Schedulers will optimize for energy per token, routing traffic to the most power‑efficient hardware.
  • Multimodal expansion: Inference platforms will increasingly support images, video and other modalities, demanding new hardware and software optimizations.
  • Regulation & privacy: Data sovereignty laws will solidify the need for local and multi‑site deployments, making orchestration a key differentiator.

Conclusion

Choosing an inference provider in 2026 requires more nuance than picking the fastest hardware. Clarifai leads with an orchestration‑first approach, offering hybrid deployment, cost efficiency and evolving features like speculative inference. SiliconFlow impresses with proprietary speed and a full‑stack experience. Hugging Face remains unparalleled for model variety. Fireworks AI pushes the envelope on multimodal speed, while Together AI provides reliable, balanced performance. DeepInfra offers a budget option, and custom hardware players like Groq and Cerebras deliver deterministic and wafer‑scale speed at the cost of flexibility.

The Inference Metrics Triangle, Speed‑Flexibility Matrix, Scorecard, Hybrid Inference Ladder and Local‑Cloud Decision Ladder provide structured ways to map your requirements—speed, cost, flexibility, energy and deployment control—to the right provider. With energy constraints and regulatory demands shaping AI’s future, the ability to orchestrate models across diverse environments becomes as important as raw performance. Use the insights here to build robust, efficient and future‑proof AI systems.
The final Trails game will be announced in 2031 and released in 2032, Falcom president confirms, so you have 6 years to catch up on 1000 hours of JRPGs


The final game in the 22-year-old JRPG series Trails will be announced in 2031 and released the following year, Falcom president Toshihiro Kondo has announced.

For the latest print issue of Weekly Famitsu (via Gematsu), Kondo reveals some key details about the future of the Trails series, including the fact that its narrative conclusion has already been decided. He also says the theme song for Trails in the Sky 2nd Chapter, the remake of the second game in the series, is already finished just months after Trails in the Sky 1st Chapter‘s launch, and the plot for The Legend of Heroes: Trails Beyond the Horizon 2 is already written just weeks after Horizon 1 released.

Best Mattress for Back Pain (2026): Saatva, Bear, Helix


Compare Our Top Six Favorite Mattresses for Back Pain

Honorable Mentions

Brooklyn Bedding Aurora Luxe Cooling Mattress for $1,699: If you’re looking for something akin to the Plank Natural that’s firm without being too firm, this is another good pick. It has cooling features, too, which is a nice bonus.

DreamCloud Premiere Hybrid for $1,099: This soft mattress was still supportive. I liked sleeping on it, but it didn’t erase my back pain as much as other mattresses we recommend. Still, it was a nice option if you want support without too much firmness as a side sleeper.

Essentia Tatami Organic Mattress for $3,435: This mattress is made of a really comfortable organic latex support core that has holes for breathability (and to help with cooling), and the active organic foam center helps spinal alignment and contouring support for pressure points. It doesn’t have coils or springs, but it’s still surprisingly supportive.

Leesa Sapira Chill for $1,969: If you’re grappling with whether you want a cooling mattress or a pain-relieving mattress, Leesa’s Sapira Chill is a well-priced option that can do it all. The Sapira Chill is our runner-up in the Best Mattresses guide, thanks to its problem-solving capabilities.

Saatva Memory Foam Hybrid for $1,699: The Saatva Memory Foam Hybrid is marketed as firm, and is designed to support your lower back with cushioning in the center. WIRED contributor Nicole Kinning was a little too short at 5’2″ for the lumbar support, but it could be a good fit for more average-sized folks. There are also cooling properties, but they didn’t stand out compared to other cooling mattresses.

Saatva Solaire for $4,199: If you and your partner want different firmness levels, the Saatva Solaire has a fascinating solution: letting you adjust the firmness with inflatable air chambers and a remote for either side of the bed. There are 50 firmness levels, and WIRED reviewer Divya Viswanathan says her husband prefers a lower setting, around 25, to help with his lower back pain and to relieve pressure, while she prefers a firmer feel, around 35 out of 50.

Nectar Premier for $949: WIRED reviewer Martin Cizmar is a side sleeper who suffers from sciatica back pain from time to time, and he says that this hybrid mattress is a great choice for anyone who wants a softer mattress to sink into while getting plenty of pressure relief and excellent contouring while you sleep.

Plank Firm for $999: WIRED reviewer Adrienne So says it takes a few days to reach its full firmness levels—she thought it was too soft after she initially unboxed it, but it became much firmer after a little more time. She describes the Plank Firm as sleeping on a clean wooden floor (which she loves). It’s entirely foam, and flippable with two different firmness levels on each side.

Plank Firm Luxe for $1,199: I really liked the firm support this mattress offered, and it has a better support system with a center layer of individually encased coils instead of just the firm foam the basic Plank has. It’s flippable, but the softer side is still very firm, and the firmest side is the hardest surface I’ve ever slept on. I did prefer the more nuanced support of the firm Bear Elite and a firmer Helix, and both of those models were more comfortable for both myself as a side sleeper and my back sleeper husband.

Purple Restore Cool Touch for $2,699: WIRED contributor Nicole Kinning says this is the absolute best cooling mattress by a long shot. It’s also got a gridlike gel layer, called GelFlex, that adds extra support and makes it easy to get out of bed in the morning.

WinkBeds The WinkBed for $1,799: WIRED reviewer Julian Chokkattu recommends this mattress for his fellow stomach and back sleepers. There are three levels of firmness. He tried the Luxury Firm and liked that the plush pillow-top also adds a luxe, hotel-like feel to a relatively firm bed.

Wolf 12-Inch Memory Foam Hybrid Medium Firm Mattress for $899: WIRED reviewer Molly Higgins found herself surprisingly impressed with this affordable mattress. She says the medium-firm memory foam hybrid mattress feels much more luxe than its price point suggests, and that individually wrapped coils give great support and help with overall structure, while the top gel foams conform to your body’s curves and aid in pressure relief.

Mattresses to Avoid

While the horrible futon mattress that started my hunt doesn’t exist anymore—hallelujah for that!—there are plenty of other mattresses that have flared up my or other WIRED reviewers’ back pain.

Tempur-Pedic Tempur-Adapt for $2,199: This mattress was super soft and conforming, but it wasn’t supportive whatsoever and had more of a sinking sensation when you laid on it. My right side’s muscle pain was worse after nights on this mattress, and my damaged spine felt distinctly unhappy. My sister also tried sleeping on it, and she described it as “sleeping on an air mattress that is losing air throughout the night.”

Magniflex Magnistretch 12 for $3,699: This Italian-made mattress advertises itself as stretching the spine. It’s endorsed by retired Italian soccer player Giorgio Chiellini and current pro basketballer Stefano Tonut, who plays for the Italian equivalent of the Boston Celtics. Well, the Magniflex definitely does something to the spine, though WIRED reviewer Martin Cizmar found it very unwelcome. He lasted only two nights on the Magnistretch before crying uncle and limping over to the next test mattress. He describes the morning-after sensation as similar to sleeping on a hammock made of chainlink fence.

FAQs

How Does a Mattress Help With Back Pain?

What makes a mattress ideal for solving back pain? A common rule of thumb is to aim for a medium-firm mattress. “A mattress that is medium-firm may be better for people with back pain instead of one that’s soft or firm,” but these are based on low-quality studies, says Sean Mackey. Harvard Health also recommends avoiding both very soft and very hard mattresses if you have back pain.

You’re looking for something that can provide spinal support if your pain originates in your spine, or pressure relief if your pain comes from pressure points you’re sleeping on. Mattress firmness plays a big role, but so does the overall design of the coils, foam layers, and any additional support measures added.

During my testing, I was impressed to find that a firmer mattress really did lead to big improvements in my back pain. I expected a harder surface to cause flare-ups of pain or to even throw my back out of place, which has happened on cheap, hard mattresses before. However, I slept well and woke up without any aches or soreness. While a softer sleep surface was my go-to since I’m a side sleeper, choosing a firmer style of mattress immediately supported my spine better and kept pain away, rather than flaring it up like I assumed.

Mackey also recommends checking in with your own doctor or an occupational therapist. “With chronic conditions, we don’t have a ‘This is the best thing for you,’” he says. He also recommends trialing out a few things while you sleep, whether that’s different pillows or mattresses of different firmnesses. You might also try physical therapy or stretching before bed: Mattress maker Charles P. Rogers has an entire area of its site dedicated to sleeping pain-free. It’s not just about what you’re sleeping on, but how well you’re taking care of yourself before you go to bed too.

I will probably always live with my spine conditions, and there are things that help, like stretching before bed and staying super active during the day. But sleeping on a better mattress is a good first step to staying active and pain-free—at least for the morning.

If you’re hesitant about investing in a new mattress, there’s an easy place to start: a knee pillow. It was one of the first recommendations that Sean Mackey, doctor of neurology, chief of the Division of Stanford Pain Medicine, and past president of the American Academy of Pain Medicine (AAPM), gave me when I asked him about how to reduce pain while you sleep. He explained that one of the sources of pain can be a lack of rachis alignment, or the alignment of your spine. “Generally, you should either be sleeping on your back or putting a pillow or support underneath your knees for spinal alignment,” says Mackey.

As a side sleeper, I went out and tried a few knee pillows designed for side sleepers with my original, crappy foam mattress I’ve been sleeping on for the past five years. Mackey wasn’t kidding—it did help. I was more comfortable and fell asleep faster. I liked both the Pillow Cube Knee Cube (which is discontinued) and the Everlasting Comfort Knee Pillow ($34) for different reasons. The Everlasting has a strap to keep it in place, but it’s nice and small if you don’t want something as bulky as the Pillow Cube in your bed. I did find that the smaller Everlasting was more likely to end up on the floor, though, versus the Pillow Cube’s being easier to relocate and tuck back into my knees in the middle of the night. Both helped with my spinal alignment and reduced my back pain a bit, but I still found switching to a more supportive mattress to be a bigger improvement.

How Does WIRED Test Mattresses for Back Pain?

For mattress testing in general, we sleep on all mattresses for at least a week, if not longer (many of my picks I slept on for closer to a month) depending on how they perform. I previously tested all of my mattresses on an old Article bed frame, and now am testing mattresses on an IKEA Tonstad bed frame. For back pain, I pay attention to my back pain spots the night before and see if they’re better or worse in the morning after a night on this mattress. I also look for pressure relief as a side sleeper (and another pain source) and I ask my back-sleeper husband about his experience and if it created any issues or pain for him that I wouldn’t discover as a side sleeper.

Power up with unlimited access to WIRED. Get best-in-class reporting and exclusive subscriber content that’s too important to ignore. Subscribe Today.

Ray Tracing in Architectural Visualization: Why It’s Essential for Design Firms and Freelance Services


From large-scale massive projects to services of freelance architects offering custom design, communication of designs in a manner that effectively transmits spatial relationships, lighting, materials, and overall ambiance becomes quite important. Ray tracing has totally revolutionized the presentation of architecture, improving the quality of the image and showcasing the capabilities of architectural design services. A result impossible to integrate into architectural visualization before.

As a leading agency connecting design firms with the best freelance 3D visualization, Cad Crowd has learned the ins and outs of 3D and architectural visualization. This article focuses on the significance of ray tracing for architectural visualization and its potential for future projects.


🚀 Table of contents


What is ray tracing?

It is a rendering technique used in architectural visualization to demonstrate the effect of light rays on a specific environment, whether it’s sunny or shady, among other things. From the word ray tracing, it traces paths for rays traveling through a 3D environment, reflecting off surfaces, and scattering in all directions. It is used to generate high-quality images based on very complex behaviors like reflection, refraction, and shadows—a method integral to architectural visualization services.

Unlike traditional rendering, where approximations are used to simulate the lighting behavior, ray tracing traces direct light rays passing through a scene, producing high accuracy results, and may be applied in architectural visualization and details such as natural light play and interplay of shadows or characteristics of materials.

Why is ray tracing needed in an architectural design firm?

Architectural design firms need clearly communicated design ideas, where usually architects illustrate their designs using 2D objects such as drawings or hand-drawn sketches. Designs like these are too simple to represent the design clearly. With ray tracing, architects’ work can now be more dynamically represented with architectural drafting services in 3D visualization and rendering because of its realistic outputs.

This is how ray tracing takes 3D visualization to the next level, with a realistic level that is appropriate for internal decision-making purposes as well as for client presentations. The following are some reasons why it is sure to be a game-changer for architectural design firms:

RELATED: What are architectural 3D visualization costs, service fees & rates for companies?

Ray Tracing in Architectural Visualization

1. Photorealistic visualization

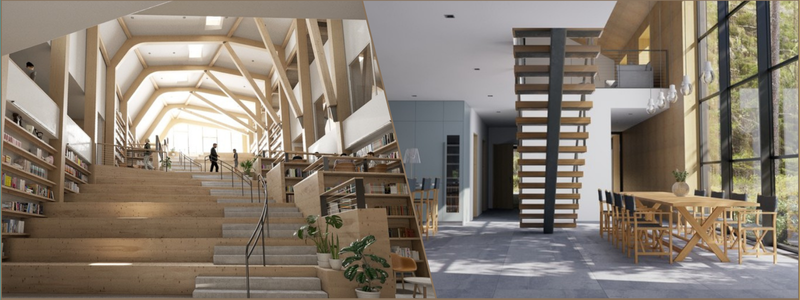
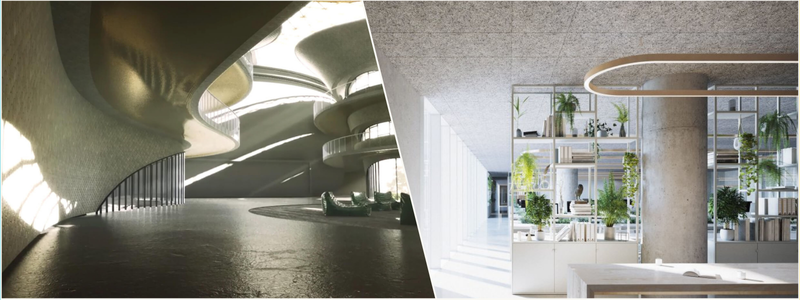
Ray tracing comes with an unmatched realistic rendering, which is used for presenting architectural designs and is a key part of CAD design services. It enables architects to show the geometrical interpretation of their designs and how they will look in real life. For instance, how much light will pass through the windows, what the reflection of the wood, glass, or stone might look like, and where the shadows will fall inside a room. This very important thing is to present designs before clients because that gives people an idea of how the final product looks.

2. Better representation of materials

Materials often play a crucial role in design and thus should be represented accurately. Ray tracing allows precise approximations of glossiness, transparency, roughness, and even reflection properties. For example, the behavior of light, when it bounces off a shiny marble floor vs a concrete matte floor, is different. These functions of ray tracing make the design more helpful in presenting the actual design, therefore affecting decision-making for architects and clients.

RELATED: All you need to know about 3D visualization for architectural design and CGI projects

3. Accurate lighting simulation 

The lighting factor of architectural design sets the mood and functionality of a place, with a strong association with energy efficiency. Ray tracing simulates real light, including direct, indirect, or reflected light, and simulates accurate lighting analysis needed in studying the effect of space from dawn till dusk, as well as how lighting in the space will be performed using 3D rendering services. Whether it is the display of how sunlight will illuminate a room in the morning or how artificial lights will brighten a corridor during nighttime.

4. Design iteration and decision-making

Trying different design options and customizing them in real-time allows the designer to receive instant feedback about material and lighting object placement, which can be used in optimizing the whole design process.

RELATED: Techniques for 3D architectural visualizations and tips for your services firm

Why freelance services should use ray tracing

Freelancers and Professional designers can handle everything from innovative design to technical work. Even if the firm is not large in size, freelancers also gain experience with the use of ray tracing because of its ability to render photorealistic visualizations without requiring large infrastructure.

1. Leveling the playing field

Freelancers, as independent designers, have the chance to be on equal footing with the use of ray tracing and CAD design services. However, freelancers need to invest in high-quality hardware and software to be able to compete with large firms that have the budget to generate realistic visualizations and advanced effects.

2. Broader impressive portfolio and marketing

Ray Tracing in Architectural Visualization

A freelancer’s portfolio is his most prized possession. With the aid of ray tracing-based high-quality renderings, there can be a big difference in making a portfolio that may impress the clients you are marketing to. Whether marketing or pitching to a future client, if you make your visualizations photo-realistic, this changes the game significantly in terms of attracting new business.

RELATED: 5 types of 3D visualization used by architectural design firms for CGI projects

3. Improved client communication

It enables freelancers to produce final product designs similar to those of established design firms, which can help enlighten clients on the intended result. Ray tracing also helps minimize misunderstandings about designs, leading to fewer design alterations before the end product. With this, a more satisfactory client response is achieved by leveraging architectural CAD services.

4. Improved cost estimate

Ray tracing allows freelancers to give more precise estimates of the costs involved in a certain project. This is because freelancers can simulate the interaction between the light and material with a space, therefore giving them an idea as to whether there are some materials or changes in design that may be required to be included in the budget. Such a head-of-time study may save them more hours and money, thus helping the freelancer provide cost estimations upfront with a higher degree of accuracy.

5. Diversity in services

Architectural visualization freelancers who would apply ray tracing technology can offer much more extensive services by integrating 3D animation services. Freelancers shall be able to offer further services like voluminous 3D renderings that create virtual tours or even interactive walkthroughs, which add value to their service. Thus, they increase and diversify their business prospects and can serve all kinds of clients, from real estate developers and architects to interior designers and the like.

Future of ray tracing in architectural visualization

The future of ray tracing in architectural visualization is endless. The ability to simulate real-world lighting and materials with increasingly high accuracy means rendering can achieve photorealism even better in the future.  Furthermore, ray tracing will still be used in the design process, using improved augmented (AR) and virtual reality (VR) to achieve immersive architectural experiences. Design firms, freelancing professionals, and even other professionals will continue with this technology to push the bounds of what can be accomplished in architectural visualization.

RELATED: What is architectural visualization and why architectural rendering services use it

How Cad Crowd Can Help

Architectural visualization, which was once a sketchy guess, is now revolutionized by ray tracing to become a very accurate, photorealistic, and worthwhile tool for every design firm and freelancer. The incredibly detailed mimicking of the way light behaves, interacts with materials, and computes space makes this tool indispensable in the design process.

Ray tracing in architectural visualization has now become an integral tool for design firms and freelance services. Here at Cad Crowd, we can help you find the best expert for you if you wish to set yourself apart from your competitors. Don’t hesitate to reach out to us, and we will be more than happy to help. Get a free quote today. 

author avatar

MacKenzie Brown is the founder and CEO of Cad Crowd. With over 18 years of experience in launching and scaling platforms specializing in CAD services, product design, manufacturing, hardware, and software development, MacKenzie is a recognized authority in the engineering industry. Under his leadership, Cad Crowd serves esteemed clients like NASA, JPL, the U.S. Navy, and Fortune 500 companies, empowering innovators with access to high-quality design and engineering talent.

Connect with me: LinkedIn ✦ X ✦ Cad Crowd

All Slay The Spire 2 Bosses


For those who loved the original, Slay The Spire 2 offers more of the same card-collecting, monster-slaying action. Some of the gameplay hits a similar note, but with a new tower to scale, which also means there are a whole host of new bosses to overcome on each floor, each with their own tactics that will stretch even the most robust builds.

During the first phase of early access, there are two first acts, one second act, and one third act available to play. This means that there are 12 bosses in total for you to fight, of which you’ll fight three at a time. However, given that this is a Roguelike game with random perks, classes, and cards in every run, you’ll probably want to know ahead of time what the best ways to deal with them are. A big part of this is the cards, classes, and perks you’ll earn by unlocking the Slay The Spire 2 Epochs, with some of the stuff hidden behind these goals being essential to making even the toughest boss battle far easier.

Vantom (Act 1 Overgrowth)

  • Found in: Act 1 Overgrowth
  • Enemies: Vantom (173 HP)

The Vantom has nine charges of Slippery at the start of the fight. For each hit, one charge is spent, but you only deal one point of damage. Its tail will also slowly rise up and over your character, doing one or two attacks each turn. When it dangles above you like the Sword of Damocles, it has a huge boost to the amount of damage it deals. It also adds three Wounded status cards to your deck, which are unplayable and only serve to clog up your hand. It then buffs its strength before starting the cycle again.

The Kin

  • Found in: Act 1 Overgrowth
  • Enemies: Kin Priest (190 HP), Kin Follower x2 (58/59 HP)

The Kin Followers will buff their strength and attack, while the Kin Priest simultaneously attacks and debuffs you with Frail or Weak, or buffs its own strength. It’s best to try to kill the followers first, as they have lower HP, but still deal a similar amount of damage with their melee attacks. That said, if you manage to kill the Kin Priest first, the Kin Followers will flee as they are minions, so it depends on whether you think you can withstand the Followers’ attacks.

Ceremonial Beast

  • Found in: Act 1 Overgrowth
  • Enemies: Ceremonial Beast (252 HP)

At the start of the fight, the Ceremonial Beast will use Plow. This increases its attack by two every turn, but will leave it vulnerable to being stunned when its health reaches 150 or below. Once it reaches this threshold, it also loses its health. After its turn being stunned, it will alternate between attacking and trying to debuff with the Ringing effect, which means you can only play one card per turn. Its attacks in this phase are weaker, but so is the potential for you to defend against them, so hit it as hard as you can while you’re able to.

Waterfall Giant

  • Found in: Act 1 Underdock
  • Enemies: Waterfall Giant (250 HP)

At the beginning of the fight, the Waterfall Giant will buff itself with Steam Eruption, which adds damage it will deal to you when you kill it. The next turn, it deals damage, casts a Weak debuff on you, and a strength buff on itself, increasing the Steam Eruption damage. It can also heal. When you reduce it to 0 HP, you have one turn to surpass the defensive requirements before it blows up.

Soul Fysh

  • Found in: Act 1 Underdock
  • Enemies: Soul Fysh (211 HP)

The Soul Fysh begins by adding a copy of Beckon to your deck and discard piles, respectively. If they are in your hand at the end of your turn, you lose six health. Thankfully, you can pay one of any resource to play it, but it stays in your deck until the end of the fight. As the fight progresses, it’ll buff itself with the Intangible stat buff, which reduces all damage taken and HP loss to one. It also attacks, casts the Vulnerable debuff, and adds more Beckons to the draw and discard piles.

Lagavulin Matriarch

  • Found in: Act 1 Underdock
  • Enemies: Lagavulin Matriarch (222 HP)

Lagavulin Matriarch starts the fight asleep with 12 armor. If you eliminate her armor while asleep, she will be stunned for the turn. After that, she will attack regularly. Occasionally, she’ll shore up her defences, then apply debuffs to decrease your strength and dexterity, while also buffing her own strength. If you know you’re up against this boss, your best bet is to focus on poison, doom, and other status ailments that aren’t affected by strength or dexterity.

The Insatiable

  • Found in: Act 2 Hive
  • Enemies: The Insatiable (321 HP)

During the first turn, it casts Sandpit. This will start a countdown, and in 4 turns, you die. That said, it will still attack you every turn, but you can extend this countdown timer with the Frantic Escape cards it adds to your deck. However, each copy of Frantic Escape increases the cost to play it by one whenever you use it. You’re essentially racing to dish out enough damage before it eats you, while also micromanaging remaining turns and so forth. Thankfully, The Insatiable doesn’t really do anything else in the fight, but its high health pool is problematic.

Knowledge Demon

  • Found in: Act 2 Hive
  • Enemies: Knowledge Demon (379 HP)

Whenever the Knowledge Demon casts a debuff on you during the fight, including the very first turn, it will give you a choice between two negative effects.

  • Disintegration: At the end of your turn, take damage (this is always an option and increases by 1 damage each time it appears)
  • Mind Rot: Draw 1 fewer card each turn.
  • Sloth: You cannot play more than 3 cards each turn.
  • Waste Away: Gain 1 less primary resource per turn.

In addition to this effect, the Knowledge Demon can buff its attacks, hit relatively hard, and even heal itself in a pinch. You want to have either a heavily defensive or a brutally offensive strategy with plenty of focus. Combos that do one thing incredibly well are the key to overcoming this fight, whether it’s the Sinner with poison strats or a Necrobinder Doom deck.

Kaiser Crab

  • Found in: Act 2 Hive
  • Enemies: Crusher (199 HP), Rocket (189 HP)

This hulking monstrosity has two pincers, with the Rocket (right) one being able to dish out major damage. Both claws can deal extra damage with back attacks, and they gain five additional strength and 99 block if the other claw dies. It sounds scary, but as it only lasts that turn, all it really means is that it’s unlikely you’ll kill both claws in the same turn.

When Rocket uses its launching attack, it will not attack the following turn, giving you time to breathe. The Crusher (left) is more tanky, as it’s able to buff its defense, so focus on Rocket first. Moves that target both claws are ideal as the fight will go quicker, but the Rocket has the more powerful attacks, so it should be dealt with first. Once both claws are dead, the Kaiser Crab in the background will flee, giving you the victory.

The Queen

  • Found in: Act 3 Glory
  • Enemies: Queen (400 HP), Torch Head Amalgam (199 HP)

The Queen can add Afflictions to your cards, which are debuffs in addition to your card’s standard effect. In this case, she inflicts Chains of Binding, which gives Bound to the first three cards you draw, which restricts you to only being able to use one of the three that turn. This is not permanent, as the effect disappears at the end of the turn. She also inflicts 99 Frail, 99 Vulnerable, and 99 Weak as a debuff, and bolsters her own strength and defense.

The Torch Head Amalgam is a minion and will flee once the Queen dies, but it’s the primary damage dealer, able to inflict up to three hits at a time. It’s not worth focusing on the Queen as the Amalgam is likely smacking you around, so try to mitigate its attack power where possible and take it down first, before focusing on the Queen.

Doormaker

  • Found in: Act 3 Glory
  • Enemies: Doormaker (489 HP), Door (155+ HP)

At the start, you’ll find only the Door enemy. It will hit hard and increase its strength on its turn. Upon dying, the Doormaker will appear stunned on the turn it arrives. It will then hit once with a powerful melee attack, before fleeing back inside the door after dishing out another heavy blow and buffing the door. Every time the Doormaker flees, the max HP of the Door it leaves behind increases by 20 points, so it’ll be tougher to break each time.

Test Subject #C8

  • Found in: Act 3 Glory
  • Enemies: Test Subject #C8 (100 HP, 200 HP, 300 HP)

The low HP you see at first is, rather predictably, deceptive. Test Subject #C8 has the Adaptable ability, an annoying perk that enables it to revive itself, coming back even stronger each time. In the first phase, it also has Enrage, which makes it gain two strength every time you play a Skill-type card, while also attacking and inflicting the Vulnerable debuff.

During the second phase, it replaces Enraged with the Painful Stabs ability, which adds Wound cards every time you get hit by unblocked damage. It will also hit harder, potentially multiple times in a turn, but aside from an increased health pool, the strategy is the same.

In the third phase, you see Adaptable and Painful Stabs phase out, but in its place, it gets Nemesis, a disgustingly powerful ability that grants it Intangible every other turn. This reduces all damage done to it by an attack to 1 HP while it’s active. This slows you down considerably and also hinders the potency of effects such as poison. In addition to the usual buffing strength and attacking, it also adds Burn cards to your discard pile, which are unplayable cards that each deal two damage if in your hand at the end of your turn.

Anduril snaps up space surveillance firm ExoAnalytic Solutions


The first step to fighting a war in space is knowing what’s happening tens of thousands of miles above the planet. Toward that end, defense tech darling Anduril is buying boutique data firm ExoAnalytic Solutions.

ExoAnalytic operates a network of 400 telescopes around the world, which it uses to track spacecraft in high orbits above the planet. The company’s engineers develop software that converts those observations into situational awareness tools for U.S. national security agencies watching adversary spacecraft and coordinating American assets on orbit.

“This is a company we’ve been working with closely for the last several years on a number of programs, and they are experts in space domain awareness and missile defense,” Anduril VP of engineering Gokul Subramanian told reporters. “We believe the [Department of Defense] deserves the best catalog of everything going on in space.”

The privately-held companies did not disclose the terms of the deal. Anduril is in the process of raising a $4 billion round from investors Thrive Capital and Andreessen Horowitz, Reuters reported last week.

ExoAnalytics will be directly integrated into Anduril, not run as a separate subsidiary, though Subramanian said it would continue to serve existing and future outside customers. Currently, Anduril has 120 employees focused on space defense, a number that will more than double with the addition of 130 ExoAnalytics employees.

The company’s technology could help Anduril win government contracts supporting Golden Dome, the missile defense system that the US Congress has appropriated billions of dollars to build. That system is expected to include thousands of satellites to track and target enemy missiles, and maintaining real-time awareness and coordination among them will be a heavy lift.

Anduril is planning to launch three spacecraft this year as internally-funded R&D projects that will draw on capabilities gained in the acquisition. Subramanian said ExoAnalytic’s experience processing space data would be used in an infrared tracking satellite it plans to launch this year in partnership with Apex Space. The space tracking data will be used to execute two missions in high orbit expected to launch this year in partnerships with Impulse Space and Argo Space, respectively.

Techcrunch event

San Francisco, CA
|
October 13-15, 2026

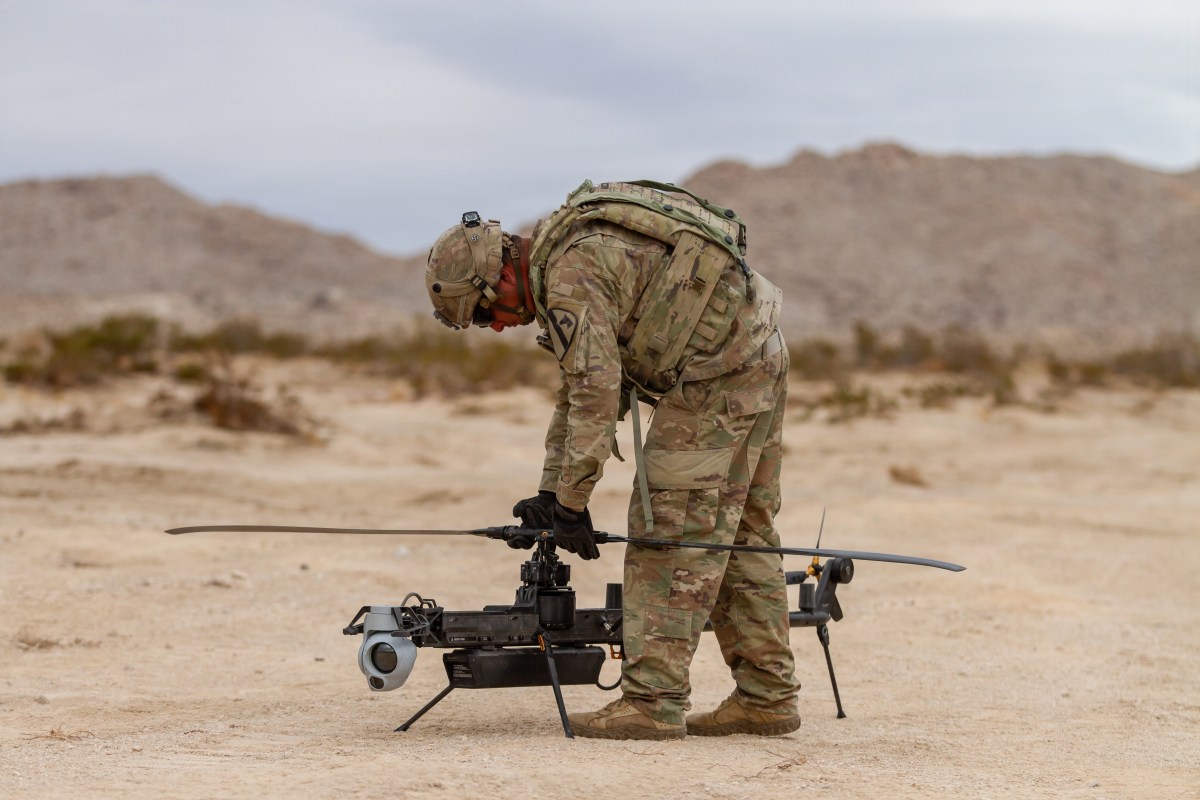
There’s another potential angle to the acquisition — the machine vision algorithms ExoAnalytic has developed to spot satellites in orbit are also useful for interceptors trying to track and engage with incoming threats. Anduril received a contract from the Pentagon in late 2025 to begin developing a space-based missile interceptor.

ExoAnalytic was founded in 2008 to adapt missile defense sensor technology to track spacecraft in orbit after U.S. military officials called for new and better ways to understand what was happening in space, CEO Doug Hendrix said in a 2024 interview. The company’s early growth was funded by grants and contracts from the federal government, including $26 million in SBIR grants since 2010.

U.S. Space Force officials have expressed deep concern about Chinese and Russian spacecraft that fly closely alongside American and European satellites, where they could potentially intercept communications or damage the satellite with electronic or other weapons.

“Two years ago, an [U.S. commander in the Pacific told] me that the fleet cannot leave the port without the space layer being secured,” Subramanian said. “We’ve been on a mission for the last several years to figure out how to be a part of that solution.”

How Tradelines and Credit Score Strategies Can Boost Credit Fast


Tradelines Can Boost Your Credit ScoreTradelines Can Boost Your Credit Score
Deposit Photos

If you’ve been working on improving your credit score, you’ve probably come across the term “tradelines” at some point. Maybe you brushed past it, thinking it was just another complicated financial term. But here’s the thing: understanding tradelines could actually be the key to giving your credit score the boost it desperately needs.

Let me break it down for you in plain English, because this topic doesn’t have to be as confusing as some people make it sound.

What Exactly Is a Tradeline?

First things first. A tradeline is simply any account that appears on your credit report. Yep, that’s it. Your credit card, car loan, mortgage, student loan, and even that store credit card you opened to get 15% off at checkout? Those are all tradelines.

Every time you open a line of credit, it becomes a tradeline on your credit report. The credit bureaus (Equifax, Experian, and TransUnion) collect information about each of these accounts and use that data to calculate your credit score.

Now, when people talk about using tradelines to boost credit scores quickly, they’re usually referring to something more specific: authorized user tradelines. This is where things get interesting.

The Authorized User Strategy

Here’s how it works. Someone with an established credit card account that has a solid payment history can add you as an authorized user. When they do this, that account’s history often gets reported on your credit report too. You get the benefit of their positive credit history without actually being responsible for the account.

Think of it like borrowing someone’s good reputation. If they’ve been making on-time payments for years and keeping their balance low, that positive behavior can reflect on your credit report once you’re added as an authorized user.

This isn’t some shady loophole, by the way. It’s a perfectly legal practice that’s been around for decades. Parents often add their kids as authorized users to help them build credit. Spouses do it for each other. The credit scoring models recognize authorized user accounts because they demonstrate that someone with good credit trusts you enough to add you to their account.

Why Tradelines Can Work So Fast

Unlike other credit-building strategies that take months or even years to show results, tradelines can impact your credit score relatively quickly. Sometimes within 30 to 45 days, you might see a noticeable change.

Why the speed? Because you’re essentially piggybacking on someone else’s credit history. Instead of waiting years to build up a perfect payment history yourself, you’re getting credit for an account that already has that history.

The impact can be especially dramatic if you have a thin credit file (meaning not many accounts) or if you’re recovering from past credit mistakes. Adding a tradeline with a long history of on-time payments and low utilization can shift the overall picture that your credit report paints.

What Makes a Good Tradeline?

Not all tradelines are created equal. If you’re considering this strategy, here’s what you want to look for:

Age matters. Older accounts are better. A credit card that’s been open for ten years carries more weight than one that’s only been around for six months. The age of your credit history makes up about 15% of your FICO score, so this isn’t a small detail.

Payment history is crucial. The whole point is to benefit from positive payment history, so you want an account with a spotless record of on-time payments. Even one late payment can drag down the value of that tradeline.

Low utilization is key. Utilization refers to how much of the available credit is being used. An account that has a $10,000 limit but only carries a $500 balance (5% utilization) looks much better than one that’s maxed out. Lower is always better here.

Higher credit limits help. Bigger credit limits can improve your overall credit utilization ratio, which is a major factor in your credit score. An account with a $20,000 limit is generally more valuable than one with a $2,000 limit.

Things to Keep in Mind

While tradelines can be powerful, they’re not magic. You can’t just add a tradeline and expect all your credit problems to disappear overnight.

If you have recent late payments, collections, or other negative marks on your report, a tradeline can help balance things out, but it won’t erase those issues. Think of it as one tool in your credit-building toolbox, not the only tool.

Also, the credit scoring models have gotten smarter over the years. They can sometimes distinguish between accounts where you’re genuinely responsible for payment versus ones where you’re just an authorized user. That said, authorized user accounts still carry weight, especially with FICO scoring models.

Is This Right for You?

Tradelines make the most sense for specific situations. Maybe you’re trying to qualify for a mortgage and you’re just a few points short of getting the best interest rate. Or perhaps you have a limited credit history and need to build it up faster than the traditional methods allow.

On the other hand, if you’re dealing with serious credit issues like bankruptcy or multiple charge-offs, you might need a more comprehensive credit repair strategy. Tradelines can help, but they’re not a substitute for addressing underlying financial problems.

The Bottom Line

Adding tradelines to your credit report can genuinely help boost your score faster than building credit from scratch on your own. It’s a legitimate strategy that takes advantage of how credit scoring works.

That said, approach it wisely. Make sure you understand what you’re getting, do your research, and remember that building good credit is ultimately about developing solid financial habits. Tradelines can give you a boost, but maintaining that improved score means managing your own accounts responsibly going forward.

Your credit score affects everything from the interest rates you pay to whether you get approved for that apartment you want. If tradelines can help you reach your goals faster, they’re definitely worth considering as part of your overall financial strategy.

Find a Home-Based Business to Start-Up >>> Hundreds of Business Listings.

Do You Have What It Takes to Be ‘Future Chief of Police’ of Starbase, Texas?


Does “protecting a commercial spaceport environment,” along with “critical infrastructure and high-value technology assets,” in a community “shaped by aerospace activity, coastal ecology, and a pioneering spirit of exploration” sound like your dream job? Well why not apply to be the “future chief of police” of Elon Musk’s company town in Texas?

As noted in a story last month on ValleyCentral.com, which is affiliated with Brownsville, Texas area TV news station KGBT, the city of Starbase (yes, it’s a real, incorporated city) approved an ordinance (yes, it has the authority to make laws) establishing a municipal police department. That will include a chief of police and eight officers, with that chief, according to ValleyCentral, elected by the city’s commission.

To that end, apparently, the city just published a job listing seeking applicants for a job titled “Public Safety Director / Future Chief of Police.” The rather puzzling hybrid title may stem from the sheer speed at which the institutional trappings of a city are being assembled in Starbase. The city was incorporated about ten months ago, has a mayor, and will be holding an election on May 2 of this year according to its website.

ValleyCentral makes it sound like policing is a somewhat urgent matter in Starbase because a $3.5 million contract with the Cameron County Sheriff fell through. What were meant to be five-year positions as Starbase-based deputies weren’t appealing to potential recruits. City Administrator Kent Myers told ValleyCentral “We didn’t have a lot of success in finding deputies through the county, so we decided to change direction.”

The job ad says this position will involve creating a “future-ready workforce” that will prioritize, “Integrating advanced technology and analytics into operations.” Starbase’s ideal applicant, the ad says, is a “visionary, ethical, and innovative leader with unquestioned integrity.”

But that ideal candidate will also “thrive in a startup-like environment.”

As for what the sociological picture looks like in the area for someone considering being top cop there, the first thing to keep in mind is that it’s a short drive from the Mexican border where, as of 2026, drug trafficking remains an issue of concern at the federal level. And according to a report from 2023, Cameron County was on the list of the 45 counties (out of 254 counties total) in Texas considered to be in poverty.

Closer to Starbase, there has been considerable agitation over SpaceX’s control of an ostensibly public beach, and a statue of Elon Musk in the area was vandalized last year. So social unrest due to dislike of SpaceX and Elon Musk seem like potential areas of concern.

But it’s presumptuous to try and paint a picture of the crime situation in Starbase because it’s in many ways still just a construction site. The population was about 500 as of last year, which is the approximate standing capacity of a Cheesecake Factory. And the infrastructure to support a police department isn’t even in place yet in Starbase. TechCrunch noticed some government filings last month showing that the city will likely soon have a courthouse. Common sense-wise, it stands to reason that a jail will soon follow.