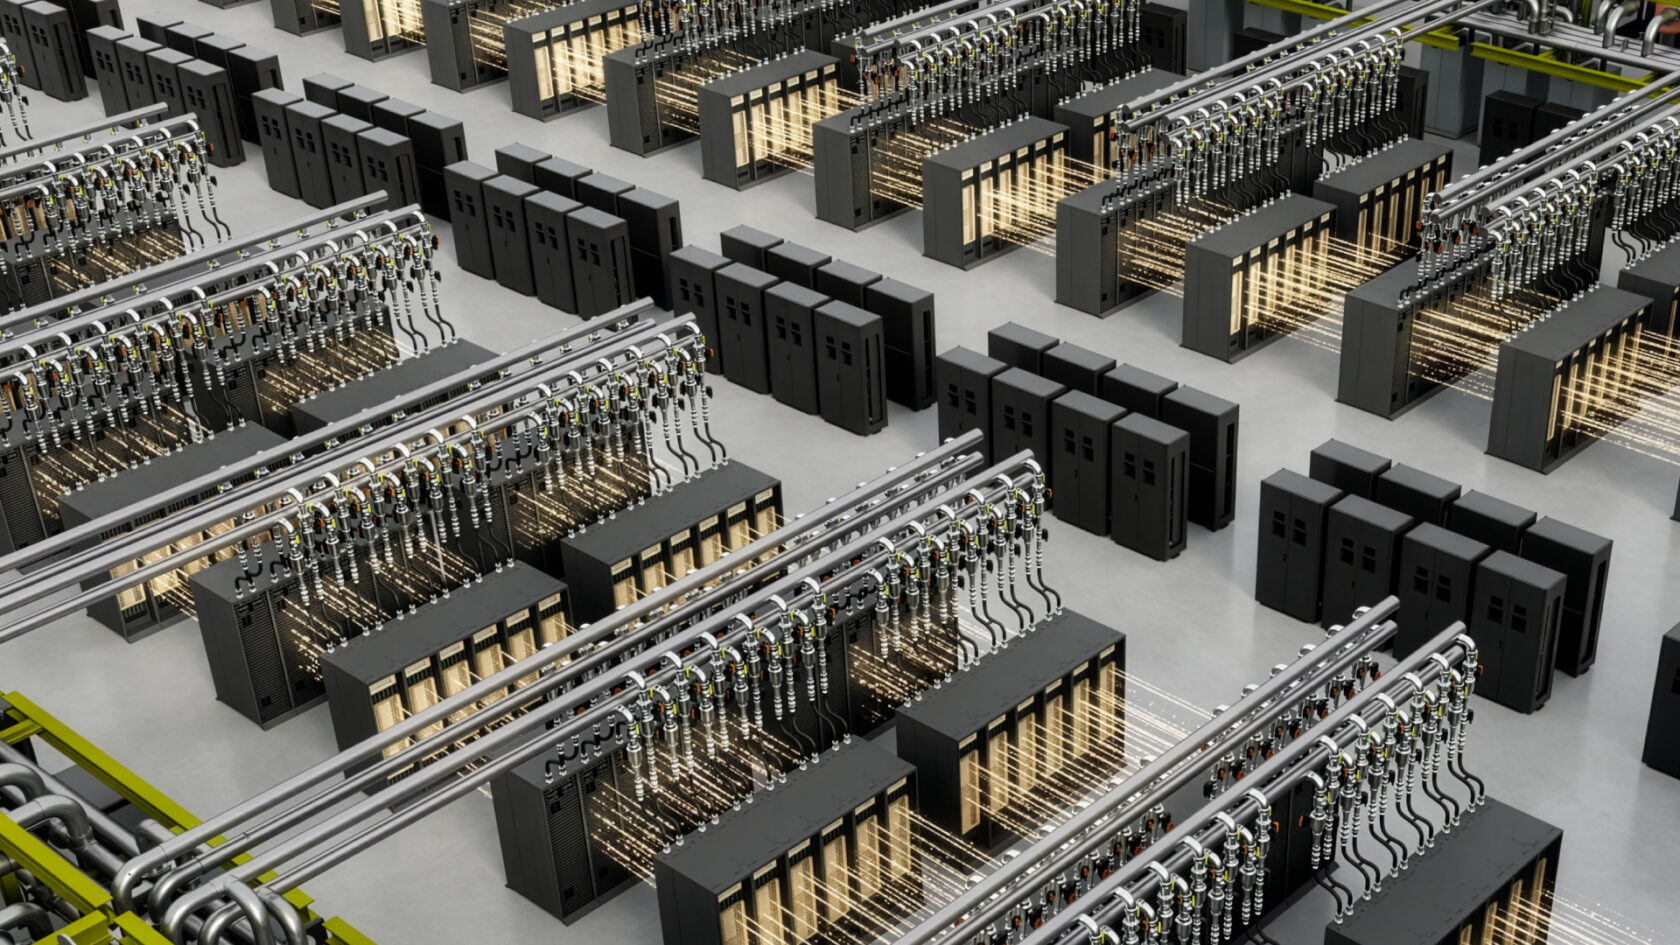
As AI factories grow from megawatts to gigawatts, building them takes more than advanced computing. Open standards are helping the industry scale AI infrastructure faster, more efficiently and more reliably.
At the Open Compute Project (OCP) Global Summit, taking place in the San Jose McEnery Convention Center, NVIDIA announced new partnerships and contributions aimed at creating a common foundation for next-generation AI infrastructure.
NVIDIA contributed key NVIDIA Vera Rubin rack and compute tray designs to OCP through the open NVIDIA MGX architecture, giving system builders a common foundation for developing next-generation AI factory infrastructure.
Together, these efforts span the AI factory itself, the utility grid that powers it and the rack-scale architecture at the heart of modern accelerated computing.
NVIDIA and Partners Announce Open Architecture Advances
At the OCP event, NVIDIA and partners made a handful of announcements:
- NVIDIA and hyperscalers published open standards for next-generation AI factories, including AI factory design standards and grid resilience.
- NVIDIA launched new open source software components for NVIDIA DSX AI Factory.
- Meta and NVIDIA advanced open AI networking with NVIDIA Spectrum-X Ethernet SuperNIC and Spectrum-6 innovations.
- Visionbay introduced an 800V DC AI factory design for the Vera Rubin era.
- NVIDIA and Cisco announced the Ultra-Dense Small Form Factor Pluggable (USFP) standard, the industry’s first module for 400Gb/s-based networking fabrics.
- NVIDIA and Google announced Falcon Transport support on future NVIDIA ConnectX-10 SuperNICs and BlueField DPUs.
Before a packed audience, Ian Buck, vice president of hyperscale and high-performance computing at NVIDIA, discussed how open infrastructure is becoming a critical ingredient for scaling AI factories worldwide.
The news at OCP spotlights how NVIDIA’s extreme codesign combined with open standards is accelerating deployment, improving power efficiency and driving tokens-per-watt performance.
Vera Rubin AI Factories Advance With MGX Rack Contributions at OCP 🔗
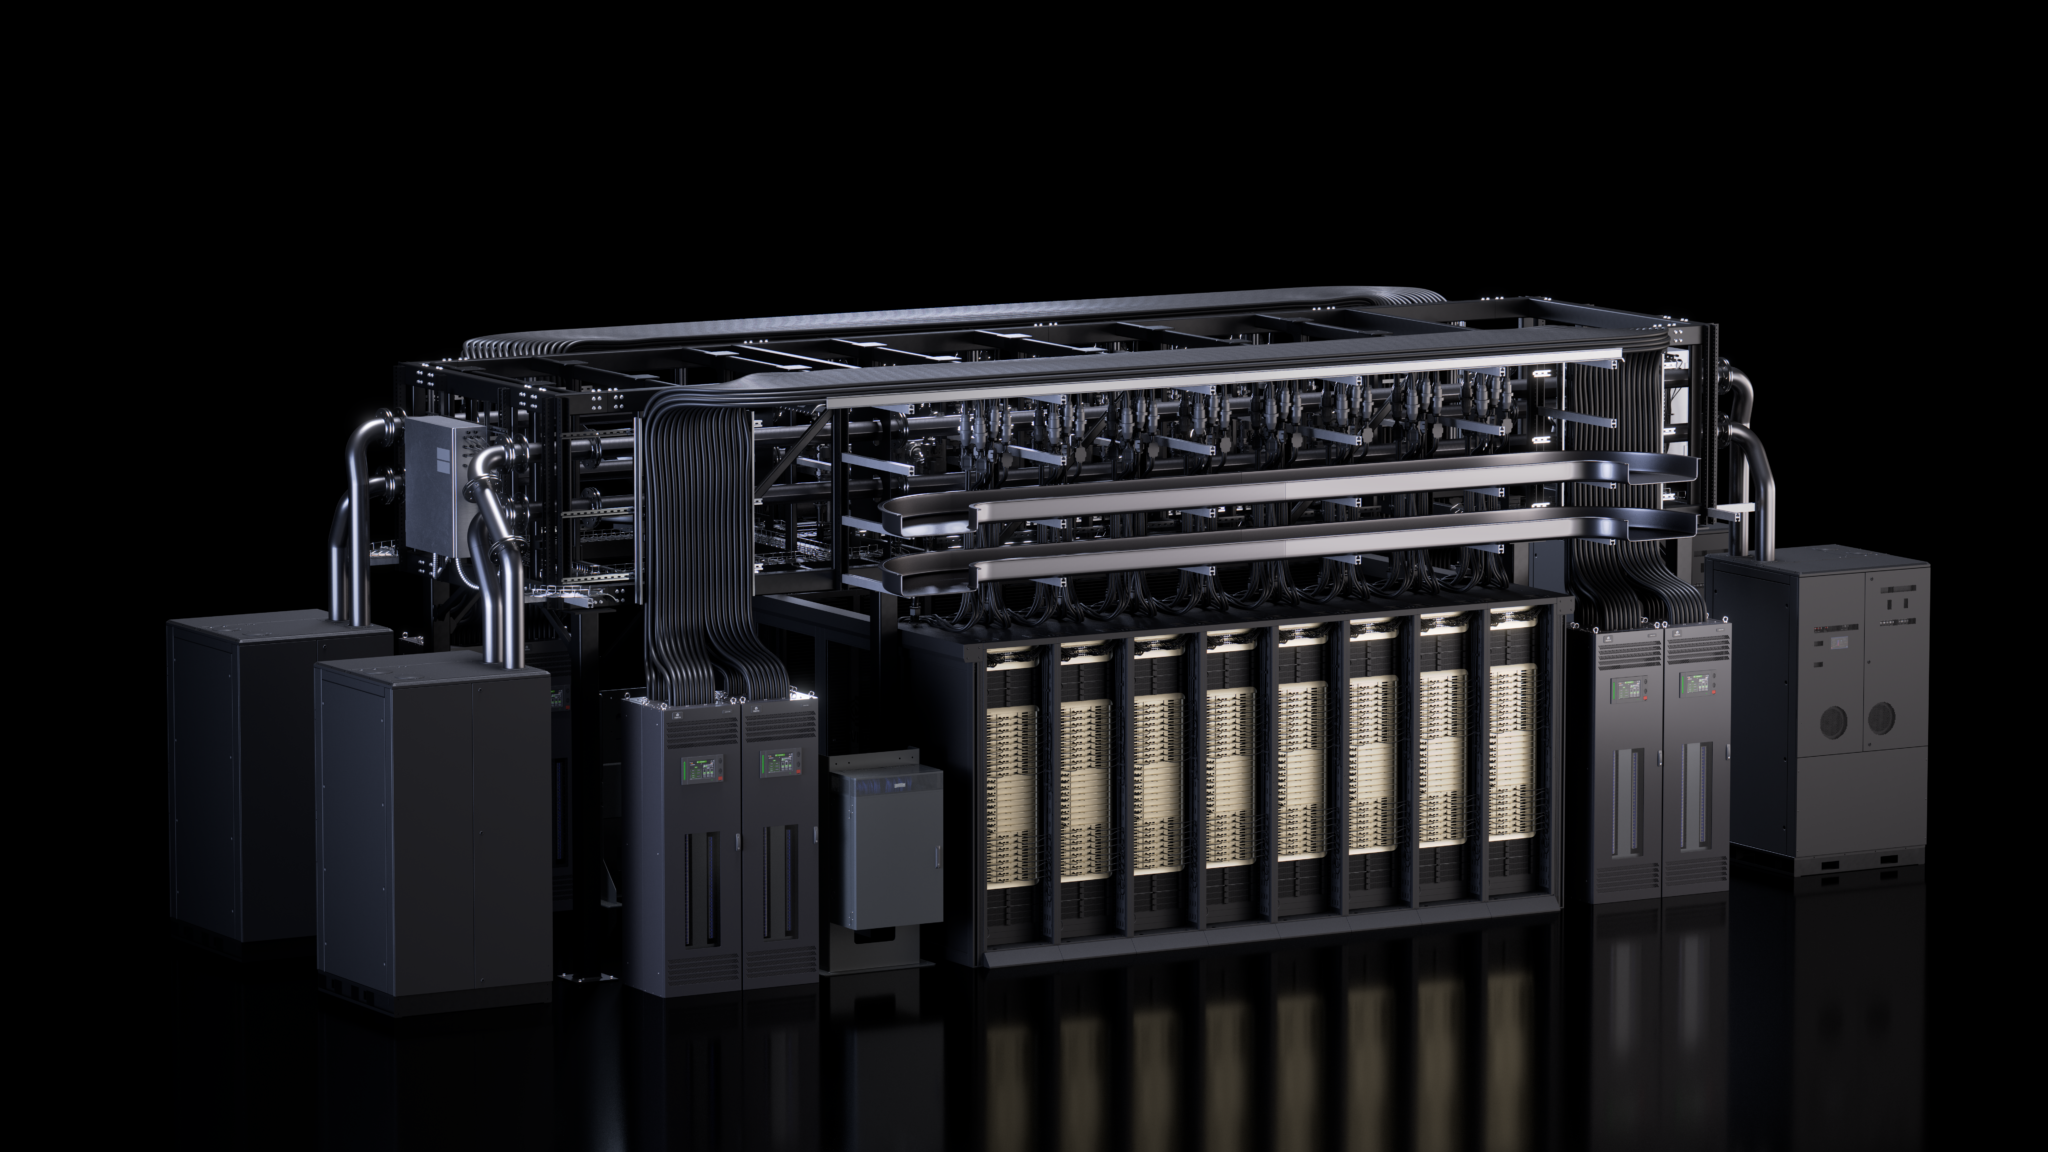
NVIDIA joined industry leaders in contributing to the third-generation MGX AI data center reference design through OCP’s Open DC Initiative.
Combined with open liquid-cooling technologies such as MQD and MQDB, the effort helps turn proven AI factory designs into industry standards that others can adopt, manufacture and scale.
For NVIDIA Vera Rubin AI factories, the updated MGX 1.2 specification extends the open architecture for AI factories with rack-scale blind-mate liquid cooling, interoperable rack-scale interconnect infrastructure and a liquid-cooled 5,000A busbar designed for higher-power AI systems. It also adds native 19-inch equipment support and higher-density rack designs.
MGX 1.2 further expands modularity with configurable I/O bays, fanless liquid-cooled compute trays, standardized power and cooling interfaces, and a common infrastructure that helps ecosystem partners build interoperable accelerated computing platforms. It improves assembly, test and service times to streamline manufacturing and field service to enable faster and more efficient infrastructure buildout. The architecture supports rack deployments up to 250kW while simplifying serviceability, deployment and infrastructure reuse.
The Vera CPU rack design specification extends the NVIDIA MGX open architecture beyond accelerated computing, providing a purpose-built platform for the growing agentic AI era. While Vera Rubin NVL72 serves as the foundation for large-scale training and inference, the NVIDIA Vera CPU rack is designed to support tool calling, orchestration and sandboxed execution, helping AI agents interact with applications, data and services in real time.
Built on the third-generation NVIDIA MGX rack architecture, the Vera CPU rack shares the same rack-scale design principles that unite compute, networking, power and cooling into a common modular platform. This approach enables partners to deploy specialized infrastructure while benefiting from a shared ecosystem, simplified integration and a consistent foundation for next-generation AI factories.
NVIDIA Launches New Open Source Software Components for DSX AI Factory 🔗
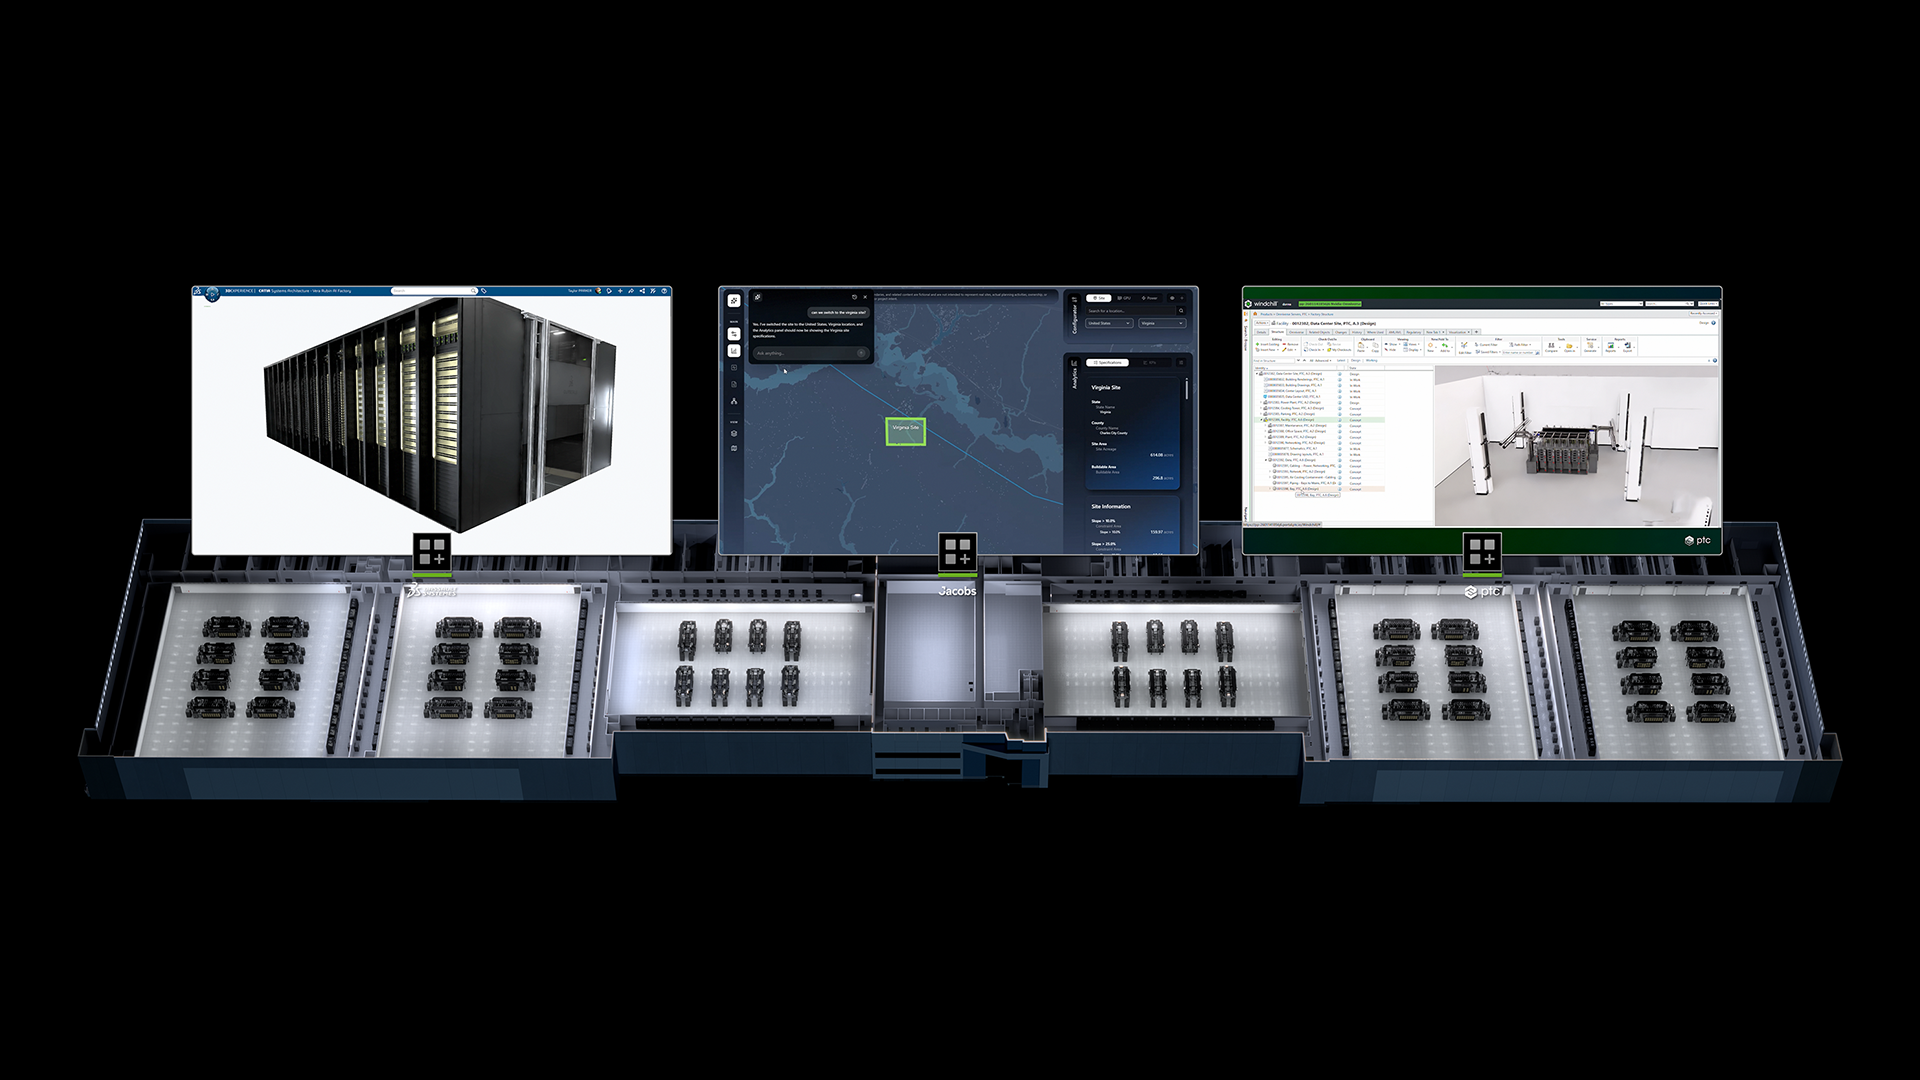
NVIDIA DSX AI factory platform applies extreme codesign to unify computing, networking, power, cooling, facilities and software, helping AI factories operate as a single optimized system, maximizing AI output within available infrastructure constraints. At the center of this unified system is DSX OS, the open operating layer that turns the DSX architecture into coordinated, repeatable operations at scale.
At OCP, NVIDIA expanded DSX OS with open source components for configuring networks, validating clusters, managing racks and provisioning bare metal:
- NVIDIA Config Manager: Automates switch configurations at scale, allowing customers to deploy, validate and maintain consistent AI factory network fabrics with minimal to zero manual intervention/
- NVIDIA Cluster Readiness Engine: Helps eliminate costly job crashes by stress-testing GPU clusters with real workload simulations to guarantee hardware health before training begins
- NVIDIA Rack Management Service: Offers a rack hardware abstraction and operations solutions that treats racks as first-class units for improved AI factory scale firmware management.
- Cluster API Provider for NVIDIA Infrastructure Controller: Accelerates bare-metal deployment and tenant onboarding, turning raw AI hardware into production-ready clusters in hours instead of days.
Developed from NVIDIA’s experience running NVIDIA DGX Cloud, these open source components enable cloud providers and software partners to integrate AI factory capabilities directly into their multi-tenant platforms.
Developers can visit the DSX AI Factory Github page to explore and contribute to both the new and existing open source software components from NVIDIA DSX AI Factory platform.
NVIDIA and Hyperscalers Publish Open Standards for Next-Generation AI Factories 🔗
For AI infrastructure to scale globally, it needs more than advanced hardware — it needs a common foundation that the entire industry can build on.
At OCP, NVIDIA joined AMD, Google and Meta to publish a new open specification that establishes that foundation. The Open Data Center Specification v0.7 defines a unified blueprint for next-generation AI factory facility design — from power architecture to cooling infrastructure to physical layout.
The OCP Grid Resilience Specification, published by Google, Meta, Microsoft and NVIDIA, establishes how large-scale AI infrastructure should behave during utility grid disturbances: staying connected, responding automatically and restoring to near-full load within less than two seconds.
With these standards now open, manufacturers around the world have a common target to build for. Equipment makers, colocation providers and data center operators can begin designing, fabricating and delivering the infrastructure layer that powers AI factories under construction globally — without waiting for proprietary specifications from individual customers.
Being NVIDIA DSX reference design-compatible, these specifications provide a validated, deployable implementation of both specs, from facility layout and power architecture to the software that monitors and responds to grid signals in real time. For operators building Vera Rubin AI factories, there’s now a straight line from open community standard to a running system.
Visionbay.ai Designs 800VDC AI Factory for the Vera Rubin Era 🔗
As AI factories grow larger and more powerful, one challenge looms over them all: delivering enough power to the accelerated computing systems driving the next generation of AI.
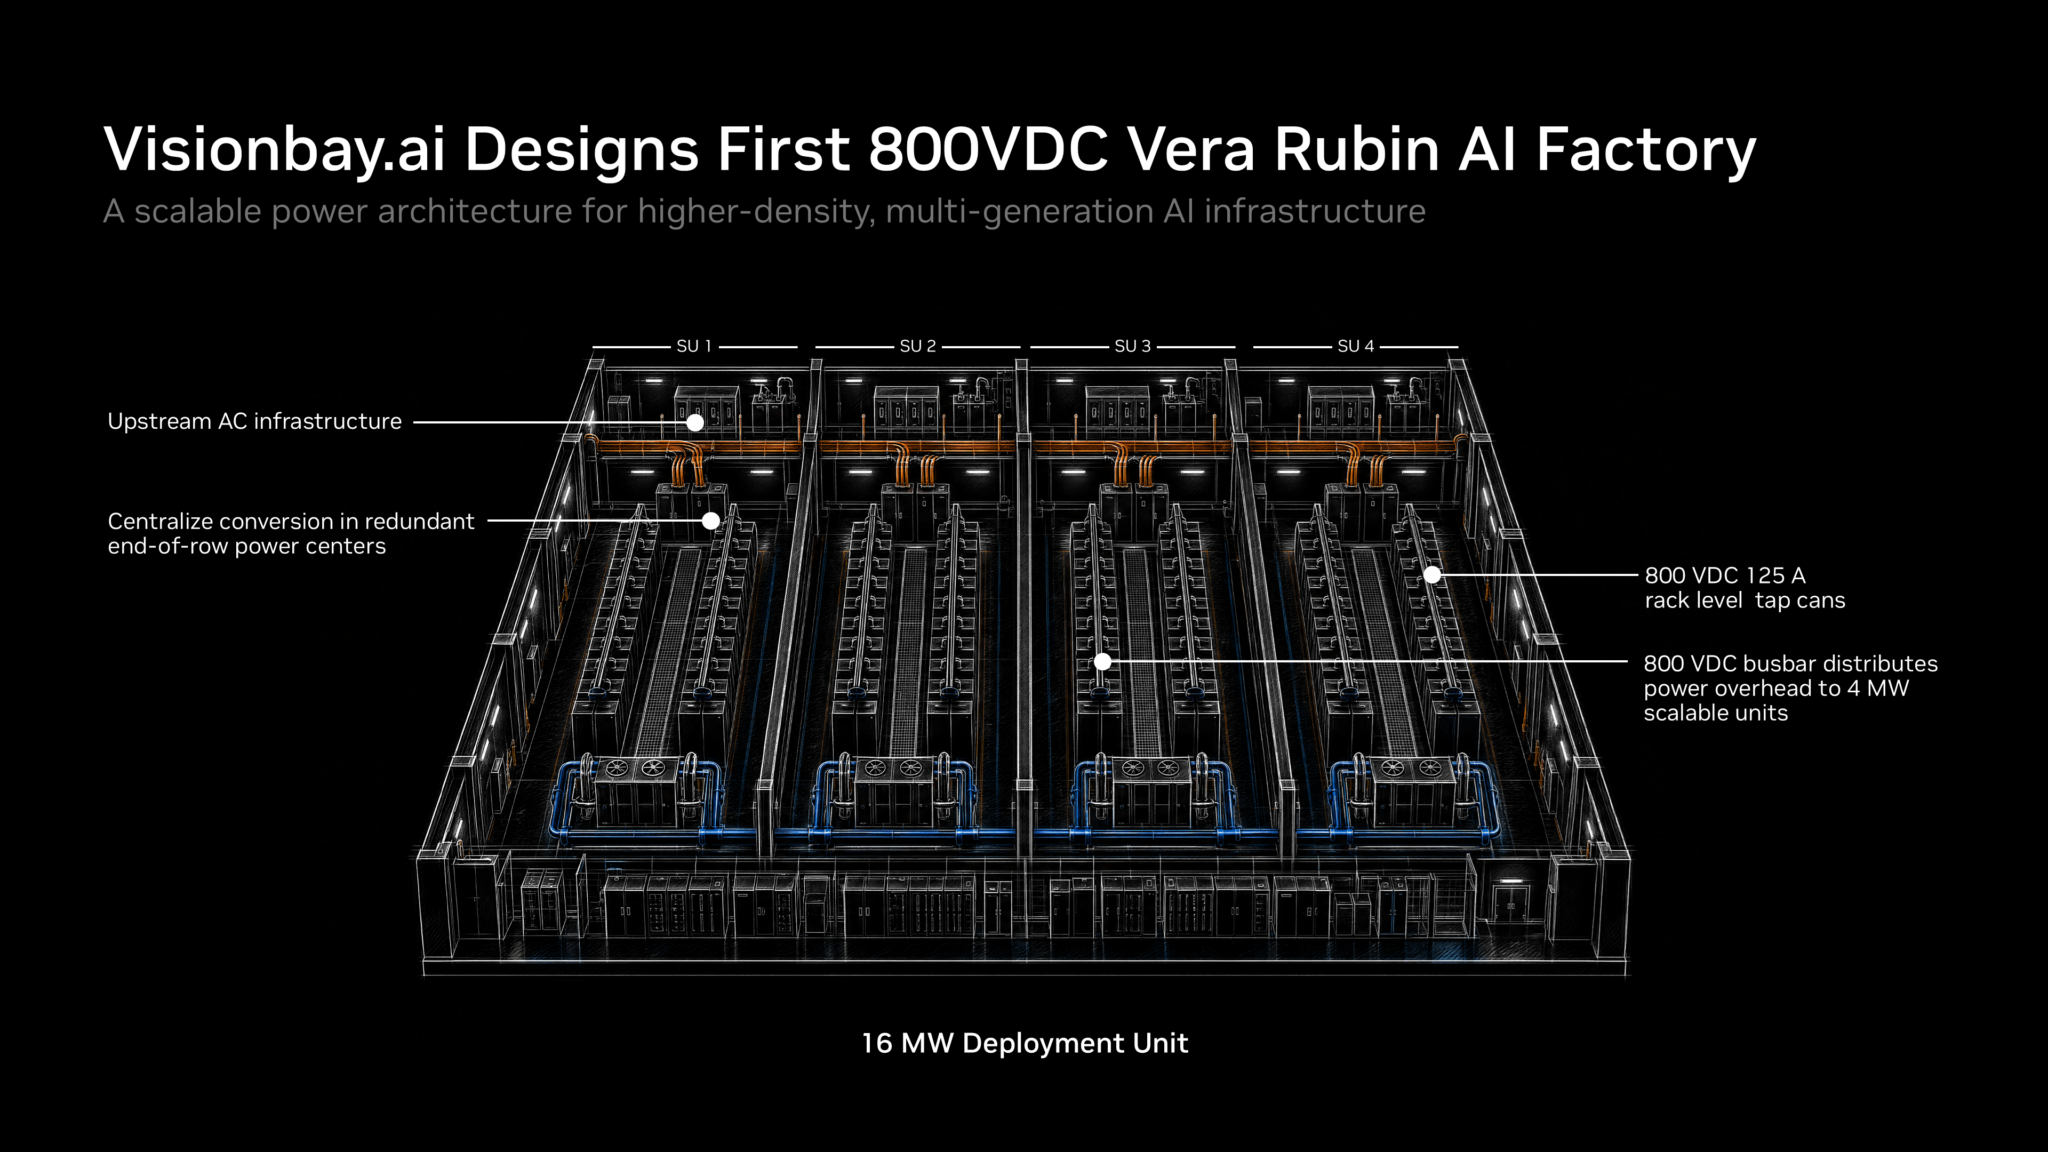
At OCP, Visionbay unveiled plans for K-1, a next-generation AI factory platform designed around an 800 VDC architecture and built with future NVIDIA Vera Rubin deployments in mind. The project combines NVIDIA’s 800 VDC reference architecture with power and thermal technologies from Vertiv to create a scalable foundation for high-density AI infrastructure.
The design addresses a growing industry challenge. As AI training, inference and reasoning workloads expand, rack power densities continue to rise. Traditional low-voltage power distribution becomes increasingly difficult to scale, requiring more copper, more cabling and more power-conversion equipment.
By adopting NVIDIA’s 800 VDC architecture, K-1 creates a path toward higher-density AI infrastructure while preserving flexibility for existing deployments. Rather than requiring a complete transition on day one, the platform is designed to phase in 800 VDC distribution where it delivers the greatest benefit, helping operators prepare for future generations of accelerated computing without extensive facility redesign.
The architecture is designed around cluster-level power centers that centralize AC-to-DC conversion and distribute 800 VDC closer to compute resources. The approach simplifies downstream power delivery, supports modular expansion and creates repeatable building blocks for future AI factory growth.
K-1 also reflects the system-level design philosophy behind NVIDIA AI factories, where power, cooling and computing are engineered together. With support for liquid-cooled infrastructure, scalable power distribution and future Vera Rubin-class deployments, the project demonstrates how ecosystem partners are translating NVIDIA’s AI factory architecture into deployable infrastructure designed for the next era of accelerated computing.
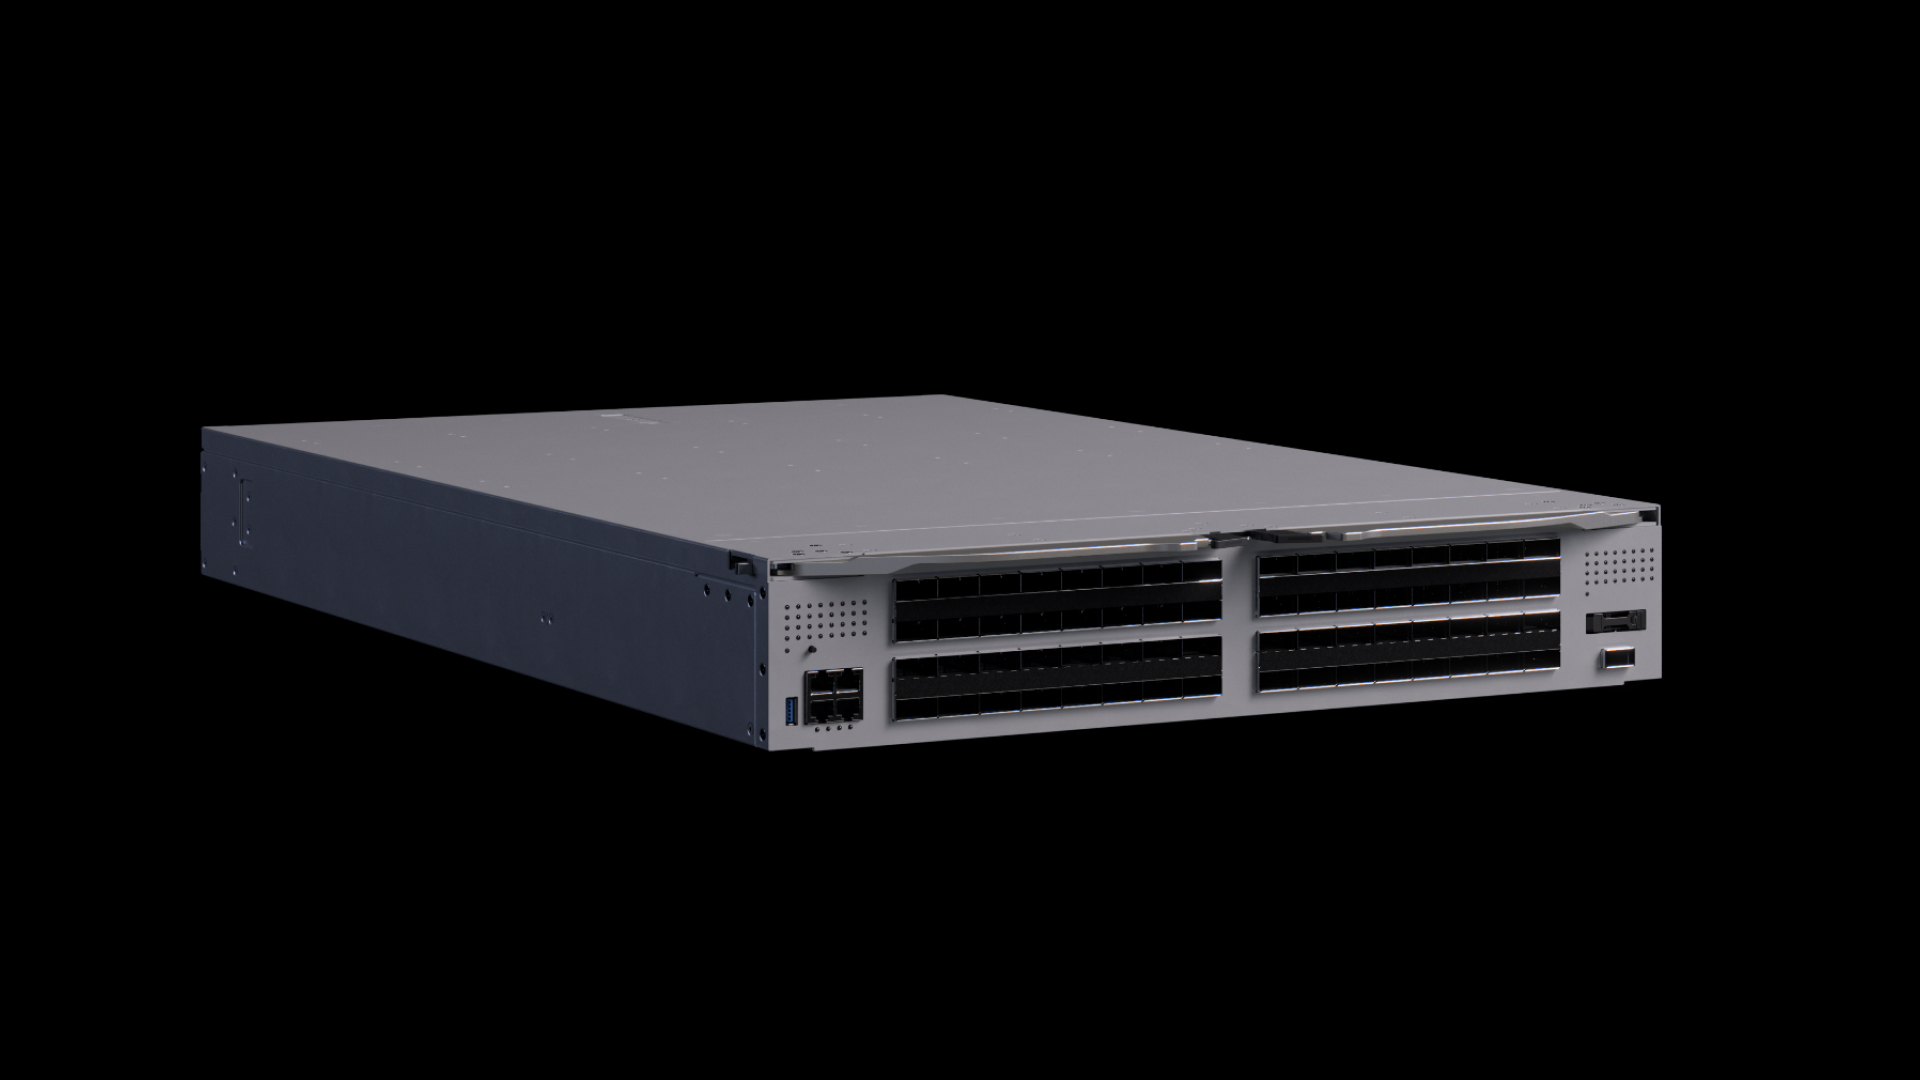
At the event, Meta and NVIDIA announced that Meta is adopting NVIDIA Spectrum-6 102.4Tb/s Ethernet switches to build larger, higher-performance NVIDIA Vera Rubin AI factories on open networking.
Spectrum-6 delivers twice the switching capacity and per-lane bandwidth of Spectrum-4, and provides a lossless Ethernet AI fabric at 200G per lane, with high effective bandwidth and performance isolation that keeps one job’s traffic from slowing another’s.
Meta’s Spectrum-6-based switch, N-IceCube, slots into IcePack, Meta’s 100T, liquid-cooled rack. N-IceCube runs the Facebook Open Switching System (FBOSS), Meta’s open source network operating system that contributed to OCP to support efficient networking at hyperscale.
FBOSS is built on the Switch Abstraction Interface, an OCP standard NVIDIA helped develop, providing a vendor-independent way of controlling switch hardware. Together, these technologies support agentic AI factories of more than 100,000 GPUs that train and serve massive mixture-of-experts models.
The announcement marks the next step in a collaboration that combines Meta’s experience operating AI infrastructure at hyperscale with NVIDIA’s networking technology.
At the heart of this collaboration is Spectrum-X Multiplane technology, enabled by Spectrum-6 switches and ConnectX-9 SuperNICs. Multiplane distributes GPU traffic in hardware across up to eight independent network planes, enabling AI factories to scale beyond 100,000 GPUs with fewer switch tiers and lower infrastructure costs. Multiple paths between GPUs improve network utilization and resilience: when a component fails, traffic shifts to the remaining planes, keeping GPUs productive and AI applications running, even at reduced bandwidth.
Meta and NVIDIA worked together to strengthen that resilience through deployment experience and rapid engineering iteration. The teams validated improvements across on-premises and cloud environments.
“We are excited about our close partnership with NVIDIA in making multiplane fabrics operationally scalable and performant, a critical requirement both for our own infrastructure builds and for our joint cloud partners,” said Omar Baldonado, senior director of data center and AI networking at Meta. “Extending FBOSS to Spectrum ASICs means we can run that same software stack across our fabrics, and Meta’s new Spectrum-based switch, N-IceCube, brings that into Icepack – our liquid-cooled 102.4T network rack for scale-out that connects upcoming generations of accelerators in our fleet.”
Together, Meta and NVIDIA are developing an architecture and operational playbook that other AI infrastructure operators can adopt, turning lessons from demanding production workloads into more scalable, resilient and efficient AI factories.
With USFP, NVIDIA and Cisco Reinvent Pluggable Optics for AI Factory Scale 🔗
As AI factories scale to support larger models and surging inference demand, every component of the infrastructure stack must deliver more performance, efficiency and simplicity — right down to the network connection itself.
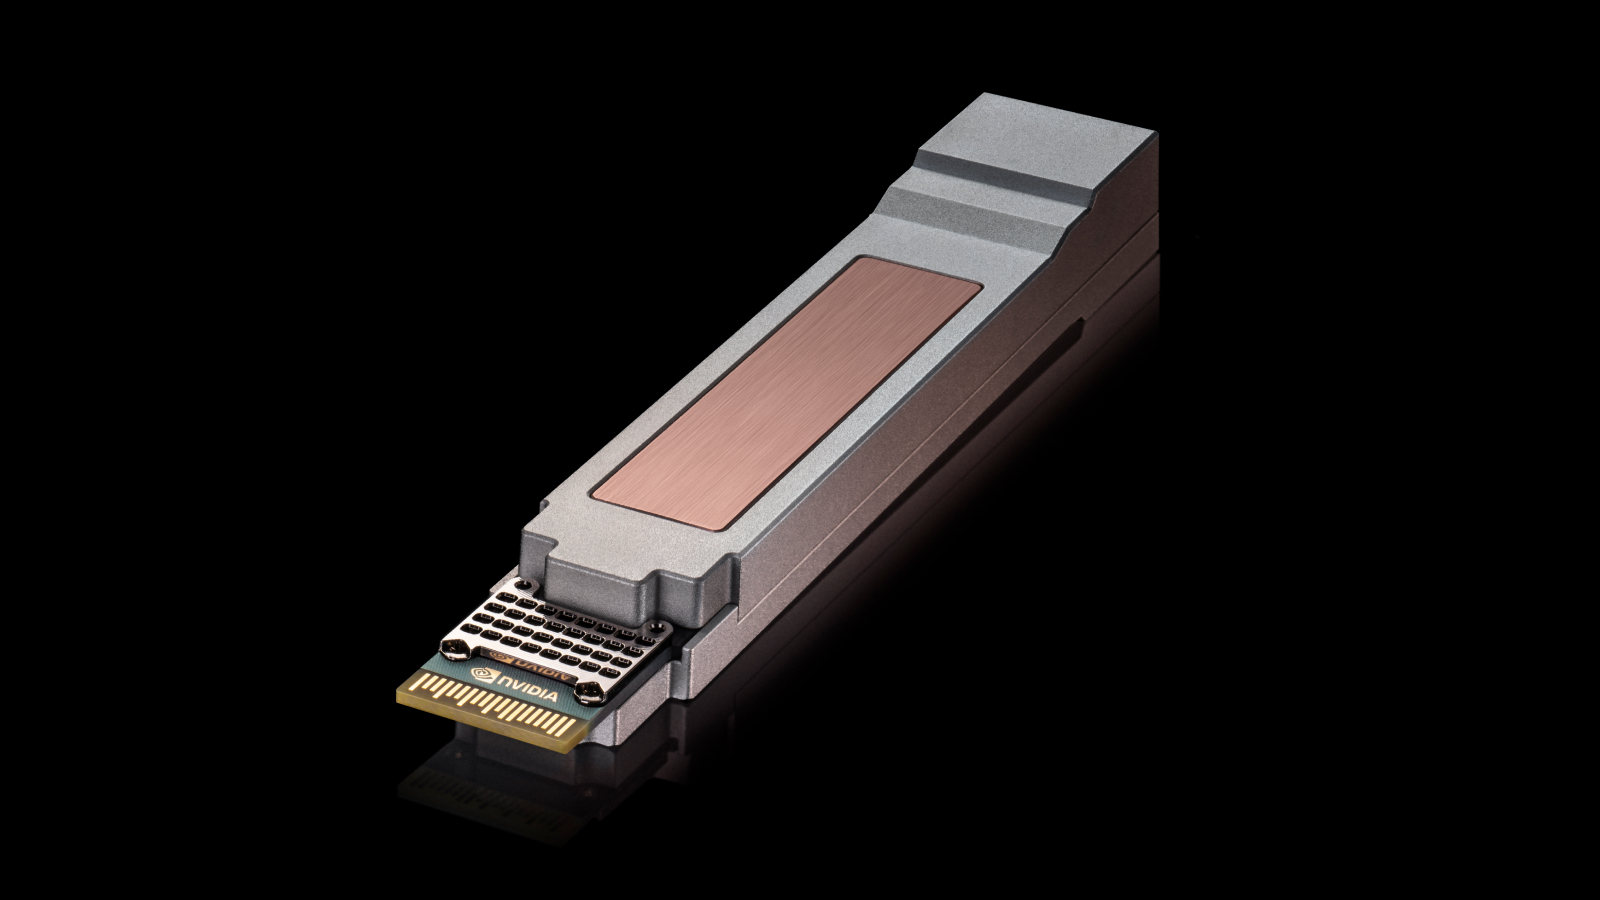
At OCP, NVIDIA and Cisco announced plans for USFP, a new optical pluggable transceiver module form factor designed to help AI factory builders scale next-generation AI fabrics while improving bandwidth density and power efficiency.
With approximately the same footprint as the widely adopted 200Gb/s-per-lane OSFP form factor, USFP will provide a path to 400Gb/s-per-lane networking and will extend a transceiver-based deployment model already proven across generations of data center networks. Packing 16 full-duplex lanes with plans to scale up to 32 lanes, USFP will deliver four times the bandwidth density of traditional 200Gb/s-per-lane pluggable optics.
The result is the ability to connect more compute resources without adding network tiers that can increase latency, power consumption and complexity.
The new form factor is designed for the scale and efficiency demands of next generation AI factories, supporting higher-bandwidth fabrics while preserving the flexibility and serviceability that have made pluggable optics a mainstay of modern data centers. It also will deliver roughly 1.3x greater power efficiency, helping operators move more data with less energy.
To help drive an open ecosystem, NVIDIA and Cisco are collaborating with TE Connectivity and Amphenol on cages, connectors and modules, with plans to advance USFP through a community-led, multi-source effort. Together, the companies are laying the foundation for more scalable, efficient and interoperable AI factory networking.
Google Falcon Transport Supports NVIDIA ConnectX-10 for Interoperable AI Networking 🔗
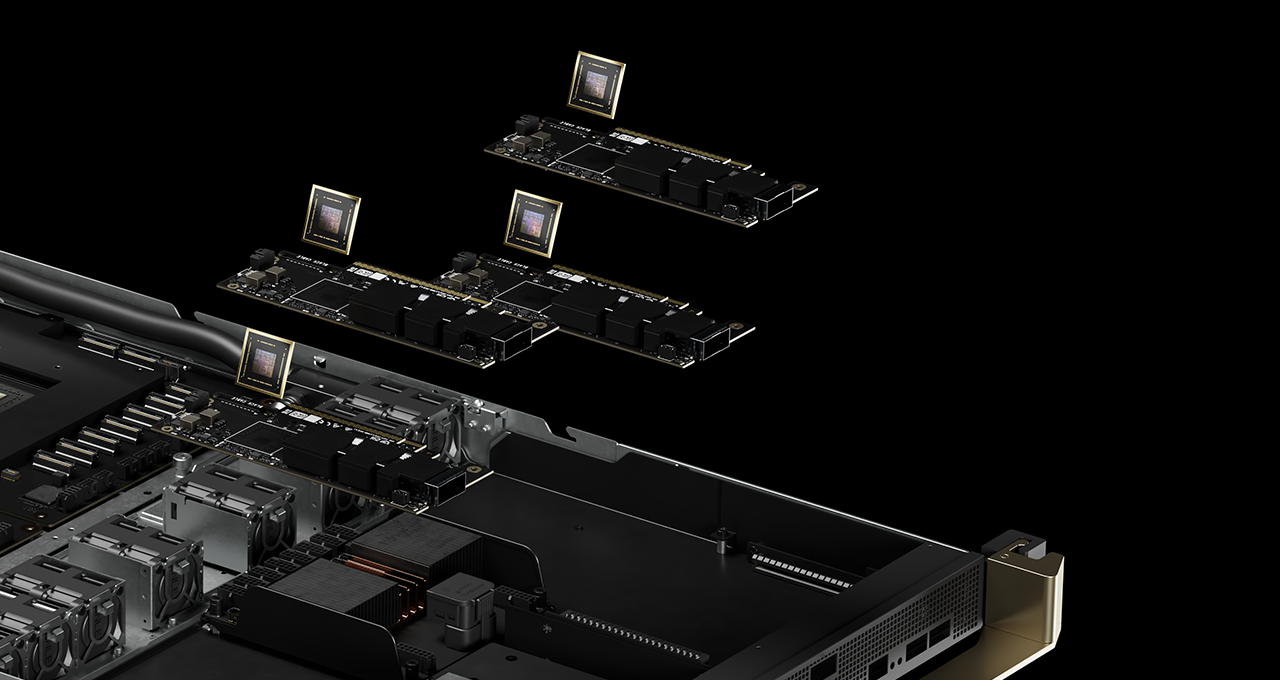
NVIDIA and Google also announced Falcon Transport support on future NVIDIA ConnectX-10 SuperNICs and BlueField DPUs, helping improve network efficiency for large-scale AI infrastructure.
Falcon is a transport protocol designed to deliver data reliably over Ethernet networks, which can otherwise drop packets under congestion. It supports AI and storage workloads through multipath load balancing, programmable congestion control, hardware loss recovery and per-connection security.
This collaboration combines NVIDIA hardware acceleration with DOCA software to implement Falcon and extend NVIDIA networking to Google’s data center transport. NVIDIA and Google NICs can communicate over a common transport while applications retain standard RDMA programming interfaces.
By distributing traffic across paths, adapting to congestion, recovering dropped packets and protecting connections, Falcon helps workloads make better use of available bandwidth and maintain predictable performance as Ethernet fabrics scale.
Learn more by joining NVIDIA at OCP.