Bitcoin biopic starring Casey Affleck to use AI to generate locations and tweak performances


Killing Satoshi, an upcoming biopic about the elusive creator of Bitcoin, will reportedly rely heavily on artificial intelligence to generate locations and adjust actors’ performances, Variety reports. The film was announced in 2025 as being directed by Doug Liman (The Bourne Identity, The Edge of Tomorrow) and starring Casey Affleck and Pete Davidson in undisclosed roles, but its connection to overhyped technology was previously understood to begin and end with cryptocurrency.

According to a UK casting notice viewed by Variety, the producers of Killing Satoshi reserve the right to “change, add to, take from, translate, reformat or reprocess” actors’ performances, using “generative artificial intelligence (GAI) and/or machine learning technologies.” No digital replicas will be created of performers, but it sounds like plenty of other AI-driven tweaks are on the table. The production’s use of AI will also extend to the setting of its shoots, per Variety’s source. Killing Satoshi will be shot on a “markerless performative capture stage” and things like backgrounds and locations will be entirely generated by AI.

You guess is as good as mine as to why a film about blockchain technology needs to be filmed this way, but Doug Liman has been connected with plenty of unusual projects in the past, including a rumored Tom Cruise film that was supposed to film on the International Space Station. Killing Satoshi will be far less practical in comparison, and walking a much finer line of what’s acceptable in the entertainment industry.

A major sticking point in SAG-AFTRA’s 2023 contract negotiations was guaranteeing protections for actors who could be replaced by AI. Equity, the union representing actors in the UK, is currently negotiating protections for members that are concerned that AI could be used to reproduce their likenesses and voices and let studios use them without their consent.

Long Delayed Siri Functions Are Reportedly Being Delayed Once Again Because They’re Slow and Inaccurate


Mark Gurman, Bloomberg’s Apple scoops guy, says the development of the latest version of Siri is not looking good in tests. It’s apparently going badly enough that Apple will release only a partial version when the updated voice assistant debuts in the next version of iOS. To be clear, the iOS 26.4 update is still expected to arrive next month, and it’s still expected to have a new version of Siri, but it may be a bit of a letdown.

That’s not good for Apple. Perhaps you’ll recall that Apple has been advertising a version of Siri that works as a smart, seamless, automated personal assistant in your pocket for a long time. Apple even made a commercial about this with Bella Ramsey released in fall of 2024:

But that ad had to be pulled because Apple couldn’t ship a real-life version of what it depicted. Asking Siri questions as if it’s a chatbot and then getting good answers drawn from your information across multiple apps is a function that certainly feels possible based on existing technology. But it’s now 2026 and Apple still hasn’t released that version of Siri.

And as I wrote late last month, Apple is perceived as needing to notch a win in the AI area after falling way behind Google in AI authority. The AI model driving the new, still unreleased, Siri is essentially rented from Google for $1 billion per year. And who knows, perhaps Google’s model is the culprit behind the latest problems with Siri, but it’s hard to picture consumers blaming Google if Apple can’t execute a solid new Siri product.

Gurman’s sources tell him tests of the new Siri found that it processes queries incorrectly, and that it sometimes takes “too long”—too long for what? We don’t get to know, but it’s clearly slow. Gurman points to the feature from the Bella Ramsey ad in which the AI mines answers from your personal data, and answers questions like “What was that Greek restaurant Larry told me to try?” as one likely to be delayed past iOS 26.4.

If it’s iOS 26.5 that eventually gets the Bella Ramsey version of Siri, and the user interface ends up being designed like the working version of that operating system that Apple employees are using to perform tests, Gurman says there may be an optional toggle allowing the user to “preview” that new Siri version, meaning it’ll be framed as something that the user can try at their own peril.

So ostensibly, these Siri features aren’t being cancelled or eliminated, but delayed. Apple will, Gurman says, release some sort of partial Siri update in March with iOS 26.4, and then the rest of the new Siri features will be sprinkled into the 26.5 update in May, and the larger update to iOS 27 in September, when the iPhone 18 line is scheduled to roll out. Though this “remains a fluid situation, and Apple’s plans may change further,” Gurman writes.

Apparently, according to Gurman, another delayed feature will be Siri-based voice controls for “App Intents,” a new framework for controlling apps that Apple says will perform an “increasingly critical role within Apple’s developer platforms.” This delay may not be grieved by developers, who, judging from X posts, don’t seem super eager to figure out how to use it.

Nemotron Labs: How AI Agents Are Turning Documents Into Real-Time Business Intelligence


Editor’s note: This post is part of the Nemotron Labs blog series, which explores how the latest open models, datasets and training techniques help businesses build specialized AI systems and applications on NVIDIA platforms. Each post highlights practical ways to use an open stack to deliver value in production — from transparent research copilots to scalable AI agents.

Businesses today face the challenge of uncovering valuable insights buried within a wide variety of documents — including reports, presentations, PDFs, web pages and spreadsheets.

Often, teams piece together insights by manually reviewing files, copying data into spreadsheets, building dashboards and using basic search or template-based optical character recognition (OCR) tools that often miss important details in complex media.

Intelligent document processing is an AI-powered workflow that automatically reads, understands and extracts insights from documents. It interprets rich formats inside those documents — including tables, charts, images and text — using AI agents and techniques like retrieval-augmented generation (RAG) to turn the multimodal content into insights that other multi-agent systems and people can easily use.

With NVIDIA Nemotron open models and GPU-accelerated libraries, organizations can build AI-powered document intelligence systems for research, financial services, legal workflows and more.

These open models, datasets and training recipes have powered strong results on leaderboards such as MTEB, MMTEB and ViDoRe V3, benchmarks for evaluating multilingual and multimodal retrieval models. Teams can choose from among the best models for tasks like search and question answering.

How Document Processing Streamlines Business Intelligence

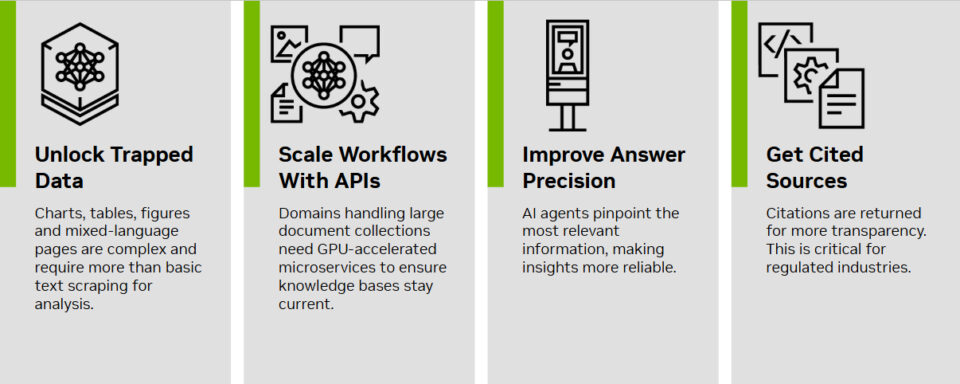
Document intelligence systems that can pull meaning from complex layouts, scale to huge file libraries and show exactly where an answer came from are incredibly useful in high-stakes environments. These systems:

  • Understand rich document content, moving beyond simple text scraping to capture information from charts, tables, figures and mixed-language pages and treating documents as a human would by recognizing structure, relationships and context​​.
  • Handle large quantities of shifting data, ingesting and processing massive collections of documents in parallel, and keeping knowledge bases continuously up to date.​​
  • Find exactly what users need, helping AI agents pinpoint the most relevant passages, tables or paragraphs to a query so they can respond with precision and accuracy.​​
  • Show the evidence behind answers by providing citations to specific pages or charts so teams can gain transparency and auditability, which is critical in regulated industries.​​

The result is a shift from static document archives to living knowledge systems that directly power business intelligence, customer experiences and operational workflows.

Document Intelligence at Work

Intelligent document processing systems built on NVIDIA Nemotron RAG models, Nemotron Parse and accelerated computing are already reshaping how organizations across industries gain insights from their documents.​​

Justt: AI-Native Chargeback Management and Dispute Optimization

In financial services, payment disputes create significant revenue loss and operational complexity for merchants, largely because the evidence needed to handle them lives in unstructured formats. Transaction logs, customer communications and policy documents are often fragmented across systems and difficult to process at scale, making dispute handling slow, manual and costly.

Justt.ai provides an AI-driven platform that automates the full chargeback lifecycle at scale. The platform connects directly to payment service providers and merchant data sources to ingest transaction data, customer interactions and policies, then automatically assembles dispute-specific evidence that aligns with card network and issuer requirements.

The platform’s AI-powered dispute optimization, powered by Nemotron Parse, applies predictive analytics to determine which chargebacks to fight or accept, and how to optimize each response for maximum net recovery. Leading hospitality operators like HEI Hotels & Resorts use the platform to automate dispute handling across their properties, recapturing revenue while maintaining guest relationships.

By pairing document-centric intelligence with decision automation, merchants can recapture a significant portion of revenue lost to illegitimate chargebacks while reducing manual review effort.​

Read about how Justt’s chargeback management tool autonomously processes financial data to handle disputes for merchants.

Docusign: Scaling Agreement Intelligence

Docusign is the global leader in Intelligent Agreement Management, handling millions of transactions every day for more than 1.8 million customers and over 1 billion users.

Agreements are the foundation of every business, but the critical information they contain are often buried inside pages of documents. To surface the information, Docusign needed high-fidelity extraction of tables, text and metadata from complex documents like PDFs so organizations could understand and act on obligations, risks and opportunities faster.

Docusign is evaluating Nemotron Parse for deeper contract understanding at scale. Running on NVIDIA GPUs, the model combines advanced AI with layout detection and OCR. The system can reliably interpret complex tables and reconstruct tables with required information. This reduces the need for manual corrections and helps ensure that even the most complex contracts are processed with the speed and accuracy their customers expect.

With this foundation, Docusign will transform agreement repositories into structured data that powers contract search, analysis and AI-driven workflows — turning agreements into business assets that help organizations and their teams improve visibility, reduce risk and make faster decisions.

Edison Scientific: Research Across Massive Literature Scale

Edison Scientific’s Kosmos AI Scientist helps researchers navigate complex scientific landscapes to synthesize literature, identify connections and surface evidence.​

Edison needed a way to rapidly and accurately extract structured information from large volumes of PDFs, including equations, tables and figures that traditional information parsing methods often mishandle.​

By integrating the NVIDIA Nemotron Parse model into its PaperQA pipeline, Edison can decompose research papers, index key concepts and ground responses in specific passages, improving both throughput and answer quality for scientists.​​ This approach turns a sprawling research corpus into an interactive, queryable knowledge engine that accelerates hypothesis generation and literature review.​

The high efficiency of Nemotron Parse enables cost-efficient serving at scale, allowing Edison’s team to unlock the whole multimodal pipeline.

Designing an Intelligent Document Processing Application With NVIDIA Technologies

A robust, domain-specific document intelligence pipeline requires technologies that can handle data extraction, embedding and reranking, while keeping the data secure and compliant with regulations.​​

  • Extraction: Nemotron extraction and OCR models rapidly ingest multimodal PDFs, text, tables, graphs and images to convert them into structured, machine-readable content while preserving layout and semantics.
  • Embedding: Nemotron embedding models convert passages, entities and visual elements into vector representations tuned for document retrieval, enabling semantically accurate search.​​
  • Reranking: Nemotron reranking models evaluate candidate passages to ensure the most relevant content is surfaced as context for large language models (LLMs), improving answer fidelity and reducing hallucinations.​​
  • Parsing: Nemotron Parse models decipher document semantics to extract text and tables with precise spatial grounding and correct reading flow. Overcoming layout variability, they turn unstructured documents into actionable data that enhances the accuracy of LLMs and agentic workflows.

These capabilities are packaged as NVIDIA NIM microservices and foundation models that run efficiently on NVIDIA GPUs, allowing teams to scale from proof of concept to production while keeping sensitive data within their chosen cloud or data center environment.

The most effective AI systems use a mix of frontier models and open source models like NVIDIA Nemotron, with an LLM router analyzing each task and automatically selecting the model best suited for it. This approach keeps performance strong while managing computing costs and improving efficiency.

Get Started With NVIDIA Nemotron

Access a step-by-step tutorial on how to build a document processing pipeline with RAG capabilities. Explore how Nemotron RAG can power specialized agents tailored for different industries.​

Plus, experiment with Nemotron RAG models and the NVIDIA NeMo Retriever open library, available on GitHub and Hugging Face, as well as Nemotron Parse on Hugging Face.

Join the community of developers building with the NVIDIA Blueprint for Enterprise RAG — trusted by a dozen industry-leading AI Data Platform providers and available now on build.nvidia.com, GitHub and the NGC catalog.

Stay up to date on agentic AI, NVIDIA Nemotron and more by subscribing to NVIDIA AI news, joining the community and following NVIDIA AI on LinkedIn, Instagram, X and Facebook.  

Explore self-paced video tutorials and livestreams.


Everything Will Be Represented in a Virtual Twin, Jensen Huang Says at 3DEXPERIENCE World


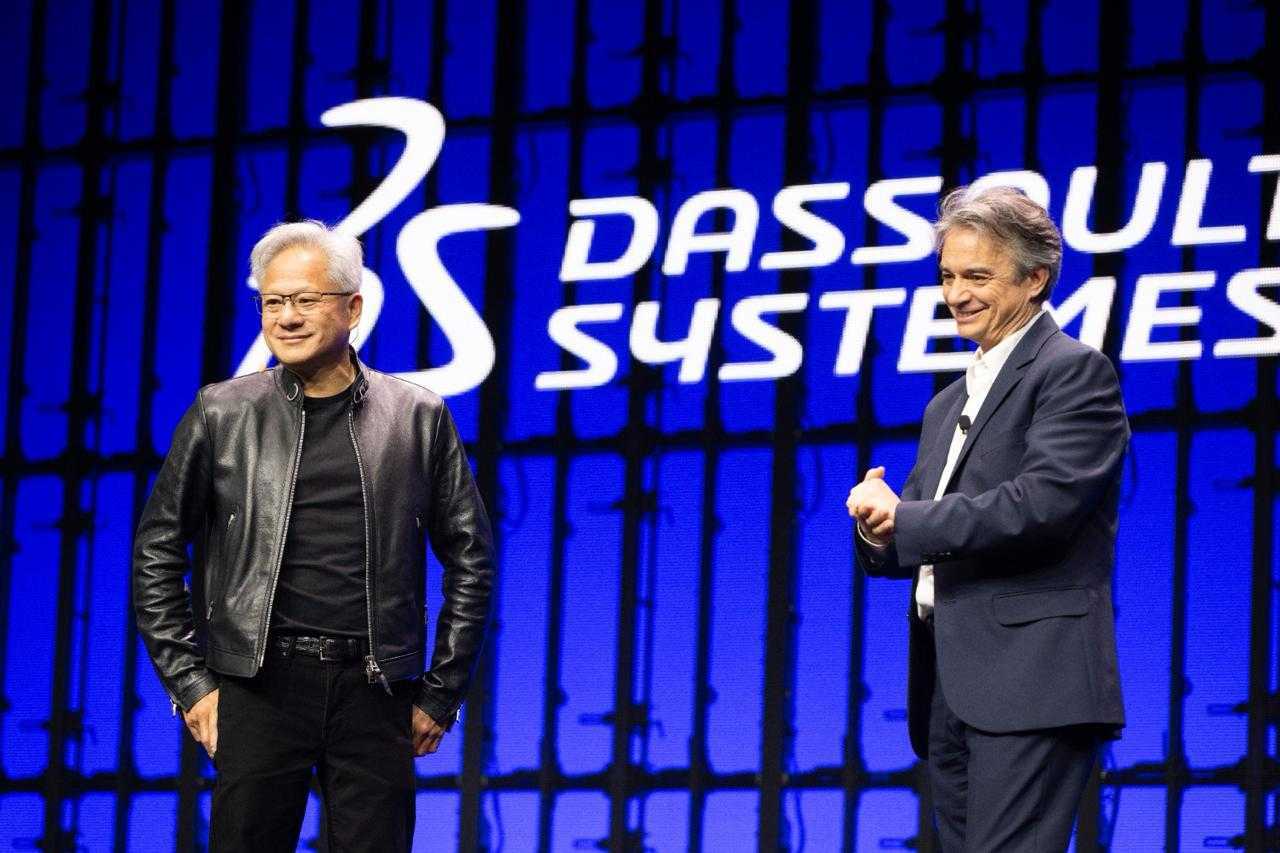
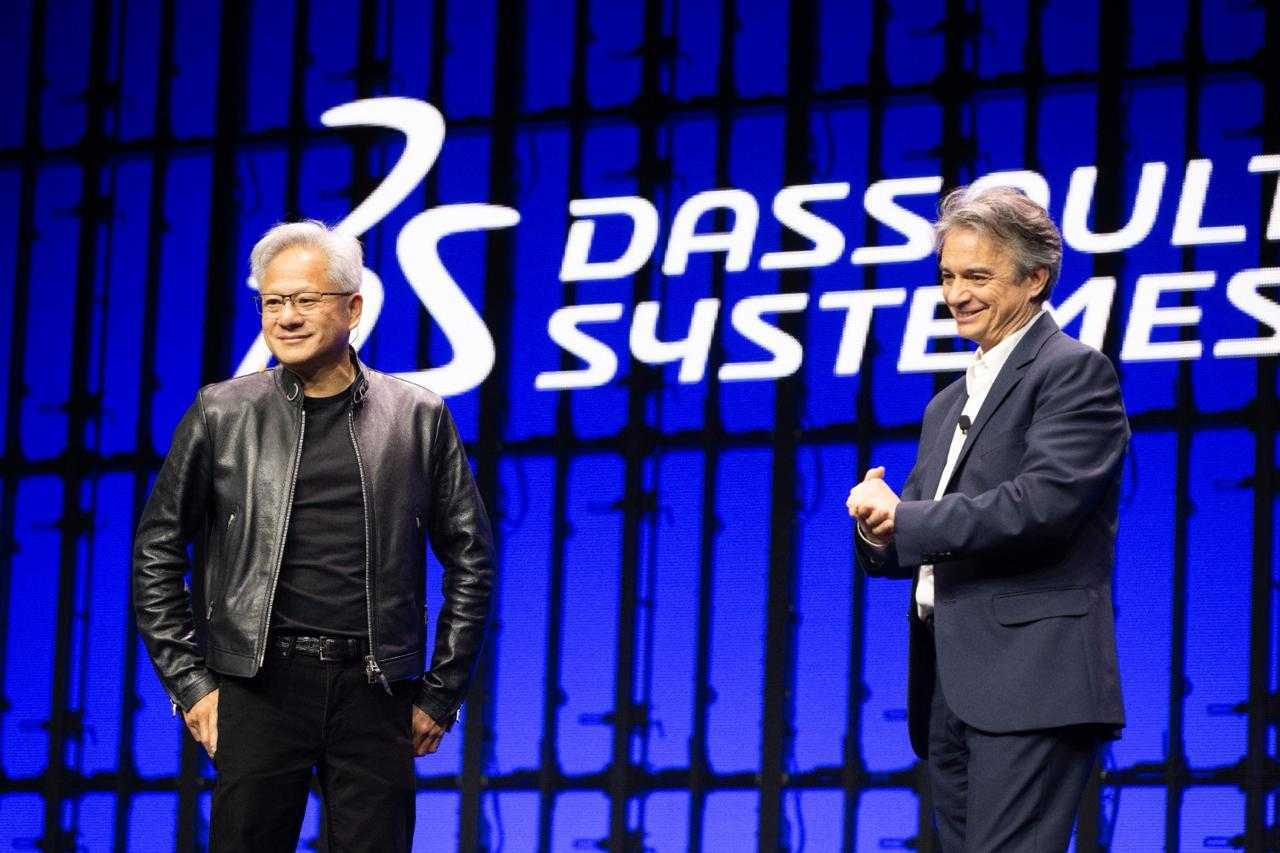
At 3DEXPERIENCE World in Houston, NVIDIA founder and CEO Jensen Huang and Dassault Systèmes CEO Pascal Daloz laid out a blueprint for industrial AI rooted in physics-based “world models” — systems designed to simulate products, factories and even biological systems before they’re built.

“Artificial intelligence will be infrastructure,”  like water, electricity, and the internet Huang told the crowd, playfully referring to the engineering-heavy audience as “Solid Workers,” a nod to Dassault Systèmes’ SolidWorks platform.

The announcement continues a collaboration spanning more than a quarter century between NVIDIA and Dassault Systèmes.

“This is the largest collaboration our two companies have ever had in over a quarter century,” Huang said. “We’re going to fuse these technologies so engineers can work at a scale that’s 100 times, 1,000 times — and eventually a million times greater than before.”

The new partnership brings NVIDIA accelerated computing and AI libraries together with Dassault Systèmes’ Virtual Twin platforms to move more engineering work into real-time digital workflows, powered by AI companions that help teams explore, validate, prototype and iterate faster.

Huang framed the shift as a reinvention of the computing stack: moving from hand-specified, structured digital designs to systems that can generate, simulate and optimize in software — at industrial scale.

From Digital Models to Industry World Models

Virtual twins are not applications, “they are knowledge factories,” Daloz said.

The partnership aims to establish industry world models — science-validated AI systems grounded in physics that can serve as mission-critical platforms across biology, materials science, engineering and manufacturing.

In Daloz’s framing, the value moves upstream: virtual twins become the place where knowledge is created, tested, and trusted — before anything is built in the physical world.

Dassault Systèmes, whose 3DEXPERIENCE platform serves more than 45 million users and 400,000 customers globally, has long been a leader in virtual twin technology — digital replicas that let engineers simulate products and processes before building them physically.

The collaboration brings together accelerated computing, AI and digital twin technologies so engineers can design not only geometry, but behavior — and explore radically larger design spaces earlier in development.

Together, the companies outlined how this shared architecture will show up across science, engineering and manufacturing workflows:

  • Advancing Biology and Materials Research​: The NVIDIA BioNeMo platform and BIOVIA science-validated world models accelerate the discovery of new molecules and next-generation materials.
  • AI-Driven Design and Engineering: SIMULIA AI-based Virtual Twin Physics Behavior leveraging NVIDIA CUDA-X libraries and AI physics libraries empowers designers and engineers to accurately and instantly predict outcomes.
  • Virtual Twins for Every Factory: NVIDIA Omniverse physical AI libraries integrated into the DELMIA Virtual Twin enable autonomous, software-defined production systems.
  • Virtual Companions Supercharge Dassault Systèmes’ Users: The 3DEXPERIENCE agentic platform, combining NVIDIA AI technologies and NVIDIA Nemotron open models with Dassault Systèmes’ Industry World Models, powers Virtual Companions to tap into deep industrial context, delivering trusted, actionable intelligence.

Huang said that in domains like biology and materials, the frontier is learning the underlying “language” of complex systems and then generating new options that can be evaluated and validated in simulation.

Designing and Operating the Factory in Software

A central theme of the discussion was how factories themselves are changing — from static physical assets to living systems that are designed, simulated and operated as virtual twins.

As part of the partnership, Dassault Systèmes is deploying NVIDIA-powered AI factories on three continents through its OUTSCALE sovereign cloud, enabling customers to run AI workloads while maintaining data residency and security requirements.

Both executives emphasized that the goal isn’t to replace engineers — it’s to amplify them. As AI agent companions take on more exploratory and repetitive tasks, designers and engineers gain leverage and creativity, not redundancy.

AI Companions That Expand Human Creativity

Every designer will have a “team of companions,” Huang said — a shift he described as fundamentally positive for engineers, software platforms and the broader ecosystem built on them.

For the tens of millions of engineers who use Dassault Systèmes tools to design everything from aircraft to consumer packaged goods, the shift isn’t about replacing human creativity — it’s about expanding it.

“Success is not about automation,” Daloz said. “[Engineers] don’t want to automate the past — they want to invent the future.”

Looking ahead, Daloz framed the partnership as about more than performance gains – it’s an effort to open new possibilities, help companies eliminate bad choices before they become expensive mistakes, and create entirely new categories of products.

“Virtual twins and the 3D Universes are not applications,” Daloz said. “They are knowledge factories.”

The fireside conversation between Huang and Daloz was broadcast live from 3DEXPERIENCE World.

New study shows AI isn’t ready for office work


It has been nearly two years since Microsoft CEO Satya Nadella predicted that generative AI would take over knowledge work, but if you look around a typical law firm or investment bank today, the human workforce is still very much in charge. Despite all the hype about “reasoning” and “planning,” a new study from training-data company Mercor explains exactly why the robot revolution is stalled: AI just can’t handle the messiness of real work.

A reality check for the “replacement” theory

Mercor released a new benchmark called APEX-Agents, and it is brutal. unlike the usual tests that ask AI to write a poem or solve a math problem, this one uses actual queries from lawyers, consultants, and bankers. It asks the models to do complete, multi-step tasks that require jumping between different types of information.

The results? Even the absolute best models on the market—we are talking about Gemini 3 Flash and GPT-5.2—couldn’t crack a 25% accuracy rate. Gemini led the pack at 24%, with GPT-5.2 right behind it at 23%. Most others were stuck in the teens.

Why AI is failing the “office test”

Mercor CEO Brendan Foody points out that the issue isn’t raw intelligence; it’s context. In the real world, answers aren’t served up on a silver platter. A lawyer has to check a Slack thread, read a PDF policy, look at a spreadsheet, and then synthesize all that to answer a question about GDPR compliance.

Humans do this context-switching naturally. AI, it turns out, is terrible at it. When you force these models to hunt for information across “scattered” sources, they either get confused, give the wrong answer, or just give up entirely.

The “Unreliable Intern”

For anyone worried about their job security, this is a bit of a relief. The study suggests that right now, AI functions less like a seasoned professional and more like an unreliable intern who gets things right about a quarter of the time.

That said, the progress is terrifyingly fast. Foody noted that just a year ago, these models were scoring between 5% and 10%. Now they are hitting 24%. So, while they aren’t ready to take the wheel yet, they are learning to drive much faster than we expected. For now, though, the “knowledge work” revolution is on hold until the bots learn how to multitask p

Document Disclosures Reveal Microsoft’s Influence as OpenAI Became a Revenue-Crazed Behemoth


Way back in March of 2019, this weird thing happened where a relatively insignificant tech nonprofit called OpenAI became a “capped” for-profit company—whatever that is. The month earlier, OpenAI had announced the creation of an uncanny, über-powerful language model called GPT-2 that was supposedly just too dangerous to release. Then in November, OpenAI seemingly changed its mind and GPT-2 was released after all.

OpenAI said in the blog post about the release that it saw, “no strong evidence of misuse so far,” but added that it was impossible to “be aware of all threats.” Most people never used GPT-2, because OpenAI never injected it into a viral chatbot.

As someone who wrote about this at the time, it was puzzling to watch it all play out. OpenAI seemed like small potatoes, but it was also building creepy AI tech, and shifting in public image from being a do-gooder computer lab advertising its trepidation about harming a hair on anyone’s head to an enterprise that needed to ship something asap because it was clearly promising someone, somewhere, that they were going to get rich.

Document discovery from Elon Musk’s lawsuit against OpenAI and Microsoft has provided a tiny window into what was actually happening inside Microsoft during this bizarre time for this bizarre company, and how the transition may have turned OpenAI into the money-hungry beast it is today, with revenues growing tenfold between 2023 and 2025.

GeekWire’s Todd Bishop dug through the cache of emails, memos, texts and the like from Microsoft and OpenAI, and what he found was revealing. Microsoft, and CEO Satya Nadella in particular, had invested heavily in OpenAI by then, and were not quiet during OpenAI’s uneasy transition to for-profit status. Nor were they shy about the need to make money as soon as possible. Absolutely none of this should come as a surprise, but it makes for fascinating reading anyway.

During that gap where GPT-2 was sitting there unreleased and OpenAI had recently become a capped nonprofit, Microsoft’s chief financial officer, Amy Hood, weighed in about the company’s concerns about that “capped” part. She wrote in a July 14 email to a group including Nadella, “Given the cap is actually larger than 90% of public companies, I am not sure it is terribly constraining nor terribly altruistic but that is Sam’s call on his cap.”

GPT-3, which was even more exciting than GPT-2 was released in 2020, and the first version of OpenAI’s language model, Dall-E was released in January 2021. The next month, Microsoft and OpenAI were negotiating an additional injection of money from Microsoft, and Sam Altman wrote an email to Microsoft, saying “We want to do everything we can to make you all commercially successful and are happy to move significantly from the term sheet,” and he added that he wanted “to make you all a bunch of money as quickly as we can and for you to be enthusiastic about making this additional investment soon.”

In November of 2022, ChatGPT was released, and as you know, all hell broke loose. In January of 2023, Nadella sent a text message to Altman, saying “when do you think you will activate your paid subscription for ChatGPT?”

Altman said he was “hoping to be ready by end of jan, but we can be flexible beyond that. the only real reason for rushing it is we are just so out of capacity and delivering a bad user experience,” and asked “any preference on when we do it?”

“Let me think about it and weigh in. Overall getting this in place sooner is best,” Nadella replied. Two weeks later, he followed up and asked “how many subs have you guys added to ChatGPT?”

Three days later, the paid version of ChatGPT launched.

CEOs of NVIDIA and Lilly Share ‘Blueprint for What Is Possible’ in AI and Drug Discovery


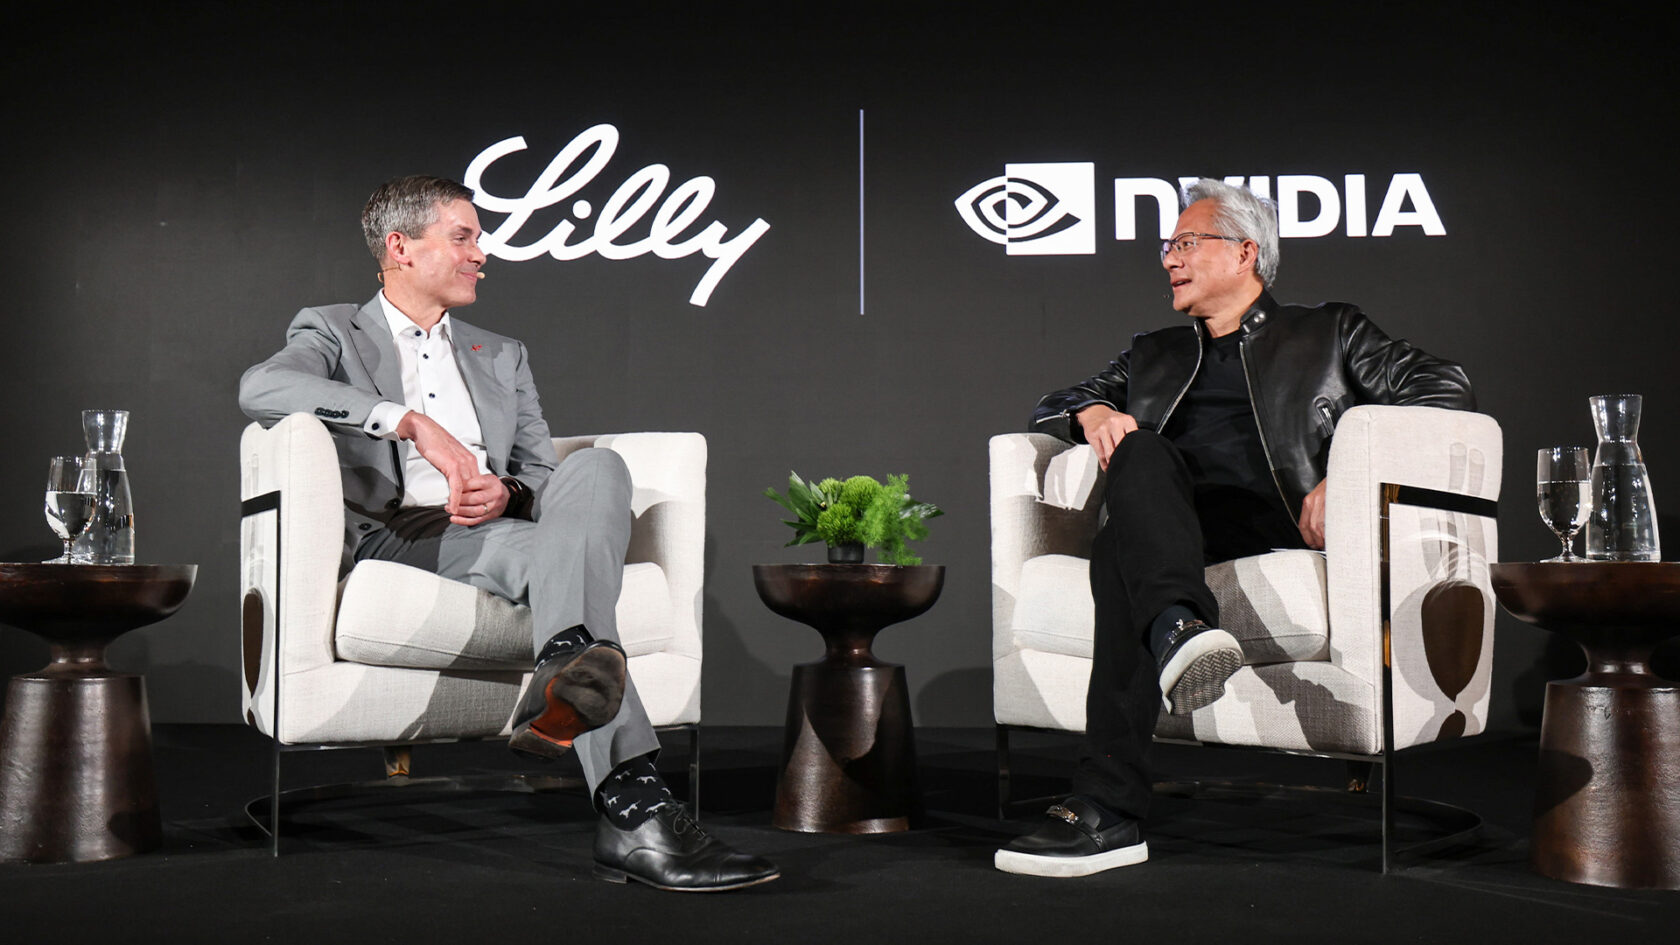
NVIDIA and Lilly are putting together “a blueprint for what is possible in the future of drug discovery,” NVIDIA founder and CEO Jensen Huang told attendees at a fireside chat Monday with Dave Ricks, chair and CEO of Lilly.

The conversation — which took place during the annual J.P. Morgan Healthcare Conference in San Francisco — focused on the announcement of a first-of-its-kind AI co-innovation lab by NVIDIA and Lilly.

“We’re systematically bringing together some of the brightest minds in the field of drug discovery and some of the brightest minds in computer science,” Huang said. “We’re going to have a lab where the expertise and the scale of that lab is sufficient to attract people who really want to do their life’s work at that intersection.”

The initiative will bring together Lilly’s world-leading expertise in the pharmaceutical industry with NVIDIA’s leadership in AI to tackle one of humanity’s greatest challenges: modeling the complexities of biology. The two companies will jointly invest up to $1 billion in talent, infrastructure and compute over five years to support the new lab, which will be based in the San Francisco Bay Area.

During the fireside chat, Ricks reflected on the painstaking work of drug discovery and AI’s potential to transform the cycle of pharmaceutical invention.

“Each small molecule discovery is like a work of art,” he said. “If we can make that an engineering problem, versus this sort of discovery, this artisanal drug-making problem, think of the impact on human life.”

The lab will operate under a scientist-in-the-loop framework, where agentic wet labs are tightly connected to computational dry labs in a continuous learning system. This framework aims to enable experiments, data generation and AI model development to continuously inform and improve one another.

“Machines are made to work day and night to solve this problem,” Ricks said.

The co-innovation lab builds on Lilly’s previously announced AI supercomputer — the biopharma industry’s most powerful AI factory, an NVIDIA DGX SuperPOD with DGX B300 systems — which will train large-scale biomedical foundation and frontier models for drug discovery and development.

By integrating AI into drug discovery, Ricks explained, pharmaceutical researchers can rapidly simulate a massive number of possible molecules, test them at scale in silico and filter out promising candidates. The next challenge is to find more biological targets using AI.

“The holy grail is that you put those two things together, and we can model the whole system at once,” Ricks said.

Huang and Ricks also discussed Lilly’s long history of harnessing computing for pharmaceutical research — and how diseases of the aging brain are the next frontier for drug discovery.

“I can’t imagine a more worthy field to apply computer science to,” Huang said. “Hopefully we can bend the arc of history.”

NVIDIA at J.P. Morgan Healthcare

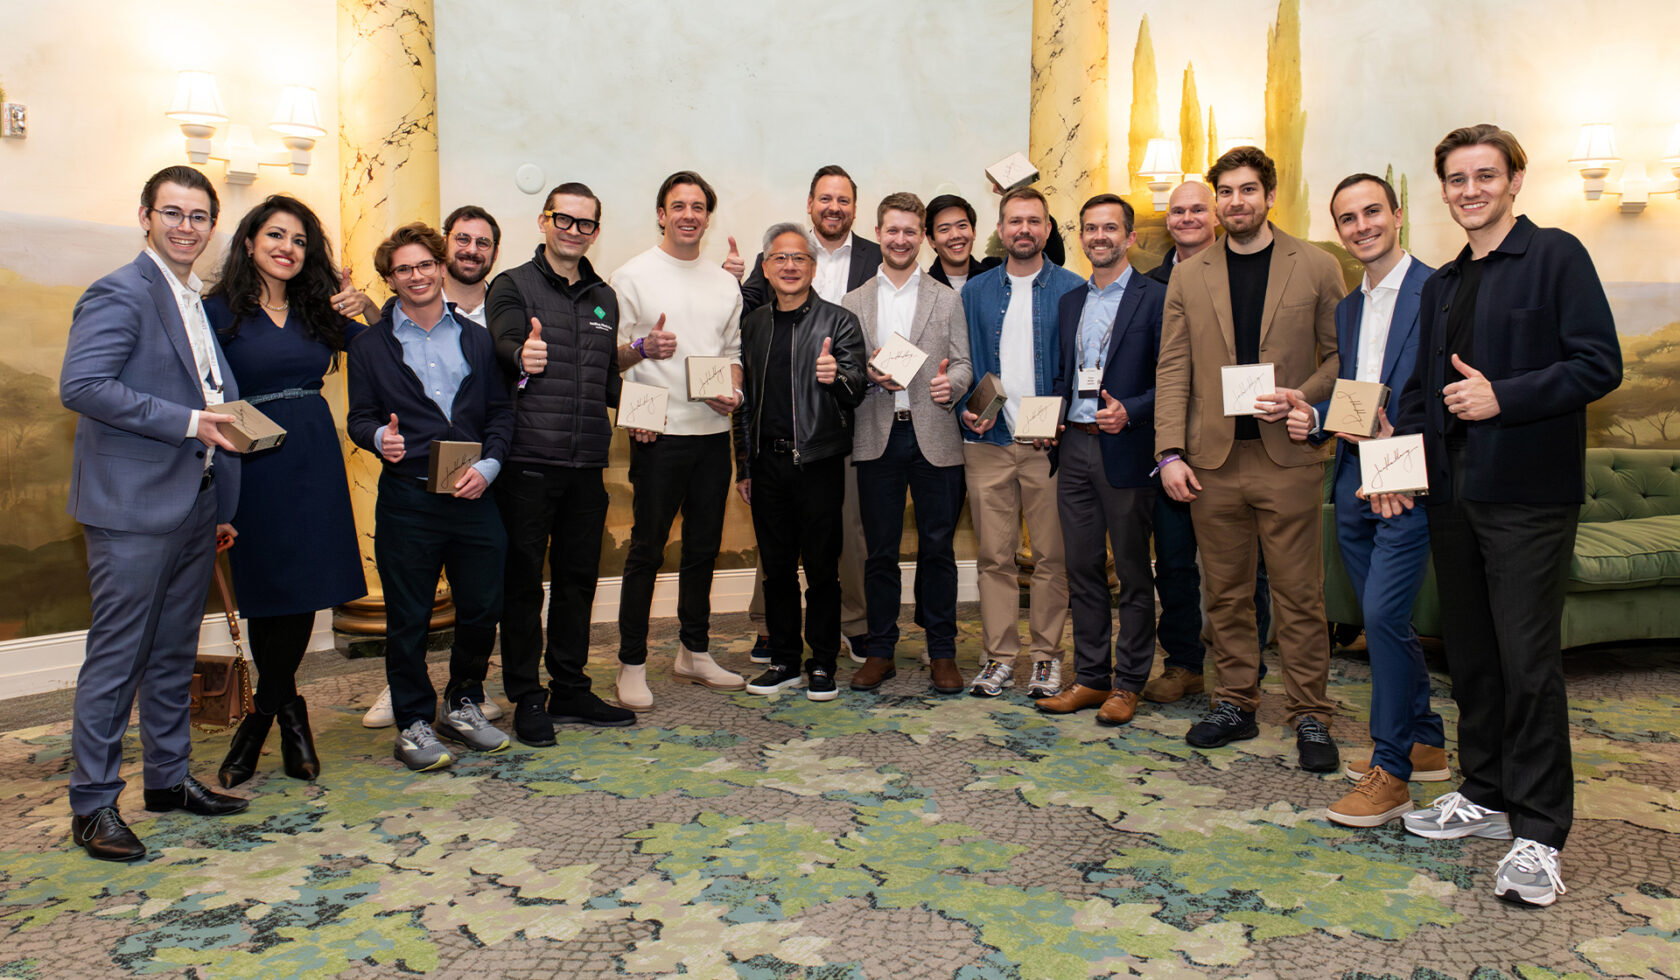
NVIDIA’s full-stack AI platform is accelerating the creation and deployment of leading foundation models across digital biology and drug discovery. To recognize some of the recent advancements, Huang raised a toast at J.P. Morgan Healthcare in honor of about a dozen leaders in the field — and the AI models they’ve pioneered.

“In the last 10 years, we’ve advanced AI 1 million times,” Huang said. “I believe that over the next 10 years, you will enjoy the same adventure that I’ve enjoyed in our generation … and so for each one of you — for your happy new year present and a thank you for everything that you do for the industry and for the future of humanity — I give to you a DGX Spark.”

Over a dozen leaders in AI and drug discovery received NVIDIA DGX Spark systems signed by NVIDIA founder and CEO Jensen Huang at the J.P. Morgan Healthcare Conference.

The honorees included:

  • Zach Carpenter, CEO of VantAI, developer of the Neo model family for co-folding and design across all biological molecules.
  • Gabriele Corso, CEO of Boltz, creator of one of the most well-established open-source families of biomolecular models.
  • Evan Feinberg, CEO of Genesis Molecular AI, which developed Pearl, a protein and small molecule structure prediction model.
  • Chris Gibson and Najat Khan, chairman and CEO, respectively, of Recursion, which developed the OpenPhenom vision transformer model for microscopy data.
  • Glen Gowers, CEO of Basecamp Research, creator of EDEN, a biodiversity-scale genome language model family.
  • Brian Hie, innovation investigator at the Arc Institute, which was a major collaborator in the development of Evo 2, part of the Evo family of DNA language models.
  • Max Jaderberg, president of Isomorphic, which is extending the capabilities of AlphaFold, the defining family of protein structure and interaction models.
  • Simon Kohl, CEO of Latent Labs, developer of the Latent-X family of generative models for protein sequence and structure.
  • Joshua Meier, CEO of Chai Discovery, which developed the Chai family of generative AI models for molecular structure prediction and design.
  • Tom Miller, cofounder and CEO of Iambic Therapeutics, developer of the NeuralPLexer model family for flexible, accurate and fast structure prediction for proteins and small molecules.
  • Alex Rives, head of science at Biohub, which created the ESM family of leading protein language models.
  • Alex Zhavoronkov, CEO of Insilico Medicine, which built Pharma.AI, an integrated model suite spanning target discovery, generative chemistry and clinical prediction.

At J.P. Morgan Healthcare, NVIDIA also announced a major expansion of the NVIDIA BioNeMo platform for AI-driven biology and drug discovery with tools including:

  • NVIDIA Clara open models for predicting RNA structures and ensuring AI-designed drugs are practical to synthesize.
  • BioNeMo Recipes to accelerate and scale biological foundation model training, customization and deployment.
  • BioNeMo data processing libraries such as nvMolKit, a GPU-accelerated cheminformatics tool for molecular design.

NVIDIA also highlighted a collaboration with instrumentation leader Thermo Fisher to build autonomous lab infrastructure using NVIDIA’s full-stack AI computing — and highlighted the work of Multiply Labs, a San Francisco-based startup that offers end-to-end robotic systems to automate cell therapy manufacturing at scale.

J.P. Morgan Healthcare is the world’s largest healthcare investment symposium, attracting over 8,000 global professionals including investors, policymakers and executives from across the healthcare industry.

For more from the conference, listen to the audio recording and view the presentation deck of a special address by Kimberly Powell, vice president of healthcare at NVIDIA, who discusses AI’s impact across healthcare.

CoreWeave CEO defends AI circular deals as ‘working together’


It’s been quite the year for CoreWeave. In March, the AI cloud infrastructure provider went public in one of the biggest and most anticipated IPOs of the year that didn’t live up to its hype.

Another setback took place in October, when a planned acquisition of the cloud provider’s business partner, Core Scientific, faltered due to skepticism from the acquisition target’s shareholders. 

In the meantime, the firm has acquired a number of different companies, its stock has gone up and down, and it’s been both criticized and lauded for its role in the booming AI data center market. 

In an interview at the Fortune Brainstorm AI summit in San Francisco on Tuesday, CoreWeave’s co-founder and CEO, Michael Intrator, defended his company’s performance from critics, noting that it was in the midst of creating a “new business model” for how cloud computing can be built and run. Their collection of Nvidia GPUs is so valuable, they borrow against it to help finance their business. The executive seemed to imply: If you’re charting a new path, you’re destined to encounter some road bumps along the way.  

“I think people are myopic a lot of times,” Intrator said when questioned about his company’s occasionally unstable stock price. “Yes, it is seesawing,” he admitted, while noting that the CoreWeave IPO took place not long before President Trump’s tariffs went into effect — a notably uncertain moment for the overall economy. 

“We came out into one of the most challenging environments, right around Liberation Day and, in spite of the incredible headwinds, were able to launch a successful IPO,” the CEO told Brainstorm editorial director Andrew Nusca. “I couldn’t be prouder of what the company has accomplished,” he added. 

CoreWeave’s stock may have debuted amid the economic doldrums of March but its price has gone on quite the journey since then. It debuted at $40 and, over the past eight months, has climbed to well over $150, but currently rests at around $90. Its more wary critics have compared it to a meme stock due to its penchant for going up and down. 

Techcrunch event

San Francisco
|
October 13-15, 2026

Some of the uncertainty around CoreWeave’s stock has been credited to the company’s hefty level of debt. Not long after CoreWeave announced a deal on Monday to issue even more debt to finance its data center buildout, its stock dropped some 8%.

Intrator seems to see his company as a disruptor, one whose unconventional tactics may take some getting used to. “When you introduce a new model, when you introduce a new way of doing business, when you disrupt what has been a static environment, it’s going to take some people some time,” he said during his appearance Tuesday. 

CoreWeave actually started its corporate life as a crypto miner but in short order built itself into a pivotal provider of “AI infrastructure” to some of the tech industry’s most major players. In that role, it provides GPUs to AI developers and has made major partnerships with Microsoft, OpenAI, Nvidia, Meta, and other tech titans.  

Another topic broached Tuesday was the notion of “circularity” within the AI industry. “Circular” business deals, in which a small number of powerful AI companies invest in one another, have frequently been criticized and have raised questions about the industry’s long-term economic stability. Perhaps not surprisingly, since Nvidia is one of its investors and its supplier of GPUs, Intrator swatted away such concerns. “Companies are trying to address a violent change in supply and demand,” he said. “You do that by working together.”
 
Since the IPO, CoreWeave has continued to make efforts to expand its business. After it acquired Weights & Biases, an AI developer platform, in March, it went on to acquire OpenPipe, a startup that helps companies create and deploy AI agents through reinforcement learning. In October, it also made deals to acquire Marimo (the creator of an open source notebook) and Monolith, another AI company. It also recently announced an expansion of its cloud partnership with OpenAI and said it has plans to move into the federal market, where it wants to provide cloud infrastructure to U.S. government agencies and the defense industrial base. 

The State of AI 2025: Why Trust Matters More Than Ever


AI’s Growing Pains

The 2025 State of AI Report marks something of a watershed moment. After years of racing to see what AI could accomplish, we’re finally asking the tough questions about whether we should trust it to do those things at all.

Just because something is powerful doesn’t make it trustworthy or reliable. Today’s AI systems are remarkable. They write, they code and they converse, but these are all predictions that don’t come with an explanation as to why they did what they did. And if you’re running a financial institution, an insurance company, or an accounting firm, that’s a big compliance problem.

When you can’t explain how a system reached its conclusion, you can’t defend that decision to regulators, customers, or your own board. The good news is we seem to be moving past the era of taking AI’s word for it and into one where we need answers we can trust.

What’s Changed

This year’s report reveals several trends that all point in the same direction: trust has become the make-or-break factor for enterprise AI adoption.

Regulation is no longer playing catch-up. The EU AI Act and US financial guidelines aren’t suggestions anymore. Boards want to know not just does it work? but can we prove it is correct? For the first time, regulators are getting ahead of the curve, not chasing it.

Highly regulated industries need explainability. Banks, insurers, auditors, healthcare providers, the sectors that need AI most urgently, also face the strictest requirements. They have to demonstrate their automated decisions are fair, consistent, and compliant. Building AI that has these attributes has not been easy, but necessary to close the gap from PoC to production. In short, it’s where the real value lies.

Agentic AI has emerged as the go-to architecture, adopting the principle of breaking down complex problems to be tackled by smaller agents, all with their own specialist function. This has introduced new risks. 

Everyone’s excited about the potential of AI agents that are provided with the “agency” to take action, but rightly remain concerned about the implications. The probabilistic nature of the Large Language Models (LLMs) that power such agents means that the institutional knowledge which is prompting them is not a precise programming instruction. Common approaches like prompting, RAG and Graph-RAG lack engineering precision. So although an agentic approach looks to simulate a logical process, it isn’t. Each agent still suffers the innate limitations, lacking precision, determinism and auditability.

Perhaps the biggest shift is conceptual. 

A knowledge-first approach beats a data-first approach. 

Instead of training models on historical data, which incidentally typically results from a documented human process, we can take knowledge sources and use them to build “world models” that describe the underlying principles of decision-work. The key to quality decisioning is being able to scale institutional knowledge, and make that a “first-class citizen” in AI systems, leverageable with precision. 

The future belongs to AI that can logically reason over the world, not just make predictions based on publicly trained data.

The Fundamental Problem

Current Gen AI systems share one critical flaw: they don’t know when they’re wrong. They generate answers that sound right because they’re statistically probable, not because they’re logically calculated.

For creative work, that’s fine. LLMs are ideal for creating marketing content for example, but not for ensuring that marketing content meets compliance obligations. For high-stakes decisions: loan approvals, insurance claims, tax filings, medical eligibility, it’s unacceptable. In high-stakes applications you need precision, consistency and an audit trail that describes how that decision was reached. 

We founded Rainbird on a simple principle: if a system can’t explain its reasoning, it can’t be trusted where it matters. 

You need systems that reason over what’s important to you, your institutional knowledge, without being knocked off course by publicly trained data. You need to be able to generate the same answer from the same inputs, every single time. Determinism matters! And finally you need to understand the reasoning, not an ad-hoc after-the-event prediction as to what might have happened, but the logic that led to an outcome. This is the difference between believing its the right answer and being able to prove it’s the right answer.

A Different Approach

Our approach combines three elements. 

First, the modelling of knowledge as graph-based world models that represent the rules, regulations, and expertise required for a specific decision domain. 

Second, a powerful symbolic reasoning engine that can process knowledge with the same mathematical precision that Excel processes numbers. A deterministic engine that produces consistent, auditable results with a clear trail showing how each conclusion was reached.

Third, LLMs but only where they are strong: understanding natural language and extracting knowledge, but not as a proxy for reasoning where they are inherently weak.

This gives enterprises what they actually need: Gen AI benefits but with none of the risks. Regulated organisations can deploy it readily in decision-intensive processes that are knowledge-dense and there are commercial or regulatory consequences of error. 

Why Trust Matters for Business

Trust isn’t just about doing the right thing, it’s an economic necessity. Our research shows the next trillion dollars in AI value will come from areas where precision, consistency, and auditability aren’t optional: financial crime prevention, tax and audit automation, insurance underwriting, claims, etc.

In these fields, companies don’t just want faster poor decisions, they want better quality decisions that are fully auditable and therefore justifiable. As the inevitable adoption of AI expands, trust becomes more critical than ever, and as much of a competitive advantage as any feature or price.

That’s why the most regulated institutions have started asking “how certain are you that your model is right?” That question will define the next decade of AI adoption. It’s the question we built Rainbird to answer. We didn’t pivot to trust when it became trendy, we started there.

Looking Forward

Ben Taylor and James Duez founded Rainbird in 2013 on what seemed like a contrarian bet: that AI’s future would depend more on being able to make judgements, not just predictions. Twelve years later, the rest of the world has arrived at the same conclusion.

2025 will be remembered as the year AI matured somewhat, when the industry accepted that with power comes responsibility, and that trust in AI is an unquestionable necessity. 

The choice for enterprises and regulators is straightforward: adopt AI that is trustworthy by design, or risk being audited and fined for AI you can’t explain. 

Our goal has always been to help our customers to scale their organisational knowledge to machine levels to deliver consistent, auditable intelligence-led products and services that customers can rely on. The future won’t belong to whoever generates the most content, but to those who can architect AI to deliver trusted solutions. AI that isn’t just powerful, but provable.
Intel’s chief executive of products departs among other leadership changes


Semiconductor giant Intel continues to shake up its senior leadership since Lip-Bu Tan took the helm as CEO in March.

Intel announced Monday that Michelle Johnston Holthaus will depart the company after more than three decades. Johnston Holthhaus was most recently chief executive officer of Intel products and will remain a strategic adviser.

The company also announced the creation of a central engineering group that will build a new custom silicon business for outside customers, according to Intel. This group will be helmed by Srinivasan “Srini” Iyengar who joined Intel from Cadence Design Systems in July.

Intel also said that Kevok Kechichian, formerly of ARM, will join the company as head of its data center group. Jim Johnson has been appointed senior vice president and general manager of Intel’s client computing group. Naga Chandrasekaran, the chief technology and operations officer of Intel Foundry, the company’s business unit that builds custom chips for outside customers, is also taking on an expanded role.

“With Srini leading Central Engineering, we’re aligning innovation and execution more tightly in service to customers,” Tan said in a company press release. “We are laser-focused on delivering world-class products and empowering our engineering teams to move faster and execute with excellence. Kevork, Jim, and Srini are exceptional leaders whose deep technical acumen and industry relationships will be instrumental as we continue building a new Intel.”

This news comes just a few weeks after the U.S. government announced a plan to convert existing government grants into a 10% stake in Intel. The deal was structured to penalize Intel if the company dropped below 50% ownership of its foundry unit.

These weren’t the only leadership changes at Intel this year.

Techcrunch event

San Francisco
|
October 27-29, 2025

Tan taking over as CEO in March is a notable one. In July the company announced that it hired four new people for sales and engineering roles including Greg Ernst to serve as Intel’s chief revenue officer.

Intel declined to comment.