“At its peak in early 2014, Stack Overflow received more than 200,000 questions per month,” notes the site DevClass.com. But in December they’d just 3,862 questions were asked — a 78 percent drop from the previous year.
But Stack Overflow’s blog announced a beta of “a redesigned Stack Overflow” this week, noting that at July’s WeAreDevelopers conference they’d “committed to pushing ourselves to experiment and evolve…”
Over the past year, on the public platform, we introduced new features, including AI Assist, support for open-ended questions, enhancements to Chat, launched Coding Challenges, created an MCP server [granted limited access to AI agents and tools], expanded access to voting and comments, and more.
However, these launches are not standalone features. We have also been rethinking our look and feel, how people engage with Stack Overflow, and how content is created and shared. These new features, along with the redesign, represent how we are bringing Stack Overflow’s new vision to life and delivering value that developers cannot find elsewhere.
Our goal is to build the space for every technical conversation, centered on real human-to-human connection and powered by AI when it helps most. To support this, we are introducing a redesigned Stack Overflow to best reflect this direction… During the beta period, users can visit the beta site at beta.stackoverflow.com and share feedback as we build towards a new experience on Stack Overflow. They’ve updated their library of reusable UI components (buttons, forms, etc.), and are promising “More ways to share knowledge and ask any technical question.” (“Alongside looking for the single right answer to your question, you can now find and share experience-based insights and peer recommendations…”)
They’re launching all the planned features and functionality in April, when “More users will automatically redirect to the new site.” (Starting in April users “can continue to toggle back to the classic site for a limited time.”)
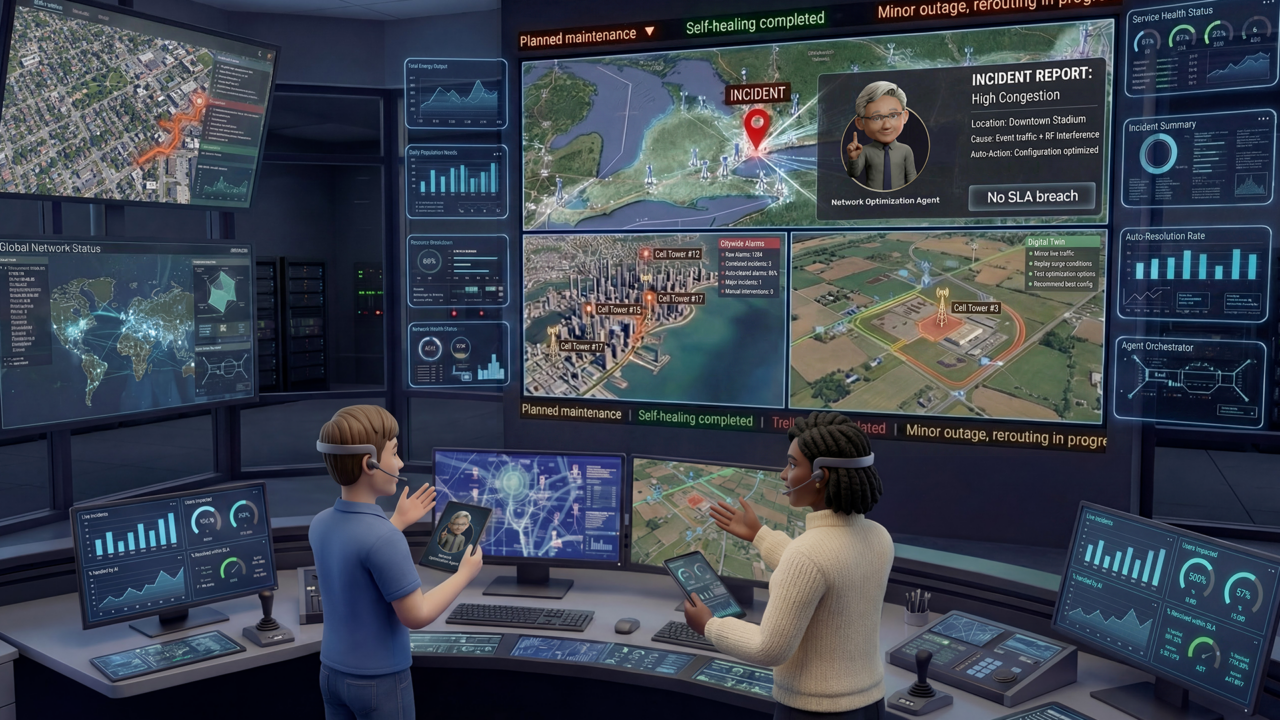
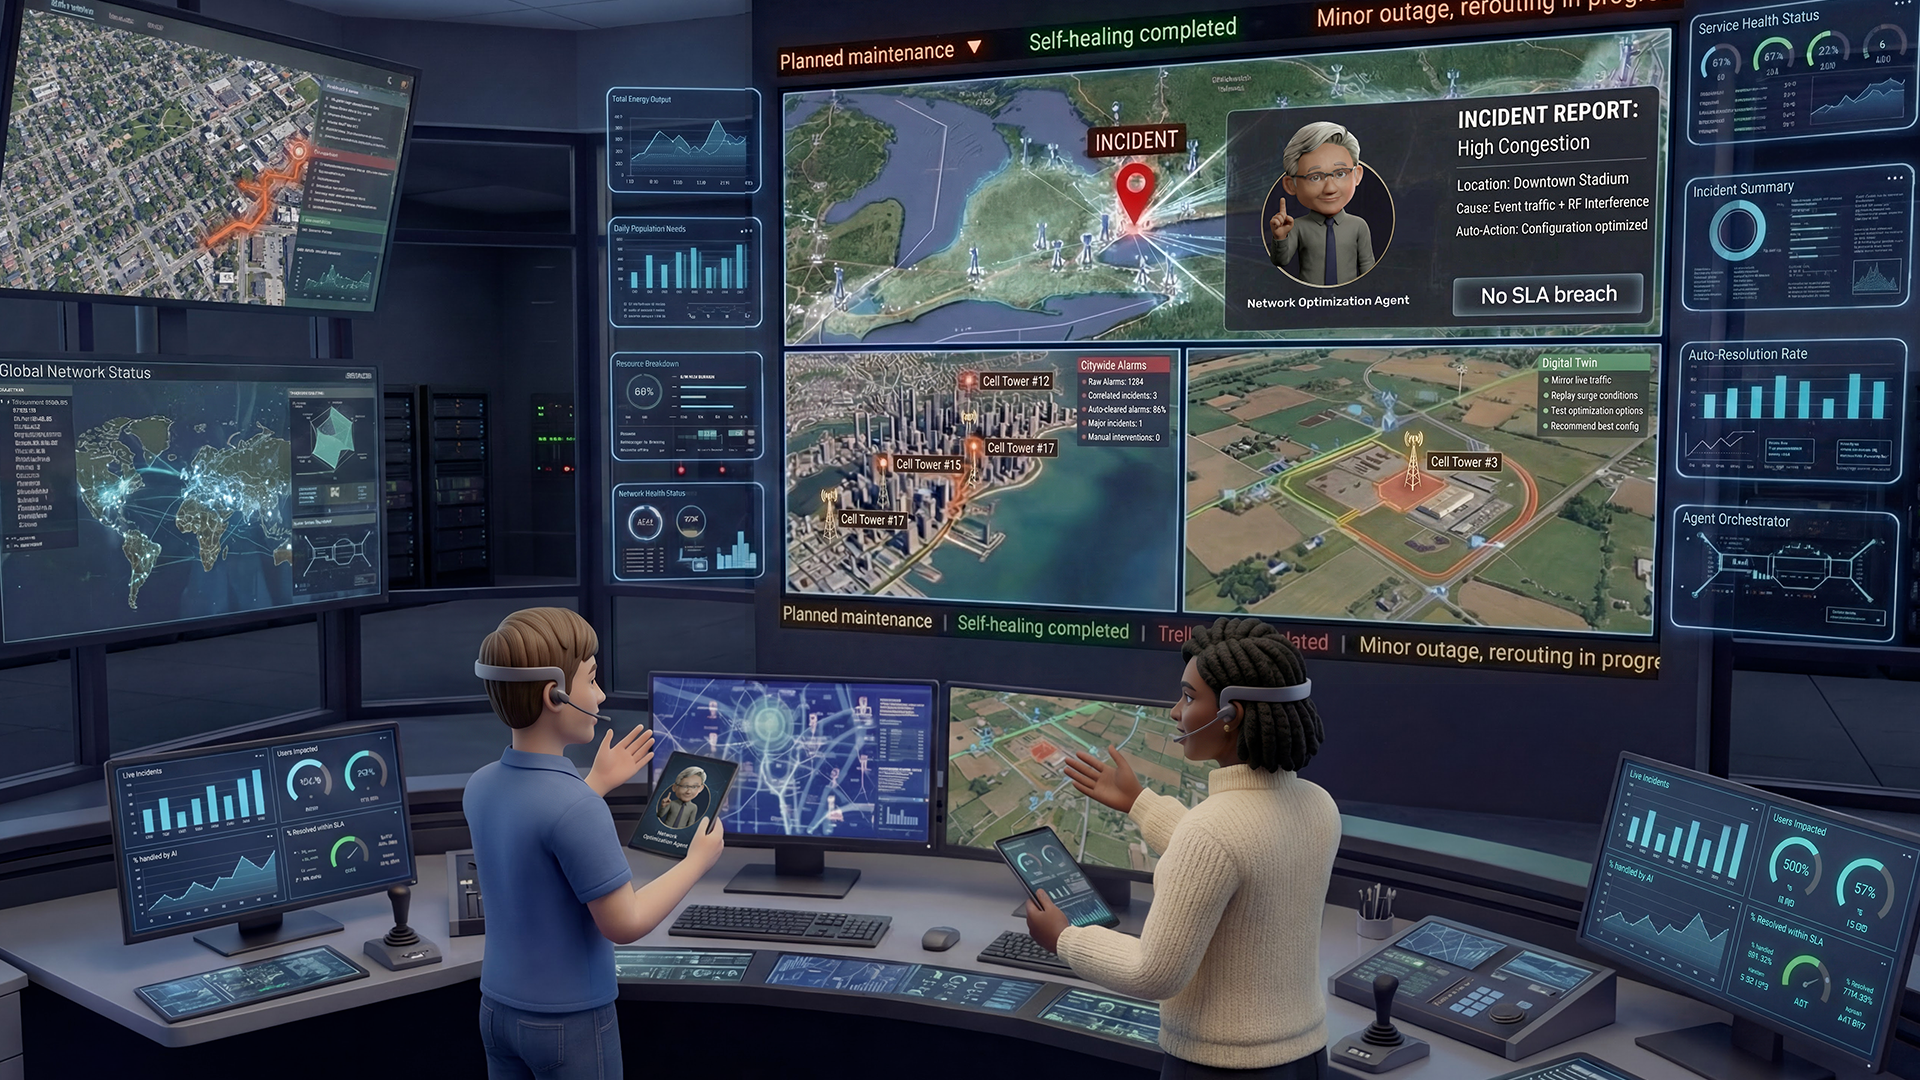
Autonomous networks — intelligent, self-managing telecommunications operations — are moving from a future vision to a current priority for telecom operators. In the latest NVIDIA State of AI in Telecommunications report, network automation emerged as the top AI use case for investment and return on investment.
Automation is different from autonomy. Beyond executing predefined workflows, autonomous networks must understand operator intent, reason over tradeoffs and decide what actions to take. Reasoning models and AI agents fine-tuned on telecom data are key to enabling this shift.
For networks to become autonomous, there’s a need for an end-to-end agentic system that includes key components like telco network models and AI agents that talk to each other and use network simulation tools to validate actions.
Ahead of Mobile World Congress Barcelona, NVIDIA unveiled an open NVIDIA Nemotron-based large telco model (LTM), a comprehensive guide for building reasoning agents for network operations, and new NVIDIA Blueprints for energy saving and network configuration with multi-agent orchestration to help operators advance toward autonomy.
And as part of GSMA’s new Open Telco AI initiative — launching tomorrow — NVIDIA is releasing the new open source LTM, implementation guide and agentic AI blueprints as open resources through GSMA, an organization for the mobile communications industry.
Open Nemotron 3 Large Telco Model Brings Reasoning to Telecom
For telcos to successfully operationalize generative and agentic AI across their operations, AI models must have the ability to understand the language of telecom and reason through complex workflows. NVIDIA has collaborated with AdaptKey AI to release a new open source, 30-billion-parameter NVIDIA Nemotron LTM that operators around the world can use to build autonomous networks.
Built on the NVIDIA Nemotron 3 family of foundation models and fine-tuned by AdaptKey AI using open telecom datasets including industry standards and synthetic logs, the LTM is optimized to understand telecom industry terminology and reason through workflows such as fault isolation, remediation planning and change validation.
As an open model, the Nemotron LTM gives telcos full transparency into how it was trained and what data was used, enabling secure and fast on‑premises deployment within their networks, where they can build and run agents directly. It also lets telcos safely adapt and extend telecom‑tuned reasoning with their own network and operational data, so they can move toward autonomous operations without sacrificing control over data or security.
Teaching AI Agents to Reason Like Network Engineers
NVIDIA and Tech Mahindra have published an open source guide that shows telecom operators how to fine-tune domain-specific reasoning models and build agents that can safely execute network operations center (NOC) workflows.
The guide outlines a framework for teaching models to reason like NOC engineers: focus on high‑impact, high‑frequency incident categories, translate expert resolutions into step‑by‑step procedures and turn those into structured reasoning traces that capture each action, tool call, outcome and decision. These traces become the “thinking examples” the model learns from, so it understands not just what to do, but why a particular sequence of checks and fixes is safe and effective.
Using the NVIDIA NeMo-Skills pipeline, operators can fine-tune a reasoning model on these traces, laying the foundation for telco-specialized AI agents that can reason and solve problems like a network engineer.
Maximizing Energy Efficiency With New Intent-Driven Energy Saving Blueprint
Autonomous networks rely on closed‑loop operation: models that understand the network, agents that act on intent and simulation that feeds results back into the system to validate and refine decisions. The new NVIDIA Blueprint for intent-driven RAN energy efficiency brings these pieces together, helping operators systematically reduce power consumption in 5G radio access networks (RAN) while maintaining quality of service.
The blueprint integrates network test and measurement leader VIAVI’s TeraVM AI RAN Scenario Generator (AI RSG) platform to generate synthetic network data — including cell utilization, user throughput and other traffic patterns — and convert it into a simple, queryable format.
An energy planning agent then reasons over the synthetic data to generate energy-saving policies that can be simulated in AI RSG, allowing operators to safely validate energy-saving policies in a closed loop to meet their intent without changing live configurations or impacting subscribers.
Telcos Put the NVIDIA Blueprint for Network Configuration to Work
Cassava Technologies is using the blueprint to build Cassava Autonomous Network, an agentic platform designed to optimize Africa’s diverse, multi-vendor mobile network environment. The platform implements three agents: one to monitor the network and recommend configuration changes, one to apply changes with documentation and governance, and one to assess the impact of changes made and safely roll them back if they have unintended effects.
NTT DATA is implementing the blueprint to bring intelligence to traffic regulation, helping the network manage surges when users reconnect after an outage, and is deploying it with a tier 1 operator in Japan.
An AI agent looks at real-time demand across the network and then decides when and how to admit new users on specific cells. As conditions stabilize, the agent adapts its decisions, turning what used to be manual configurations into a data-driven optimization cycle for more resilient mobile networks.
Evolving Network Configuration With Multi-Agent Orchestration
BubbleRAN is integrating NAT and BAT into its Opti-Sphere platform to manage network monitoring, configuration and validation agents more flexibly across containers and workloads, and connect them to tools that report network metrics and traffic status so they can continuously propose and validate configuration changes.
Telenor Group will be the first telco to adopt the blueprint with BubbleRAN to enhance its 5G network for Telenor Maritime, the group’s global connectivity provider at sea.
Learn more about the latest advancements in agentic AI for telecommunications at Mobile World Congress, taking place in Barcelona from March 2-5.
See notice regarding software product information.
Ransomware attackers are increasingly employing sophisticated tactics designed to defeat traditional defenses. Relying on basic security is no longer enough to protect your organization’s data. This checklist provides a comprehensive framework to help you develop an effective protection plan, covering everything from email entry points to lateral movement prevention.
In this checklist, you will learn how to:
Protect Your Email: Implement AI-enabled phishing protection and establish ongoing user training to secure your primary entry point.
Secure Your Applications: Utilize Zero-Trust access and network segmentation to prevent attackers from moving laterally through your network.
Fortify Your Backups: Learn why attackers target your backups first and how to protect them using encryption and IP restrictions.
Develop a Recovery Plan: Move beyond technical fixes to establish a full business response plan, including forensic analysis and full-scale testing.
Master the Basics: Close common gaps with updated patching schedules, strong password management, and multi-factor authentication (MFA).
Lenovo has a long-standing habit of showing up to MWC with at least one laptop concept that makes you stop in your tracks and double back for a closer look. Usually, those concepts are eye-catching but clearly something that makes you go – “cool, but never happening.” The ThinkBook Transparent Display Laptop we saw back in 2024 was one such futuristic laptop, but at MWC 2026, things felt different.
It’s not the kind of thing you just admire behind glass; it’s actually something you can see yourself using.
Lenovo showcased its new ThinkBook Modular AI PC concept, and surprisingly, it felt very normal. Don’t get me wrong; this is a good thing. This means the laptop is not the kind of thing you just admire behind glass; it’s actually something you can see yourself using in real life, albeit with some minor tweaks and refinements.
From the front, the ThinkBook Modular AI PC concept looks like any other 14-inch touchscreen business laptop. It’s thin, clean, and professional. There’s nothing about it that instantly screams “concept.” But then you walk around to the back, and that’s where the real story slowly starts to reveal itself.
Firmly attached to the rear lid via pogo pins is a second 14-inch display. It sits flush, almost invisible until you actually see it, and one use case that comes to mind almost immediately is sharing your screen with someone sitting across from you. Instead of awkwardly swiveling your laptop or having people huddle around your screen, you can just have one screen facing you, while the other faces the person across the table. Neat, right? But that’s not all…not by a long shot.
Don’t want to miss the best from Android Authority?
That secondary display at the back isn’t fixed. In fact, it’s magnetic and detachable, and Lenovo clearly designed it to be more than a gimmick. Pop it off, and you have a whole other portable display that can be mounted using a kickstand. You can use the secondary screen both vertically and horizontally, though it does need power from a separate pogo pin adapter.
Adamya Sharma / Android Authority
Things get even more interesting once you start rearranging the core pieces. The keyboard itself is removable, and you can swap it out for that second display, using the keyboard wirelessly with what’s now a dual-screen workstation.
The way all of this just works didn’t feel like I was using a concept laptop; it felt like I was using a laptop that just happened to be way more flexible than usual.
Then there are the brilliantly removable and swappable ports. The IO modules can physically shift from left to right (and vice versa) depending on how your desk or setup looks that day. USB-A, USB-C, and HDMI are all modular and move for your convenience. There’s even a small case that stores the removable ports, so you don’t lose them once they are out of the laptop.
The ThinkBook Modular AI PC feels more like Lenovo is testing what it should do next.
Under the hood, the ThinkBook Modular AI PC gets an Intel Core Ultra 7 255H processor, 32GB memory, and 1TB of M.2 PCIe SSD storage. There’s a 33Wh battery powering the whole thing, which is quite unfortunate, but then again, the story here isn’t the specs. This is a concept laptop, and one that Lenovo can always refine and upgrade if it ever becomes a reality. We may never see the whole laptop release as is, but parts of its modular design could very well show up in Lenovo’s retail units in the future.
Lenovo has shown ambitious modular ideas before, and several of them have quietly turned into shipping products over the years. Similarly, the ThinkBook Modular AI PC doesn’t feel like Lenovo is showing off what it can do; it feels more like Lenovo is testing what it should do next.
Thank you for being part of our community. Read our Comment Policy before posting.
Nested Lands is a ruthless medieval RPG game featuring in-depth village building, large-scale social management and combats. Gather survivors, build a settlement, craft, master your skills, survive, and endure alone or in online co-op.
Nested Lands is a multiplayer settlement-building RPG set in a dark, plague-ravaged world where twisted madmen and bandits roam the land. Your life will depend on how well you manage and grow your settlement. Fortunately, you’re not alone in this dark world — your peasants will help you gather resources, craft items, and build defenses as you lead them through danger and privation. But remember, every choice you make has consequences and can lead your village to prosperity or a senseless death from the plague.
BUILD YOUR SETTLEMENT
Start from a clean slate and build a brand-new civilization. Assign each peasant a specific role and order them to build, craft, or gather the resources you need to survive the hardships you will face. With dozens of upgradable buildings and hundreds of items to craft and customize, including farms and animals, you’re free to shape your settlement as you see fit. Call of Duty: Black Ops 6
RECRUIT YOUR ALLIES
The only way to break through the endless darkness of Nested Lands is to gather the other survivors who share your plight, but have yet to fully give up hope. Save and recruit peasants during your journey across the world. But keep in mind that they will need your protection.
MAKE YOUR NAME
Start from nothing. Rise from the bottom, overcome monumental challenges, and make your fame echo across the Nested Lands. But be careful – all your decisions will be carefully watched and evaluated. Will your name be praised by all, or will its very sound instill fear into the common folk who dwell in this open world? The choice is yours.
SURVIVE IN A POST-PLAGUE WORLD
The disfigured nature of the world makes survival even more challenging. Before facing other threats, you need to secure the basics — a lack of medicine can wipe your village out faster than any blade. Craft, improve your skills, and endure the harsh reality of Nested Lands. Brutal weather and the coming winter may be your greatest foes, but random encounters won’t offer any respite.
Features and System Requirements:
Nested Lands is a dark survival city-builder set in a plague-ravaged medieval world.
Establish and grow a settlement while defending it from raids, disasters, and deadly diseases.
Manage resources carefully as hunger, fear, and sickness threaten your people’s survival.
Build walls, train defenders, and make hard moral choices to keep hope alive.
Its grim atmosphere and challenging systems create a tense, immersive survival experience.
Screenshots
SystemRequirements
Minimum
OS *: Windows 10 and above
Processor: Intel(R) Core(TM) i3 or higher
Memory: 16 GB RAM
Graphics: NVIDIA GeForce RTX 3050 4GB or higher
DirectX: Version 12
Storage: 15 GB available space
Support the game developers by purchasing the game on Steam
InstallationGuide
TurnOff Your Antivirus Before Installing Any Game
1 :: Download Game 2 :: Extract Game 3 :: Launch The Game 4 :: Have Fun 🙂
Generative AI has been showing up in games so often these days that I don’t know who to trust anymore. It seems like every day there’s another game studio or publisher plaguing their games with more gen AI voice acting, gen AI chat bots, or gen AI art.
Blizzard developers, however, have come out against gen AI, implying it’s not being used in the development of their games. Overwatch game director Aaron Keller told GameSpot last month that the team isn’t “comfortable” putting “AI-generated content out in front of players.” Former World of Warcraft franchise director John Hight explicitly said no gen AI was being used for the MMO last year, too.
Speaking to Game Informer in a recent interview, WoW: Midnight’s lead composer Leo Kaliski says gen AI isn’t being used to make the score either. “I think we here at Blizzard feel very lucky and happy that we’re not using generative AI,” he says. “We’re just writing what we think is cool, and are happy to do that.”
Kaliski’s comment almost makes it sound like all of Blizzard isn’t using gen AI, which could be true. But given the specificity of the past comments from each team and Blizzard president Johanna Faries’ recent statement to Eurogamer about how the company has a “centralized governance team specifically focused on AI and the role it can or should play in development cycles,” I want to be careful assuming too much here.
That said, I think it’s notable that Blizzard doesn’t seem to be trying to control its messaging around gen AI use, and that it might be allowing the teams to decide if they want to experiment with it or not. This is much different than a CEO who picks up a megaphone and shouts about the glory of AI and how it alone will pioneer the company’s future.
Unfortunately, a lot of this could change at any point, especially when we know just how much Blizzard’s parent company, Microsoft, is determined to inject gen AI into everything it creates. The best we can hope for is that the developers on the inside can keep it away from their games. I wouldn’t be surprised if the relatively new unions at Blizzard are trying to fight this wherever they can.
Keep up to date with the most important stories and the best deals, as picked by the PC Gamer team.
Investors have been pouring billions into AI companies over the past few years, as the technology continues to hold sway in the Valley and thus the world. But not all AI companies are grabbing investor attention.
Indeed, even as it seems every company these days is rebranding to include “AI” in its name, some startup ideas are just no longer in favor with investors. TechCrunch spoke with VCs to learn what investors aren’t looking for in AI software-as-a-service startups anymore.
Popular SaaS categories for investors now include startups building AI-native infrastructure, vertical SaaS with proprietary data, systems of action (those helping users complete tasks), and platforms deeply embedded in mission-critical workflows, according to Aaron Holiday, a managing partner at 645 Ventures.
But he also gave a list of companies that are considered quite boring to investors these days: Startups building thin workflow layers, generic horizontal tools, light product management, and surface-level analytics — basically, anything an AI agent can now do.
Abdul Abdirahman, an investor at the firm F Prime, added that generic vertical software “without proprietary data moats” is no longer popular, and Igor Ryabenky, a founder and managing partner at AltaIR Capital, went deeper on that point. He said investors aren’t interested in anything, really, that doesn’t have much product depth.
“If your differentiation lives mostly in UI [user interface] and automation, that’s no longer enough,” he said. “The barrier to entry has dropped, which makes building a real moat much harder.”
New companies entering the market now need to build around “real workflow ownership and a clear understanding of the problem from day one,” he said. “Massive codebases are no longer an advantage. What matters more is speed, focus, and the ability to adapt quickly. Pricing also needs to be flexible: rigid per-seat models will be harder to defend, while consumption-based models make more sense in this environment.”
Techcrunch event
San Francisco, CA | October 13-15, 2026
Jake Saper, a general partner at Emergence Capital, also had thoughts on ownership. To him, the differences between Cursor and Claude Code are the “canary in the coal mine.”
“One owns the developer’s workflow, the other just executes the task,” Saper continued. “Developers are increasingly choosing the execution over process.”
He said any product dealing with “workflow stickiness” — meaning trying to attract as many human customers as possible to continuously use the product — might find themselves in an uphill battle as agents takeover the workflow.
“Pre-Claude, getting humans to do their jobs inside your software was a powerful moat, but if agents are doing the work, who cares about human workflow?” he told TechCrunch.
He also thinks integrations are becoming less popular, especially as Anthropic’s model context protocol (MCP) makes it easier than ever to connect AI models to external data and systems. This means someone doesn’t need to download multiple integrations or build their own customer integrations; they can just use the MCP.
“Being the connector used to be a moat,” Saper said. “Soon, it’ll be a utility.”
Also, no longer en vogue include the “workflow automation and task management tools that enable the coordination of human work become less necessary if, over time, agents just execute the tasks,” Abdirahman said, citing examples, mainly public SaaS companies whose stocks are down as new AI-native startups arise with better, more efficient technology.
Ryabenky said the SaaS companies struggling to raise right now are the ones that can easily be replicated, he said.
“Generic productivity tools, project management software, basic CRM clones, and thin AI wrappers built on top of existing APIs fall into this category,” he said. “If the product is mostly an interface layer without deep integration, proprietary data, or embedded process knowledge, strong AI-native teams can rebuild it quickly. That is what makes investors cautious.”
Overa, what remains attractive about SaaS is depth and expertise, with tools embedded in critical workflows. He said companies should right now look into integrating AI deeply into their products and update their marketing to reflect that, Ryabenky continued.
“Investors are reallocating capital toward businesses that own workflows, data, and domain expertise,” Ryabenky said. “And away from products that can be copied without much effort.”
I did not expect Running With Scissors to announce a new FPS where you play as a victim of one of the massacres depicted in the original Postal. Then again, I find it wise not to expect anything from Running with Scissors. The developer made its name on stoking outrage with its largely terrible games, though I will concede that Postal 2 was, despite its many, many flaws, ahead of its time in certain ways.
Even so, Flesh & Wire is a twist I didn’t see coming. Described by Running With Scissors as a “horror first-person shooter”, it puts you in the shoes of Angel, a young woman seeking vengeance against the Postal Dude after being caught on the wrong end of his rifle during his 1997 killing spree. The game will involve tracking the Dude across the Arizona desert, battling military forces and your own traumatic memories as you search for vengeance.
Running With Scissors released a trailer for the game to go with the announcement, and on the face of it, Flesh & Wire certainly seems to be striving for a more serious tone than the mainline Postal series, though the combat looks like it needs tightening up even in what little we see of it. I’m also not convinced it’s going to be the most nuanced depiction of struggles with PTSD, given how Angel wraps her arms in barbed wire and can apparently employ supernatural forces to fight enemies.
Flesh & Wire – Official Announcement Trailer | IGN Fan Fest 2026 – YouTube
There’s no doubt that wrangling with the ramifications of the original Postal’s story is an interesting idea, especially given the US’ torrid history with mass shootings in the years since. Do I trust Running with Scissors in handling such material? No! And neither should you!
Nonetheless, I would love to be proven wrong and for Flesh & Wire to turn out great. At the very least, Running With Scissors has time to get the game right. Flesh & Wire isn’t coming out until sometime next year. If in the meantime you want to play a Postal game that doesn’t suck, Hyperstrange’s spinoff Postal: Brain Damaged is an entertaining, if thoroughly disposable, boomer shooter lark.
Keep up to date with the most important stories and the best deals, as picked by the PC Gamer team.
Modern generative‑AI experiences hinge on speed. When a user types a question into a chatbot or triggers a long‑form summarization pipeline, two latency metrics define their experience: Time‑to‑first‑token (TTFT) and throughput. TTFT measures how quickly the first sign of life appears after a prompt; throughput measures how many tokens per second, requests per second or other units of work a system can process. Over the past two years, these metrics have become central to debates about model selection, infrastructure choices and user satisfaction.
In early generative systems circa 2021, any response within a few seconds felt magical. Today, with LLMs embedded in IDEs, voice assistants and decision support tools, users expect nearly instantaneous feedback. New research on goodput—the rate of outputs that meet latency service‑level objectives (SLOs)—shows that raw throughput often hides poor user experience. At the same time, innovations like prefill‑decode disaggregation have transformed server architectures. In this article we unpack what TTFT and throughput actually measure, why they matter, how to optimize them, and when one should take priority over the other. We also weave in Clarifai’s platform features—compute orchestration, model inference, local runners and analytics—to show how modern tooling can support these goals.
Quick Digest
Definitions & Evolution: TTFT reflects responsiveness and psychological perception, while throughput reflects system capacity. Goodput bridges them by counting only SLO‑compliant outputs.
Context‑Driven Trade‑offs: For human‑centric interfaces, low TTFT builds trust; for batch or cost‑sensitive pipelines, high throughput (and goodput) drives efficiency.
Optimization Frameworks: The Perception–Capacity Matrix, Acknowledge‑Flow‑Complete model and Latency–Throughput Tuning Checklist provide structured approaches to balancing metrics across workloads.
Clarifai Integration: Clarifai’s compute orchestration and local runners reduce network latency and support hybrid deployments, while its analytics dashboards expose real‑time TTFT, percentile latencies and goodput.
Defining TTFT and Throughput in LLM Inference
Why do these metrics exist?
The labels may be new, but the tension behind them is old: systems must feel responsive while maximizing work done. TTFT is defined as the time between sending a prompt and receiving the first output token. It captures user‑perceived responsiveness: the moment a chat UI streams the first word, anxiety diminishes. Throughput, in contrast, measures total productive work—often expressed as tokens per second (TPS) or requests per second (RPS). Historically, early inference servers optimized throughput by batching requests and filling GPU pipelines; however, this often delayed the first token and undermined interactivity.
How are they calculated?
At a high level, end‑to‑end latency equals TTFT + generation time. Generation time itself can be decomposed into time‑per‑output‑token (TPOT) and the total number of output tokens. Throughput metrics vary: some frameworks compute request‑weighted TPS, while others use token‑weighted averages. Good instrumentation logs each event—prompt arrival, prefill completion, token emission—and counts tokens to derive TTFT, TPOT and TPS.
Metric
What it measures
Core formula
TTFT
Delay until first token
Arrival → First token
TPOT / ITL
Average delay between tokens
Generation time ÷ tokens generated
Throughput (TPS)
Tokens processed per second
Tokens ÷ total time
Goodput
SLO‑compliant outputs per second
Sum of outputs meeting SLO / total time
Trade‑offs and misinterpretations
Low TTFT delights users but can limit throughput because smaller batches underutilize GPUs. Conversely, maximizing throughput via large batches or heavy prompts can inflate TTFT and degrade perception. A common mistake is to equate average latency with TTFT; averages hide long‑tail percentiles that frustrate users. Another misconception is that high TPS implies good user experience; in reality, a provider may produce many tokens quickly but start streaming after several seconds.
Original Framework: Perception–Capacity Matrix
To help teams visualize these dynamics, consider the Perception–Capacity Matrix:
Quadrant I:High TTFT / Low Throughput – worst of both worlds; often due to large prompts or overloaded hardware.
Quadrant II:Low TTFT / Low Throughput – ideal for chatbots and code editors; invests in quick response but processes fewer requests concurrently.
Quadrant III:High TTFT / High Throughput – batch‑oriented pipelines; acceptable for long‑form generation or offline tasks but poor for interactivity.
Quadrant IV:Low TTFT / High Throughput – aspirational; often requires advanced caching, dynamic batching and disaggregation.
Mapping workloads onto this matrix helps decide where to invest engineering effort: interactive applications should target Quadrant II, while offline summarization can live in Quadrant III.
Expert Insights
Interactive applications depend on TTFT: Anyscale notes that interactive workloads benefit most from low TTFT.
Throughput shapes cost: Larger batches and high TPS maximize GPU utilization and lower per‑token cost.
High TPS can be misleading: Independent benchmarks show providers with high TPS but poor TTFT.
Clarifai analytics: Clarifai’s dashboard tracks TTFT, TPOT and TPS in real time, enabling users to monitor long‑tail percentiles.
Quick Summary
What is TTFT? The time until the first token appears.
Why care? It shapes user perception and trust.
What is throughput? Total work done per second.
Key trade‑off: Low TTFT usually reduces throughput and vice versa.
Why TTFT Matters More for Human‑Centric Applications
Humans hate waiting in silence
Psychologists have shown that people perceive idle waiting as longer than the actual time. In digital interfaces, a delay before the first token triggers doubts about whether a request was received or if the system is “stuck.” TTFT functions like a typing indicator—it reassures the user that progress is happening and sets expectations for the rest of the response. For chatbots, voice assistants and code editors, even 300 ms differences can affect satisfaction.
Operational playbook to reduce TTFT
Measure baseline: Use observability tools to collect TTFT, p95/p99 latencies and GPU utilization; Clarifai’s dashboard provides these metrics.
Optimize prompts: Remove unnecessary context, compress instructions and order information by importance.
Choose the right model: Smaller models or Mixture‑of‑Experts configurations shorten prefill time; Clarifai offers small models and custom model uploads.
Reuse KV caches: When repeating context across requests, reuse cached attention values to skip prefill.
Deploy closer to users: Use Clarifai’s Local Runners to run inference on‑premise or at the edge, cutting network delays.
For chatbots and real‑time translation, aim for TTFT under 500 ms; code completion tools may require sub‑200 ms latencies.
When TTFT should not be prioritized
Batch analytics: If responses are consumed by machines rather than humans, a few seconds of TTFT have minimal impact.
Streaming with heavy generation: In tasks like essay writing, users may accept a slower start if tokens subsequently stream quickly. However, avoid using long prompts that block user feedback for tens of seconds.
Network noise: Optimizing model-level TTFT doesn’t help if network latency dominates; on‑premise deployment solves this.
Original Framework: Acknowledge‑Flow‑Complete Model
This model breaks user experience into three phases:
Acknowledge – the first token signals the system heard you.
Complete – the answer finishes when the last token arrives or the user stops reading.
By instrumenting each phase, engineers can identify where delays occur and target optimizations accordingly.
Expert Insights
Human reading speed is limited: Baseten notes that humans read only 4–7 tokens per second, so extremely high throughput does not translate to better perception.
TTFT builds trust: CodeAnt highlights how quick acknowledgment reduces cognitive load and user abandonment.
Clarifai’s Reasoning Engine benchmarks: Independent benchmarks show Clarifai achieving TTFT of 0.32 s with 544 tokens/s throughput, demonstrating that good engineering can balance both.
Quick Summary
When to prioritize TTFT? Whenever a human is waiting on the answer, such as in chat, voice or coding.
How to optimize? Measure baseline, shrink prompts, pick smaller models, reuse caches and reduce network hops.
When Throughput Takes Priority—Scaling for Efficiency and Cost
Throughput for batch and server efficiency
Throughput measures how many tokens or requests a system processes per second. For batch summarization, document generation or API backends that process thousands of concurrent requests, maximizing throughput reduces per‑token cost and infrastructure spend. In 2025, open‑source servers began to saturate GPUs by continuous batching, grouping requests across iterations.
Operational strategies
Dynamic batching: Adjust batch size based on request lengths and SLOs; group similar length prompts to reduce padding and memory waste.
Prefill‑decode disaggregation: Separate prompt ingestion (prefill) from token generation (decode) across GPU pools to eliminate interference and enable independent scaling.
Compute orchestration: Use Clarifai’s compute orchestration to spin up compute pools in the cloud or on‑prem and automatically scale them based on load.
Goodput tracking: Measure not just raw TPS but the fraction of requests meeting SLOs.
Decision logic
If tasks are offline or machine‑consumed: Maximize throughput. Choose larger batch sizes and accept TTFT of several seconds.
If tasks require mixed human/machine consumption: Use dynamic strategies; maintain moderate TTFT (<3 s) while increasing throughput via disaggregation.
If tasks are highly interactive: Keep batch sizes small and avoid sacrificing TTFT.
Original Framework: Batch‑Latency Trade‑off Curve
Visualize throughput on one axis and TTFT on the other. As batch size increases, throughput climbs quickly then plateaus, while TTFT increases roughly linearly. The “sweet spot” lies where throughput gains begin to taper yet TTFT remains acceptable. Overlays of cost per million tokens help teams choose the economically optimal batch size.
Common mistakes
Chasing throughput without goodput: Systems that achieve high TPS with many long‑running requests may violate latency SLOs, lowering goodput.
Comparing TPS across providers blindly: Throughput numbers depend on prompt length, model size and hardware; reporting a single TPS figure without context can mislead.
Ignoring data transfer: Throughput gains vanish if network or storage bottlenecks throttle token streaming.
Expert Insights
Research on prefill‑decode disaggregation: DistServe and successor systems show that splitting phases enables independent optimization.
Clarifai’s Local Runners: Running inference on‑prem reduces network overhead and allows enterprises to select hardware tuned for throughput while meeting data residency requirements.
Goodput adoption: Papers published in 2024–2025 argue for focusing on goodput rather than raw throughput, signalling an industry shift.
Quick Summary
When to prioritize throughput? For batch workloads, document pipelines, and scenarios where cost per token matters more than immediate responsiveness.
How to scale? Apply dynamic batching, adopt prefill‑decode disaggregation, track goodput and leverage orchestration tools to adjust resources.
Watch out for: High throughput numbers with low goodput; ignoring latency SLOs; not considering network or storage bottlenecks.
Balancing TTFT and Throughput—Decision Frameworks and Optimization Strategies
Understanding the inherent trade‑off
LLM serving involves balancing two competing goals: keep TTFT low for responsiveness while maximizing throughput for efficiency. The trade‑off arises because prefill operations consume GPU memory and bandwidth; large prompts produce interference with ongoing decodes. Effective optimization therefore requires a holistic approach.
Step‑by‑step tuning guide
Collect baseline metrics: Use Clarifai’s analytics or open‑source tools to measure TTFT, TPS, TPOT and percentile latencies under representative workloads.
Tune prompts: Shorten prompts, compress context and reorder important information.
Select models strategically: Small or Mixture‑of‑Experts models reduce prefill time and can maintain accuracy for many tasks. Clarifai allows uploading custom models or selecting from curated small models.
Leverage caching: Use KV‑cache reuse and prefix caching to bypass expensive prefill steps.
Apply dynamic batching and prefill‑decode disaggregation: Adjust batch sizes based on traffic patterns and separate prefill from decode to improve goodput.
Deploy near users: Choose between cloud, edge or on‑prem deployments; Clarifai’s Local Runners enable on‑prem inference for low TTFT and data sovereignty.
Iterate using metrics: Set SLO thresholds (e.g., TTFT <500 ms, TPOT <50 ms) and iterate. Use Clarifai’s alerting to trigger scaling or adjust batch sizes when p95/p99 latencies exceed targets.
Decision tree for different workloads
Interactive with short responses: Choose small models and small batch sizes; reuse caches; scale horizontally when traffic spikes.
Long‑form generation with human readers: Accept TTFT up to ~3 s; focus on stable inter‑token latency; stream results.
Offline analytics: Use large batches; separate prefill and decode; aim for maximum throughput and high goodput.
Original Framework: Latency–Throughput Tuning Checklist
To operationalize these guidelines, create a checklist grouped by categories:
Prompt Design: Are prompts short and ordered by importance? Have you removed unnecessary examples?
Model Selection: Is the chosen model the smallest model that meets accuracy requirements? Should you switch to a Mixture‑of‑Experts?
Caching: Have you enabled KV‑cache reuse or prefix caching? Are caches being transferred efficiently?
Batching: Is your batch size optimized for current traffic? Do you use dynamic or continuous batching?
Deployment: Are you serving from the region closest to users? Could local runners reduce network latency?
Monitoring: Are you measuring TTFT, TPOT, TPS and goodput? Do you have alerts for p95/p99 latencies?
Reviewing this list before each deployment or scaling event helps maintain performance balance.
Expert Insights
Infrastructure matters: DBASolved emphasizes that GPU memory bandwidth and network latency often dominate TTFT.
Prompt engineering is powerful: CodeAnt provides recipes for compressing prompts and reorganizing context.
Adaptive batching algorithms: Research on length‑aware and SLO‑aware batching reduces padding and out‑of‑memory errors.
Quick Summary
How to balance both metrics? Collect baseline metrics, tune prompts and models, apply caching, adjust batches, choose deployment location and monitor p95/p99 latencies.
Framework to use: The Latency–Throughput Tuning Checklist ensures no optimization area is missed.
Key caution: Over‑tuning for one metric can starve another; use metrics and decision trees to guide adjustments.
Case Study – Comparing Providers & Clarifai’s Reasoning Engine
Benchmarking landscape
Independent benchmarks like Artificial Analysis evaluate providers on common models (e.g., GPT‑OSS‑120B). In 2025–2026, these benchmarks surfaced surprising differences: some providers delivered exceptionally high TPS but had TTFTs above four seconds, while others achieved sub‑second TTFT with moderate throughput. Clarifai’s platform recorded TTFT of ~0.32 s and 544 tokens/s throughput at a competitive cost; another test found 0.27 s TTFT and 313 TPS at $0.16/1M tokens.
Operational comparison
Create a simple comparison table for conceptual understanding (names anonymized). The values are representative:
Provider
TTFT (s)
Throughput (TPS)
Cost ($/1M tokens)
Provider A
0.32
544
0.18
Provider B
1.5
700
0.14
Provider C
0.27
313
0.16
Provider D
4.5
900
0.13
Provider A resembles Clarifai’s Reasoning Engine. Provider B emphasizes throughput at the expense of TTFT. Provider C may represent a hybrid player balancing both. Provider D shows that extremely high throughput can coincide with very poor TTFT and may only suit offline tasks.
Choosing the right provider
Startups building chatbots or assistants: Choose providers with low TTFT and moderate throughput; ensure you have instrumentation and the ability to tune prompts.
Batch pipelines: Select high‑throughput providers with good cost efficiency; ensure SLOs are still met.
Enterprises requiring flexibility: Evaluate whether the platform offers compute orchestration and local runners to deploy across clouds or on‑prem.
Regulated industries: Verify that the platform supports data residency and governance; Clarifai’s control center and fairness dashboards help with compliance.
Original Framework: Provider Fit Matrix
Plot TTFT on one axis and throughput on the other; overlay cost per million tokens and capability (e.g., local deployment, fairness tools). Use this matrix to decide which provider fits your persona (startup, enterprise, research) and workload (chatbot, batch generation, analytics).
Expert Insights
Independence matters: Benchmarks vary widely; ensure comparisons are done on the same model with the same prompts to make fair conclusions.
Clarifai differentiators: Clarifai’s compute orchestration and local runners enable on‑prem deployment and model portability; analytics dashboards provide real‑time TTFT and percentile latency monitoring.
Watch tail latencies: A provider with low average TTFT but high p99 latency may still yield poor user experience.
Quick Summary
What matters in benchmarks? TTFT, throughput, cost and deployment flexibility.
Which provider to choose? Match provider strengths to your persona and workload; for interactive apps, prioritize TTFT; for batch jobs, prioritize throughput and cost.
Caveats: Benchmarks are model‑specific; check data residency and compliance requirements.
Beyond Throughput – Introducing Goodput and Percentile Latencies
Why throughput isn’t enough
Throughput counts all tokens, regardless of how long they took to arrive. Goodput focuses on outputs that meet latency SLOs. A system may process 100 requests per second, but if only 30% meet the TTFT and TPOT targets, the goodput is effectively 30 r/s. The emerging consensus in 2025–2026 is that optimizing for goodput better aligns engineering with user satisfaction.
Defining and measuring goodput
Goodput is defined as the maximum sustained arrival rate at which a specified fraction of requests meet both TTFT and TPOT SLOs. For token‑level metrics, goodput can be expressed as the sum of outputs meeting SLO constraints divided by time. Emerging frameworks like smooth goodput further penalize prolonged user idle time and reward early completion.
To measure goodput:
Set SLO thresholds (e.g., TTFT <500 ms, TPOT <50 ms).
Instrument at fine granularity: log prefill completion, each token emission and request completion.
Compute the fraction of outputs meeting SLOs and divide by elapsed time.
Visualize percentile latencies (p50, p95, p99) to identify tail effects.
Clarifai’s analytics dashboard allows configuring alerts on p95/p99 latencies and goodput thresholds, making it easier to prevent SLO violations.
Goodput in the context of emerging architectures
Prefill‑decode disaggregation enables independent scaling of phases, improving both goodput and throughput. Advanced scheduling algorithms—length‑aware batching, SLO‑aware admission control and deadline‑aware scheduling—focus on maximizing goodput rather than raw throughput. Hardware‑software co‑design, such as specialized kernels for prefill and decode, further raises the ceiling.
Original Framework: Goodput Dashboard
A Goodput Dashboard should include:
Goodput over time vs. raw throughput.
Distribution of TTFT and TPOT to highlight tail latencies.
SLO compliance rate as a gauge (e.g., green above 95%, yellow 90–95%, red below 90%).
Phase utilization (prefill vs decode) to identify bottlenecks.
Per‑persona view: separate metrics for interactive vs batch clients.
Integrating this dashboard into your monitoring stack ensures engineering decisions remain aligned with user experience.
Expert Insights
Focus on user‑satisfying outputs: Research emphasises that goodput better captures user happiness than aggregate throughput.
Latency percentiles matter: High p99 latencies can cause a small subset of users to abandon sessions.
SLO‑aware algorithms: New scheduling approaches dynamically adjust batching and admission to maximize goodput.
Quick Summary
What is goodput? The rate of outputs meeting latency SLOs.
Why care? High throughput can mask slow outliers; goodput ensures user satisfaction.
How to measure? Instrument TTFT and TPOT, set SLOs, compute compliance, track percentile latencies and use dashboards.
Emerging Trends and Future Outlook (2026+)
Hardware, models and architectures
By 2026, new GPUs like NVIDIA’s H100 successor (H200/B200) offer higher memory bandwidth, enabling faster prefill and decode. Open‑source inference engines such as FlashInfer and PagedAttention reduce inter‑token latency by 30–70%. Research labs have shifted towards disaggregated architectures by default, and scheduling algorithms now adapt to workload patterns and network conditions. Models are more diverse: mixture‑of‑experts, multimodal and agentic models require flexible infrastructure.
Strategic implications
Hybrid deployment becomes the norm: Enterprises mix cloud, edge and on‑prem inference; Clarifai’s local runners support data sovereignty and low latency.
Configurable modes: Future systems may let users choose between Ultra Low TTFT and Maximum Throughput modes on the fly.
Goodput‑centric SLAs: Contracts will include goodput guarantees rather than raw TPS.
Responsible AI demands: Fairness dashboards, bias mitigation and audit logs become mandatory.
Original Framework: Future‑Readiness Checklist
To prepare for the evolving landscape:
Monitor hardware roadmaps: Plan upgrades based on memory bandwidth and local availability.
Adopt modular architectures: Ensure your serving stack can swap inference engines (e.g., vLLM, TensorRT‑LLM, FlashInfer) without rewrites.
Invest in observability: Track TTFT, TPOT, throughput, goodput and fairness metrics; use Clarifai’s analytics and fairness dashboards.
Plan for hybrid deployments: Use compute orchestration and local runners to run on cloud, edge and on‑prem simultaneously.
Stay up to date: Participate in open‑source communities; follow research on disaggregated serving and goodput algorithms.
Expert Insights
Disaggregation becomes default: By late 2025, almost all production‑grade frameworks adopted prefill‑decode disaggregation.
Latency improvements outpace Moore’s law: Serving systems improved more than 2× in 18 months, reducing both TTFT and cost.
Regulatory pressure rises: Data residency and AI‑specific regulation (e.g., EU AI Act) drive demand for local deployment and governance tools.
Quick Summary
What’s next? Faster GPUs, new inference engines (FlashInfer, PagedAttention), disaggregated serving, hybrid deployments and goodput‑centric SLAs.
How to prepare? Build modular, observable and compliant stacks using compute orchestration and local runners, and stay active in the community.
Key insight: Latency and throughput improvements will continue, but goodput and governance will define competitive advantage.
Frequently Asked Questions (FAQ)
What is TTFT and why does it matter?
TTFT stands for time‑to‑first‑token—the delay before the first output appears. It matters because it shapes user perception and trust. For interactive applications, aim for TTFT under 500 ms.
How is throughput different from goodput?
Throughput measures raw tokens or requests per second. Goodput counts only those outputs that meet latency SLOs, aligning better with user satisfaction.
Can I optimize both TTFT and throughput?
Yes, but there is a trade‑off. Use the Latency–Throughput Tuning Checklist: optimize prompts, choose smaller models, enable caching, adjust batch sizes and deploy near users. Monitor p95/p99 latencies and goodput to ensure one metric doesn’t sacrifice the other.
What is prefill‑decode disaggregation?
It’s an architecture that separates prompt ingestion (prefill) from token generation (decode), allowing independent scaling and reducing interference. Disaggregation has become the default for large‑scale serving and improves both TTFT and throughput.
How do Clarifai’s products help?
Clarifai’s compute orchestration spins up secure environments across clouds or on‑prem. Local runners let you deploy models near data sources, reducing network latency and meeting regulatory requirements. Model inference services support multiple models, with fairness dashboards for monitoring bias. Its analytics track TTFT, TPOT, TPS and goodput in real time.
By using frameworks like the Perception–Capacity Matrix and Latency–Throughput Tuning Checklist, focusing on goodput rather than raw throughput, and leveraging modern tools like Clarifai’s compute orchestration and local runners, teams can deliver AI experiences that feel instantaneous and scale efficiently into 2026 and beyond.
So you have an idea for the next “big” thing that will revolutionize the world. Maybe it struck you in the shower. Maybe it struck you in the wee hours of 3 in the morning when you’re half-awake and chatted with your cat. You drew something vaguely potato-wing-like on a napkin, and now you’re certain that it will shake up at least three markets. To the exhilarating and sometimes frightening world of hardware concept creation!
Hardware development is not a weekend hack-a-thon to build a new app. There are no quick patches or magical “undo” buttons when you find that your prototype’s battery roasts like a toaster oven on steroids. That is precisely why there are concept design services. It is the step that prevents your idea from becoming a costly paperweight.
Startups like to downplay how complicated this stage can be. There are drawings to figure out, user requirements to go over, materials to keep in mind, and prototyping techniques to schedule. Leave any of these behind, and you’ll have something lovely on Instagram but breakable in half when a toddler lays hands on it.
The best news is, you don’t have to do this on your own. Product design service firms are experts at taking goofy ideas and turning them into viable, manufacturable designs. Hiring professionals up front will protect you from unwarranted expense and torturous revisions. Places like Cad Crowd enable you to get in touch easily with seasoned product designers who both know how to be creative and also understand engineering. They’re your concept design safety net.
Here, we will take you through the basics of hardware concept design without blowing your mind with techno-jargon. We will also touch on why sketches matter more than you know, running tests on assumptions without spending a fortune, and what you can expect when working with design services companies. There will be some laughs, some cautionary tales, and plenty of real-world tips along the way. When you are finished, you will have a clear vision for taking your “potato with wings” and making it a polished product that has a legitimate chance at succeeding in the marketplace.
🚀 Table of contents
The thrill and terror of your first hardware idea
All entrepreneurs have experienced that shivery moment when a flash of inspiration hits you. Your mind leaps ahead to the media spotlights, the TED talk, and the yacht you will one day buy. But between your scribbling in the notebook and your first prototype, harsh reality will snap you back to attention with a large rubber glove.
Hardware does not play nice. While software may be a question of painting a virtual image, hardware is a question of sculpting marble. As soon as you take away too much, you can’t just hit “undo.” No, there is something about watching your “innovative” design splatter its initial drop test onto a cold concrete floor. It wobbles, flails, and then your brilliant idea is torn to smithereens like a disappointed LEGO set after a fit from a toddler.
This is where concept design saves your sanity. It has nothing to do with making pretty pictures. Concept design experts ask difficult questions before you invest hard money. It forces you to see options, consider functionality, and consider manufacturability. Good product design services companies will even shoot holes in your plan to prevent it from falling apart literally.
Hardware concept design is really the translation office from your imagination to the factory floor. What you are doing here is taking your idea and making it something that can be translated, tested, and ultimately made.
It involves sketches, renderings, rough models, and lots of “what if” talking. Unlike industrial design, which is deeply interested in form and appearance, or engineering design, which drills into technical detail, concept design is the playpen where art and science meet.
Consider a Venn diagram where one of the circles is “Looks Cool,” and the other is “Actually Works.” Concept design is the lovely overlap. It is why your shiny toy won’t need duct tape to function.
Good concept design is also narrative. A business-grade rendering or mockup tells investors, fellow colleagues, and potential clients, “This exists. This is happening.” And when you use a service like Cad Crowd to source designers, you are not just hiring a pair of hands. You are getting access to people who understand how to take your idea and make them understand clearly without your needing to defend your napkin scribble in a boardroom.
Turning brain sparks into tangible plans
Do not rush off to your CAD software or 3D printing design service just yet. Step back and ask yourself: Does anyone actually need this thing? Founders are prone to falling in love with what they’ve created, only to discover later that no one else wants it either.
Begin with market research. It does not need to be a grueling spreadsheet endurance test. Interview prospective users. Blog. Observe what people grumble about in criticisms of products that already exist. If your device resolves a genuine pain point, you are already ahead of half the startups in the world.
Next, describe your product’s major functions. What is it solving for you? What sets it apart? Keep it brief. There is a temptation to pack it with every conceivable feature. Now your sleek smart toothbrush doubles as a music player, weather checker, and espresso machine. That is feature creep, and it is the bane of good hardware design.
Product design companies can help here, too. They’ve seen what works, what doesn’t, and what eats through a budget faster than “crowdfunding fiasco.” A company you find through Cad Crowd can help your idea flow into a tight, buildable idea without your laying out one dime on tooling.
Sketches, renderings, and rough models
Don’t underestimate the authority of a poor drawing. Some of the greatest products ever created were badly drawn. Perfection isn’t the goal here. Communication is the goal.
Start with pencil sketches. Even if your drawings in elementary school were better, you can still mark principal shapes and functions. Once you have a number of promising leads, go to digital media like CAD.
They enable you to experiment with proportions, dimensions, and mechanical components more accurately.
Your professional design team can bring it to life. They make it possible for stakeholders to see your product as real. Photo-realistic images are something that product design experts can do well. These can be used to entice investors or test consumer appeal on social media. Platforms like Cad Crowd introduce you to designers who can turn your gadget into a million-dollar product before manufacturing a prototype.
If you’re the do-it-yourself type, you can make crude models using foam, cardboard, or even clay. Low-cost models allow you to try out size and ergonomics without jeopardizing expensive materials. You may find that your hand-held device is child-proof but painful for an adult. Worse to find that out than after a complete production run.
Prototyping without burning your wallet
At some point, your sketches and CAD models must leave the virtual world. That is where prototyping fits in. It is like the ugly teenager phase of your product. It is not yet attractive, but it is growing really fast. Rapid prototyping is within surprisingly easy reach. 3D printing lets you make physical models rapidly and inexpensively. You can try out shapes, fit, and even primitive functions without selling your kidney for the price of production. Foam models are another inexpensive way to check ergonomics. They are the action figure figurine form of your product: inexpensive, small, and surprisingly enlightening.
CNC machining costs more but produces more accurate and durable prototypes. It’s convenient if you need to test-run mechanical pieces or stress areas. Regardless of what you choose to do, don’t fall into the thinking trap that your first prototype must be perfect. It is meant to fail where you did not expect it. That is what it is for.
It is at this point that most entrepreneurs fear, believing that defective prototypes will scare away investors or partners. Actually, the fact that you are working towards refining and testing your idea indicates that you are mature. Product design services companies, especially those you can access through Cad Crowd, can guide you through prototyping design services without resource wastage. They know what areas can be started with for trial purposes and what can be done on the next round.
Manufacturing and material considerations prior to pledge
Oh, materials. They are the unsung heroes and sometimes villains of hardware creation. Get it wrong, and your product cracks, warps, or costs more to make than you wanted. Get it right, and you can save money, increase longevity, and get your product to be more appealing.
Start by considering the environment in which your product will exist. Will it see moisture, heat, or abuse? A fashion plastic can be stylish-looking, but it could melt faster than an ice cream cone at the beach on a hot summer day if it’s exposed to high temperatures. Metals are strong but heavy, and some composites are light but stiff. There are always compromises with each.
Manufacturability is as much a consideration as appearance. Some materials are harder to machine, mold, or assemble. If your product requires exotic parts or impossible tolerances, factories will avoid you or charge you an outrageous sum. It is for this reason that hiring a product design services company in the beginning is a good idea. They can identify manufacturing nightmares in advance before you become infatuated with a design that cannot be produced in quantity.
Another thing to consider is sustainability. Consumers have become increasingly conscious of saving the environment (as we all should). By using recyclable materials on your product, you can attract consumers that promotes sustainability. Like the designers from Cad Crowd, they can help you and your engineering design firm find a balance between sustainability, quality, and price.
Designing with product design services firms
Working with a product design services firm is like leaving your baby with a babysitter for the first time. You worry that they will mess it up or, worse still, will attempt to make it “better” in a way you don’t like. But a good design partner will treat your conception carefully and react with proficiency that you can never reproduce by yourself.
Start by looking for prospective partners. Look for portfolios that match your product’s level of style and complexity. Check out reviews and testimonials. Don’t be afraid to ask for references or samples of similar projects.
In any aspect of life, communication is always the key. Always know what you want, especially regarding the project deadline and allocation of money. Ask for updates, even if it’s a drawing or scribbles. A professional designer can’t deliver your expected results if you can’t communicate clearly what you need.
Legal protection is also important. Use of non-disclosure agreements (NDAs) to protect your intellectual property. Most professional CAD design services will require it and will willingly sign.
Platforms like Cad Crowd make it easier for you to complete your team. They can connect you with screen-tested designers and engineers specializing in hardware concept design or CAD. Especially, if you require assistance in creating starting sketches, 3D modeling, or production-ready file preparation, you can find the perfect match for you without wasting months asking for recommendations.
Lastly, don’t forget cooperation is a two-way street. Hear criticism out. Experienced designers may propose changes that maximize usability, minimize cost, or ease manufacturing. While it stings to leave behind your original idea, the changes often are between a product that fails and a product that succeeds.
Common mistakes first-time founders make
Every new hardware startup founder has a horror story to tell. Some of them are funny in hindsight. Some of them are a nightmare. Listening to them can spare you the expensive mistakes.
One of the biggest mistakes in business is adding more features to a product. It all starts with a simple idea, let’s say you want to produce a cooler bottle that keeps drinks cold for longer hours. Next, you want to include a Bluetooth speaker, a cup warmer, and a built-in blender. Now, the final product is more expensive than the latest game console. This reminds you to keep your product simple and not add unnecessary features just because it’s in the latest trend.
Another common mistake is neglect of design for manufacturability services. You may create a beautiful product that looks wonderful, but is impossible to produce at an affordable price. Factories are not magic. If you specify super-tiny tolerances or unique parts never made before, expect stratospheric prices or pleasant rejection letters.
Forgetting to test is another classic repeat offender. You’re convinced your design is perfect, so you launch straight into manufacturing. And you discover that the battery lasts only twenty minutes, or the hinges collapse at slight pressure. Iteration is dull, but it’s much cheaper than recalling ten thousand dead units.
Finally, poor communication can swamp even a good project. When you are vague with your product design services company, you invite miscommunication. Specific instructions, attainable expectations, and regular feedback prevent frustration from both sides. Cad Crowd makes it a lot easier to locate communicative, talented designers, but you still need to speak up.
Iteration isn’t sexy, but this is where the magic happens. Every incredible piece of hardware you adore, from your favorite headphones to your appliances in the kitchen, had thousands of iterations before it went to market. Even Apple and Dyson, those industry giants, test and iterate furiously.
Each revision is picking up something new. Maybe your device is cumbersome to hold, or maybe one button’s placement is confusing for users. These small adjustments, repeated time and again, make a good product into a great product through prototype engineering services.
User testing is worth its weight in gold. Show your prototype to someone who has never seen it before and observe what they do. They will press the wrong button, flip it over, or use it in a way that you never dreamed. It’s an eye-opener, but it teaches you things that no spreadsheet ever could.
Never give up on failure. Treat every mistake as a veil for progress. The earlier your mistakes, the earlier your growth. Work with your product design services company to incorporate critiques, re-doing designs, and building improved prototypes. Cad Crowd’s network of designers can guide you through such loops efficiently and steer clear of wasteful setbacks.
Bonus tips for navigating the wild world of hardware design
Even with the best design, hardware development tends to surprise you. These are some other tricks to put in your regular bag and maybe avoid a surprise crash:
But packaging can shatter or create the first customer impression. Packaging design services decide shipping expenses, shelf life, and even safety. Involve your product design company in packaging decisions. Designers on sites like Cad Crowd can suggest functionalities that are affordable, aesthetic, and functional.
Don’t accept the first manufacturing offer at face value. Research alternatives like injection molding, vacuum forming, or die casting. Another option, usually, will be cheaper or improve the quality. A skilled designer will walk you through the pros and cons without getting bogged down with details.
Real-life situations
Just imagine the pet feeder; the first designs were stunning on paper. However, when the first batch of manufactured products arrived, the hinge on the lid failed after a few cycles. Customers posted videos of cats blissfully trashing the feeders like furry little engineers. The company recalled the product and re-engineered the hinge, an expensive lesson in testing in real-world environments.
And another founder wanted to create a wearable fitness tracker with a revolutionary clasp system. They skipped user testing because “everyone knows how to use a clasp.” But they didn’t. The clasp was so user-unfriendly that customers wore the tracker backwards or broke it attempting to buckle it. A single round of user testing could have avoided months of embarrassment and lost sales.
It’s because of anecdotes like these that iteration, open feedback, and collaboration with product development experts are so crucial. A good designer will not just provide you with neat files. They will burst bubbles in assumptions, suggest ways to make it better, and guide you around pitfalls that have swallowed up other founders whole.
It’s easy to take only care of the physical aspects of your product and neglect branding. Branding, however, is not merely logos and color schemes. Branding is what informs your design decisions from the start. Is your product sleek and futuristic? Friendly and playful? Outdoor-inspired and tough? These decisions determine everything from material selection to button shape.
Your designer can incorporate branding into the concept phase. If, for instance, your company is concerned about sustainability, that should guide your selection of materials and packaging. If your item is aimed at a high-end market, your concept design should be sophisticated and precise. Cad Crowd’s network has designers who know branding as part of the larger picture and will make sure your product and your brand are a natural fit.
Getting ready for manufacturing like a pro
Once you have already planned your product, you must prepare for large-scale production. This is the most underestimated phase for the first-time businessman. For them to create a successful product, they need detailed drawings, clear specifications, and clear illustrations. That’s why sloppy documentation and management can result in a very expensive failure.
Work with your product design services firm to create manufacturing-ready documents. Double-check every measurement, every tolerance, and every material specification. Don’t rely on the manufacturing design firm to “figure it out.” They will produce exactly what you give them, which can mean producing 10,000 pieces with a defect that could have been identified early on.
You ought also to think about production locations. Home-country production can be easier in terms of communication and quality control, but foreign production can be less expensive, but needs to have great screening and perhaps longer lead times. Think in terms of shipping, tariffs, and variations in communication styles. A seasoned global manufacturing designer will make this easier to do.
Holding sanity together through the highs and lows
Hardware construction is a series of rollercoasters. There will be a time when you will wonder why in the world you ever thought that your plan was a good idea, but that’s fine. Remember to surround yourself with positive peers, mentors, or even online communities of fellow founders. Share your stories, and sometimes, a word of encouragement here and there from someone who has walked in your footsteps can make all the difference.
Failures are redirections. These are your long-term motivations. Keep in mind that you’re making something real, that people can hold, use, and keep close to their hearts. That’s worth the headaches. Knowing you’re leaving a legacy.
You now have information, game plans, and a little bit of sound advice. But information does not build a product. Action does. Start sketching. Research your market. Get in touch with a product design services company. Sites like Cad Crowd wait in the wings with a group of good designers who can transform your “someday” idea into a real, producible product.
Don’t wait until your concept is perfected because it won’t be. Perfection is the progress killer. The sooner you get your idea in motion, the sooner you can learn, adapt, and build something amazing. The world doesn’t need another napkin drawing that has been left behind. It needs your idea, refined, experimented with, and ready to take over the world. Request a quote today.
MacKenzie Brown is the founder and CEO of Cad Crowd. With over 18 years of experience in launching and scaling platforms specializing in CAD services, product design, manufacturing, hardware, and software development, MacKenzie is a recognized authority in the engineering industry. Under his leadership, Cad Crowd serves esteemed clients like NASA, JPL, the U.S. Navy, and Fortune 500 companies, empowering innovators with access to high-quality design and engineering talent.