Serious Sam Classic: The First Encounter Direct Download
Serious Sam is a high-adrenaline single-play and 16-player co-operative arcade-action FPS and Gamespot’s Game of the Year 2001!
Serious Sam is a high-adrenaline arcade-action shooter heavily focused on frantic arcade-style single player action. In a world where cyberpunk meets fantasy-fiction and advanced technology is mixed with black magic and psycho-powers, Sam travels through the beautiful world of ancient Egypt and several diverse planets, confronting countless Mental’s minions on his way to the Mental’s base. Demon Tides
Key Features
Frantic Arcade-Style Action – Fight your way through 15+ nightmarish warriors in Mental’s army, including the charging Sirian Werebull, screaming Headless Kamikaze and other crazy monsters, and finally challenge the multi-story Ugh-Zan boss!
Various Environments and Secrets – Unleash mayhem in ancient Egypt. Discover over 80 secrets hidden in the fray!
Special Weapons and Power-Ups – Wreak havoc with a huge arsenal of weapons including Double Shotgun, Rocket Launcher, Minigun and Cannon!
Co-Op Multiplayer – Embrace the mayhem with up to 16 players!
Versus Multiplayer – Drop the gauntlet and let the heavy ordinance fly in incredible Deathmatch and Scorematch!
Split Screen – Huddle up with up to 4-player local split screen co-op and versus modes!
Level Editor – Create your own levels, MODs, textures and other content with the inclusion of the fully featured Serious Editor and Serious Modeller!
Features and System Requirements:
Serious Sam Classic: The First Encounter pits you against massive hordes of enemies in frantic, fast-paced shooting combat.
You get a wide arsenal of weapons, from shotguns to chainguns, each feeling powerful and satisfying.
Levels are large and open, encouraging movement, dodging, and strategic positioning.
Classic arcade-style gameplay with health and armor pickups keeps the action relentless.
Co-op support lets you tackle waves of enemies with friends for even wilder chaos.
Screenshots
SystemRequirements
Minimum
OS *: Windows 95 OSR2, Windows 98, Windows 98SE, Windows ME, Windows NT 4.0 (with Service Pack 5), Windows 2000, Windows XP, Windows Vista or Windows 7 operating system
Processor: AMD K6-3 400MHz, Pentium II or Celeron-A 300MHz
Memory: 64MB
Graphics: full OpenGL compliant 3D accelerator
Hard Drive: 600MB free hard disk space
Support the game developers by purchasing the game on Steam
InstallationGuide
TurnOff Your Antivirus Before Installing Any Game
1 :: Download Game 2 :: Extract Game 3 :: Launch The Game 4 :: Have Fun 🙂
Open-source LLMs and multimodal models are released at a steady pace. Many report strong results across benchmarks for reasoning, coding, and document understanding.
Benchmark performance provides useful signals, but it does not determine production viability. Latency ceilings, GPU availability, licensing terms, data privacy requirements, and inference cost under sustained load define whether a model fits your environment.
In this piece, we’ll outline a structured approach to selecting the right open-source model based on workload type, infrastructure constraints, and measurable deployment requirements.
TL;DR
Start with constraints, not benchmarks. GPU limits, latency targets, licensing, and cost narrow the field before capability comparisons begin.
Match the model to the workload primitive. Reasoning agents, coding pipelines, RAG systems, and multimodal extraction each require different architectural strengths.
Long context does not replace retrieval. Extended token windows require structured chunking to avoid drift.
MoE models reduce the number of active parameters per token, lowering inference cost relative to dense architectures of similar scale.
Instruction-tuned models prioritize formatting reliability over depth of exploratory reasoning.
Benchmark scores are directional signals, not deployment guarantees. Validate performance using your own data and traffic profile.
Durable model selection depends on repeatable evaluation under real workload conditions.
Effective model selection begins with defining constraints before reviewing benchmark charts or release notes.
Before You Look at a Single Model
Most teams begin model selection by scanning release announcements or benchmark leaderboards. In practice, the decision space narrows significantly once operational boundaries are defined.
Three questions eliminate most unsuitable options before you evaluate a single benchmark.
What exactly is the task?
Model selection should begin with a precise definition of the workload primitive, since models optimized for extended reasoning behave differently from those tuned for structured extraction or deterministic formatting.
Say, for instance, a customer support agent for a multilingual SaaS platform. It must call internal APIs, summarize account history, and respond under strict latency targets. The challenge is not abstract reasoning; it is structured retrieval, controlled summarization, and reliable function execution within defined time constraints.
Most production workloads fall into a small number of recurring patterns.
Workload Type
Primary Technical Requirement
Multi-step reasoning and agents
Stability across long execution traces
High-precision instruction execution
Consistent formatting and schema adherence
Agentic coding
Multi-file context handling and tool reliability
Long-context summarization and RAG
Relevance retention and drift control
Visual and document understanding
Cross-modal alignment and layout robustness
Where does it need to run?
Infrastructure imposes hard limits. A single-GPU deployment constrains model size and concurrency. Multi-GPU or multi-node environments support larger architectures but introduce orchestration complexity. Real-time systems prioritize predictable latency, while batch workflows can trade response time for deeper reasoning.
The deployment environment often determines feasibility before quality comparisons begin.
What are your non-negotiables?
Licensing defines enterprise eligibility. Permissive licenses such as Apache 2.0 and MIT allow broad flexibility, while custom commercial terms may impose restrictions on redistribution or usage.
Data privacy requirements can mandate on-premises execution. Inference cost under sustained load frequently becomes the decisive factor as traffic scales. Mixture-of-Experts architectures reduce active parameters per token, which can lower operational cost, but they introduce different inference characteristics that must be validated.
Clear answers to these questions convert model selection from an open-ended search into a bounded engineering decision.
Open-Source AI Models Comparison
The models below are organized by workload type. Differences in context length, activation strategy, and reasoning depth often determine whether a system holds up under real production constraints.
Reasoning and Agentic Workflows
Reasoning-heavy systems expose architectural tradeoffs quickly. Long execution traces, tool invocation loops, and verification stages demand stability across intermediate steps.
Context window size, sparse activation strategies, and internal reasoning depth directly influence how reliably a system completes multi-step workflows. The models in this category take different approaches to those constraints.
Kimi K2.5
Kimi K2.5, developed byMoonshot AI and built on theKimi-K2-Base architecture, is a native multimodal model that supports vision, video, and text inputs via an integrated MoonViT vision encoder. It is designed for sustained multi-step reasoning and coordinated agent execution, supporting a 256K token context window and using sparse activation to manage compute across extended reasoning chains.
Why Should You Use Kimi K2.5
Long-chain reasoning depth: The 256K token window reduces breakdown in extended planning and agent workflows, preserving context across the full length of a task.
Agent swarm capability: Supports coordinated multi-agent execution through an Agent Swarm architecture, enabling parallelized task completion across complex composite workflows.
Sparse activation efficiency: Activates a subset of parameters per token, balancing reasoning capacity with compute cost at scale.
Deployment Considerations
Long-context management. Retrieval strategies are recommended near maximum sequence length to maintain coherence and reduce KV cache pressure.
Modified MIT license: Large-scale commercial products exceeding 100M monthly active users or USD 20M monthly revenue require visible attribution.
GLM-5, developed byZhipu AI, is positioned as a reasoning-focused generalist with strong coding capability. It balances structured problem-solving with instructional stability across multi-step workflows.
Why Should You Use GLM-5
Reasoning–coding balance: Combines logical planning with code generation in a single model, reducing the need to route between specialized systems.
Instruction stability: Maintains consistent formatting under structured prompts across extended agentic sessions.
Broad evaluation strength: Performs competitively across reasoning and coding benchmarks, including AIME 2026 and SWE-Bench Verified.
Deployment Considerations
Scaling by variant: Larger configurations require multi-GPU deployment for sustained throughput; plan infrastructure around the specific variant size.
Latency tuning: Extended reasoning depth should be validated against real-time constraints before production cutover.
MiniMax M2.5
MiniMax M2.5, developed byMiniMax, emphasizes multi-step orchestration and long agent traces. It supports a 200K token context window and uses a sparse MoE architecture with 10B active parameters per token from a 230B total pool.
Why Should You Use MiniMax M2.5
Agent trace stability: Achieves 80.2% onSWE-Bench Verified, signaling reliability across extended coding and orchestration workflows.
MoE efficiency: Activates only 10B parameters per token, lowering compute relative to dense models at equivalent capability levels.
Extended context support: The 200K window accommodates long execution chains when paired with structured retrieval.
Deployment Considerations
Distributed infrastructure: Sustained throughput typically requires multi-GPU deployment; 4x H100 96GB is the recommended minimum configuration.
Modified MIT license: Commercial products must comply with attribution requirements before deployment.
GLM-4.7
GLM-4.7, developed byZhipu AI, focuses on agentic coding and terminal-oriented workflows. It introduces turn-level reasoning controls that allow operators to adjust thinking depth per request.
Why Should You Use GLM-4.7
Turn-level reasoning control. Enables latency management in interactive coding environments by switching between Interleaved, Preserved, and Turn-level Thinking modes per request.
Kimi K2-Instruct, developed byMoonshot AI, is the instruction-tuned variant of the Kimi K2 architecture, optimized for structured output and tool-calling reliability in production workflows.
Why Should You Use Kimi K2-Instruct
Structured output reliability: Maintains consistent schema adherence across complex prompts, making it well-suited for API-facing systems where output structure directly affects downstream processing.
Native tool-calling support: Designed for workflows requiring API invocation and structured responses, with strong performance onBFCL-v3 function-calling evaluations.
Inherited reasoning capacity: Retains multi-step reasoning strength from the Kimi K2 base without extended thinking overhead, balancing depth with response speed.
Deployment Considerations
Instruction-tuning tradeoff: Prioritizes response speed over the depth of exploratory reasoning; workflows that require an extended chain of thought should evaluate Kimi K2-Thinking instead.
Modified MIT license: Large-scale commercial products exceeding 100M monthly active users or USD 20M monthly revenue require visible attribution.
GPT-OSS-120B, released by Open AI, is a sparse MoE model with 117B total parameters and 5.1B active parameters per token. MXFP4 quantization of MoE weights allows it to fit and run on a single 80GB GPU, simplifying infrastructure planning while preserving strong reasoning capability.
Why Should You Use GPT-OSS-120B
High output precision: Produces consistent structured responses, with configurable reasoning effort (Low, Medium, High), adjustable via system prompt to match task complexity.
Single-GPU deployment: Runs on a single H100 or AMD MI300X 80GB GPU, eliminating the need for multi-GPU orchestration in most production environments.
Deterministic behavior. Well-suited for workflows where consistent, exactness-first responses outweigh exploratory chain-of-thought.
Deployment Considerations
Hopper or Ada architecture required: MXFP4 quantization is not supported on older GPU generations, such as A100 or L40S; plan infrastructure accordingly.
Apache 2.0 license: Permissive commercial use with no copyleft or attribution requirements beyond the usage policy.
Qwen3-235B-A22B, developed byAlibaba’s Qwen team, uses a Mixture-of-Experts architecture with 22B active parameters per token from a 235B total pool. It targets frontier-level reasoning performance while maintaining inference efficiency through selective activation.
Why Should You Use Qwen3-235B
MoE compute efficiency: Activates only 22B parameters per token despite a 235B parameter pool, reducing per-token compute relative to dense models at comparable capability levels.
Frontier reasoning capability: Competitive across intelligence and reasoning benchmarks, with support for both thinking and non-thinking modes switchable at inference time.
Scalable cost profile: Offers strong capability-to-cost balance at high traffic volumes, particularly when serving diverse workloads that mix simple and complex queries.
Deployment Considerations
Distributed deployment: Frontier-scale inference requires multi-GPU orchestration; 8x H100 is a typical minimum for full-context throughput.
MoE routing evaluation: Load balancing behavior should be validated under production traffic to avoid expert collapse at high concurrency.
Apache 2.0 license: Fully permissive for commercial use with no attribution clauses.
General-Purpose Chat and Instruction Following
Instruction-heavy systems prioritize response stability over deep exploratory reasoning. These workloads emphasize formatting consistency, multilingual fluency, and predictable behavior under varied prompts.
Unlike agent-focused models, chat-oriented architectures are optimized for broad conversational coverage and instruction reliability rather than sustained tool orchestration.
Qwen3-30B-A3B
Qwen3-30B-A3B, developed by Alibaba’s Qwen team, is a Mixture-of-Experts model with approximately 3B active parameters per token. It balances multilingual instruction performance with hybrid reasoning controls, allowing operators to toggle between deeper thinking and faster response modes.
Why Should You Use Qwen3-30B-A3B
Efficient MoE architecture: Activates only 3B parameters per token, reducing compute relative to dense 30B-class models while maintaining broad instruction capability.
Multilingual instruction strength: Performs reliably across diverse languages and structured prompts, making it well-suited for international-facing products.
Hybrid reasoning control: Supports thinking and non-thinking modes via /think and /no_think prompt toggles, enabling latency optimization on a per-request basis.
Deployment Considerations
MoE routing evaluation: Performance under sustained load should be validated to ensure consistent token distribution; expert collapse under high concurrency should be tested in advance.
Latency tuning: Hybrid reasoning modes should be aligned with real-time service requirements before production cutover.
Apache 2.0 license: Fully permissive for commercial use with no attribution requirements.
Mistral Small 3.2, developed byMistral AI, is a compact 24B model tuned for instruction clarity and conversational stability. It improves on its predecessor by increasing formatting reliability, reducing repetition, improving function-calling accuracy, and adding native vision support for image and text inputs.
Why Should You Use Mistral Small 3.2
Instruction quality improvements: Demonstrates gains onWildBench andArena Hard over its predecessor, with measurable reductions in instruction drift and infinite generation on challenging prompts.
Compact deployment profile: At 24B parameters, it fits on a single RTX 4090 when quantized, simplifying local and edge infrastructure planning.
Consistent conversational stability: Maintains consistent formatting across varied prompts, with strong adherence to system prompts across multi-turn sessions.
Deployment Considerations
Context limitations: Not designed for extended multi-step reasoning workloads; systems requiring deep chain-of-thought should evaluate larger reasoning-focused models.
Hardware note: Running in bf16 requires approximately 55GB of GPU RAM; two GPUs are recommended for full-context throughput at batch scale.
Apache 2.0 license: Fully permissive for commercial use with no attribution clauses.
Coding and Software Engineering
Software engineering workloads differ from general chat and reasoning tasks. They require deterministic edits, multi-file context handling, and stability across debugging sequences and tool invocation loops.
In these environments, formatting precision and repository-level reasoning often matter more than conversational fluency.
Qwen3-Coder
Qwen3-Coder, developed by Alibaba’s Qwen team, is purpose-built for agentic coding pipelines and repository-level workflows. It is optimized for structured code generation, refactoring, and multi-step debugging across complex codebases.
Why Should You Use Qwen3-Coder
Strong software engineering performance. Achieves state-of-the-art results among open-source models onSWE-Bench Verified without test-time scaling, reflecting reliable multi-file reasoning capability across real-world tasks.
Repository-level awareness. Trained on repo-scale data, including Pull Requests, enabling structured edits and iterative debugging across interconnected files rather than isolated snippets.
Agent pipeline compatibility. Designed for integration with coding agents that rely on tool invocation and terminal workflows, with long-horizon RL training across 20,000 parallel environments.
Deployment Considerations
Context scaling: Native context is 256K tokens, extendable to 1M withYaRN extrapolation; large repository inputs require careful context management to avoid truncation at scale.
Hardware scaling by size: The flagship 480B-A35B variant requires multi-GPU deployment; the 30B-A3B variant is available for single-GPU environments.
Apache 2.0 license: Fully permissive for commercial use with no attribution requirements.
DeepSeek V3.2, developed byDeepSeek AI, is a 685B sparse MoE model built on DeepSeek Sparse Attention (DSA), an efficient attention mechanism that substantially reduces computational complexity for long-context scenarios. It is designed for advanced reasoning tasks, agentic applications, and complex problem solving across mathematics, programming, and enterprise workloads.
Why Should You Use DeepSeek V3.2
Advanced reasoning and coding strength. Performs strongly across mathematical and competitive programming benchmarks, with gold-medal results at the 2025 IMO and IOI demonstrating frontier-level formal reasoning.
Agentic task integration. Supports tool calling and multi-turn agentic workflows through a large-scale synthesis pipeline, making it suited for complex interactive environments beyond pure reasoning tasks.
Deterministic output profile. Configurable thinking mode enables precision-first responses for tasks where exact reasoning steps matter, while standard mode supports general-purpose instruction following.
Deployment Considerations
Reasoning–latency tradeoff. Thinking mode increases response time; validate against latency requirements before committing to a default inference configuration.
Scale requirements. At 685B parameters, sustained throughput requires H100 or H200 multi-GPU infrastructure; FP8 quantization is supported for memory efficiency.
MIT license. Allows unrestricted commercial deployment without attribution clauses.
Long-Context and Retrieval-Augmented Generation
Long-context workloads stress positional stability and relevance management rather than raw reasoning depth. As sequence length increases, small architectural differences can determine whether a system maintains coherence across extended inputs.
In RAG systems, retrieval design often matters as much as model size. Context window length, multimodal grounding capability, and inference cost per token directly affect scalability.
Mistral Large 3
Mistral Large 3, released by Mistral AI, supports a 256K token context window and handles multimodal inputs natively through an integrated vision encoder. Text and image inputs can be processed in a single pass, making it suitable for document-heavy RAG pipelines that include charts, invoices, and scanned PDFs.
Why Should You Use Mistral Large 3
Extended 256K context window: Supports large document ingestion without aggressive truncation, with stable cross-domain behavior maintained across the full sequence length.
Native multimodal handling: Processes text and images jointly through an integrated vision encoder, reducing the need for separate OCR or vision pipelines in document-heavy retrieval systems.
Apache 2.0 license: Permissive licensing enables unrestricted commercial deployment and redistribution without attribution clauses.
Deployment Considerations
Context drift at scale: Retrieval and chunking strategies remain essential to maintain relevance near the upper context bound; the model does not eliminate the need for careful retrieval design.
Vision capability ceiling: Multimodal handling is generalist rather than specialist; pipelines requiring precise visual reasoning should benchmark against dedicated vision models before committing.
Token-cost profile: With 675B total parameters across a granular MoE architecture, full-context inference runs on a single node of B200s or H200s in FP8, or H100s and A100s in NVFP4; multi-node deployment is required for full BF16 precision
Matching Use Cases to Models
Most model selection decisions follow recurring patterns of work. The table below maps common production scenarios to the models best aligned with those requirements.
If you’re building…
Start with…
Why
Multi-step reasoning agents
Kimi K2.5
256K context and agent-swarm support reduce breakdown in long execution traces.
Balanced reasoning + coding workflows
GLM-5
Combines logical planning and code generation in a single model
Agentic coding pipelines
Qwen3-Coder, GLM-4.7
Strong SWE-Bench performance and repository-level reasoning stability.
Precision-first structured output systems
GPT-OSS-120B, Kimi K2-Instruct
Deterministic formatting and stable schema adherence.
Multilingual chat assistants
Qwen3-30B-A3B
Efficient MoE architecture with hybrid reasoning control.
Long-document RAG systems
Mistral Large 3
256K context with native multimodal input support.
Visual document extraction
Qwen2.5-VL
Strong cross-modal grounding across document benchmarks
Edge multimodal applications
MiniCPM-o 4.5
Compact 9B footprint suited for constrained environments.
These mappings reflect architectural alignment rather than leaderboard rank.
How to Make the Decision
After narrowing your shortlist by workload type, model selection becomes a structured evaluation grounded in operational reality. The goal is alignment between architectural intent and system constraints.
Focus on the following dimensions:
Infrastructure Alignment
Validate GPU memory, node configuration, and expected request volume before running qualitative comparisons. Large, dense models may require multi-GPU deployment, while Mixture-of-Experts architectures reduce the number of active parameters per token but introduce routing and orchestration complexity.
Performance on Representative Data
Public benchmarks such as SWE-Bench Verified and reasoning leaderboards provide directional signals. They do not substitute for testing on your own inputs.
Evaluate models using real prompts, repositories, document sets, or agent traces that reflect production workloads. Subtle failure modes often emerge only under domain-specific data.
Latency and Cost Under Projected Load
Measure response time and per-request inference cost at expected traffic levels. Evaluate performance under sustained load and peak concurrency rather than isolated queries.
Long context windows, routing behavior, and total token volume directly shape long-term cost and responsiveness.
Licensing, Compliance, and Model Stability
Review license terms before integration. Apache 2.0 and MIT licenses allow broad commercial use, while modified or custom licenses may impose attribution or distribution requirements.
Beyond license terms, assess release cadence and version stability. For API-wrapped models where version control is handled by the provider, unexpected deprecations or silent updates can introduce operational risk. Durable systems depend not only on performance, but on predictable maintenance.
Durable model selection depends on repeatable evaluation, explicit infrastructure limits, and measurable performance under real workloads.
Wrapping Up
Selecting the right open-source model for production is not about leaderboard positions. It is about whether a model performs within your latency, memory, scaling, and cost constraints under real workload conditions.
Infrastructure plays a role in that evaluation. Clarifai’s Compute Orchestration allows teams to test and run models across cloud, on-prem, or hybrid environments with autoscaling, GPU fractioning, and centralized resource controls. This makes it possible to measure performance under the same conditions the model will see in production.
For teams running open-source LLMs, the Clarifai Reasoning Engine focuses on inference efficiency. Optimized execution and performance tuning help improve throughput and reduce cost at scale, which directly impacts how a model behaves under sustained load.
When testing and production share the same infrastructure, the model you validate under real workloads is the model you promote to production.
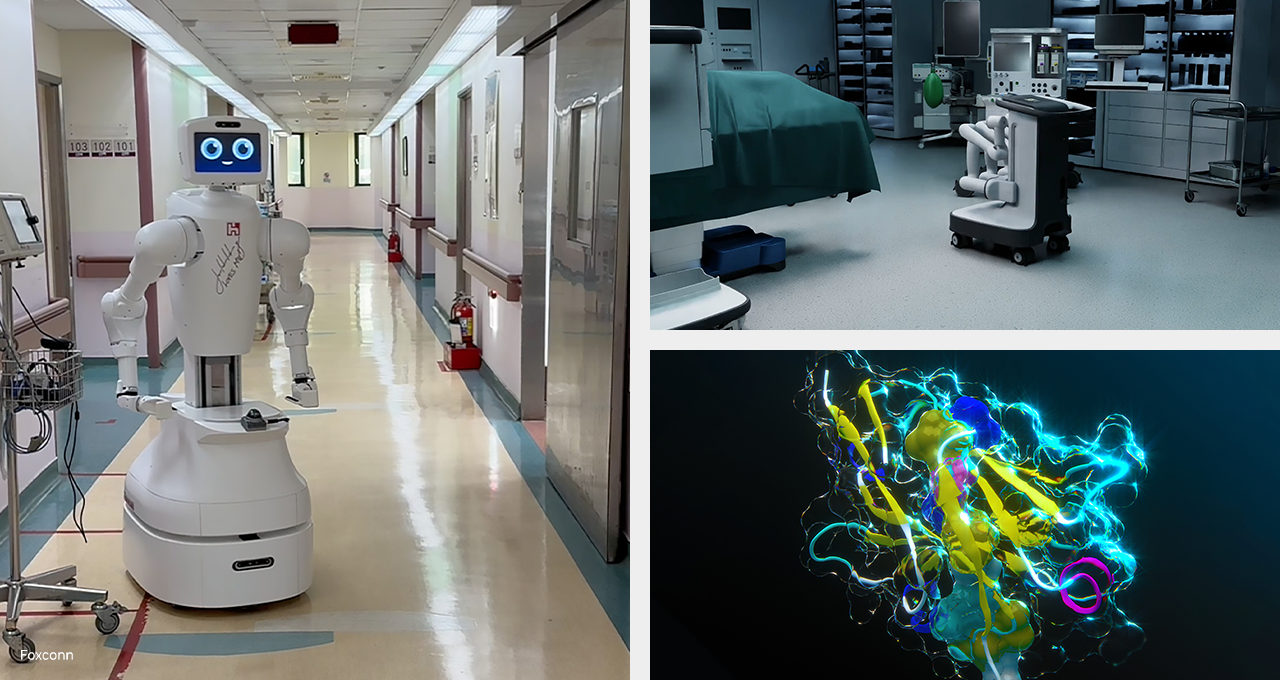
AI is accelerating every aspect of healthcare — from radiology and drug discovery to medical device manufacturing and new treatment methods enabled by digital twins of the human body.
NVIDIA’s second annual “State of AI in Healthcare and Life Sciences” survey report reveals how the industry is moving from AI experimentation to execution, reaping return on investment (ROI) on core applications like medical imaging and drug discovery.
The industry is also embracing open source software and AI models to tackle specific use cases, as well as exploring using agentic AI to speed knowledge retrieval and research paper analysis.
Highlights from this year’s report include:
70% of respondents said their organizations are actively using AI, up from 63% in 2024.
69% said they’re using generative AI and large language models, up from 54%.
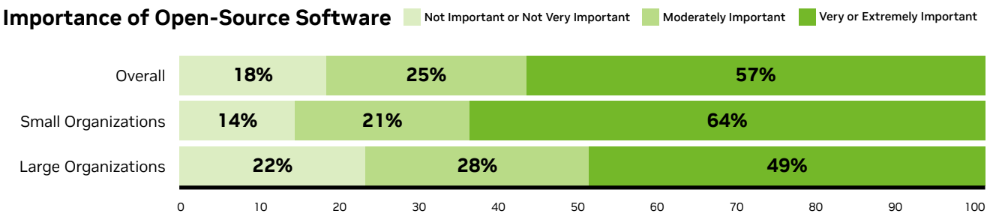
82% said open source software and models are moderately to extremely important to their organizations’ AI strategy.
47% said they’re using or assessing agentic AI.
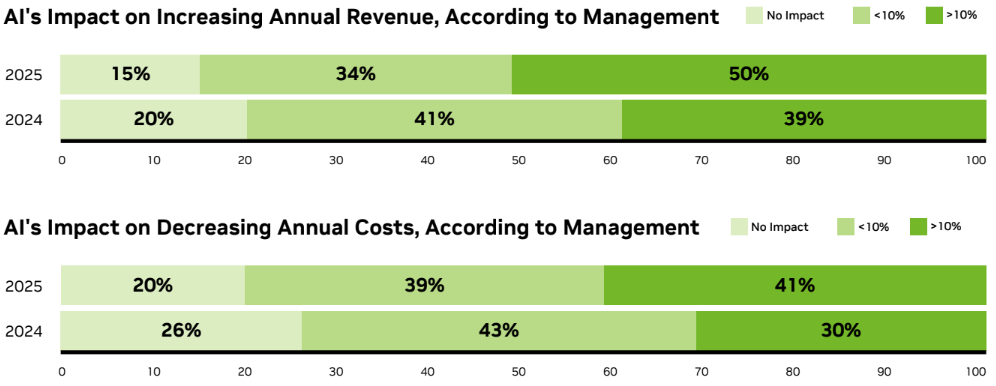
85% of executives said AI is helping increase revenue, and 80% said it’s helping reduce costs.
“Over the next 12-18 months, the most visible and scalable impact of AI will come from logistics and administrative streamlining,” said John Nosta, president of NostaLab, a healthcare think tank. “That’s where adoption curves are already steep — scheduling, documentation, coding, utilization management and care coordination.”
Read more below on some of the report’s key findings.
AI Adoption Ramps Up Across Healthcare and Life Sciences
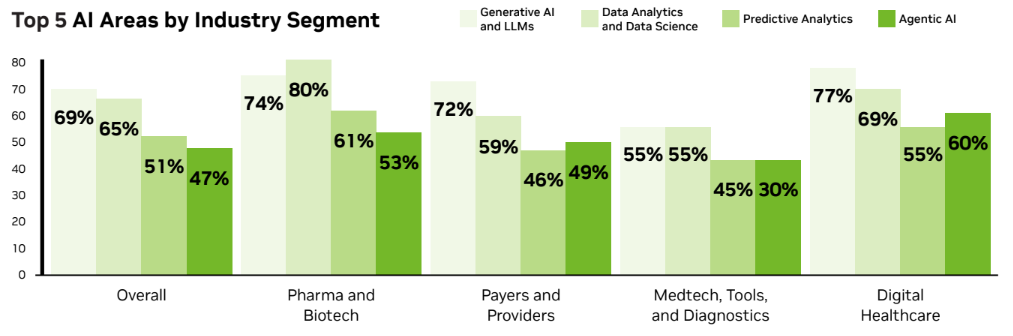
AI adoption is up across every industry segment in this year’s survey — spanning digital healthcare, pharmaceutical and biotechnology, payers and providers, and medical technology and tools — with digital healthcare leading at 78%, followed by medical technology at 74%.
The top industry workload was generative AI and large language models, according to 69% of respondents. AI for data analytics and data science was the second most-used workload, followed by predictive analytics. New to the survey, agentic AI ranked fourth, with 47% of respondents saying they’re using or assessing AI agents.
“Scaling generative AI in healthcare starts with focusing on real clinical and operational problems, rather than the technology itself,” said Dr. Annabelle Painter, clinical AI strategy lead at Visiba U.K. “The organizations seeing impact are those that embed AI into existing workflows instead of layering AI on top as a separate tool.”
Healthcare and life sciences organizations are deploying these AI workloads across a variety of use cases, each specific to their primary functions. For example, 61% of respondents from medical technology said they’re using AI for medical imaging, such as radiologists using it to work more quickly and efficiently, while 57% from pharmaceutical and biotechnology said drug discovery is being driven by AI.
For the entire industry, the top AI use cases were clinical decision support (such as radiologists highlighting areas of concern on a scan), medical imaging and workflow optimization.
AI Budgets to Increase With Strong ROI
AI is helping healthcare and life sciences organizations become even better at their core competencies — underscoring strong ROI.
In addition to increasing annual revenue and reducing annual costs, AI is boosting back-office productivity through workflow optimization and is scaling across other key business operations such as patient interaction and administrative tasks.
For example, 57% of respondents from the medical technology segment reported seeing ROI from deploying AI for medical imaging. Nearly half (46%) of pharmaceutical and biotechnology respondents said AI for drug discovery and development was among their top ROI use cases.
The top ROI use case for digital healthcare providers was virtual health assistants and chatbots, according to 37%, while 39% of respondents from payers and providers (which include hospitals, primary care providers and insurance companies) cited administrative tasks and workflow optimization as their top area of ROI.
As a result of AI’s positive impact, 85% of respondents said their AI budgets would increase this year, with another 12% saying budgets would stay the same. For almost half of respondents (46%), AI spending will increase significantly, by more than 10%.
“Healthcare organizations that successfully integrate AI are those that explicitly fund and prioritize evaluation as a core operational function, ensuring AI delivers measurable improvements in safety, quality and patient care over time,” said Painter.
Using Open Source for Domain-Specific AI Deployment
Leaning into open source models and software allows enterprises to build domain-specific applications, lending them greater flexibility and efficiency while boosting business returns.
The healthcare industry has embraced open source, with 82% of survey respondents stating it’s moderately to extremely important to their AI strategy.
“Open models will shape the intellectual field,” said Nosta. “They are essential for exploration and for keeping the field honest. But in clinical environments where safety, liability and accountability are nonnegotiable, proprietary systems will remain necessary for validation, integration and trust. The key insight here is that discovery will be open, and deployment will demand stewardship.”
Apple is in talks with major Indian banks as it prepares to introduce Apple Pay in the country sometime in the middle of 2026, reports Bloomberg.
Apple is said to be in discussions with ICICI Bank, HDFC Bank, and Axis Bank, according to people with knowledge of the matter who spoke to the publication.
The report corroborates a story in January by Business Standard that said Apple Pay was preparing to go live in the Indian market before the end of the year. The Times of India also earlier reported the India plans for Apple Pay.
Today’s report says Apple is talking through the plan with global payment networks Mastercard and Visa. UPI dominates digital payments in India, and Apple Pay is expected to support the state-backed payments interface, which allows customers to instantly transfer money and bills.
Apple Pay launched more than 10 years ago, and is already available across 89 markets globally. Late last year, India’s central bank approved new rules that allow biometric authentication like Touch ID and Face ID for digital payments. The country’s authentication methods previously relied on one-time passwords sent over SMS messages.
The timing comes at a good moment for Apple in India. The company recorded its highest quarterly shipments in the country during Q3 2025, reaching 5 million units and securing fourth place in the market for the first time, according to IDC data. Apple is also rapidly expanding its retail presence in India, with a sixth store opening in Mumbai on Thursday.
In his Power On newsletter today, Bloomberg’s Mark Gurman said Apple will have a three-day stretch of product announcements from Monday, March 2 through Wednesday, March 4. In total, he expects Apple to introduce “at least five products.”
Subscribe to the MacRumors YouTube channel for more videos.
A week ago, Apple invited selected journalists and content creators to an “Apple Experience” in…
Apple CEO Tim Cook was among a handful of top tech executives who attended a classified CIA briefing warning that China could attack Taiwan by 2027, according to a sweeping investigative report by The New York Times ($).
The previously unreported briefing was apparently held in a secure room in Silicon Valley in July 2023. The meeting is said to have been arranged at the request of the…
Apple’s software engineers are testing iOS 26.3.1, according to the MacRumors visitor logs, which have been a reliable indicator of upcoming iOS versions.
iOS 26.3.1 should be a minor update that fixes bugs and/or security vulnerabilities, and it will likely be released within the next two weeks.
Last month, Apple released iOS 26.2.1 with bug fixes and support for the second-generation…
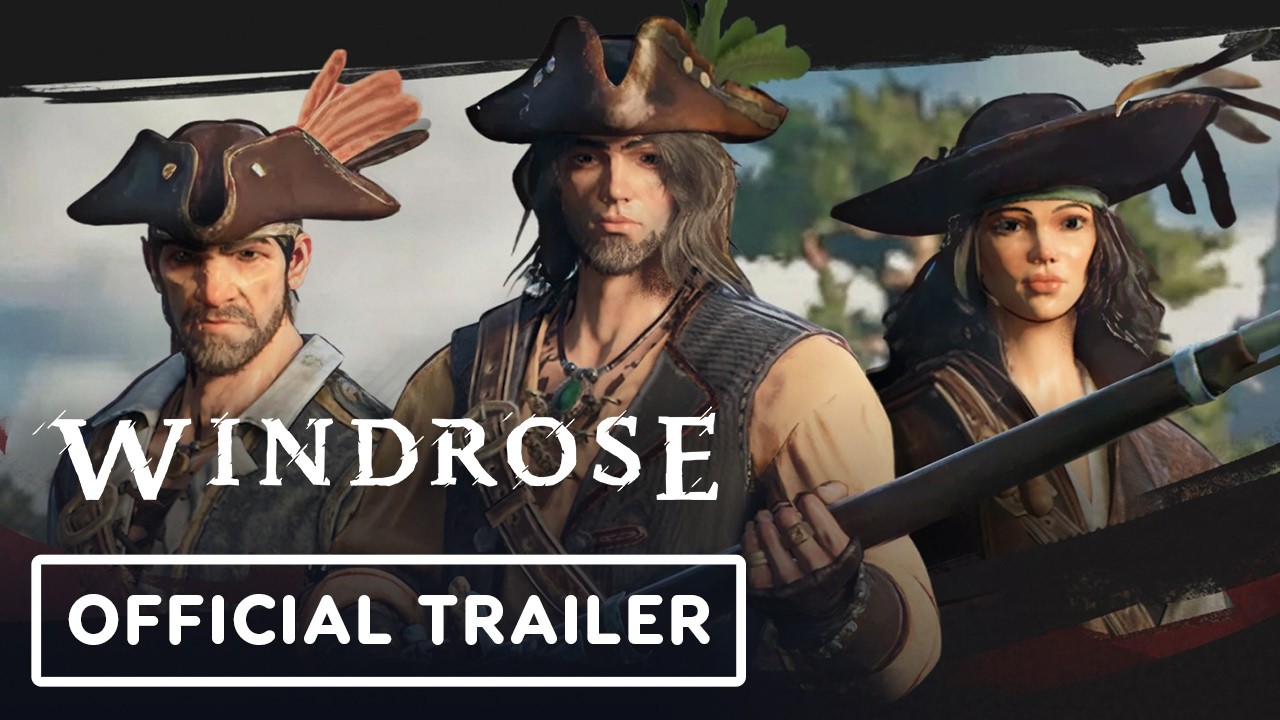
Pirate survival game Windrose is having a moment. It’s one of the most popular demos at Steam Next Fest, it’s got so many concurrent players it shows up on Steam’s most-played charts, and earlier this week it cannonballed to over 1 million wishlists. Plus, its combination of survival systems, open world pirate ship battles, and uplifting sea shanties makes for a heck of a lot of fun.
So when developer Windrose Crew announced a new trailer would be released today, a lot of players (including me) assumed a release date, or at least a release window, would come with it. The trailer shown today for IGN Fan Fest, while boisterous as always, doesn’t give any indication of when the game will be out, however.
Windrose – Official Trailer | IGN Fan Fest 2026 – YouTube
“Guys, I know many of you hoped for the release date reveal today, and we understand your passion—trust me, we are so eager to lock in the date and announce it to you as well,” the development team posted in the game’s official Discord about an hour after the new trailer appeared. “But now is not the time to do it.”
Noting that the full version of the game “could be several times bigger in content and scale than the demo” in terms of numbers of islands, points of interest, ships, and enemies, Windrose Crew said it wants to polish the game further and incorporate some player feedback before taking the step of announcing a release date.
“The process of building the game for you is a huge inspiration, your attention to Windrose is very humbling, but please, let us cook more,” the team said on Discord. “When we feel confident enough, we will announce the release date. I promise, we are not holding this information to tease your anticipation. We are holding it because we want to lock this in firmly and ship the game on time and in [the] best condition possible.”
As Tom Petty, who himself would have made a fine pirate, once said: “Waiting is the hardest part.” But much better to hold back a release date than promise one that can’t be met. I’m sure that boisterous crew of over 1 million wishlist pirates will agree.
Keep up to date with the most important stories and the best deals, as picked by the PC Gamer team.
Want to keep testing your knowledge of gaming trivia? We’ve got loads more PC Gamer quizzes, on everything from healthbars to weird currencies to absurd patch notes.
Can you believe it? Stardew Valley celebrates its 10th anniversary this year, and we’re still talking about free updates to the farming sim that don’t involve overpriced DLC or unnecessary sequels. I’ve learned to simply not listen when creator Eric Barone insists he’s done working on the valley, but I’m not complaining.
Quite the opposite, really. I’m elated we’re getting Stardew Valley 1.7, and despite establishing my millionth agricultural empire after the update’s announcement, I still feel like there’s so much I haven’t seen. That’s partially why I decided to cultivate my own Stardew Valley quiz for the anniversary. I want to know how y’all stack up to my random sampling of knowledge around the farming sim’s lore, mechanics, and secrets.
Though it was tempting to grill you in a time trial of villager likes and dislikes, I decided that’s too easy for the most hardcore farmers. Instead, I’m opting for something a little more comprehensive to get you really rooting around in that almanac of a brain.
So here’s our Stardew Valley quiz, covering everything from gift-giving no-no’s to in-game jokes and rare events. Let us know how you scored—and share your favorite bit of Stardew Valley knowledge in the comments!
Keep up to date with the most important stories and the best deals, as picked by the PC Gamer team.
Chip giant and world’s most valuable company Nvidia reported record profits in its most recent quarter on Wednesday, as demand for AI compute continues to skyrocket.
“The demand for tokens in the world has gone completely exponential,” CEO Jensen Huang said on a call with analysts following the results. “I think we’re all seeing that, to the point where even our six-year-old GPUs in the cloud are completely consumed and the pricing is going up.”
The company reported $68 billion in revenue in the most recent quarter, up 73% from the prior year, with $62 billion of that revenue coming from the company’s data center business.
Notably, Nvidia divided the data center revenue into $51 billion in compute revenue (largely GPUs) and $11 billion in networking products like NVLink. The company reported $215 billion in revenue for the full year.
As in previous quarters, the company did not report any revenue from chip exports to China, despite the recent lifting of export restrictions by the U.S. government. “While small amounts of H200 products for China-based customers were approved by the US government, they have yet to generate any revenue, and we do not know whether any imports will be allowed into China,” Colette Kress, the company’s chief financial officer, said.
“Our competitors in China, bolstered by recent IPOs, are making progress,” she continued, in an apparent reference to Moore Threads’ IPO in December, “and have the potential to disrupt the structure of the global AI industry over the long term.”
During the investor call, Huang also addressed the company’s pending investment in OpenAI, which has been reported at $30 billion.
Techcrunch event
Boston, MA | June 9, 2026
“We continue to work with OpenAI toward a partnership agreement. We believe we are close,” Huang said. He also referenced partnerships with Anthropic, Meta, and Elon Musk’s xAI. However, statements Nvidia filed with the U.S. Securities and Exchange Commission on Wednesday emphasized that there was “no assurance” an investment would take place.
Huang also addressed concerns about the sustainability of tech companies’ capex commitments, saying he believed the compute investments would soon bring revenue.
“In this new world of AI, compute is revenue. Without compute, there’s no way to generate tokens. Without tokens, there’s no way to grow revenues,” Huang said. “We’ve reached the inflection point and we’re generating profitable tokens that are productive for customers and profitable for the cloud service providers”
Broadcom introduced changes to VMware that are especially unfriendly to small- and-medium-sized businesses (SMBs), and Gartner previously predicted that 35 percent of VMware workloads would migrate else by 2028.
CloudBolt’s survey also examined how respondents are migrating workloads off of VMware. Currently, 36 percent of participants said they migrated 1–24 percent of their environment off of VMware. Another 32 percent said that they have migrated 25–49 percent; 10 percent said that they’ve migrated 50–74 percent of workloads; and 2 percent have migrated 75 percent or more of workloads. Five percent of respondents said that they have not migrated from VMware at all.
Among migrated workloads, 72 percent moved to public cloud infrastructure as a service, followed by Microsoft’s Hyper-V/Azure stack (43 percent of respondents).
Overall, 86 percent of respondents “are actively reducing their VMware footprint,” CloudBolt’s report said.
“The fear has cooled, but the pressure hasn’t—and most teams are now making practical moves to build leverage and optionality—even if for some that includes the realization that a portion of their estate never moves off VMware,” Mark Zembal, CloudBolt’s chief marketing officer, said in a statement.
While bundled products, fewer options, resellers, and higher prices make VMware harder to justify for many, especially SMB customers, migration is a long process with its own costs, including time spent researching alternatives and building relevant skills. CloudBolt’s reported multi-platform complexity (52 percent) and skills gaps (33 percent) topped the list of migration challenges.
“As organizations diversify away from VMware, they inherit the operational burden of managing multiple platforms with different operational and governance models,” the report reads.
While companies determine the best ways to limit their dependence on VMware, Broadcom can still make money from smaller customers it doesn’t deem necessary for the long term.
“Their strategy was never to keep every customer,” CloudBolt’s report says. “It was to maximize value from those still on the platform while the market slowly diversifies. The model assumes churn and it’s built to make the economics work anyway. Broadcom has done the math—and they’re fine with it.”
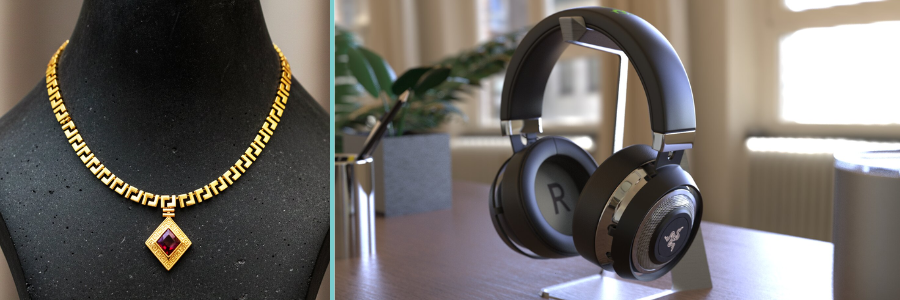
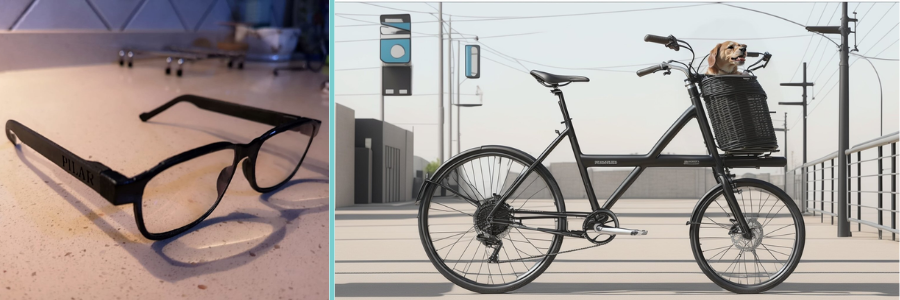
The classic napkin drawing has finally found its match. What used to begin with scribbled concepts and hours spent taking things back to the drawing board is today an extremely digitized, lightning-paced, and amazingly accurate process – and all thanks to Computer-Aided Design, or CAD design services. Today’s industrial designer does not need to struggle through trial-and-error fiddling or cumbersome prototypes that require weeks of rewriting. They use the digital might of CAD to visualize, simulate, and optimize ideas prior to making a single part.
Here comes the revolution. CAD and industrial design coming together is not a trend, but a complete paradigm shift in bringing ideas to product reality. Whether it’s consumer electronics, medical devices, wearables, or smart kitchen appliances, CAD tools are turning sketches into complex, production-worthy products quicker than ever before.
And when it comes to staying ahead in this fast-moving design world, Cad Crowd has emerged as the go-to company. More than just a talent pool, Cad Crowd is a global hub of elite CAD designers and industrial engineers who are rewriting the rules of concept development – one digital model at a time.
But how, precisely, is CAD fueling this revolution? Let’s take a closer look at the sexy, streamlined, and unexpectedly human face of computer-aided design.
🚀 Table of contents
From Scribbles to solids: CAD as the designer’s superpower
Concept design is both thrilling and agonizing. It’s the design rollercoaster where imagination gallops full-speed ahead, only to be brought back into check by the harsh realities of cost, manufacturability, and schedule. Not so long ago, this process was driven by crumpled-up pencil mark-ups, clumsy foam models, and the prayer that you got the first guess right. Those analog mockups were tangible, no doubt – but also slow, delicate, and agonizingly unforgiving when it came to redrawing.
Then, computer-aided design (CAD) emerged on the scene like a superhero cape-clad crusader for industrial designers.
With the powerhouse software of SolidWorks, Rhino, AutoCAD, and Fusion 360, the industrial design expert’s crude sketch can morph into a stunning, precise 3D model in the blink of an eye. Need to carve an ideal curve? Adjust the thickness of a casing? Try out if the design can withstand a drop? CAD makes all these possible on your screen – with the added advantage of undo keys and unlimited iterations. It’s almost like going from charcoal sketch to sculpting with light.
What used to take days using clay or cardboard now takes hours or even minutes. But more significantly, it means that designers have the liberty to experiment without fear. If it does not work, it is a quick fix – not a complete redo.
CAD didn’t simply update concept design – it’s turbocharged it. It takes nebulous ideas and turns them into proven, buildable concepts, closing the gap between imagination and manufacturing. Now, designers don’t only imagine – now, they model, simulate, and iterate those imaginations with speed and accuracy. That’s the true superpower.
Speed, precision, and no guesswork: How CAD is redefining product design
There’s that magic moment in the life of every product – when it transitions from a crude drawing or delicate prototype into something you can actually produce. That used to take an exhausting period of time. Weeks of revisions. Months of reworks. But CAD (Computer-Aided Design) has entirely revamped the playbook.
Now, once an idea is captured digitally, the actual work starts – quickly. Designers can try out immediately how a hinge will function after 10,000 cycles. Want to test airflow through a snug casing full of sensitive electronics? Model it in minutes. Wonder how the product will appear in chrome versus matte black under lighting in the showroom? Render it and observe every nuance of the reflection.
This is not a time-saver – it’s a power shift. CAD provides industrial design companies with accuracy and authority unimaginable in the past. No more assumptions, no more “wait and see.” Each design decision is supported by actual data, virtual simulations, and testing that reveal flaws before anything physical is created.
The result? Improved products. Improved decisions. Fewer surprises.
Rather than responding to issues after prototyping or production, designers are actually addressing them ahead of time in the concept stage. They’re not only creating products – they’re creating confidence in the process. CAD enables groups to see further in advance, to construct smarter from the beginning, and to optimize that pivotal process from idea to real-world innovation.
That’s not evolution. That’s brainy design – and a significant step up in how we give ideas life.
CAD + collaboration = Creative firepower
Contemporary product design isn’t the isolated, lone genius scribbling concepts on a napkin anymore. Now, it is a complex interplay between industrial designers, mechanical engineering experts, UX specialists, marketers, and even users who will ultimately be utilizing the product. That is, it’s a team effort – one that requires perpetual communication, quick iteration, and accommodation.
But in the past, concept design was not exactly a workshop of collaboration. Legacy tools – such as static sketches, foam mockups, and unnecessary email chains – were buggy and unwieldy. They were slow to accommodate the speed of innovation and the demand for real-time commentary. Designers could spend weeks honing a concept, only to discover the engineers couldn’t implement it – or that marketing had a whole different idea.
Then CAD came along – and the world changed.
Computer-Aided Design transformed the way teams ideate, iterate, and bring to life. Particularly today, with cloud-based CAD software and collaborative spaces, the design process has gone truly global. A Toronto designer can model the outside of a product while a Berlin engineer works on the internal features. Meanwhile, a Seoul UX consultant is testing how it handles in a user’s hand. It all occurs in real time, with changes automatically tracked, revisions stacked effortlessly, and no one excluded from the loop.
It’s not only efficient – it’s lightning in a bottle. This kind of transparency and integration stimulates creativity. With less siloing and more collaborative input, teams can share out-there, unconventional ideas and actually pursue them without missing deadlines. CAD unleashes diverse thinkers to collaborate in a common digital sandbox, where walls come down and innovation blooms.
This collective magic not only speeds things up. It improves things. It provides a window of opportunity for multidisciplinary innovations and brings design to the people. You no longer have to have everyone in the same room – or even on the same continent – to form something remarkable.
And this is precisely where Cad Crowd becomes the secret weapon. Cad Crowd is not merely a freelance platform. It’s a network of premium CAD designers and engineers at your disposal. Want a team that can turn your napkin sketch into a fully realized, ready-to-manufacture prototype? Done. Want someone to craft a beautiful enclosure or 3D print-optimize your product? Someone in the Cad Crowd community has already figured out a better way to do it.
With Cad Crowd, you’re not just outsourcing tasks – you’re building a remote dream team that’s already aligned with the pace and expectations of modern design. They speak the language of collaboration, and they live inside the CAD ecosystem. That’s the new creative firepower – and it’s lighting up the future of product development.
Digital twins: CAD as the secret behind smarter, sleeker products
From voice-activated thermostats to palm-top drones that deploy midair, products these days are supposed to be geniuses straight out of the box. But all that smarts – sensors, circuit boards, batteries, Bluetooth modules – must be shoehorned into increasingly slender, more ergonomic packages. Getting that magic to work without the product burning up, frying itself, or shaking apart is no small thing.
This is where CAD comes in as the silent hero.
With CAD, designers don’t simply draw good-looking shells – they create digital twins: precise virtual replicas that replicate how the real product will perform. Such models do much more than depict dimensions. They model real-world stress, thermal flow, electromagnetic interference, and even how consumers may touch the product.
Suddenly, designers and product design engineers aren’t operating in the dark anymore. They’re not guessing if a new case will heat up too much or whether a button will be easy to press. They’re trying it – all of it – before any prototype is even created.
For companies providing industrial design services, this makes all the difference. Function and design no longer need to battle for supremacy; they’re created simultaneously. Redesigns are fewer, development cycles are quicker, and a lot more confidence entering manufacturing is the new reality.
In short, CAD-enabled digital twins are making smart product design a precision engineering endeavor – and the outcomes are simply nothing short of brilliant.
Goodbye silos, hello synergy: How CAD unites design, engineering, and manufacturing
In the past, product development was a disconnected experience between designers, engineers, and manufacturers. Designers would design something wonderful, engineers would struggle with making it feasible to produce, and manufacturers would be left to figure it out – oftentimes from nothing more than a sketchy drawing and a hopeful smile. The outcome? Miscommunication, redesigns, blown budgets, and much frustration.
That antiquated model is rapidly disappearing, thanks to CAD. By beginning the design process in computer-aided design software, groups now share the same digital language. CAD files can be seamlessly transferred from design to engineering to manufacturing. A 3D model is more than an idea – it’s a living, breathing data source that everyone can collaborate on in real time.
Now, designers don’t have to speculate whether their concepts are manufacturable – they can check for manufacturability in an instant. Engineers can get involved early, making important adjustments on the fly. And manufacturing design experts? They receive accurate, detailed geometry that drives tooling and production without the need for a complete rework. What once was three disconnected steps now becomes one intelligent, integrated workflow.
This is where Cad Crowd excels. Their independent CAD professionals don’t work independently – they communicate and work with engineers and production staff to produce designs that are not just beautiful but also feasible to build. Whether prototyping or gearing up for full-on manufacturing, Cad Crowd keeps everyone on the same page and moving fast.
No more silos. No more cumbersome hand-offs. Just unadulterated synergy – concept to creation.
Iteration without the price tag: Why CAD makes experimentation affordable
Money speaks in product development – and at the concept phase, it screamed. Each design adjustment came with physical prototypes, delayed times, and material expenses. A single miscalculation could land you back to square one, losing thousands on tooling or replicating costly molds. It was a heart-pounding, wallet-emptying procedure.
Enter CAD, and all of this is different. Suddenly, testing six various housing arrangements doesn’t take six prototypes. Want to know how a new grip texture will feel? Model it and calculate the results – no injection mold needed. Need to test out another material? Replace it virtually and compare performance characteristics, all in a virtual space.
This is more than a change in workflow – it’s a radical redefinition of what iteration is. CAD eliminates the cost barrier to play. You can experiment without breaking the bank by committing to an expensive physical process each time. It converts “What if?” from a cost risk into a creative invitation.
That’s where Cad Crowd excels. Their seasoned product design services celebrate this CAD-fueled freedom, working in tandem through speedy back-and-forth iterations to hone your idea into a refined, production-critical masterpiece. They don’t only provide a design – They co-evolve it with you.
And since Cad Crowd’s talent base works remotely and on demand, you’re not financing overhead – you’re financing results. That means every development step remains affordable, scalable, and totally in sync with your project objectives.
So go ahead: push the boundaries. With CAD and Cad Crowd, iteration is no longer a cost; iteration is a step forward.
Where aesthetic meets engineering brilliance
Industrial design is not simply a matter of producing something that functions – it’s a matter of producing something that people will actually use. It’s the skill of finding a balance between beauty and performance, between emotion and accuracy. If a product is stylish but fails on day one, it’s bound for the landfill. If it’s sturdy but ugly and uninspired, it sits on store shelves in retirement. The magic occurs when form and function become one – and that’s precisely where CAD and engineering design services enter the scene.
Computer-Aided Design (CAD) turns design from guesswork to computed creativity. Those sleek curves and lines? With CAD, they’re not only pretty – they’re designed. Surfacing software allows designers to shape forms that are as functional as they are lovely. Vent holes are part of the design language, not an afterthought. An ergonomically tested smartwatch can be designed digitally, without a single prototype being produced, while internal layout and strength are optimized.
CAD bridges the gap between engineering reality and design intent. It is no longer a fight of wills to make a product visually pleasing or functional. You can do both now – and you should.
That’s why Cad Crowd is a game-changer. Their network of freelancers consists not only of CAD drafters and engineers, but also industrial designers who know that visual beauty isn’t icing on the cake – it’s in the recipe. These professionals design products that make eyes pop, hands reach out, and work perfectly. With Cad Crowd, your design doesn’t have to sacrifice style for function. You get both – engineered to perfection.
How CAD gives industrial design firms a manufacturing jandoff boost
In industrial design, a great idea is worthless if it can’t be transferred seamlessly to the production floor. That’s where CAD (Computer-Aided Design) really rocks – it closes the gap between the design studio and the factory floor with speed and accuracy, especially with design for manufacturability services.
When designers design models in CAD, they’re not merely creating something that is pretty. They’re creating digital products that are producible day one. These files can be exported directly into CNC machines, 3D printers, or injection molds without interference. This is because CAD preserves data fidelity so high that what is produced is precisely what was created, down to the micron.
Which means less surprise when parts arrive on the factory floor. With design-for-manufacturing principles integrated into the CAD process, expensive production mistakes are cut down to size, and time-to-market receives a significant improvement. From creating a prototype smart device in San Francisco to producing a large quantity of custom enclosures in Shenzhen, you can count on the same CAD file to produce reliable results.
This flexibility is a game-changer for industries like consumer electronics device companies and medical devices, where speed, precision, and quality are non-negotiable. Industrial design firms can now adopt distributed manufacturing strategies – printing or molding across multiple locations – all seamlessly powered by CAD.
And if you need CAD designs production-ready from the get-go? Cad Crowd brings you in contact with veteran designers who know the entire pipeline. These are not merely artists – they are engineers who create models developed to conform to actual manufacturing. From racing a deadline to ramping up a product launch, Cad Crowd provides you with the CAD know-how that keeps production moving smoothly.
Crowdsourced design, solution-oriented: How Cad Crowd is revolutionizing the game
Crowdsourcing isn’t what it used to be – and that’s a good thing. What once had a reputation for being a fast-and-cheap shortcut is now a powerful engine for innovation, especially in the world of CAD and industrial design. At the forefront of this transformation is Cad Crowd, a platform that’s turned the typical design process on its head by tapping into a global network of brilliant minds.
Cad Crowd offers more than just freelance help – it brings a hybrid approach that combines open design challenges with curated, one-on-one collaboration. Companies can launch design contests to spark a flurry of inventive ideas, then choose the standout designer from the crowd to bring the concept to life. It’s a clever blend of creativity and execution, where fresh perspectives meet serious engineering muscle.
For startups, entrepreneurs, and fast-scaling businesses, Cad Crowd offers a vital shortcut through the expensive and time-consuming world of in-house design. Hiring a full team isn’t always realistic – especially when agility matters. Cad Crowd acts as your virtual product design department, ready when you are, no overhead required. Whether you’re working on a consumer gadget, medical device services, or rugged industrial equipment, you get access to pre-vetted CAD professionals who understand your goals and work seamlessly to deliver stunning, functional results.
This isn’t just about slashing budgets – it’s about leveling up. Cad Crowd empowers you to pursue cutting-edge product ideas without sacrificing quality or speed. You don’t have to choose between affordability and excellence. You get both – plus the added benefit of working with a team that’s laser-focused on solving your specific design problem.
By merging global collaboration with top-tier engineering, Cad Crowd is reshaping how great products get made. It’s not just a design platform. It’s a launchpad for the next big thing.
CAD is the future – and the now
Computer-Aided Design is more than a tool of the future – it’s redefining the product development game today. With innovation hurtling ahead, CAD technology is being powered by AI-assisted design recommendations, generative modeling, real-time simulation, and even topology optimization. Product development experts don’t have to do it alone anymore; they’re working alongside smart systems that process millions of data points and design iterations within seconds.
Nevertheless, in this maelstrom of progress, there is one thing that does not waver: technology is just as strong as the minds that direct it. The human element – creative instinct, hands-on know-how, and a gut feeling for what works – is irreplaceable. AI can propose forms, but it can’t comprehend market forces or emotional design. It can refine a shape, but it can’t sense the gravity of a customer’s expectation.
That’s where Cad Crowd is different. It’s not merely a venue to hire a person who has the capability to work with CAD software – it’s where businesses encounter innovative professionals who understand how to leverage these tools strategically and creatively. These are the engineers-turned-designers who think like them, create like entrepreneurs, and mold like artists.
CAD is the driving force behind contemporary design. But visionaries continue to drive. Cad Crowd is not only a part of the CAD revolution – it’s a leader in it. When you want designs that look great on the screen but translate into the real world, this is where you’ll discover the talent that can get that done.
It’s easy to use CAD. It’s not so easy to master it.
The top industrial design experts understand that CAD is not merely about quicker drafting or more glamorous renders. It’s about revolutionizing how product ideas are developed, tested, tweaked, and released. It’s about accelerating time to market, increasing design excellence, and minimizing waste – all while extending creative horizons.
Cad Crowd doesn’t just ride this wave – they help build it. By connecting companies with elite CAD professionals around the globe, they empower businesses of all sizes to modernize their product concept design workflows. Whether you’re launching a revolutionary wearable or refreshing an existing product line, Cad Crowd makes it smarter, faster, and more scalable.
From concept sketches to manufacturable 3D files, from photorealistic rendering to functional prototyping, they’ve got the talent and tools to transform even the roughest idea into something market-ready.
In a world where the next big idea could come from anywhere, Cad Crowd ensures you’re ready to design it, model it, and bring it to life – with CAD precision and creative fire. This isn’t something that you can just find or get anywhere. It’s a result of years of expertise and well-honed skills from being in the industry.
So go ahead – dream big. CAD’s got your back. And Cad Crowd is ready to help. Get a free quote today.
MacKenzie Brown is the founder and CEO of Cad Crowd. With over 18 years of experience in launching and scaling platforms specializing in CAD services, product design, manufacturing, hardware, and software development, MacKenzie is a recognized authority in the engineering industry. Under his leadership, Cad Crowd serves esteemed clients like NASA, JPL, the U.S. Navy, and Fortune 500 companies, empowering innovators with access to high-quality design and engineering talent.